
A Survey Of Speculative Decoding Techniques In Llm Inference

A Survey of Speculative Decoding Techniques in LLM Inference

A Survey of Speculative Decoding Techniques in LLM Inference
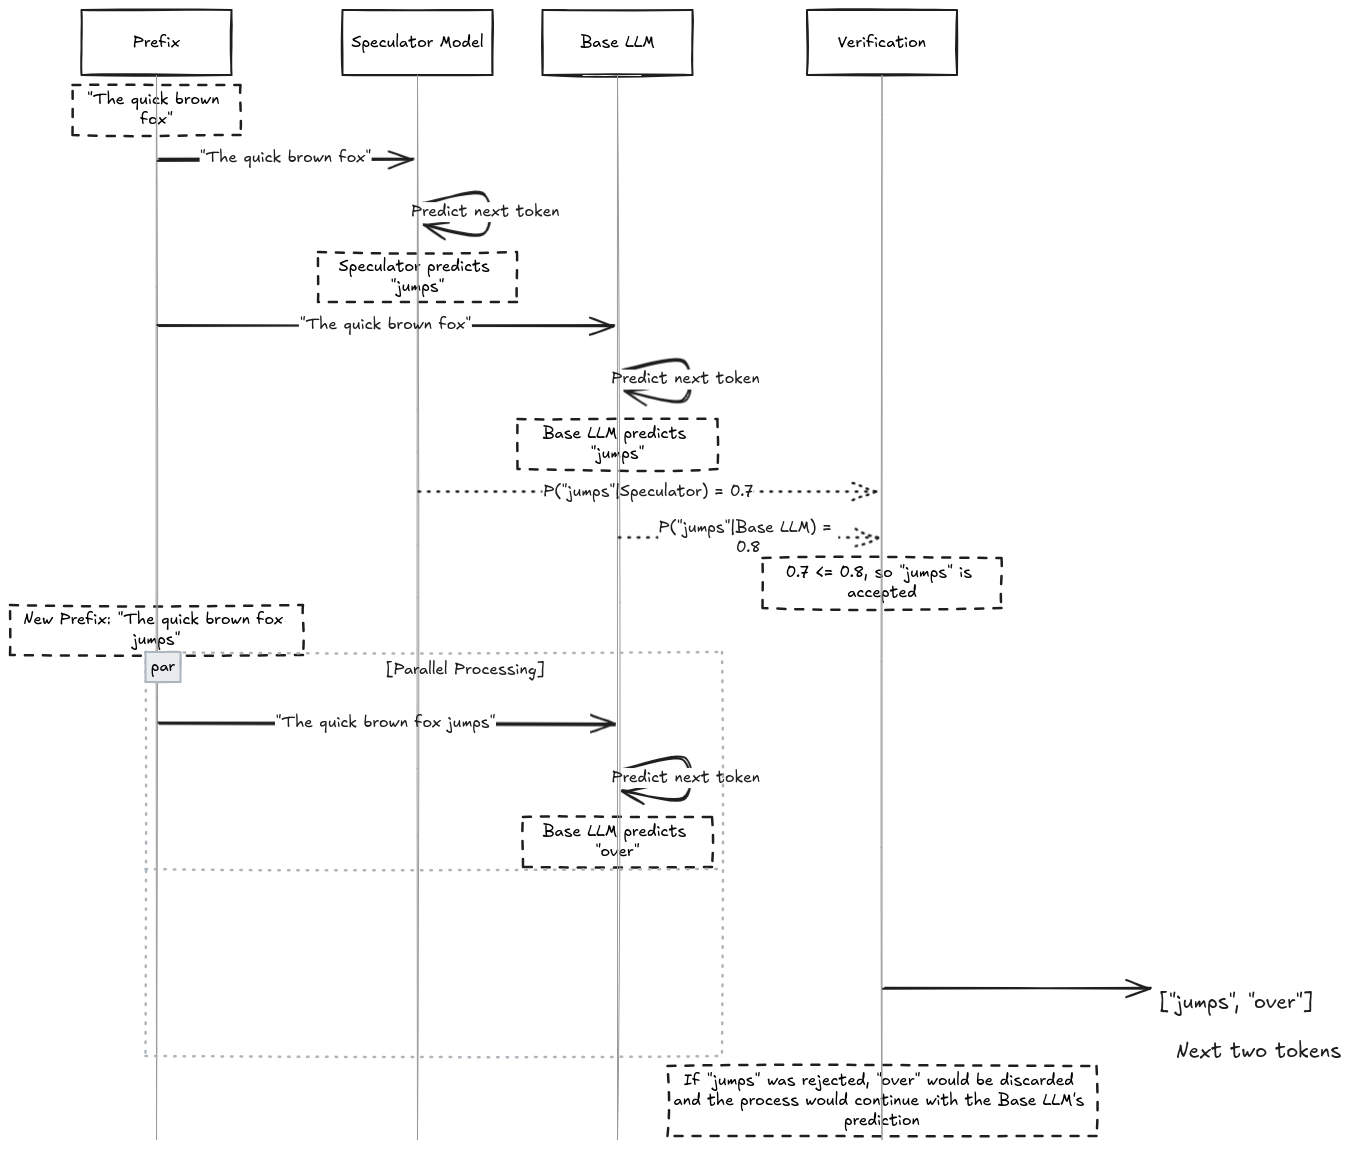
A Survey of Speculative Decoding Techniques in LLM Inference

A Survey of Speculative Decoding Techniques in LLM Inference
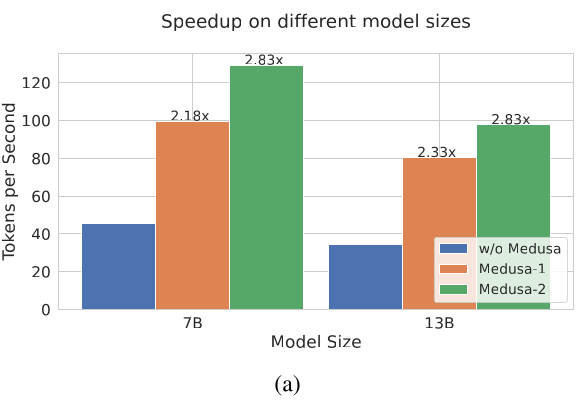
A Survey of Speculative Decoding Techniques in LLM Inference
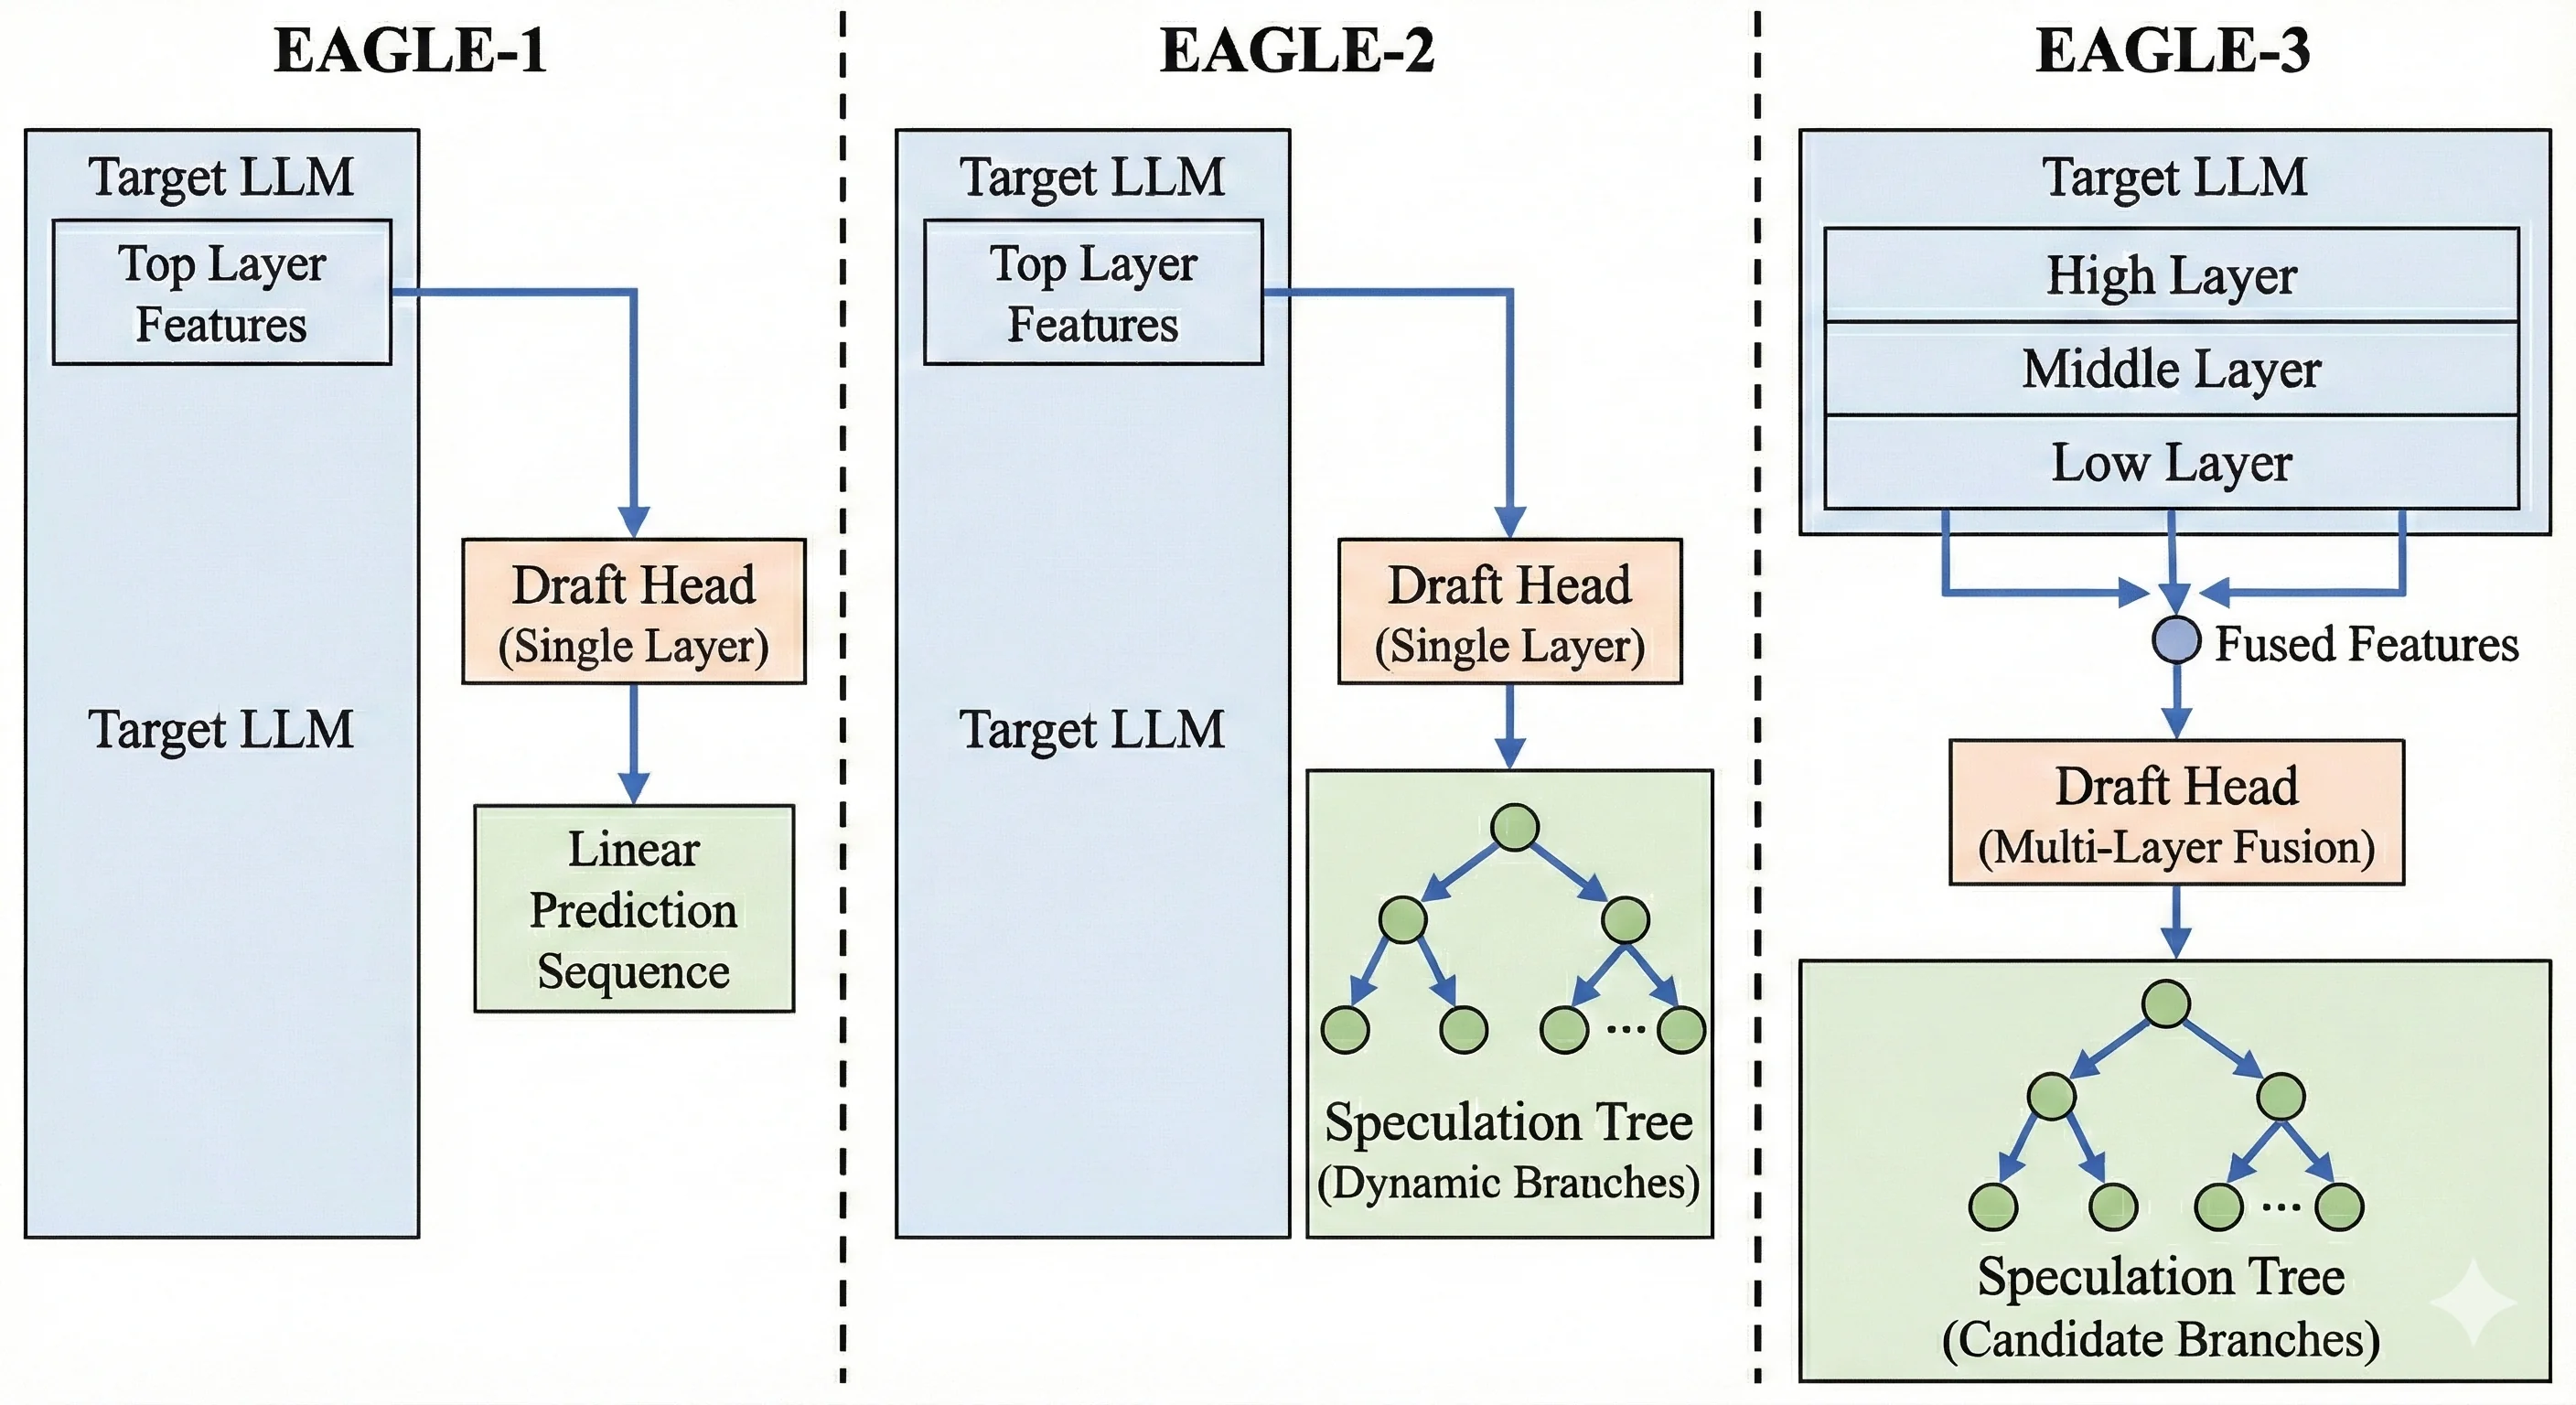
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
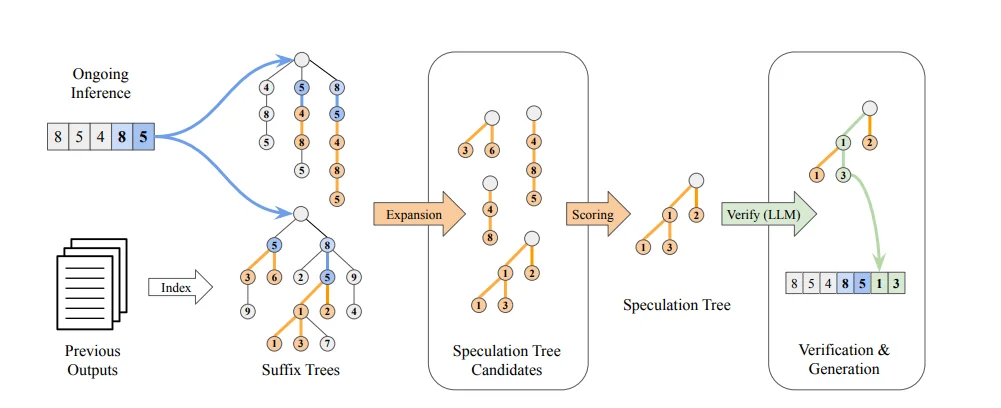
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
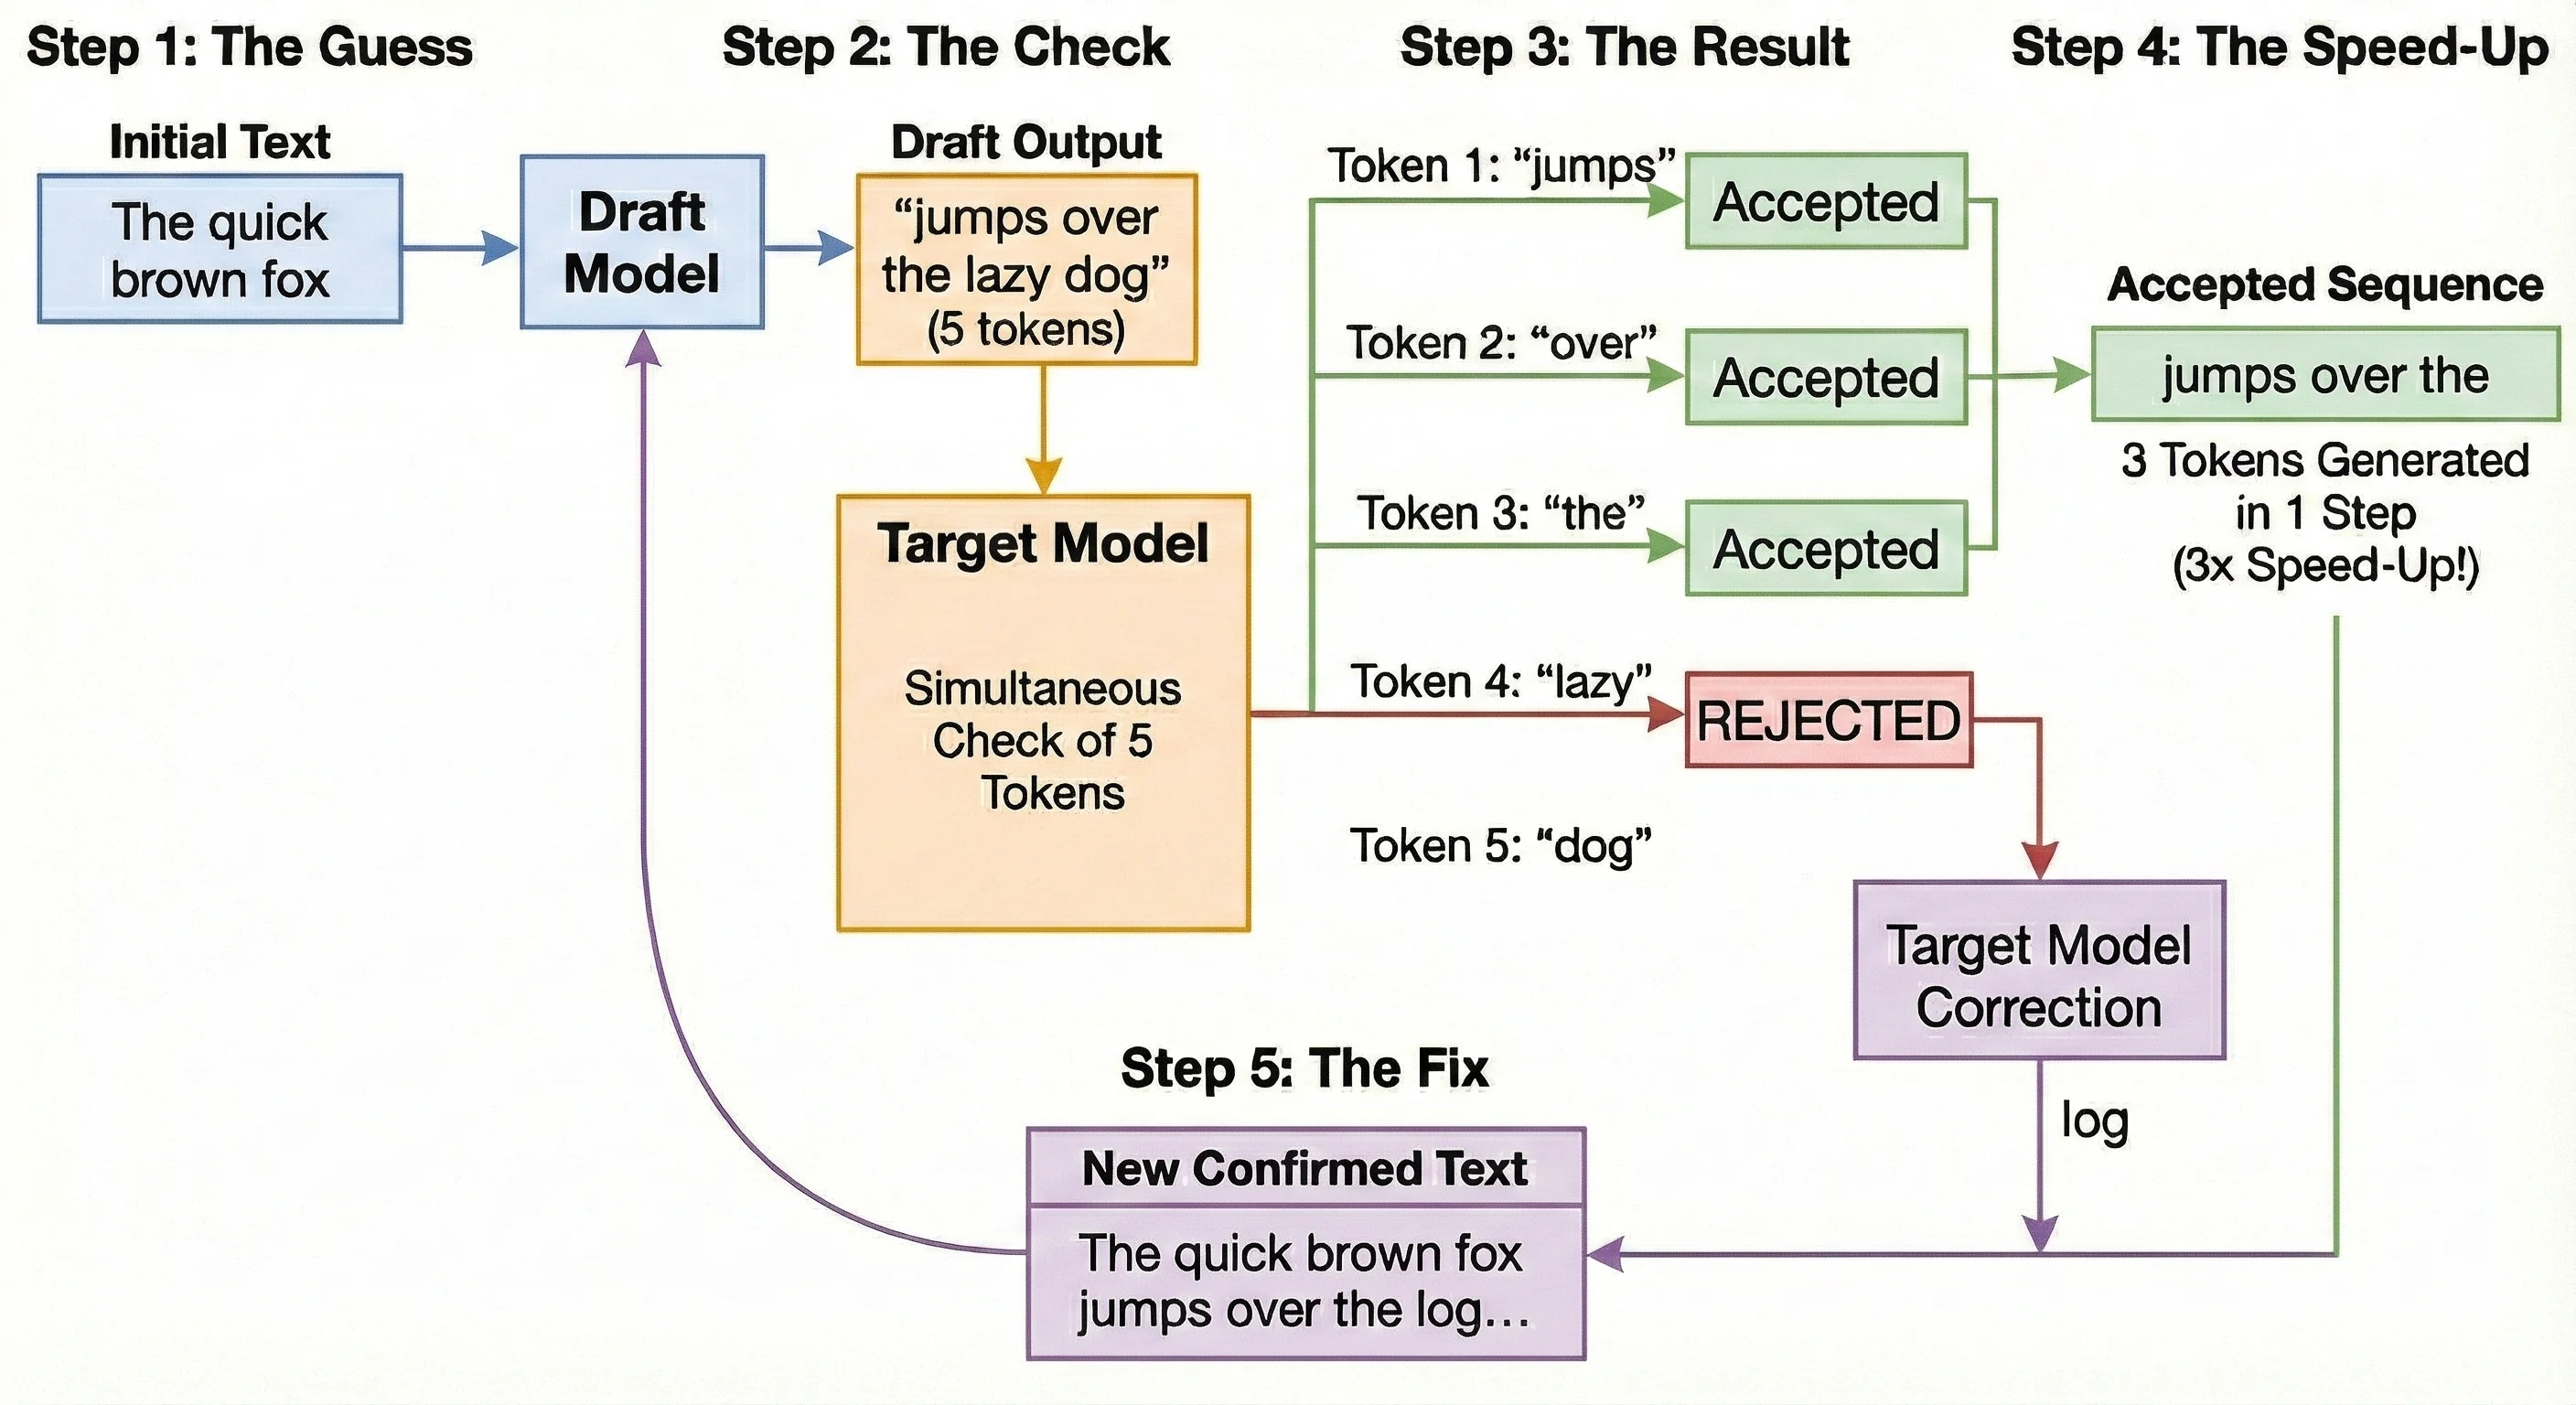
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...

Survey of Speculative Decoding in LLMs | PDF

A Survey of LLM Inference Systems
Advertisement Space (300x250)
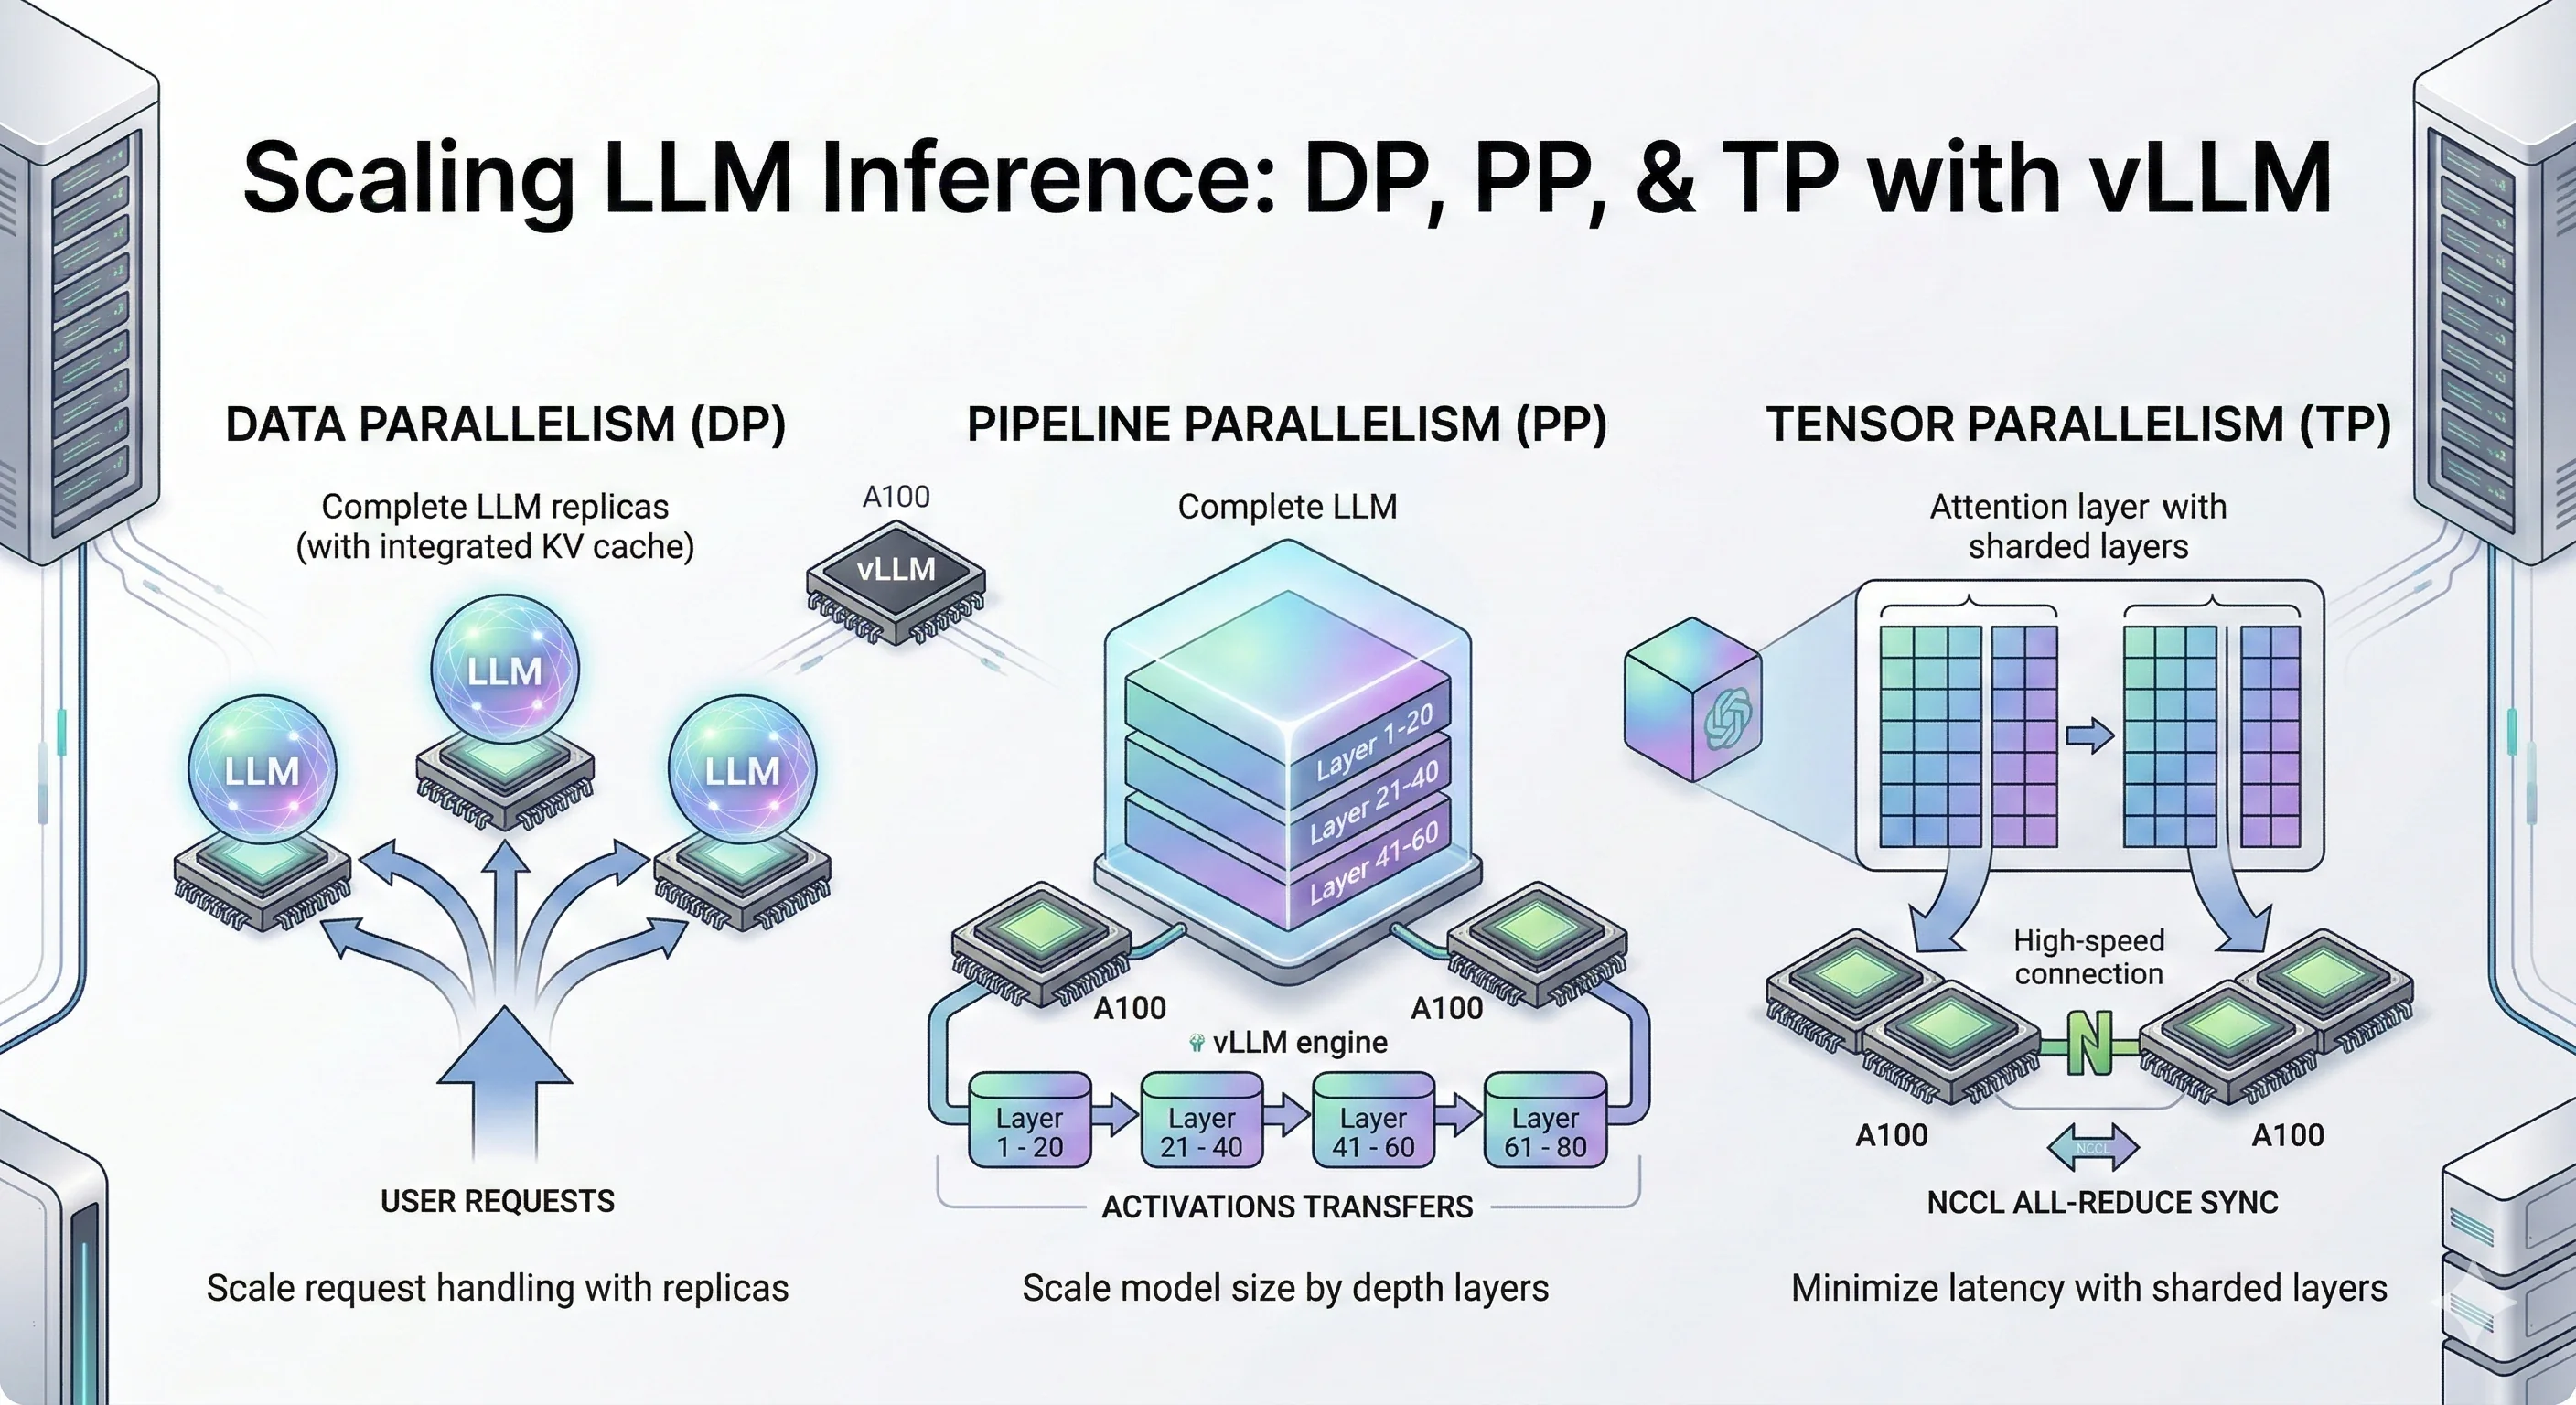
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
P-EAGLE: Faster LLM inference with Parallel Speculative Decoding in ...

[Review] Catch up on Speculative Decoding in 5 minutes: a survey for ...
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
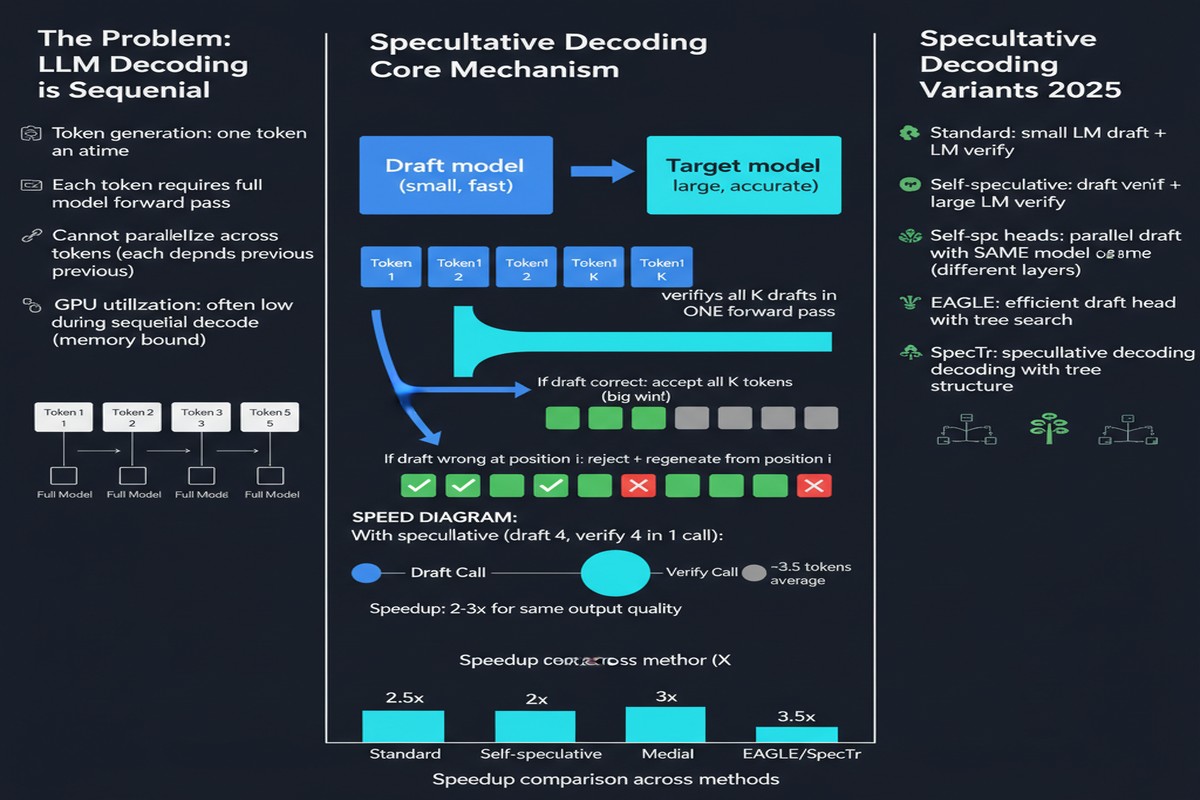
Speculative Decoding in 2025: The Inference Acceleration Technique That ...

Boosting LLM Inference Speed Using Speculative Decoding | Towards Data ...
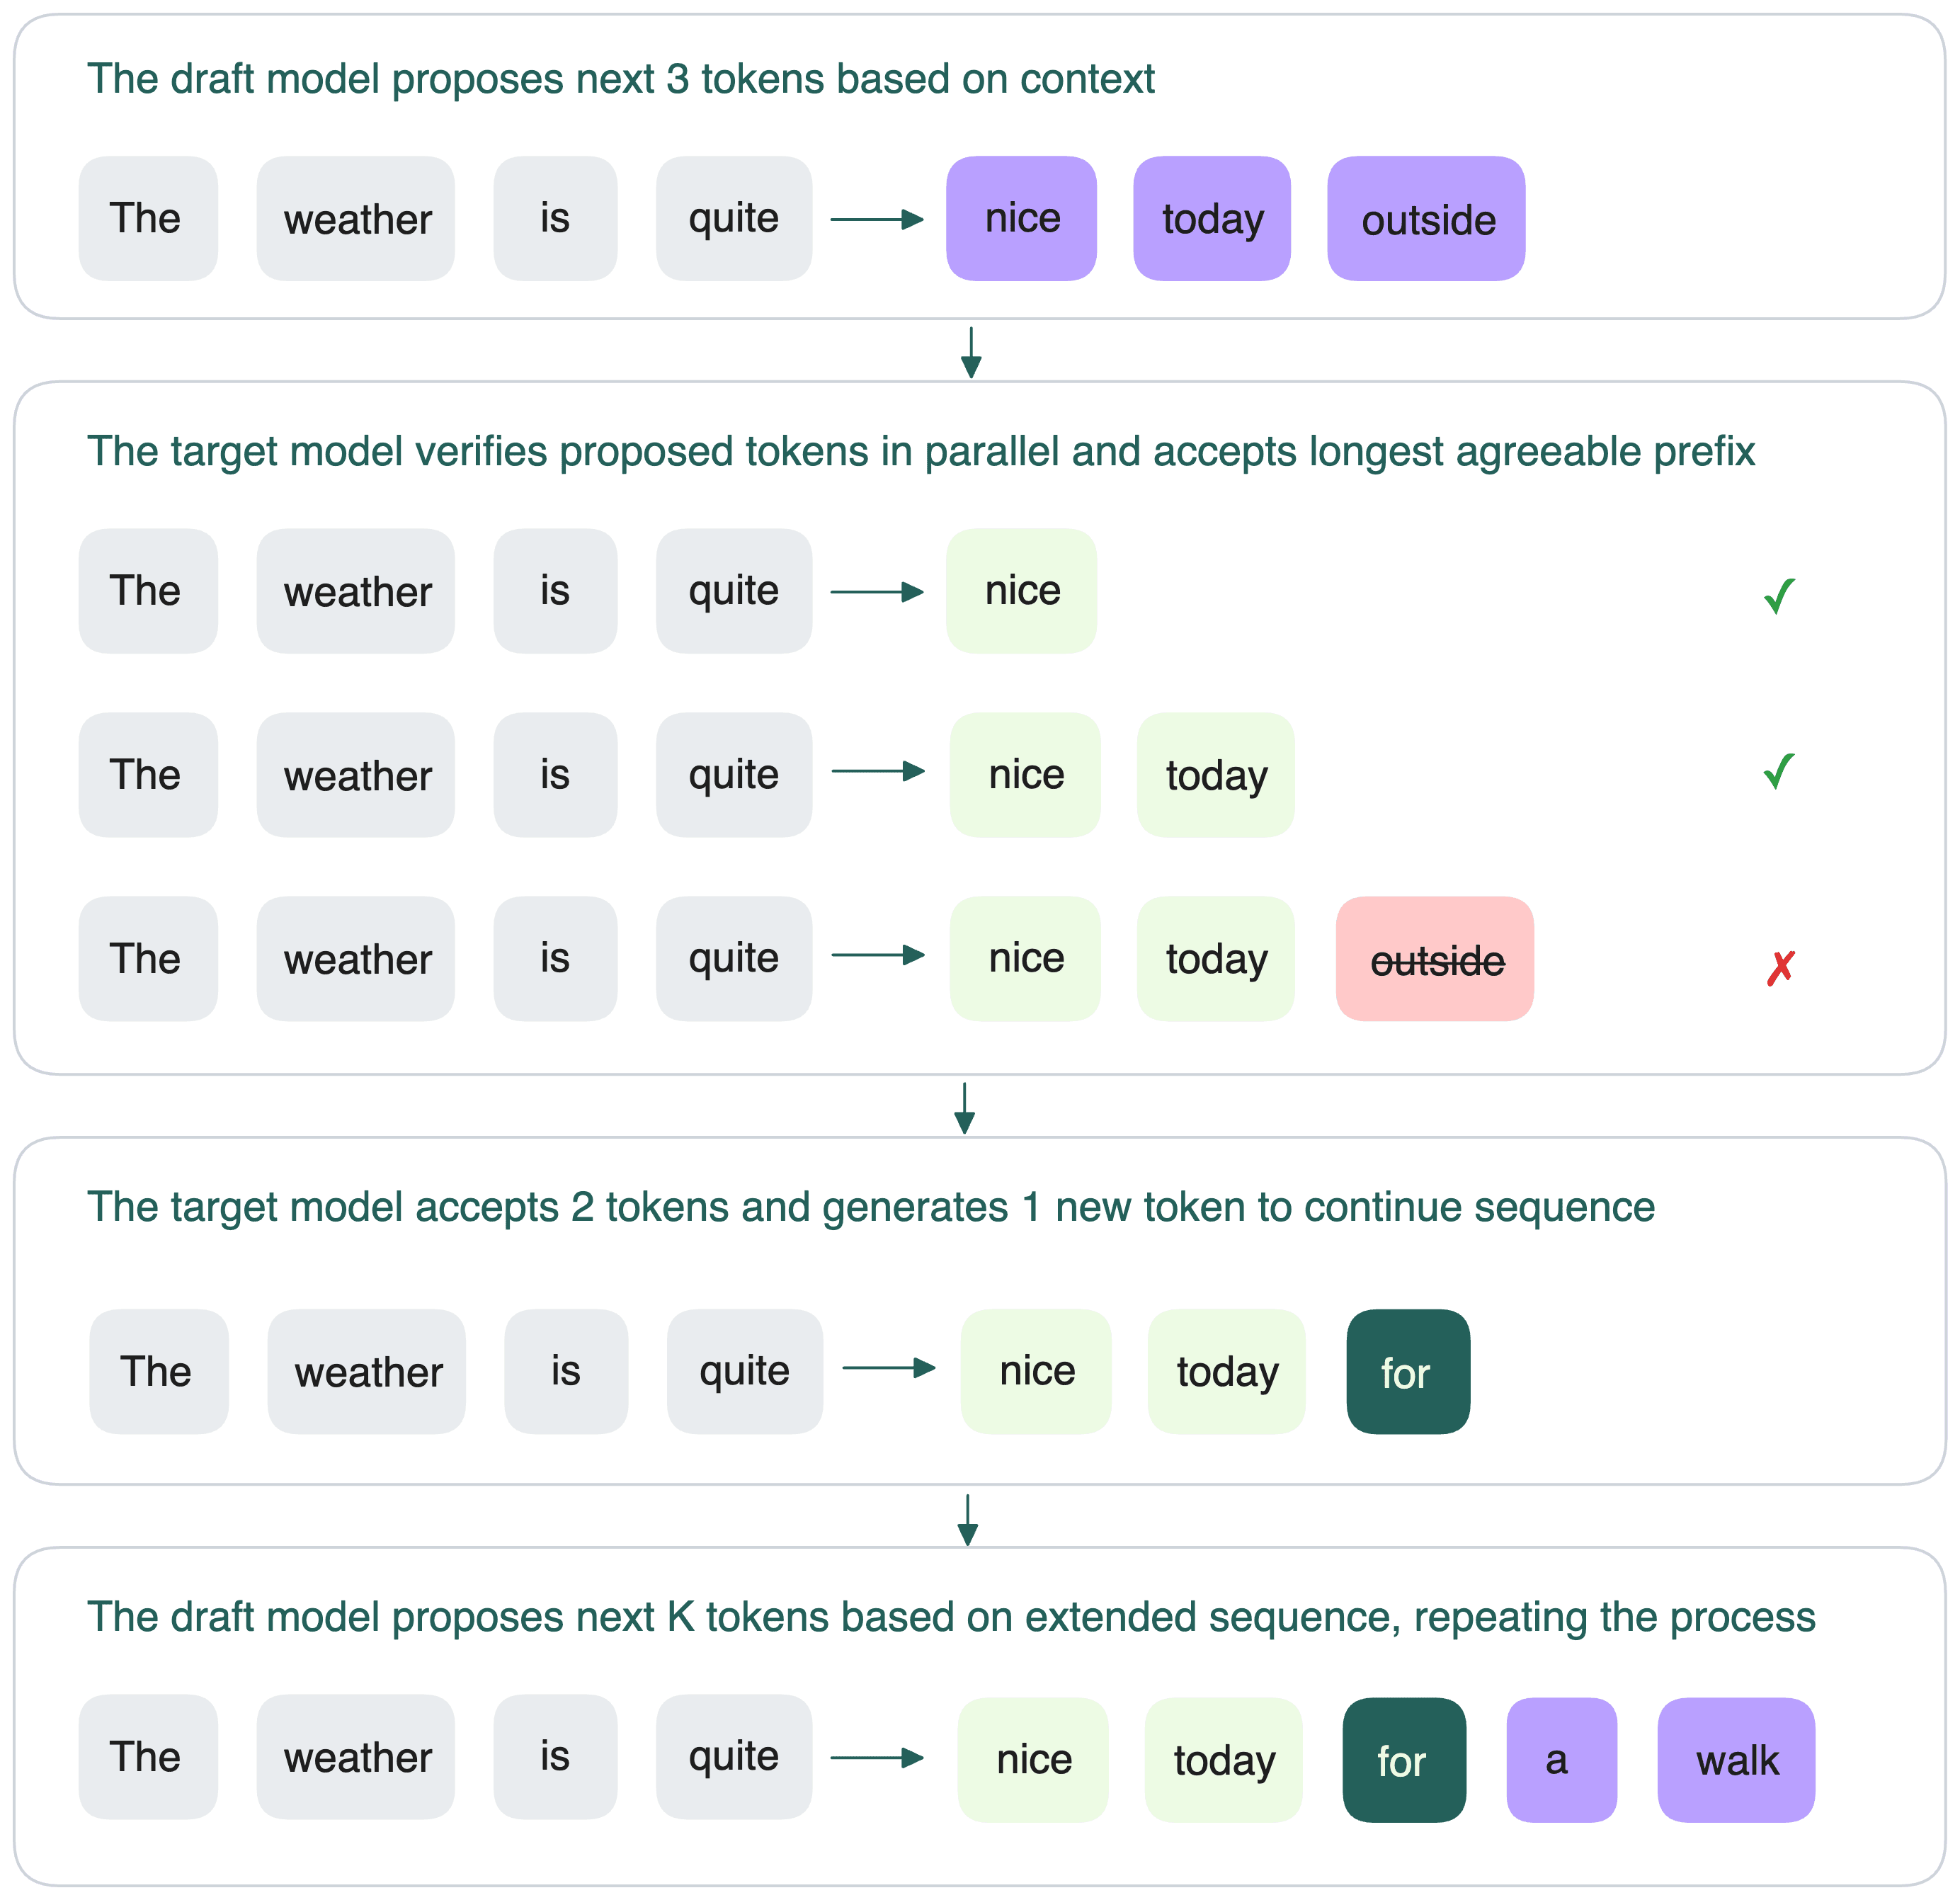
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...
🚀 Speed Up LLM Inference with Speculative Decoding | by Generative AI ...
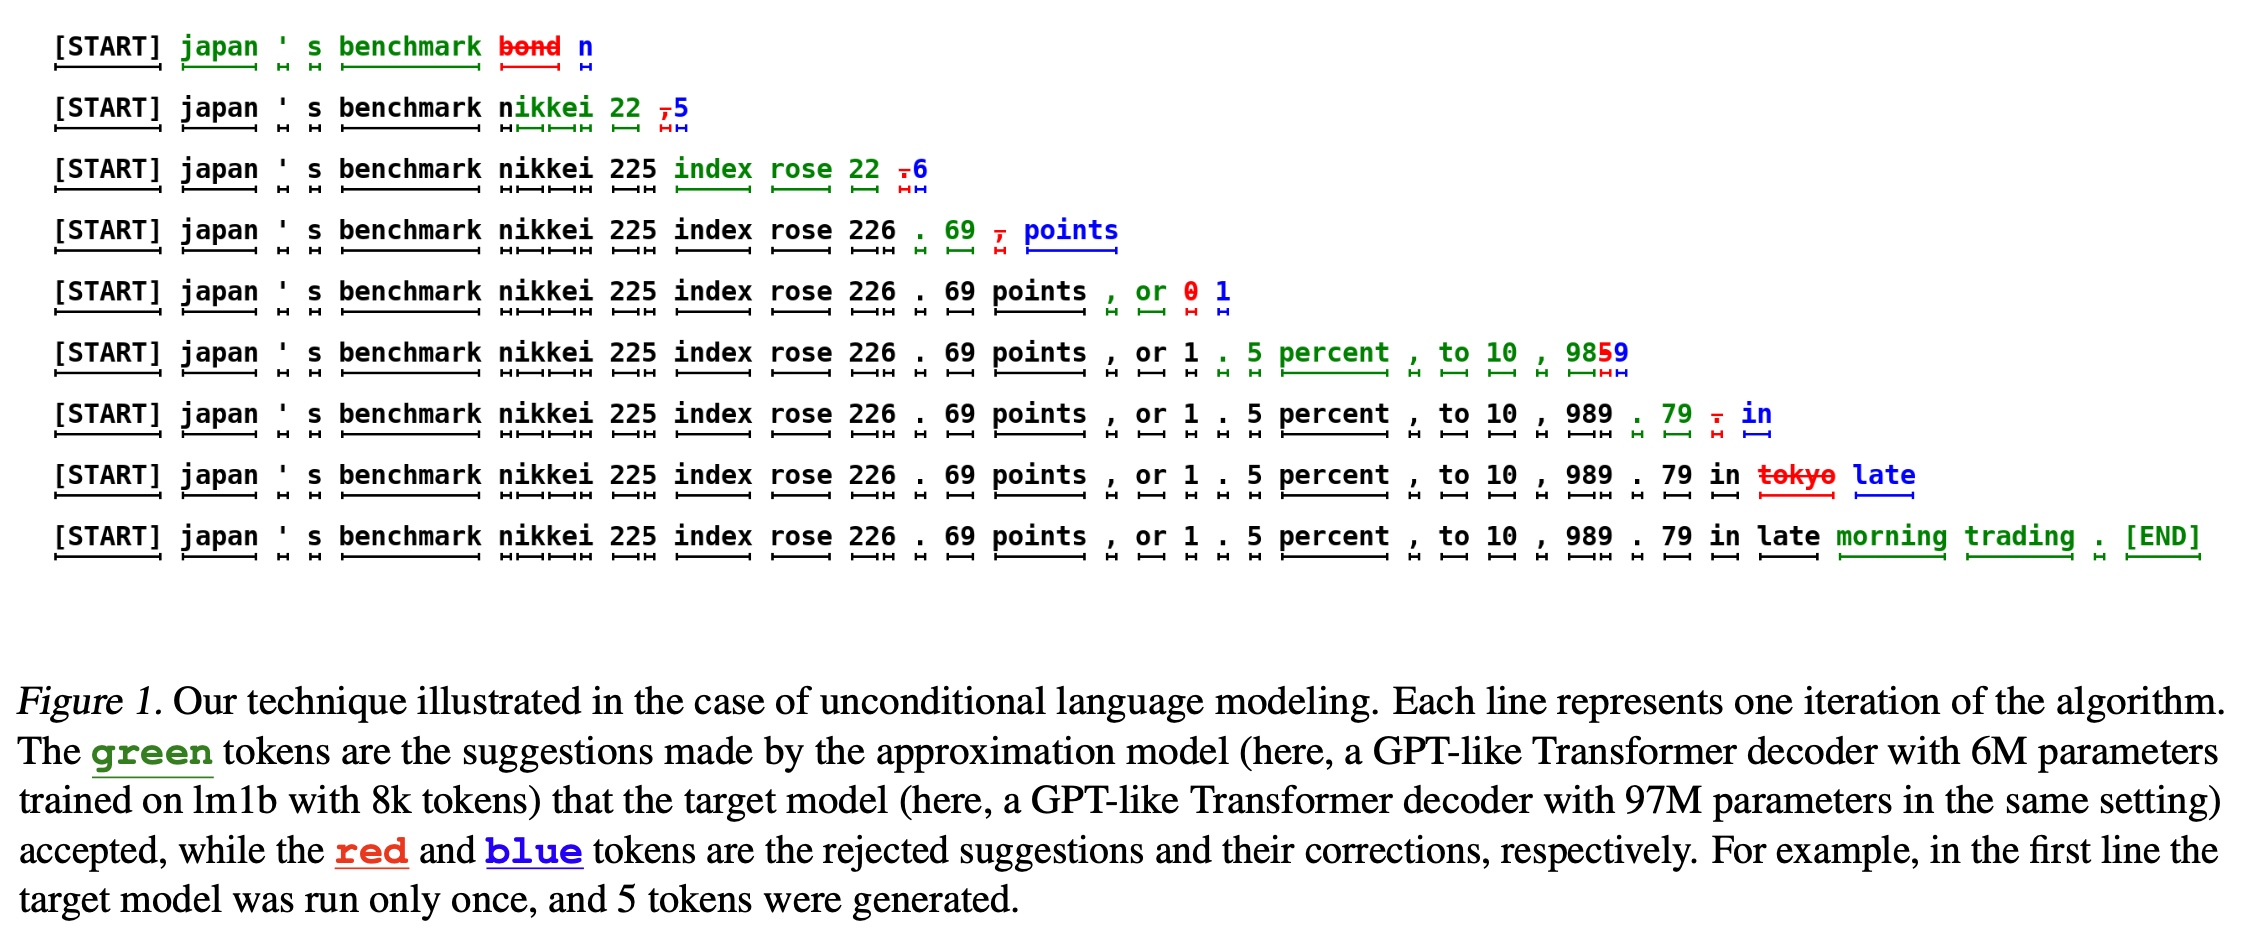
Accelerate LLM Inference with Speculative Decoding | Charles Xu

Speculative cascades — A hybrid approach for smarter, faster LLM inference
Advertisement Space (336x280)

(PDF) Accelerating LLM Inference with Staged Speculative Decoding

(PDF) Accelerating LLM Inference with Lossless Speculative Decoding ...

Paper page - Accelerating LLM Inference with Staged Speculative Decoding
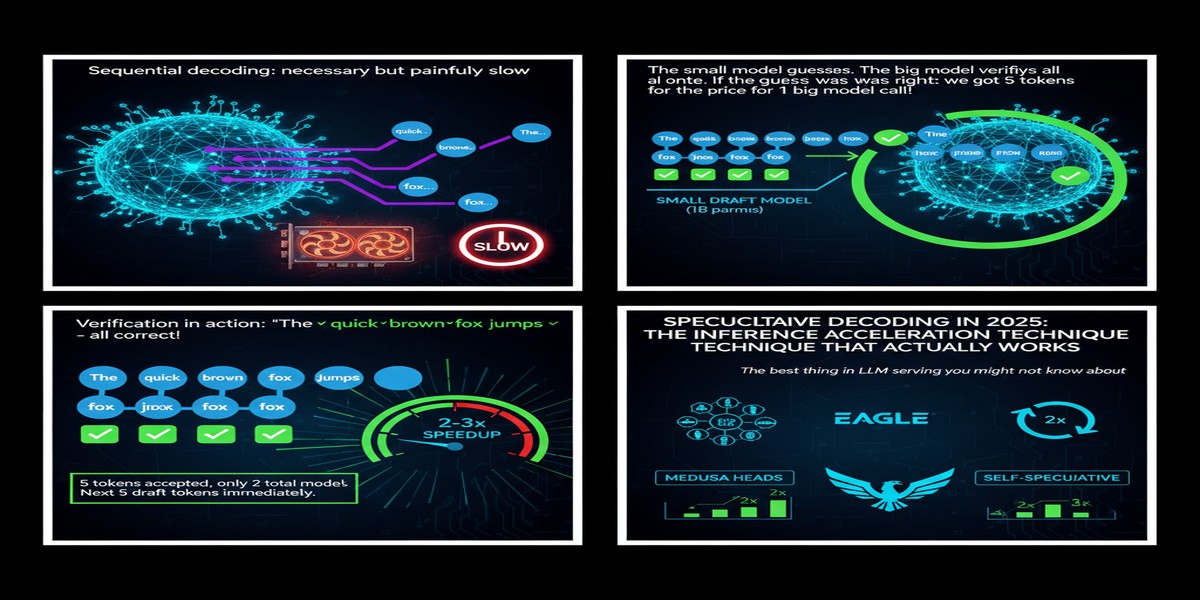
Speculative Decoding in 2025: The Inference Acceleration Technique That ...

(PDF) Closer Look at Efficient Inference Methods: A Survey of ...

Speculative Decoding with CTC-based Draft Model for LLM Inference ...

Speculative Decoding via Early-exiting for Faster LLM Inference with ...
Speculative Decoding Production Guide: 2-5x Faster LLM Inference on GPU ...

Speculative Decoding via Early-exiting for Faster LLM Inference with ...

Why Your LLM Is Wasting 90% of Its GPU — And How Speculative Decoding ...
Advertisement Space (336x280)

Free Video: Speculative Decoding: Techniques for Faster LLM Inference ...

Speculative Decoding in Decentralized LLM Inference: Turning ...

[2503.10325] Collaborative Speculative Inference for Efficient LLM ...
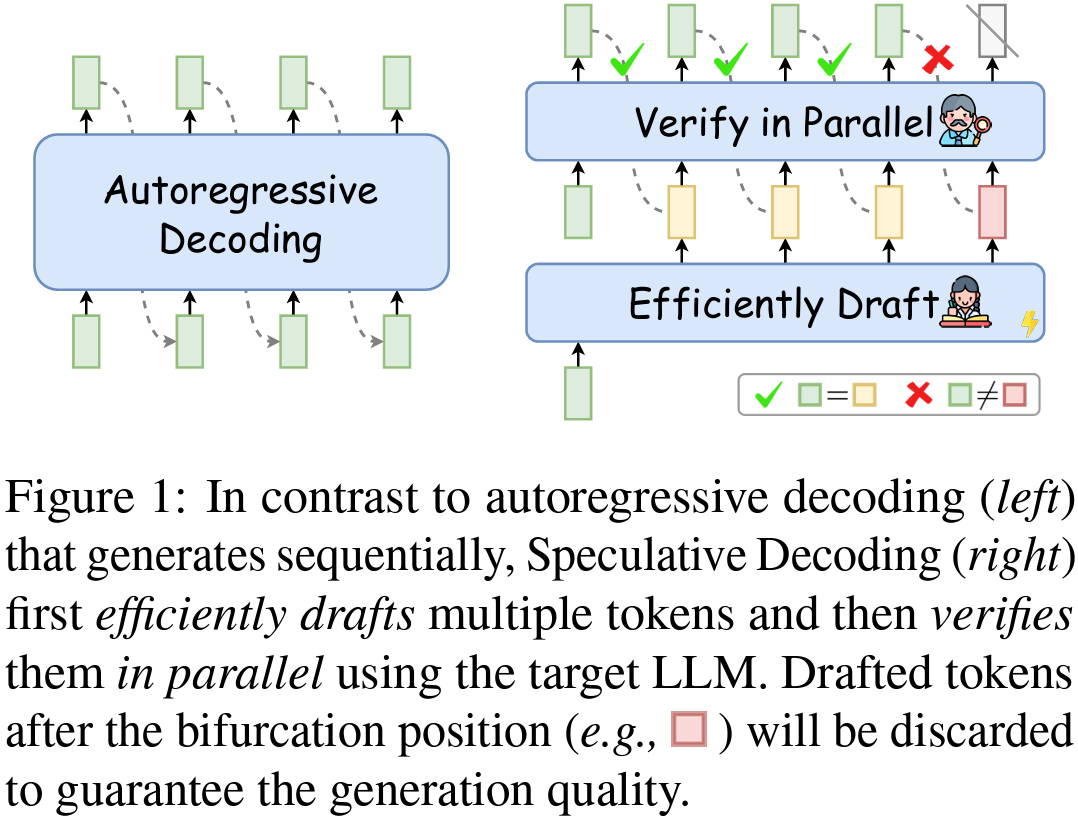
This AI Paper Unveils the Potential of Speculative Decoding for Faster ...
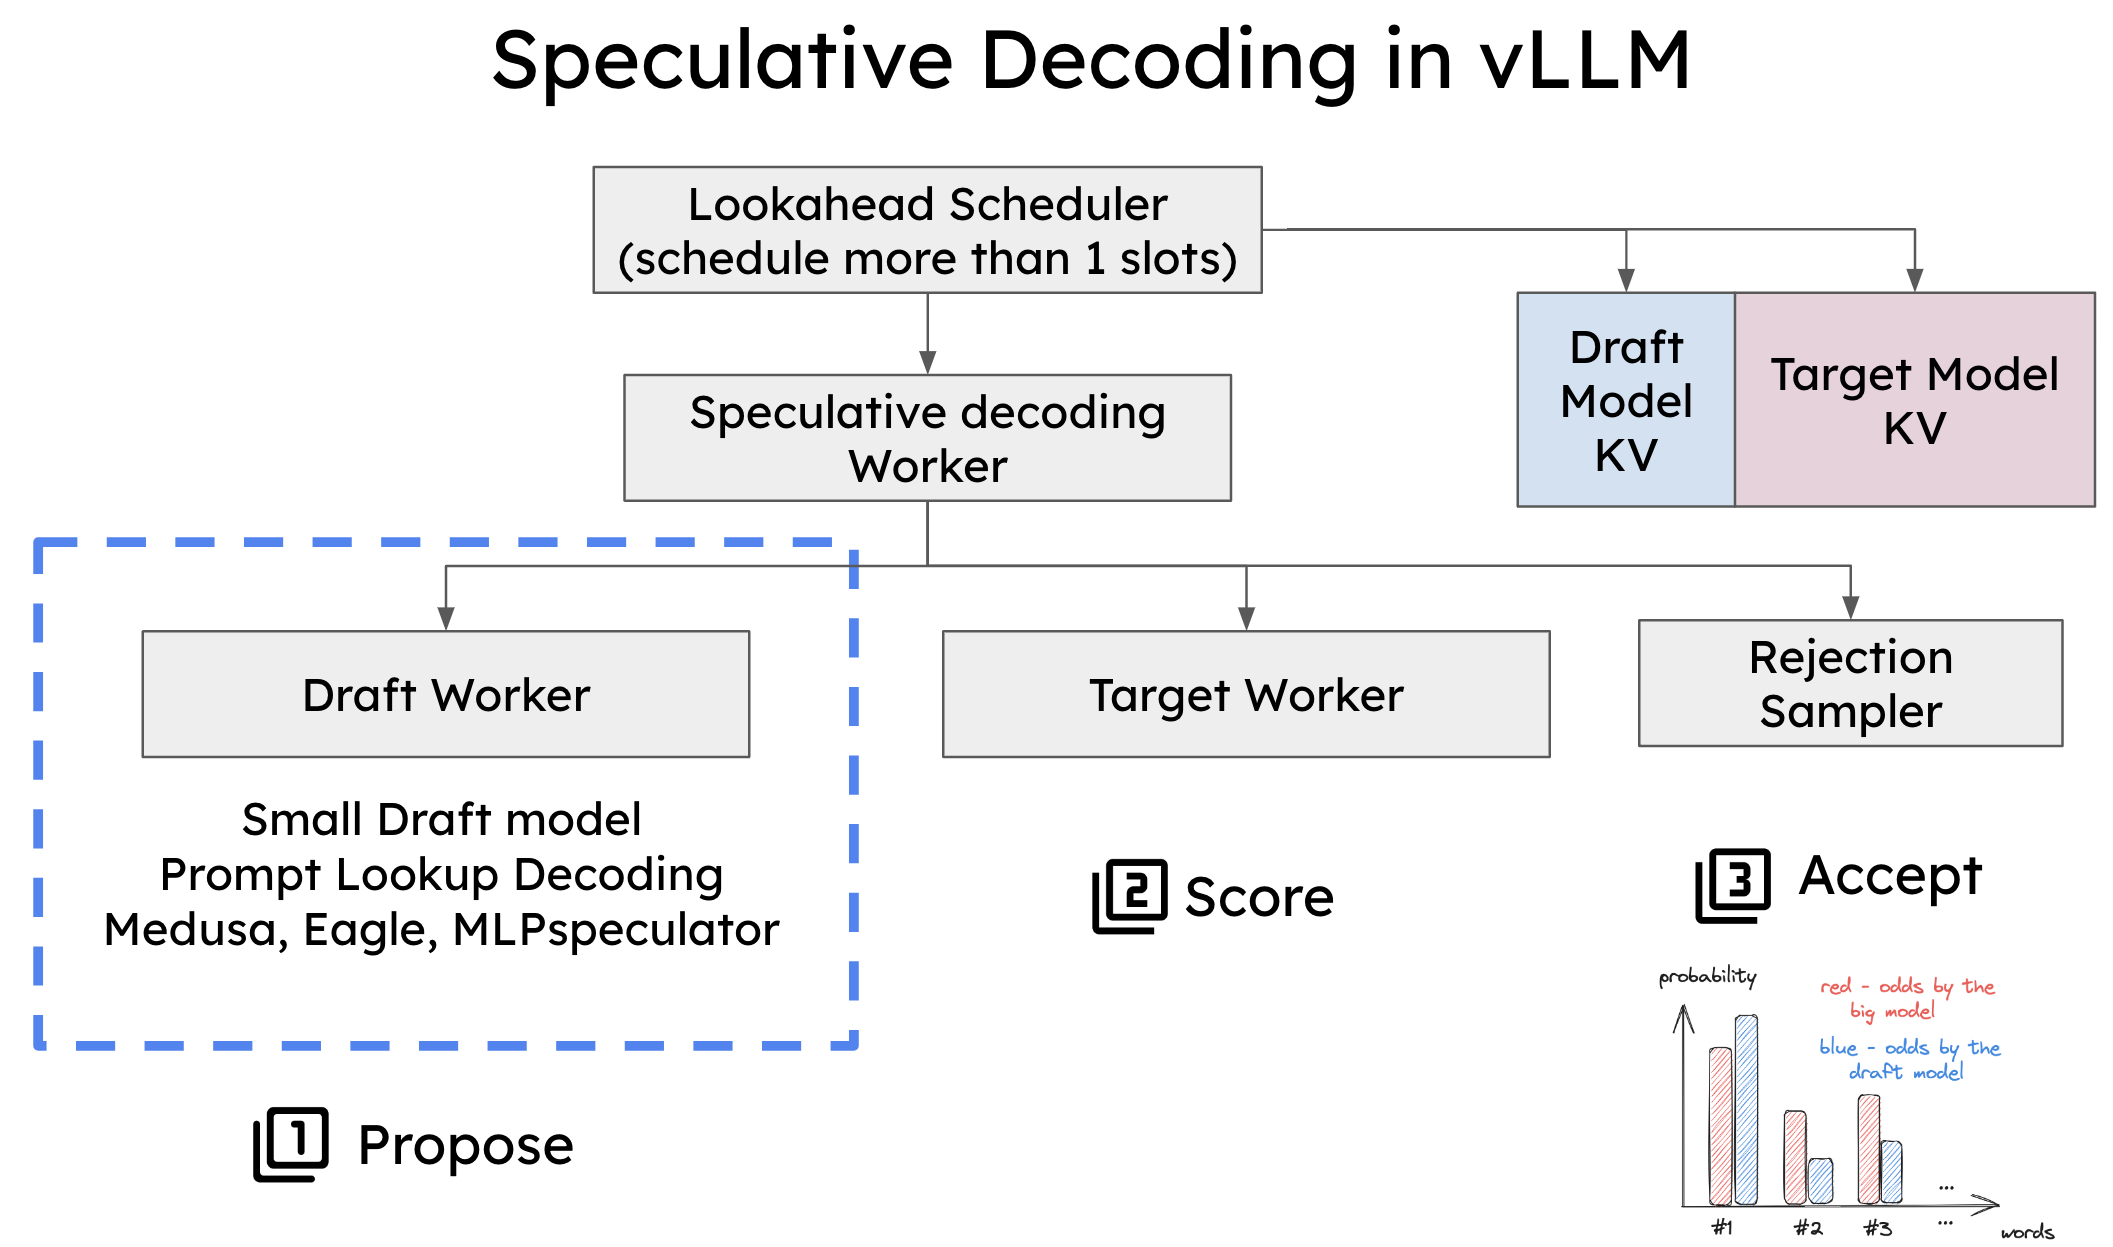
Speculative Decoding in vLLM | OpenLM.ai