
Aligning Llms With Individual Preferences Via Interaction

Figure 2 from Aligning LLMs with Individual Preferences via Interaction ...

Aligning LLMs with Individual Preferences via Interaction | AI Research ...

Aligning LLMs with Individual Preferences via Interaction - ACL Anthology

Aligning LLMs with Individual Preferences via Interaction | alphaXiv

Table 1 from Aligning LLMs with Individual Preferences via Interaction ...

Table 2 from Aligning LLMs with Individual Preferences via Interaction ...

LLM-Personalize: Aligning LLM Planners with Human Preferences via ...

(PDF) LLM-Personalize: Aligning LLM Planners with Human Preferences via ...

Aligning LLMs with Human Preferences is one of the most active research ...
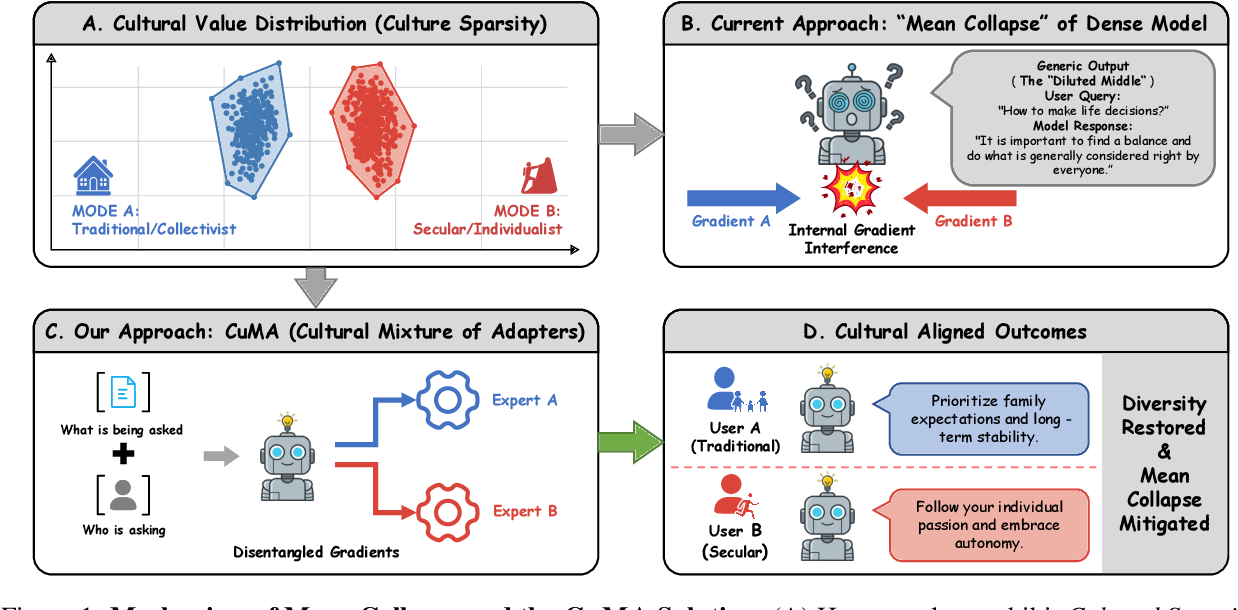
Figure 1 from CuMA: Aligning LLMs with Sparse Cultural Values via ...
Advertisement Space (300x250)

How preference learning can align LLMs with human preferences ...

WildFeedback: Aligning LLMs With In-situ User Interactions And Feedback

Aligning Large Language Models with Diverse User Preferences Using ...
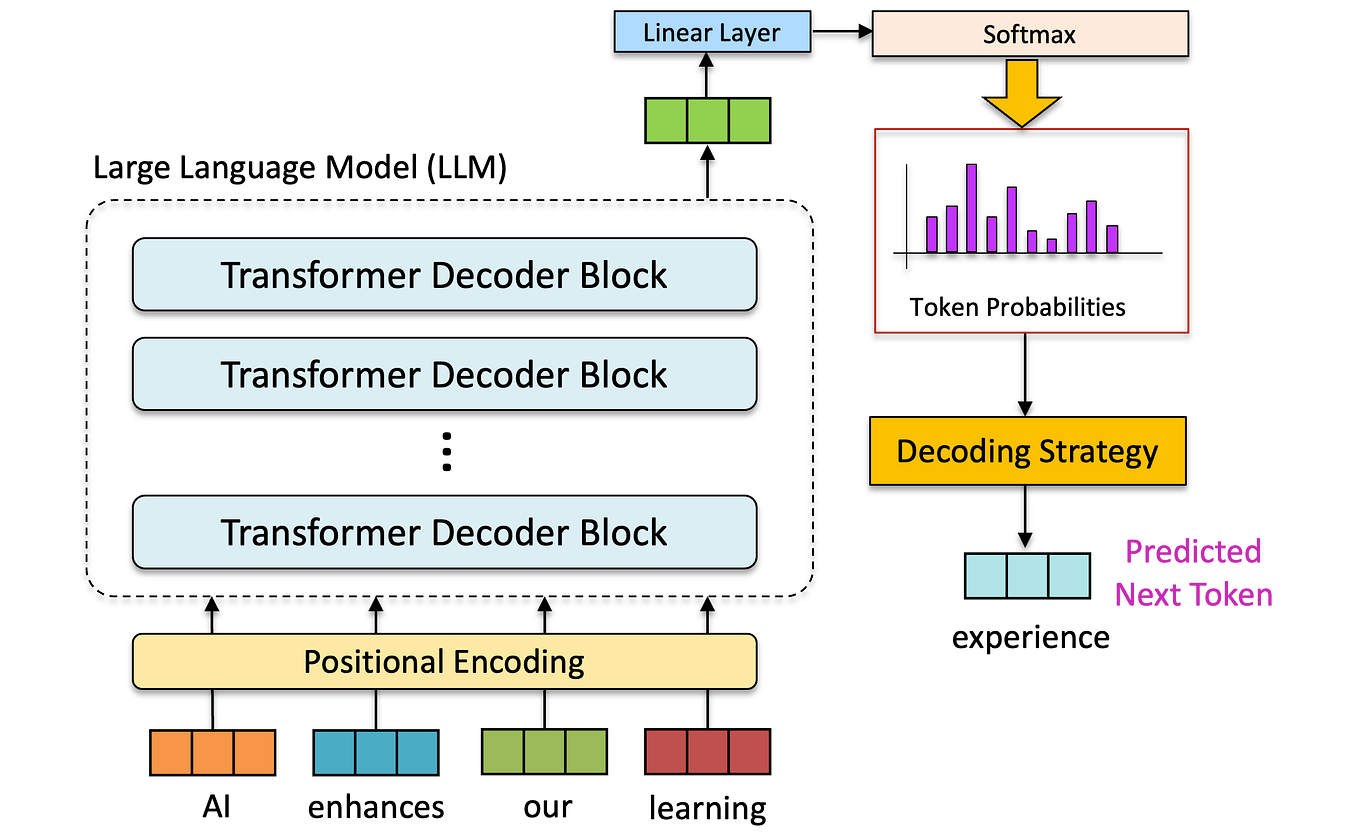
Aligning LLMs with Direct Preference Optimization (DPO)— background ...
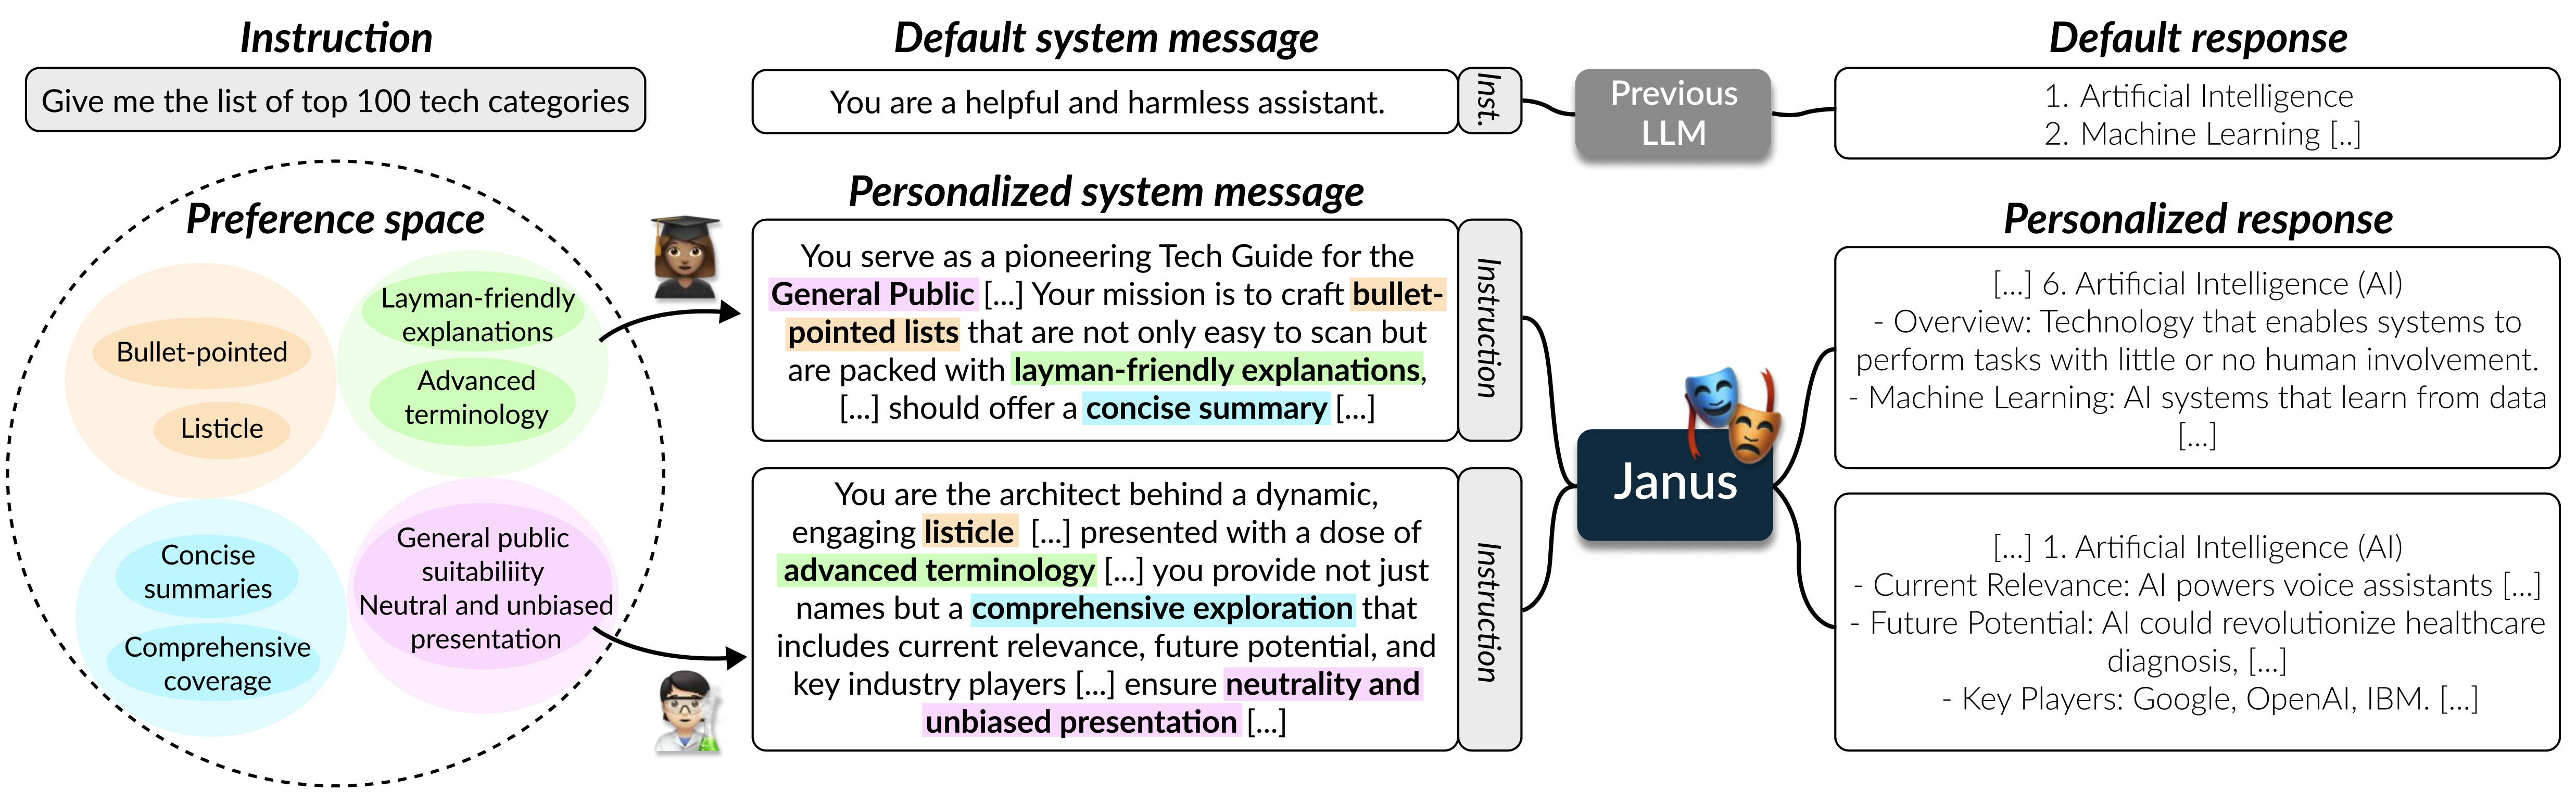
Aligning to Thousands of Preferences via System Message Generalization

From Problem-Solving to Teaching Problem-Solving: Aligning LLMs with ...

[논문 리뷰] AdaViP: Aligning Multi-modal LLMs via Adaptive Vision-enhanced ...

A General-Purpose Device for Interaction with LLMs | AI Research Paper ...

(PDF) PersonalLLM: Tailoring LLMs to Individual Preferences
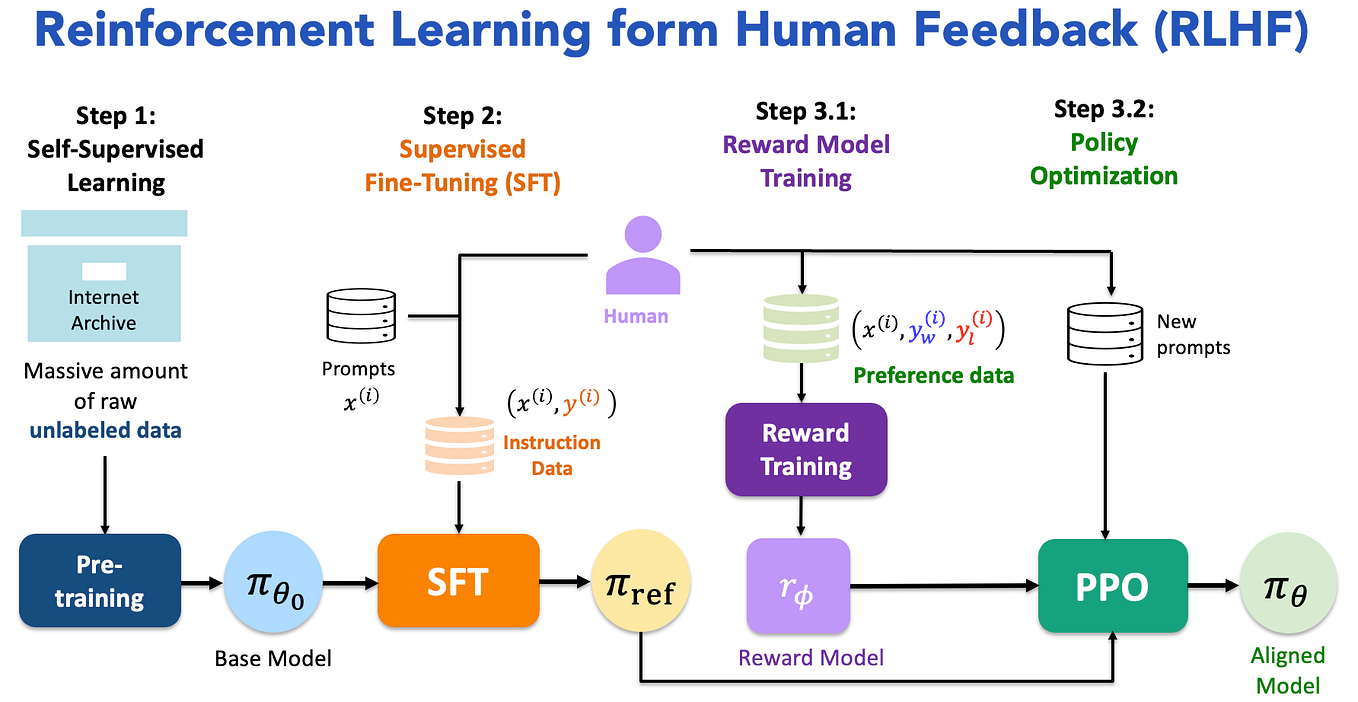
Aligning LLMs with Direct Preference Optimization (DPO)— background ...
Advertisement Space (336x280)

IOPO: Empowering LLMs with Complex Instruction Following via Input ...

Aligning llms with direct preference optimization - YouTube

Aligning LLMs with Direct Preference Optimization - Events ...

Aligning LLMs on a Budget: Inference-Time Alignment with Heuristic ...

Figure 1 from LLM-Personalize: Aligning LLM Planners with Human ...
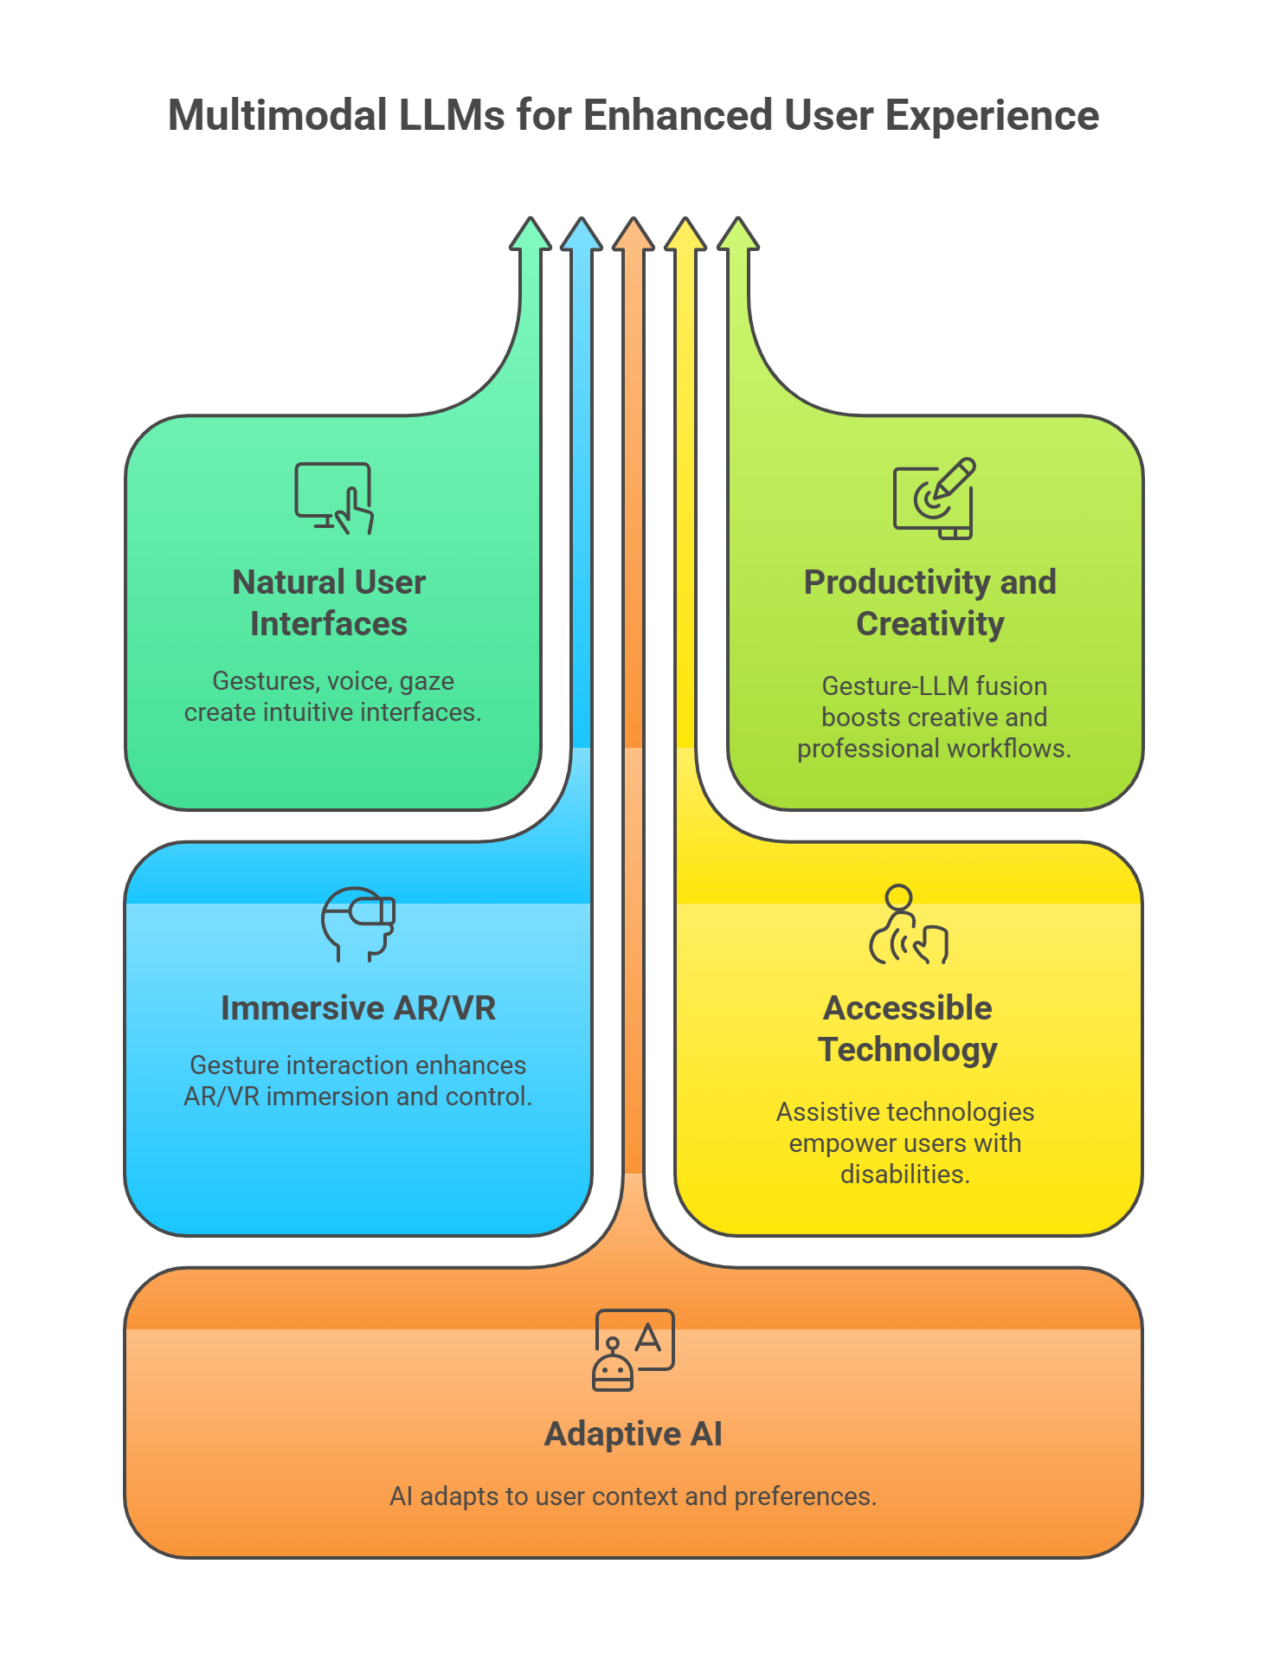
Bridging Vision and Language: The Future of Intuitive Interaction with ...

PACIFIC: Can LLMs Discern the Traits Influencing Your Preferences ...

[2406.00888] Show, Don’t Tell: Aligning Language Models with ...

Panacea: Pareto Alignment via Preference Adaptation for LLMs · NeurIPS 2024

[논문 리뷰] Aligning LLMs Toward Multi-Turn Conversational Outcomes Using ...
Advertisement Space (336x280)

[论文评述] When Weak LLMs Speak with Confidence, Preference Alignment Gets ...
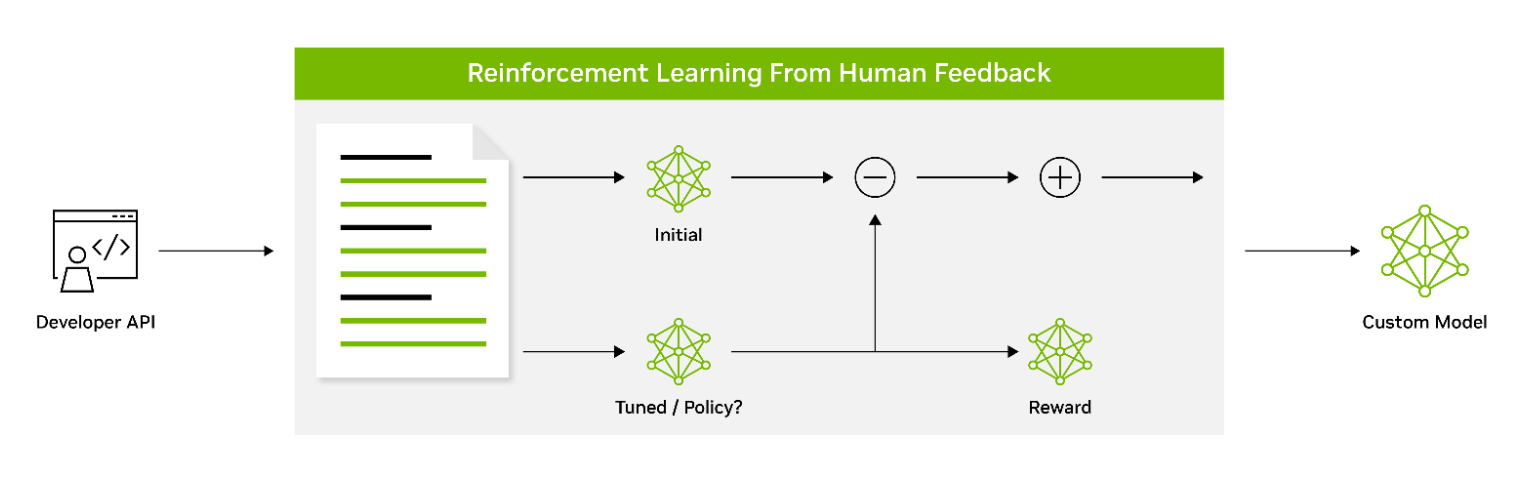
Unlocking the Power of Enterprise-Ready LLMs with NVIDIA NeMo – GIXtools

Exploring Information Interaction Preferences in an LLM-Assisted ...

POPI: Personalizing LLMs via Optimized Preference Inference | AI ...

Aligning LLMs through Multi-perspective User Preference Ranking-based ...

Reasoning on a Spectrum: Aligning LLMs to System 1 and System 2 ...