
Figure 1 From Ced Consistent Ensemble Distillation For Audio Tagging

CED: Consistent ensemble distillation for audio tagging

(PDF) CED: Consistent ensemble distillation for audio tagging

Paper page - CED: Consistent ensemble distillation for audio tagging

[2308.11957] CED: Consistent ensemble distillation for audio tagging

Figure 1 from Collaborative Score Distillation for Consistent Visual ...
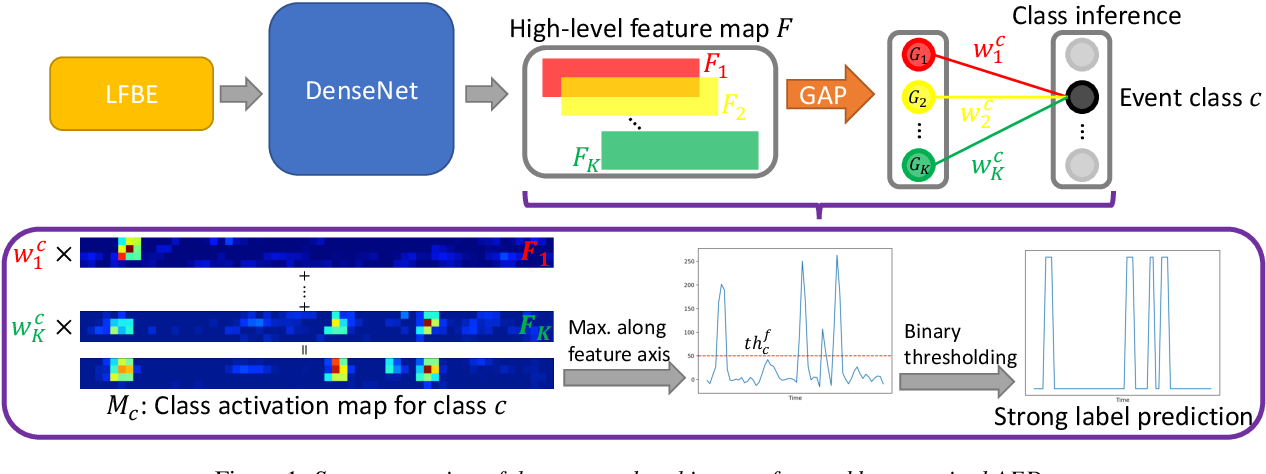
Figure 1 from A Joint Framework for Audio Tagging and Weakly Supervised ...

CED: Consistent ensemble distillation for audio tagging
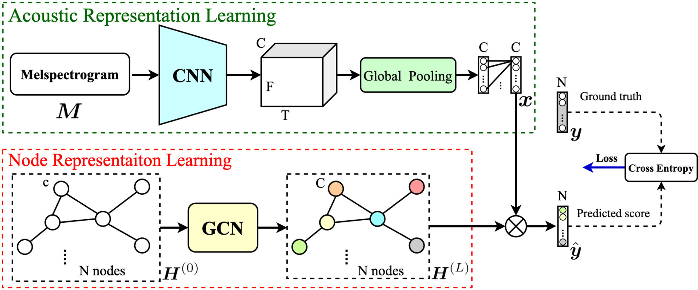
Figure 1 from Modeling Label Dependencies for Audio Tagging With Graph ...
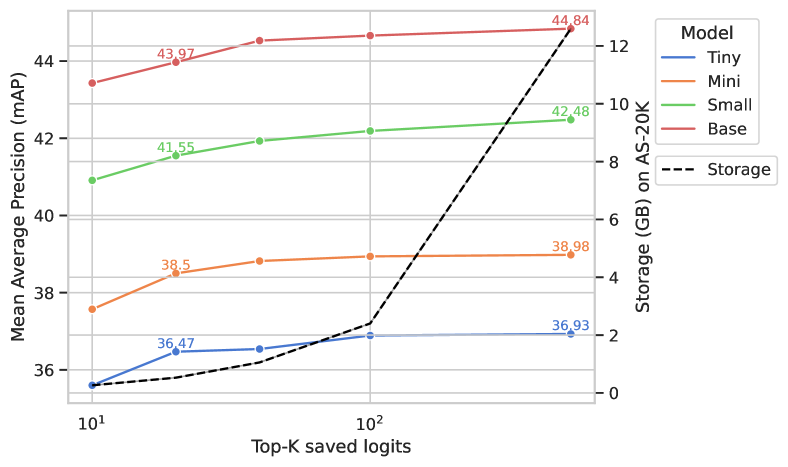
[2308.11957] CED: Consistent ensemble distillation for audio tagging
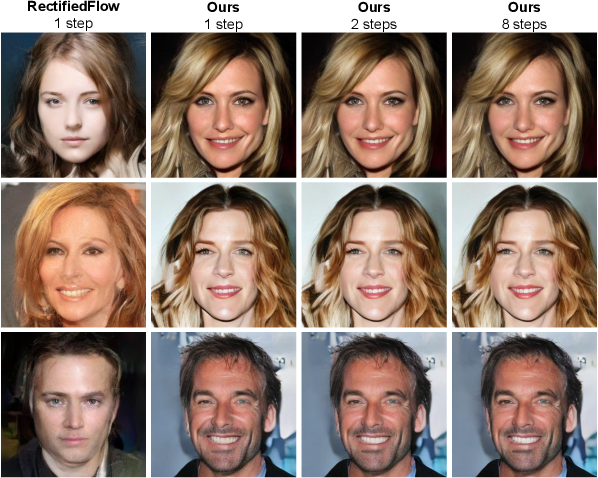
Figure 1 from Self-Corrected Flow Distillation for Consistent One-Step ...
Advertisement Space (300x250)

Figure 1 from Adaptive Ensemble Self-Distillation With Consistent ...

Figure 1 from Knowledge Distillation For CTC-based Speech Recognition ...
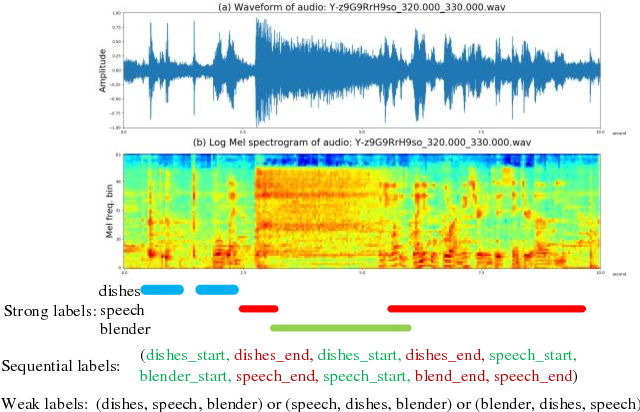
Figure 1 from Polyphonic audio tagging with sequentially labelled data ...

Figure 1 from General-purpose Tagging of Freesound Audio with AudioSet ...

Figure 1 from Knowledge Distillation for Detection Transformer with ...
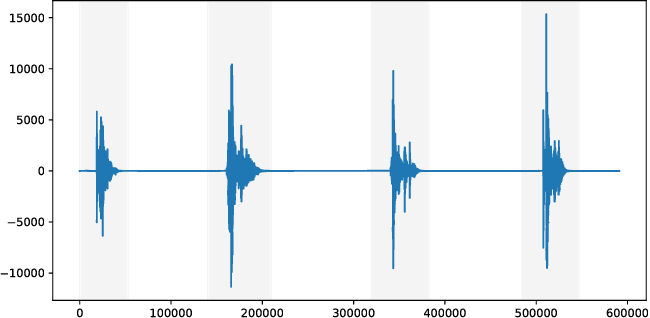
Figure 1 from General-purpose audio tagging from noisy labels using ...

Figure 1 from Knowledge Distillation For CTC-based Speech Recognition ...

Figure 1 from Acoustic Scene Classification Using Audio Tagging ...
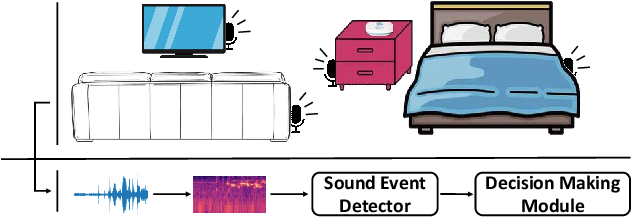
Figure 1 from Enhanced Audio Tagging via Multi- to Single-Modal Teacher ...

Figure 1 from Knowledge Distillation For CTC-based Speech Recognition ...
Advertisement Space (336x280)

Figure 1 from Self-Trained Audio Tagging and Sound Event Detection in ...

Figure 1 from Knowledge Distillation for Detection Transformer with ...
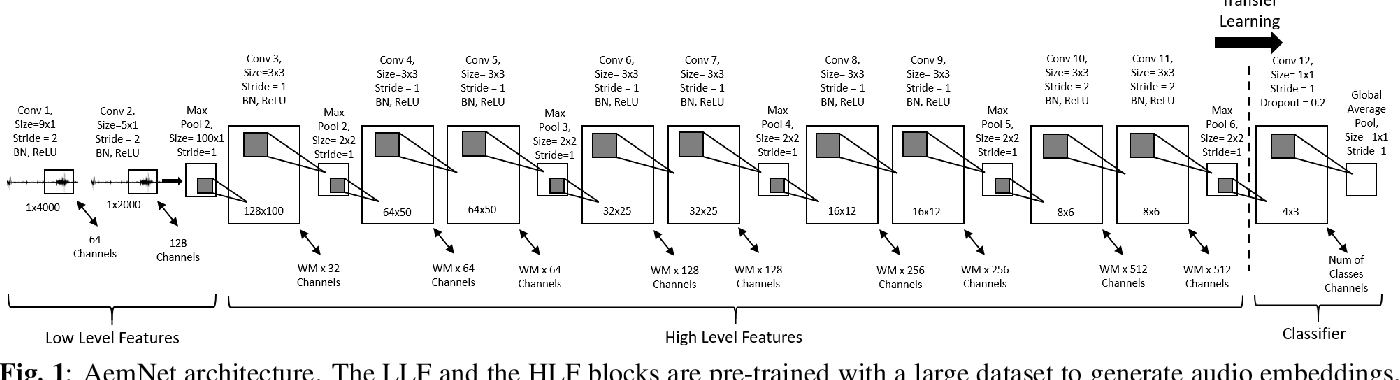
Figure 1 from Efficient End-to-End Audio Embeddings Generation for ...

Figure 1 from Sample mixed-based data augmentation for domestic audio ...

Figure 1 from Knowledge Distillation for Detection Transformer with ...
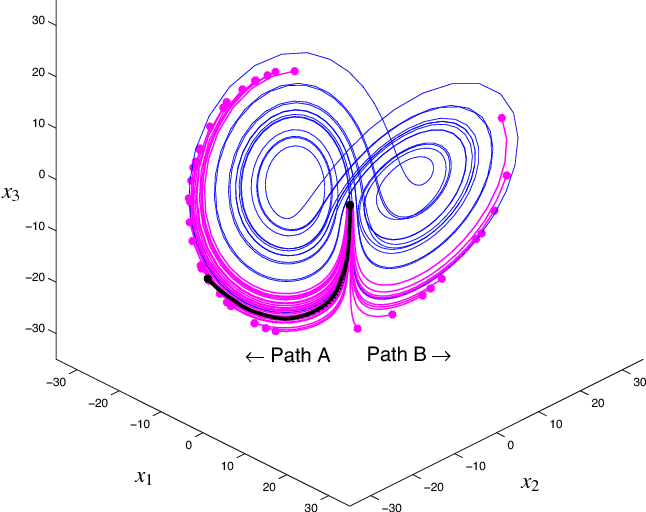
Figure 1 from EnVE : A consistent hybrid ensemble / variational ...

Figure 2 from Collaborative Score Distillation for Consistent Visual ...
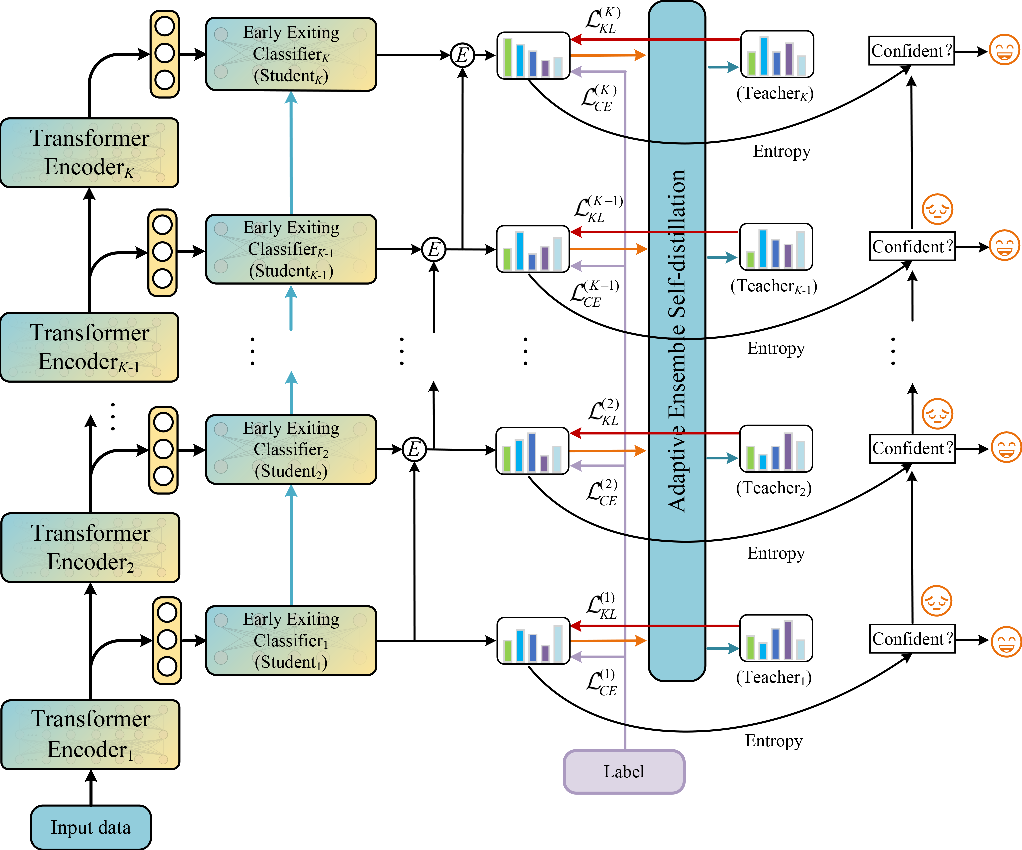
Figure 2 from Adaptive Ensemble Self-Distillation With Consistent ...

Figure 1 from Multilingual Audio Captioning using machine translated ...

Figure 1 from Audio De-identification - a New Entity Recognition Task ...
Advertisement Space (336x280)
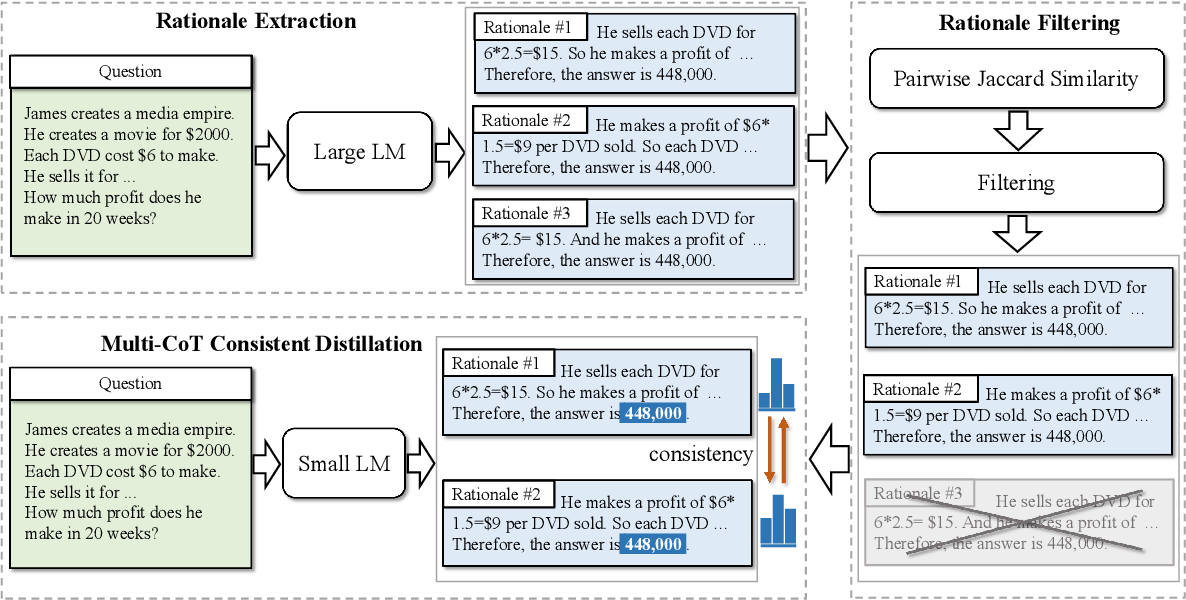
Figure 2 from MCC-KD: Multi-CoT Consistent Knowledge Distillation ...

Figure 10 from Adaptive Ensemble Self-Distillation With Consistent ...
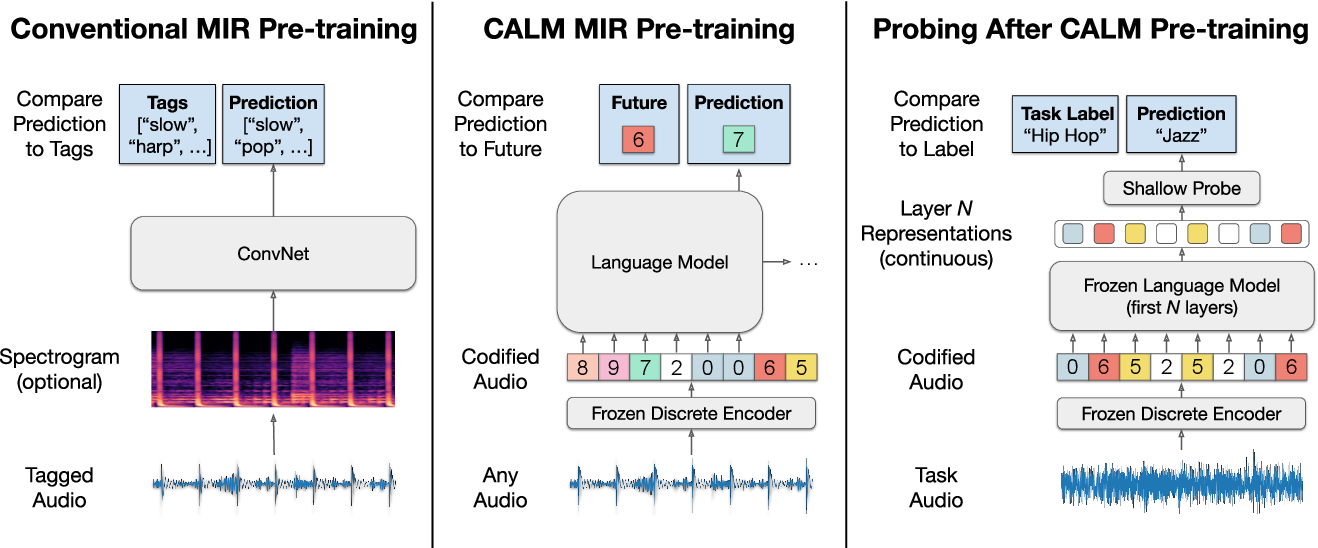
Figure 1 from Codified audio language modeling learns useful ...

Figure 1 from An End-to-End Audio Classification System based on Raw ...

Table 2 from Collaborative Score Distillation for Consistent Visual ...

An Ensemble Approach for Speaker Identification from Audio Files in ...