
Github Gmarscodefuse Codellama 34b
CodeLlama 34B errors out after 3+ completions · Issue #70 · casper ...
GitHub - yachty66/demo-codellama-34b-instruct-gptq: This is a CodeLlama ...
CodeLlama 34B Python GGUF by TheBloke — VRAM 14.2GB | LLM Explorer
Codellama 34B Instruct Hf - Specs, Capabilities & Benchmarks | Inferbase
CodeLlama 34B Instruct Hf by codellama — VRAM 67.5GB, 16K context | LLM ...
[Bug] Codellama 34B cannot handle inputs > 4k tokens despite context ...
CodeLlama 34B | Open Laboratory
GitHub - meta-llama/codellama: Inference code for CodeLlama models

Codellama CodeLlama 34b Instruct Hf - a Hugging Face Space by pnavin
CodeLlama 34B | Open Laboratory
Advertisement Space (300x250)
CodeLlama 34B v2 - API Pricing & Providers | OpenRouter
CodeFuse CodeLlama 34B AWQ by TheBloke — VRAM 18.3GB, 16K context | LLM ...
Codellama Codellama 34B HF Q8: Needs 34GB VRAM — Requirements
Phind Phind CodeLlama 34B V1 - a Hugging Face Space by edensheiko
Quantize script not working for CodeLlama 34B · Issue #239 · NVIDIA ...
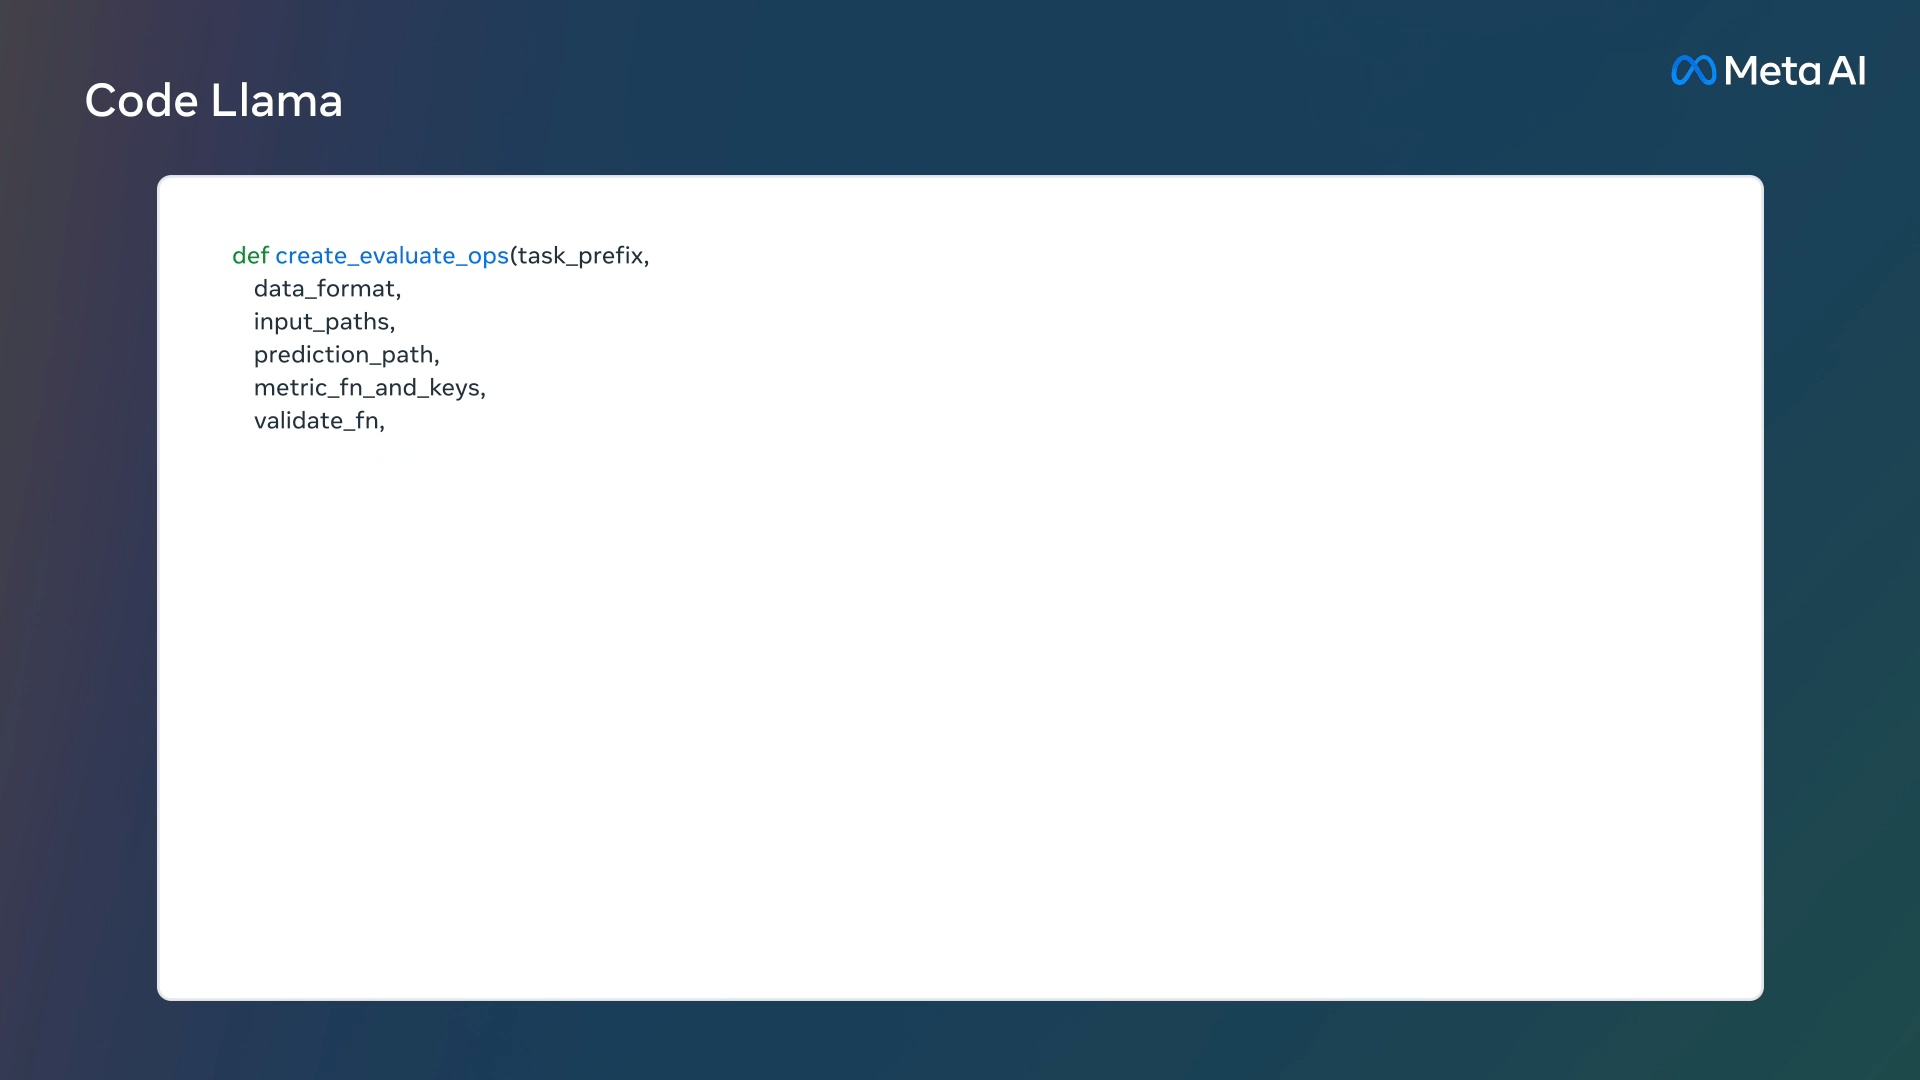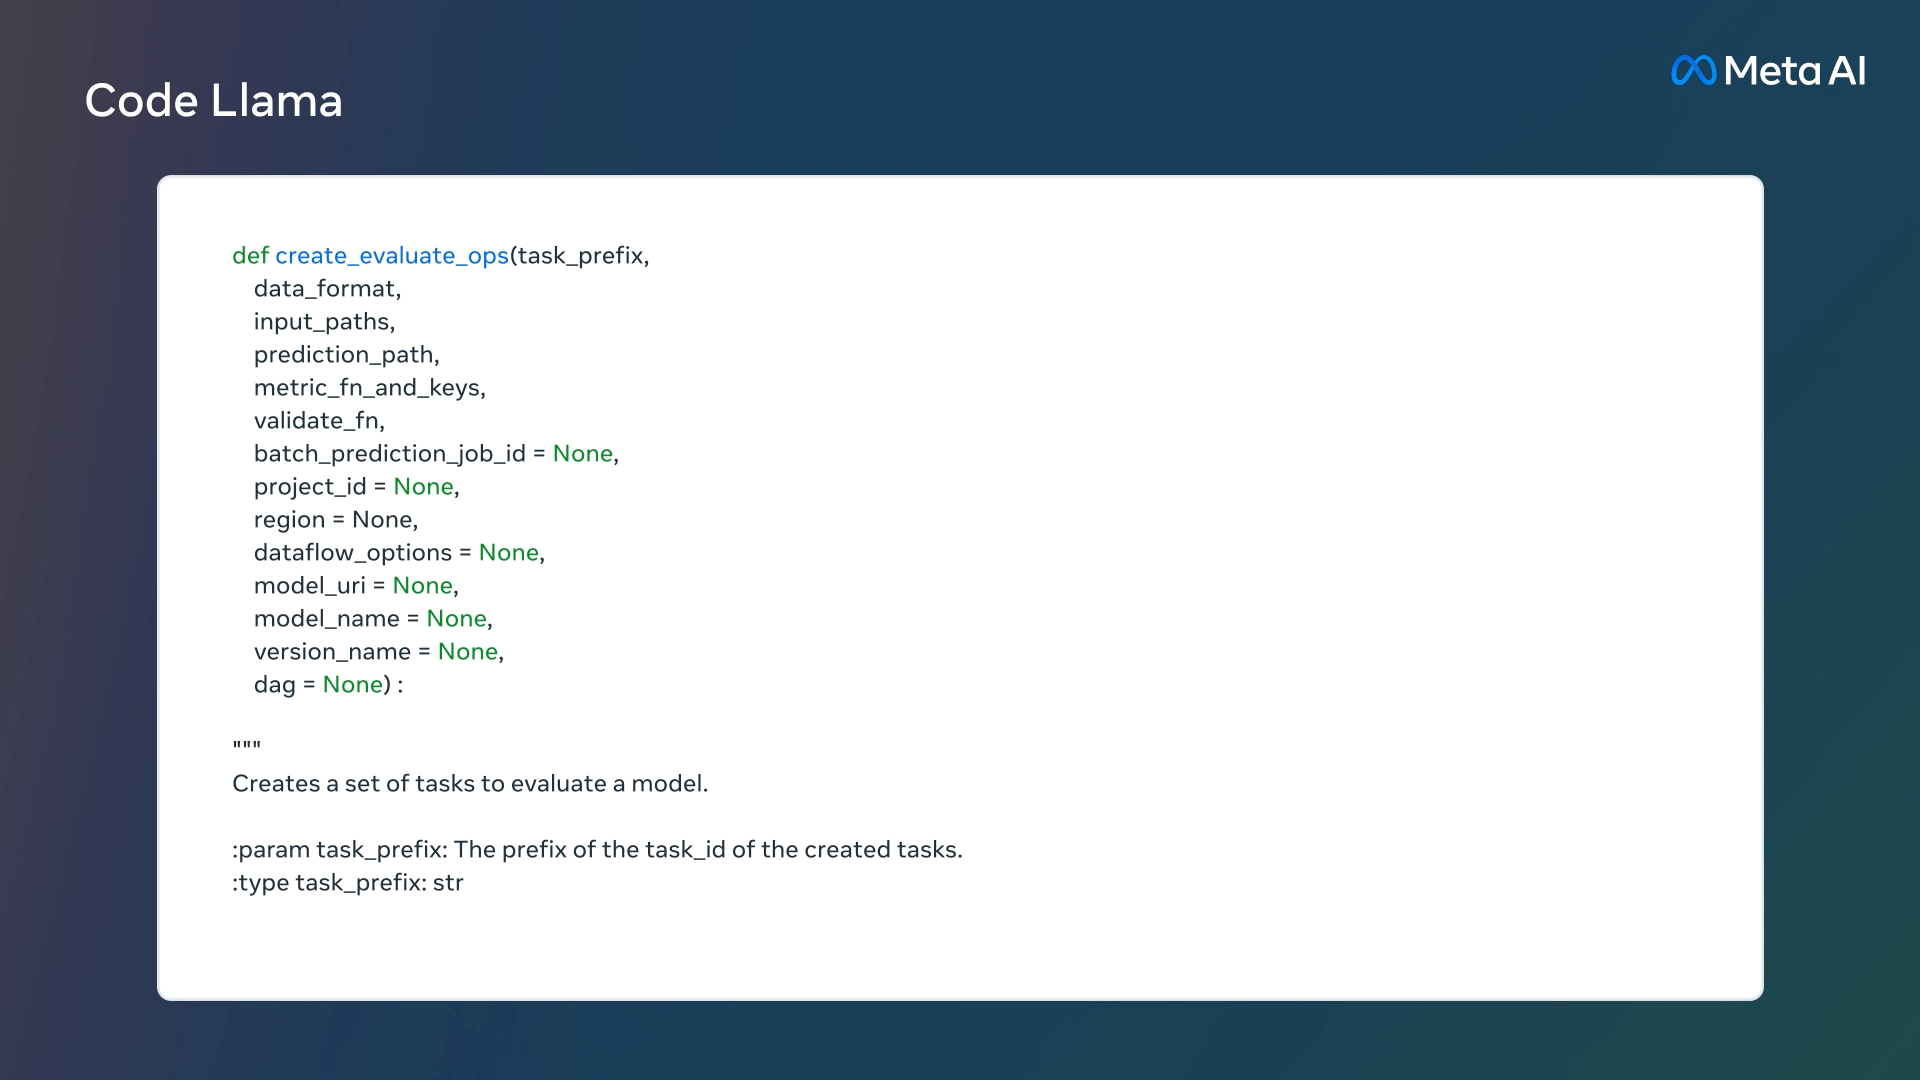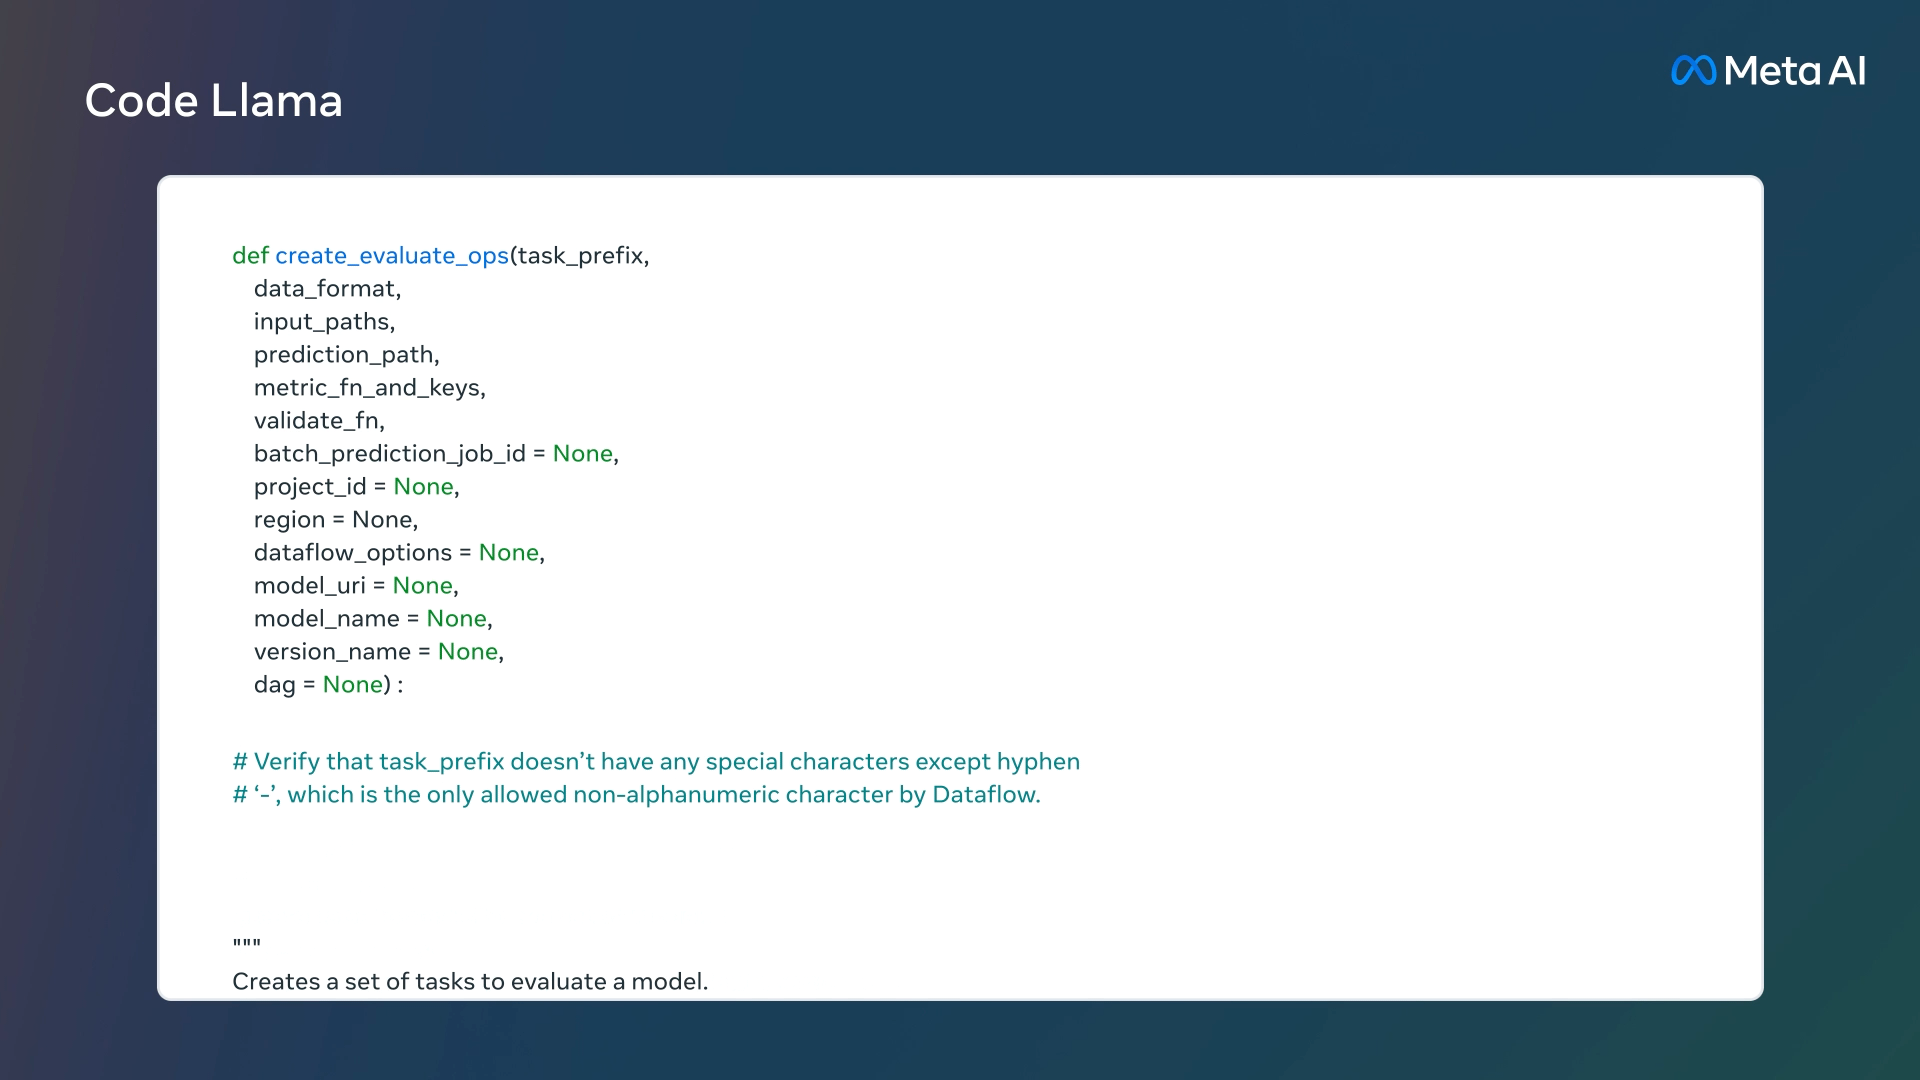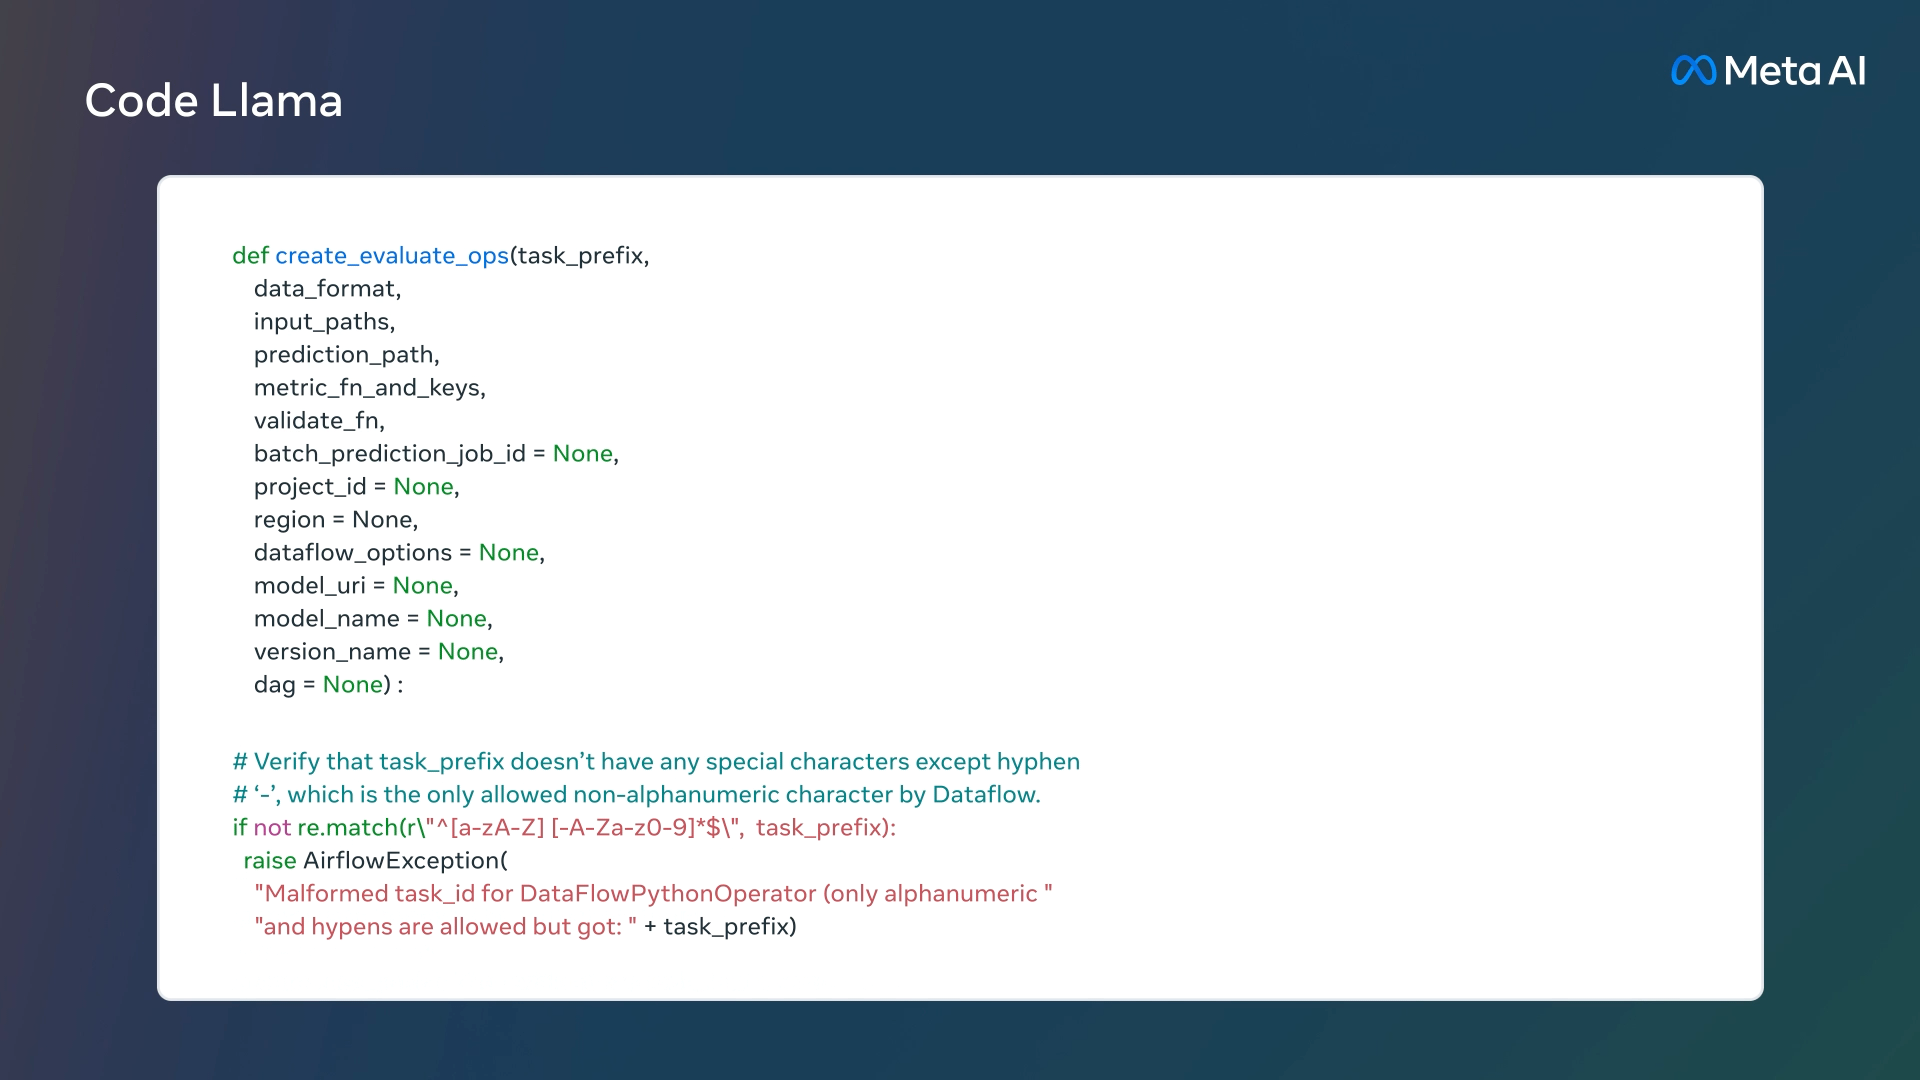
CodeLlama 34B | Open Laboratory
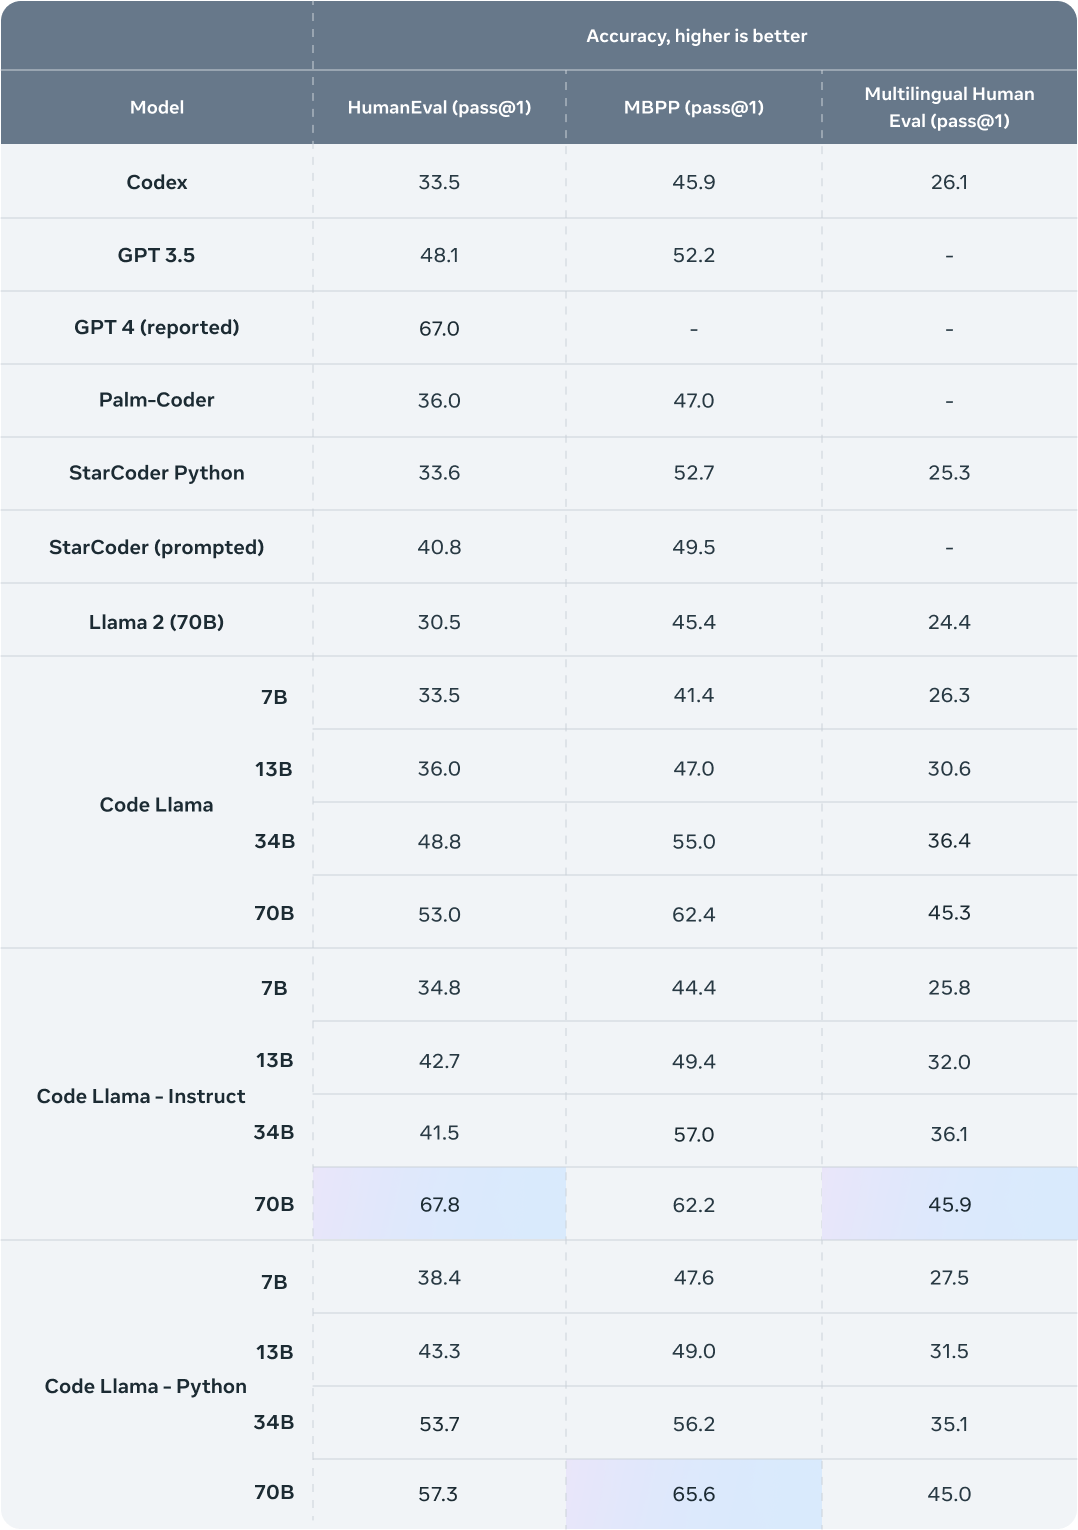
CodeLlama 34B | Open Laboratory
Togethercomputer Codellama 34B Instruct pricing — Together AI | Future AGI

Codellama CodeLlama 34b Python Hf - a Hugging Face Space by PythonAtSea

Meta Llama CodeLlama 34b Instruct Hf - a Hugging Face Space by romannai
Advertisement Space (336x280)
GitHub - gmars/CodeFuse-CodeLlama-34B
Code Llama 34B GGUF produces garbage after a certain point · Issue #121 ...
CodeLlama 34B: 48.8% HumanEval, 20GB VRAM (Q4), Ollama

[D] Insights from Deploying CodeLlama 34Bn Model with Multiple ...
请问支持CodeLlama-34b吗? · Issue #2048 · hiyouga/LLaMA-Factory · GitHub

Code Llama 34B model with Inference and HuggingChat | Local Setup Guide ...
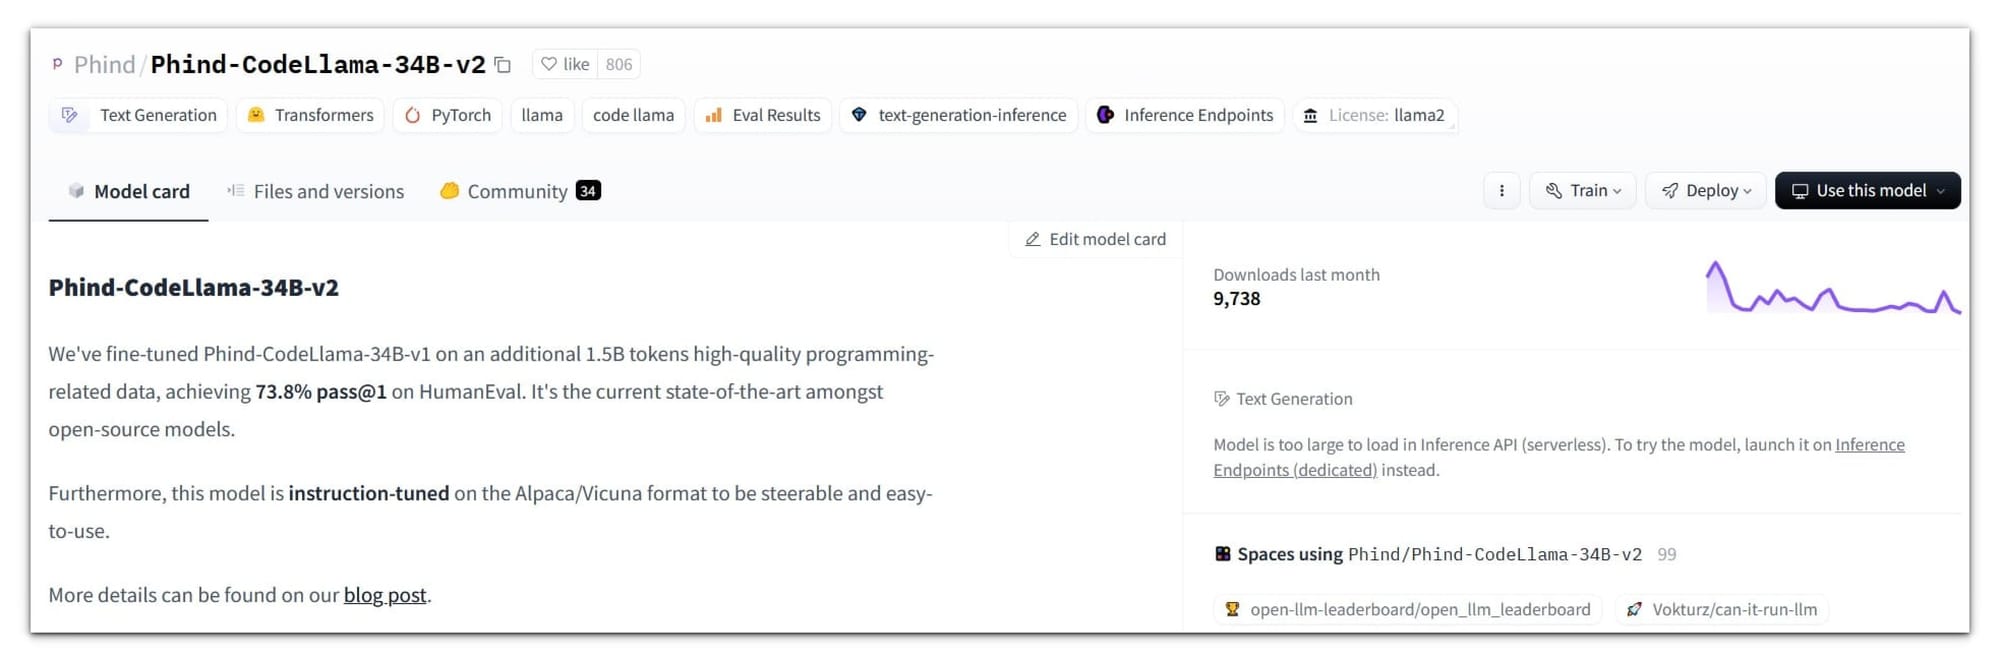
GitHub Copilot Alternatives: Best Open Source LLMs for Coding
GitHub - sadkowsk/codellama-Aug.2023: Learn about "Code Llama: Open ...
Releases · openpilot-hub/codellama-deploy · GitHub
GitHub - inferless/Codellama-7B: Code Llama is a collection of ...
Advertisement Space (336x280)
Code Llama 34B Instruct pricing & specs — Meta | CloudPrice
How to design a prompt using Codellama for code completion? · Issue ...
Does codellama 13B/34B/70B support function calling and Lora fine ...
GitHub - fiddlecube/llama-finetuning: Guide for fine-tuning Llama ...
Tactic running out of memory during Code Llama 34B build · Issue #29 ...
GitHub - 1rgs/copilot: Guide for fine-tuning Llama/CodeLlama models ...