
Int8 Nvidia Tensorrt
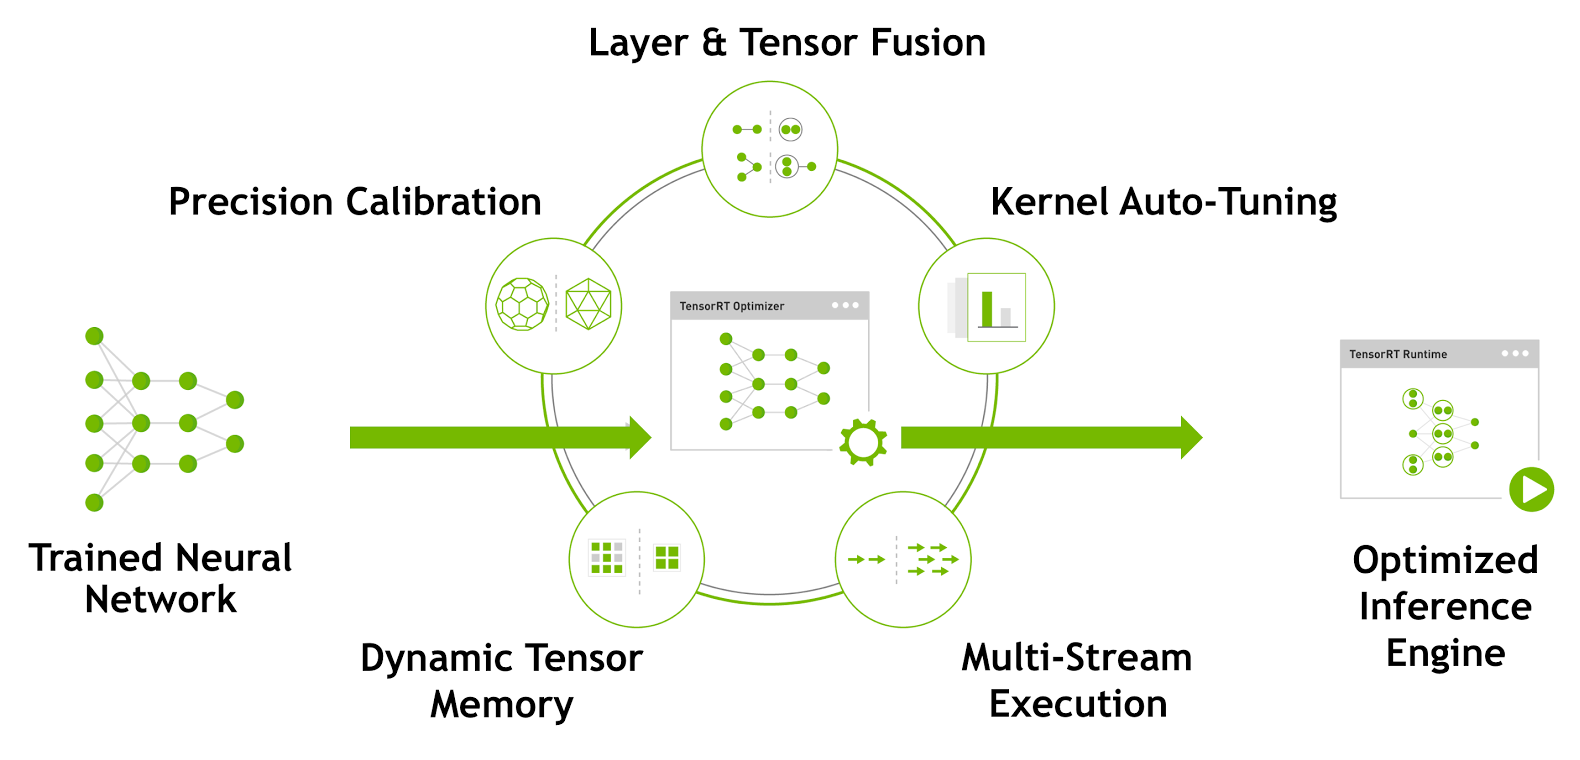
Fast INT8 Inference for Autonomous Vehicles with TensorRT 3 | NVIDIA ...
TensorRT 8.6.1.6 can't build engine with INT8 ONNX on NVIDIA GeForce ...

TensorRT Q/DQ: how to keep Gather in INT8 - TensorRT - NVIDIA Developer ...
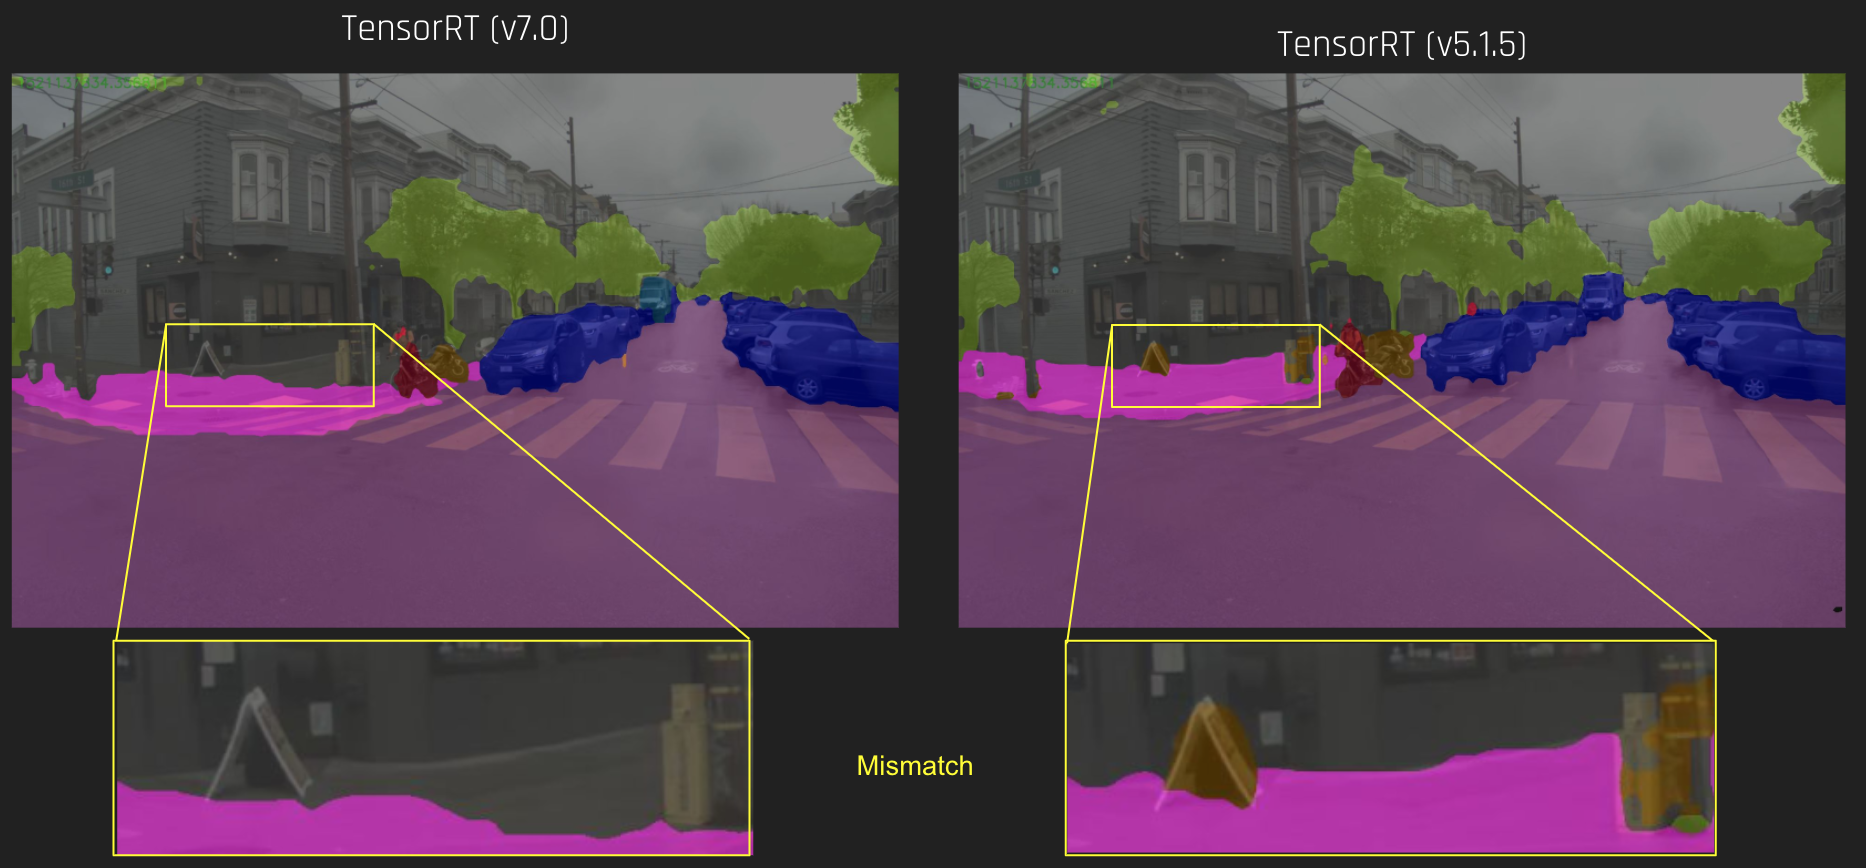
Fast INT8 Inference for Autonomous Vehicles with TensorRT 3 | NVIDIA ...

TensorRT 5 Int8 Calibration Example - TensorRT - NVIDIA Developer Forums
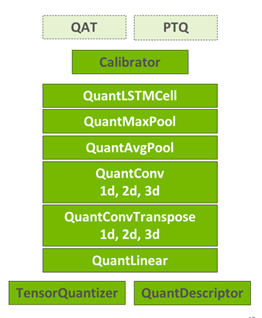
利用 NVIDIA TensorRT 量化感知训练实现 INT8 推理的 FP32 精度 - NVIDIA 技术博客

TensorRT Q/DQ: how to keep Gather in INT8 - TensorRT - NVIDIA Developer ...

Model does not get Int8 layers - TensorRT - NVIDIA Developer Forums

TensorRT INT8 engine calibration cache - TensorRT - NVIDIA Developer Forums

7. TensorRT 中的 INT8 - NVIDIA 技术博客
Advertisement Space (300x250)
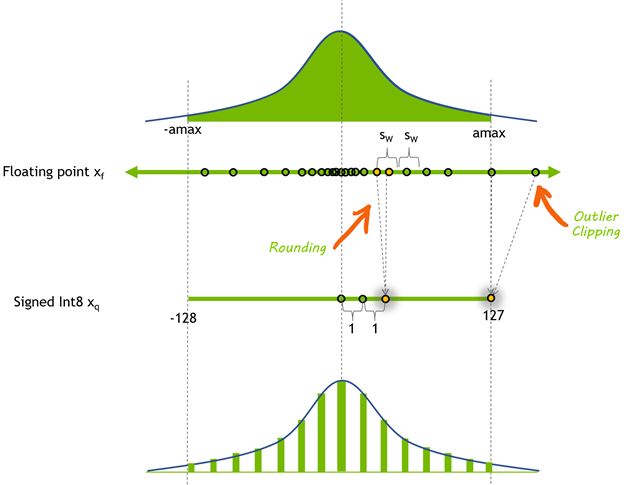
利用 NVIDIA TensorRT 量化感知训练实现 INT8 推理的 FP32 精度 - NVIDIA 技术博客

DCNV2 plugin tensorrt 8.5 arm int8 convert error · Issue #2698 · NVIDIA ...

Any guide to support int8 group_conv - TensorRT - NVIDIA Developer Forums
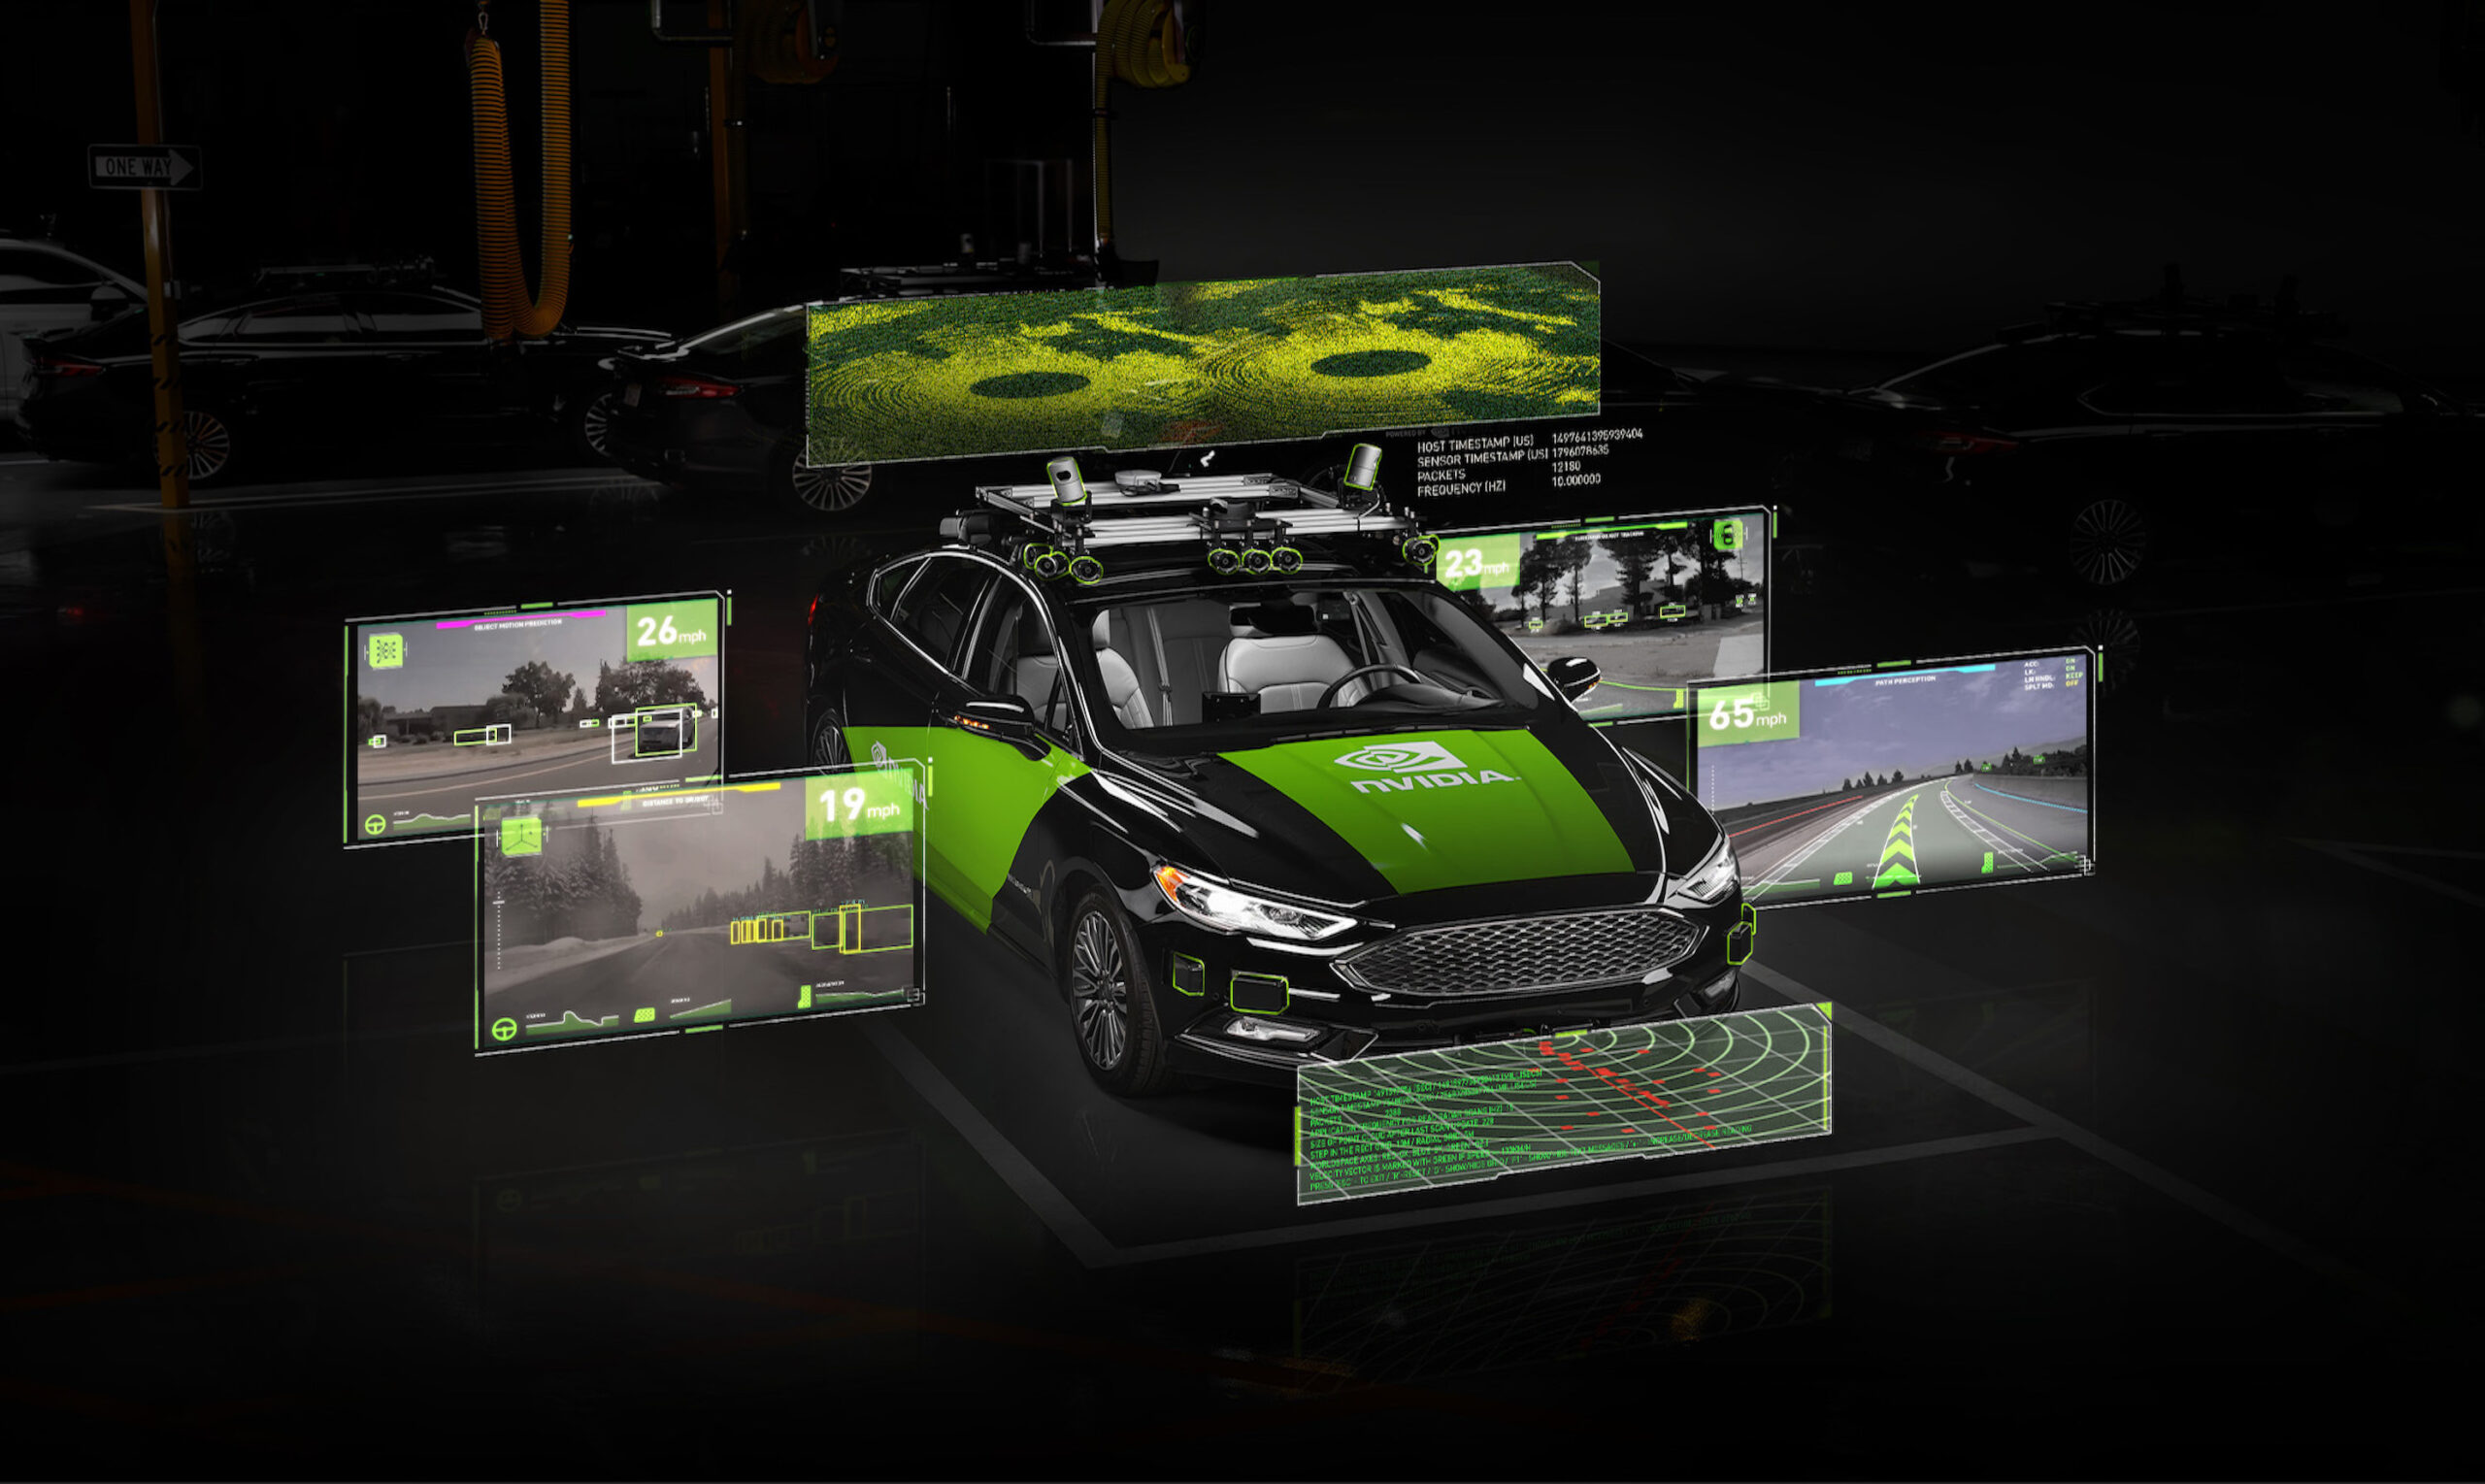
Fast INT8 Inference for Autonomous Vehicles with TensorRT 3 | NVIDIA ...
will input be quantified in tensorrt int8 mode · Issue #2927 · NVIDIA ...
TensorRT 5 INT8 calibration sample failing · Issue #389 · NVIDIA ...

Quantization to int8 still confusing - TensorRT - NVIDIA Developer Forums

NVIDIA TensorRT INT8 & FP8 quantization accelerating SD inference : r ...
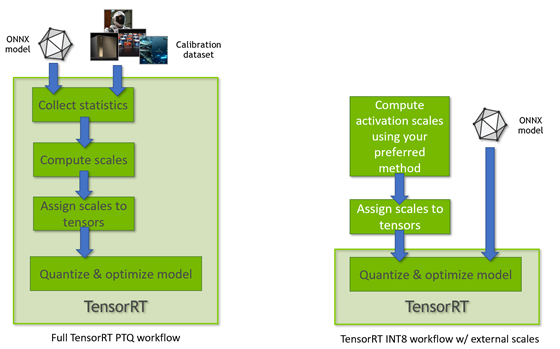
NVIDIA TensorRT를 통한 양자화 인식 학습을 사용하여 INT8 추론에 대한 FP32 정확도 달성 - NVIDIA ...
TensorRT Quantization: NVIDIA's INT8 Inference SDK | Inference Systems
Advertisement Space (336x280)

Nvidia анонсирует TensorRT 8, сокращающий время вывода BERT до миллисекунды
How does TensorRT implements the `Add` in INT8 mode ? · Issue #1144 ...

NVIDIA TensorRT Accelerates Stable Diffusion Nearly 2x Faster with 8 ...

NVIDIA Announces TensorRT 8.2 and Integrations with PyTorch and ...

NVIDIA TensorRT Accelerates Stable Diffusion Nearly 2x Faster with 8 ...

Accelerate Generative AI Inference Performance with NVIDIA TensorRT ...

NVIDIA TensorRT 8.5.10 Developer Guide for DRIVE OS :: NVIDIA TensorRT ...

NVIDIA Announces TensorRT 8 Slashing BERT-Large Inference Down to 1 ...
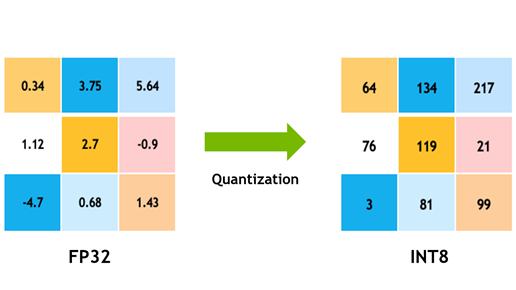
NVIDIA TensorRT를 통한 양자화 인식 학습을 사용하여 INT8 추론에 대한 FP32 정확도 달성 - NVIDIA ...
NVIDIA TensorRT - NVIDIA Docs
Advertisement Space (336x280)

TensorRT-LLM 低精度推理优化:从速度和精度角度的 FP8 vs INT8 的全面解析 - NVIDIA 技术博客

Excuse me, does the 3060Ti graphics card support TensorRT int8 ...

8-bit Inference with TensorRT - NVIDIA / 8-bit-inference-with-tensorrt ...

TensorRT-LLM 低精度推理优化:从速度和精度角度的 FP8 vs INT8 的全面解析 - NVIDIA 技术博客
Unable to convert an onnx model to tensorrt using int8 with calibration ...
TensorRT Deconvolution in INT8 mode gives obviously wrong result ...