
Masked Self Attention Matrix Source Https Yeonwoosung Github Io Posts
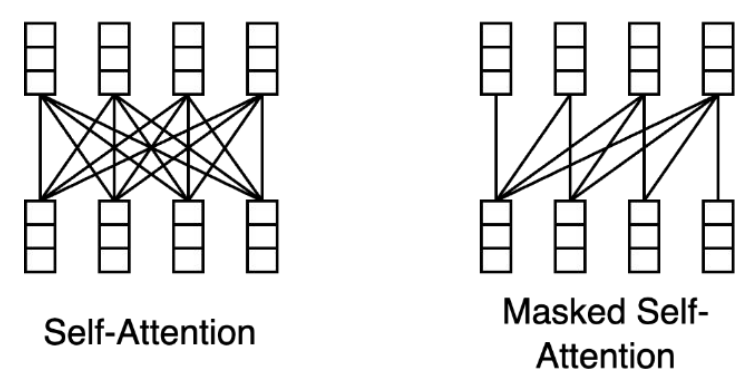
masked self attention matrix source https yeonwoosung github io posts

Masked Self Attention | Masked Multi-head Attention in Transformer ...
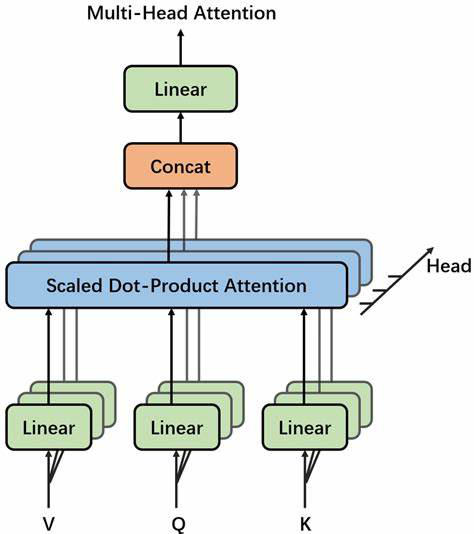
multi head attention diagram source https www vrogue co post
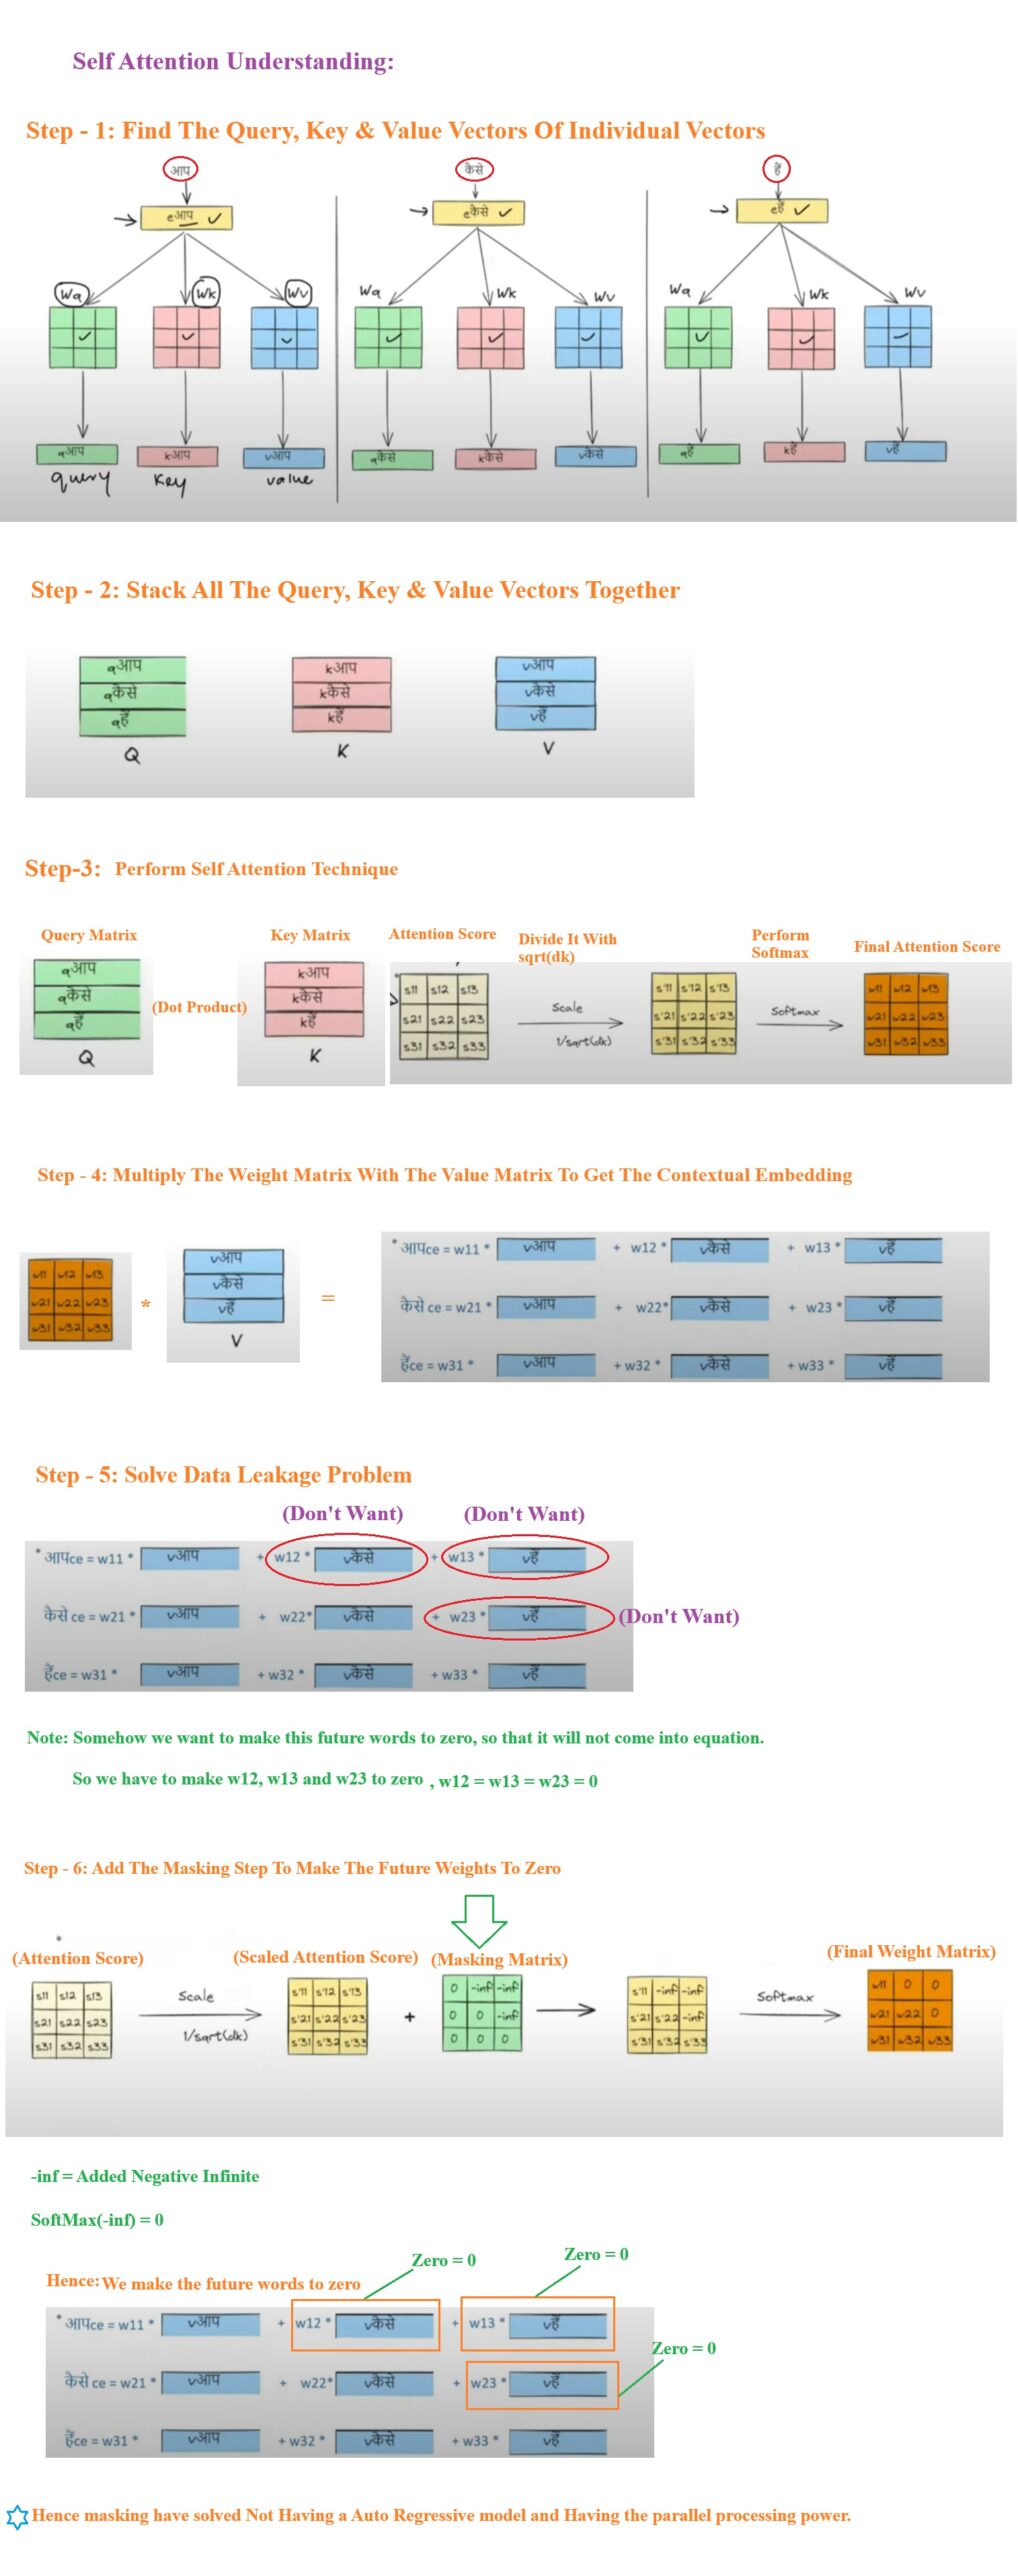
Transformer – Masked Self Attention – Praudyog
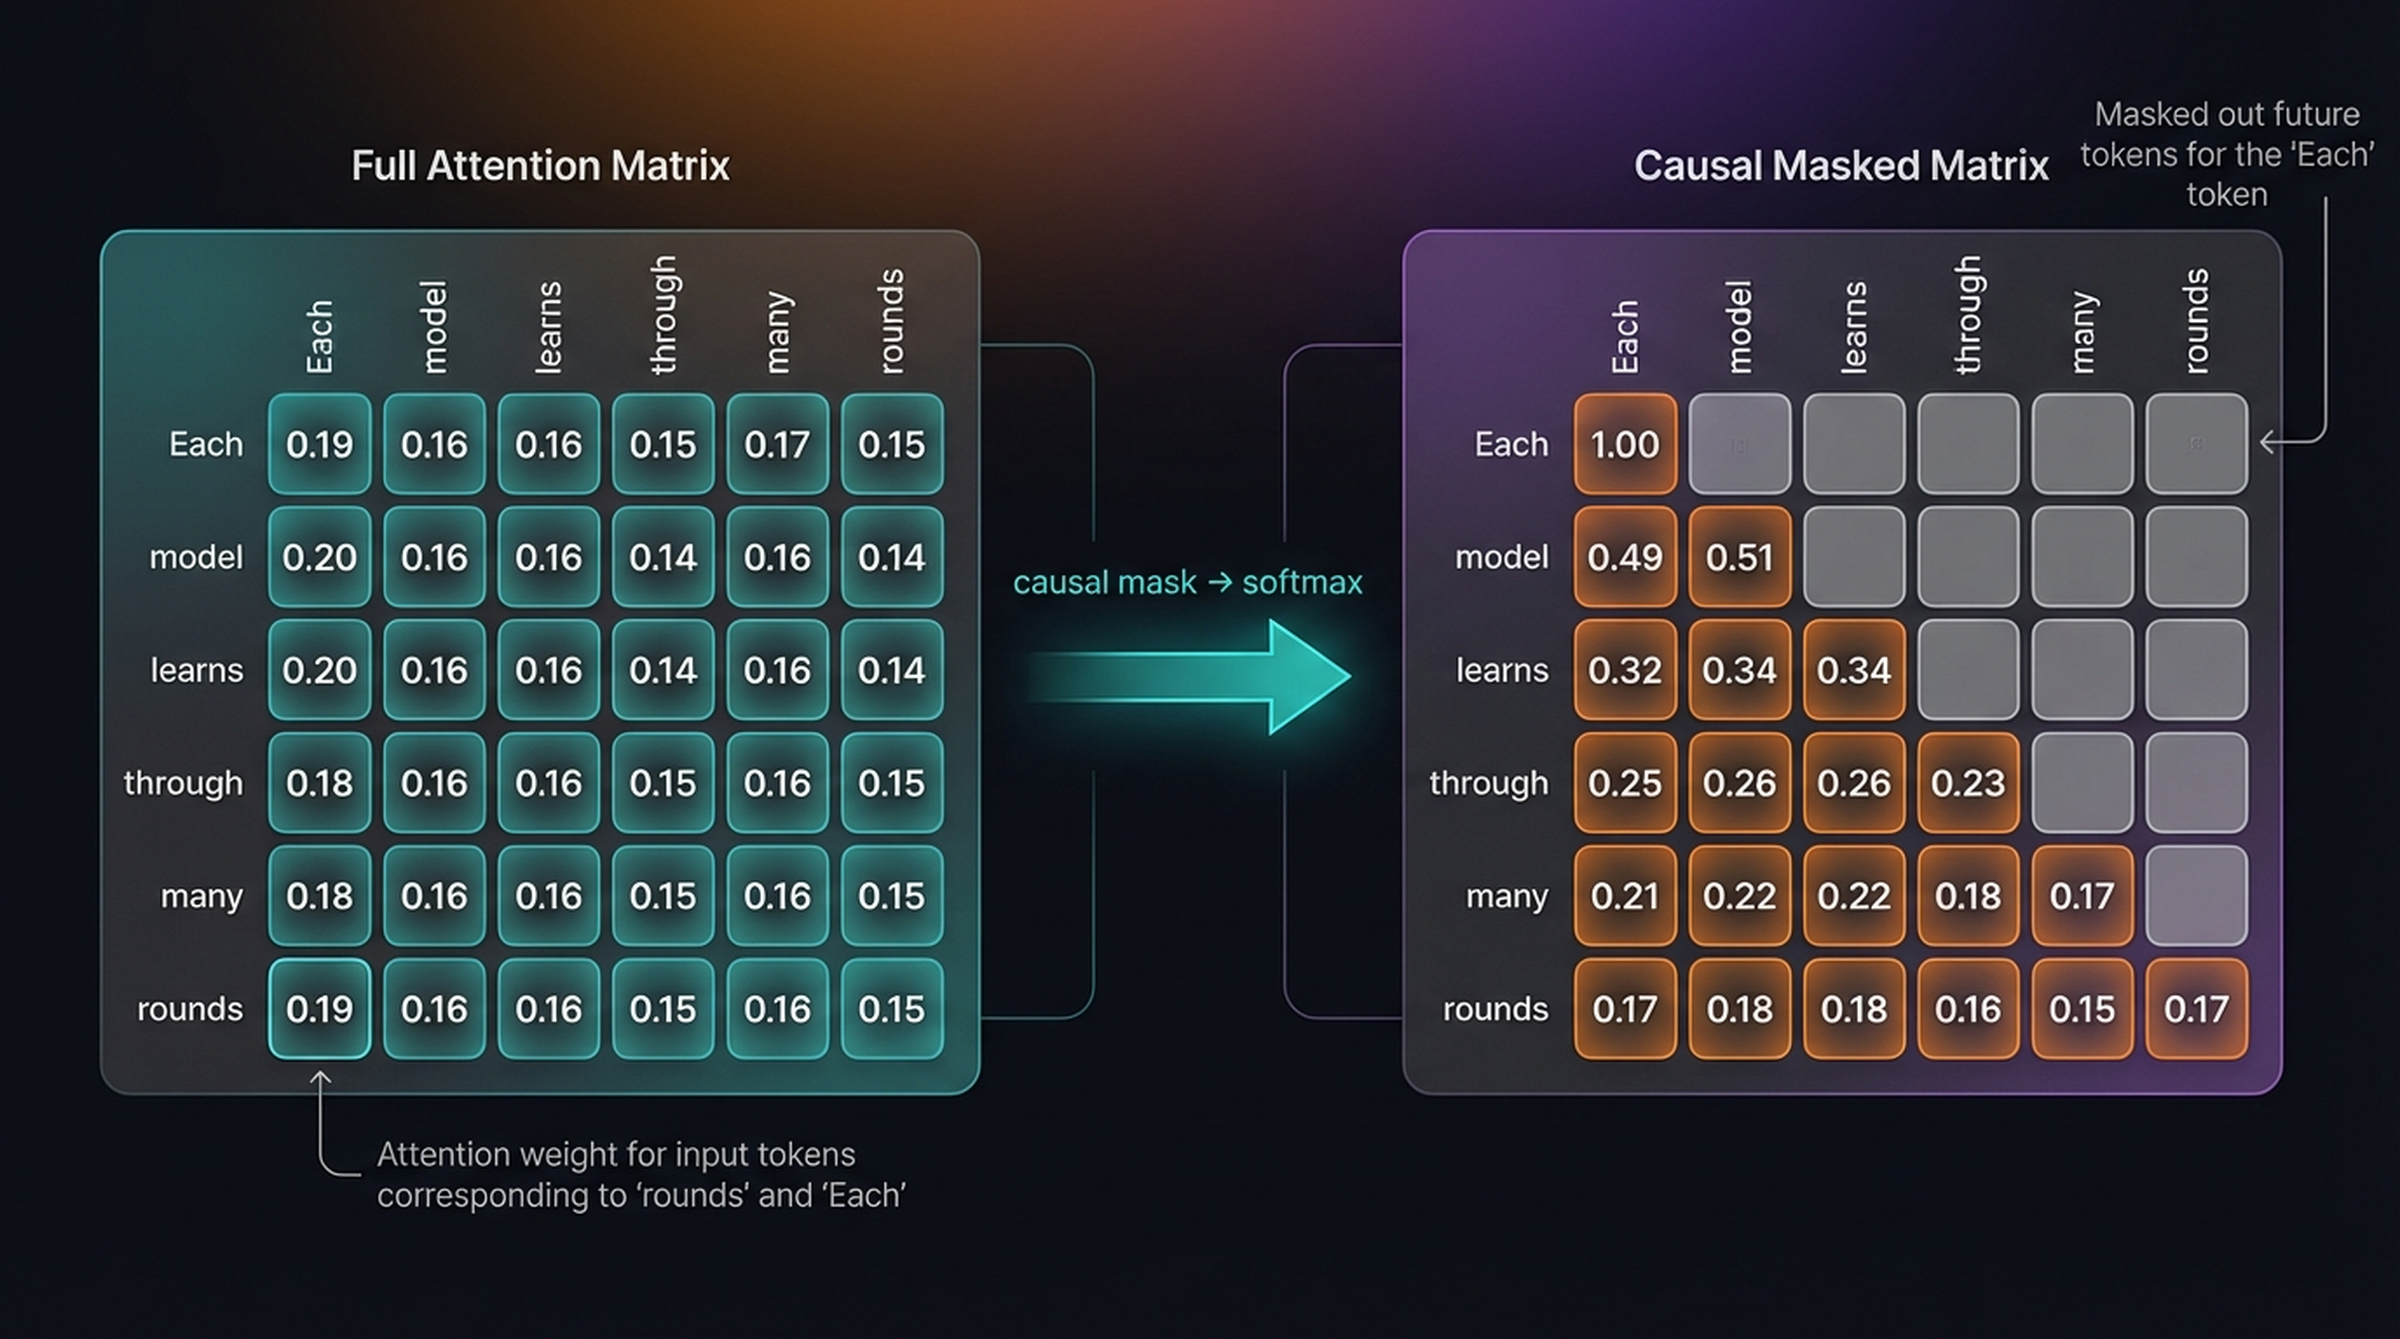
LLM_log #005: Implementing Attention Mechanisms — From Simplified Self ...
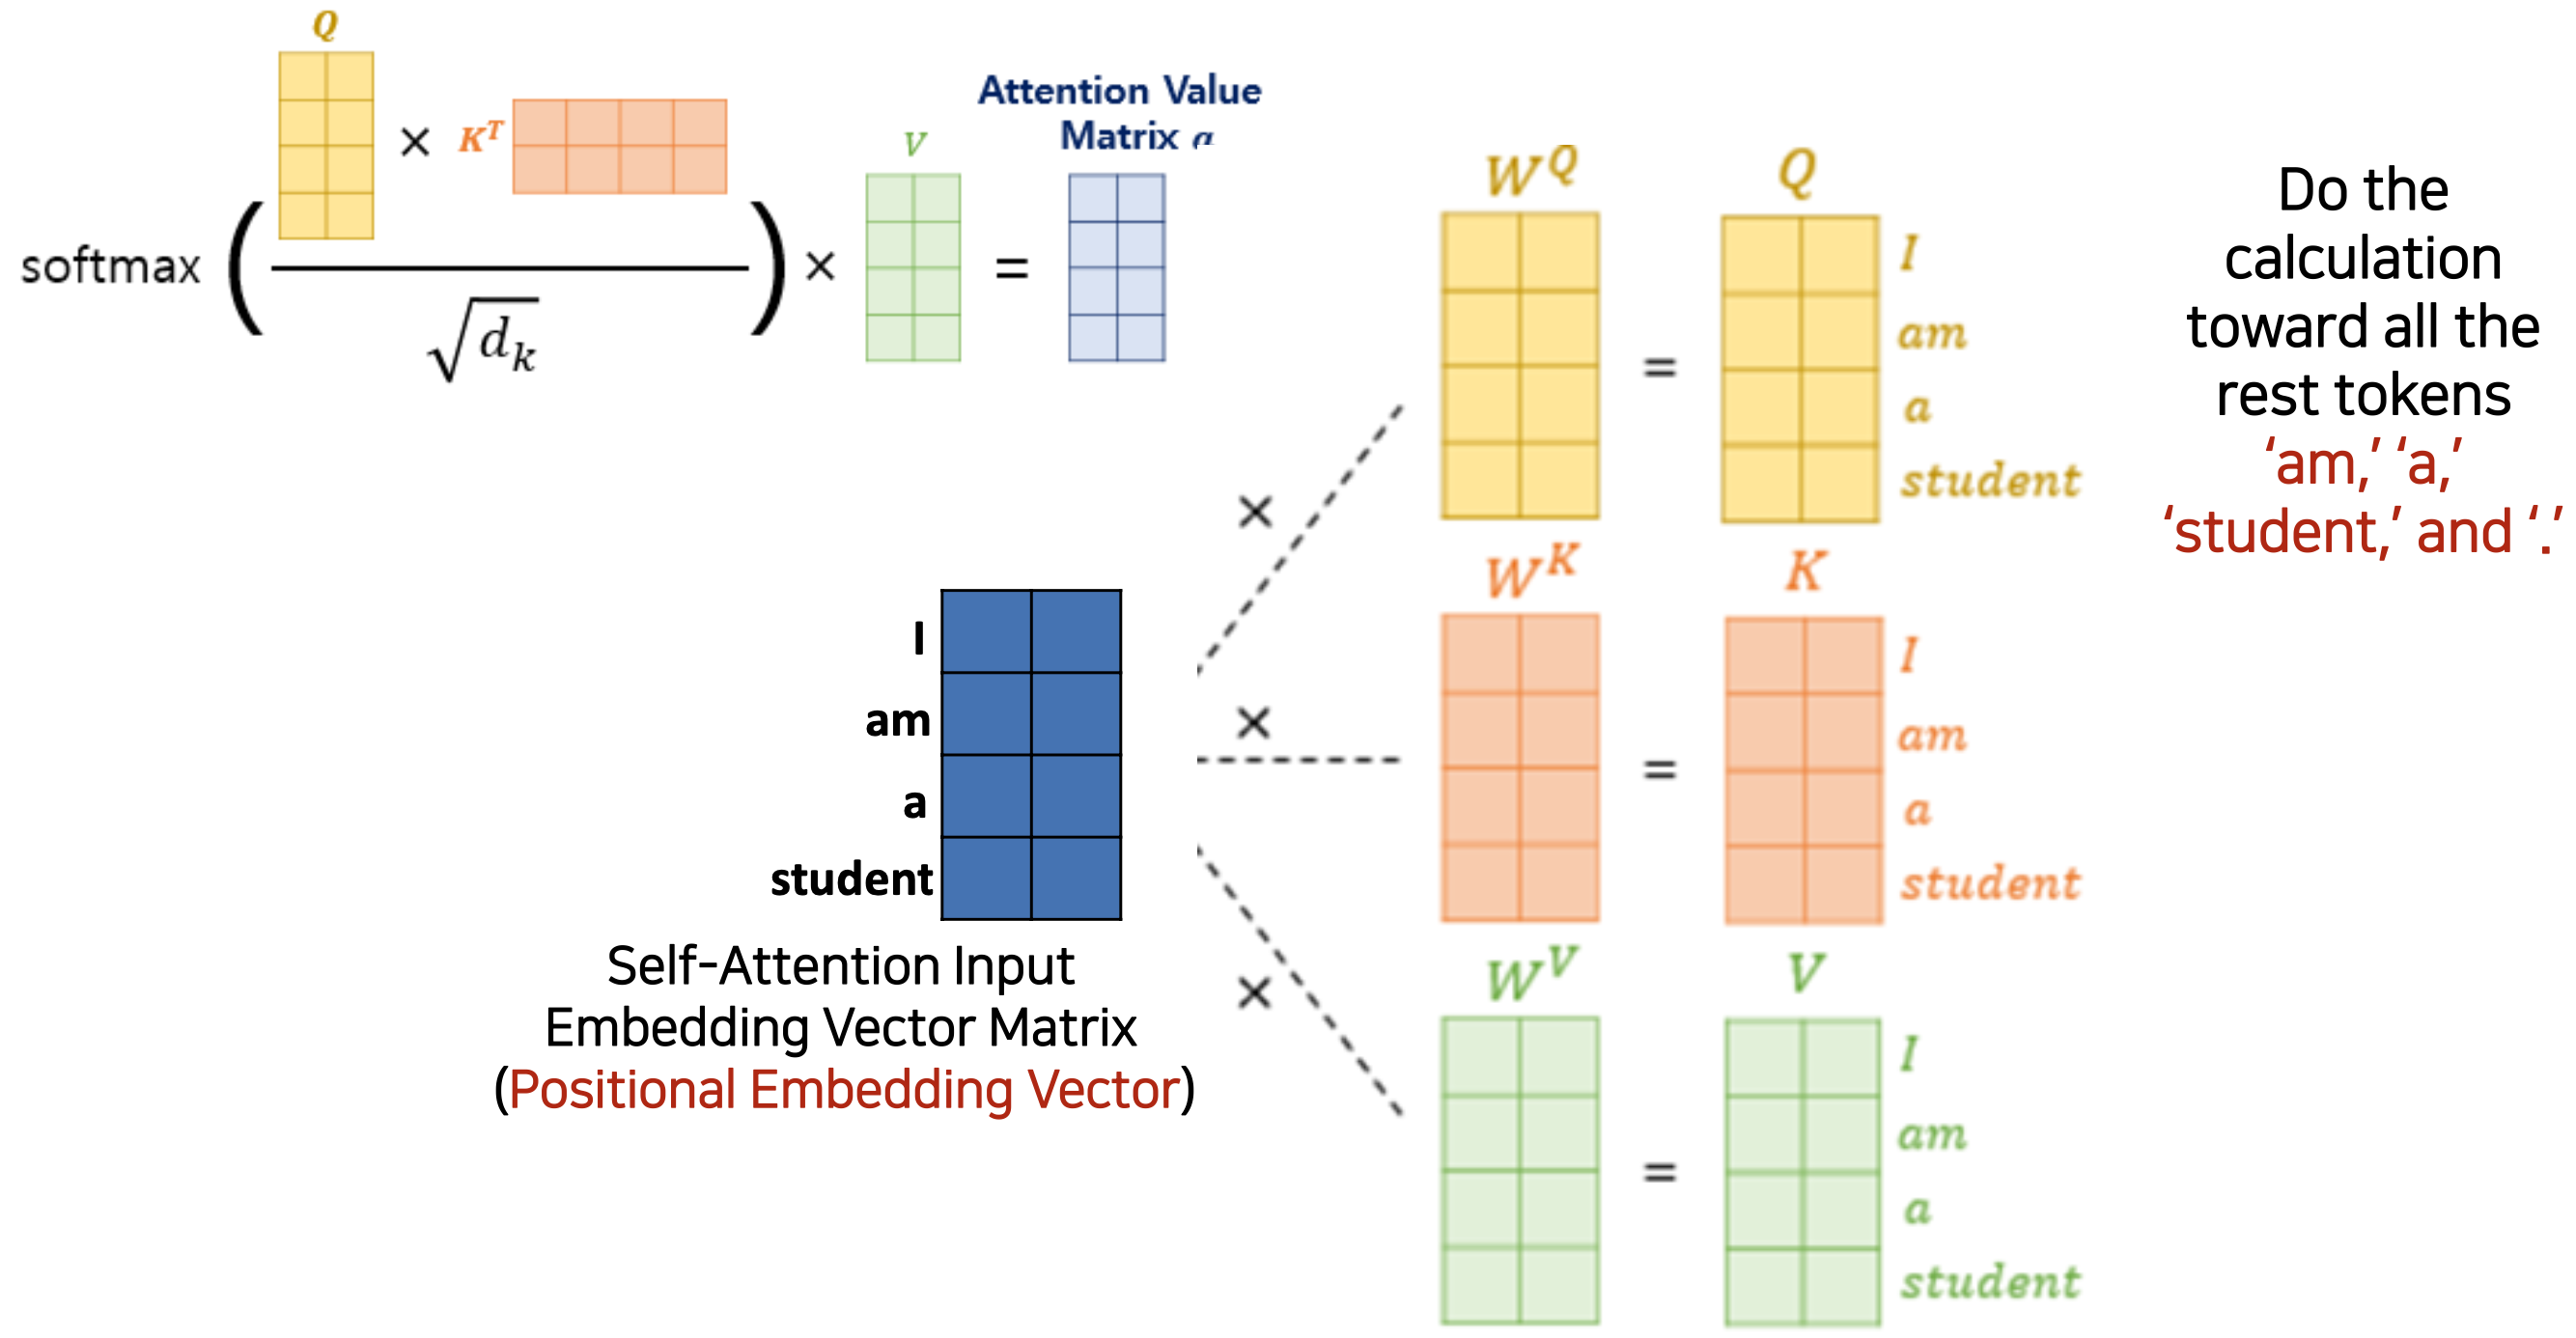
Chapter 4. Attention Value Matrix in Transformer
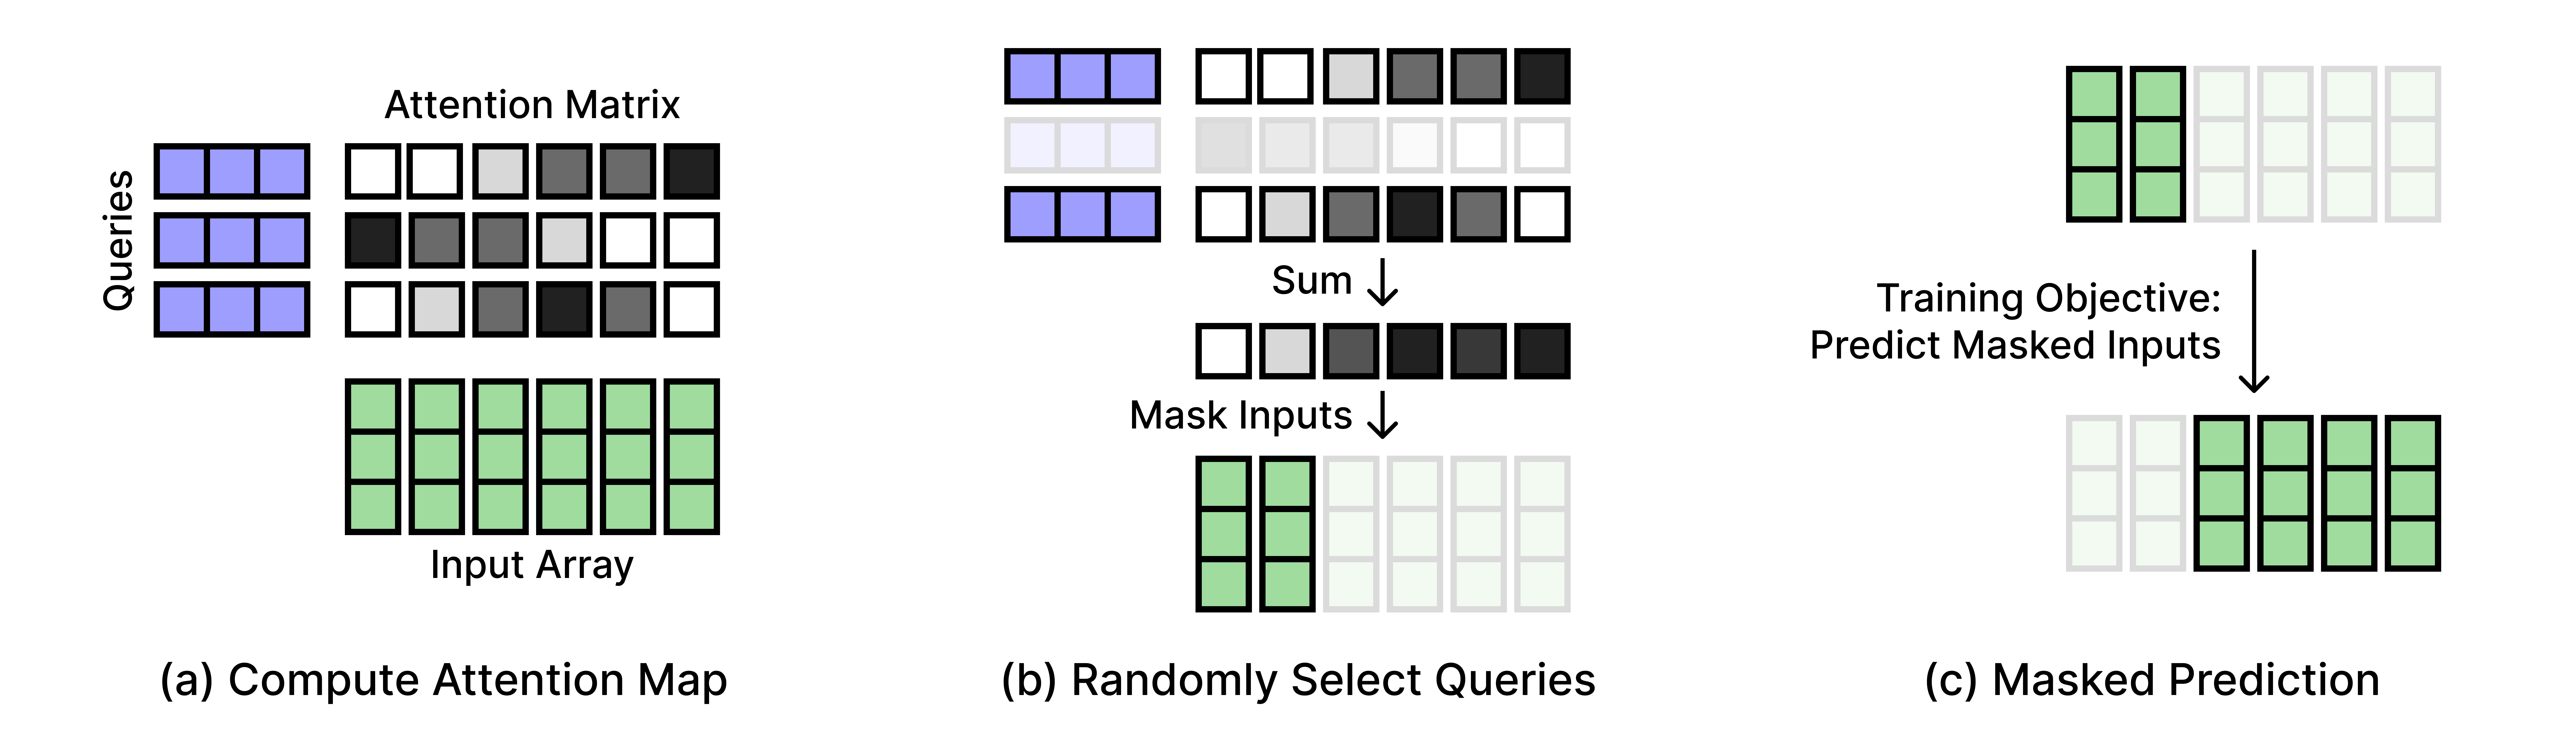
[2402.14789] Self-Guided Masked Autoencoders for Domain-Agnostic Self ...
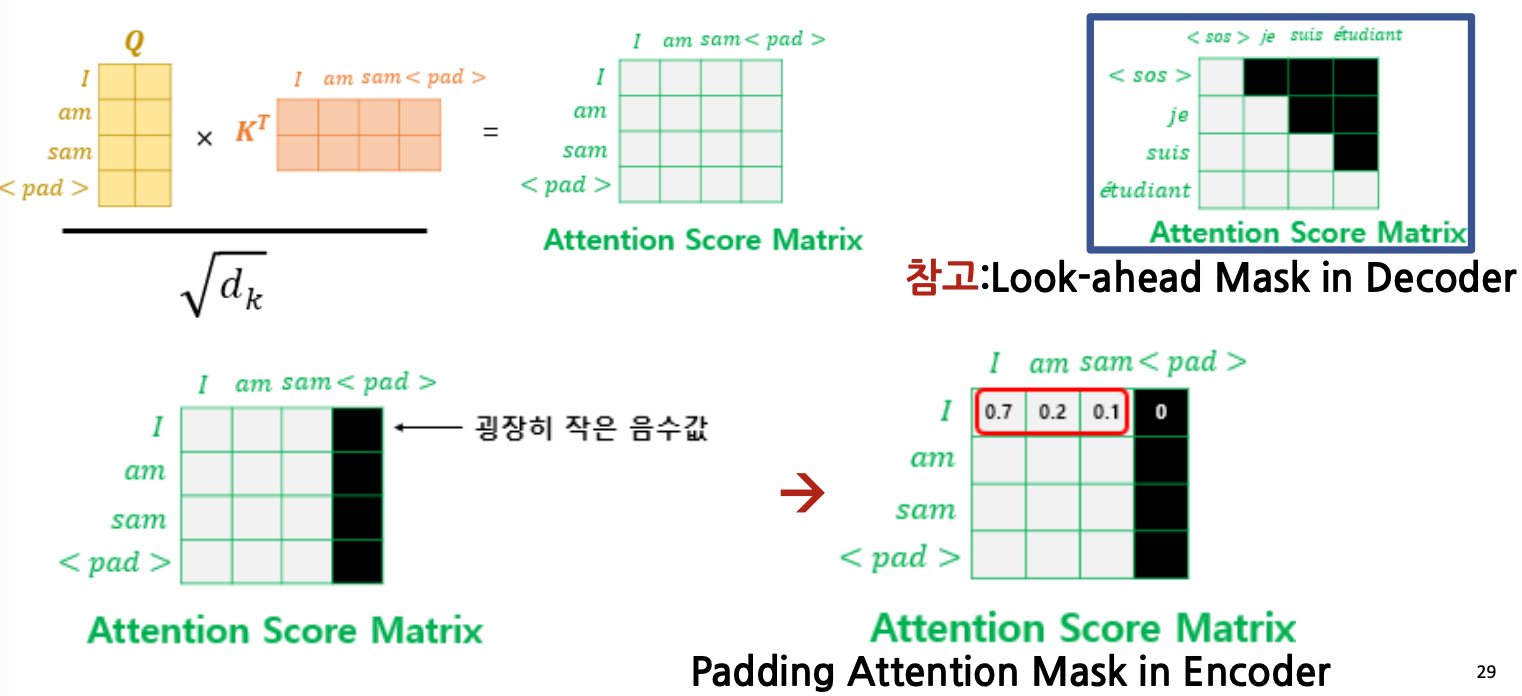
Chapter 4. Attention Value Matrix in Transformer
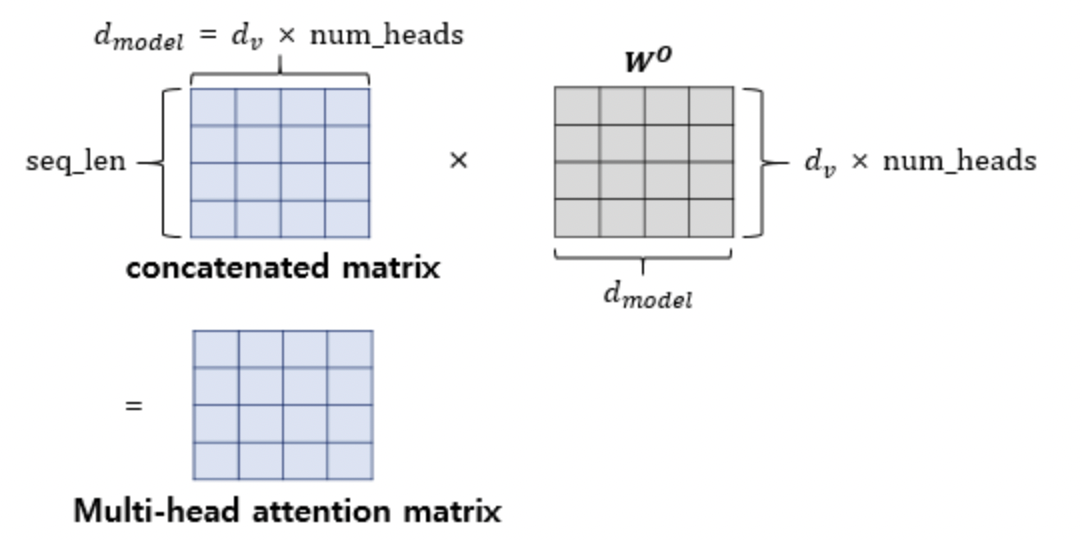
Transformer 논문 리뷰 전 프리뷰1(Attention의 흐름과 Self Attention, Masked Decoder ...
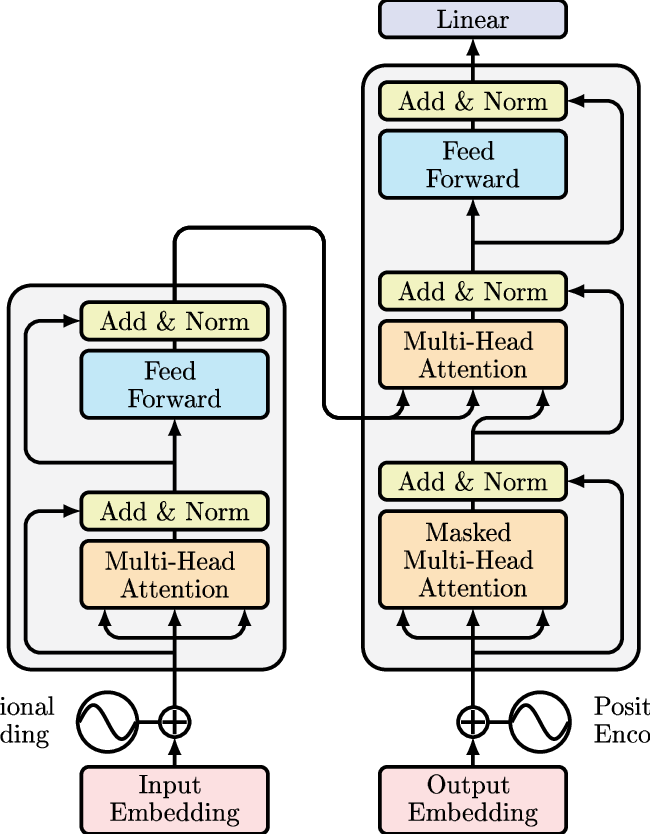
MultiHead Attention Explained:Implementing Masked Multihead attention ...
Advertisement Space (300x250)
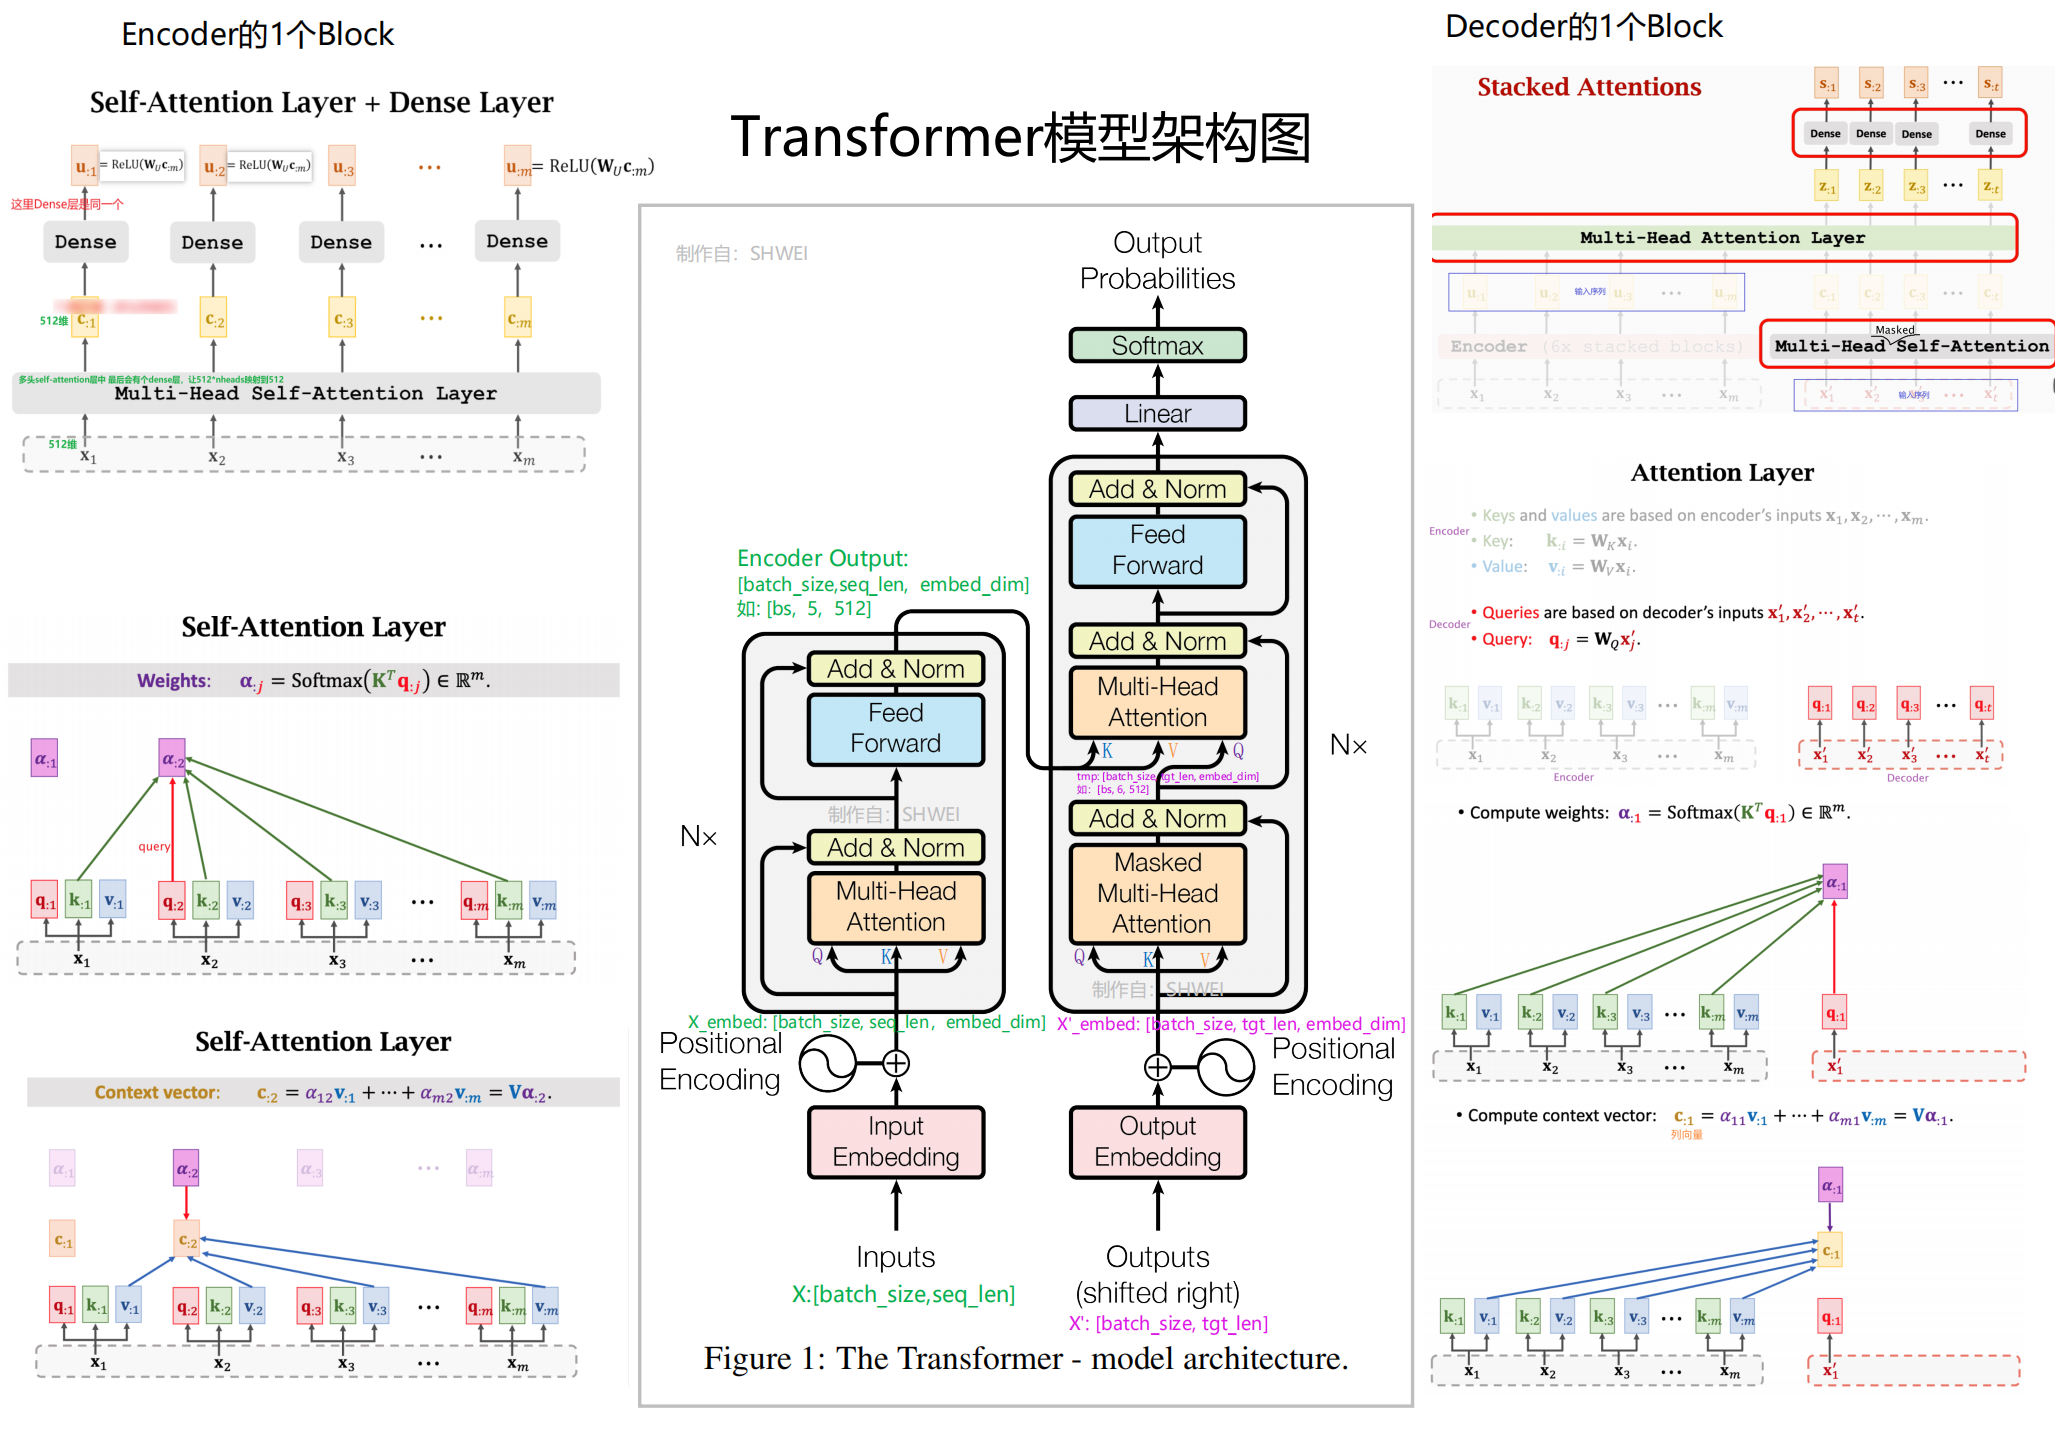
从训练和预测的角度来理解Transformer中Masked Self-Attention的原理_masked self attention ...
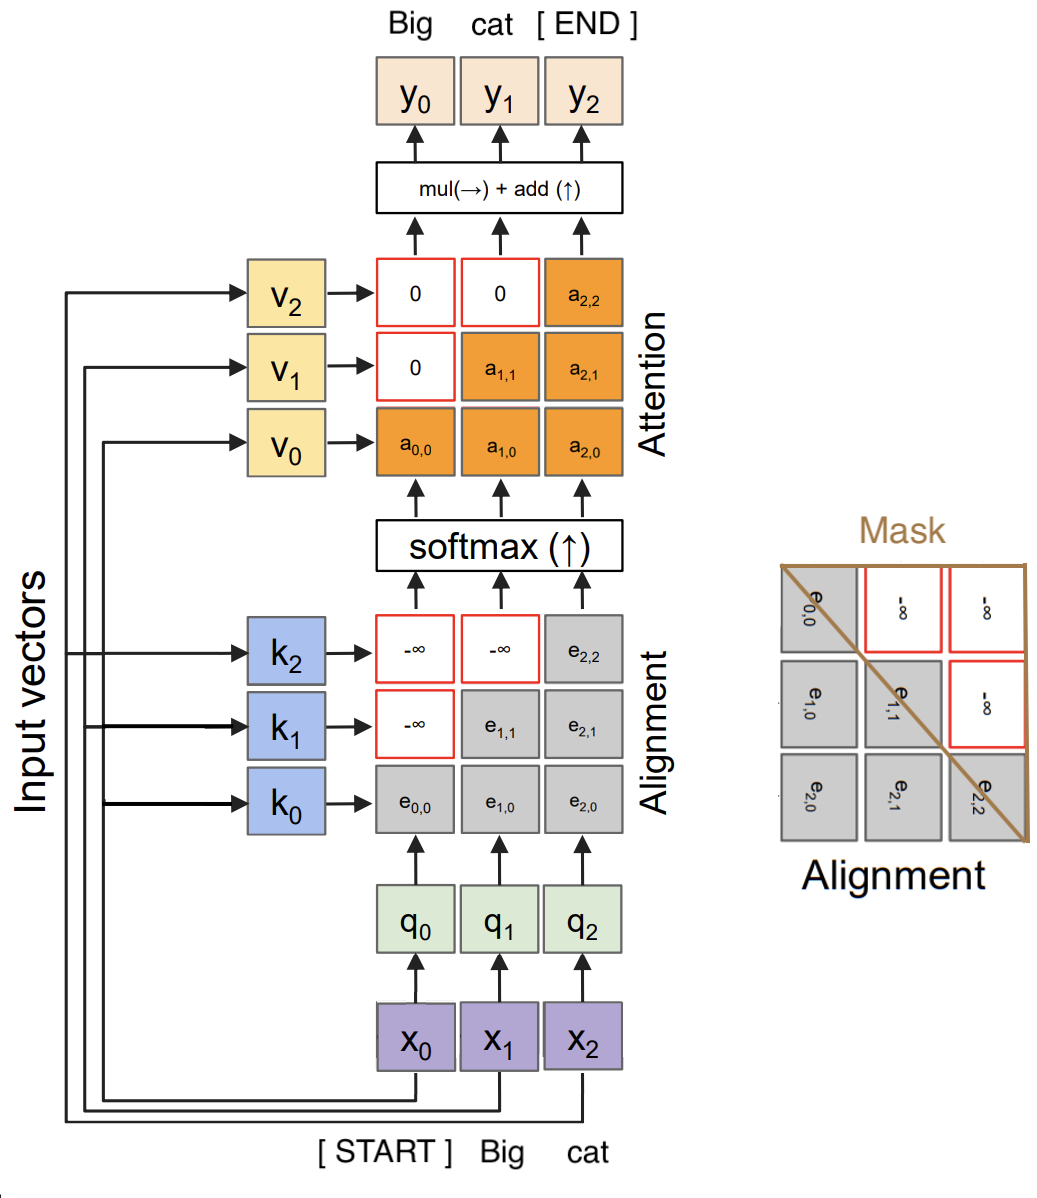
Generalizing Attention with Transformers | YA’s Almanac
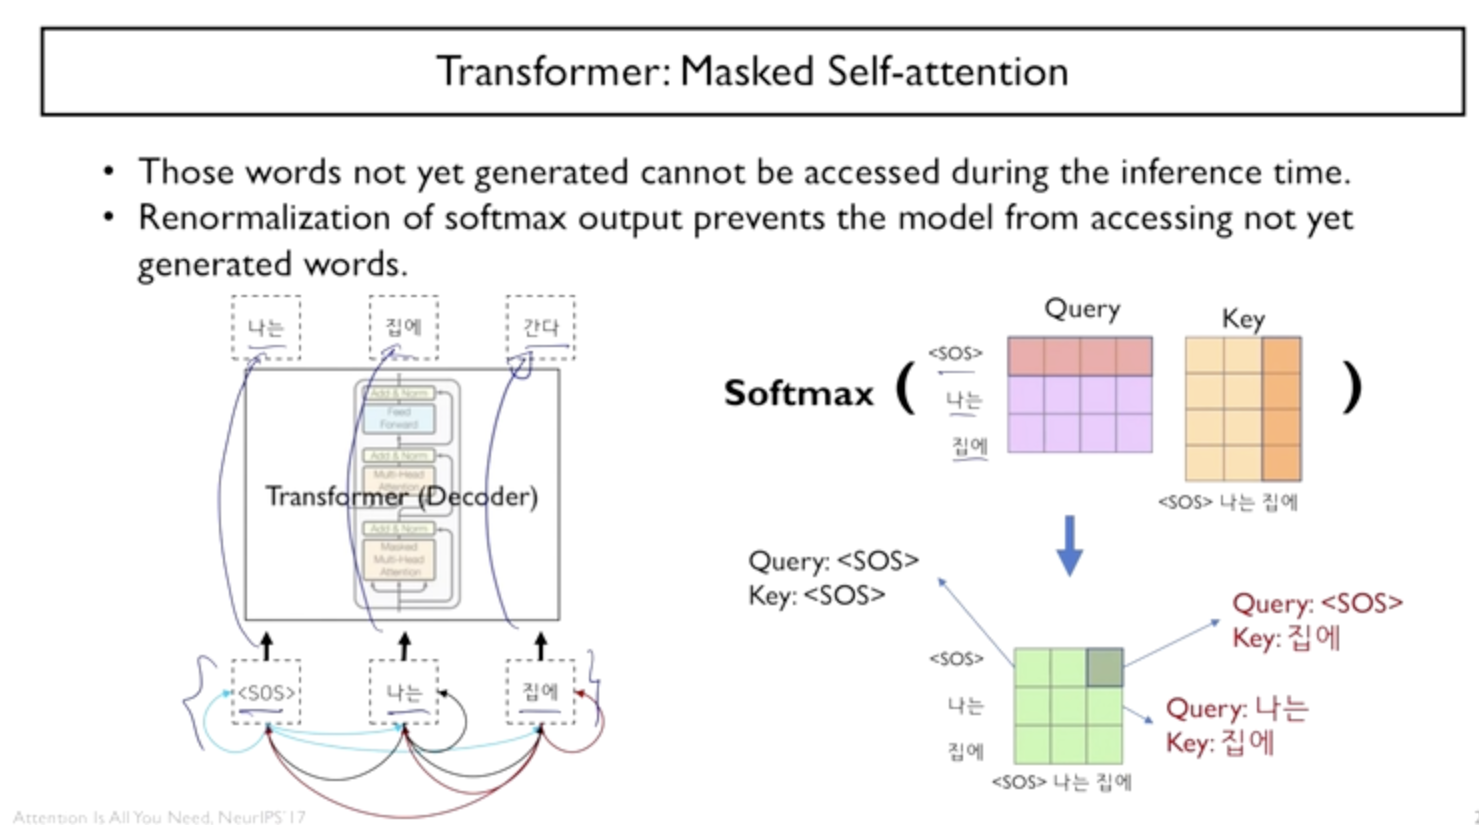
[NLP] Attention Is All You Need
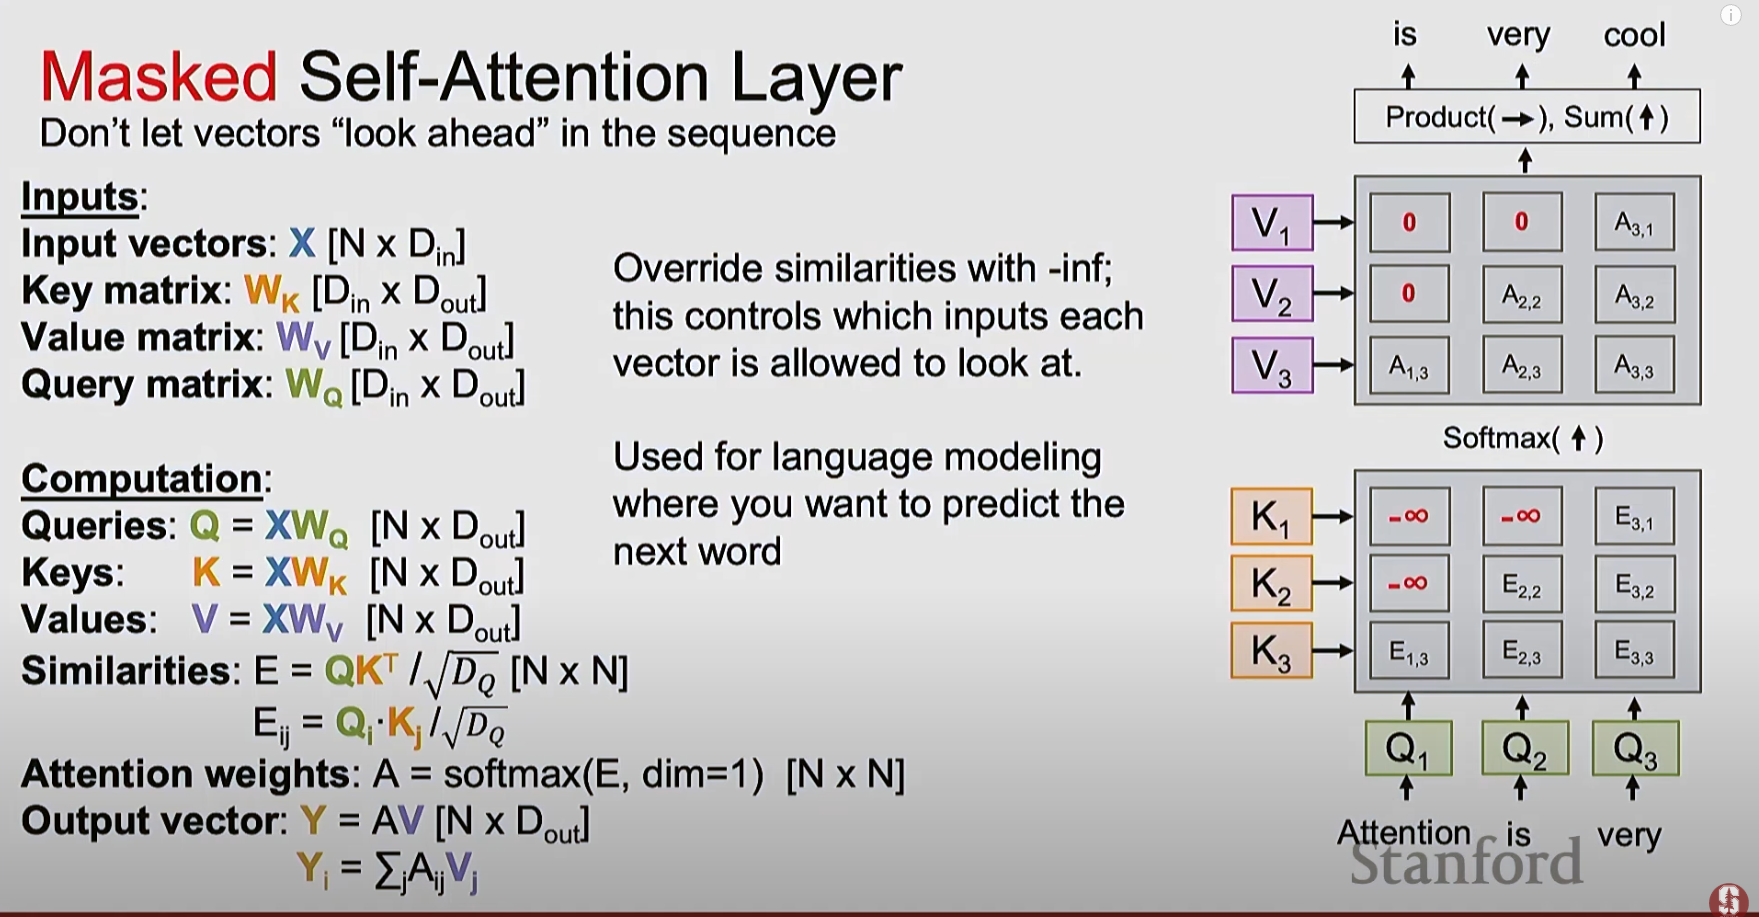
Large Language Model Notes: Attention and Transformer | Wayne’s Corner
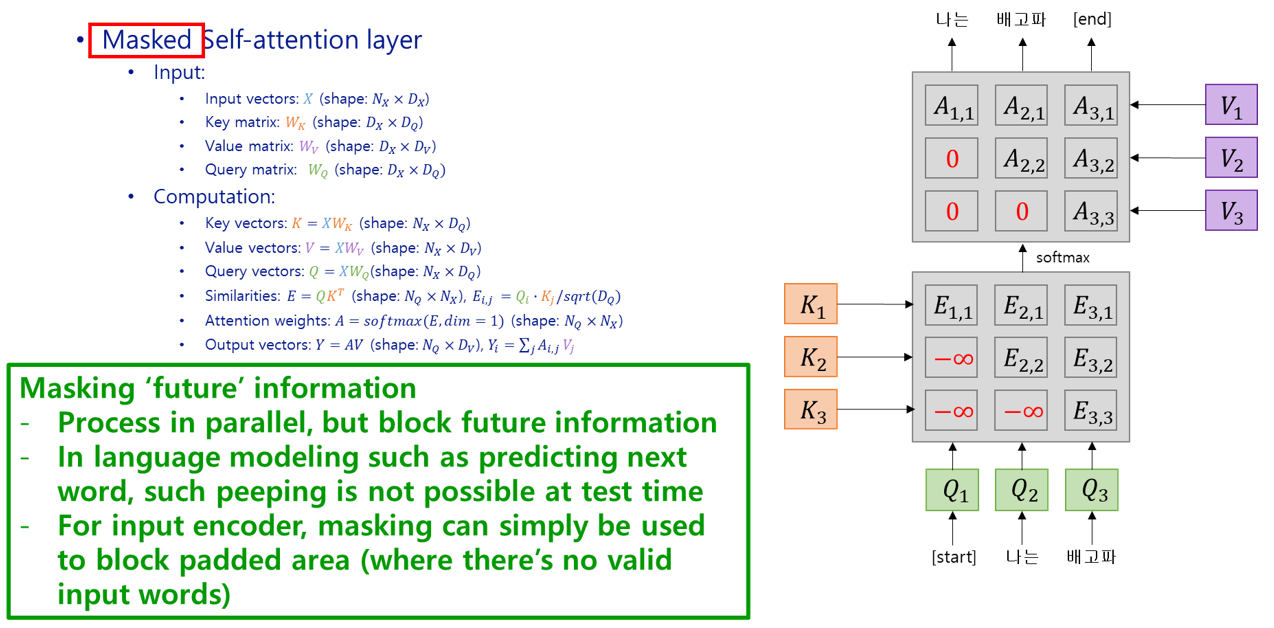
Attention and Transformer - part2 - Machine Learning Tech Blog
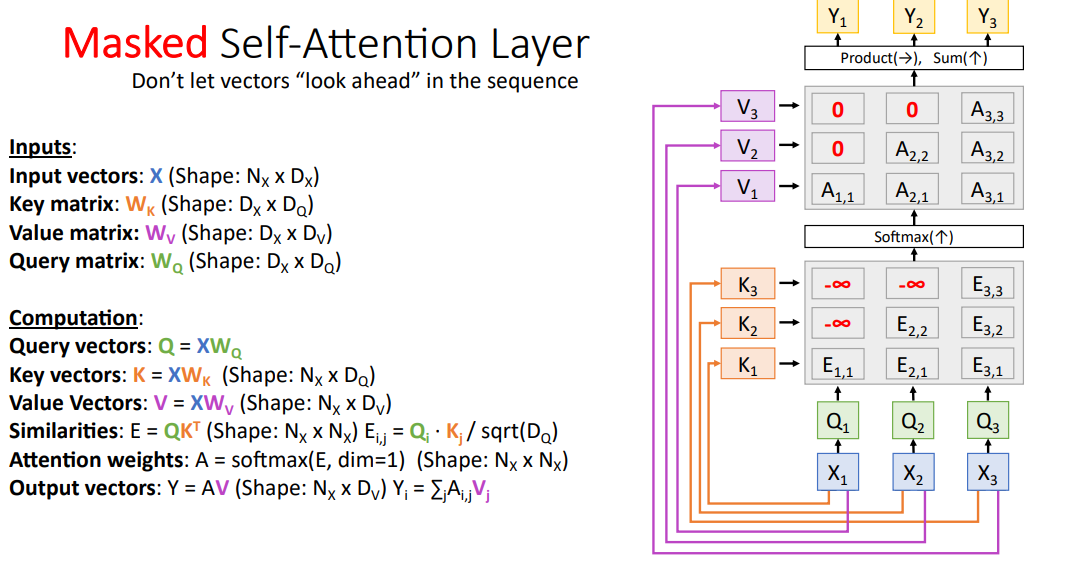
Lecture 13. Attention
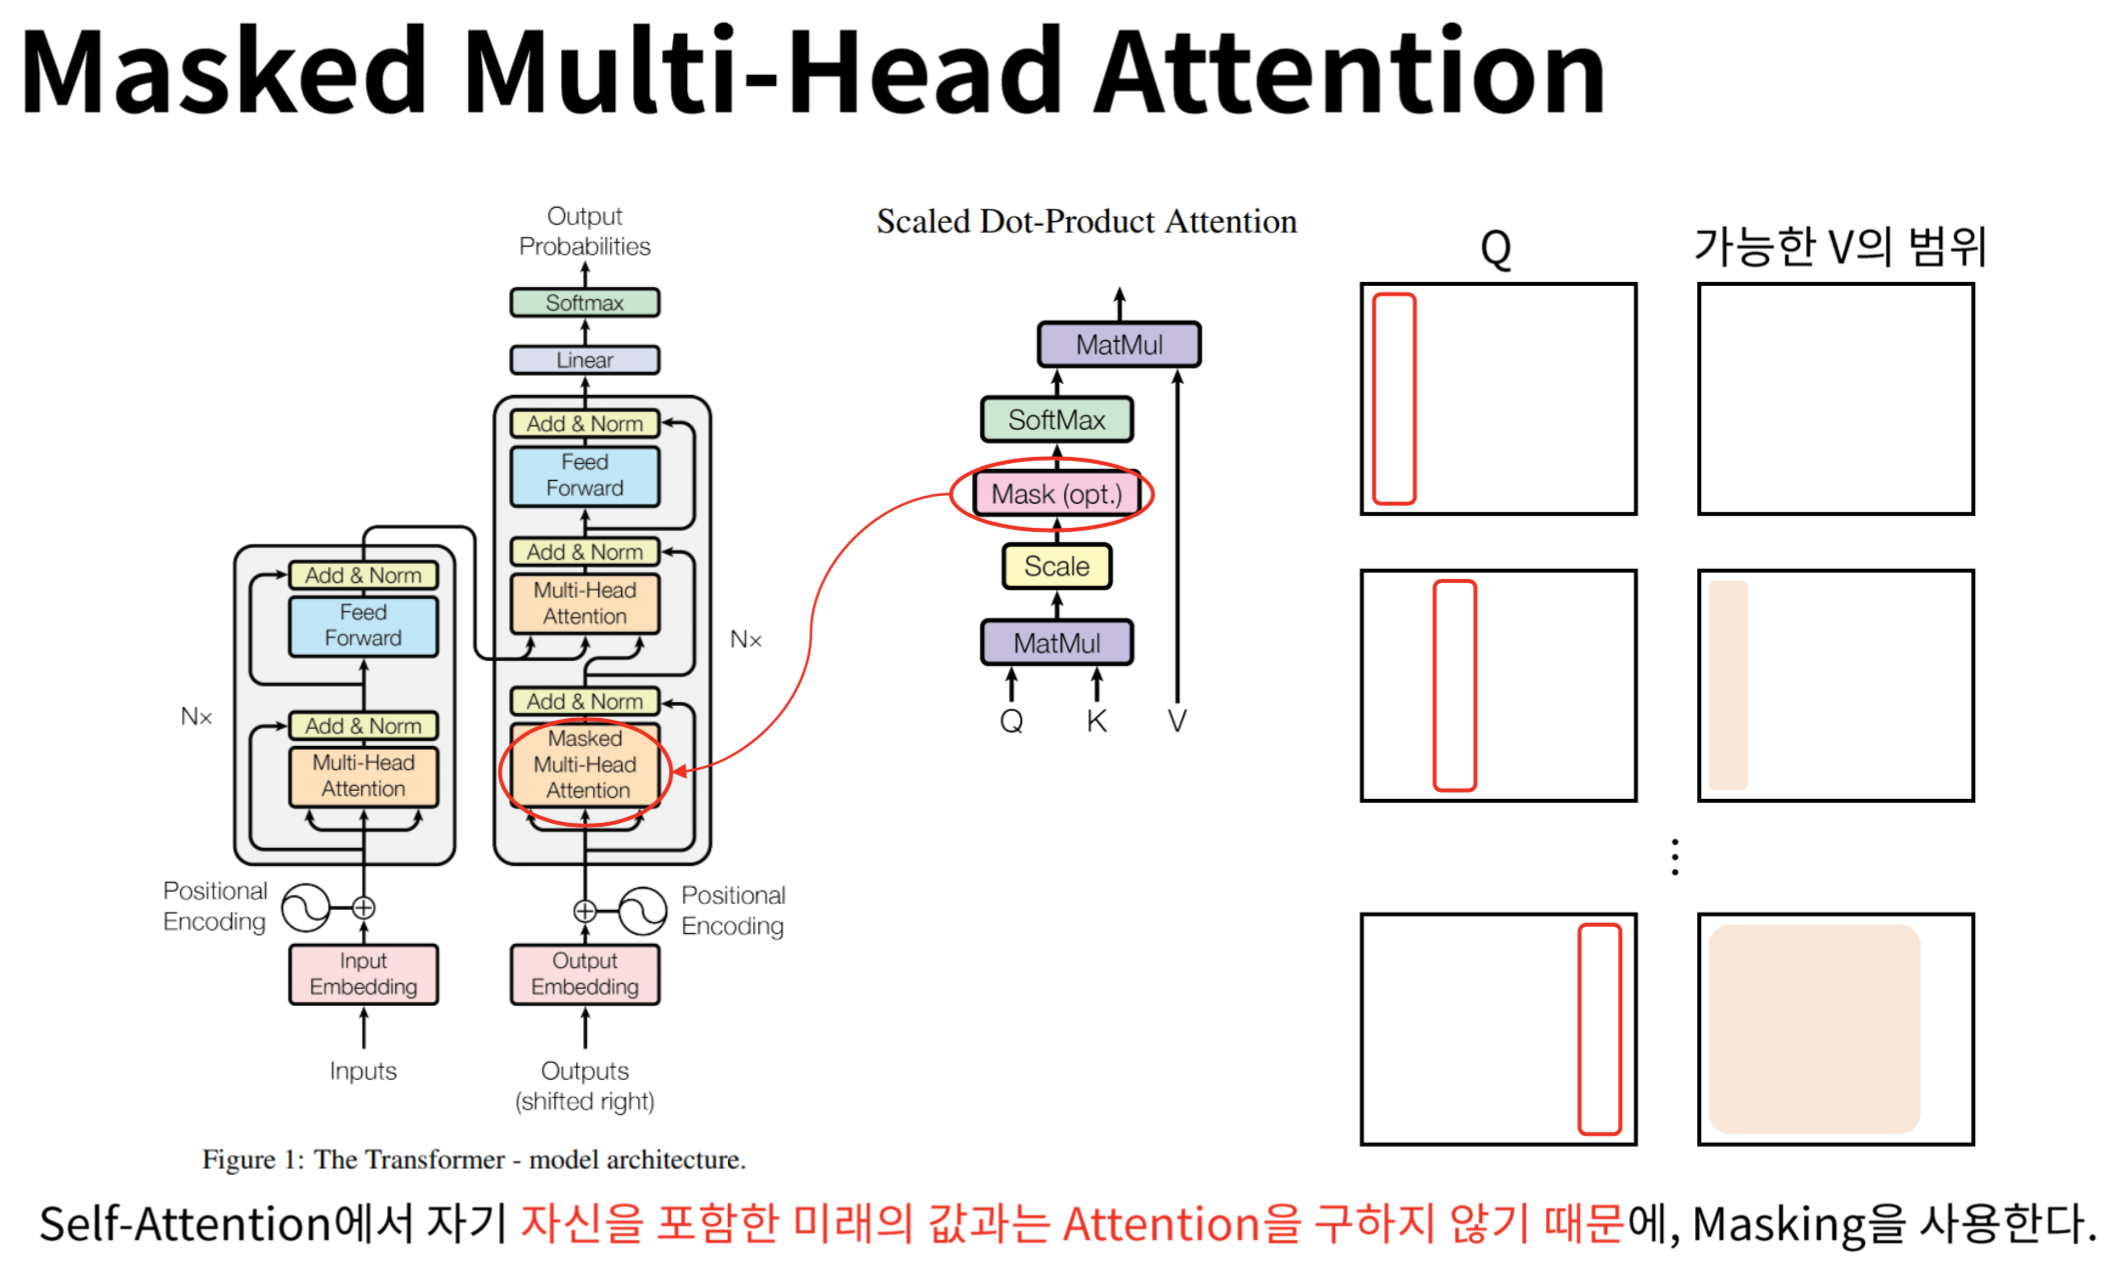
Attention 기법 | DataLatte's IT Blog

Transformer : Attention is all you need - aqaqsubin blog
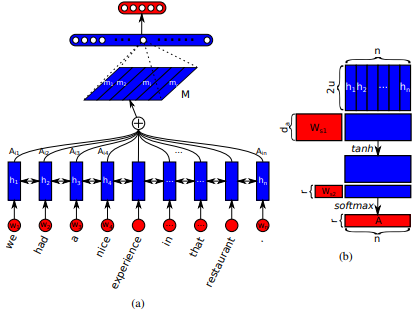
What is Attention mechanism | YeonwooSung's Blog
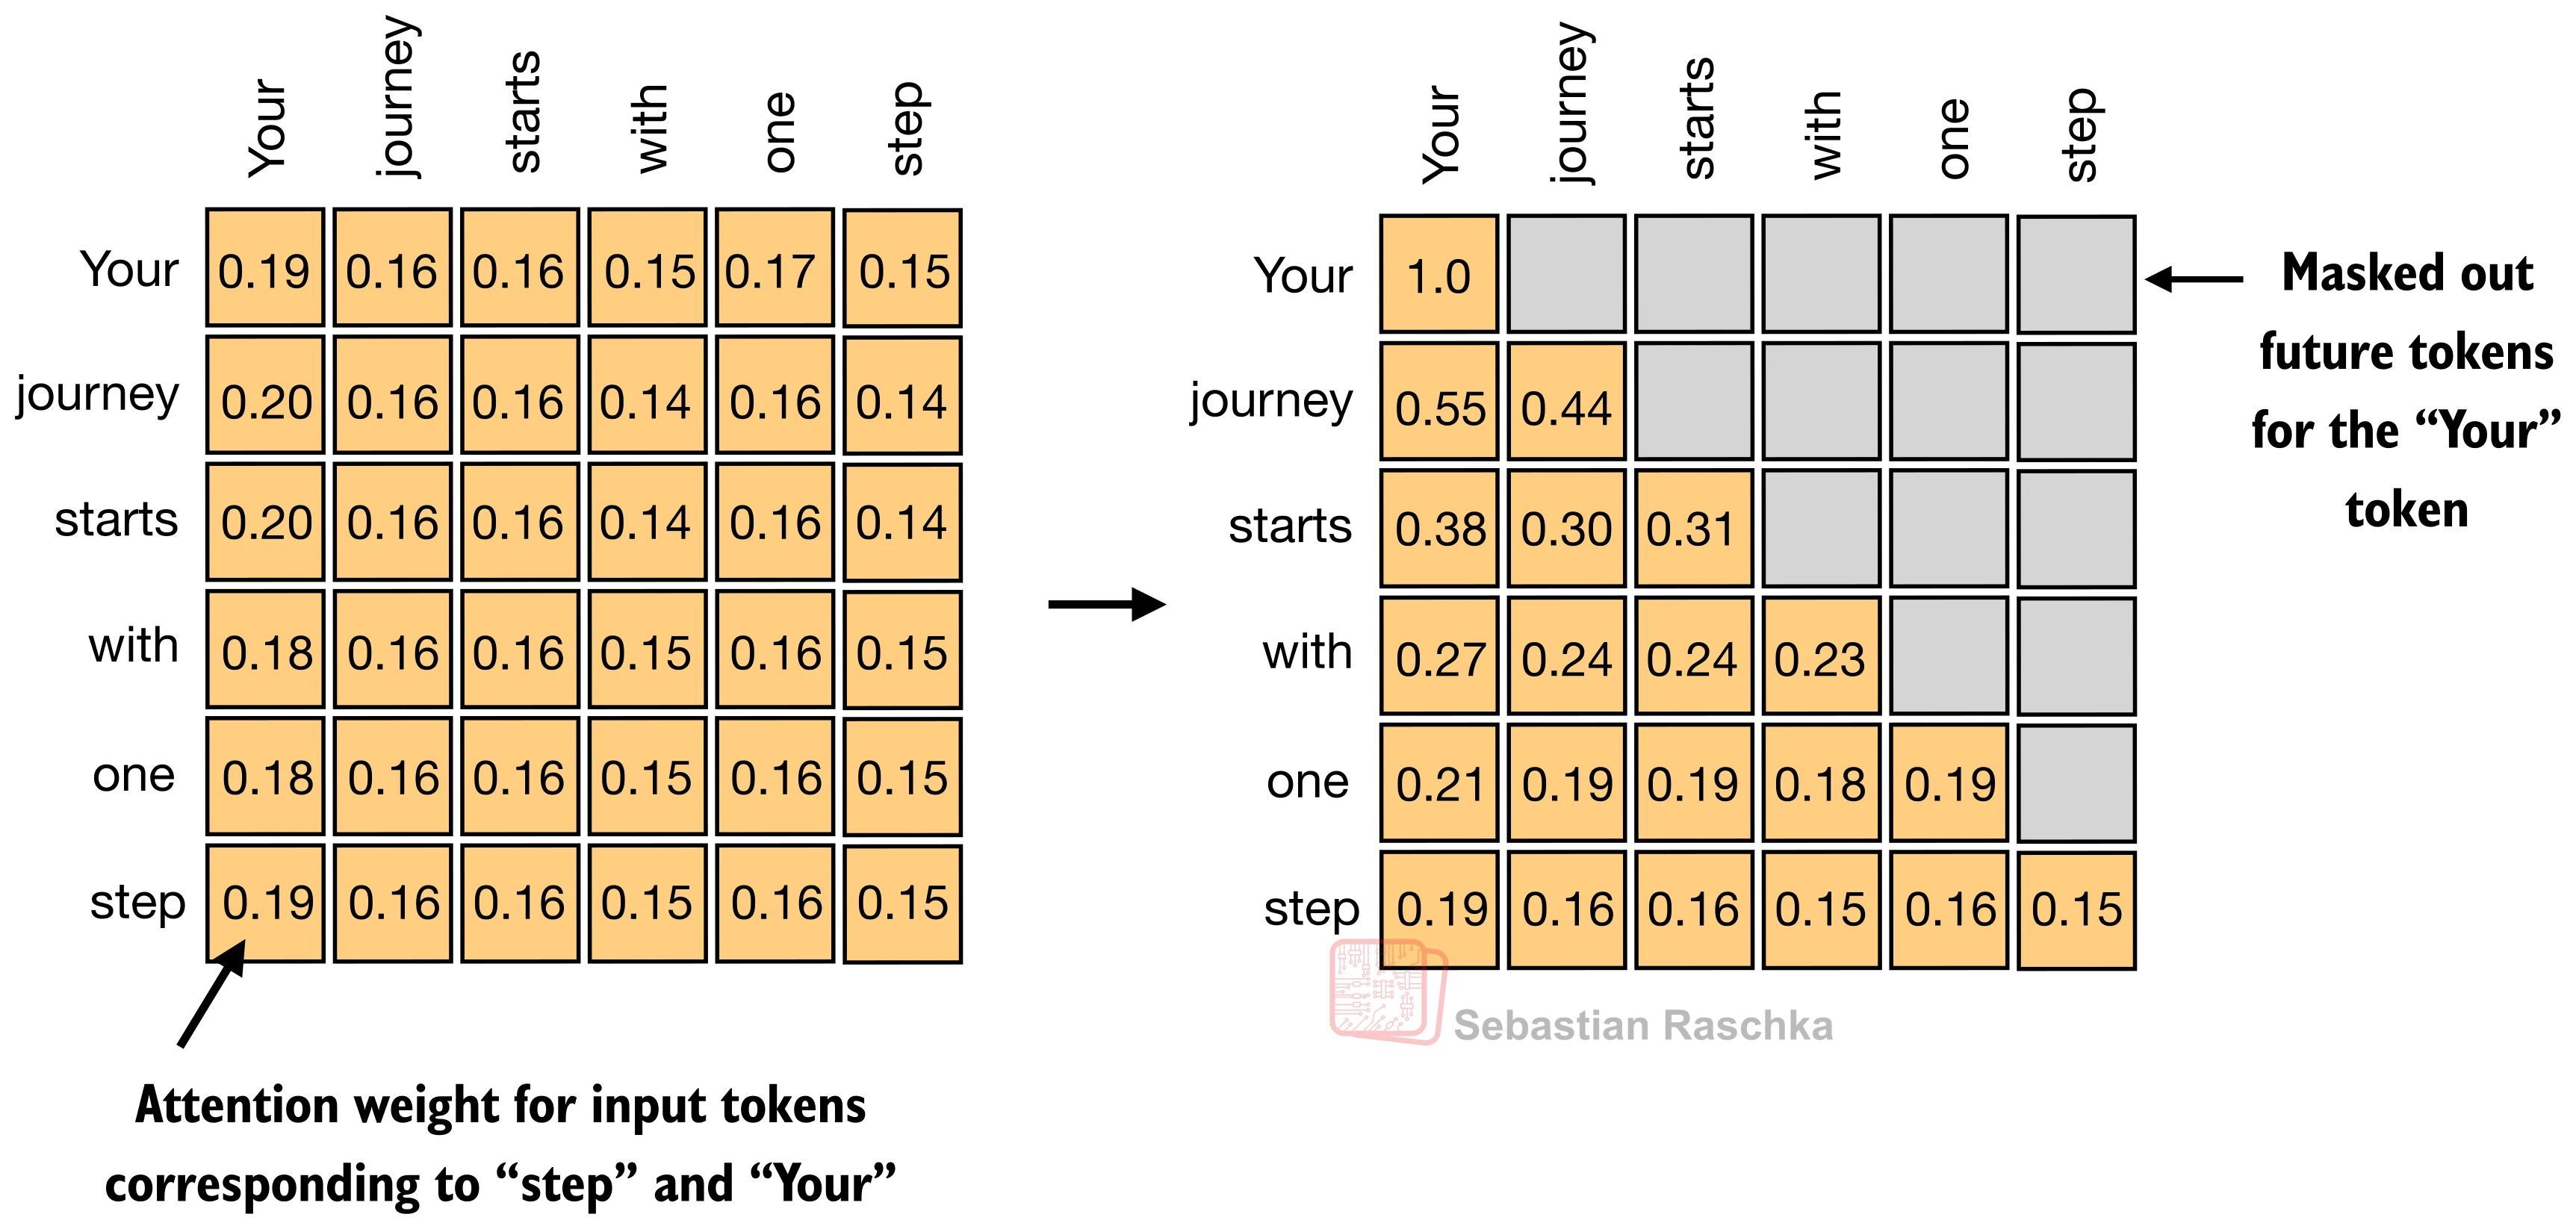
Multi-Head Attention (MHA) | Sebastian Raschka, PhD
Advertisement Space (336x280)
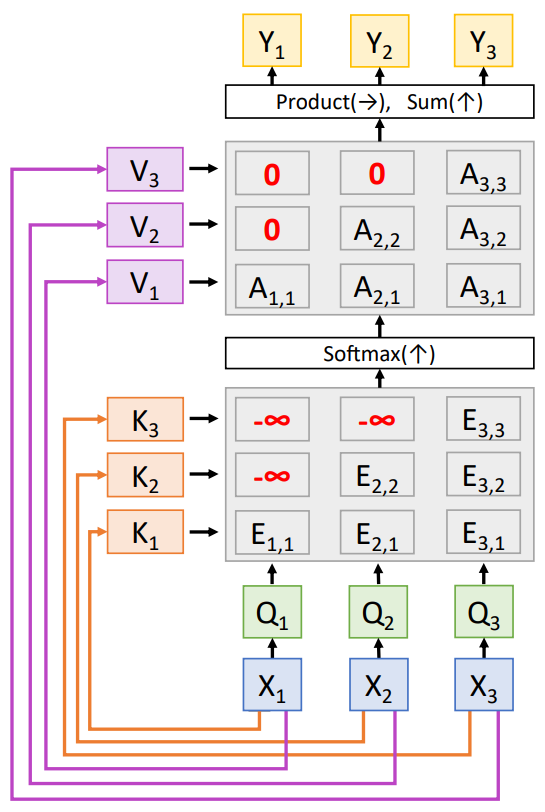
Attention & Transformers | Vision-Array

Explain Self-Attention, and Masked Self-Attention as used in ...
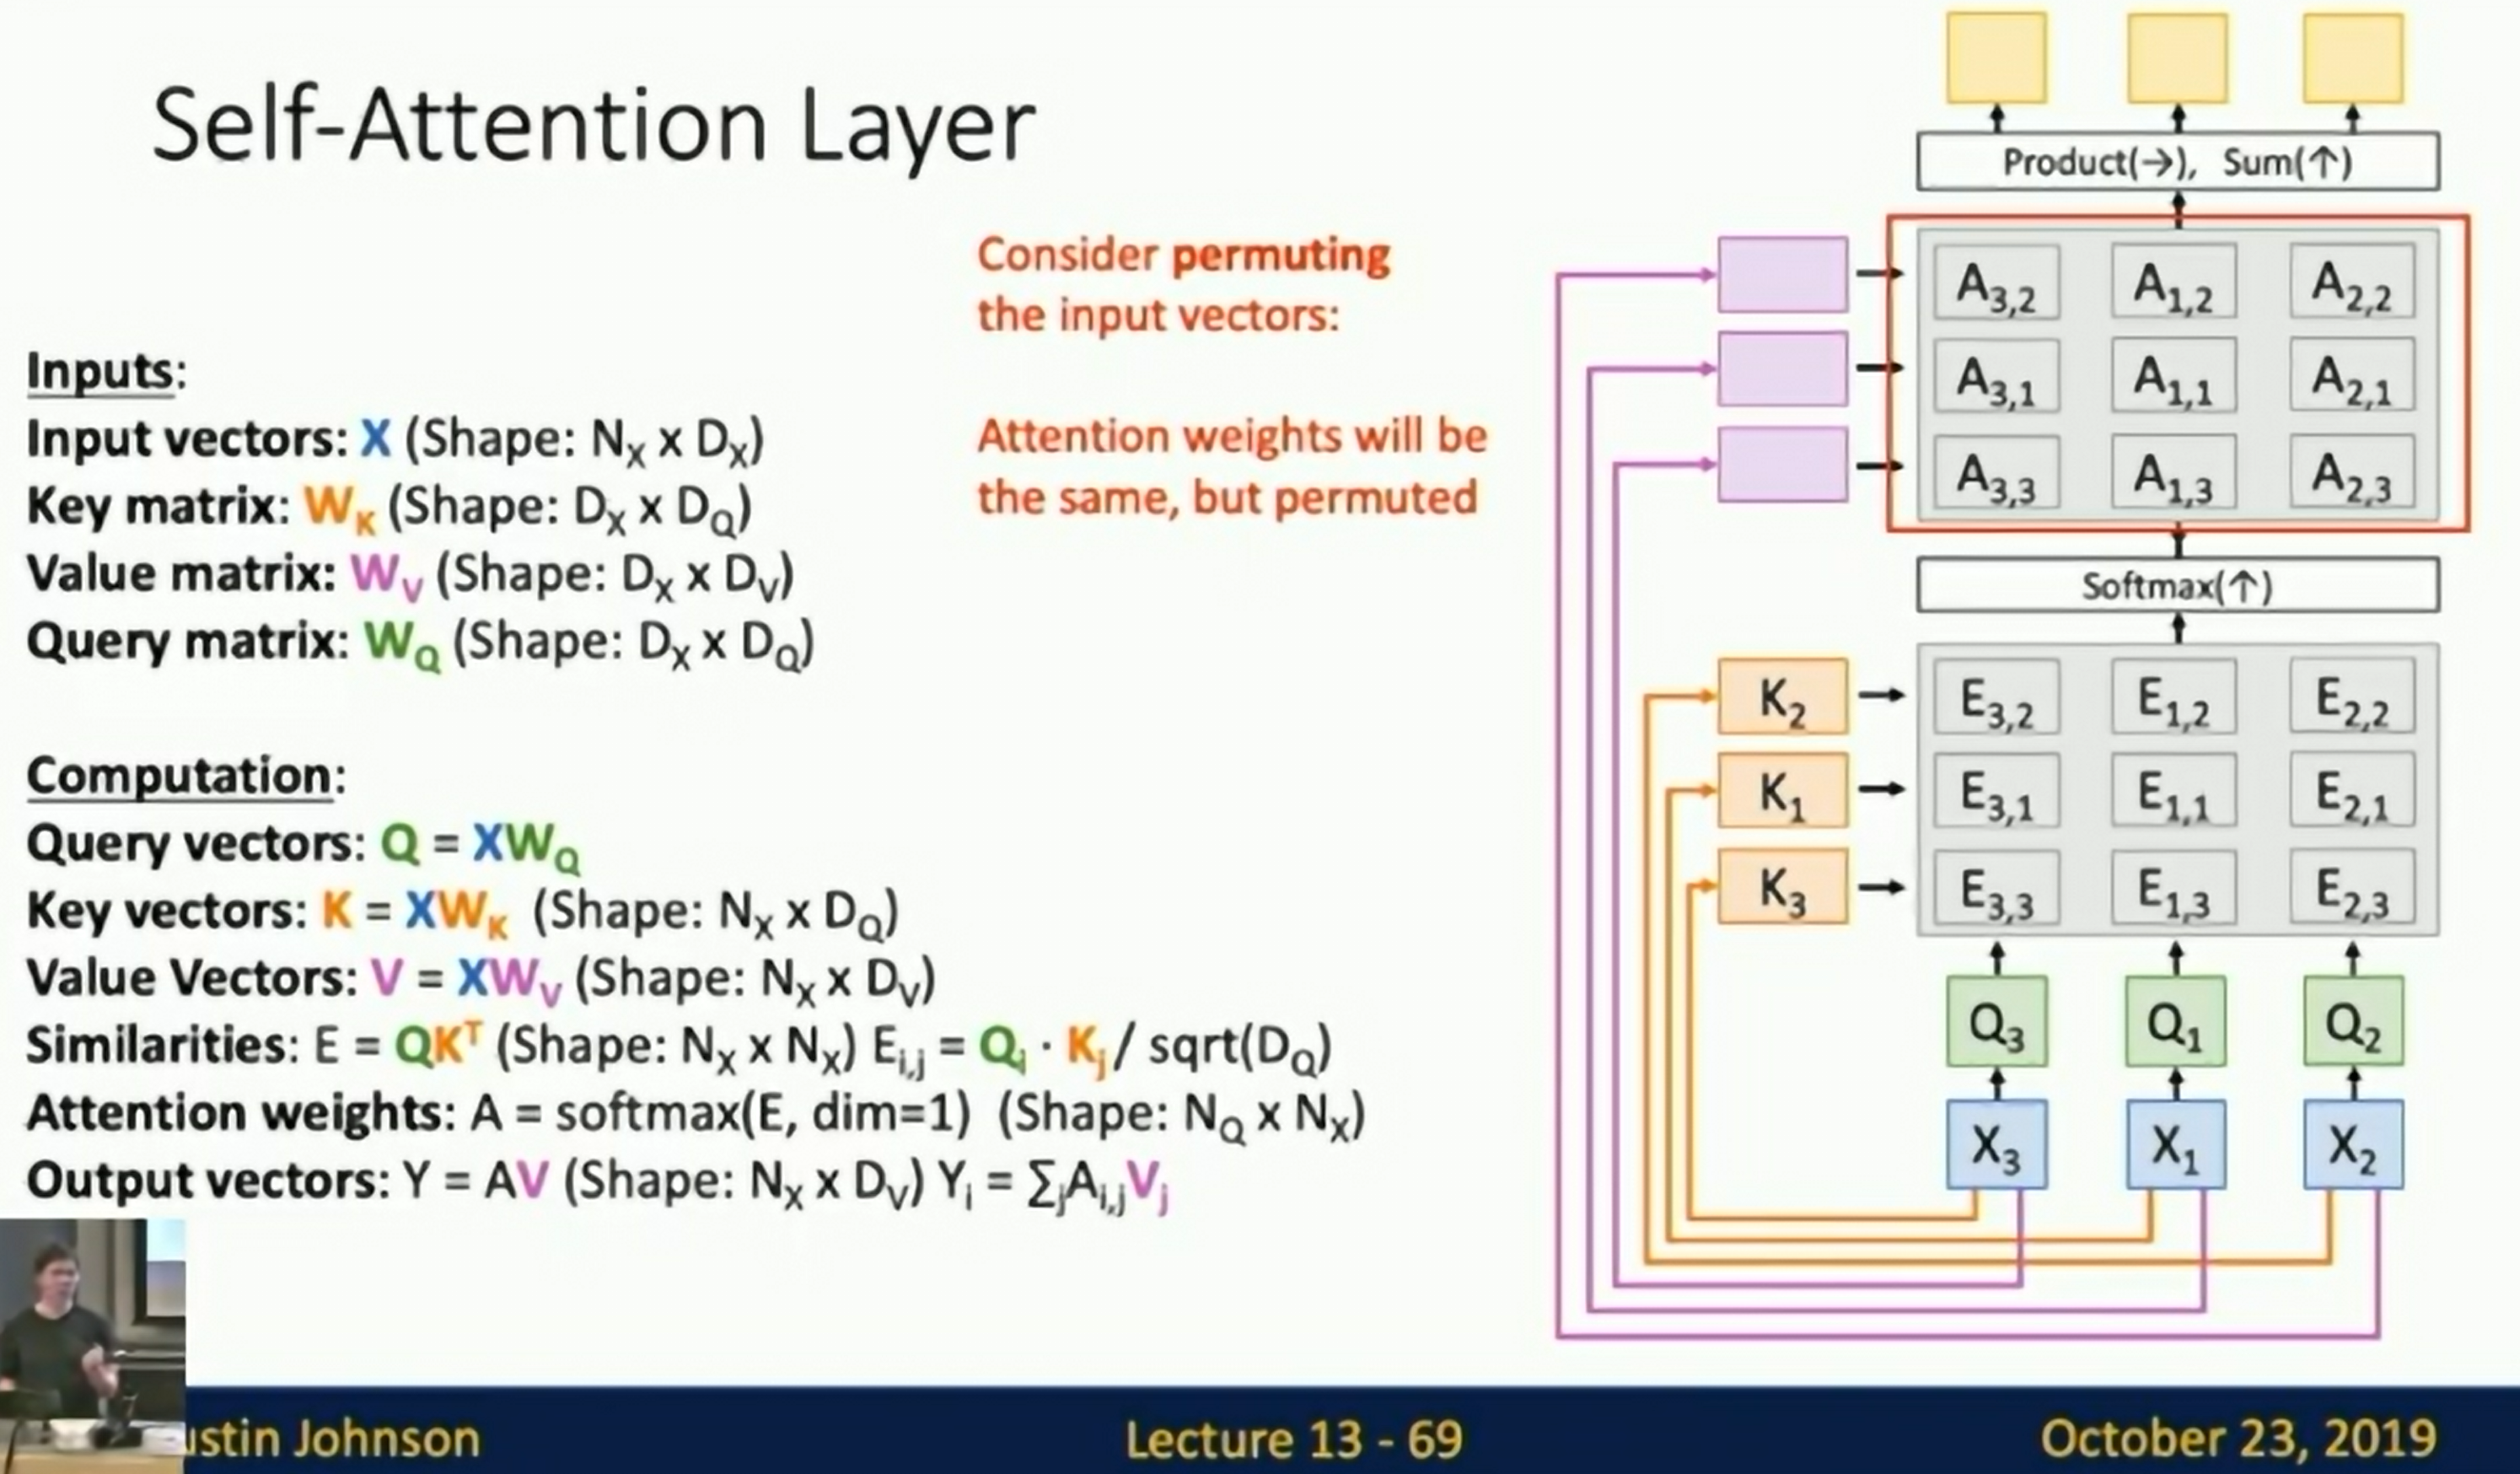
12 & 13 Recurrent Neural Networks & Attention Mechanism | SaturnTsen
Masked Language Modeling: Bidirectional Understanding in BERT ...

Multihead dynamic masked self-attention (DMA). | Download Scientific ...
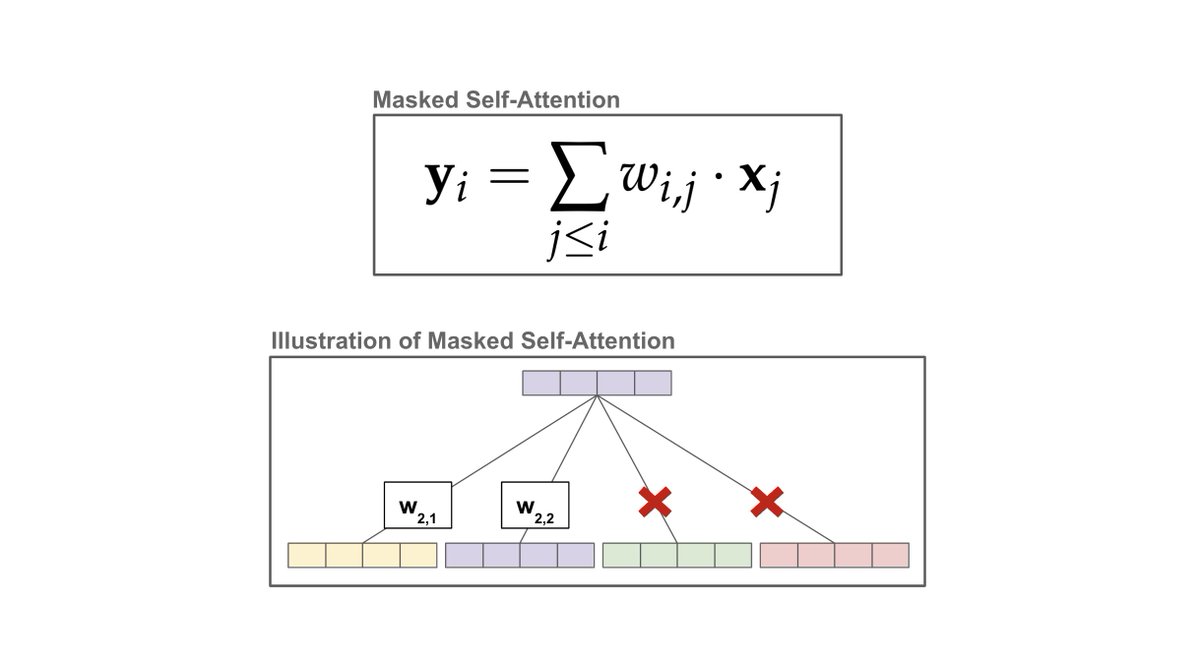
Each “block” of a large language model (LLM) is comprised of self ...
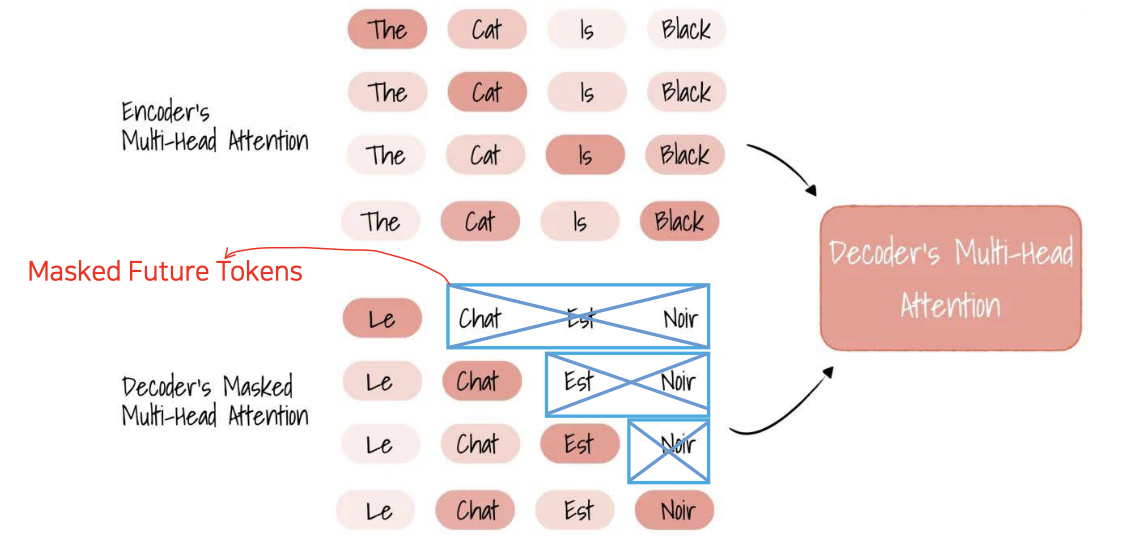
Chapter 3. Transformer and Attention

Masked self-attention mechanism. fij denotes f (xi, xj) in Eq.(9 ...

Multihead dynamic masked self-attention (DMA). | Download Scientific ...

Diagram of masked self-attention. | Download Scientific Diagram
Advertisement Space (336x280)
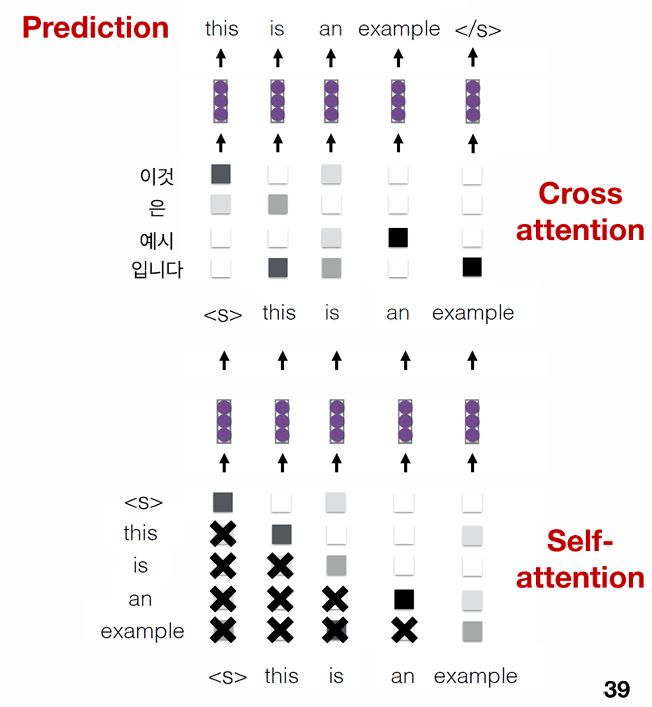
[basic] Attention and Transformer
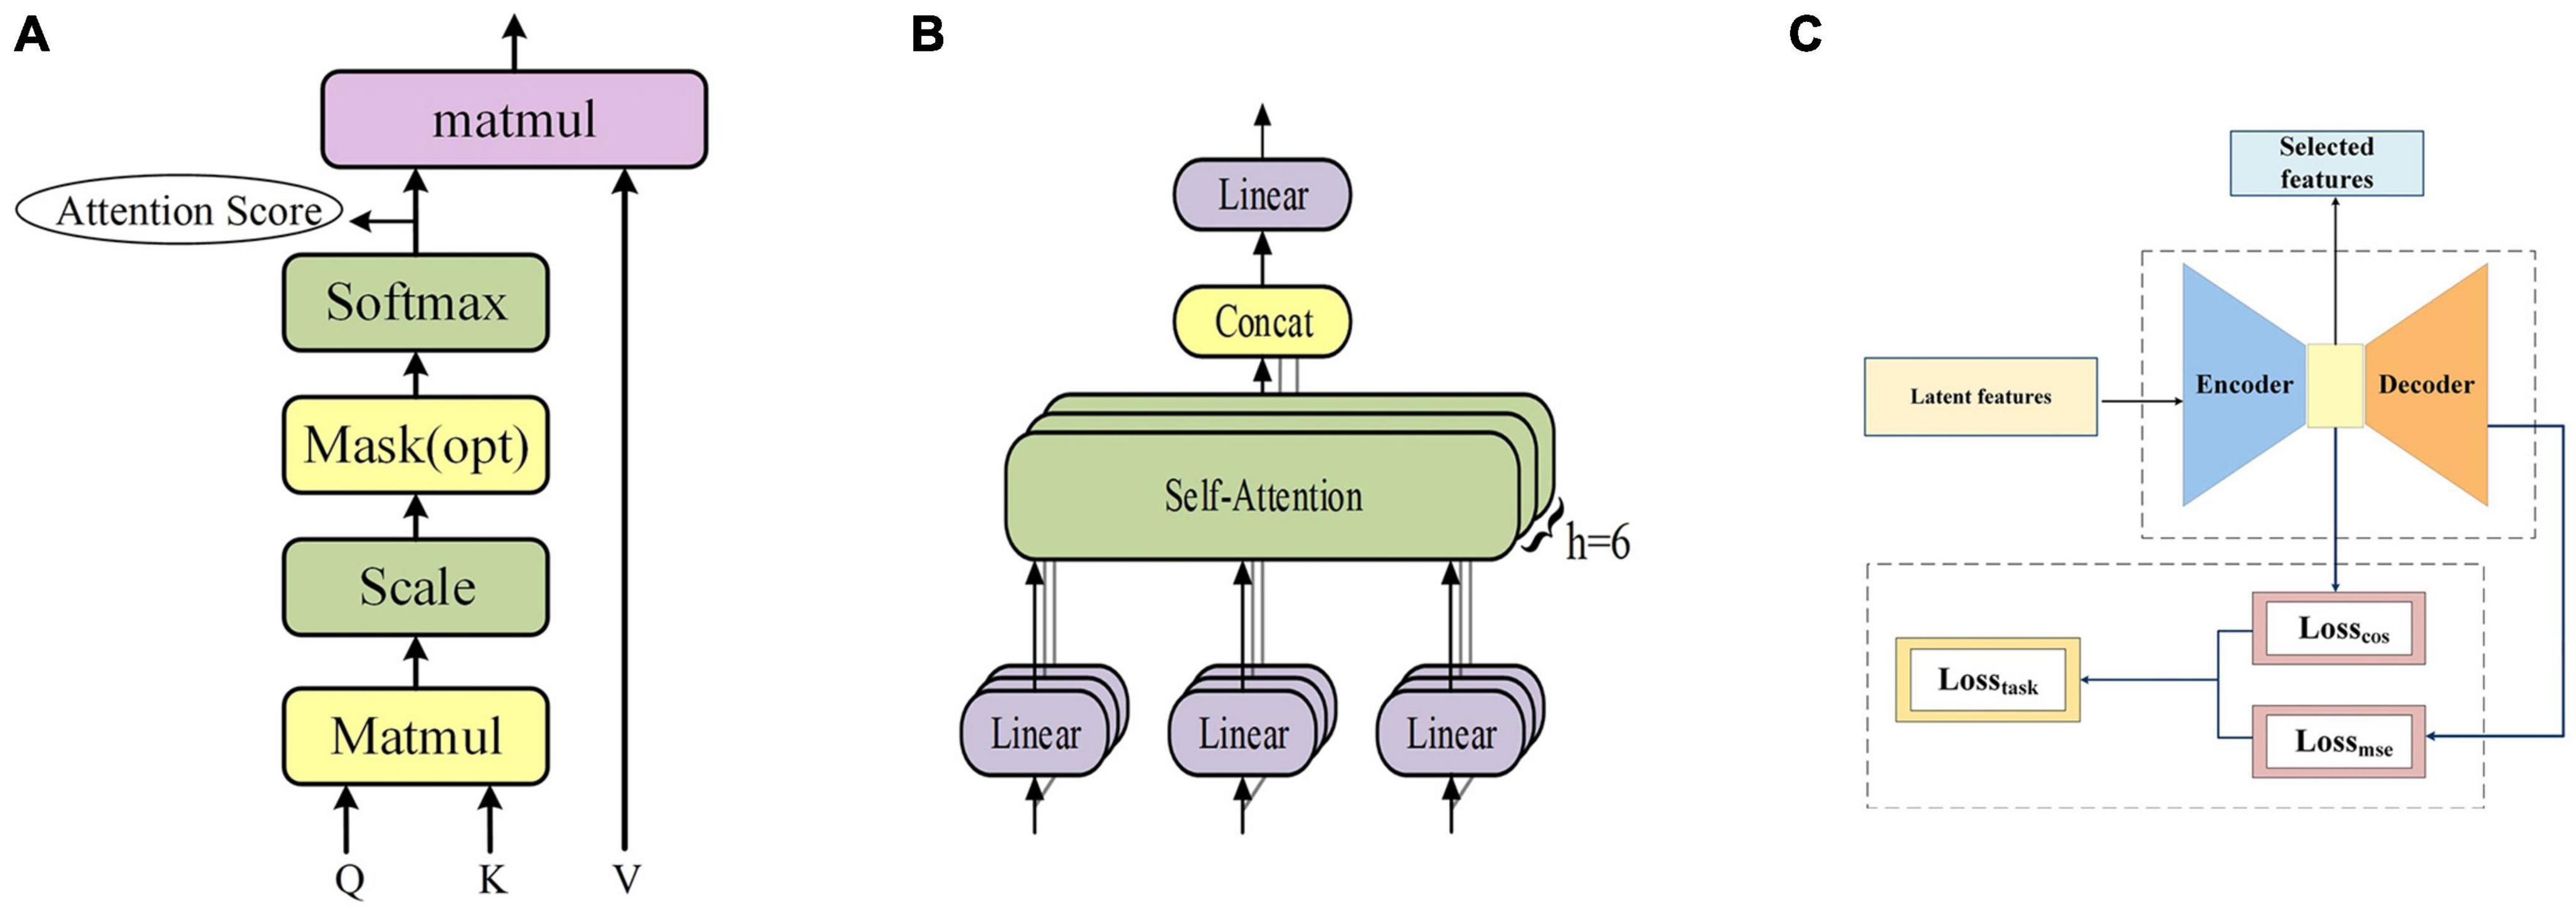
Frontiers | Multi-head attention-based masked sequence model for ...

GitHub - CatworldLee/Gaussian-Mixture-Mask-Attention

Masked Self-Attention — Por Qué los Transformer Decoders Deben Bloquear ...

Unmasking the Secrets of Self-Attention in Transformers: How Masked ...
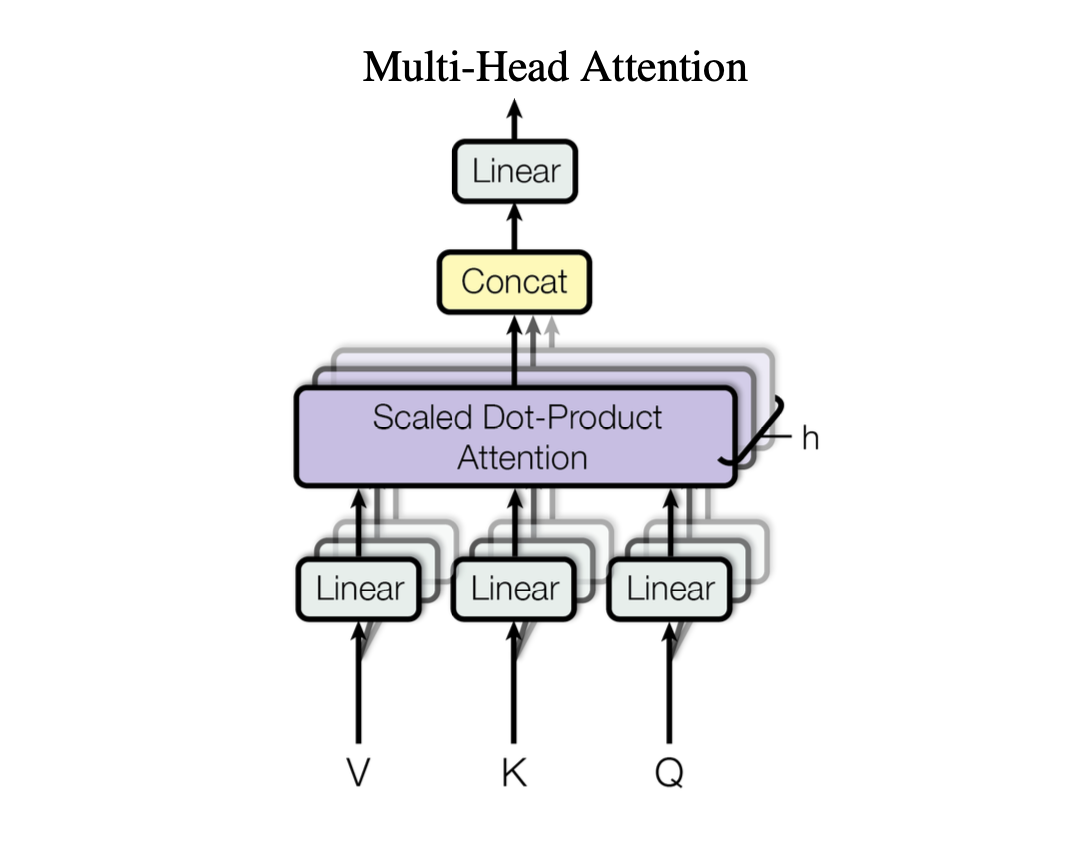
GitHub - ranfysvalle02/ai-self-attention: This repository provides a ...