
Predictable Llm Serving On Gpu Clusters

Predictable LLM Serving on GPU Clusters | AI Research Paper Details
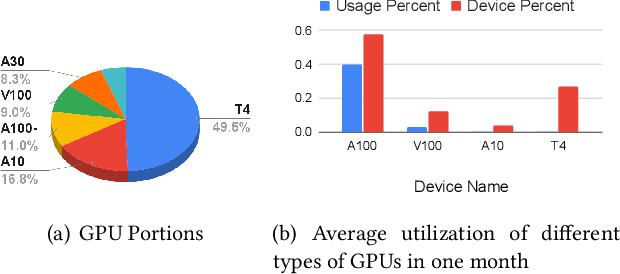
Figure 1 from LLM-PQ: Serving LLM on Heterogeneous Clusters with Phase ...

CoLLM: Continuous Adaptation for SLO-Aware LLM Serving on Shared GPU ...

CoLLM: Continuous Adaptation for SLO-Aware LLM Serving on Shared GPU ...

CoLLM: Continuous Adaptation for SLO-Aware LLM Serving on Shared GPU ...
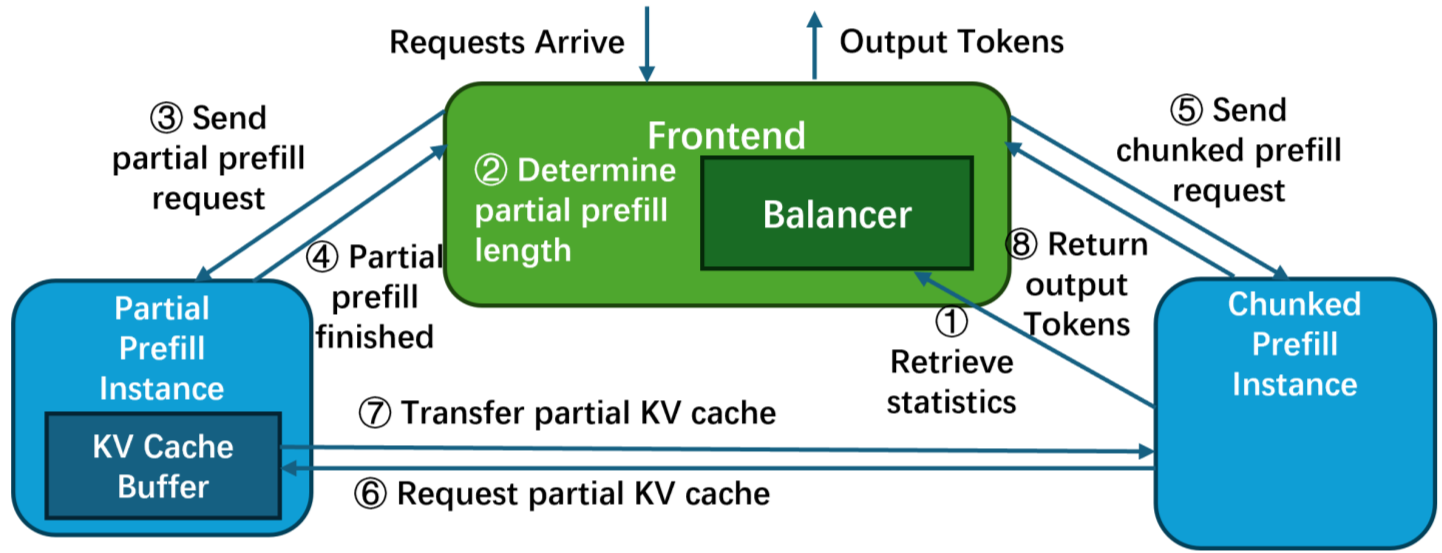
[논문 리뷰] Cronus: Efficient LLM inference on Heterogeneous GPU Clusters ...

CoLLM: Continuous Adaptation for SLO-Aware LLM Serving on Shared GPU ...
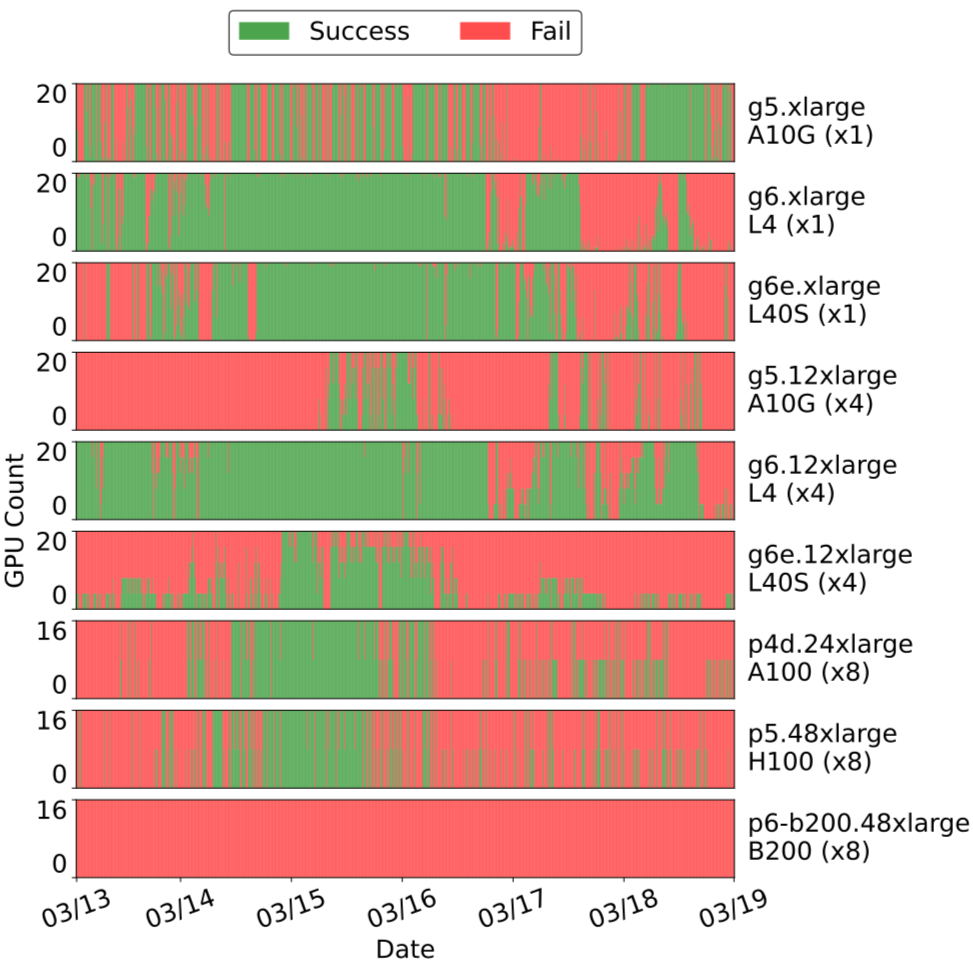
[논문 리뷰] ShuntServe: Cost-Efficient LLM Serving on Heterogeneous Spot ...
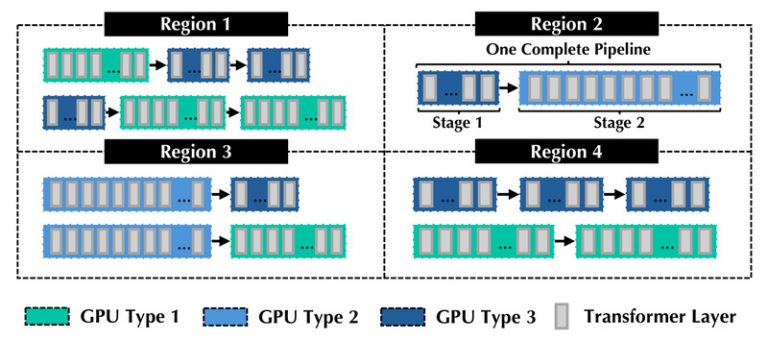
Parallax: Run LLMs on Decentralized Devices Without Costly GPU Clusters ...

Hetis: Serving LLMs in Heterogeneous GPU Clusters with Fine-grained and ...
Advertisement Space (300x250)
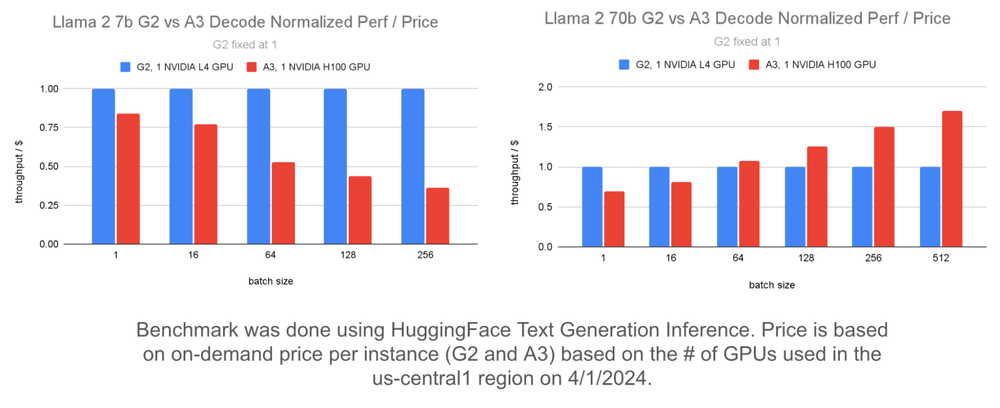
Maximize your LLM serving throughput for GPUs on GKE — a practical ...

LLM Serving Is a GPU Memory Management Problem | by Steven Li | Medium

[2504.19516] Bullet: Boosting GPU Utilization for LLM Serving via ...
Announcing GPU and LLM Model Serving | Databricks Blog

[2504.19516] Bullet: Boosting GPU Utilization for LLM Serving via ...
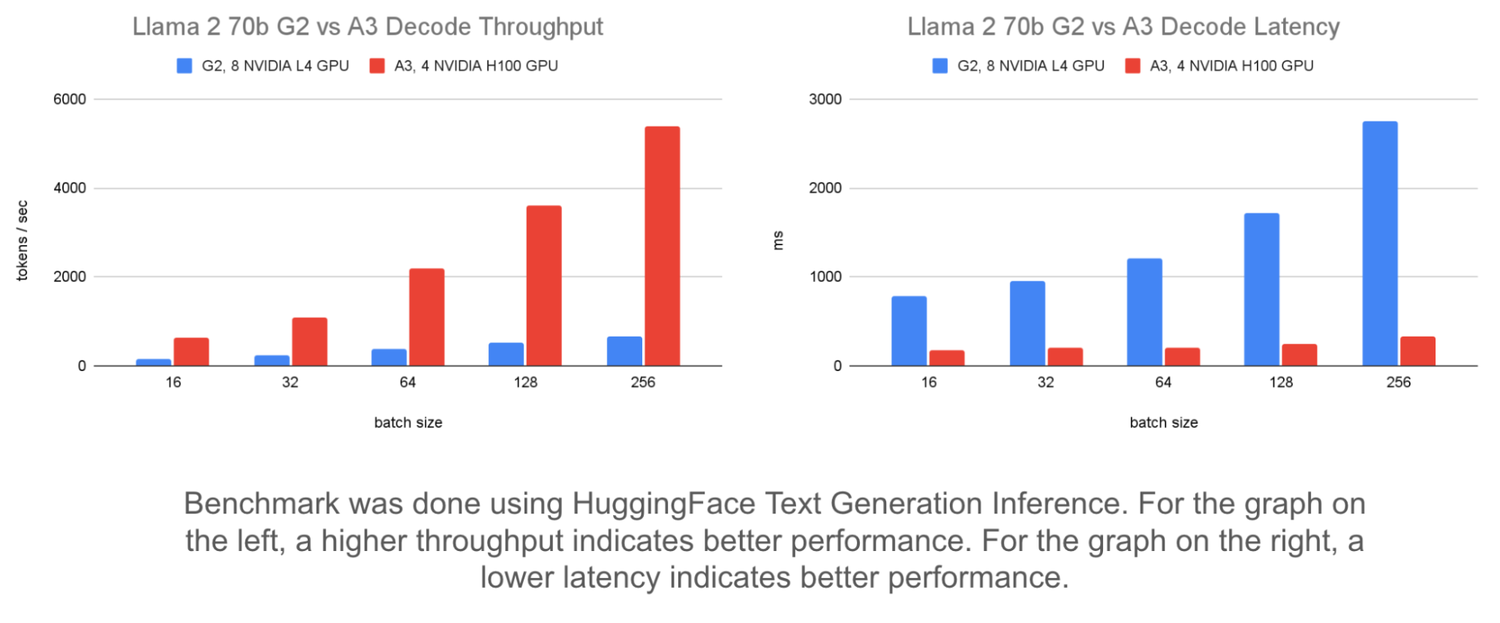
Selecting GPUs for LLM serving on GKE | Google Cloud Blog

[2509.08309] Hetis: Serving LLMs in Heterogeneous GPU Clusters with ...
MRC Protocol: Optimizing GPU Clusters for LLM Training — The Value ...

SMG: The Case for Disaggregating CPU from GPU in LLM Serving – PyTorch
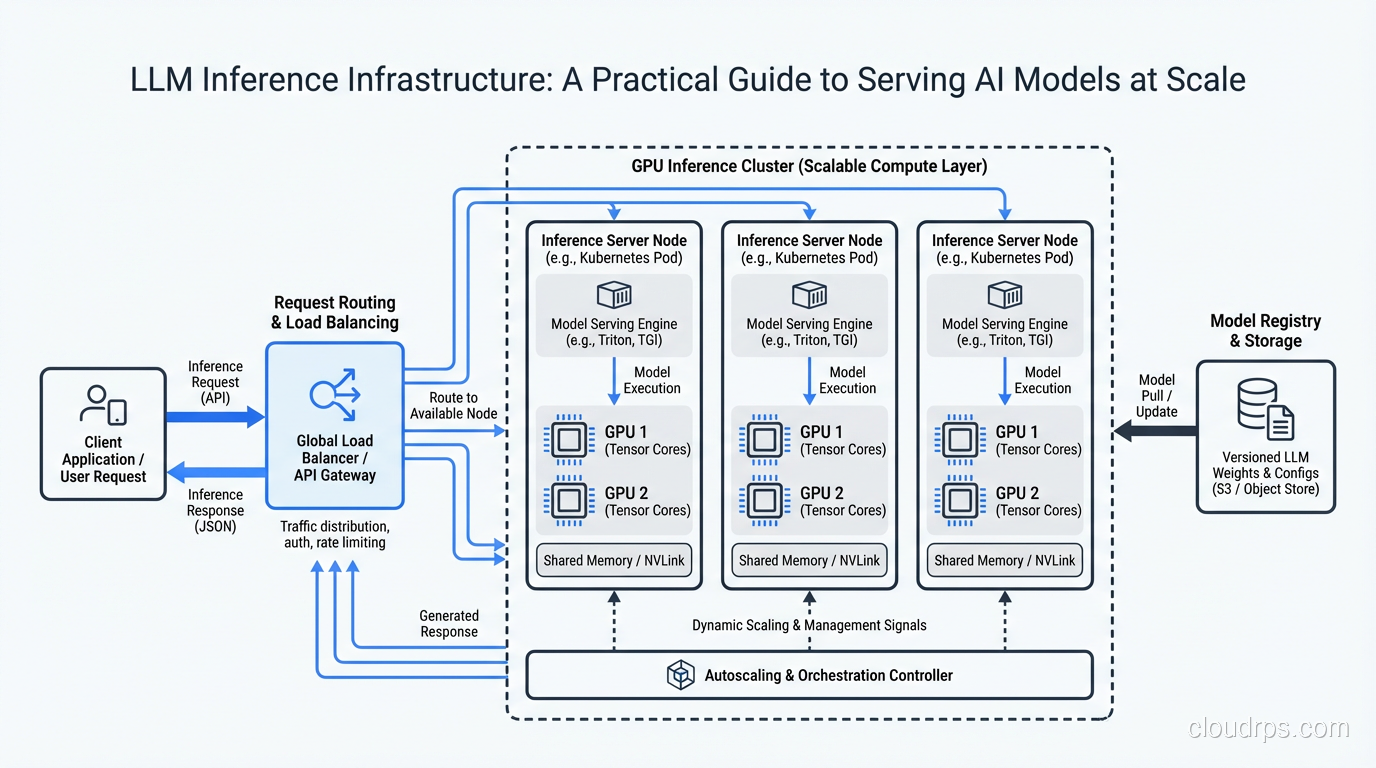
LLM Inference Infrastructure: Serving AI at Scale
Advertisement Space (336x280)
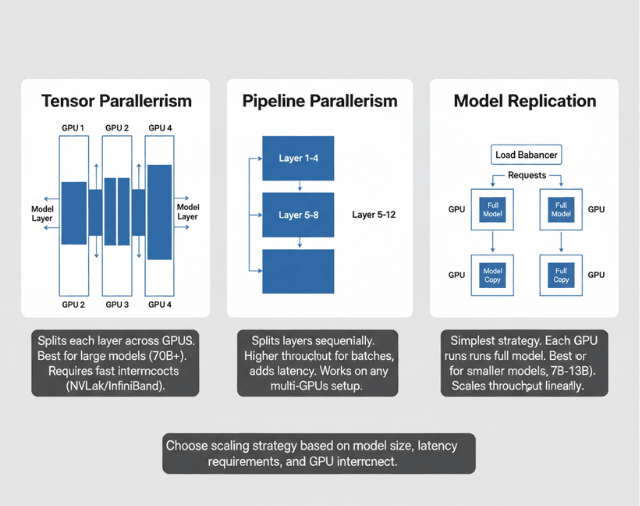
GPU Guide for LLM Deployment - RTX 4090 to A100 Benchmarks (2026)
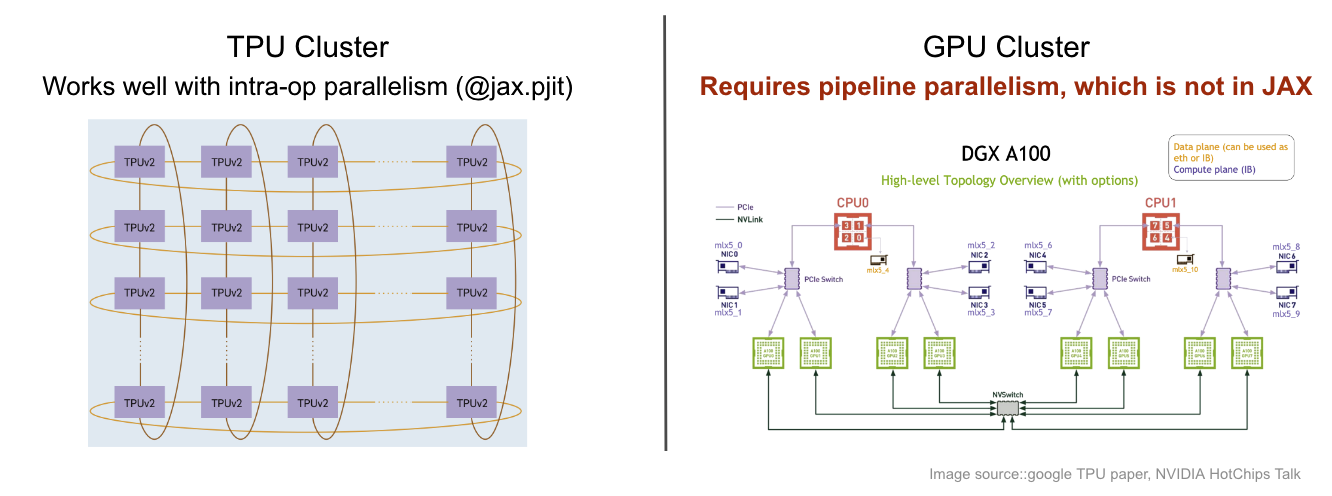
High-Performance LLM Training at 1000 GPU Scale With Alpa & Ray

[논문 리뷰] SLO-aware GPU Frequency Scaling for Energy Efficient LLM ...
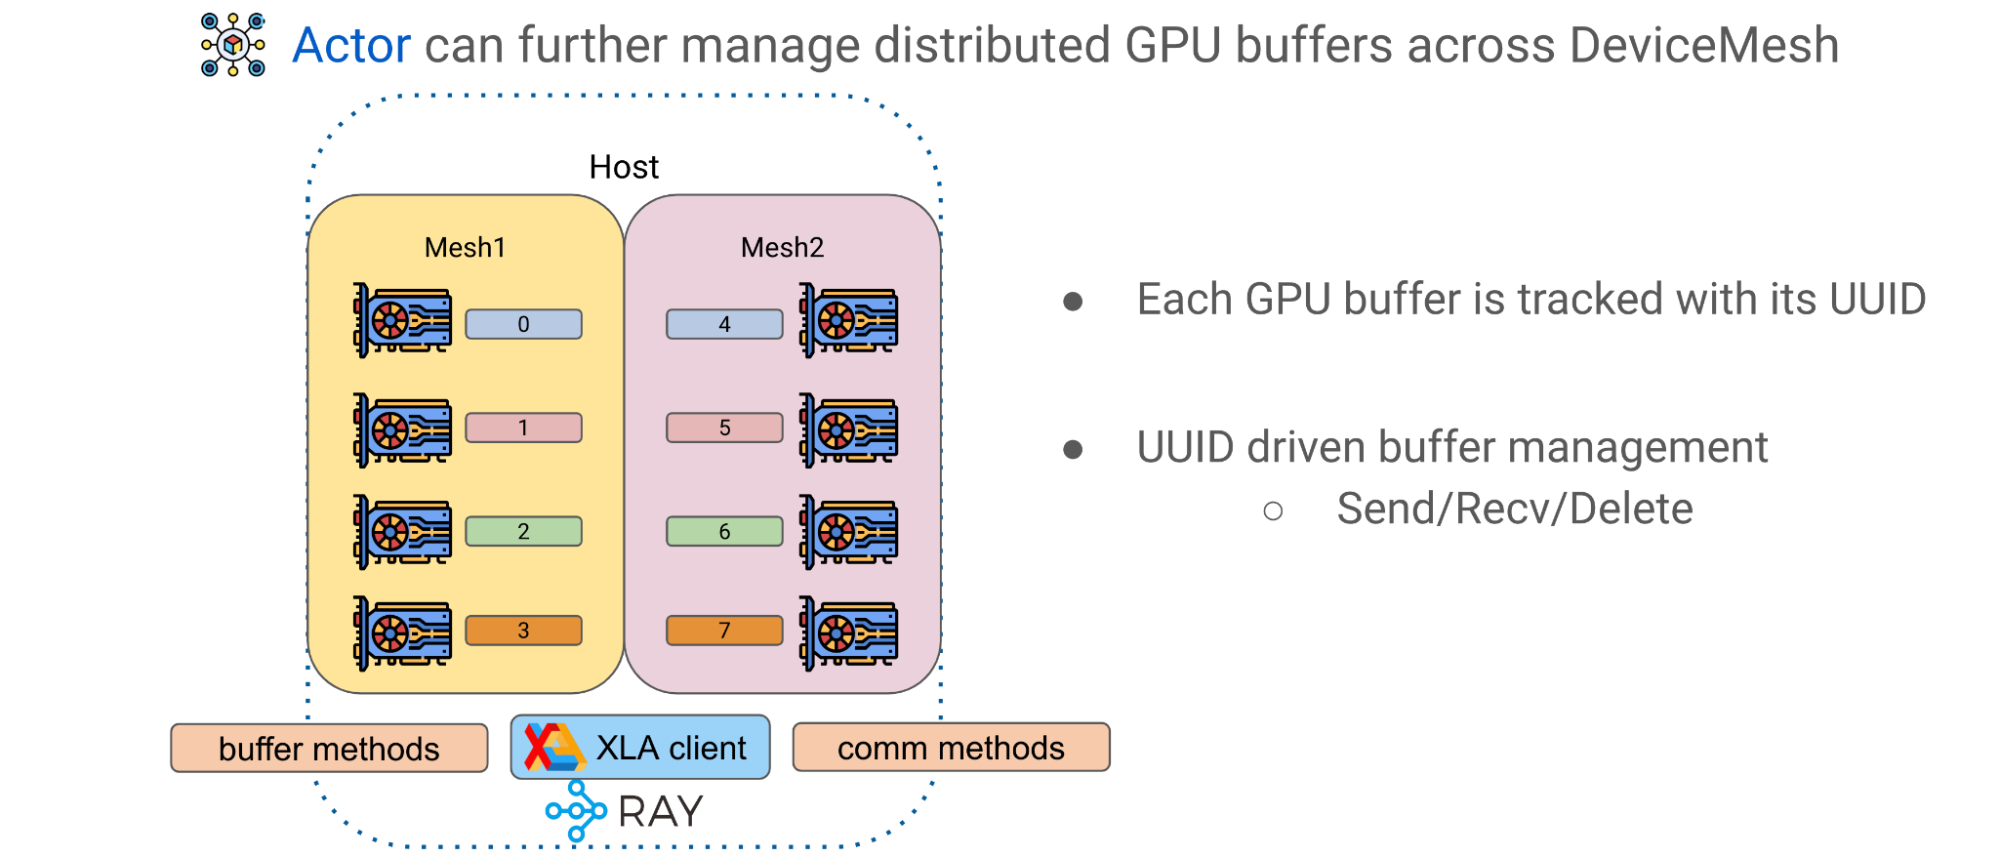
使用 Alpa 和 Ray 在大型 GPU 集群中高效扩展 LLM 训练 - NVIDIA 技术博客
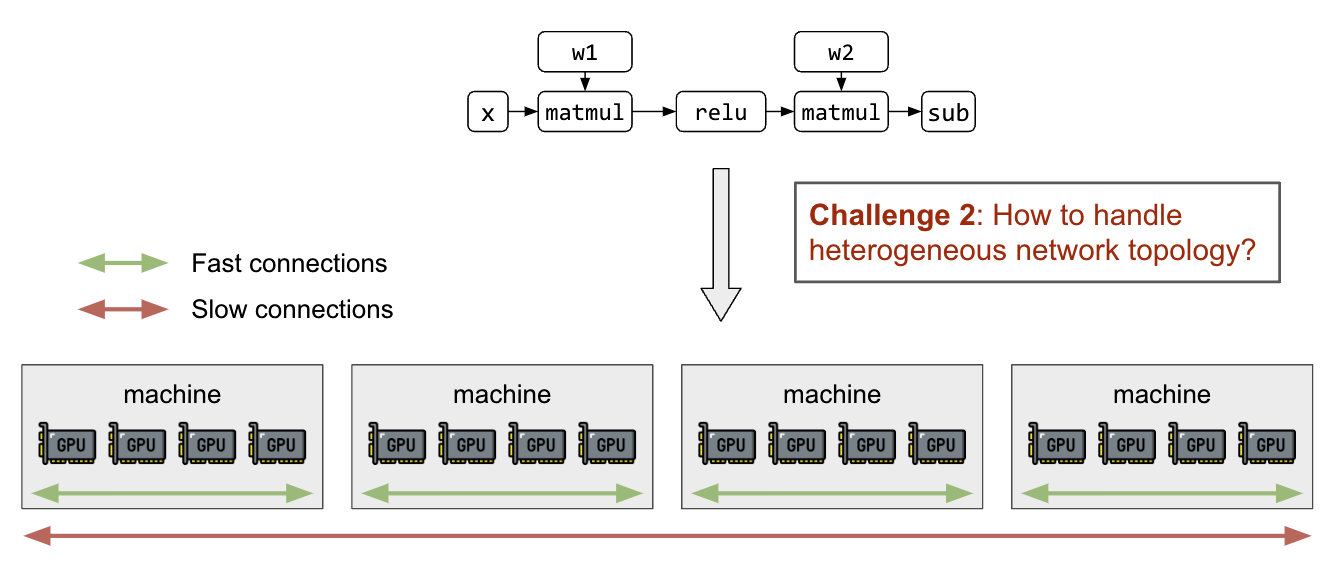
使用 Alpa 和 Ray 在大型 GPU 集群中高效扩展 LLM 训练 - NVIDIA 技术博客

Scaling Up Throughput-oriented LLM Inference Applications on ...

LLM 推理框架之上:10 种常见 LLM 推理系统总结_helix: distributed serving of large ...
H200 GPU Clusters: Ultimate LLM Training Guide

LLM 推理框架之上:10 种常见 LLM 推理系统总结_helix: distributed serving of large ...

Characterizing Software Aging in GPU-Based LLM Serving Systems This ...
Advertisement Space (336x280)

[论文评述] Characterizing and Optimizing LLM Inference Workloads on CPU-GPU ...
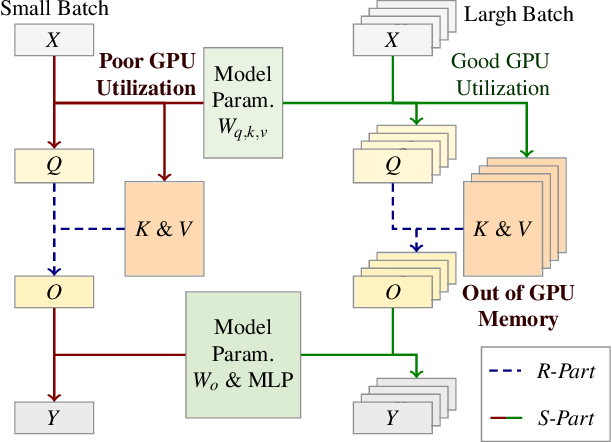
Figure 3 from FastDecode: High-Throughput GPU-Efficient LLM Serving ...
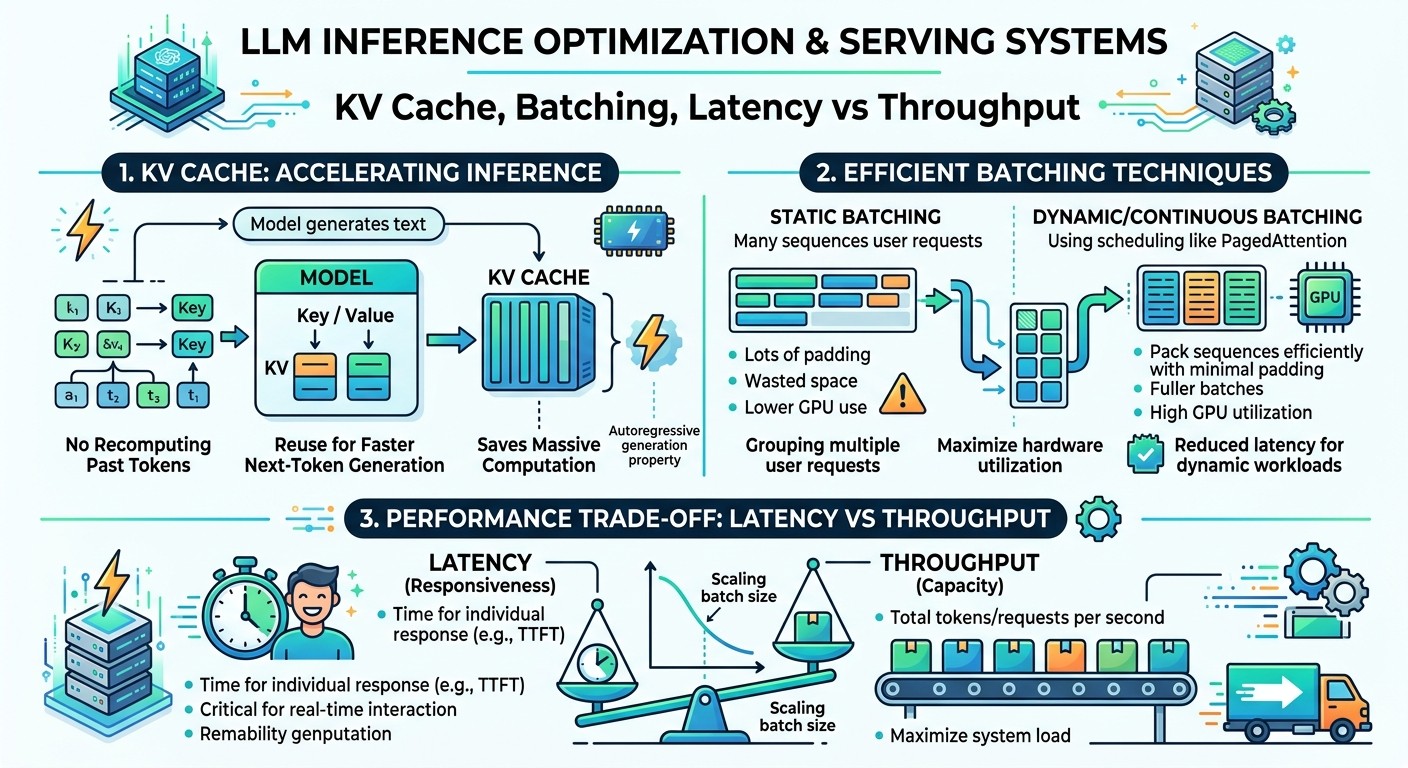
LLM Inference Optimization & Serving Systems – Billion Hopes
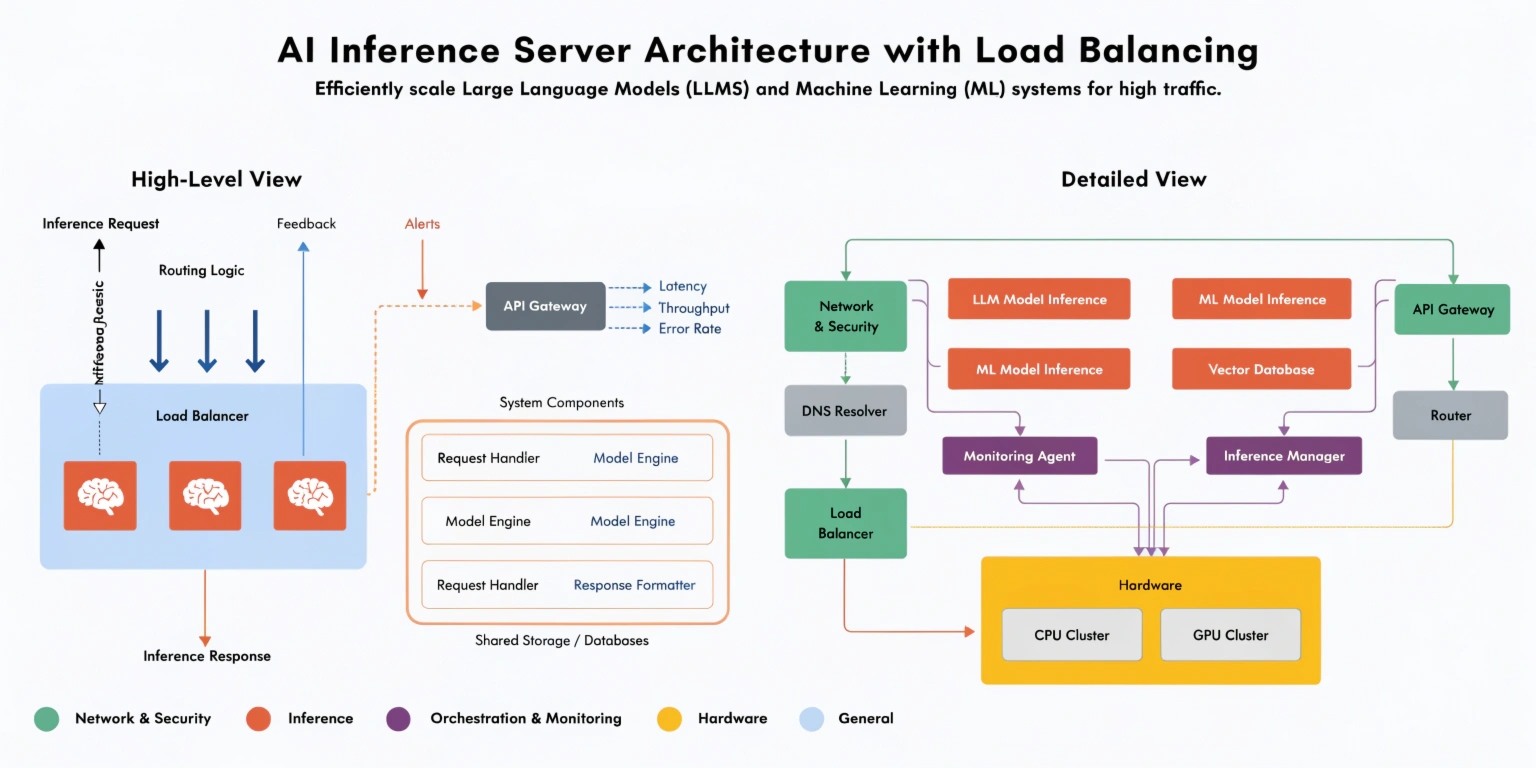
Load Balancing in AI Inference Servers | Scaling LLM, GPU Clusters ...

Efficiently Scale LLM Training Across a Large GPU Cluster with Alpa and ...
How to Calculate GPU Requirements for LLM Inference?