
Scalable Multi Model Llm Serving With Vllm And Nginx By Doil Kim Medium
Optimizing LLM Serving Speed with SGLang + Optuna + Hydra | by Doil Kim ...

Free Video: Scalable and Efficient LLM Serving With the VLLM Production ...

Deploy Large Language Model (LLM) with vLLM on K8s | by FiftyFive ...

Scale Open LLMs with vLLM Production Stack | by Shahrukh khan | Medium

Review of MLSys 2025 — LLM Model Serving Session | by Don Moon | Byte ...

Private, Scalable LLM Inference for Data Compliance: vLLM & SGLang | by ...

LLM Model Serving. Serving Large Language Models (LLMs)… | by Siddharth ...

12 vLLM Alternatives for Efficient and Scalable LLM Inference ...
Benchmarking LLM Serving Performance: A Comprehensive Guide | by Doil ...
Encoder Disaggregation for Scalable Multimodal Model Serving | vLLM Blog
Advertisement Space (300x250)

Unlocking Enterprise AI with Gaudi 3: Model Serving and Fine-Tuning at ...
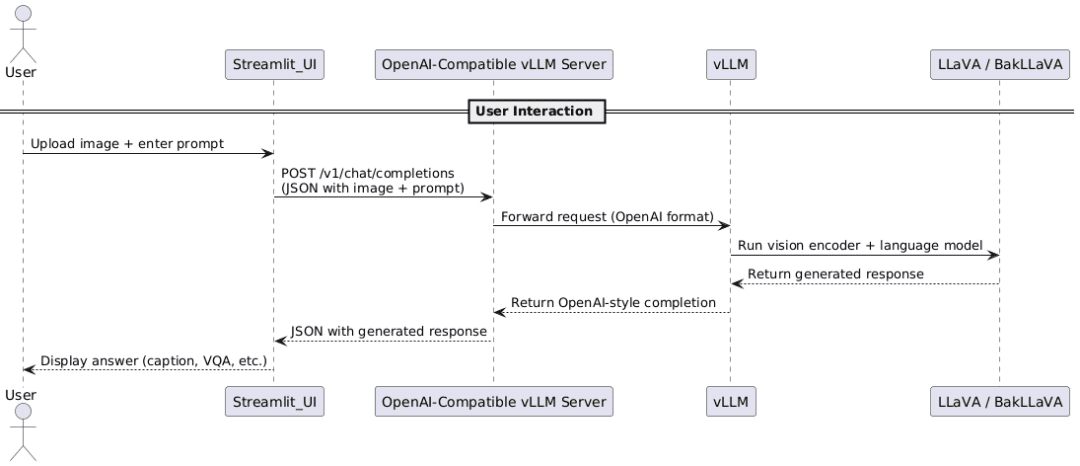
The Rise of Multimodal LLMs and Efficient Serving with vLLM - PyImageSearch
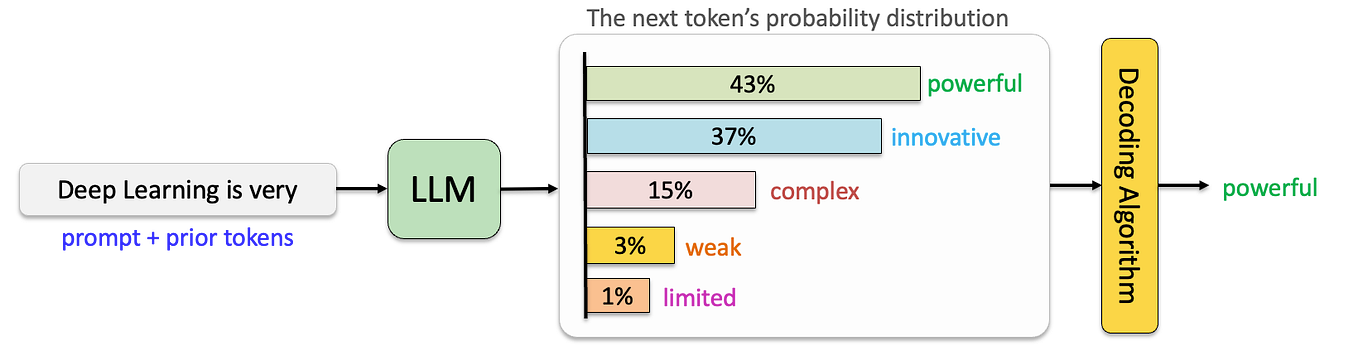
LLM Multi-GPU Batch Inference With Accelerate | by Victor May | Medium

LLM by Examples — vLLM Overview. vLLM, or virtual large language model ...
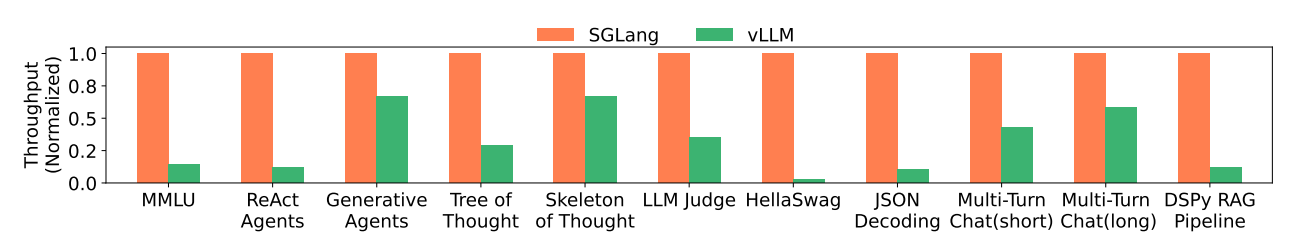
LLM by Examples — vLLM Overview. vLLM, or virtual large language model ...
Benchmarking LLM Serving Performance: A Comprehensive Guide | by Doil ...

Beyond the Model: How vLLM Powers Enterprise-Scale LLM Serving | by ...

Deploy Large Language Model (LLM) with vLLM on K8s | by FiftyFive ...
The Rise of Multimodal LLMs and Efficient Serving with vLLM ...

Multi-Node LLM Serving Using sig LWS and vLLM - CECG
Advertisement Space (336x280)
Can vllm serving clients by using multiple model instances? · Issue ...

Comparing two LLM serving frameworks: Friendli Engine vs. vLLM | by ...
Model Quantization with 🤗 Hugging Face Transformers and Bitsandbytes ...
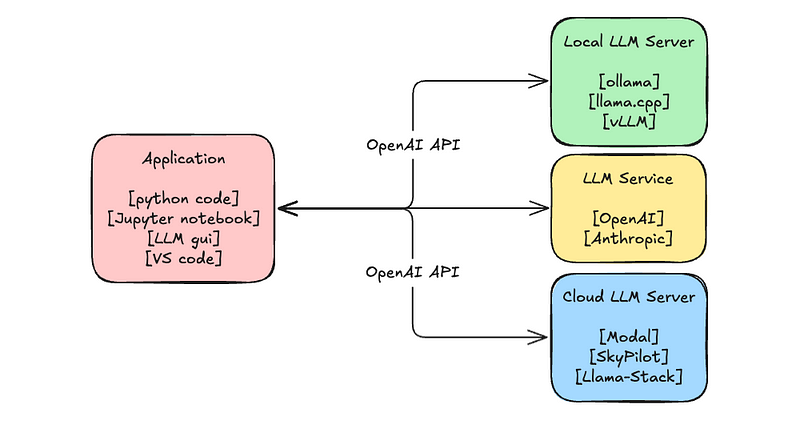
LLM Deployment with vLLM. In the rapidly evolving landscape of… | by ...

Serving Models with Ray Serve. Serving Models with Ray Serve | by Shaun ...

How vLLM solves LLM serving issues for AI apps | Aaroh Bhardwaj posted ...
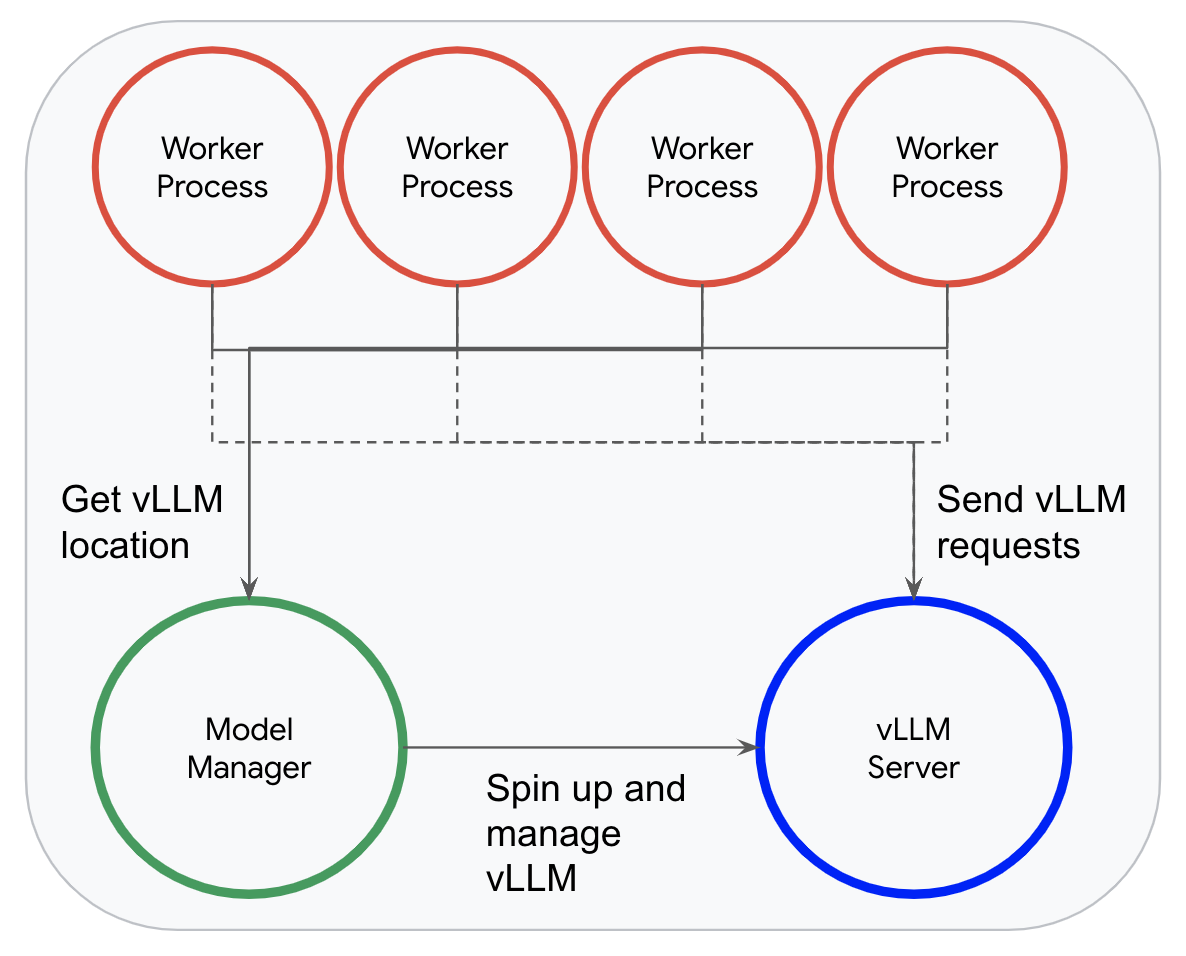
Inference with Gemma using Dataflow and vLLM - Google Developers Blog

Customize vLLM with plugins, not forks: a guide by AWS SageMaker | vLLM ...
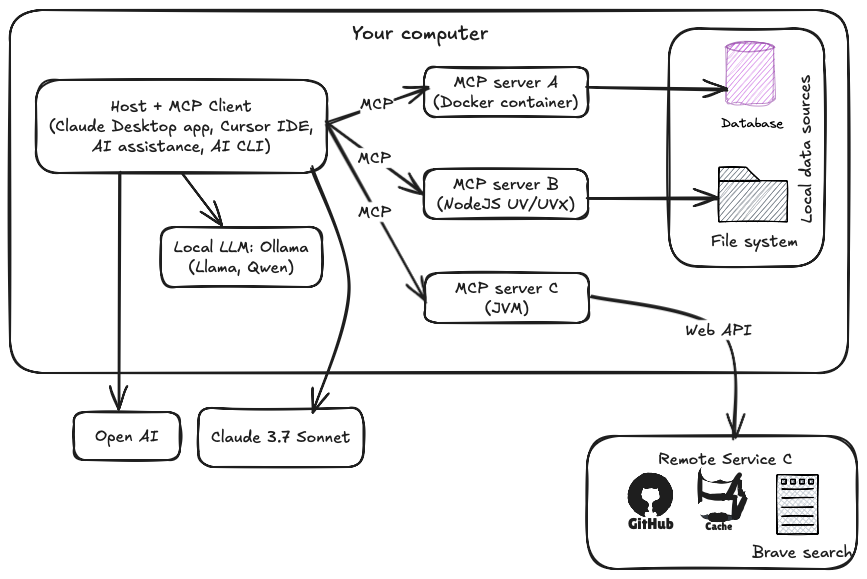
LLM Inference with vLLM, Cloud Run and GCS | Google Cloud - Community

Install vLLM on Linux for Production LLM Serving (2026 Guide)
Advertisement Space (336x280)

Guide to Handle Multiple Concurrent LLM Requests with vLLM
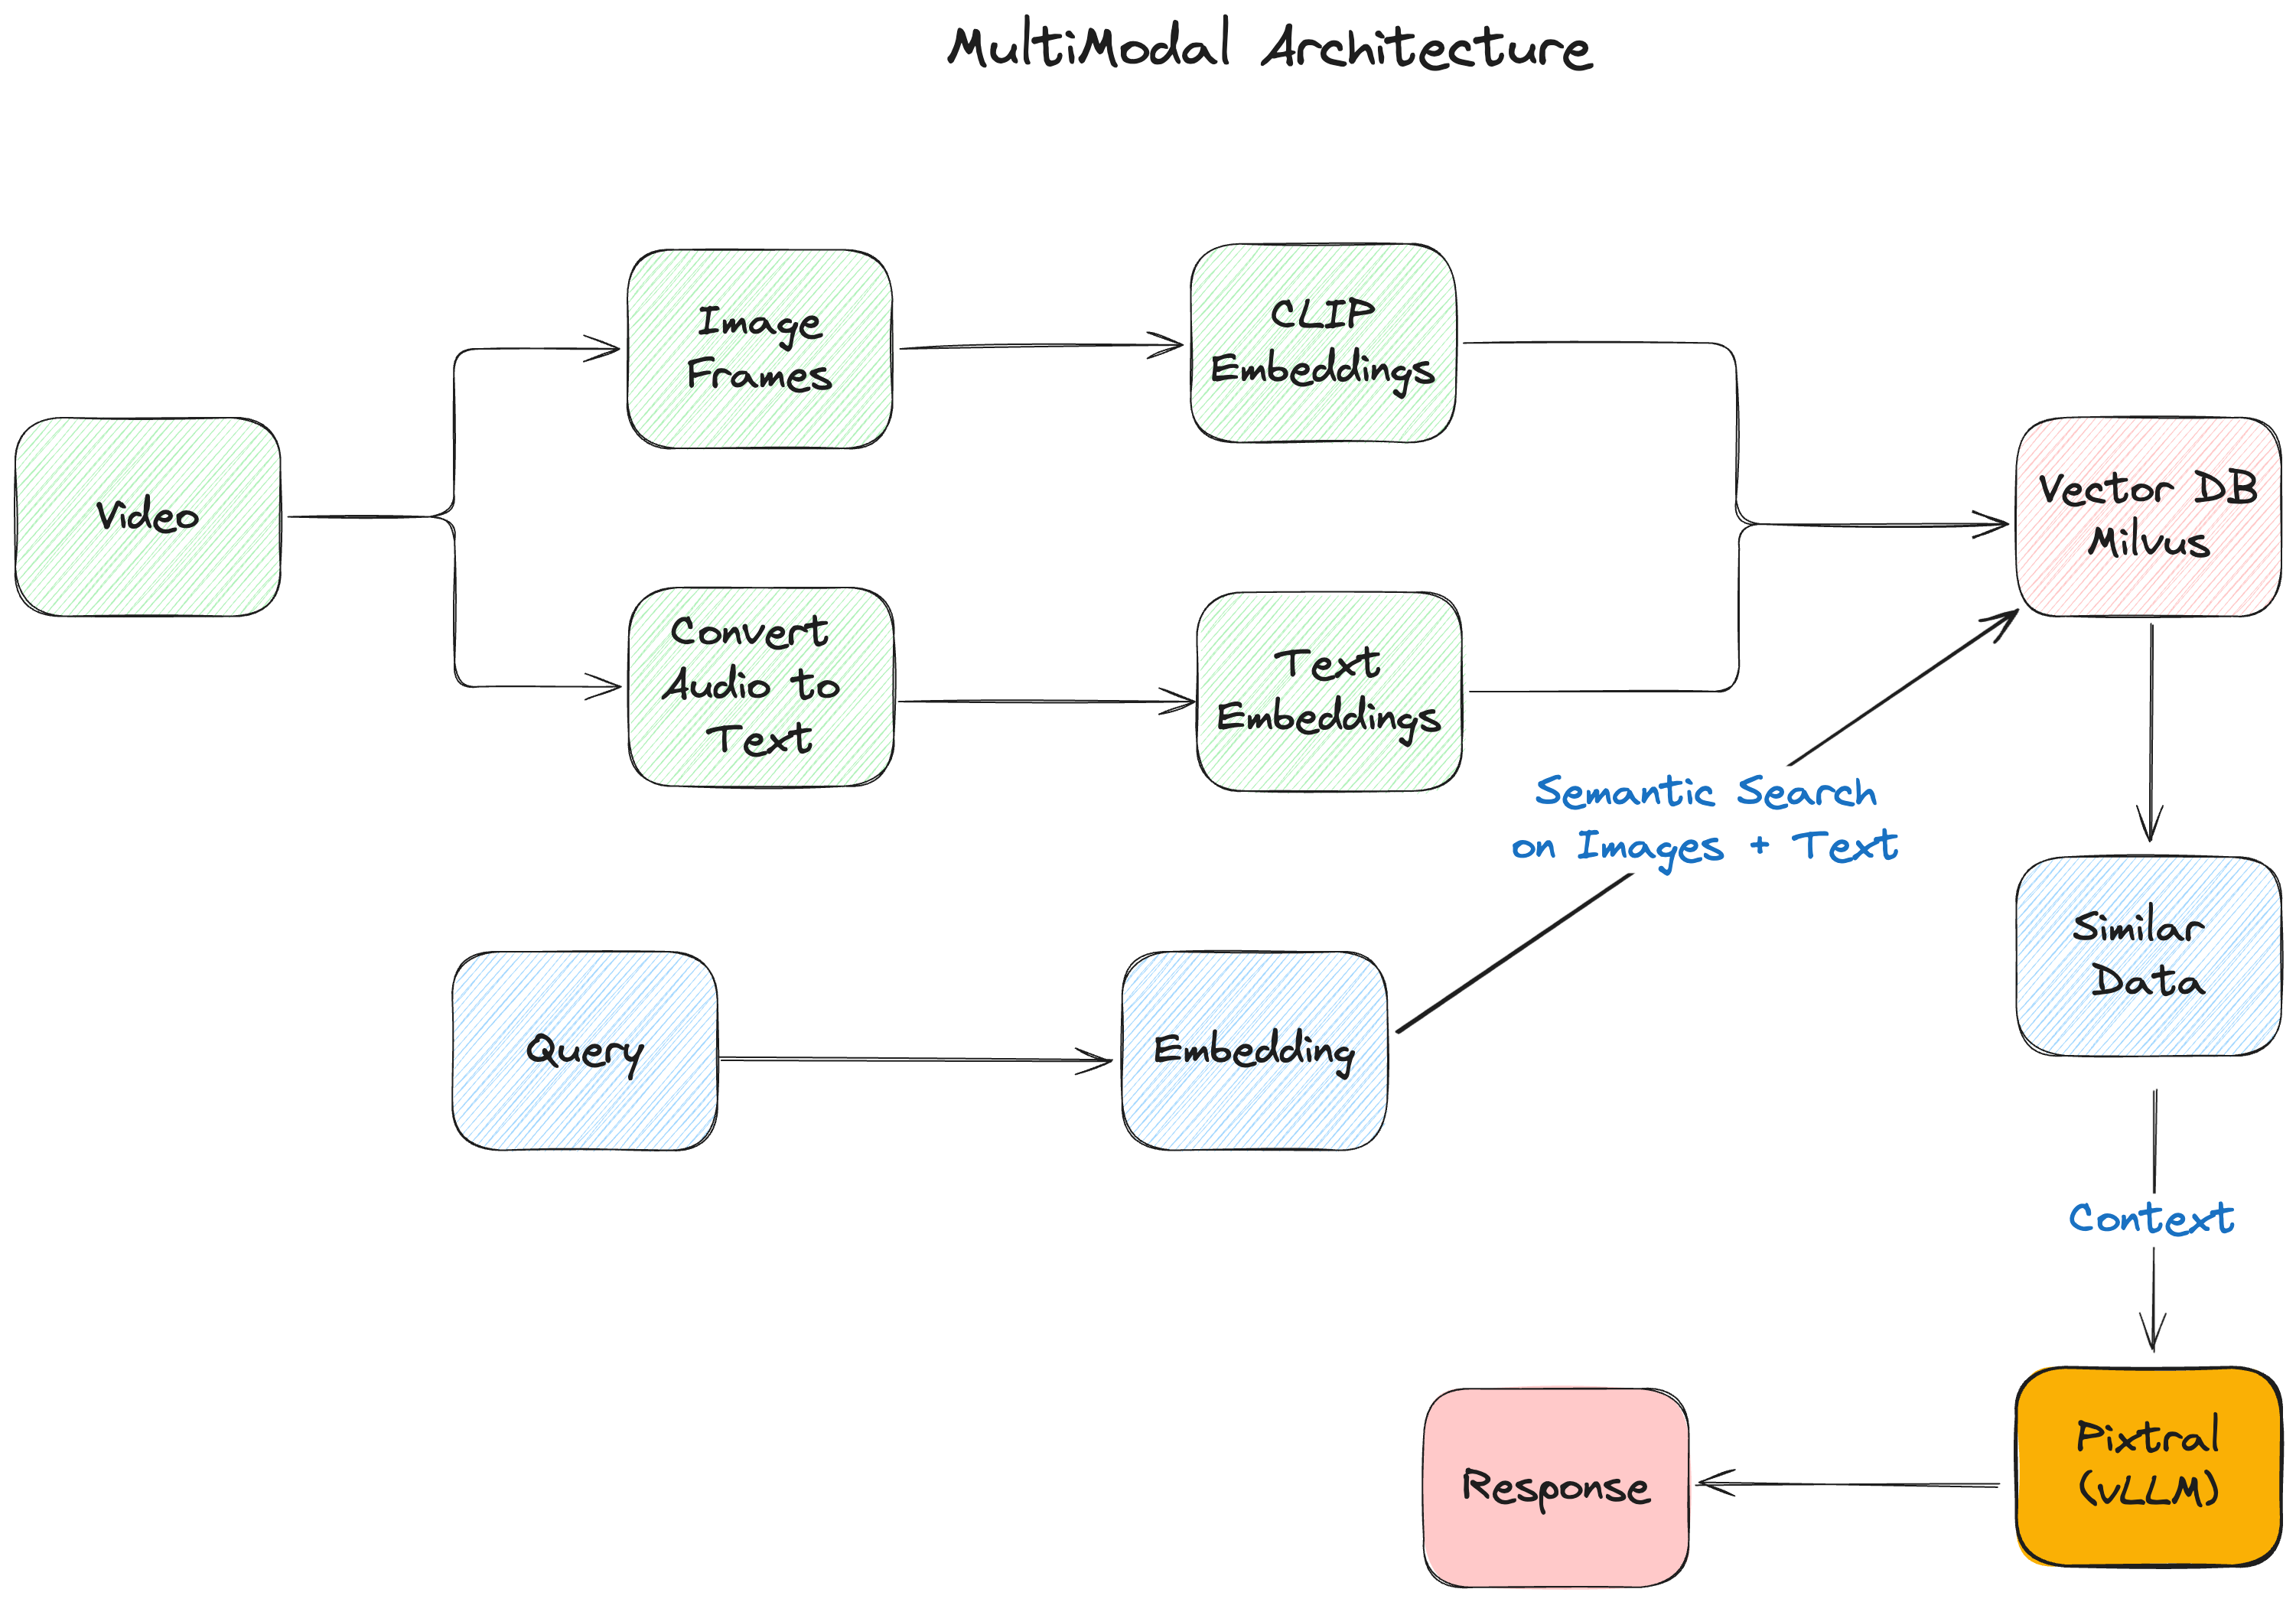
Deploying a Multimodal RAG System with vLLM and Milvus - Zilliz blog
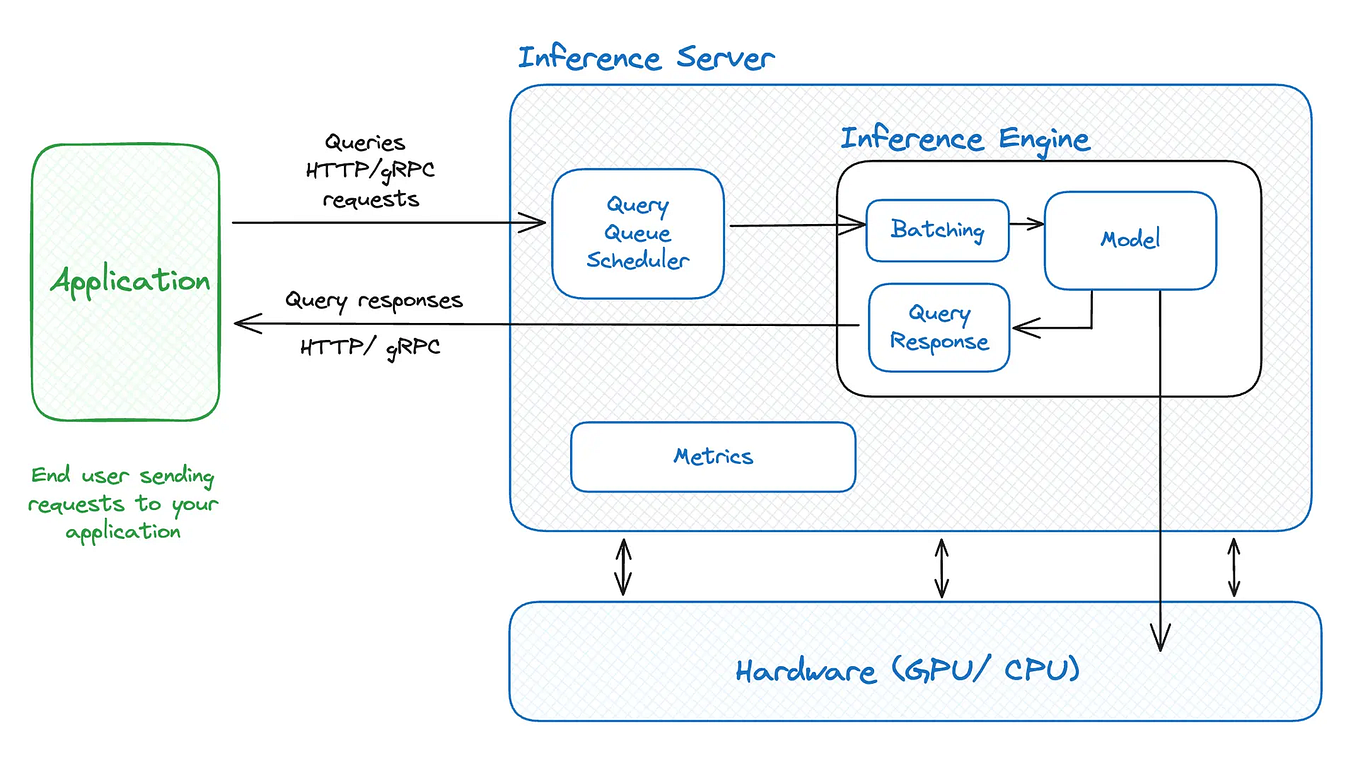
LLM Deployment with vLLM. In the rapidly evolving landscape of… | by ...

UELLM: A Unified and Efficient Approach for LLM Inference Serving | AI ...

Comparing two LLM serving frameworks: Friendli Inference vs. vLLM