
Serve Nlp Ml Models Using Accelerated Inference Api

Serve NLP ML Models using Accelerated Inference API

Serve NLP ML Models using Accelerated Inference API » ayoubb
Real time ML inference routing using an API Gateway | by Sridhar ...
Deploy a Serverless ML Inference Using FastAPI, AWS Lambda, and API Gateway
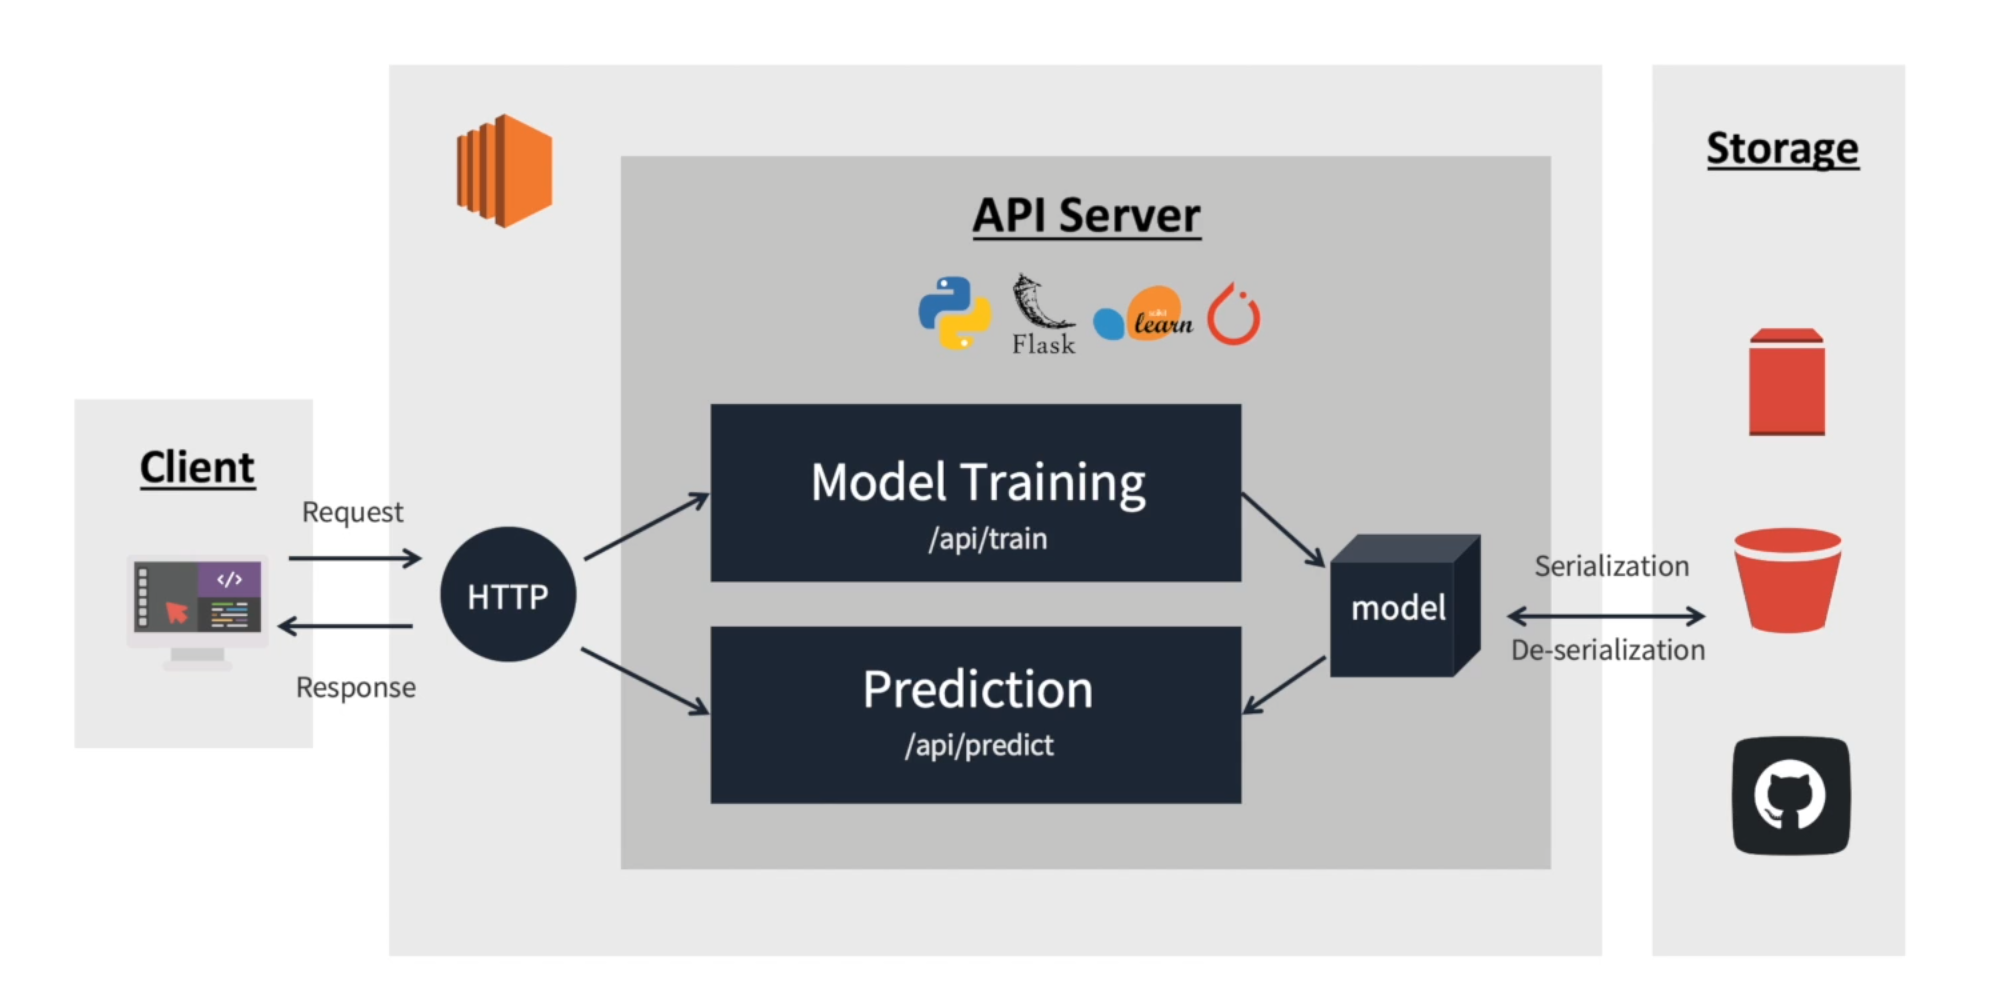
클라우드를 활용한 머신러닝 모델 Serving API 개발 3 : API to serve ML model
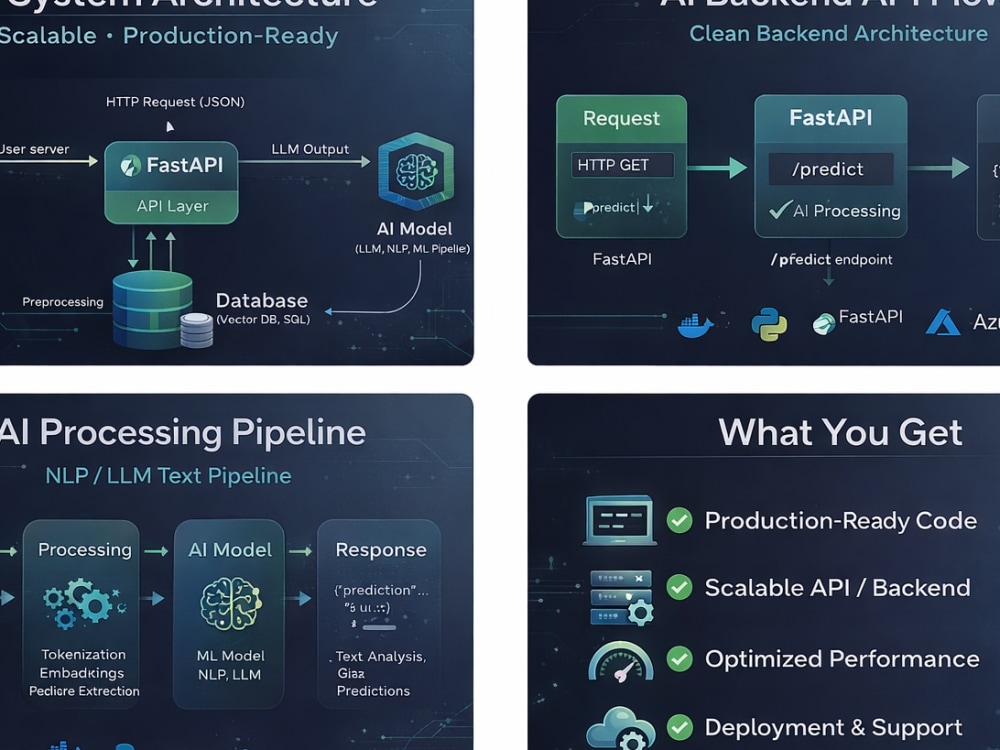
I will build AI apps using LLM, FastAPI, NLP and ML pipelines | Upwork

Inference API: The easiest way to integrate NLP models for inference ...

Building a state-of-the-art ML inference API endpoint | by CODIMITE ...
GitHub - bentoml/transformers-nlp-service: Online Inference API for NLP ...
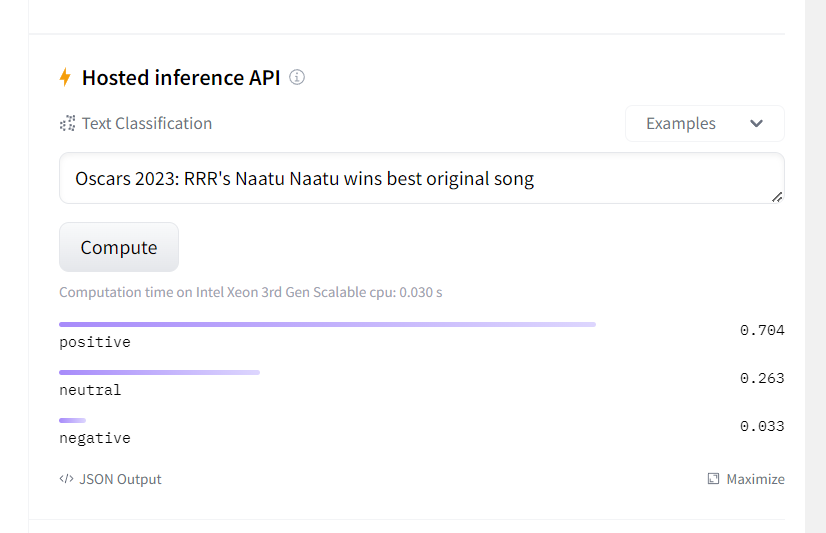
Inference API: The easiest way to integrate NLP models for inference ...
Advertisement Space (300x250)
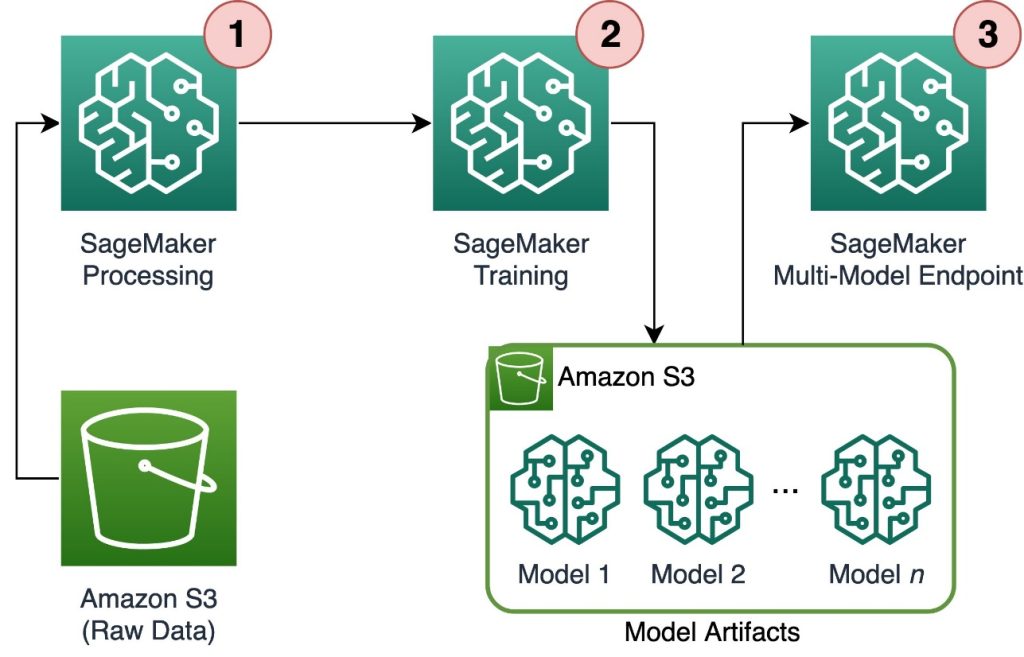
Scale training and inference of thousands of ML models with Amazon ...

Deploy a serverless ML inference endpoint of large language models ...

A guide to using the Azure AI model inference API | ML-NEWS2 – Weights ...

A guide to using the Azure AI model inference API | ML-NEWS2 – Weights ...
Deploying the AI Comic Factory using the Inference API

Improved ML model deployment using Amazon SageMaker Inference ...

Run ML inference on unplanned and spiky traffic using Amazon SageMaker ...

A guide to using the Azure AI model inference API | ML-NEWS2 – Weights ...
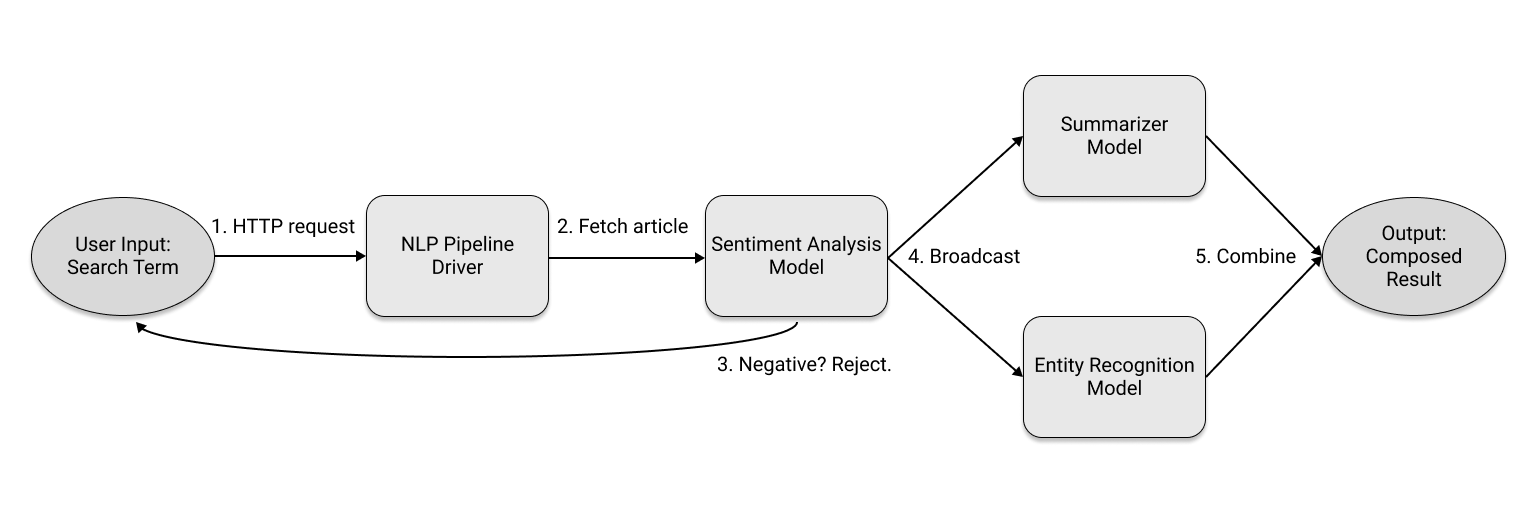
Online Inference with Ray Serve - Learning Ray - Flexible Distributed ...

NVIDIA NIM Microservices for Accelerated AI Inference | NVIDIA
Advertisement Space (336x280)
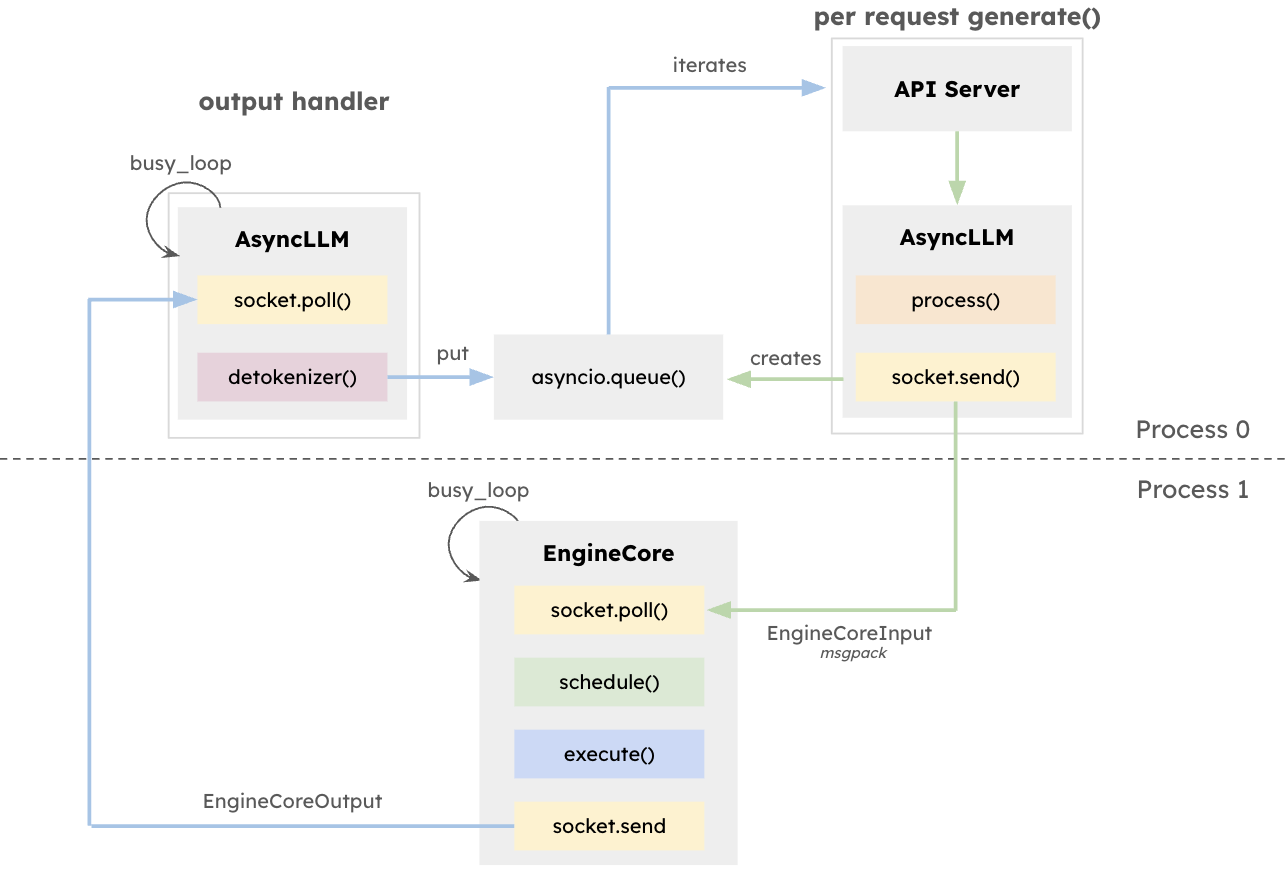
Inference Deep Dive: How To Serve Inference Faster With – RJUOJI
Accelerated AI Inference with NVIDIA NIM on Azure AI Foundry | NVIDIA ...
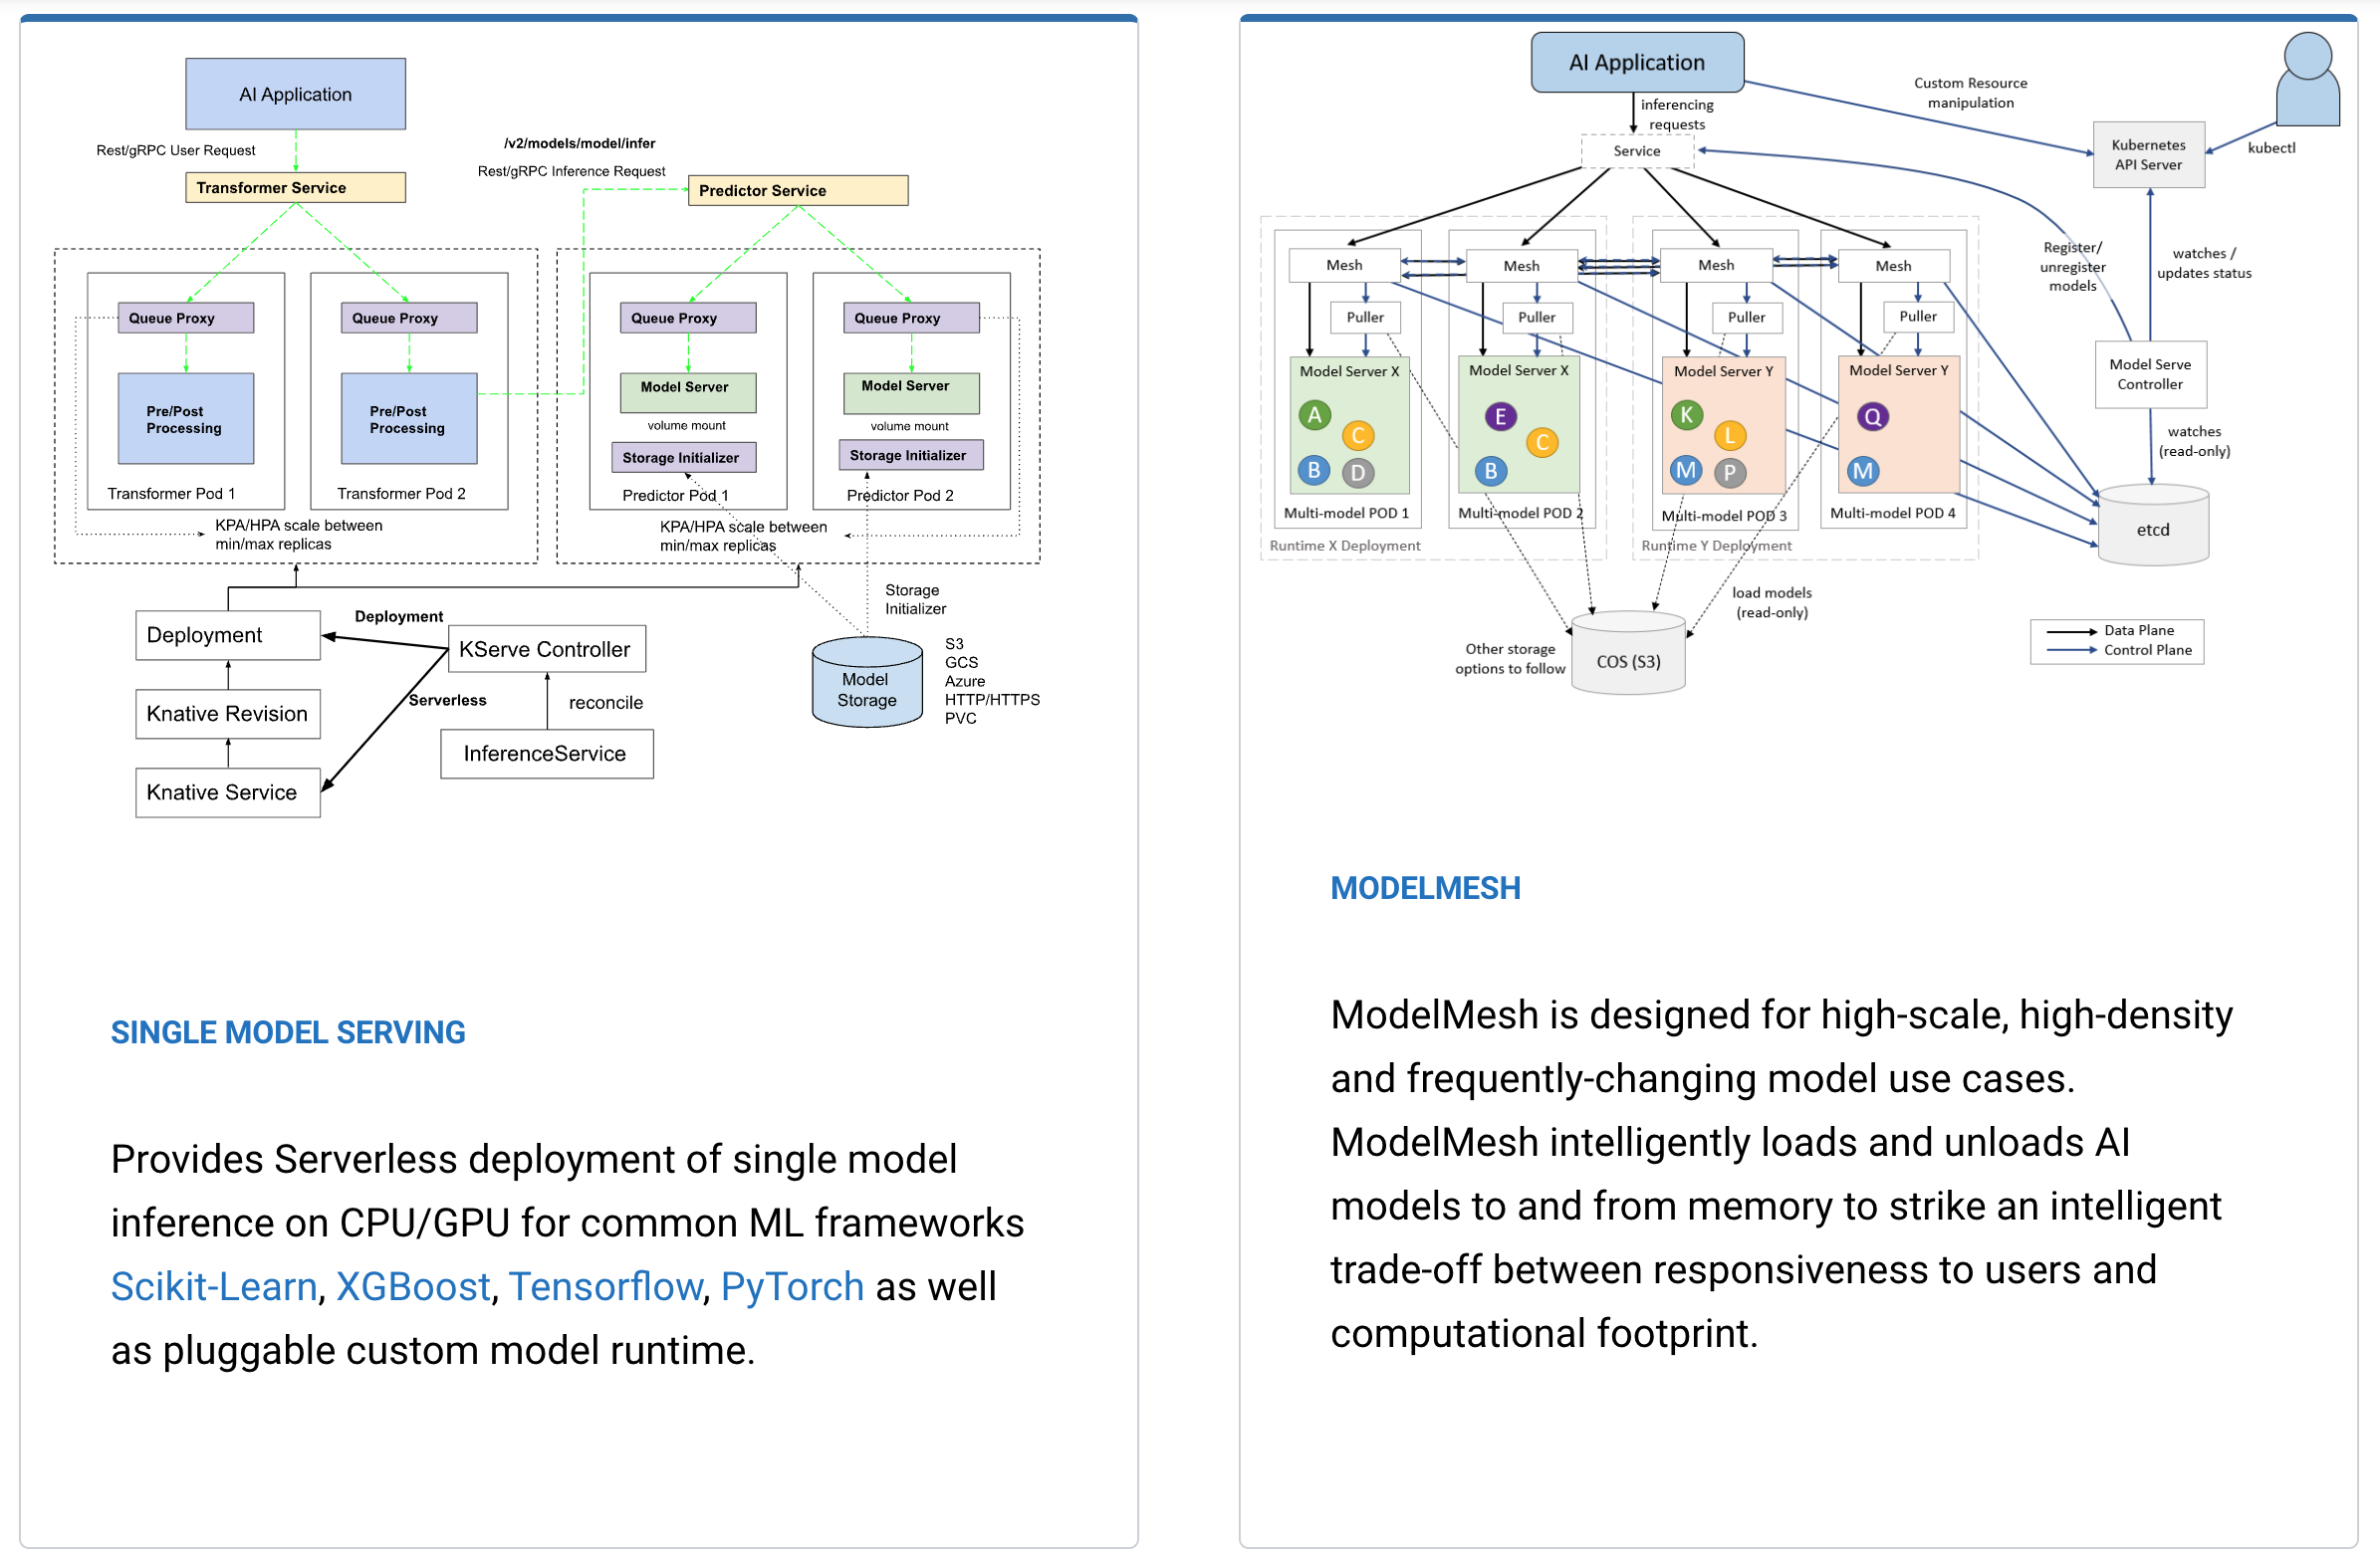
Text Generation Inference for Foundation Models | Niklas Heidloff
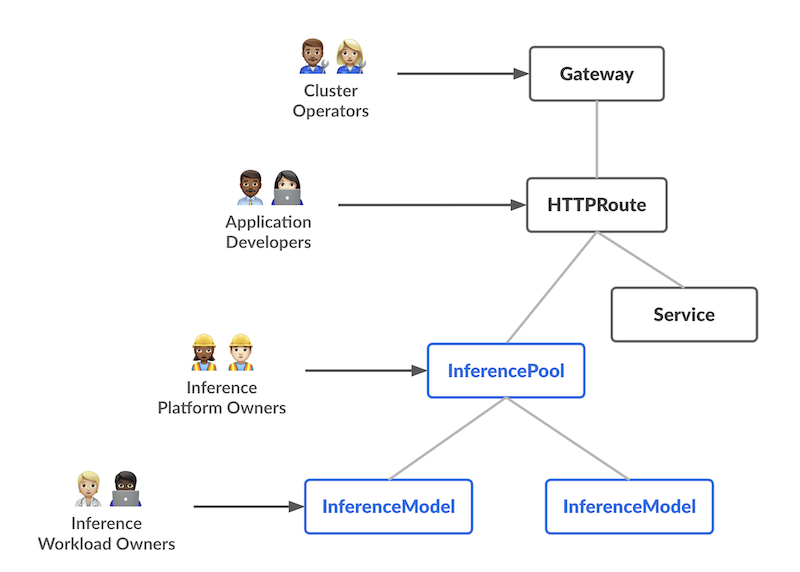
Introducing Gateway API Inference Extension | Kubernetes

[논문] LLMLingua: Compressing Prompts for Accelerated Inference of Large ...
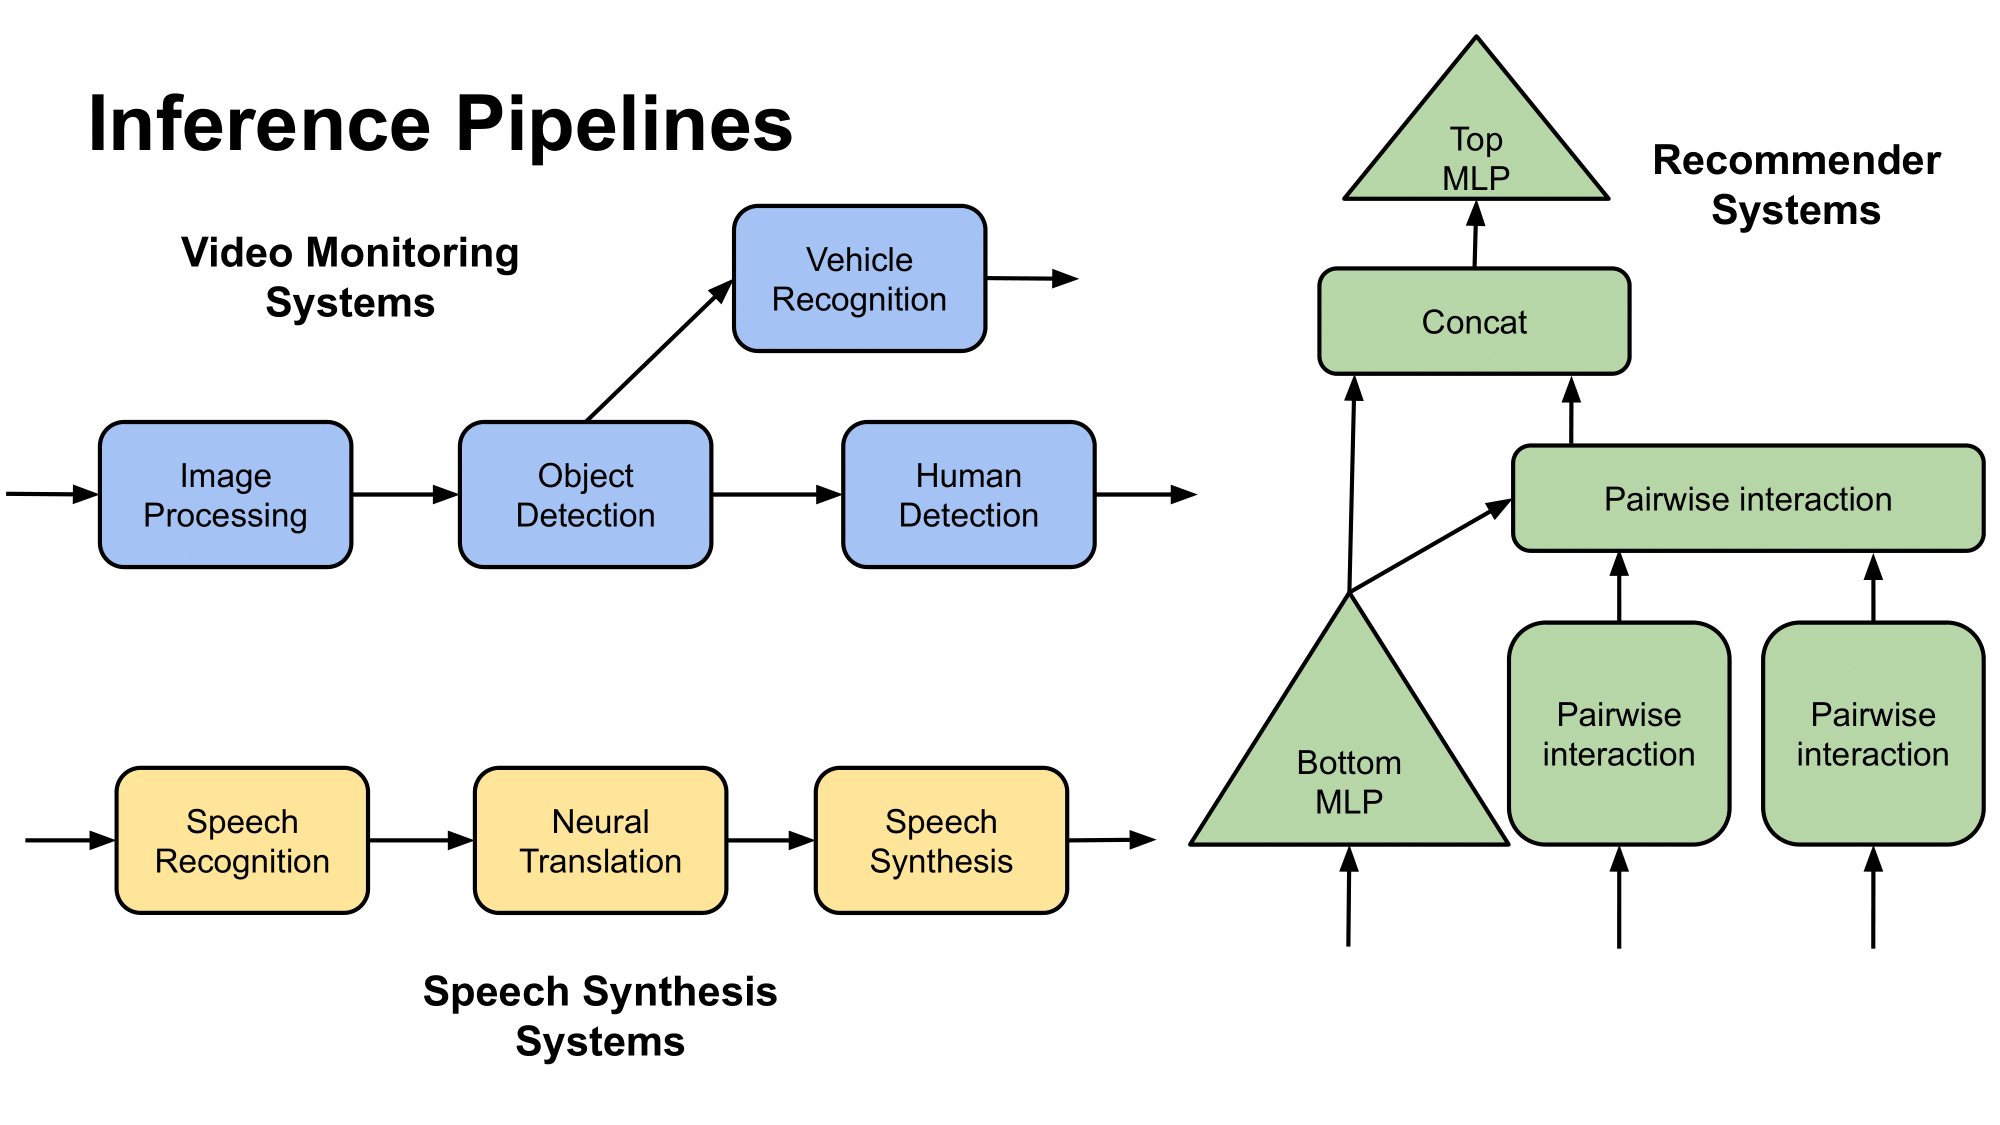
Optimizing Production ML Inference for Accuracy and Cost Efficiency ...
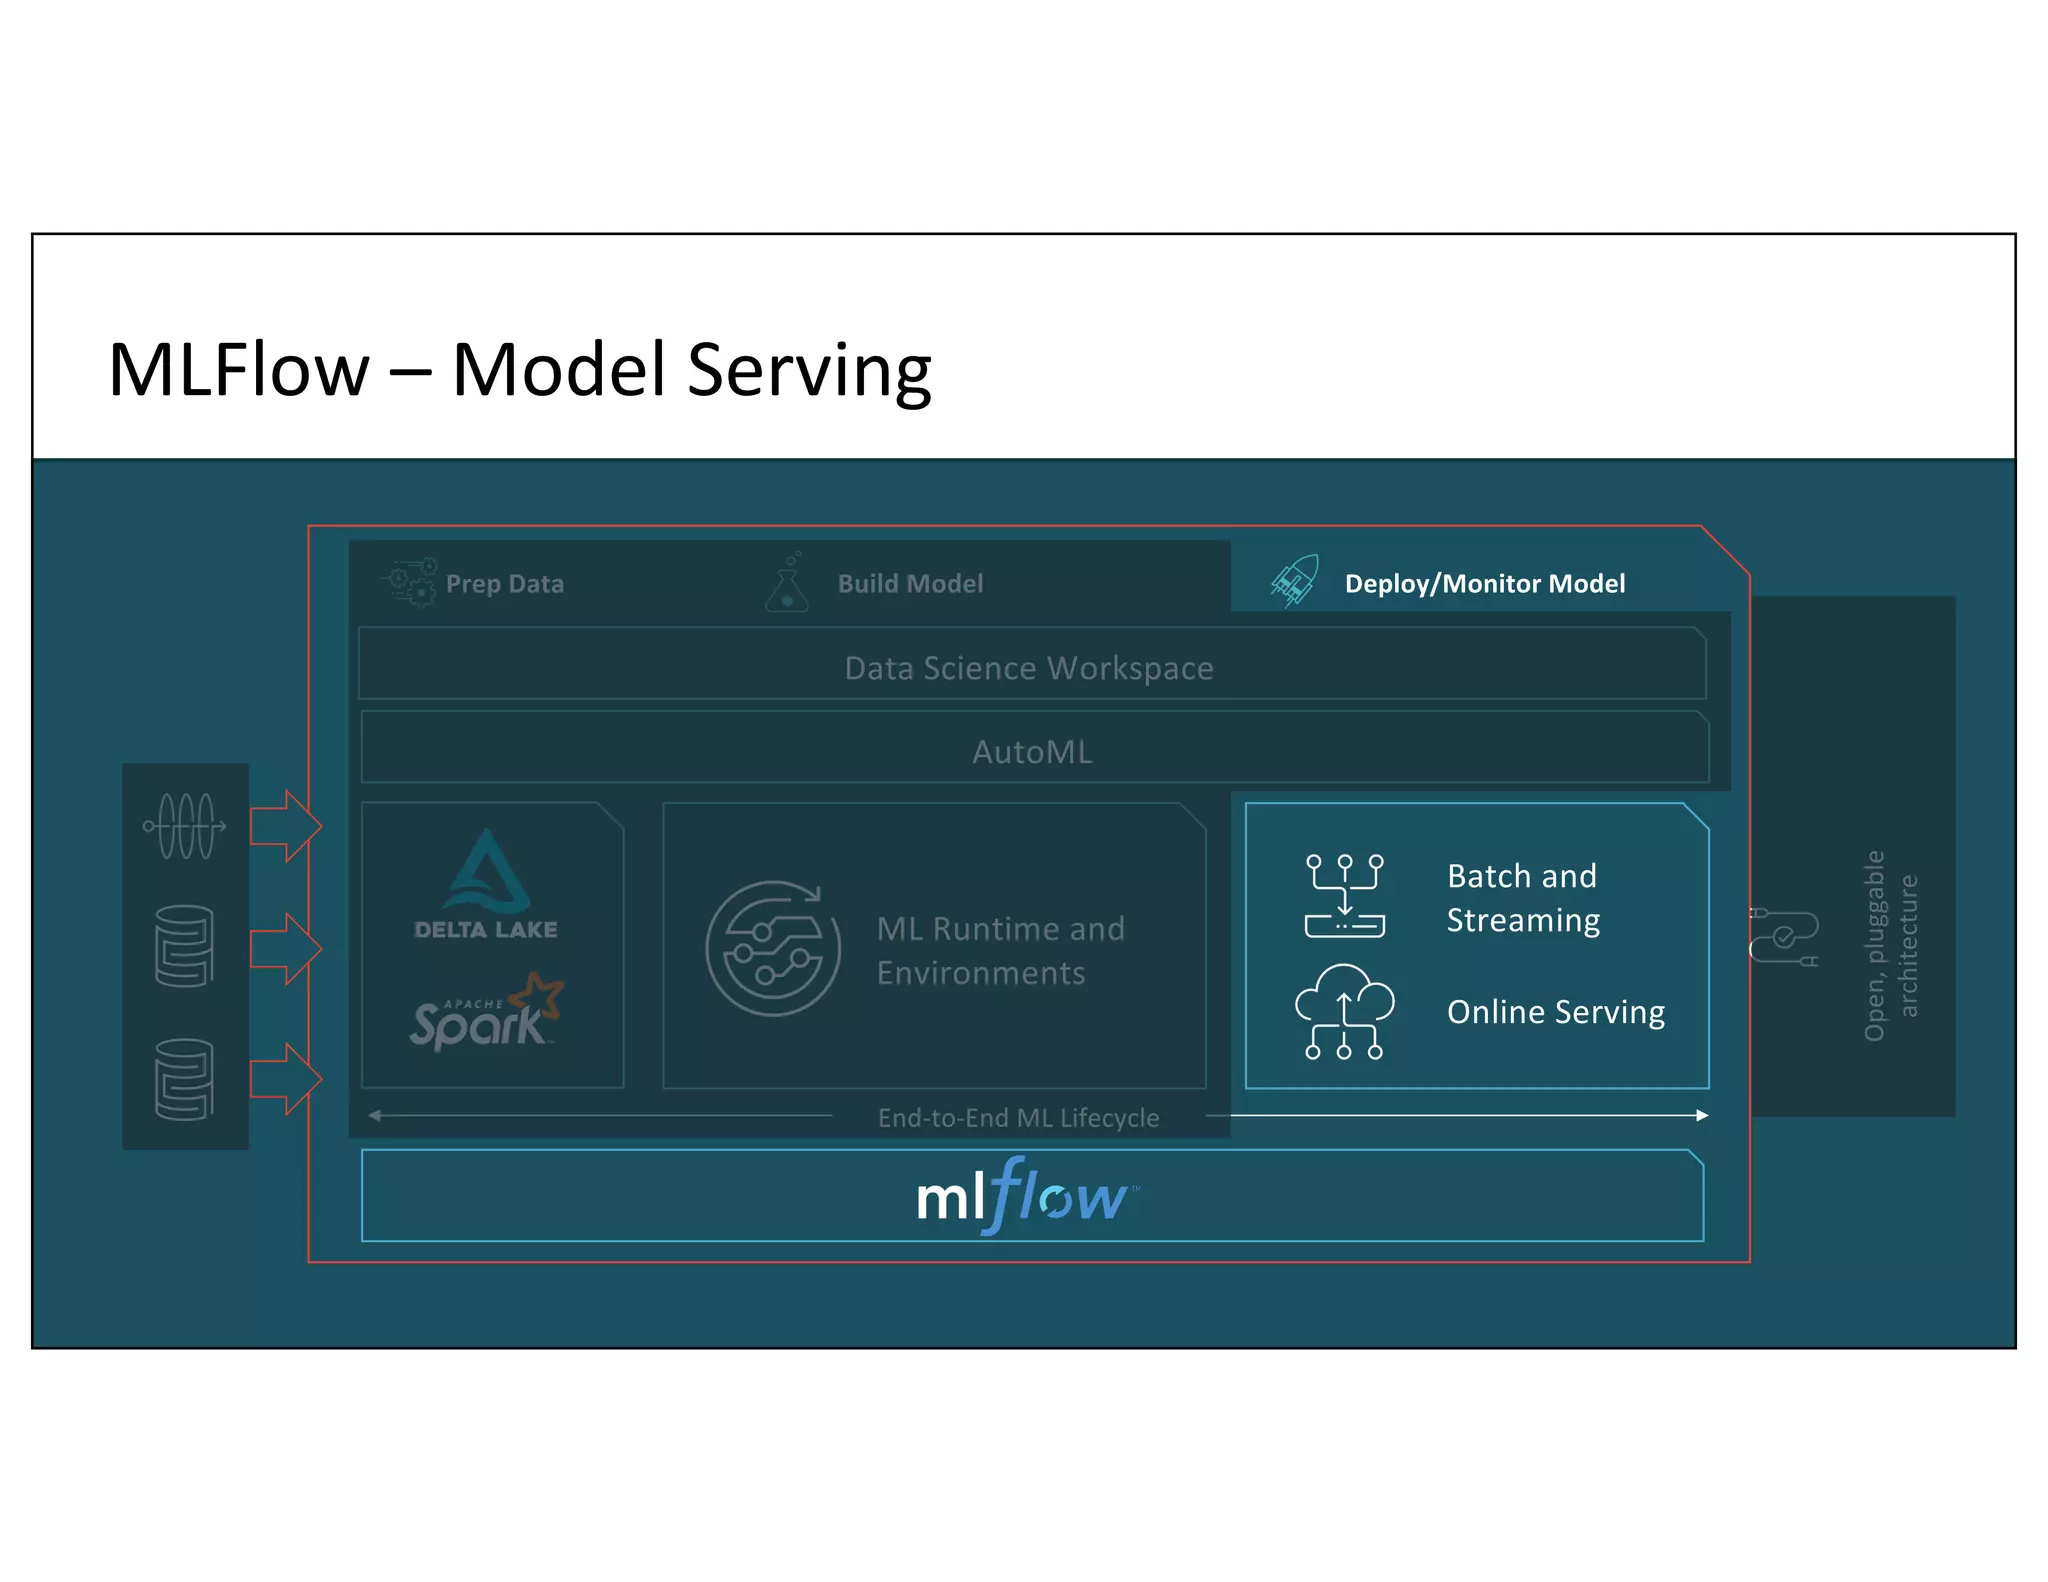
Productionzing ML Model Using MLflow Model Serving | PPT
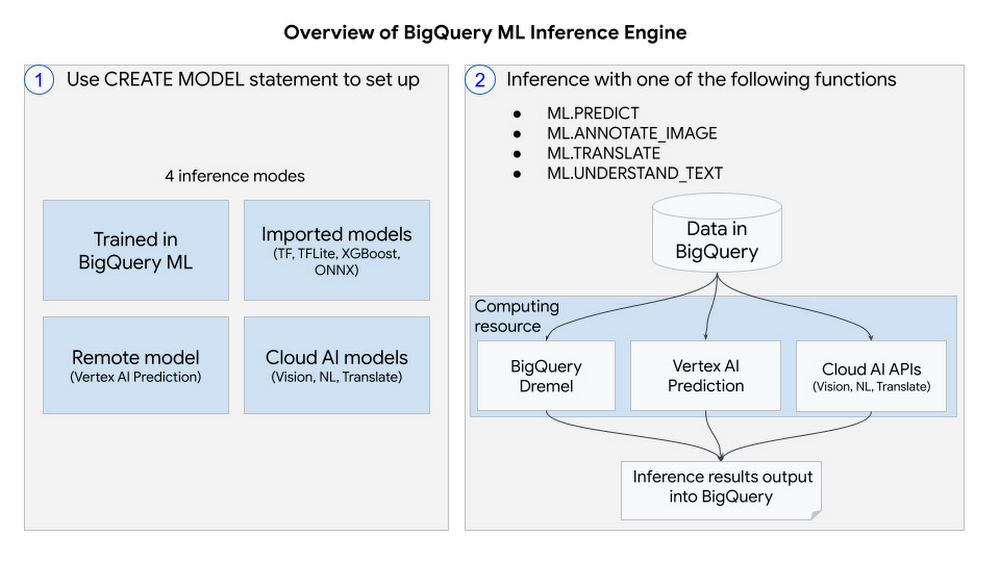
Announcing new BigQuery inference engine to bring ML closer to your ...
Serving Machine Learning Models at Scale: A Guide to Inference ...
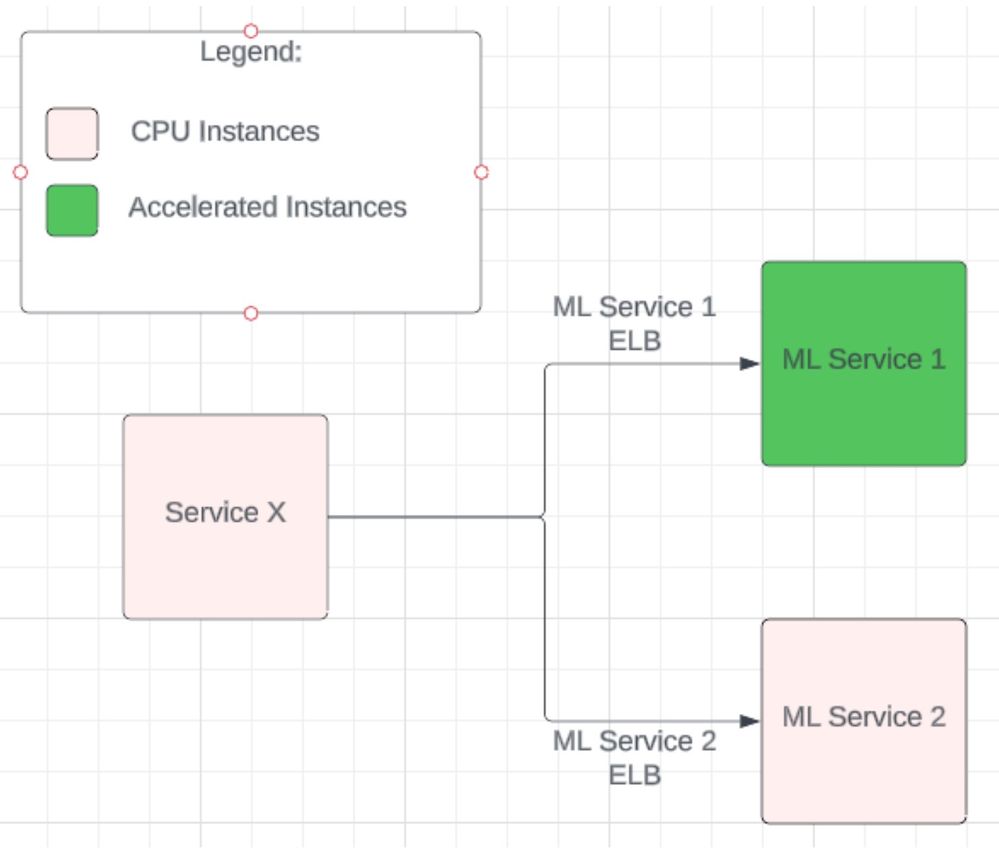
ML inference workloads on the Triton Inference Server | Palo Alto Networks
Advertisement Space (336x280)
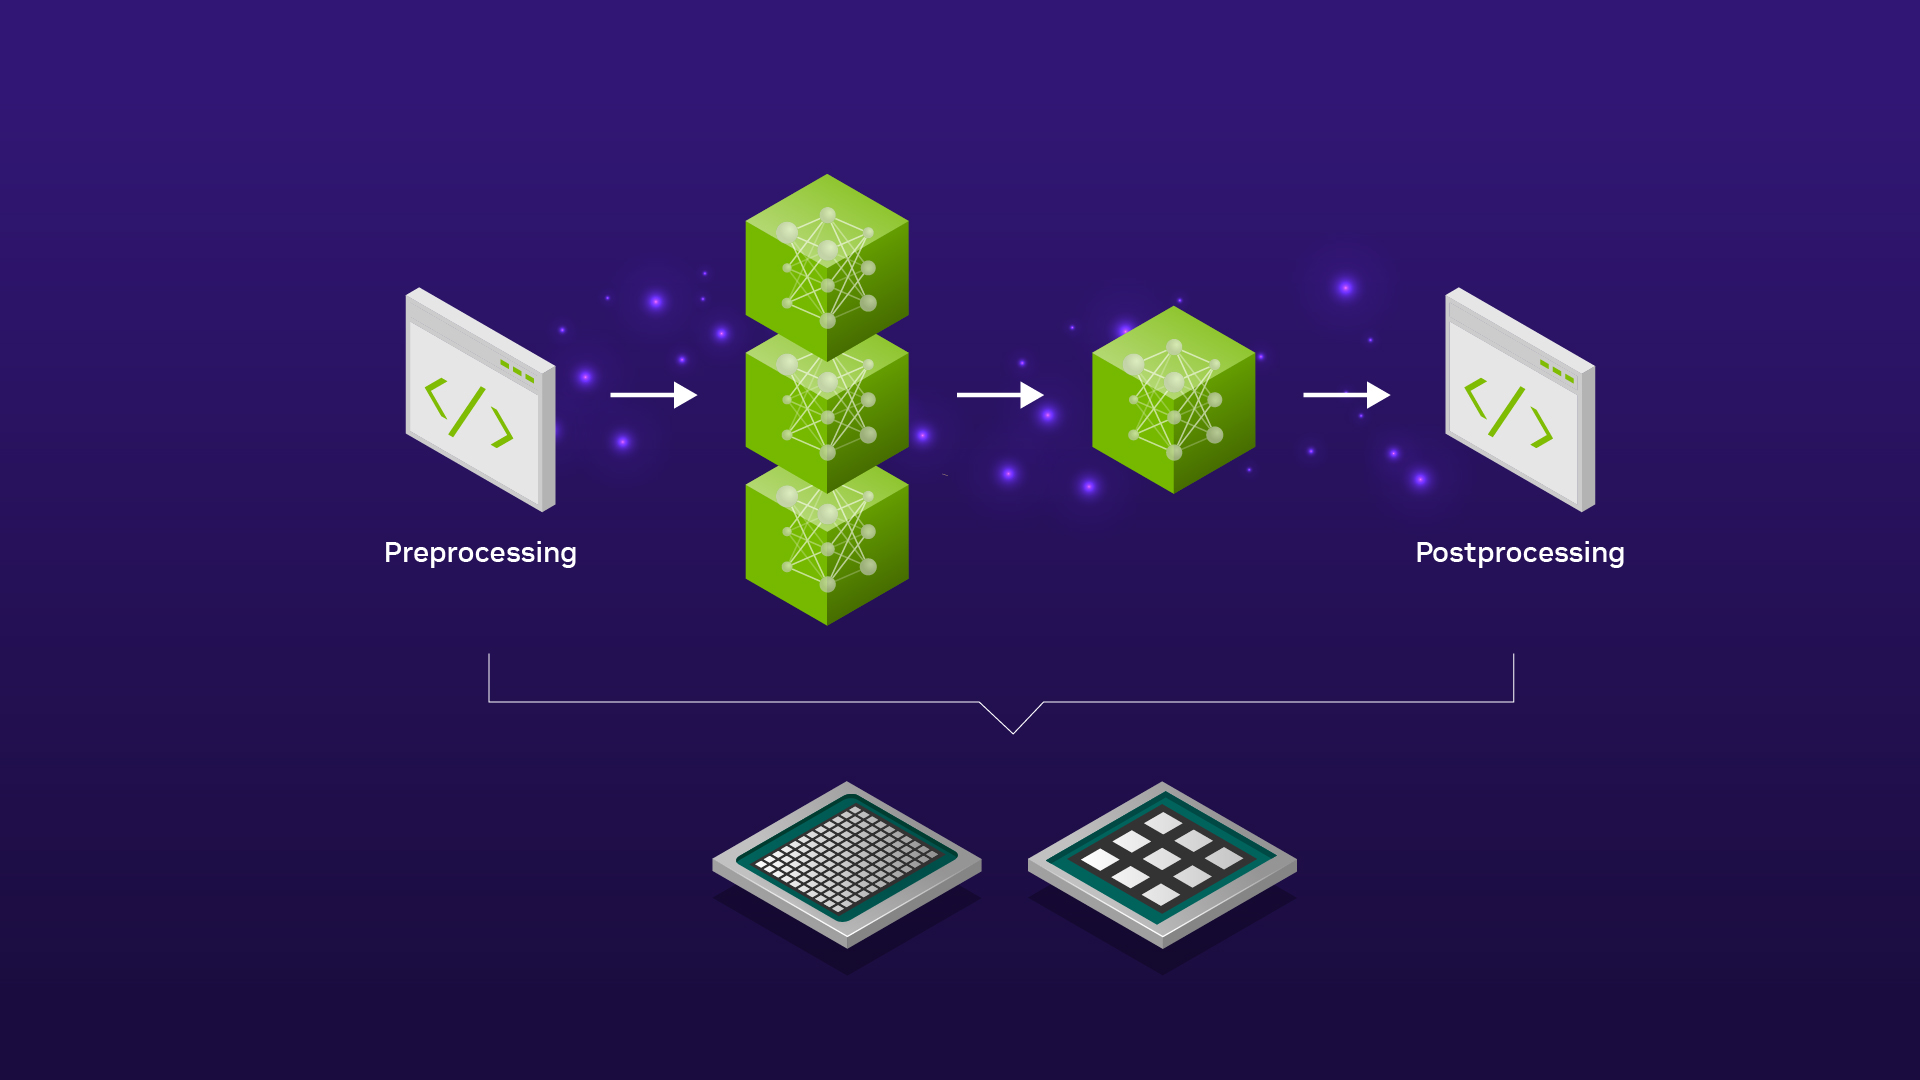
Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...

Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...

Pipeline AI - Effortless Production of ML Models with Serverless GPU ...
Model Inference & Privacy Attacks in ML
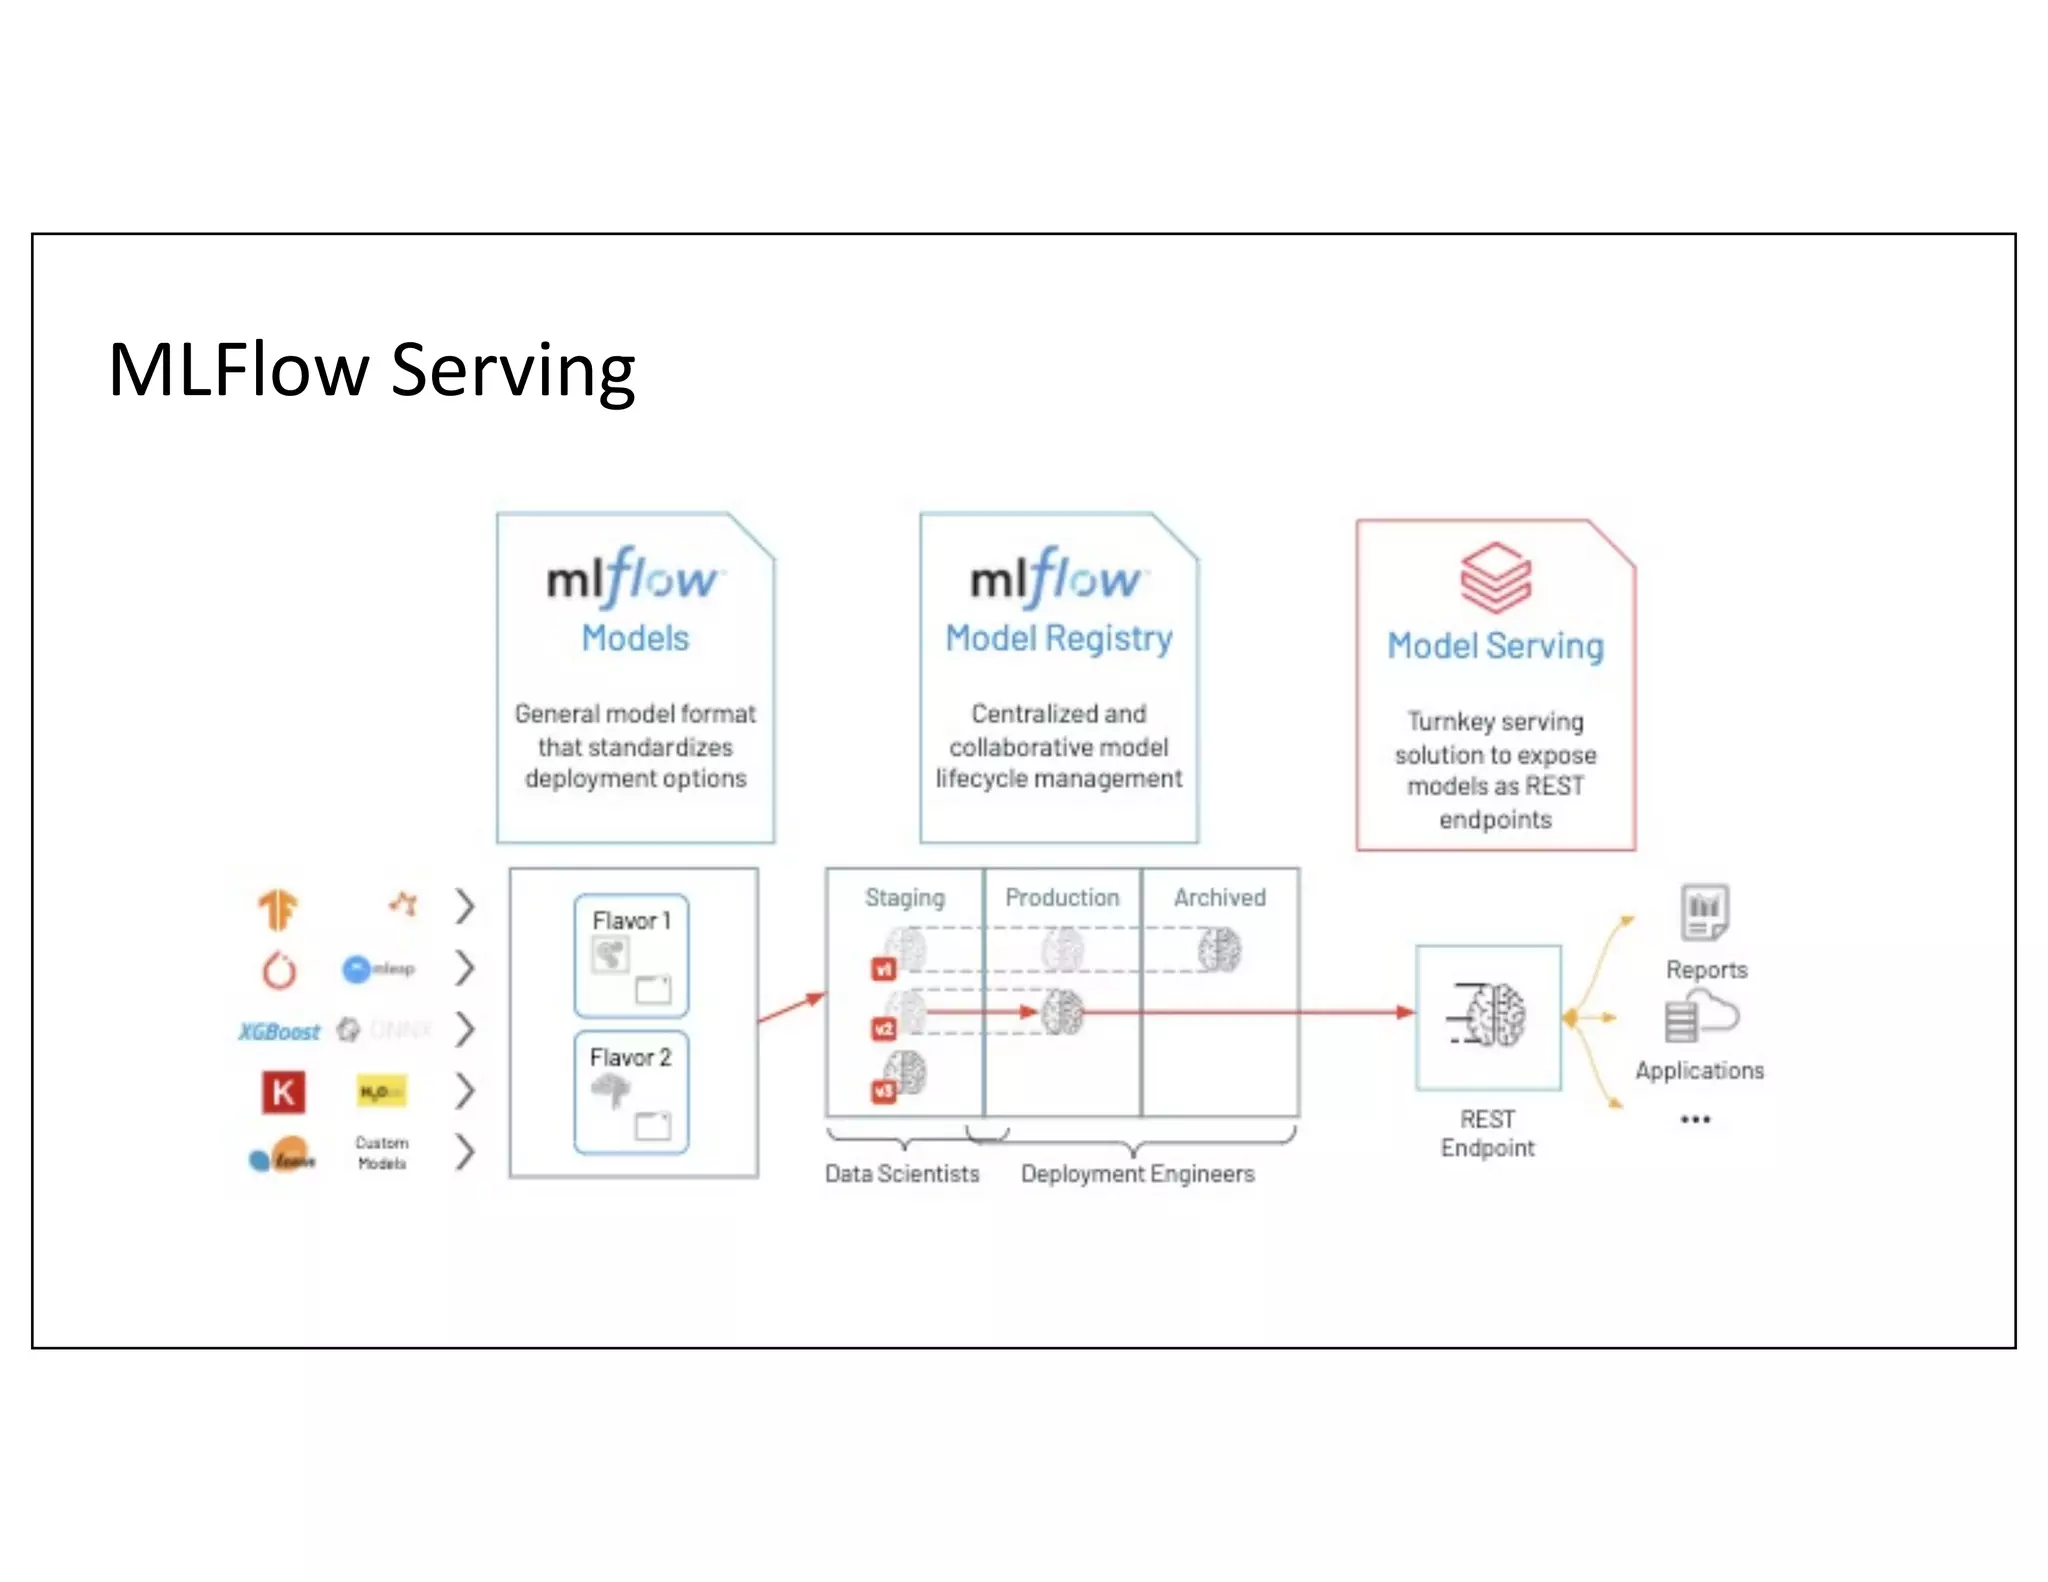
Productionzing ML Model Using MLflow Model Serving | PPT
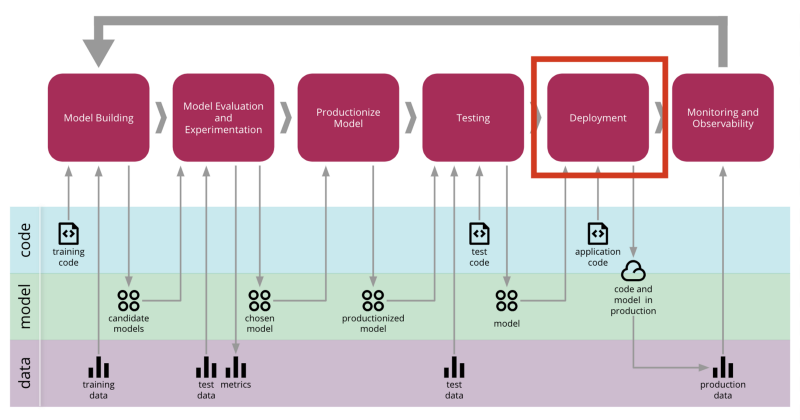
Deploying Machine Learning models to production — Inference service ...