
Vllm Integration

GraphRAG local setup via vLLM and Ollama : A detailed integration guide ...

vLLM Integration

Free Video: LLMOps: vLLM Integration with Langchain for Machine ...

vLLM Knowledge Base Integration 2026 | Connect LLM Infrastructure to ...
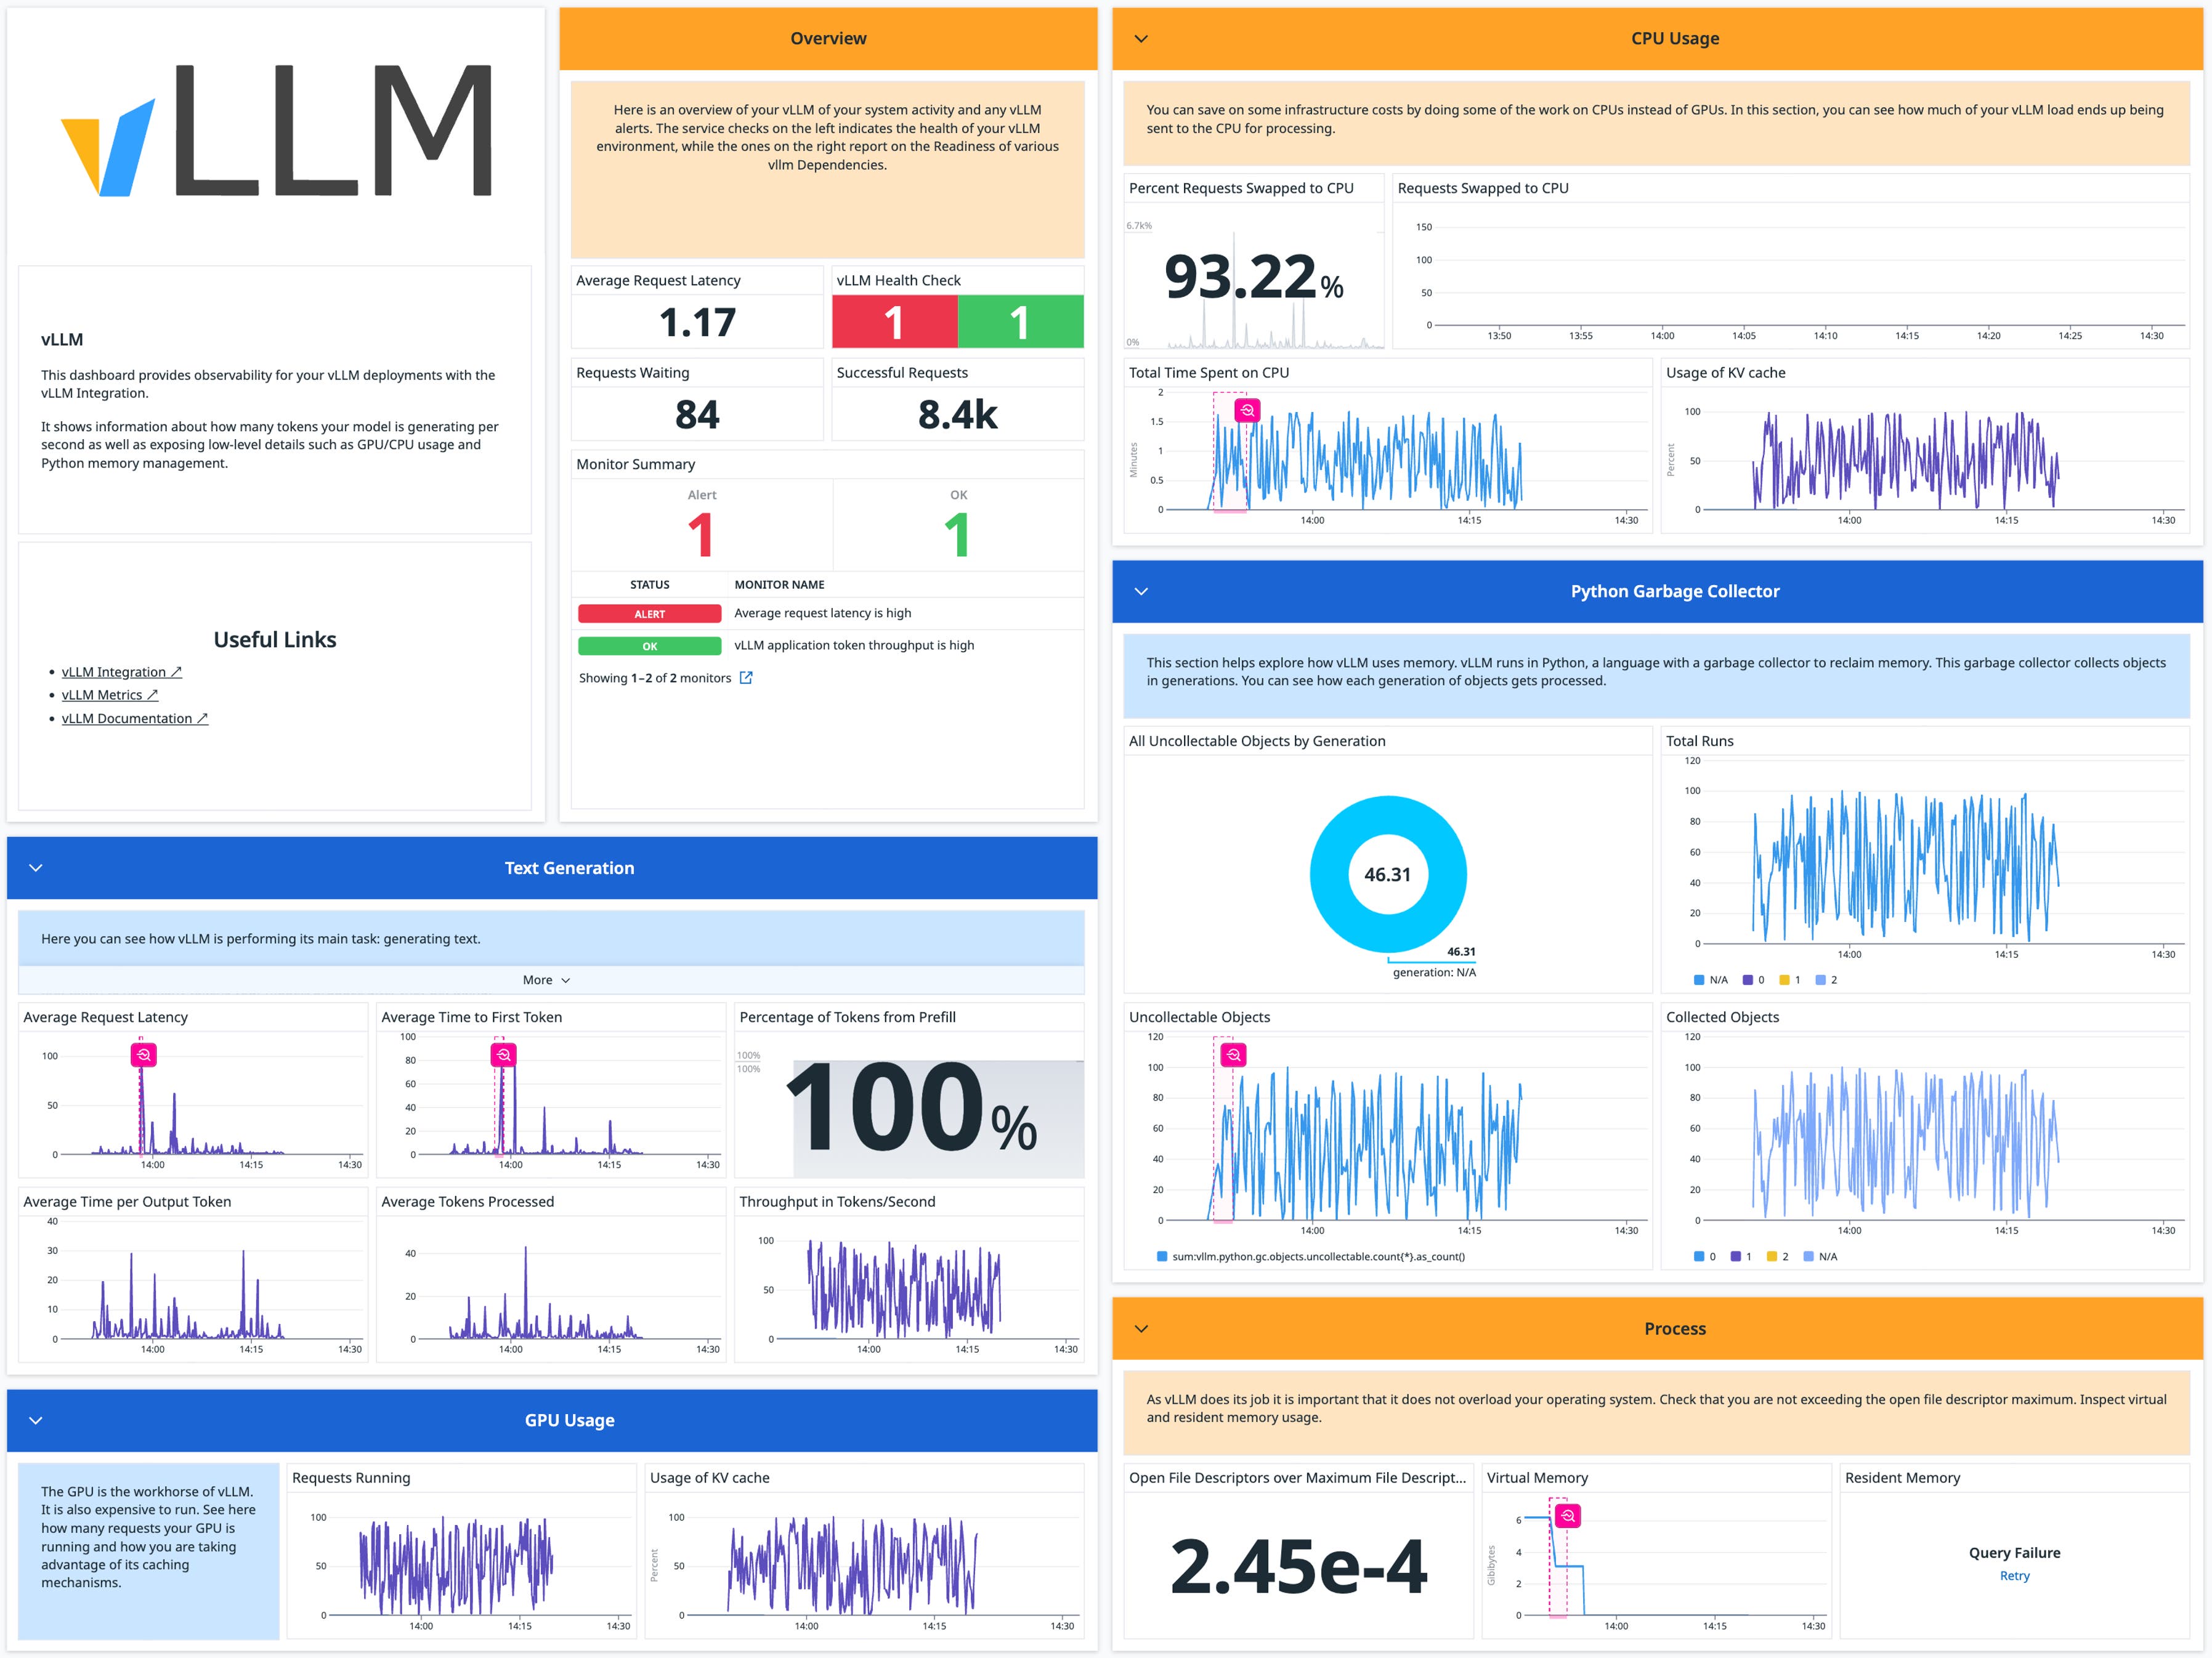
Optimize LLM application performance with Datadog's vLLM integration ...

Optimize LLM application performance with Datadog's vLLM integration ...
Transformers modeling backend integration in vLLM | vLLM Blog
vLLM Integration | vllm-project/speculators | DeepWiki

vLLM Integration

Optimize LLM Application Performance With Datadog's VLLM Integration ...
Advertisement Space (300x250)

How Does the Transformers + vLLM Integration Work? Hands-on Tutorial ...
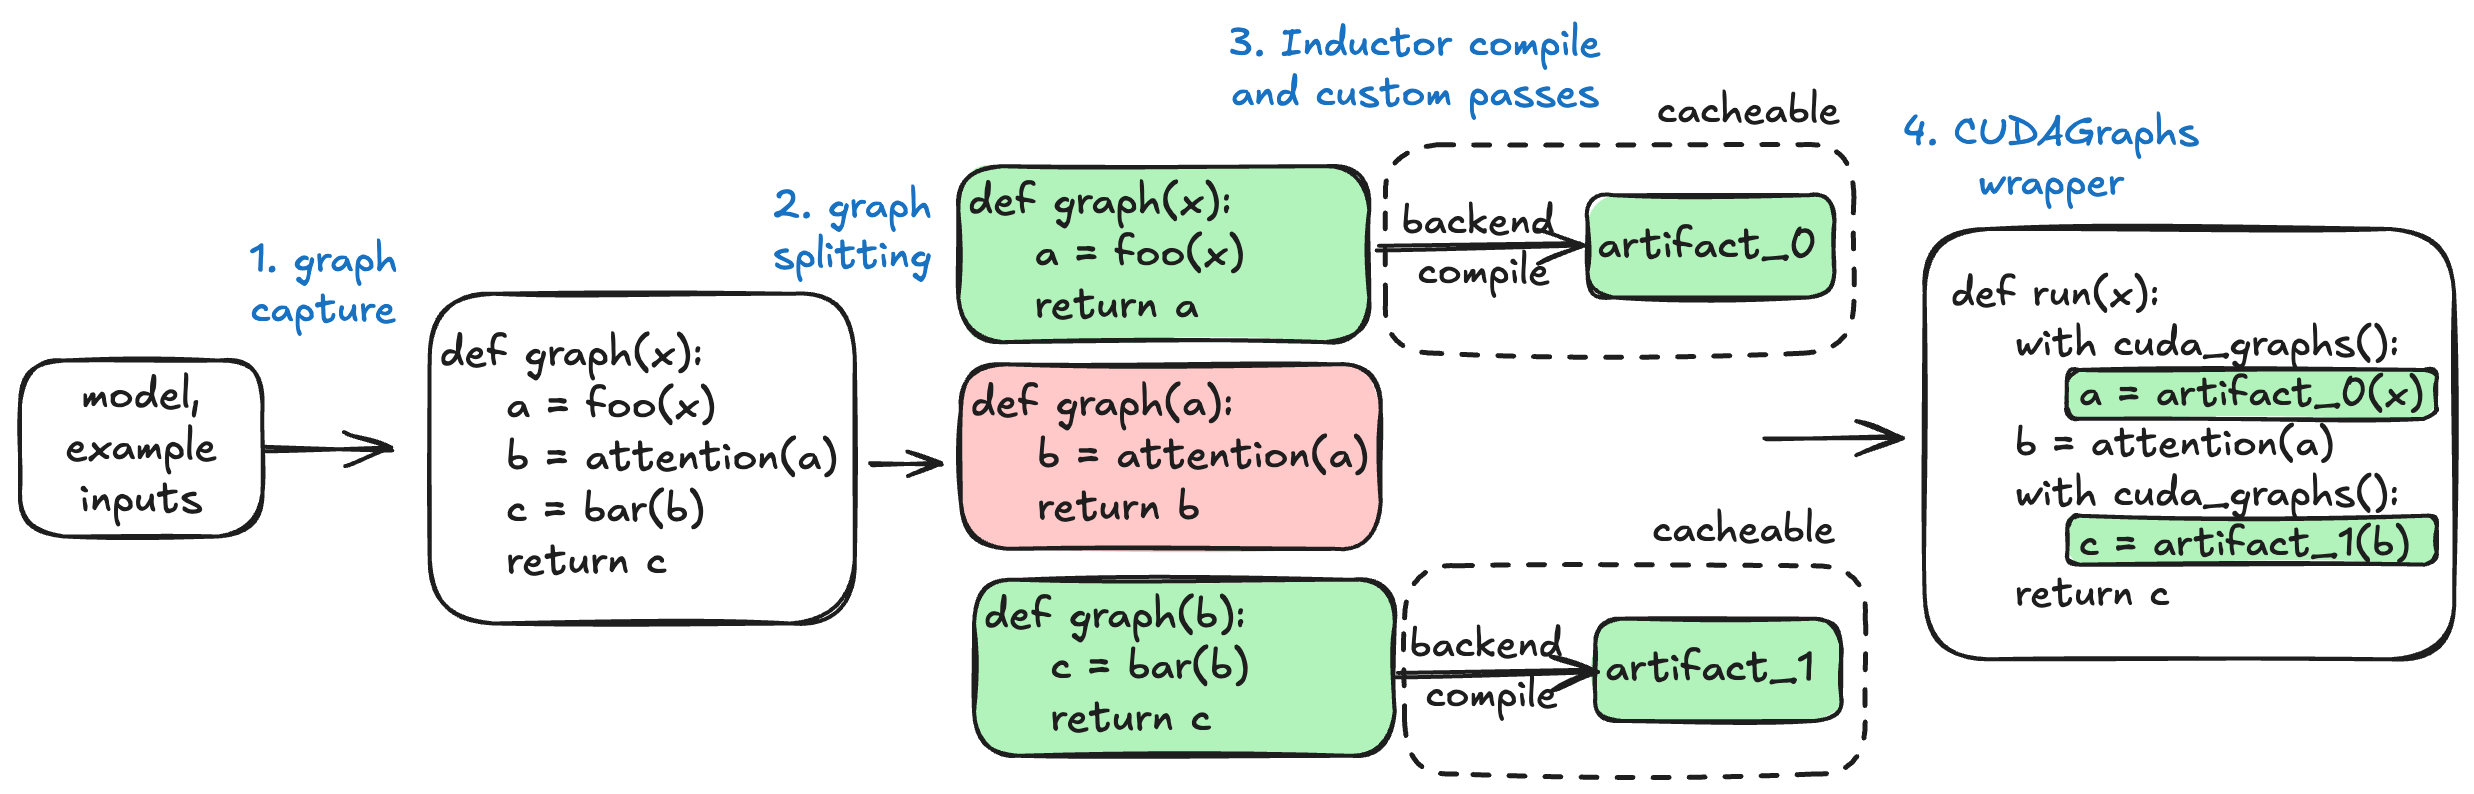
How to debug the vLLM-torch.compile integration - vLLM
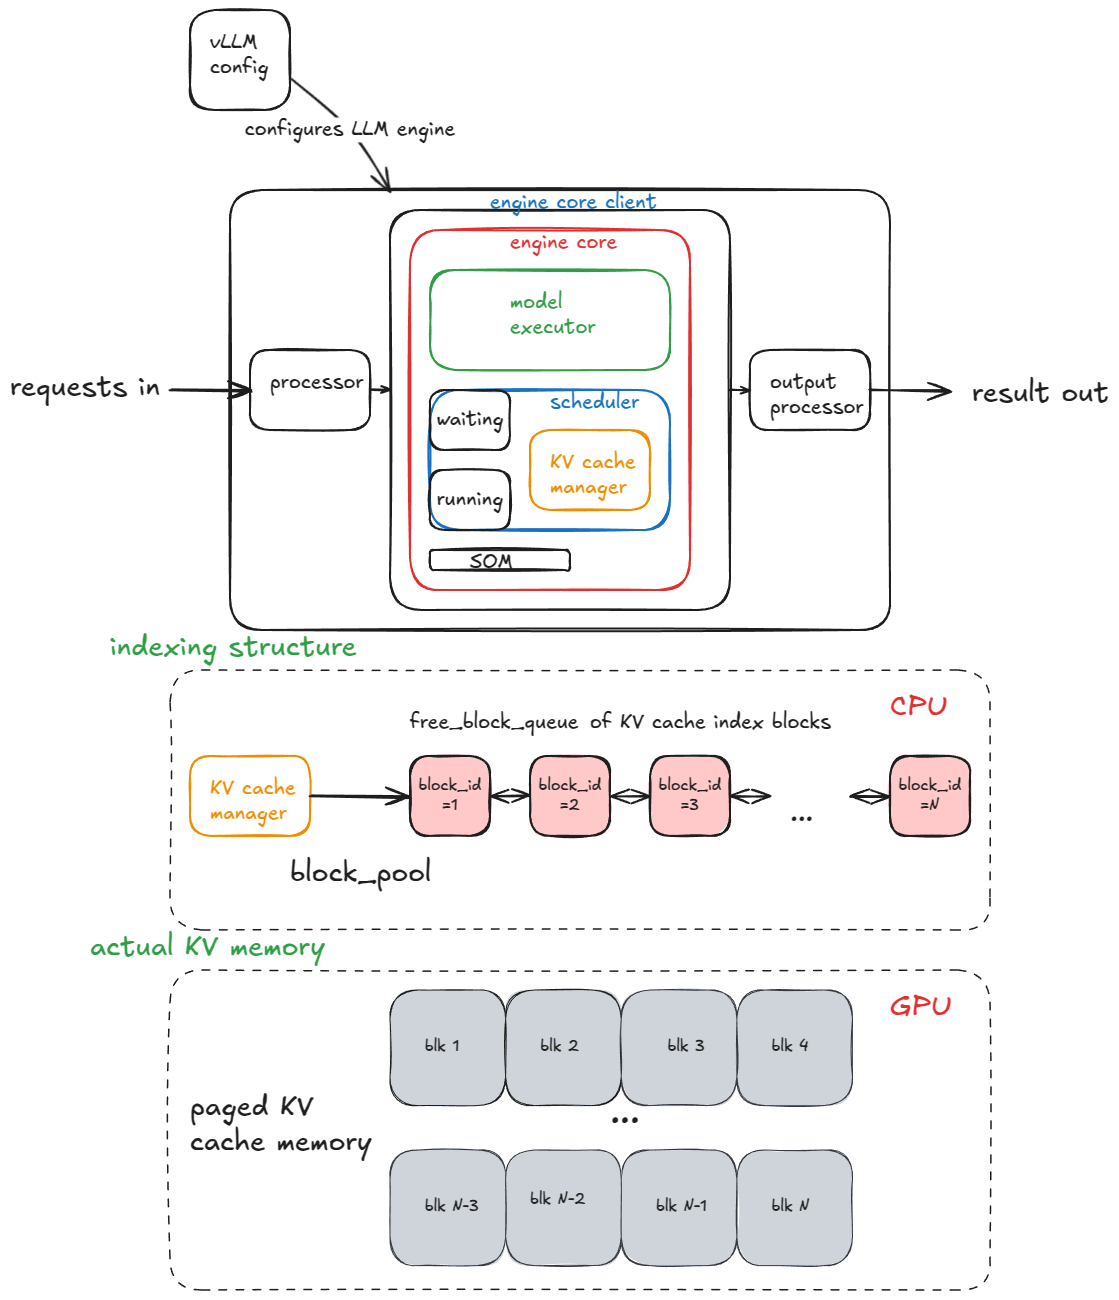
vLLM 내부: 초고처리량 LLM 추론 시스템의 해부 - Aleksa Gordić - RosettaLens 번역
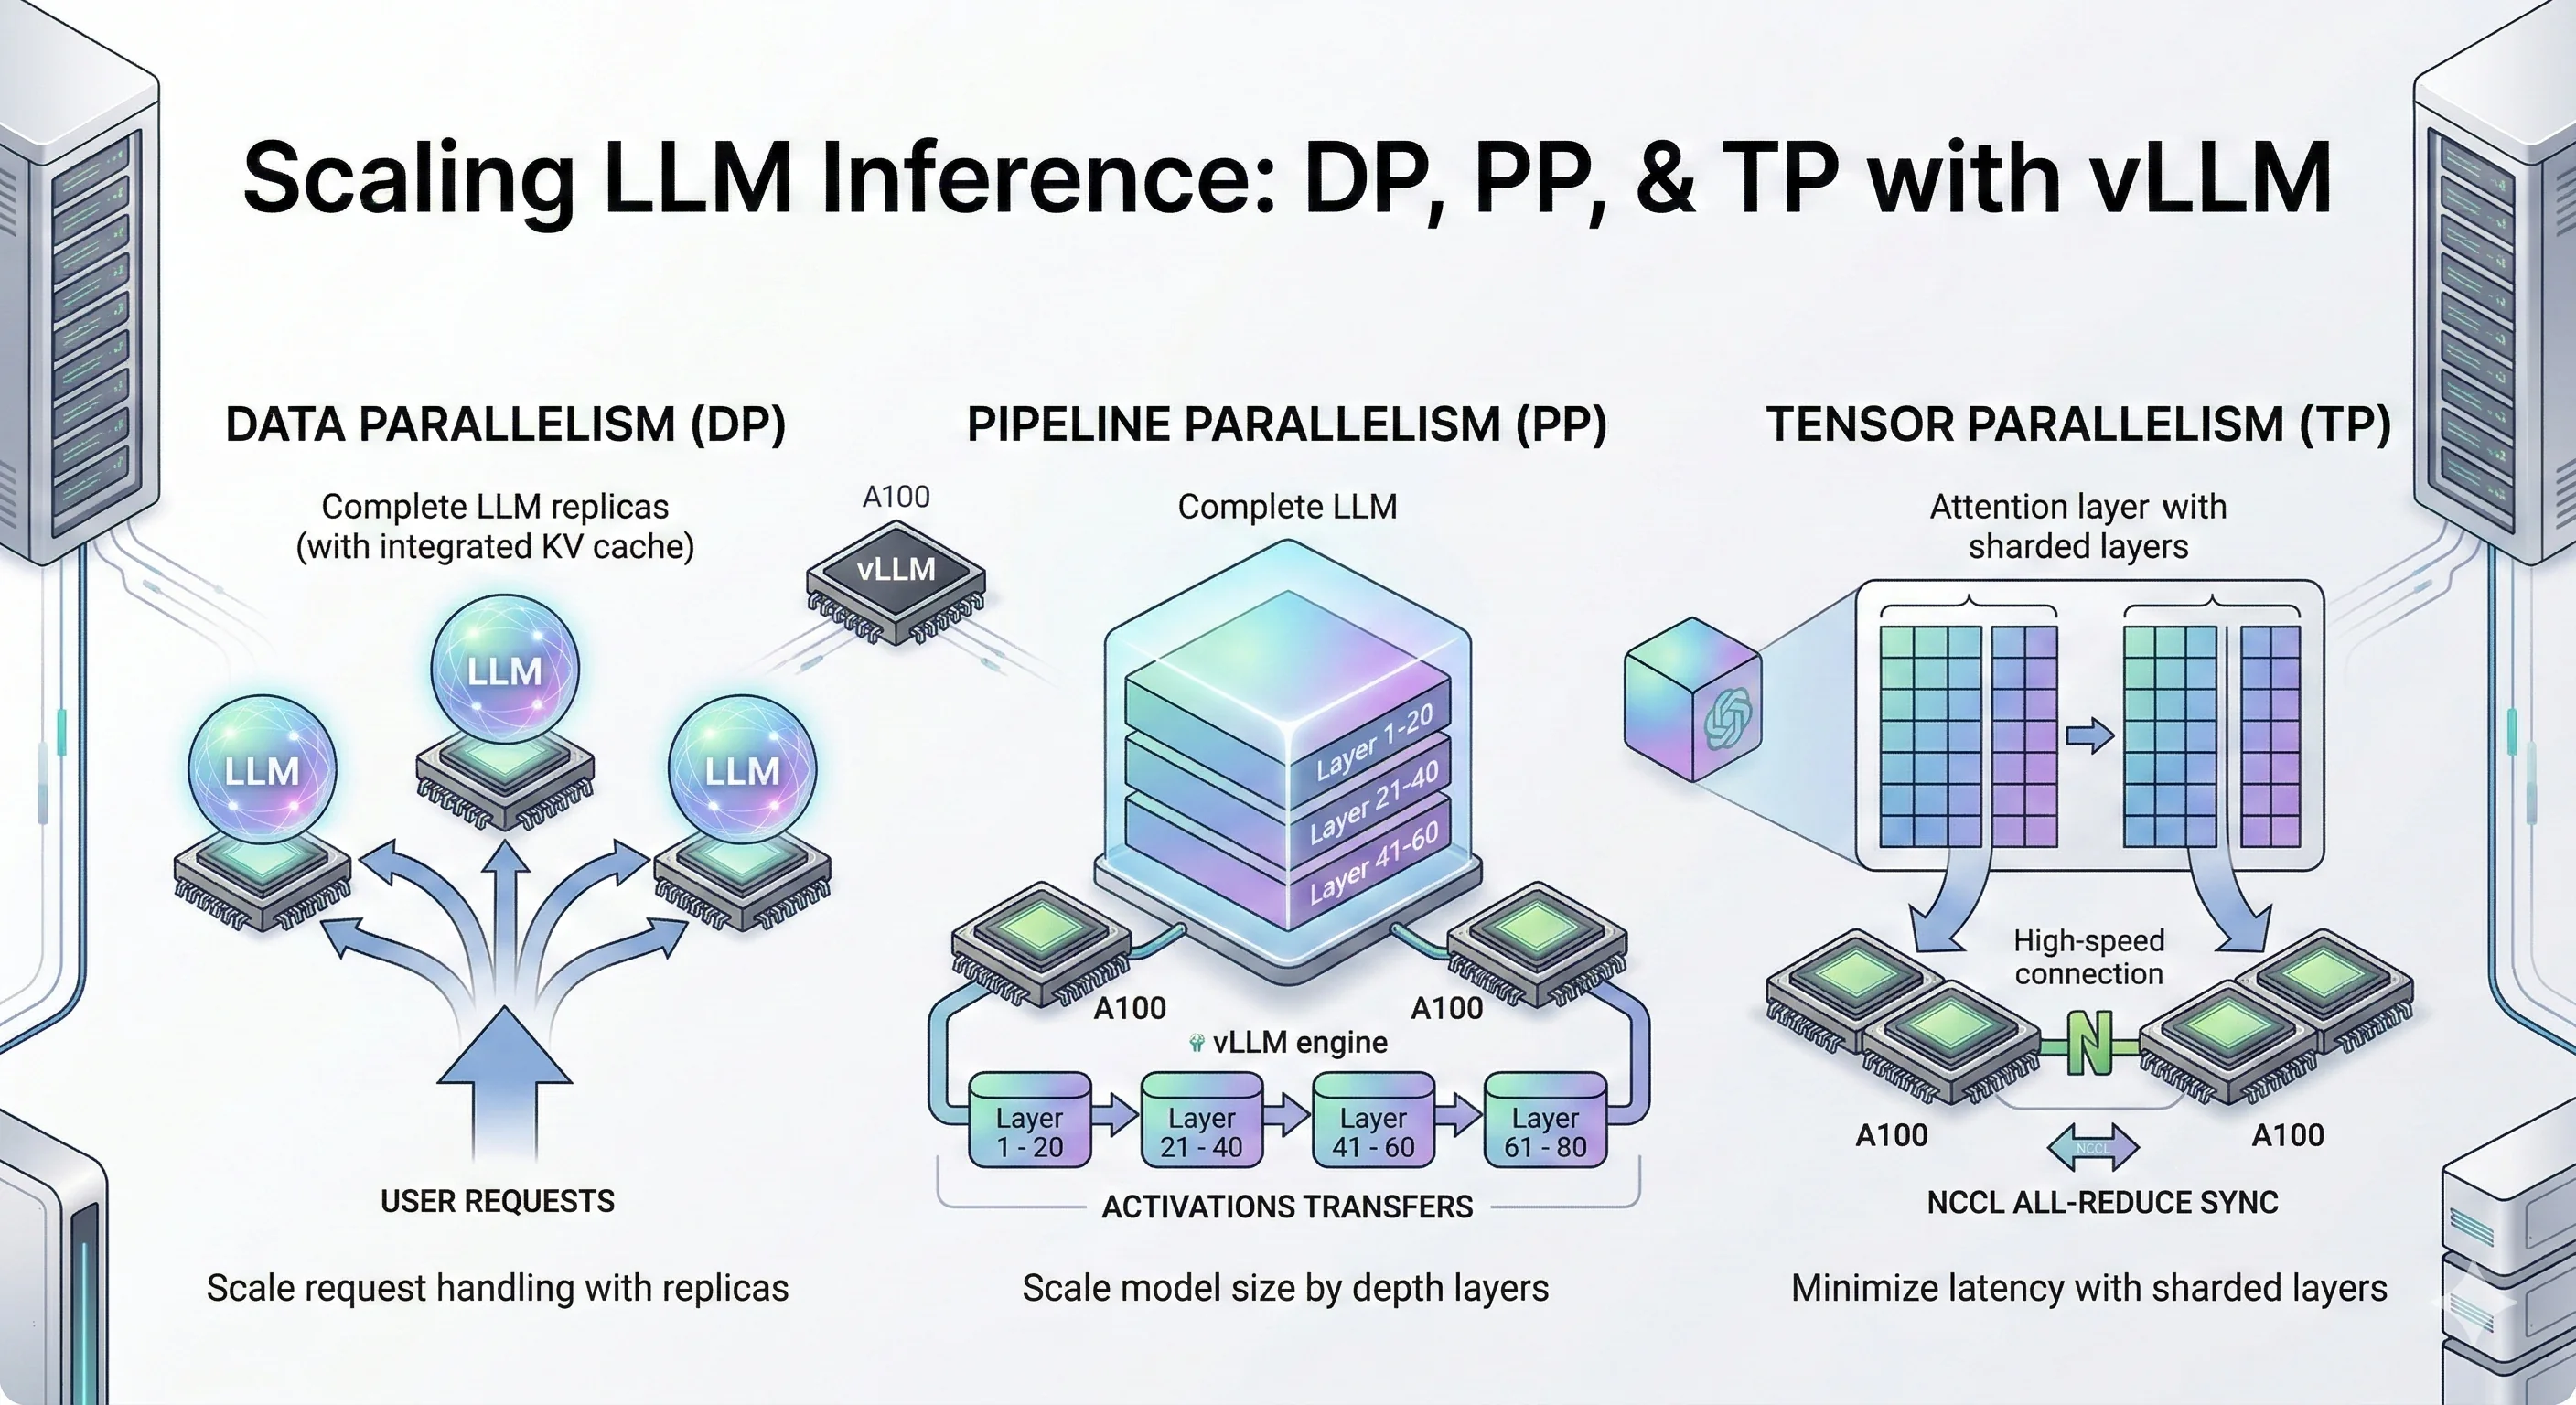
vLLM Optimization Techniques: 5 Practical Methods to Improve ...
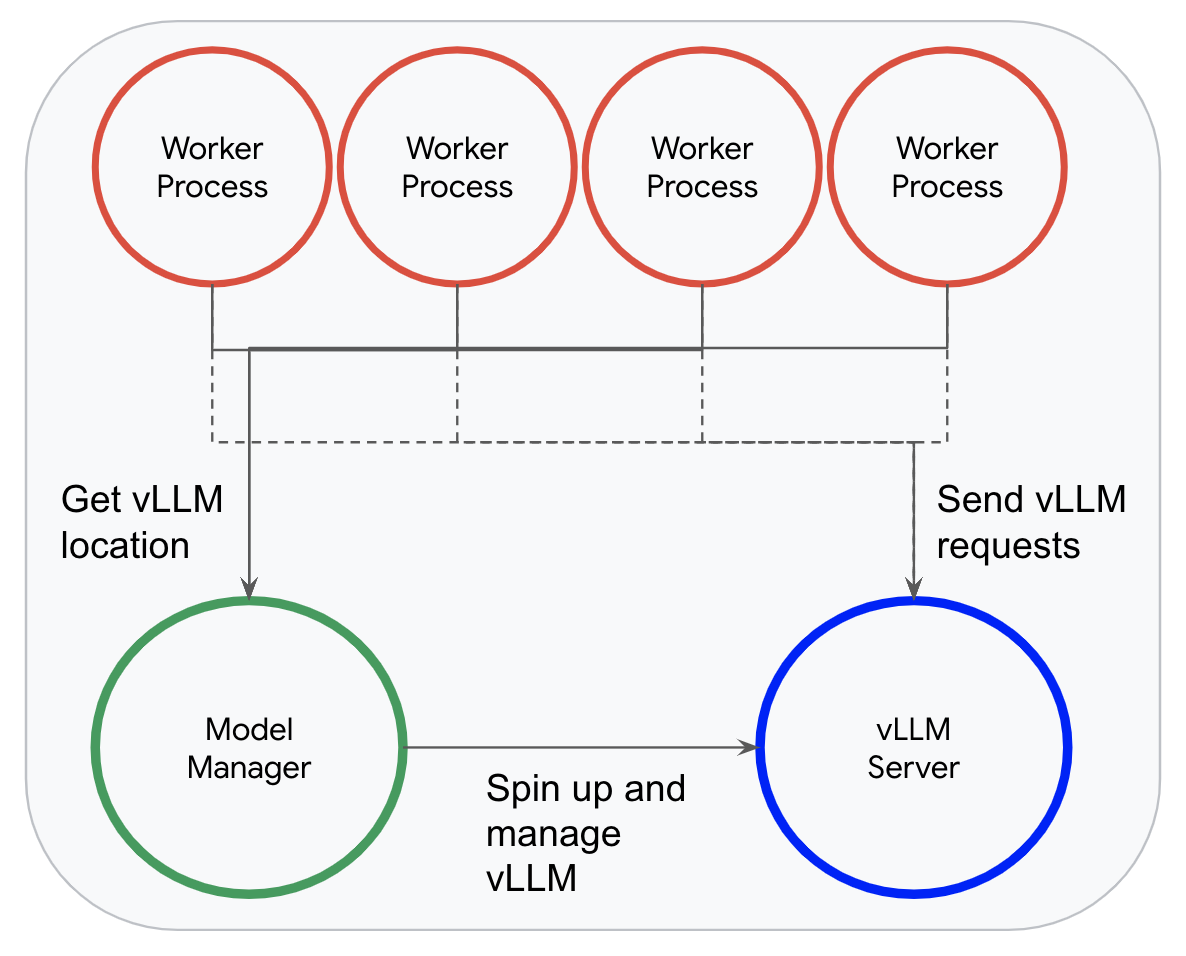
Inference with Gemma using Dataflow and vLLM - Google Developers Blog
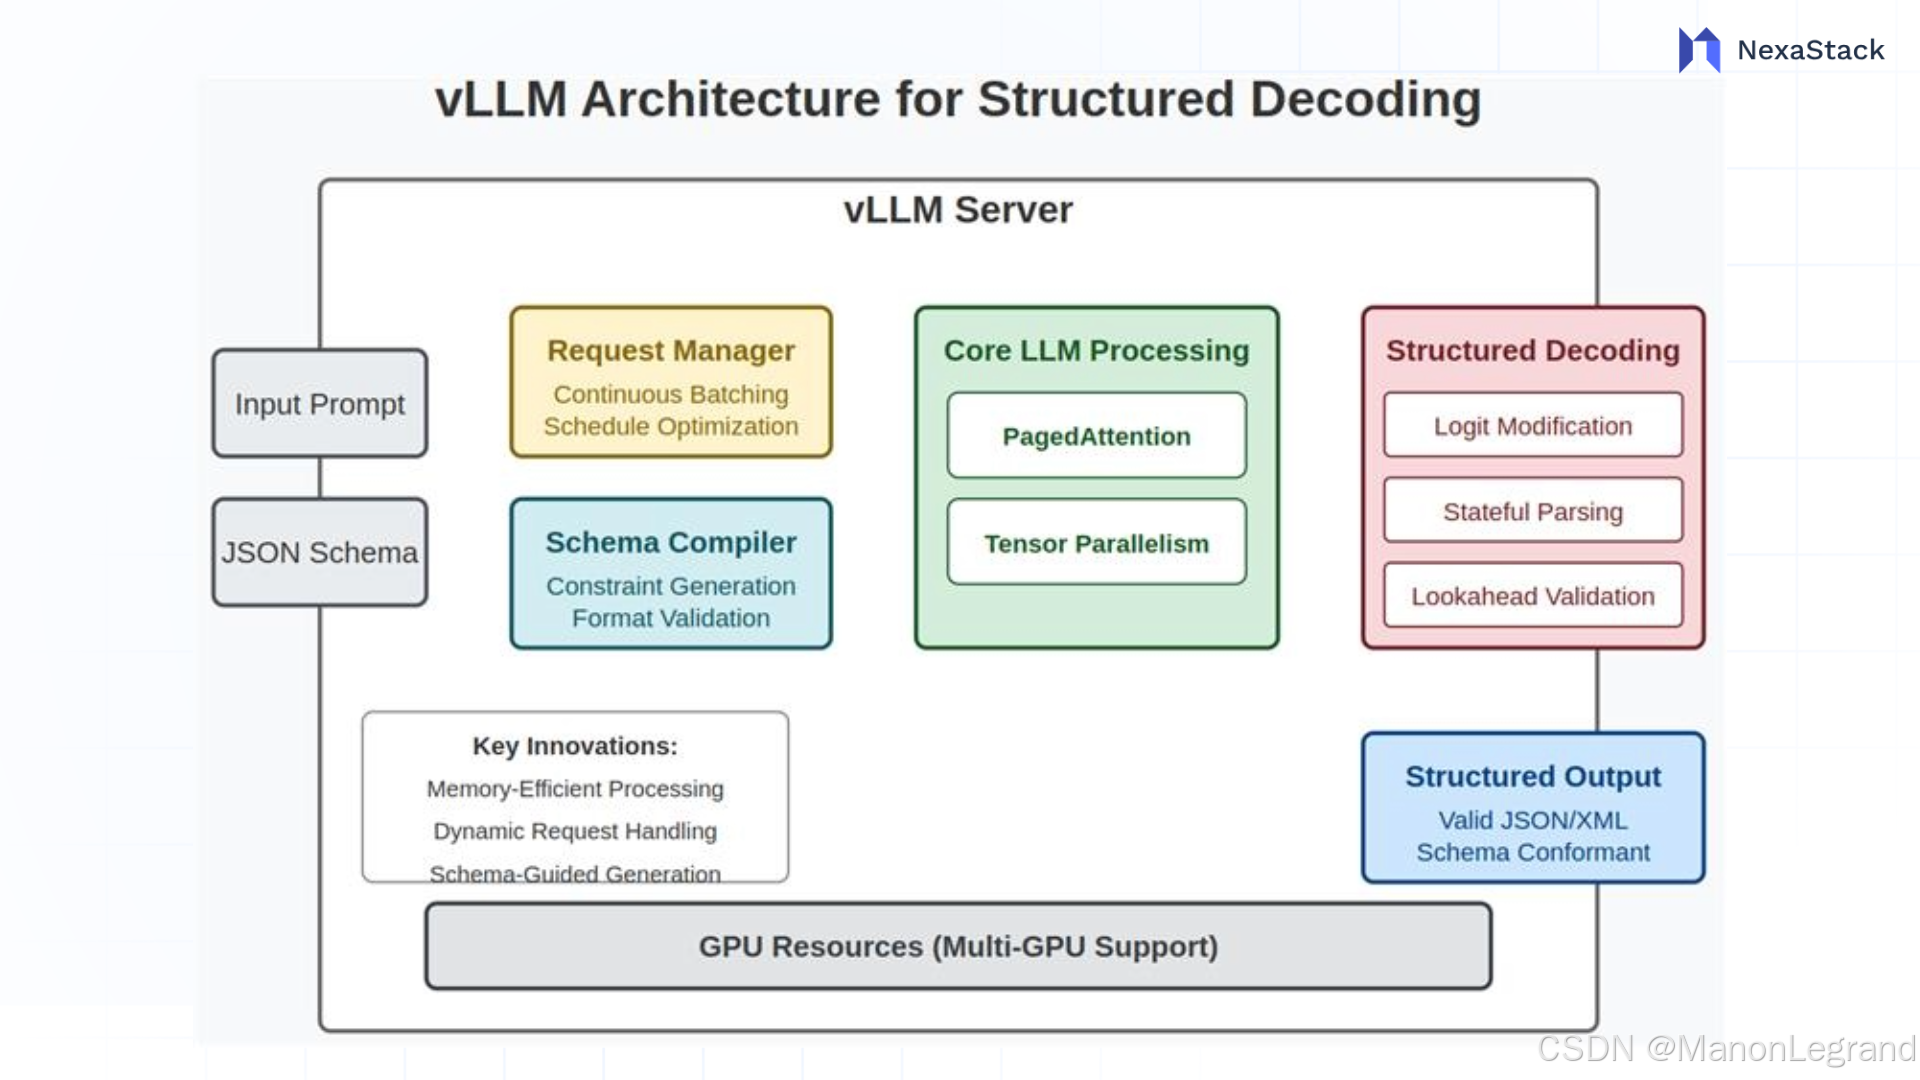
LLM - 使用 vLLM 部署 Qwen2.5-VL-32B 模型 (4卡x4090-49G) (3)_qwen2.5-vl 怎么vllm ...
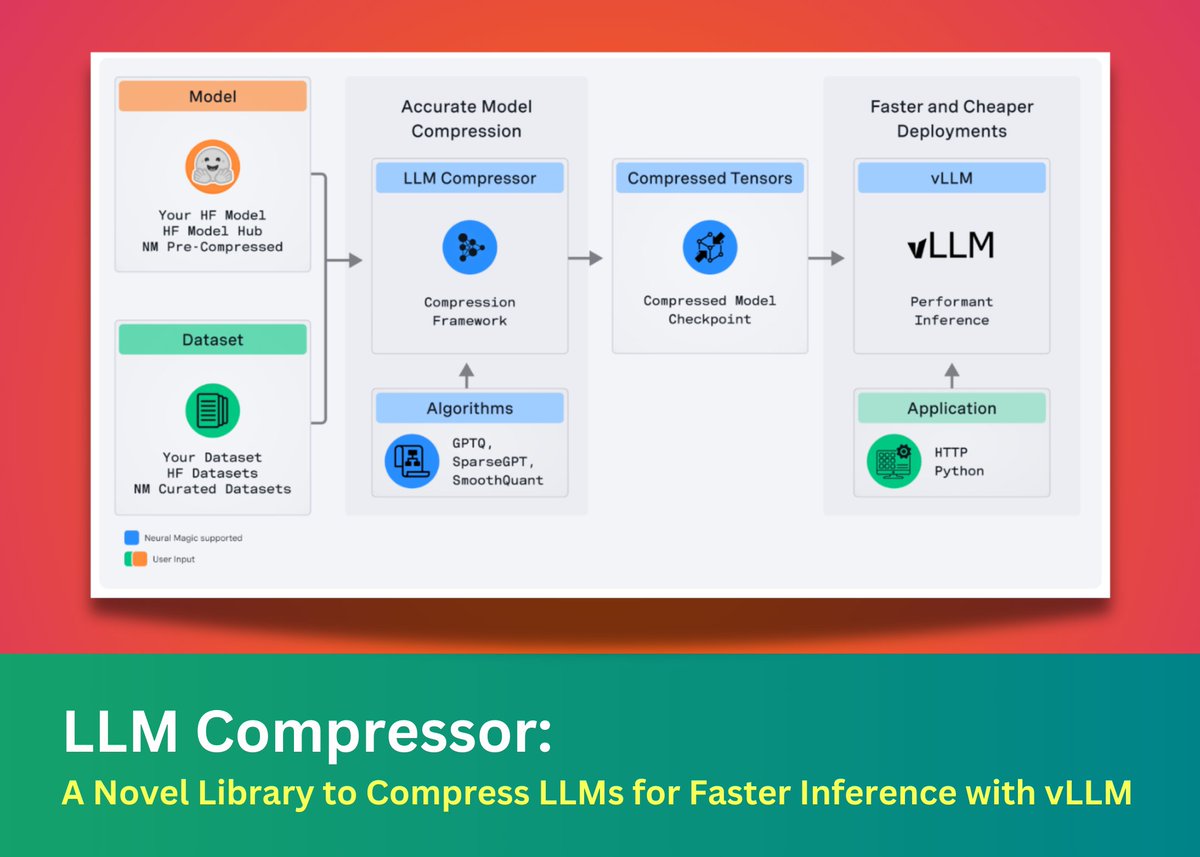
Neural Magic Releases LLM Compressor for Faster Inference with vLLM ...

vLLM Hook v0: A Plug-in for Programming Model Internals on vLLM
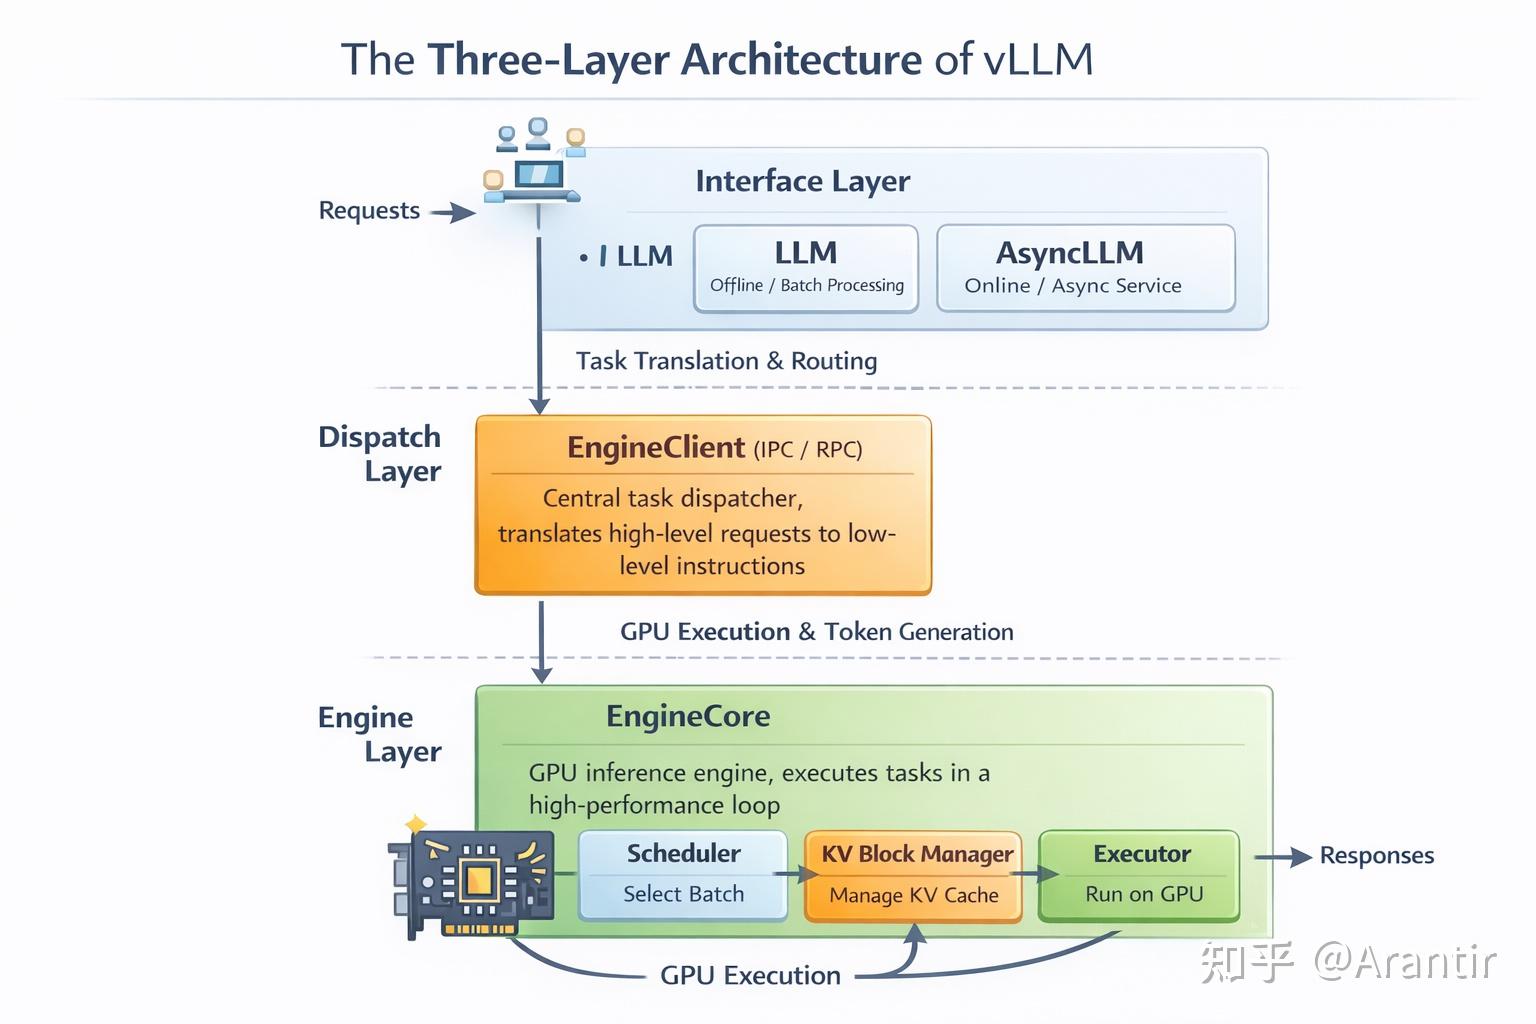
vLLM 设计导论:一步步帮你形成架构直觉 - 知乎
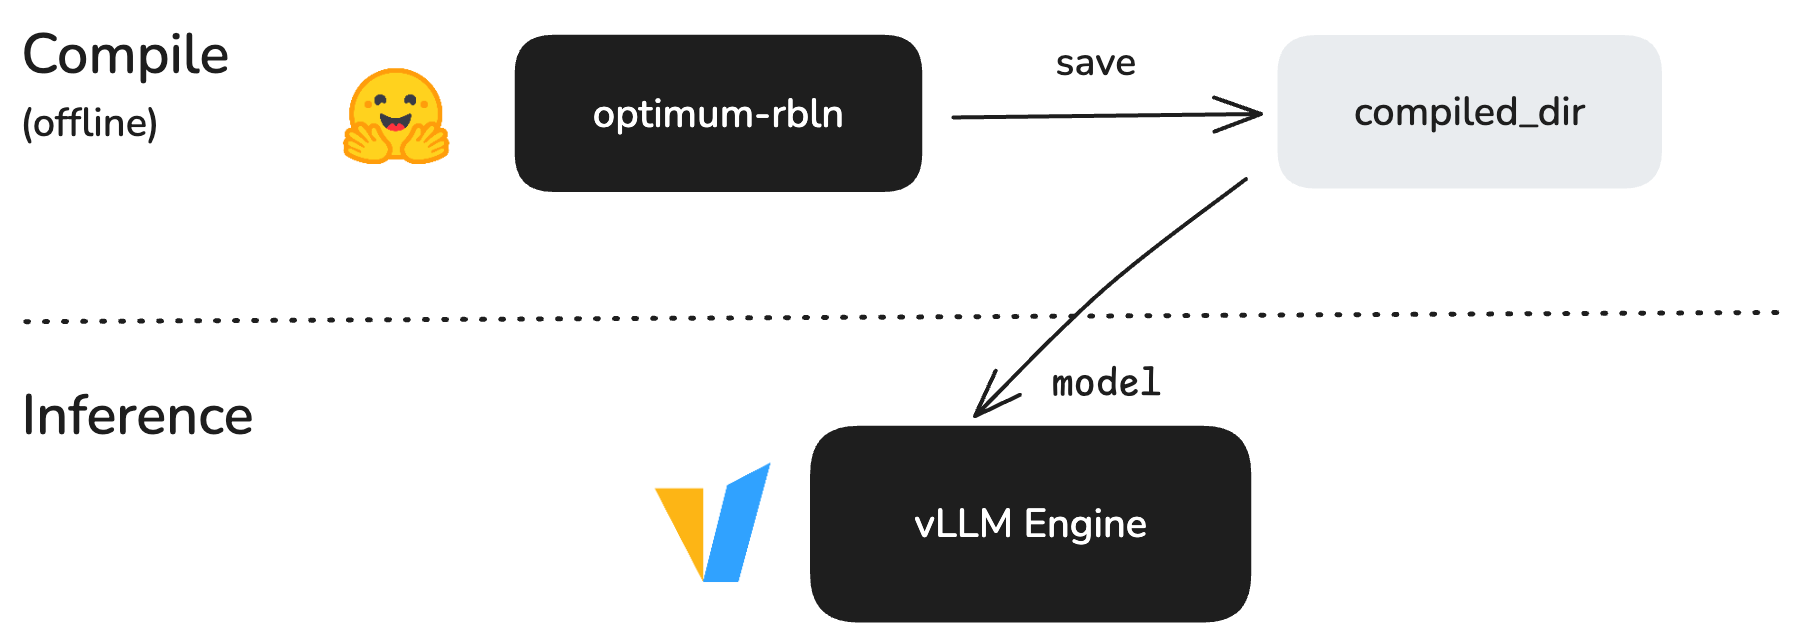
vLLM RBLN
Advertisement Space (336x280)

vLLM V1重大更新 - 知乎
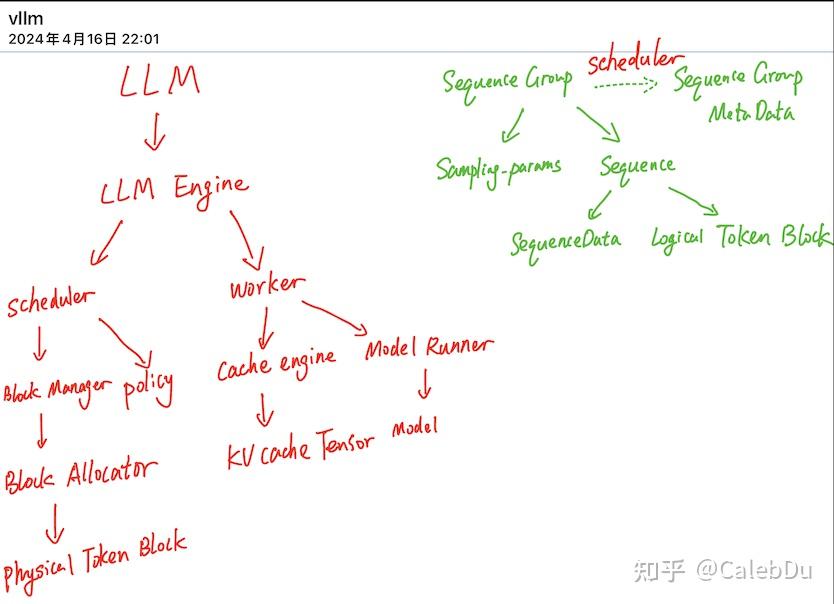
vLLM 架构详解(一) - 知乎

vLLM Hook v0: A Plug-in for Programming Model Internals on vLLM

Scale Open LLMs with vLLM Production Stack | by Shahrukh khan | Medium
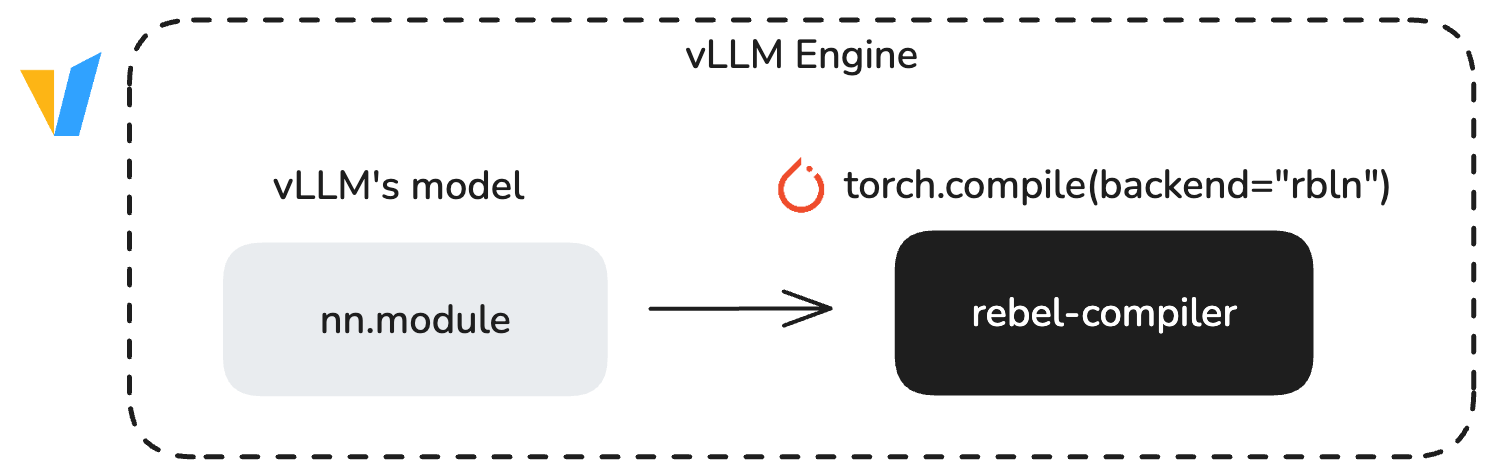
vLLM RBLN

Understanding vLLM with a Hands On Demo - YouTube
vLLM Tutorial: Fast, OpenAI‑Compatible LLM Serving Guide
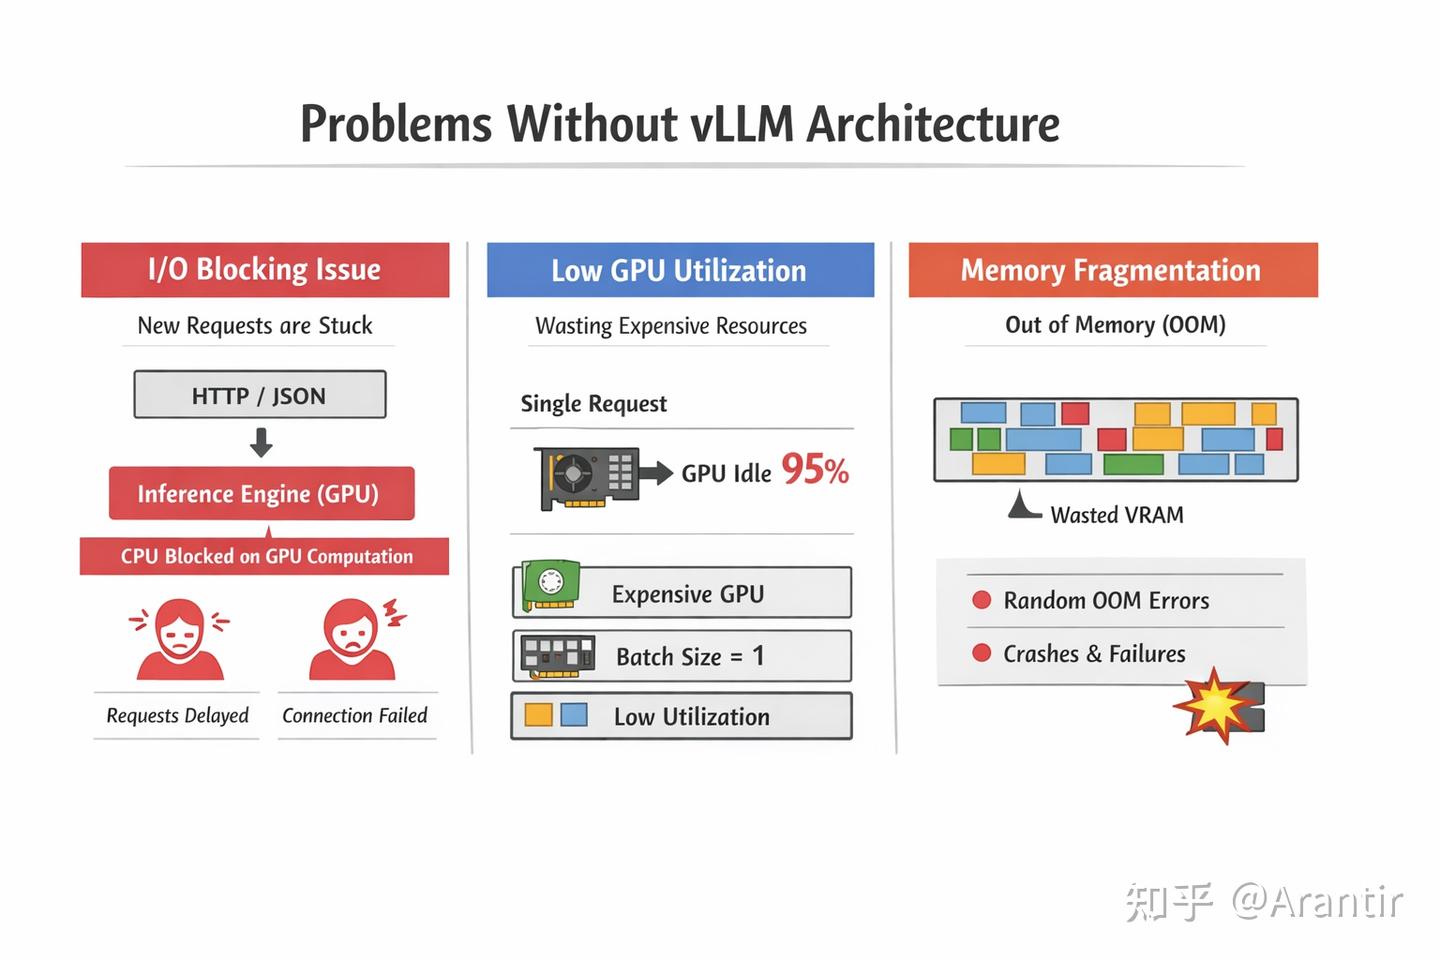
vLLM 设计导论:一步步帮你形成架构直觉 - 知乎

vLLM Inference Engine Boosts AI App Performance | SwathiLakshmi B ...
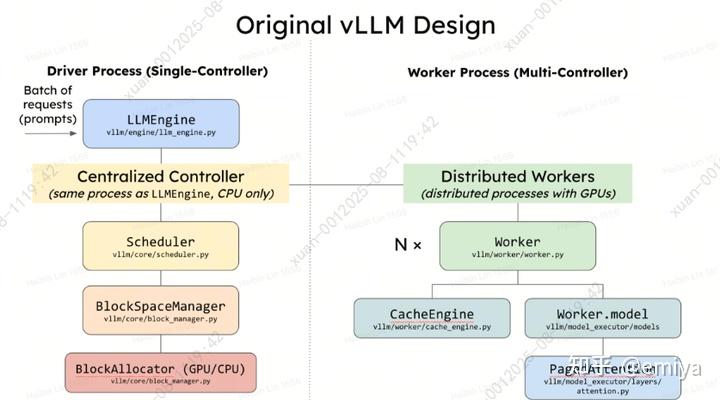
[verl-04] 利用 vLLM 进行 rollout - 知乎
Advertisement Space (336x280)
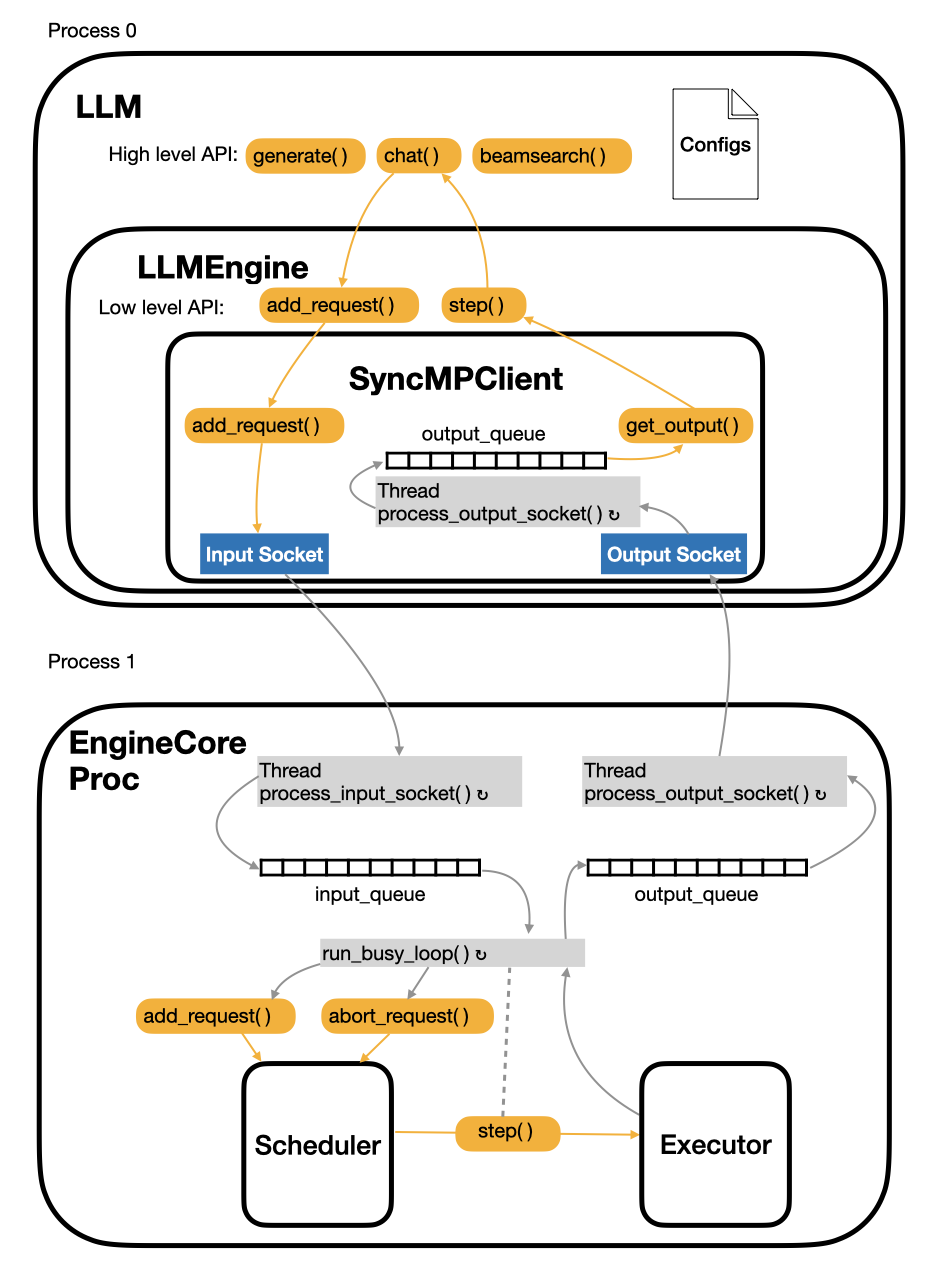
vLLM V1 Engine Design Ⅰ: The Excution Loop - Haisheng's Note Zoo

Quickstart: High-throughput LLM inference with vLLM on Amazon EKS ...
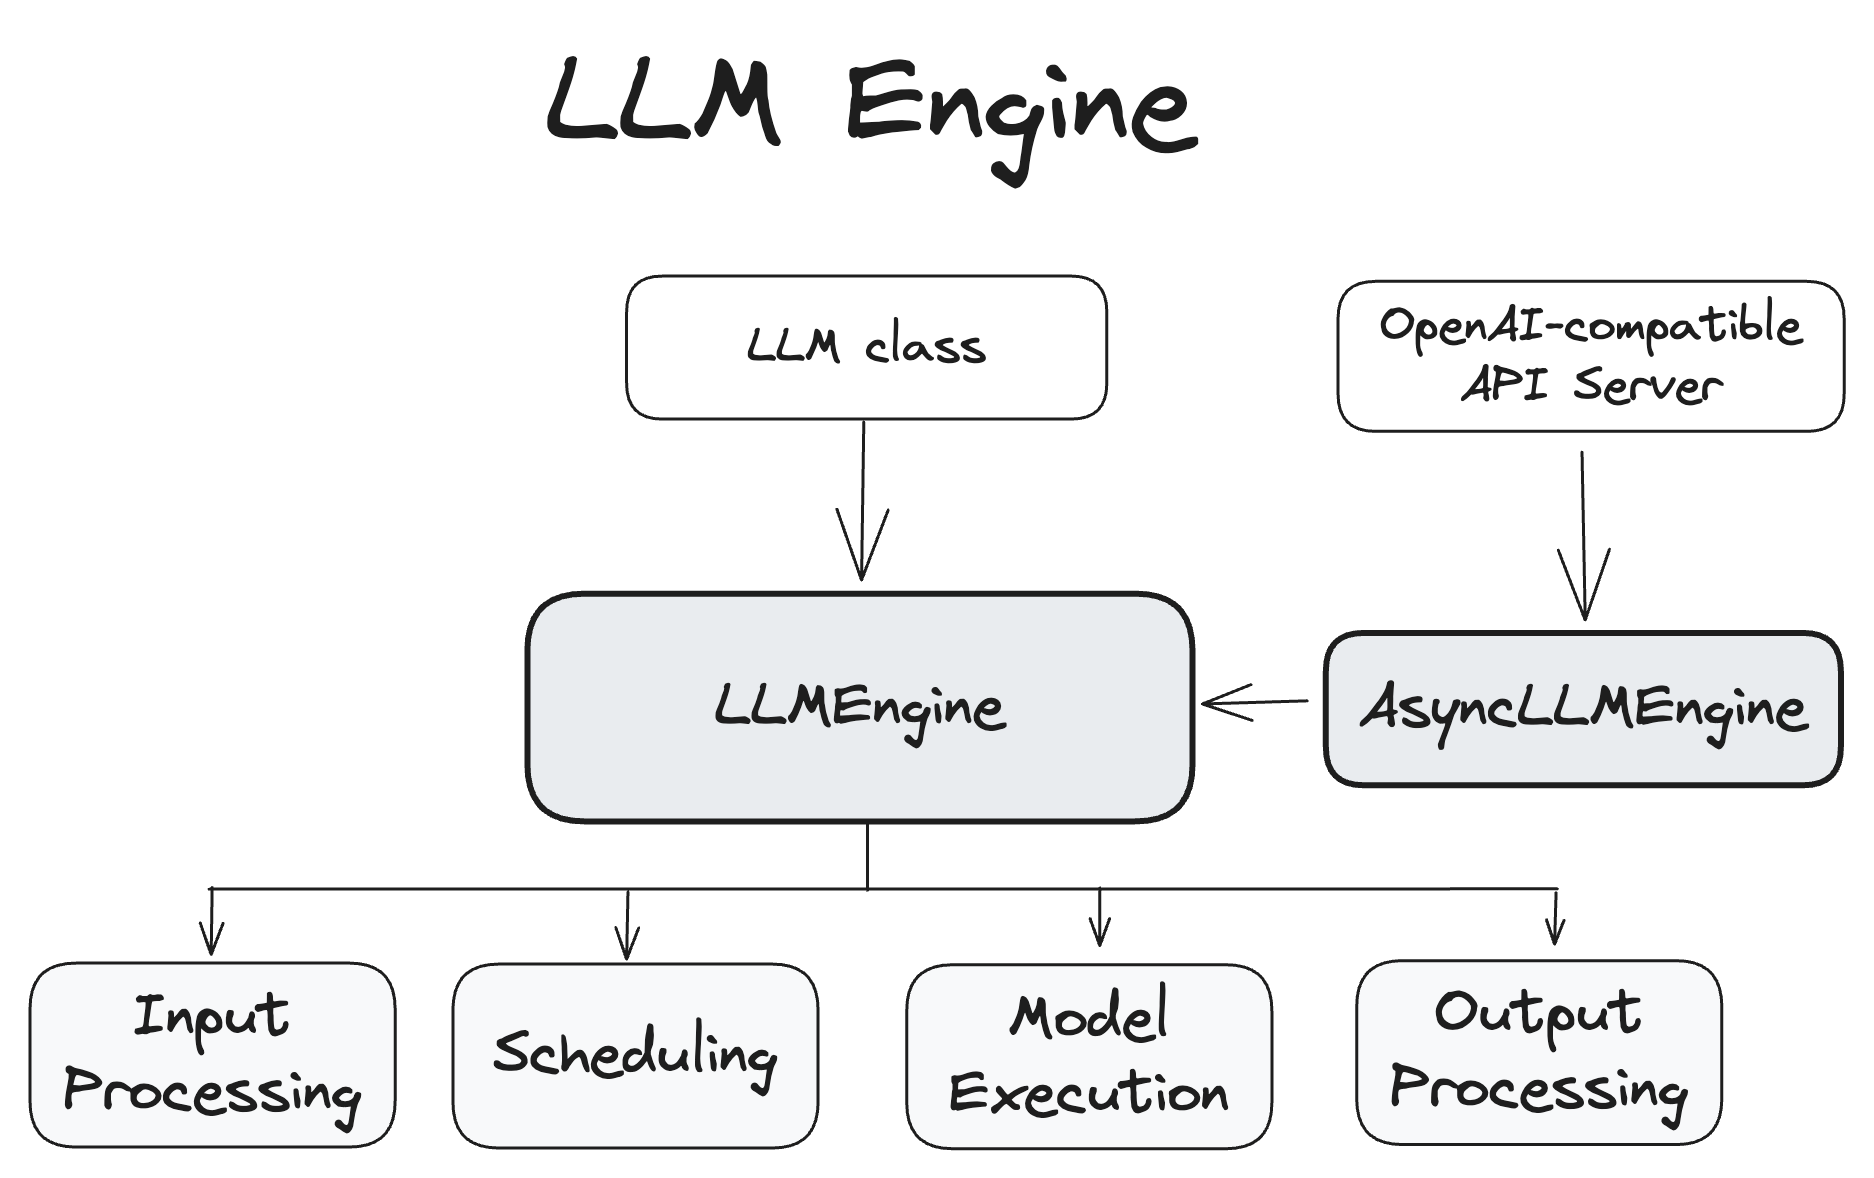
Architecture Overview — vLLM

AMD × vLLM 语义路由 (Semantic Router):共同构建系统智能 | vLLM 博客
Blog | vLLM

How to Build a vLLM Container Image for LLM Deployment | Vultr Docs