
09 Attention Transformer Bert Gptpdf Msc Deep Learning 09 Encoder

09-Attention Transformer BERT GPT.pdf - MSc. Deep Learning 09- Encoder ...

Attention and the Transformer · Deep Learning
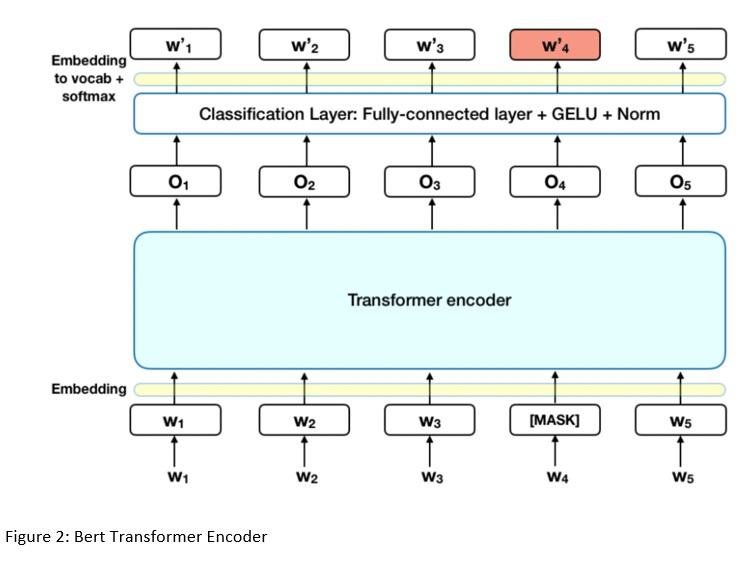
Solved Note: Homework for Deep Learning Course Attention | Chegg.com

BERT : Bidirectional Encoder Representations from Transformer
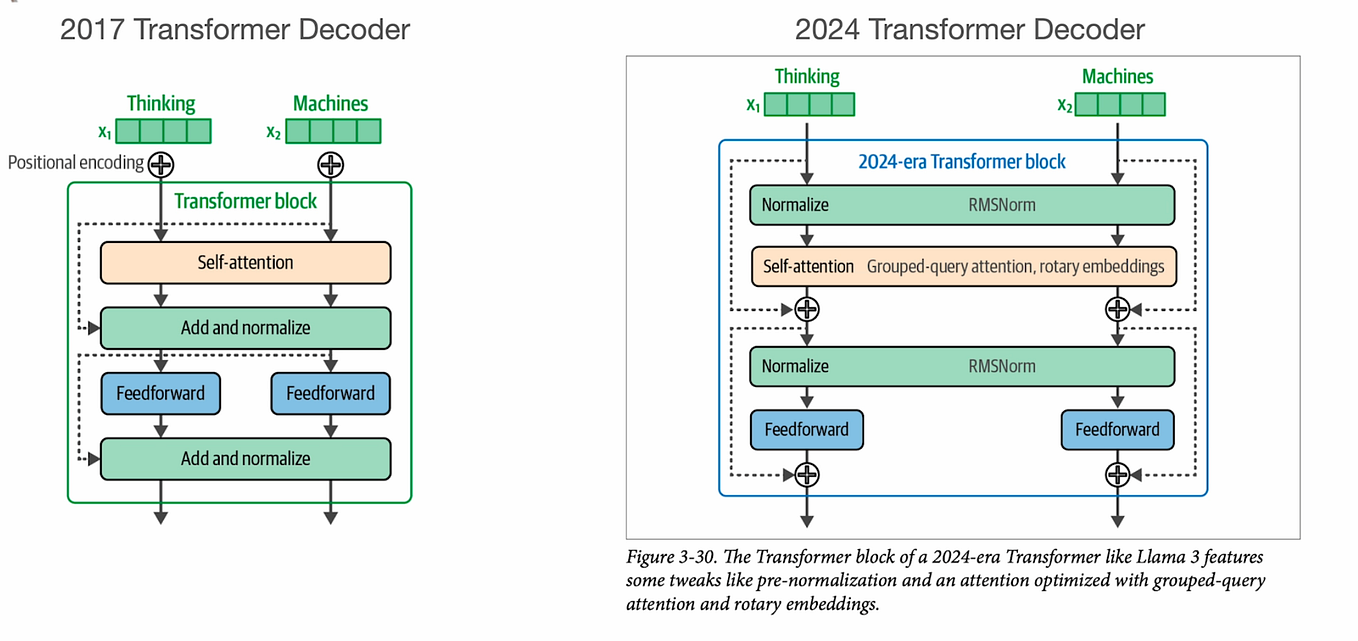
The Attention Mechanism in Deep Learning — An Example | by George Ginis ...
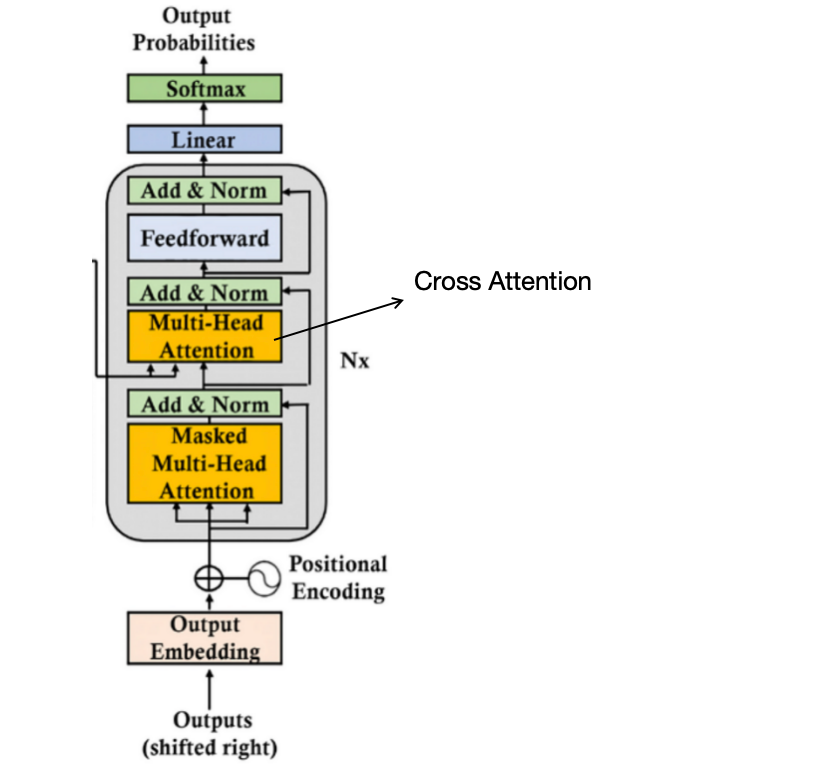
How does The Attention Mechanism in GPT Models Work? | by Deep Learning ...

Deep Learning-Based Short Text Summarization: An Integrated BERT and ...
| Transformer architectures of BERT and GPT. Illustration of the ...

Large Language Models: BERT - Bidirectional Encoder Representations ...
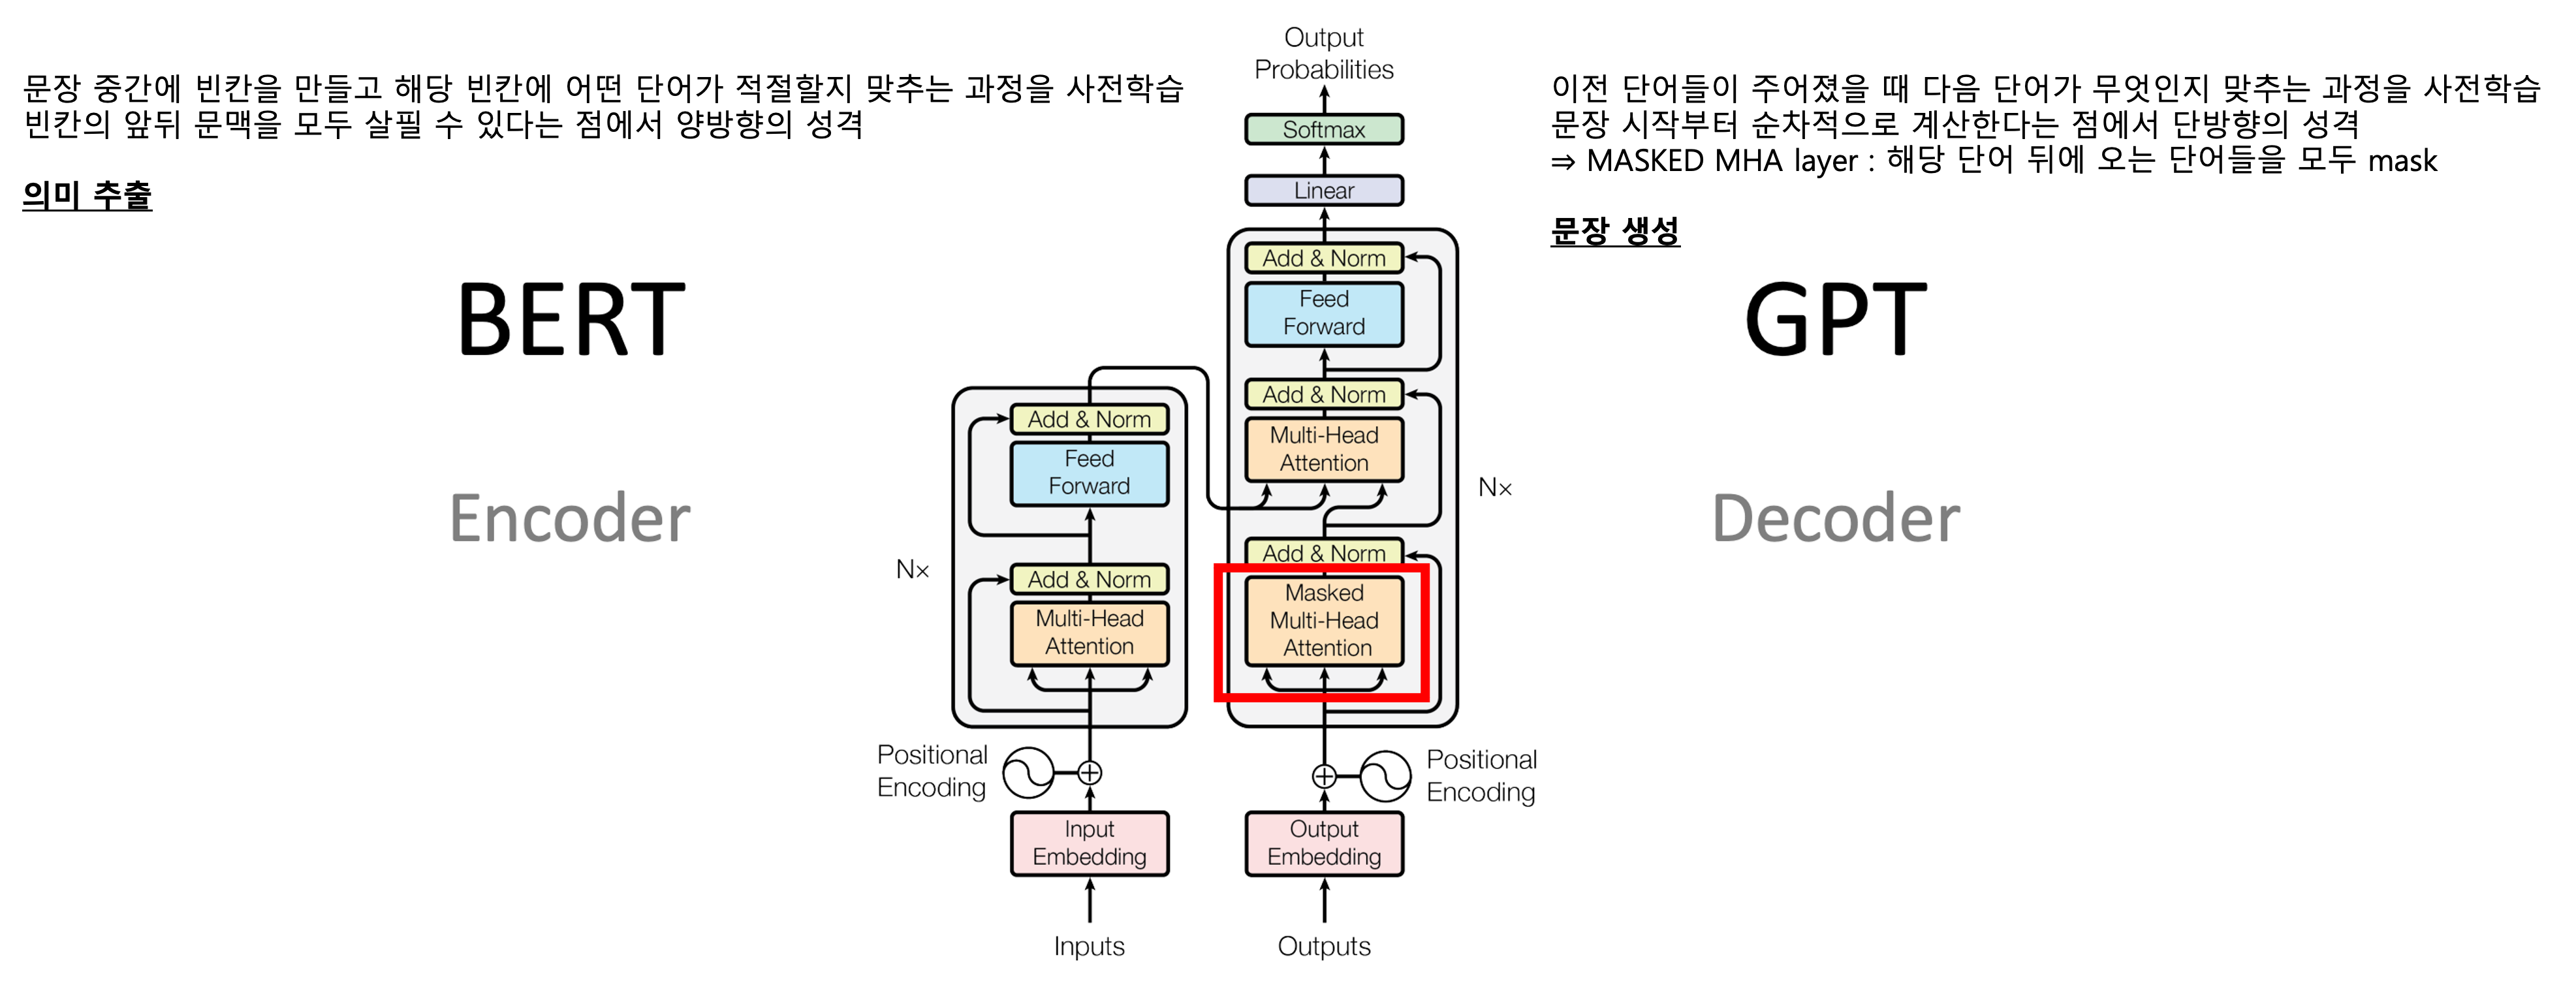
[Review] BERT : Pre-training of Deep Bidirectional Transformers for ...
Advertisement Space (300x250)
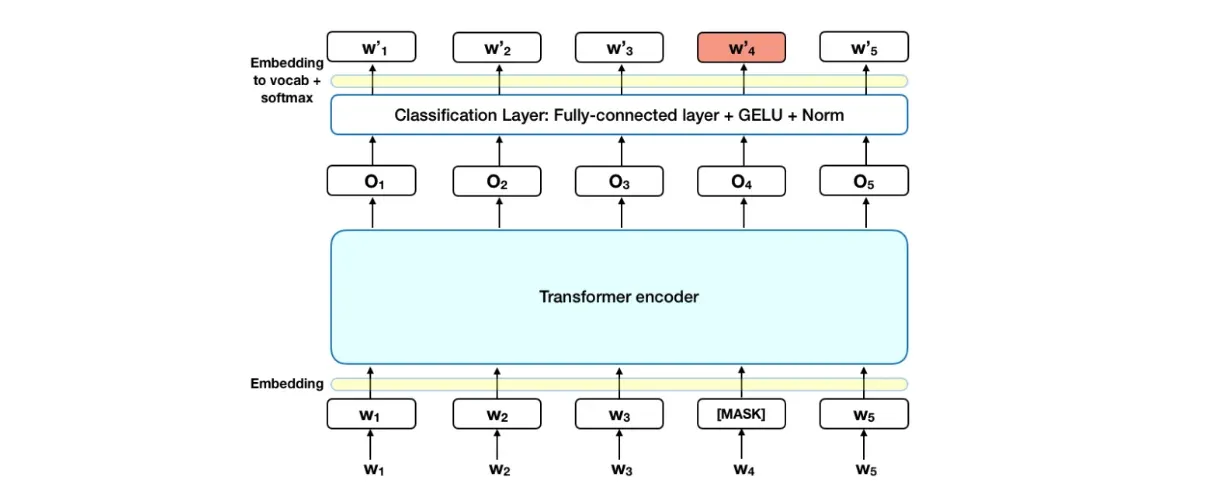
Transformer Models in Deep Learning: Latest Advancements
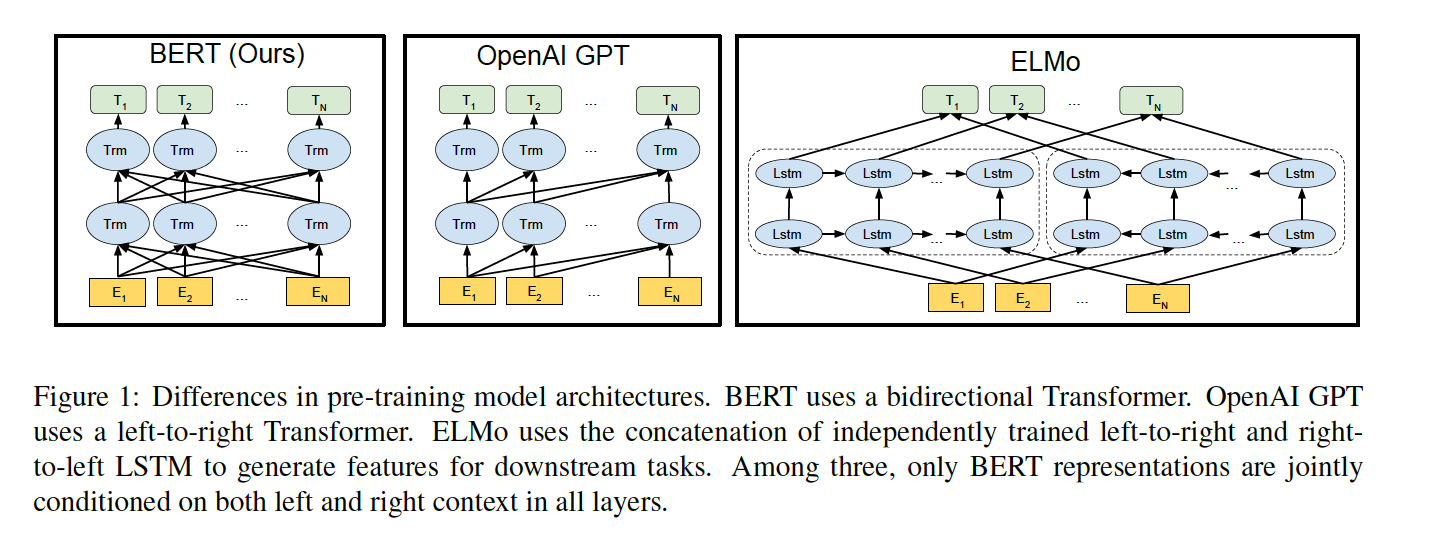
Sequence-To-Sequence, Attention, Transformer — Machine Learning Lecture

BERT 论文精读【Pre-training of Deep Bidirectional Transformers for Language ...
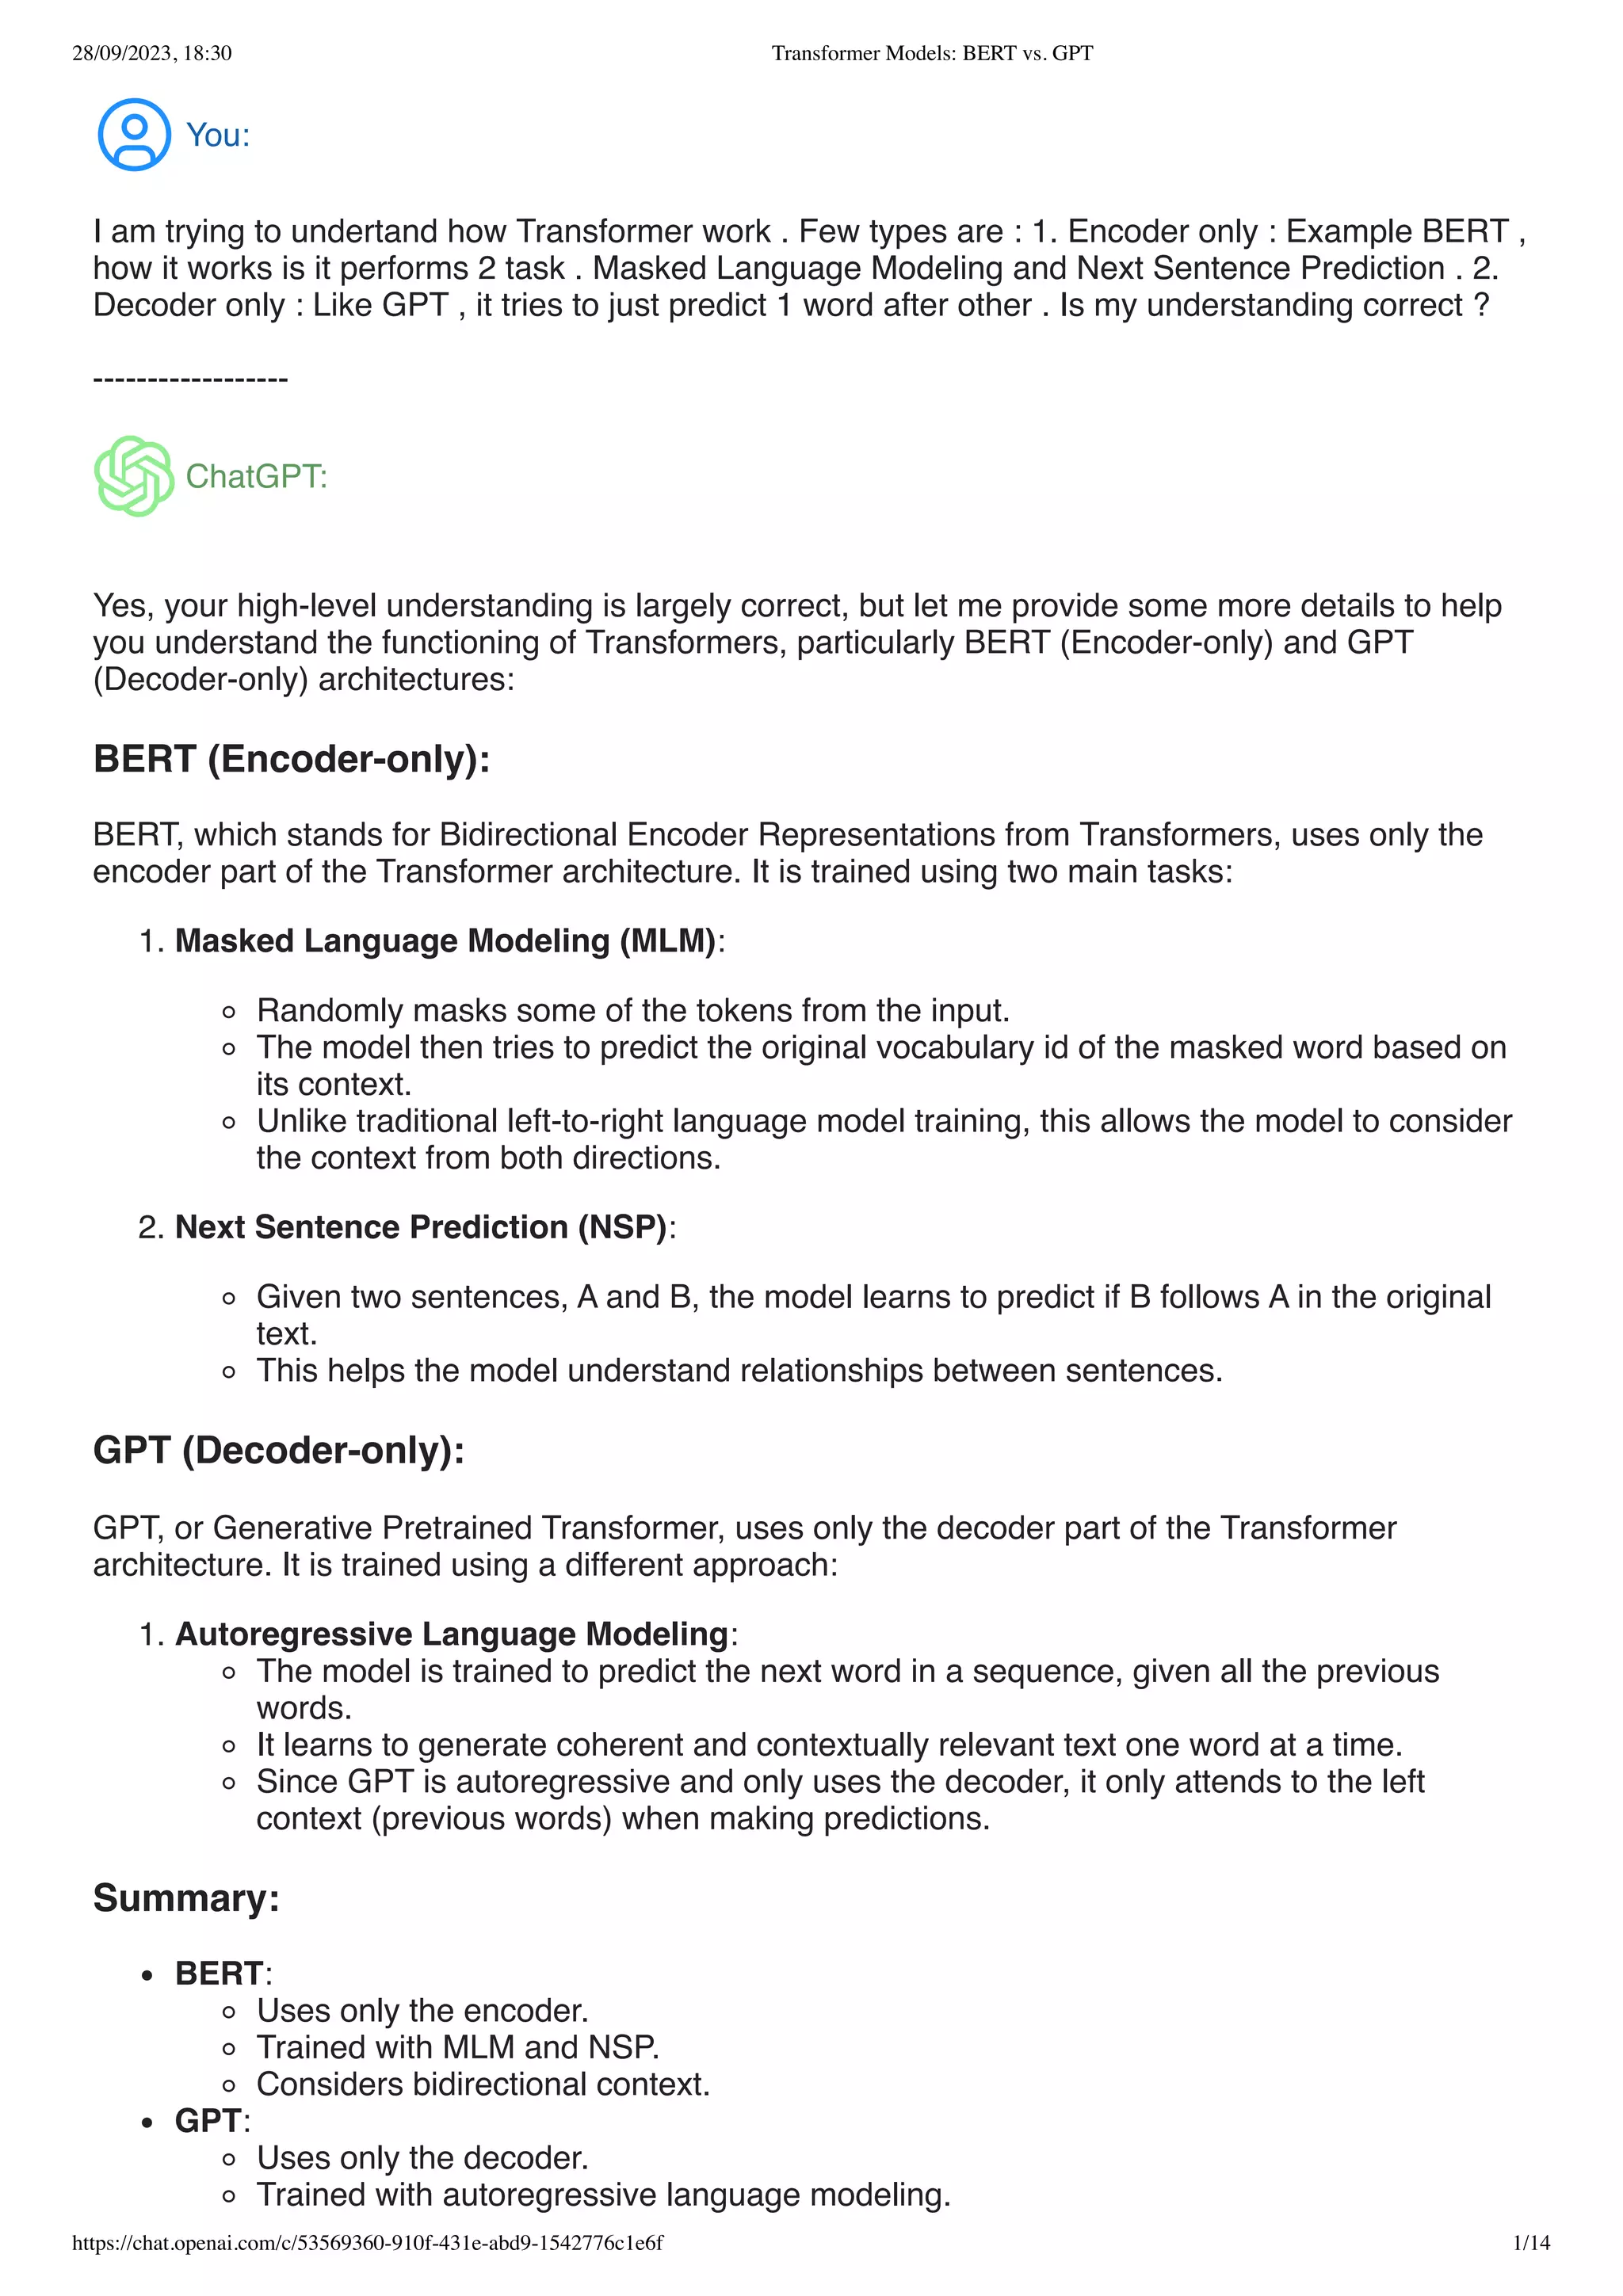
Transformer Models_ BERT vs. GPT.pdf

Deep Learning-Based Short Text Summarization: An Integrated BERT and ...

Sequence-To-Sequence, Attention, Transformer — Machine Learning Lecture

BERT-based transformer encoder architecture | Download Scientific Diagram

Live Session- Encoder Decoder,Attention Models, Transformers, Bert Part ...

Transformer Encoder (Bert)_transformer+encoder++++re+identification+ ...

Deep Learning in Security:BERTモデルを用いたテキストベースのフィッシングメール検知 | Splunk
Advertisement Space (336x280)

A Multiscale Visualization of Attention in the Transformer Model | PDF

CMC | Free Full-Text | Image Captioning Using Multimodal Deep Learning ...
GPT Transformer Bert对比分析_transformer bert gpt-CSDN博客

Encoders and Decoders in Transformer Models - MachineLearningMastery.com

Short-Text Sentiment Classification Model Based on BERT and Dual-Stream ...

A Brief Introduction to BERT - MachineLearningMastery.com

BERT, GPT, and T5 — the transformer brothers | by Zhihan Lu | Medium
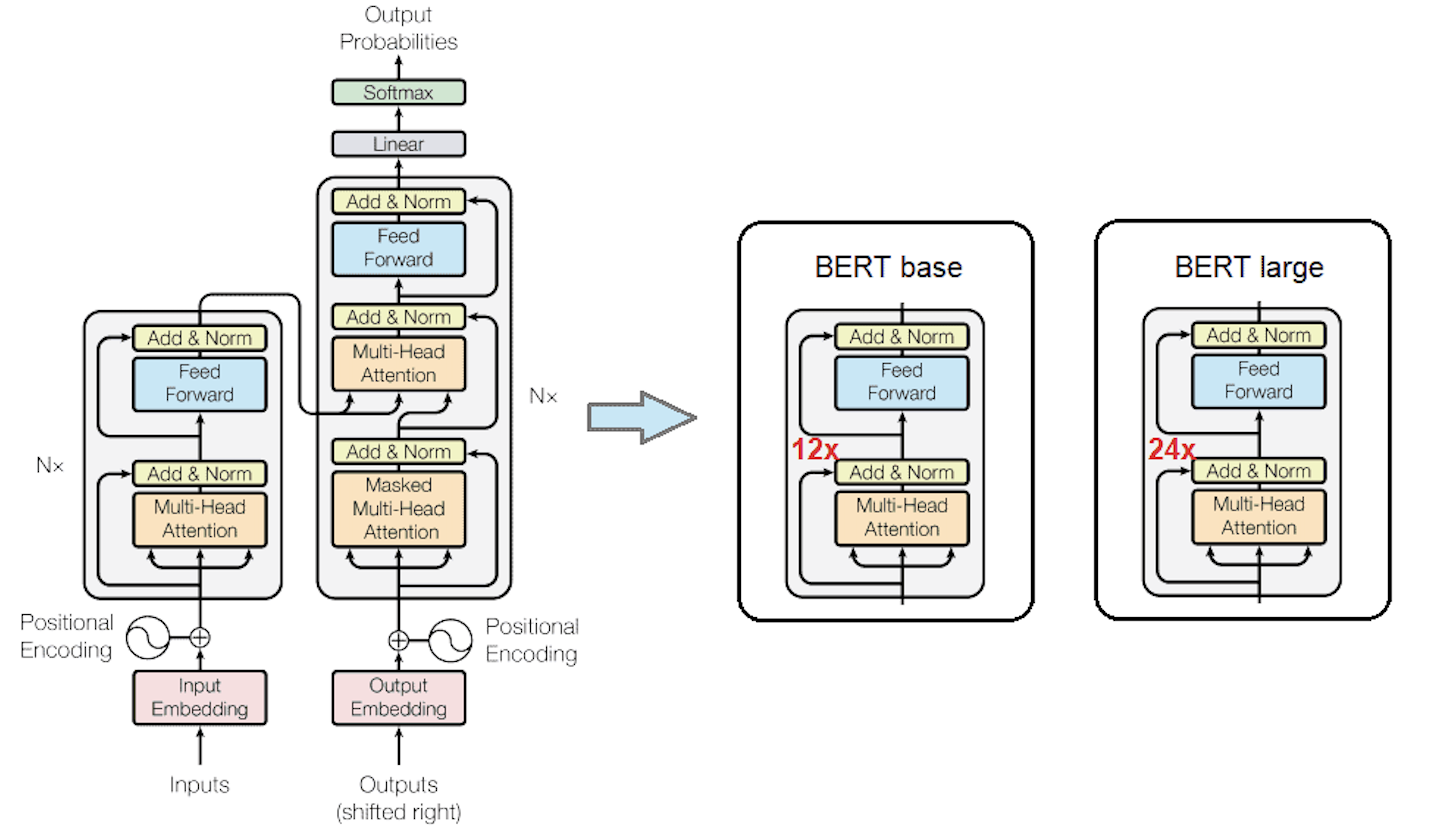
BERT: Bidirectional Encoder Representations from Transformers
Structure of encoder representations from transformers (BERT) mode ...

Loss Functions in Deep Learning: A Comprehensive Review | by Vikranth ...
Advertisement Space (336x280)

GPT vs BERT - GeeksforGeeks
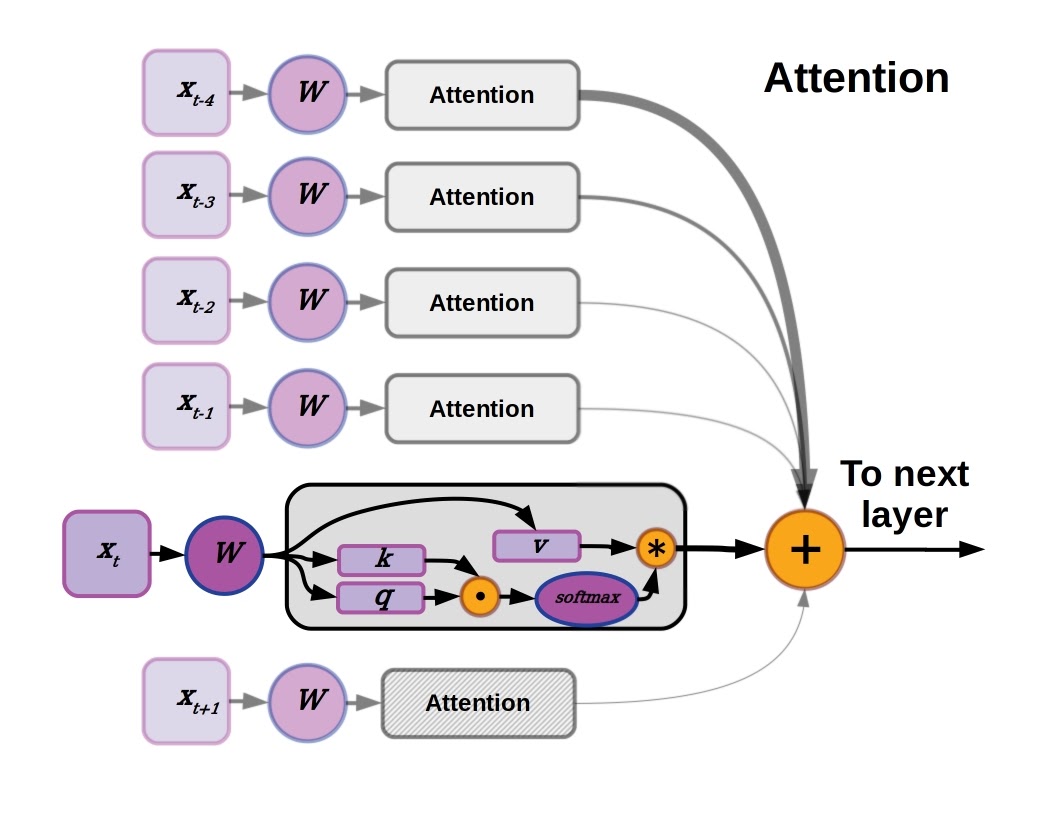
Transformer Nlp

Kirill Eremenko on LinkedIn: TRANSFORMER VARIATIONS (GPT vs. BERT) Do ...
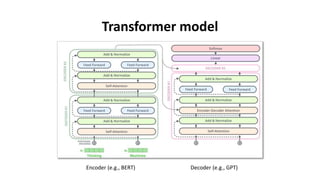
attention mechanism need_transformers.pptx

BERT: Pre-training of Deep Bidirectional Transformers for Language ...

BERT: Pre-training of Deep Bidirectional Transformers for Language ...