
1 Embedding Gpu Embedding Gpu Csdn

仅需1% Embedding 参数,硬件成本降低百倍,开源方案单GPU训练超大推荐模型_向量数据库 embedding gpu 要求-CSDN博客
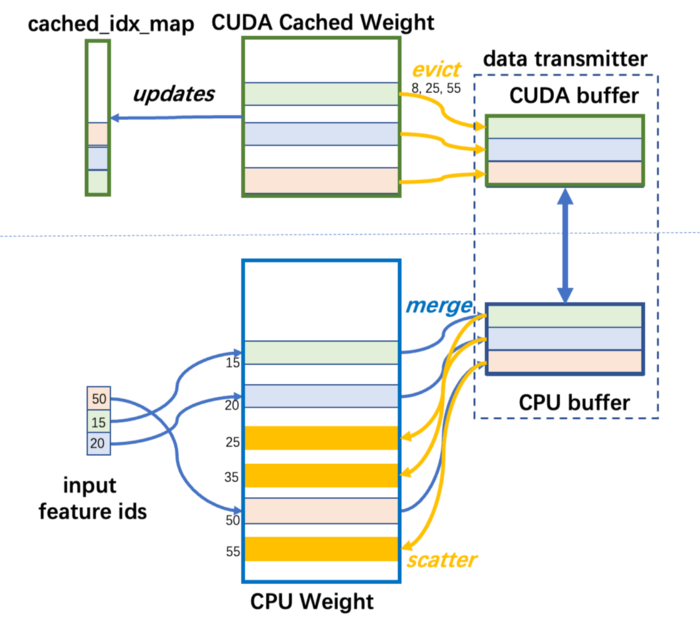
Embedding Training With 1% GPU Memory and 100 Times Less Budget, an ...

Embedding Training With 1% GPU Memory and 100 Times Less Budget, an ...
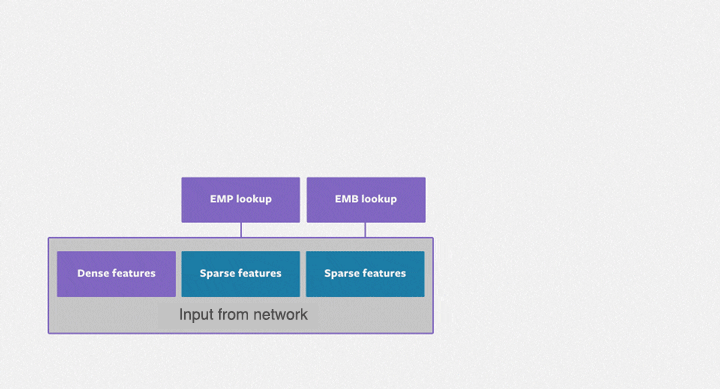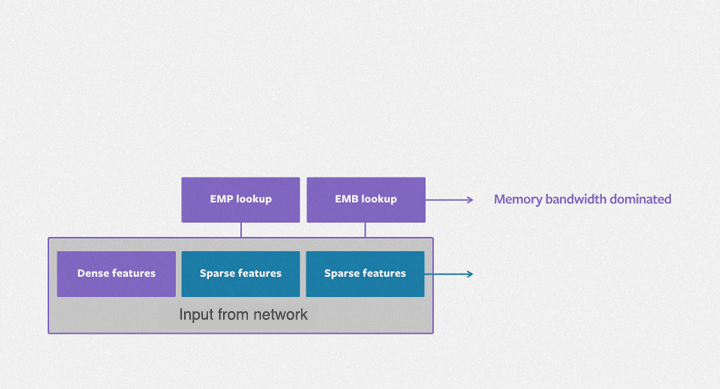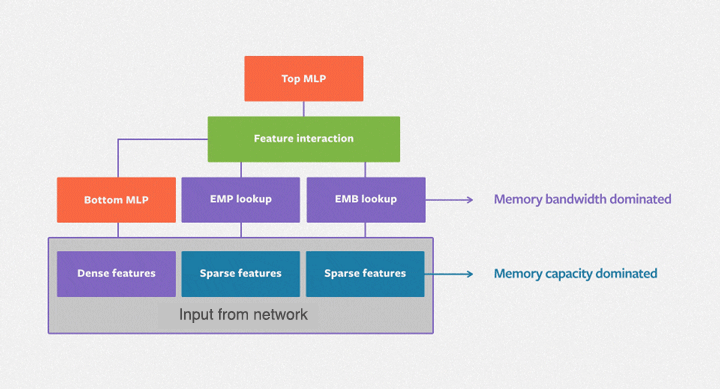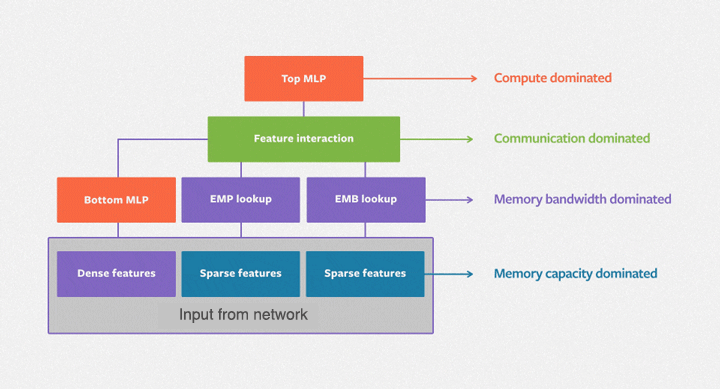
Embedding Training With 1% GPU Memory and 100 Times Less Budget, an ...
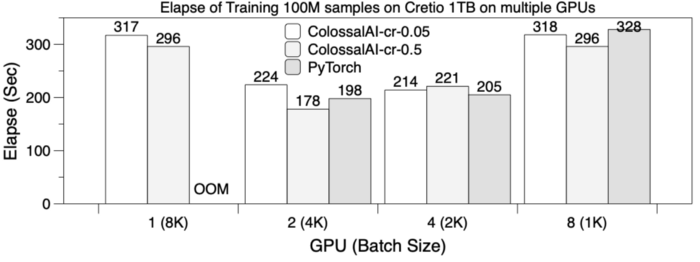
Embedding Training With 1% GPU Memory and 100 Times Less Budget, an ...

Embedding Training With 1% GPU Memory and 100 Times Less Budget, an ...
Embedding Training With 1% GPU Memory and 100 Times Less Budget, an ...
GPU embedding · Issue #42 · mat10d/EvolvePro · GitHub

(PDF) Embedding GPU Computations in Hadoop

Embedding Training With 1% GPU Memory and 100 Times Less Budget, an ...
Advertisement Space (300x250)

Near-100% GPU Utilization: Embedding Millions of Text Documents With ...

Embedding Training With 1% GPU Memory and 100 Times Less Budget, an ...
Embedding Training With 1% GPU Memory and 100 Times Less Budget, an ...

Efficient Graph Embedding at Scale: Optimizing CPU-GPU-SSD Integration
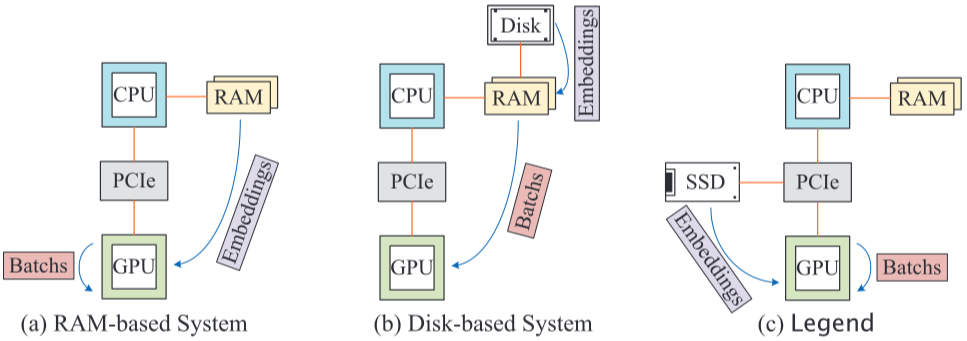
[论文评述] Efficient Graph Embedding at Scale: Optimizing CPU-GPU-SSD ...

(PDF) Architectural Implications of Embedding Dimension during GCN on ...
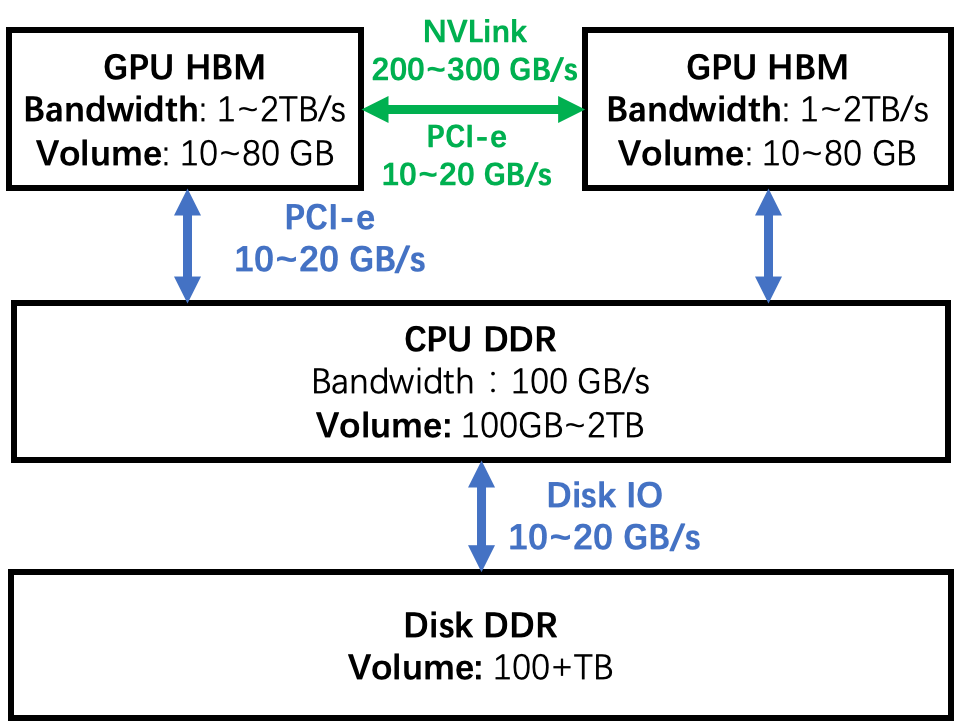
仅需1% Embedding 参数,硬件成本降低百倍,开源方案单GPU训练超大推荐模型 - 知乎
Unlocking Multi-GPU Power for Lightning-Fast Image Embedding | Jian ...
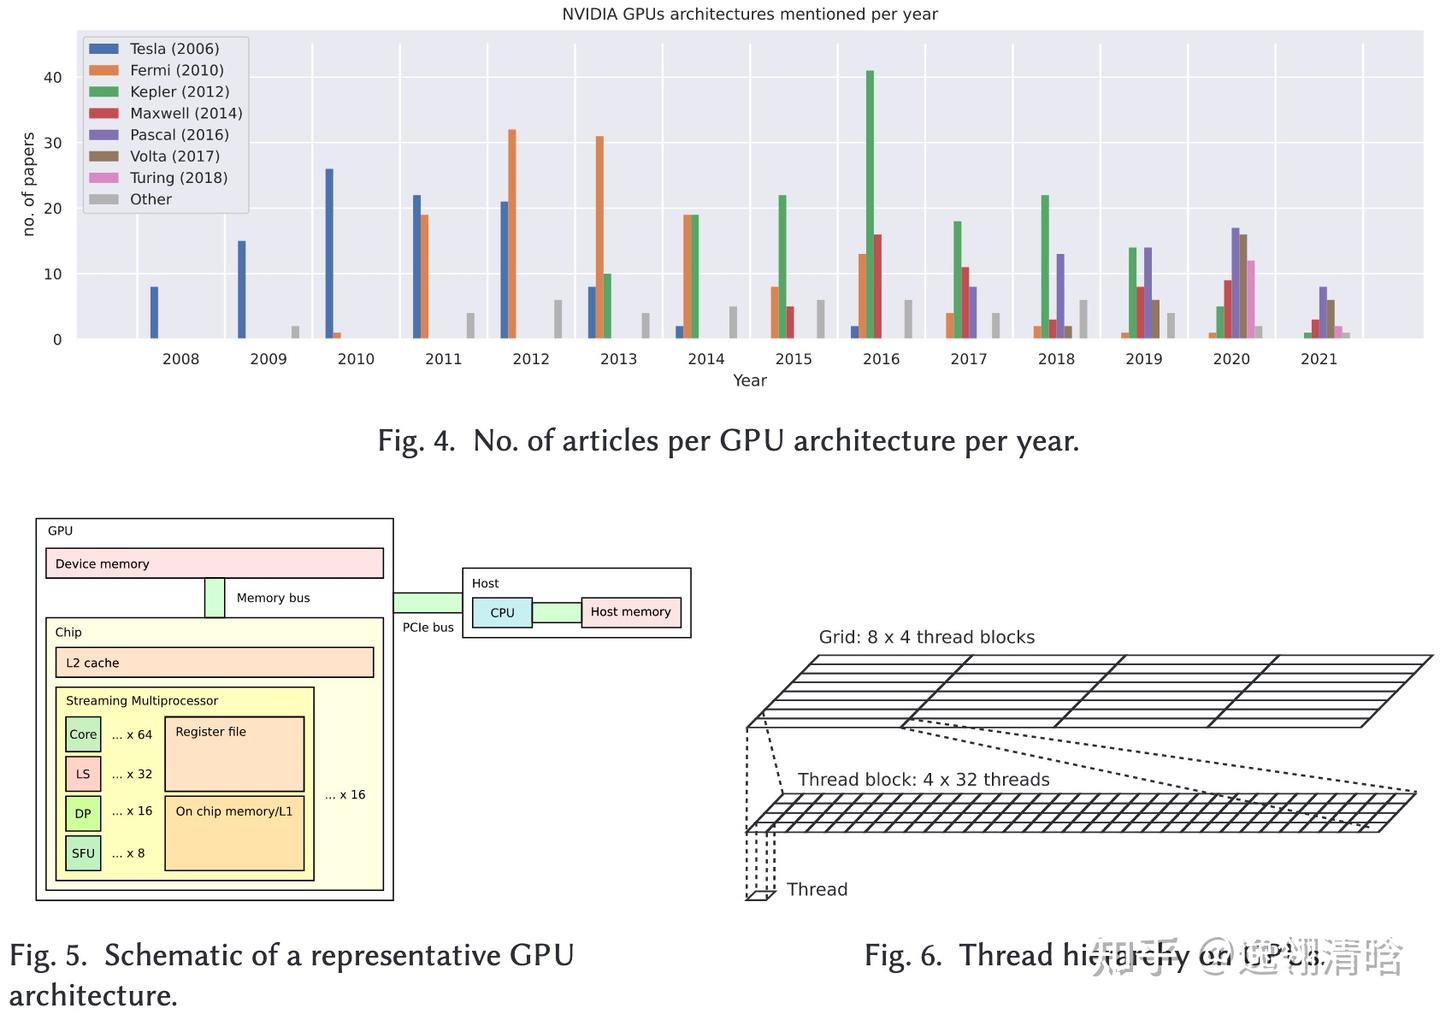
【综述解析·III】Optimization Techniques for GPU Programming(推荐)(上) - 知乎
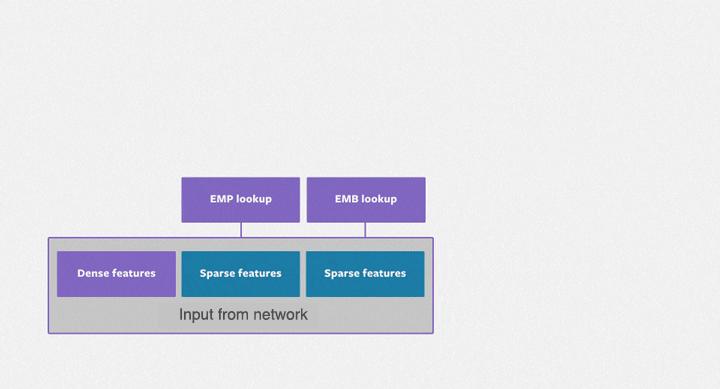
仅需1% Embedding 参数,硬件成本降低百倍,开源方案单GPU训练超大推荐模型 - 知乎
Advertisement Space (336x280)
encoder only embedding model多gpu训练卡住 · Issue #1482 · FlagOpen ...
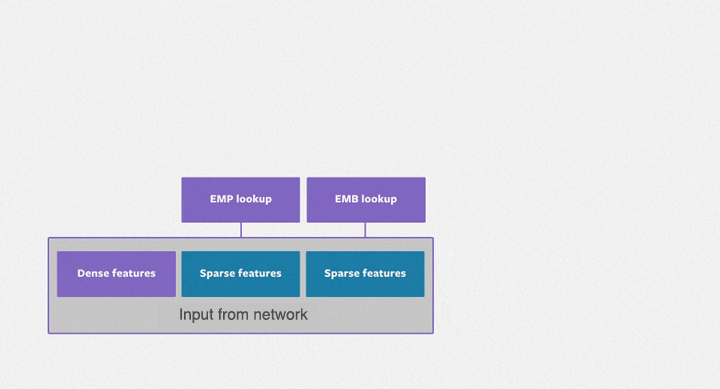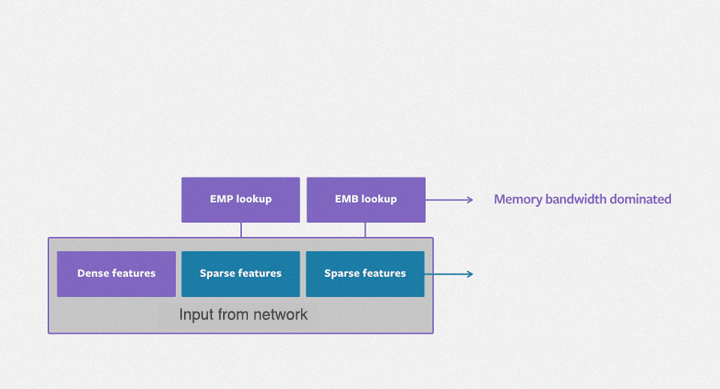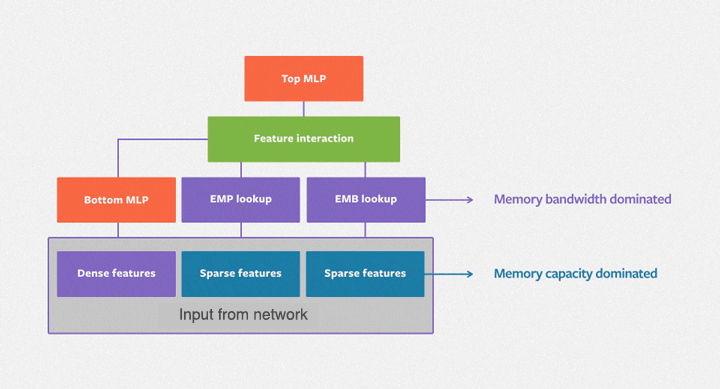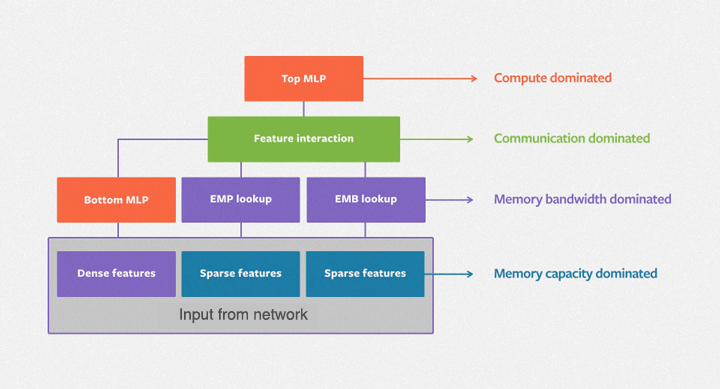
仅需1% Embedding 参数,硬件成本降低百倍,开源方案单GPU训练超大推荐模型 - 知乎

27-1 Embedding Graphics (Intermediate) - YouTube

Why embedding_bag result is different between GPU and CPU impl ...

Day 74/365 of GPU Programming I always found die shots and SM diagrams ...

Day 74/365 of GPU Programming I always found die shots and SM diagrams ...
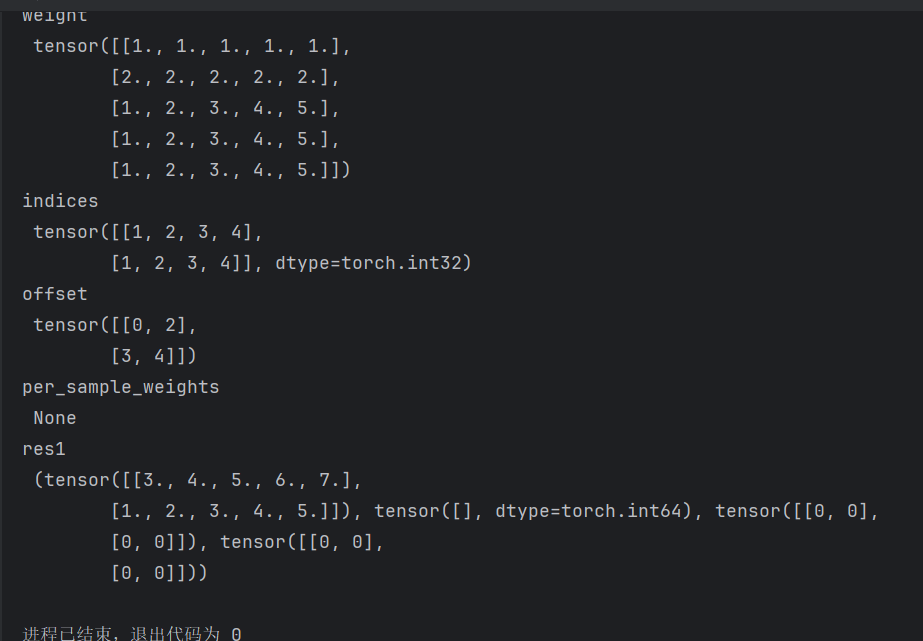
Why embedding_bag result is different between GPU and CPU impl ...
Most embedding infrastructure assumes you know exactly which model you ...
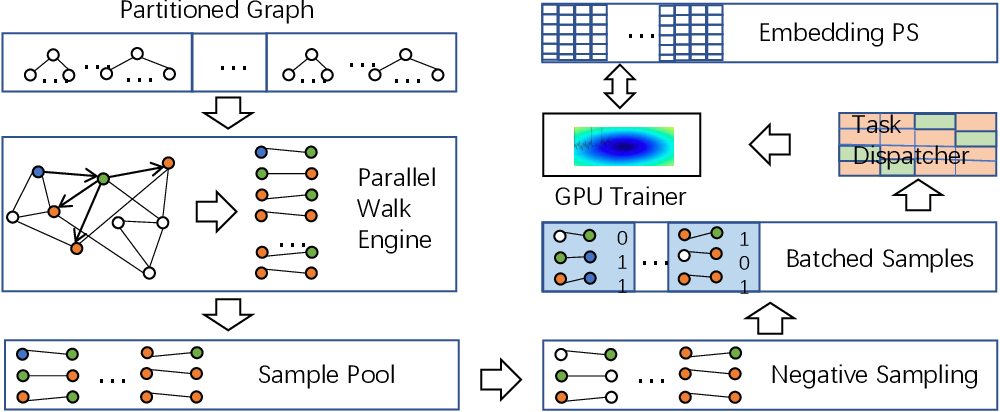
Figure 1 from A Distributed Multi-GPU System for Large-Scale Node ...

仅需1% Embedding参数,硬件成本降低十倍,开源方案单GPU训练超大推荐模型_免费embedding引擎-CSDN博客
Advertisement Space (336x280)
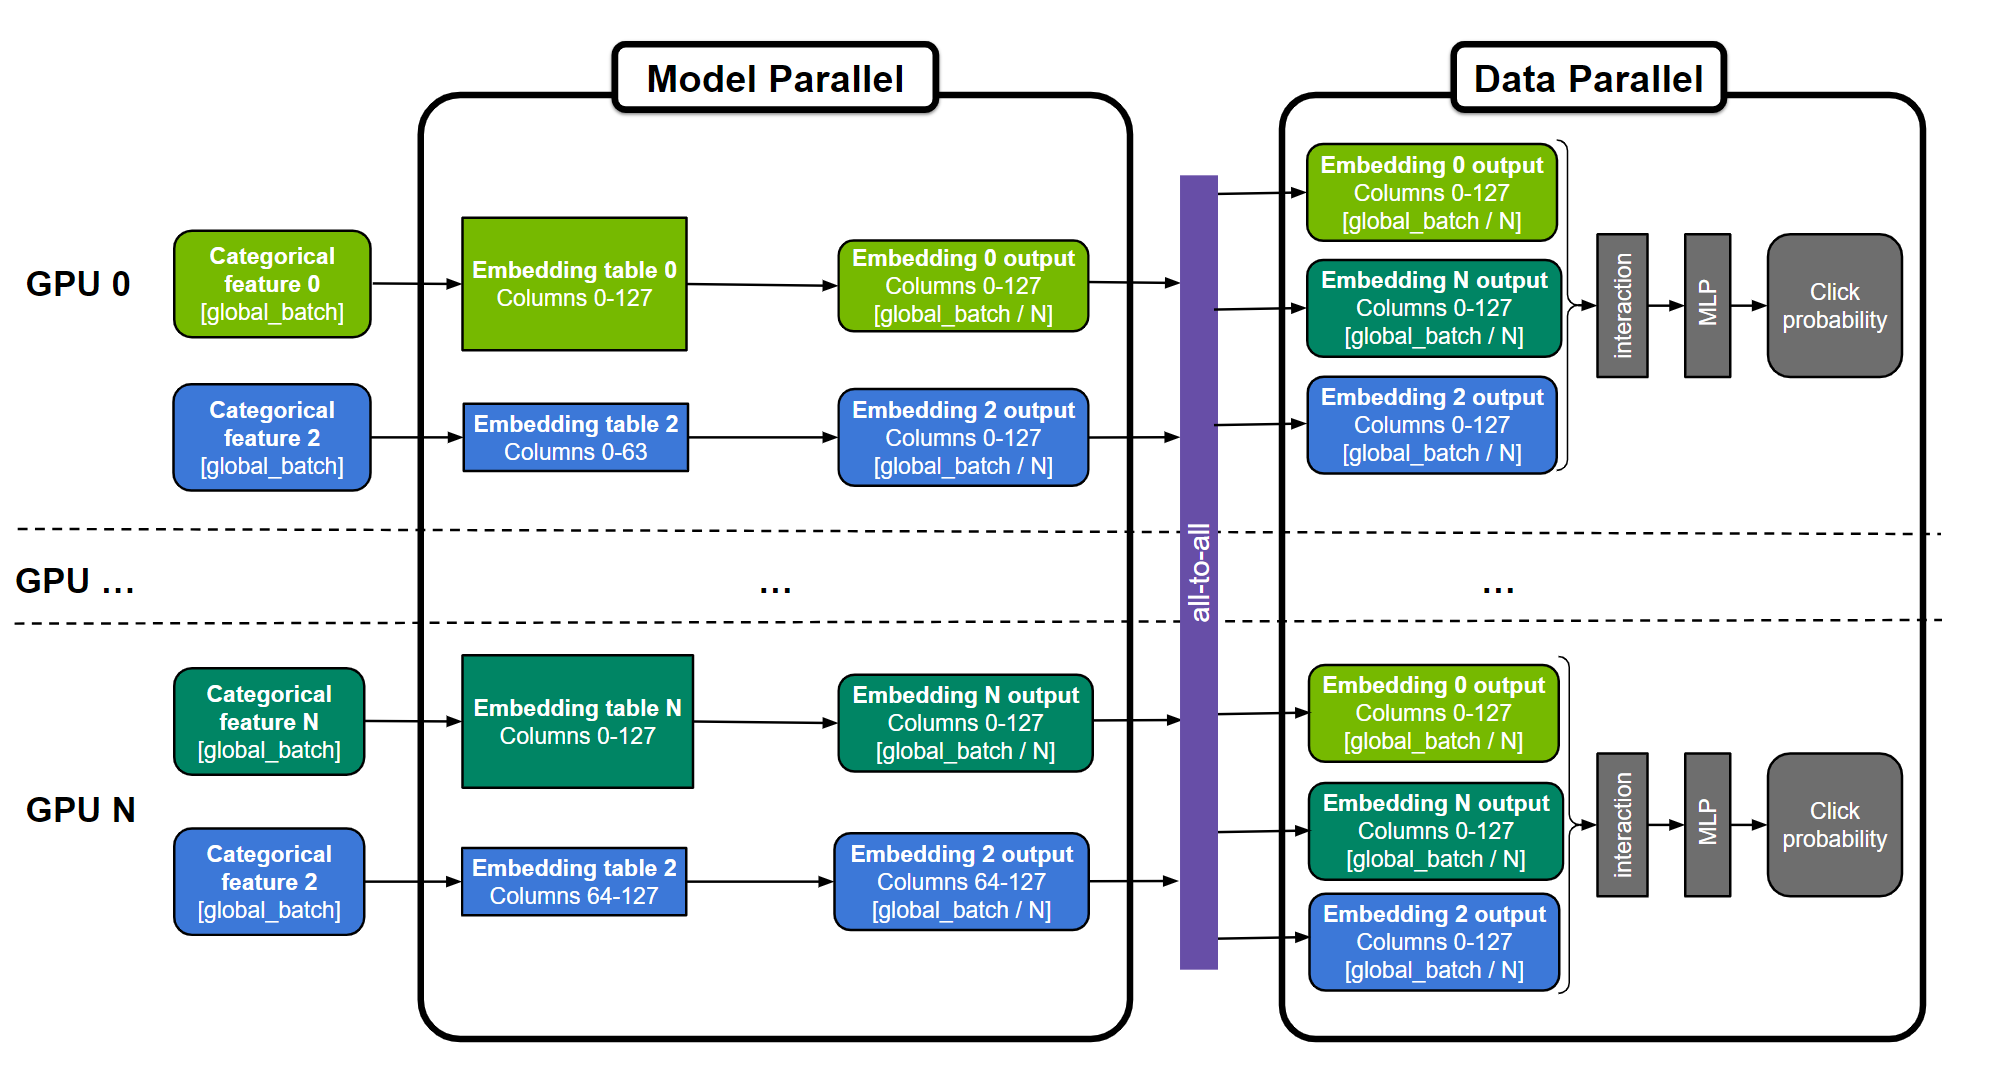
Fast, Terabyte-Scale Recommender Training Made Easy with NVIDIA Merlin ...

Unified and Near-optimal Multi-GPU Cache for Embedding-based Deep ...

万物皆可嵌入--embedding在GPU中的实现_embedding table-CSDN博客

万物皆可嵌入--embedding在GPU中的实现_embedding table-CSDN博客

仅需1% Embedding参数,硬件成本降低十倍,开源方案单GPU训练超大推荐模型_免费embedding引擎-CSDN博客
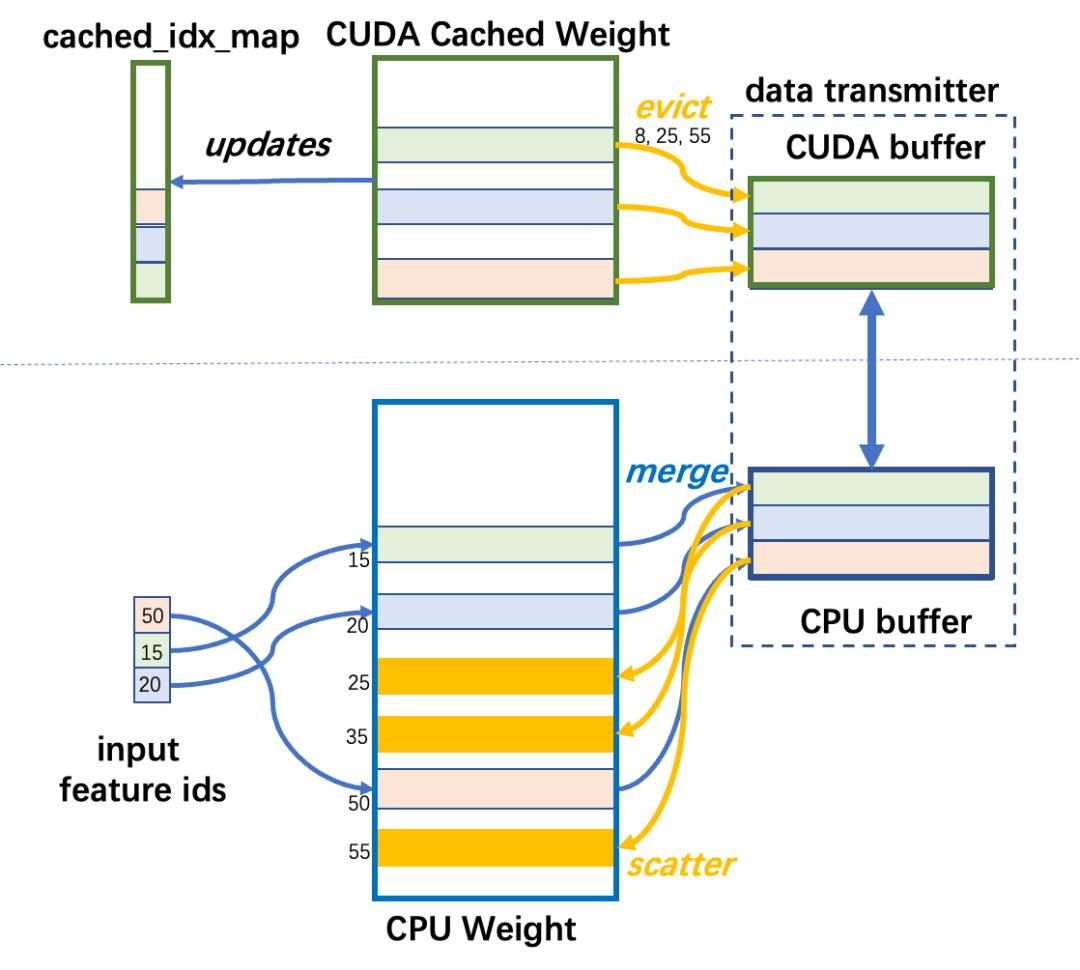
仅需1% Embedding参数,硬件成本降低十倍,开源方案单GPU训练超大推荐模型