
2 Gradient Accumulation
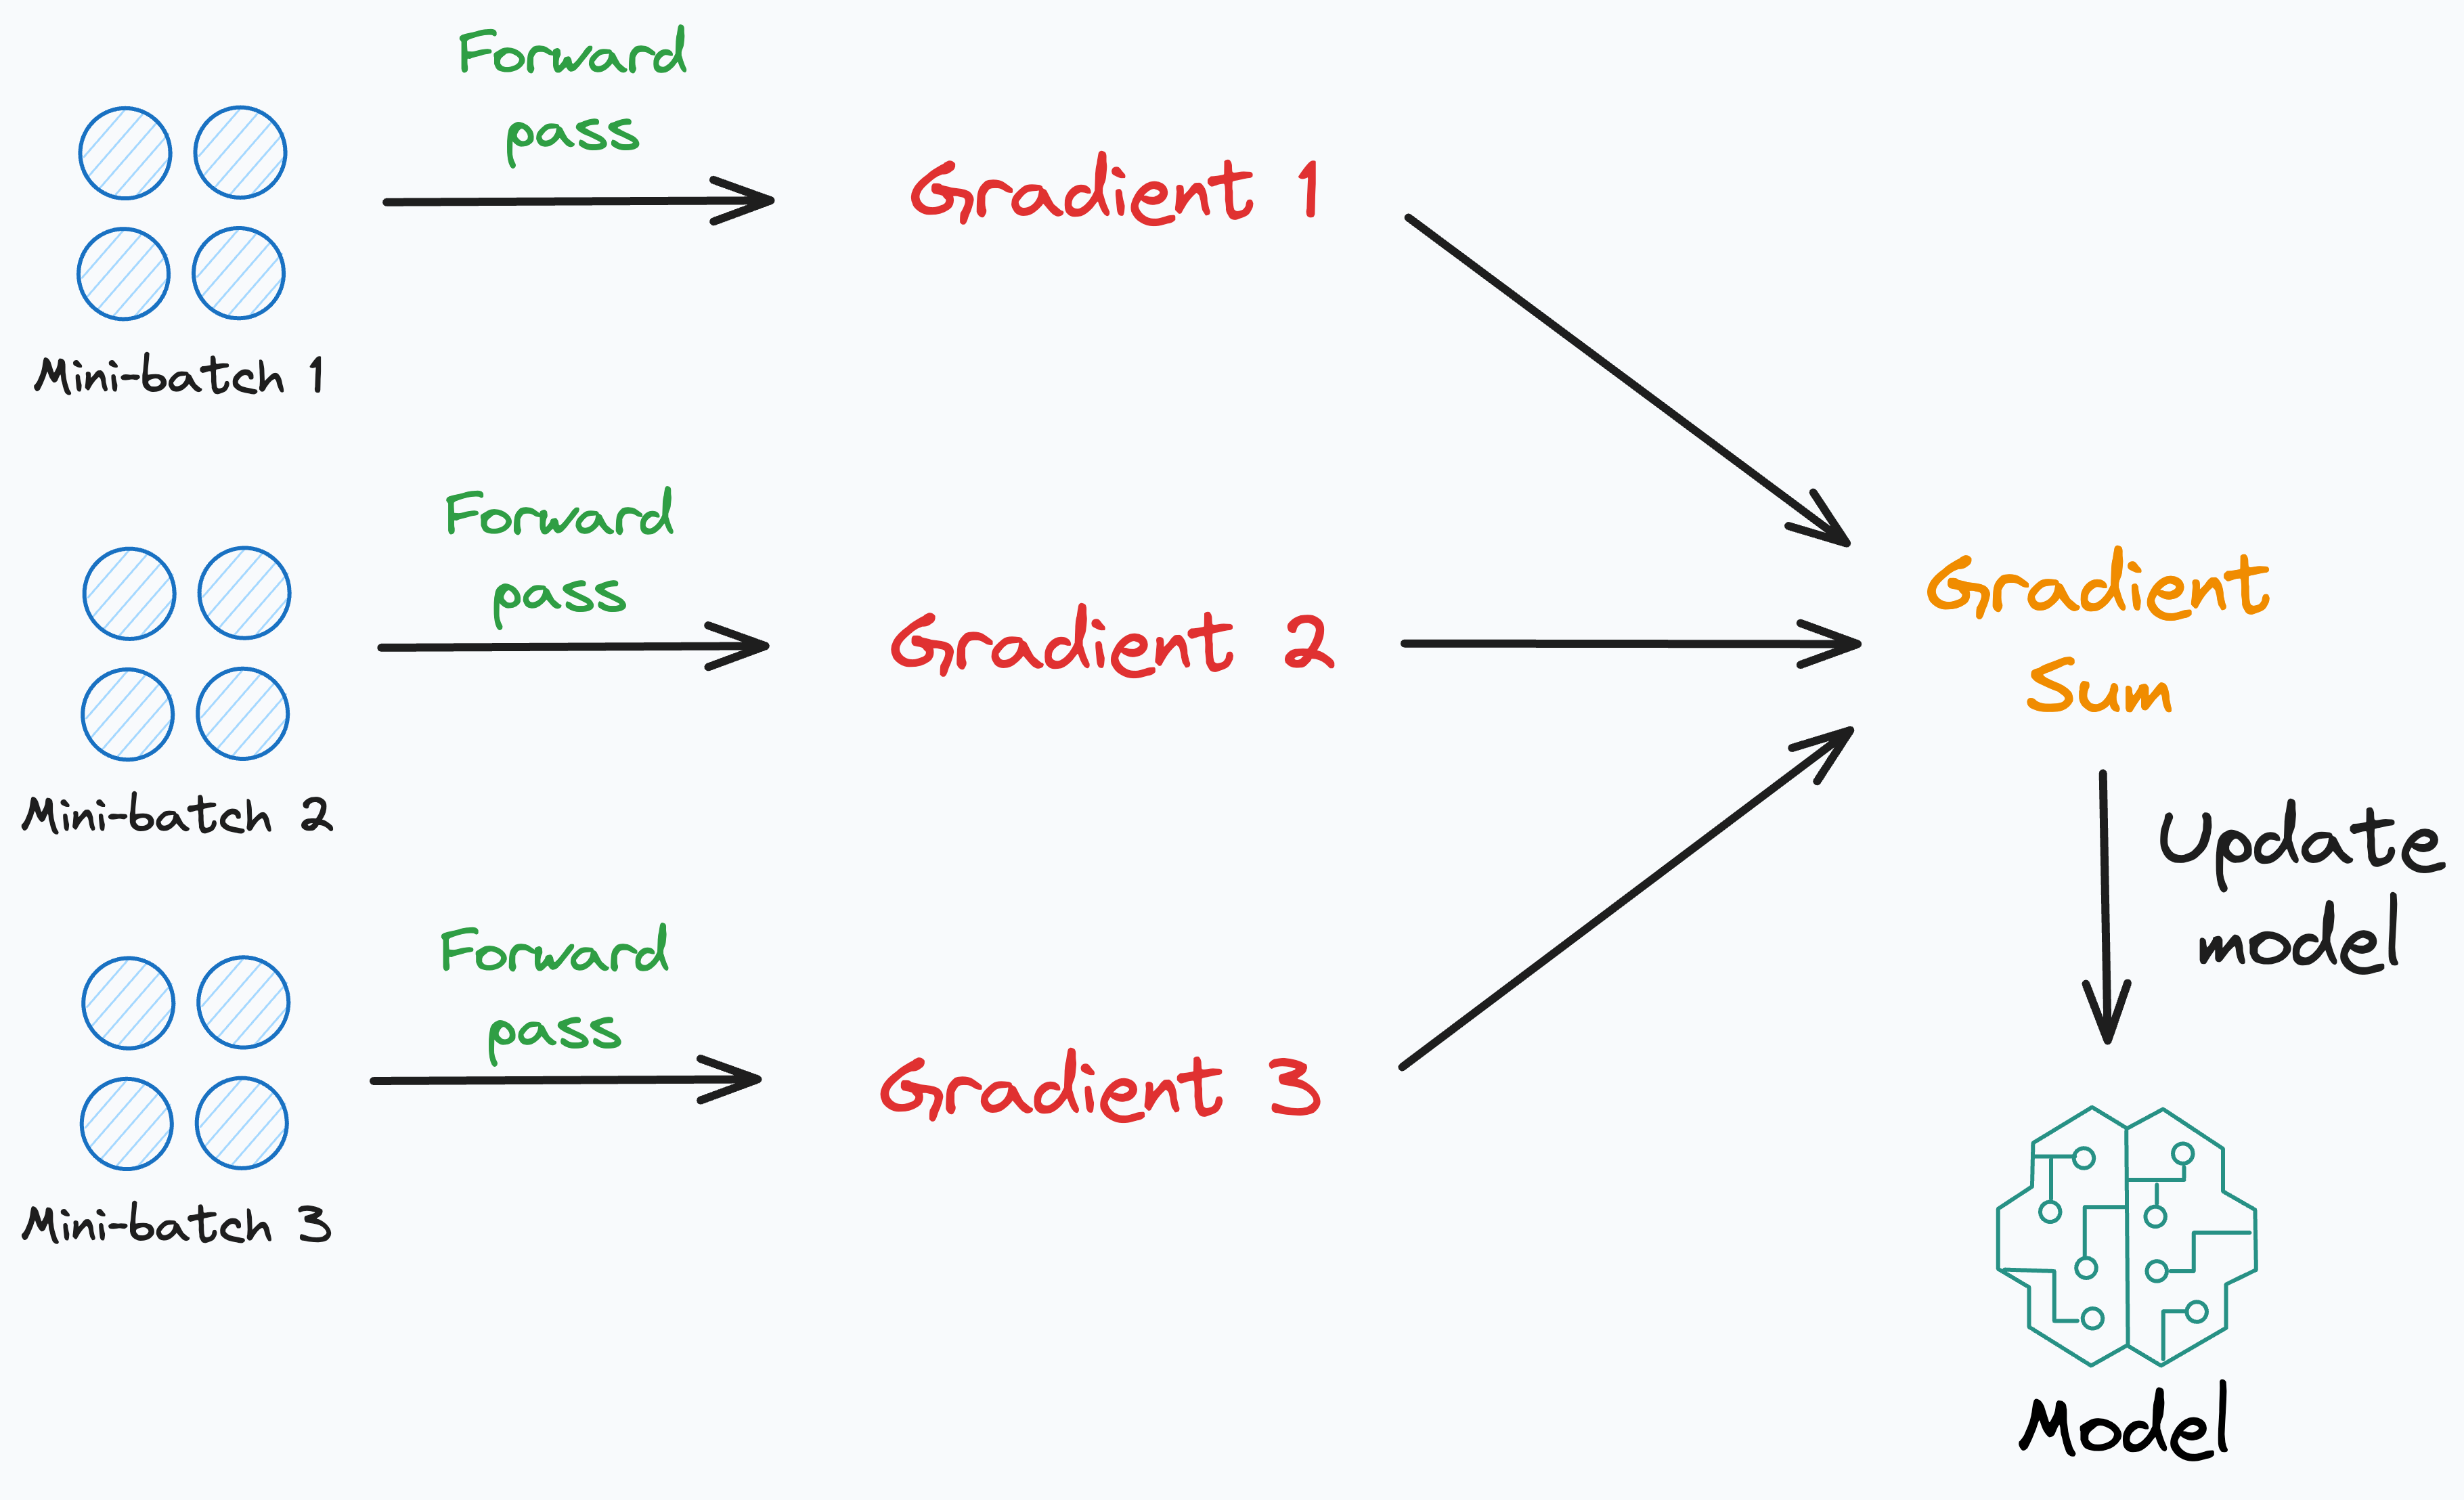
Gradient Accumulation in Neural Networks and How it Works
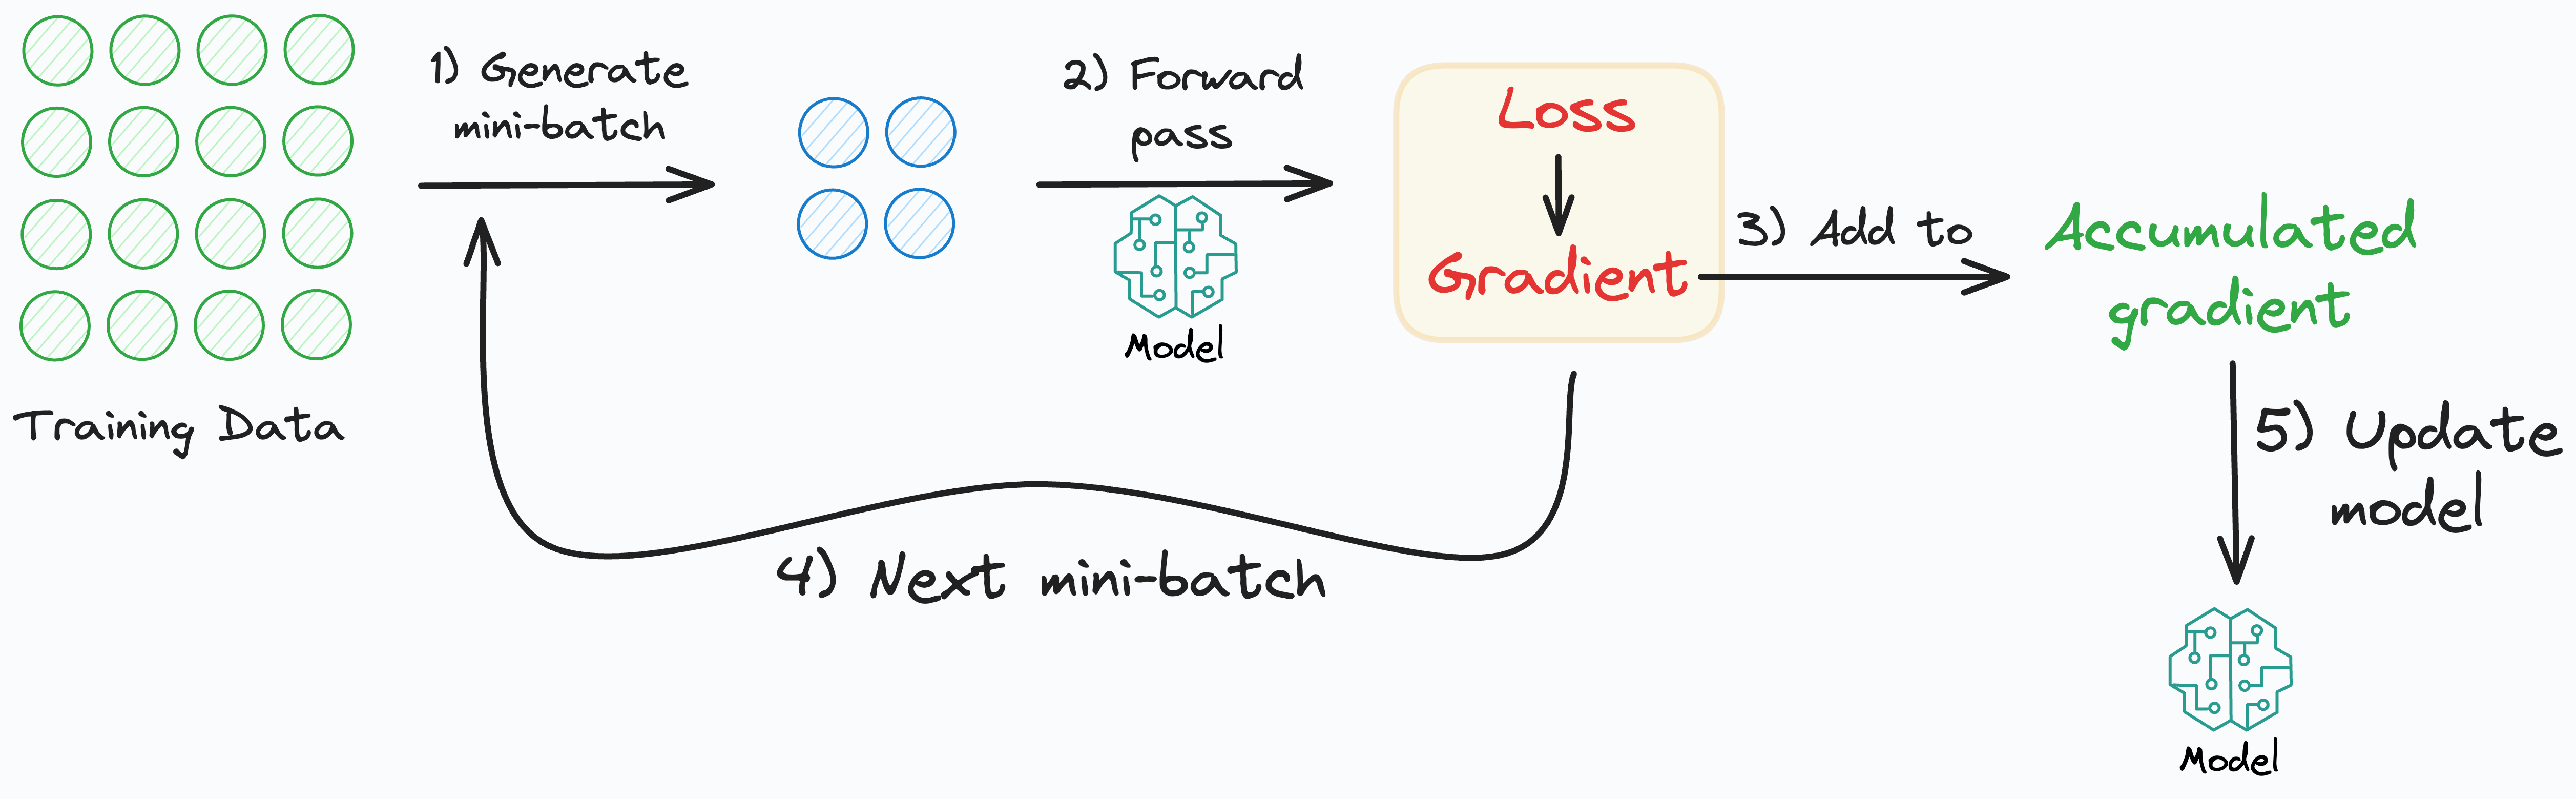
Gradient Accumulation in Neural Networks and How it Works
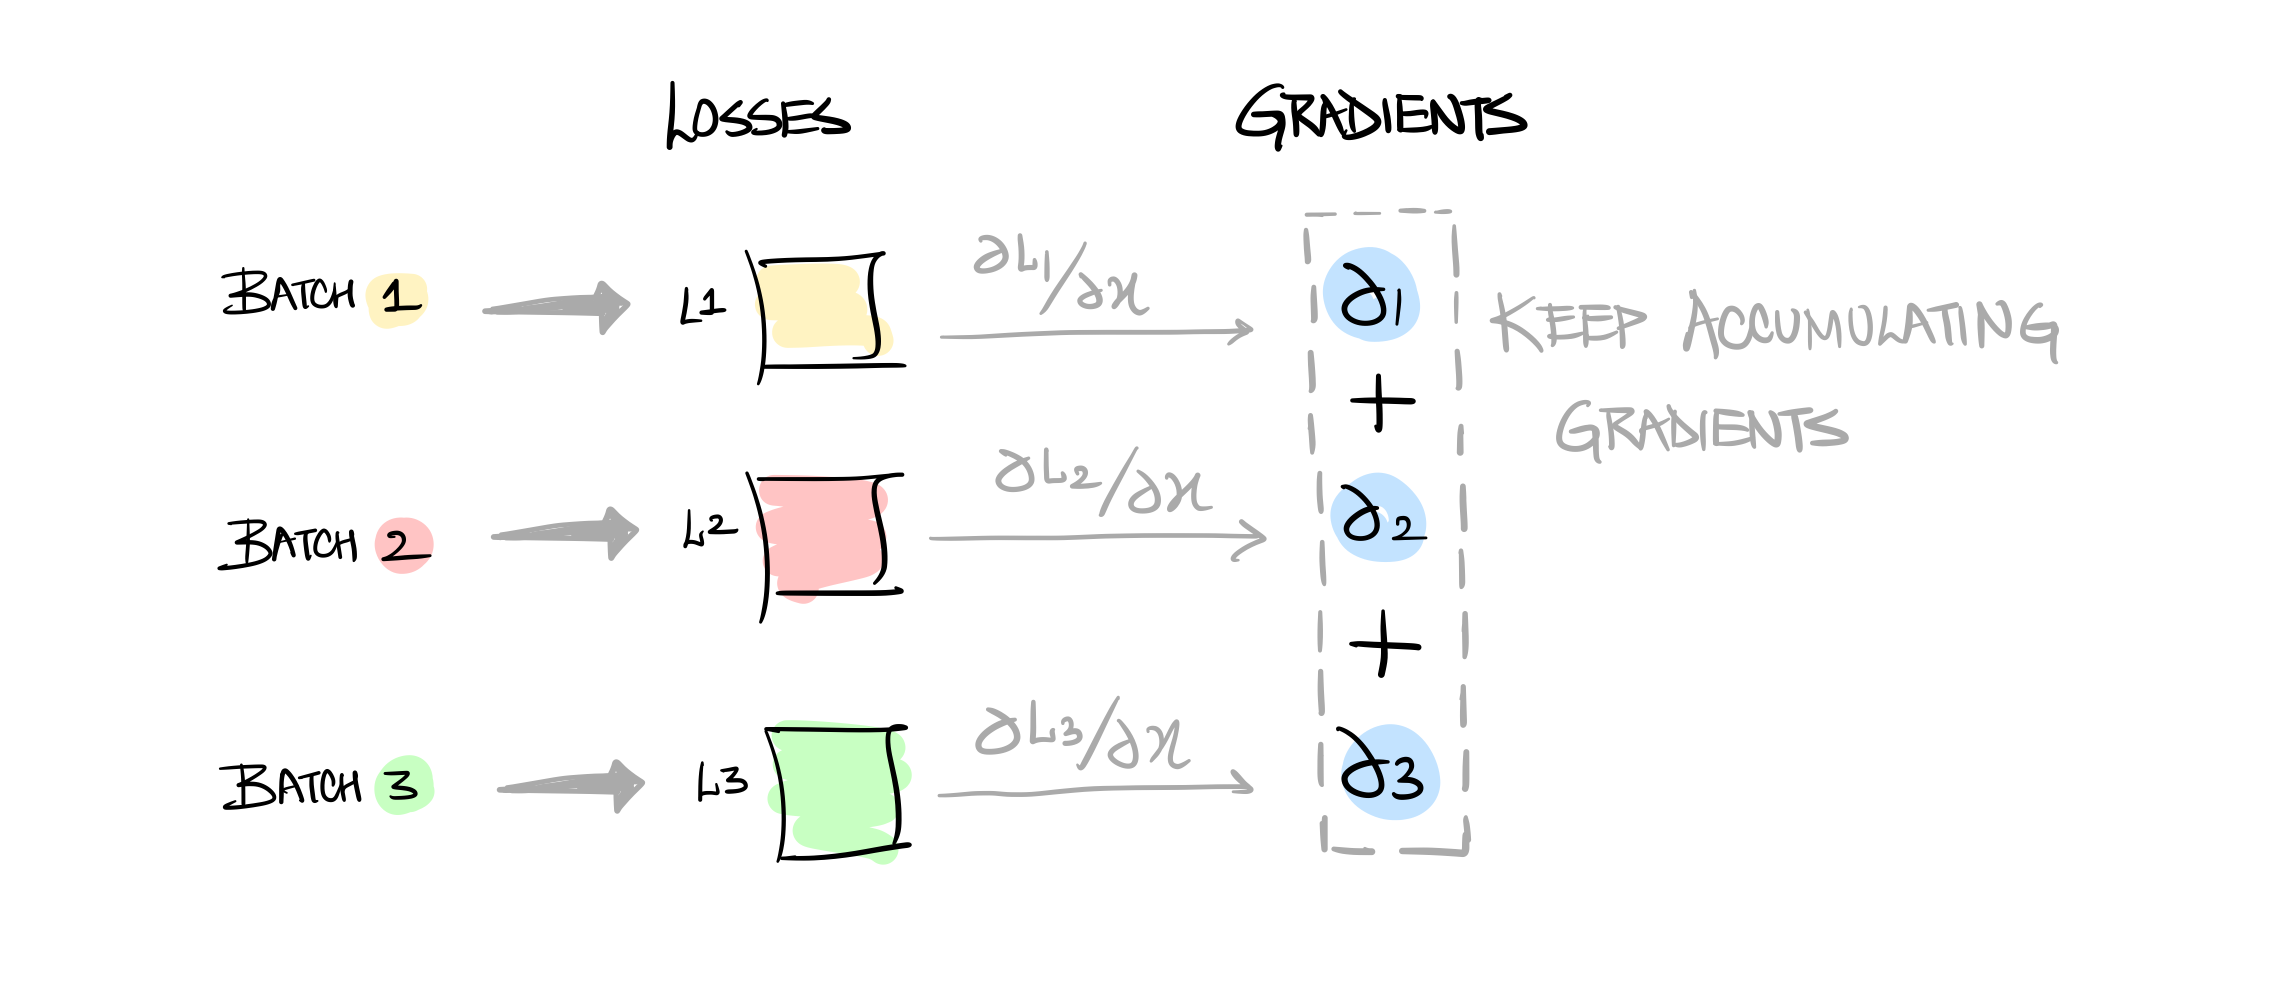
#7 | What is Gradient Accumulation ? - by Harshit Sharma
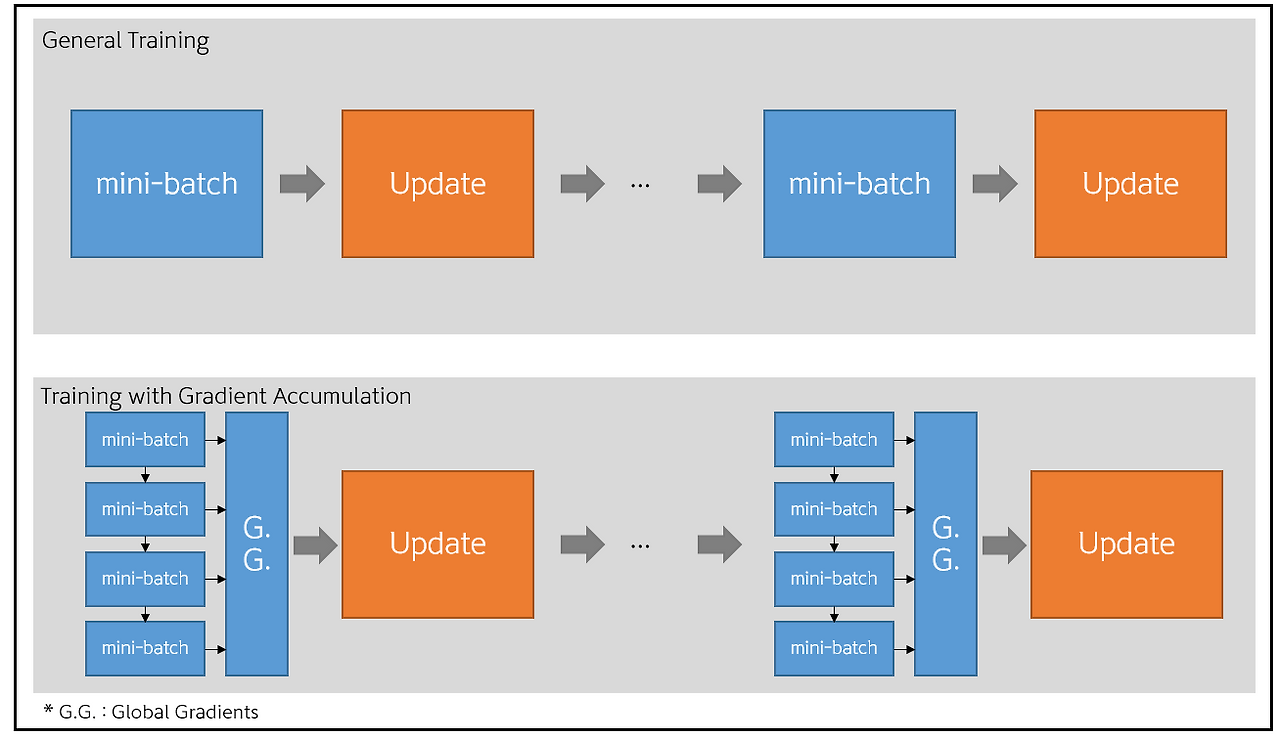
OOM를 해결하기 위한 Gradient Accumulation
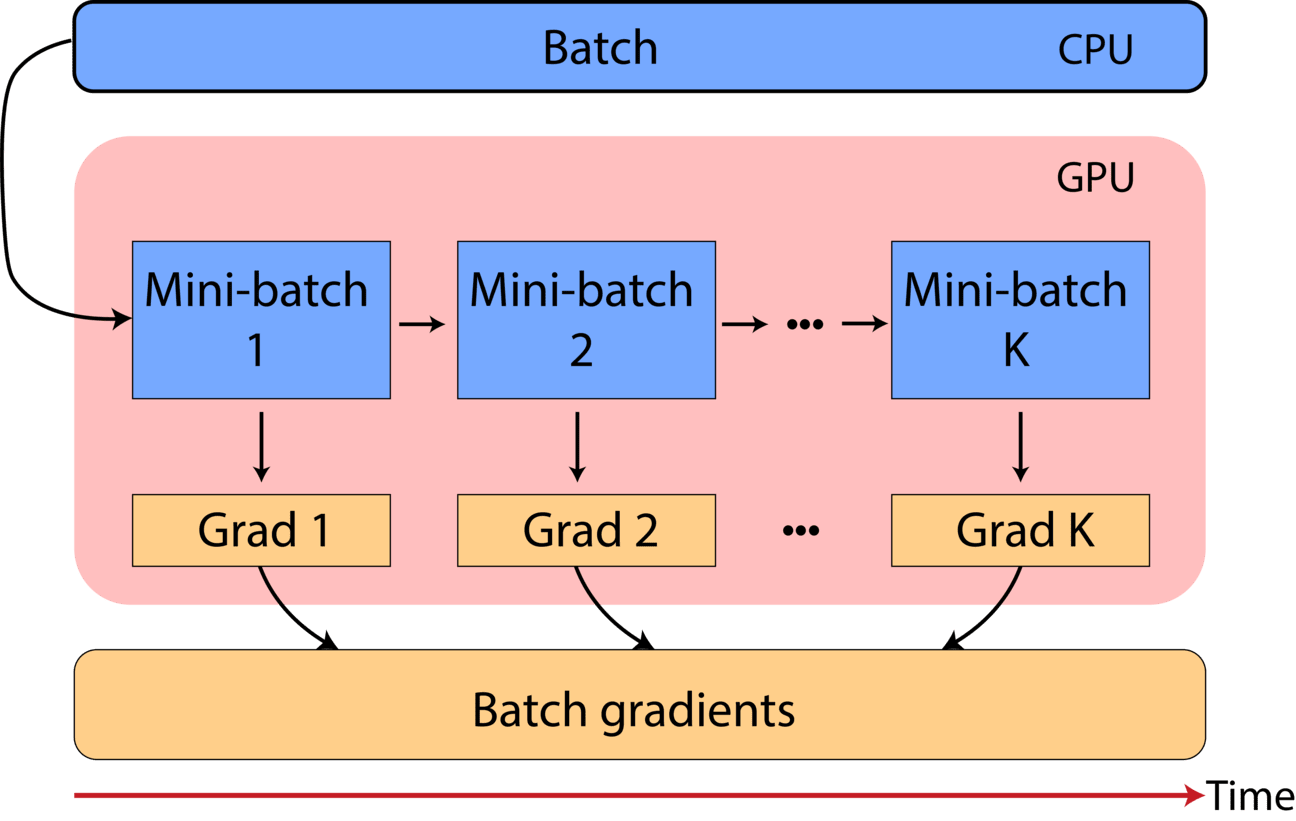
Gradient Accumulation — Python documentation
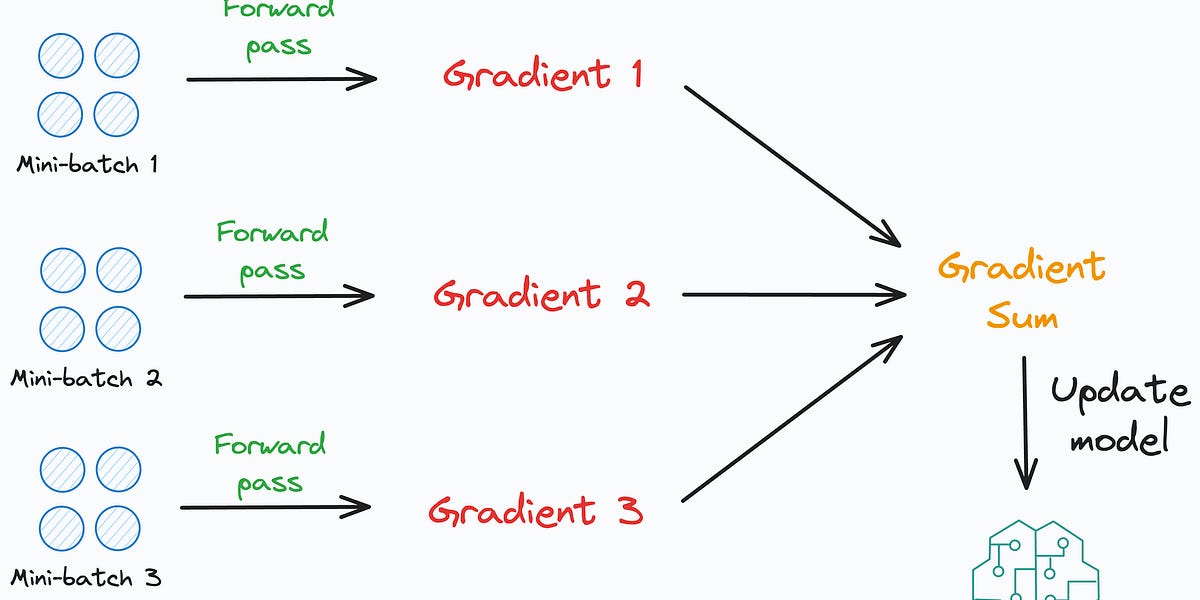
Gradient Accumulation in Neural Networks and How it Works

What is gradient accumulation and how does it work? | Jobanpreet Singh ...
Gradient Accumulation (梯度累积 / 梯度累加) in PyTorch - 技术栈
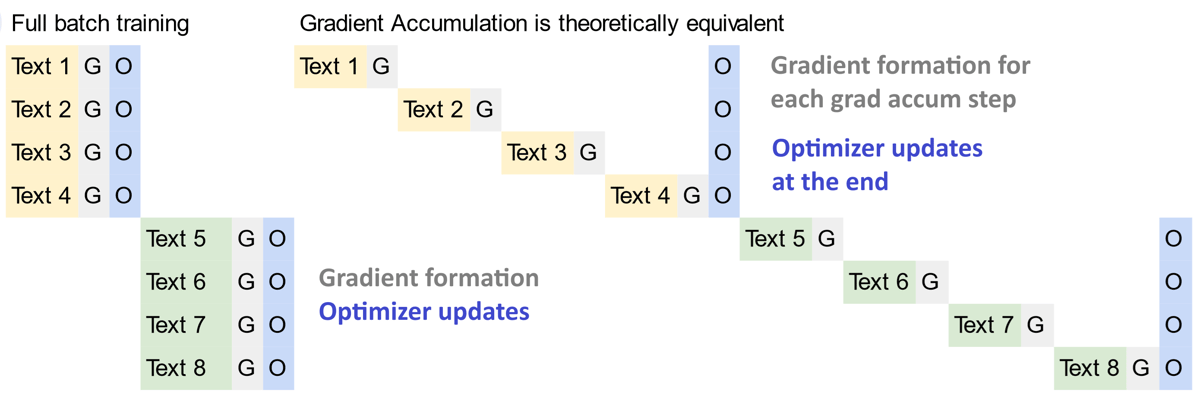
Bug Fixes in LLM Training - Gradient Accumulation

대규모 모델 학습·추론 최적화 시리즈 2편: Gradient Accumulation
Advertisement Space (300x250)
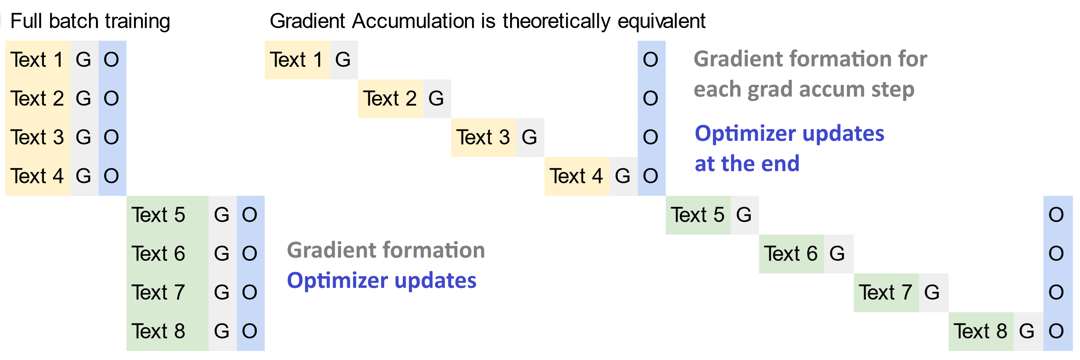
Bug Fixes in LLM Training - Gradient Accumulation
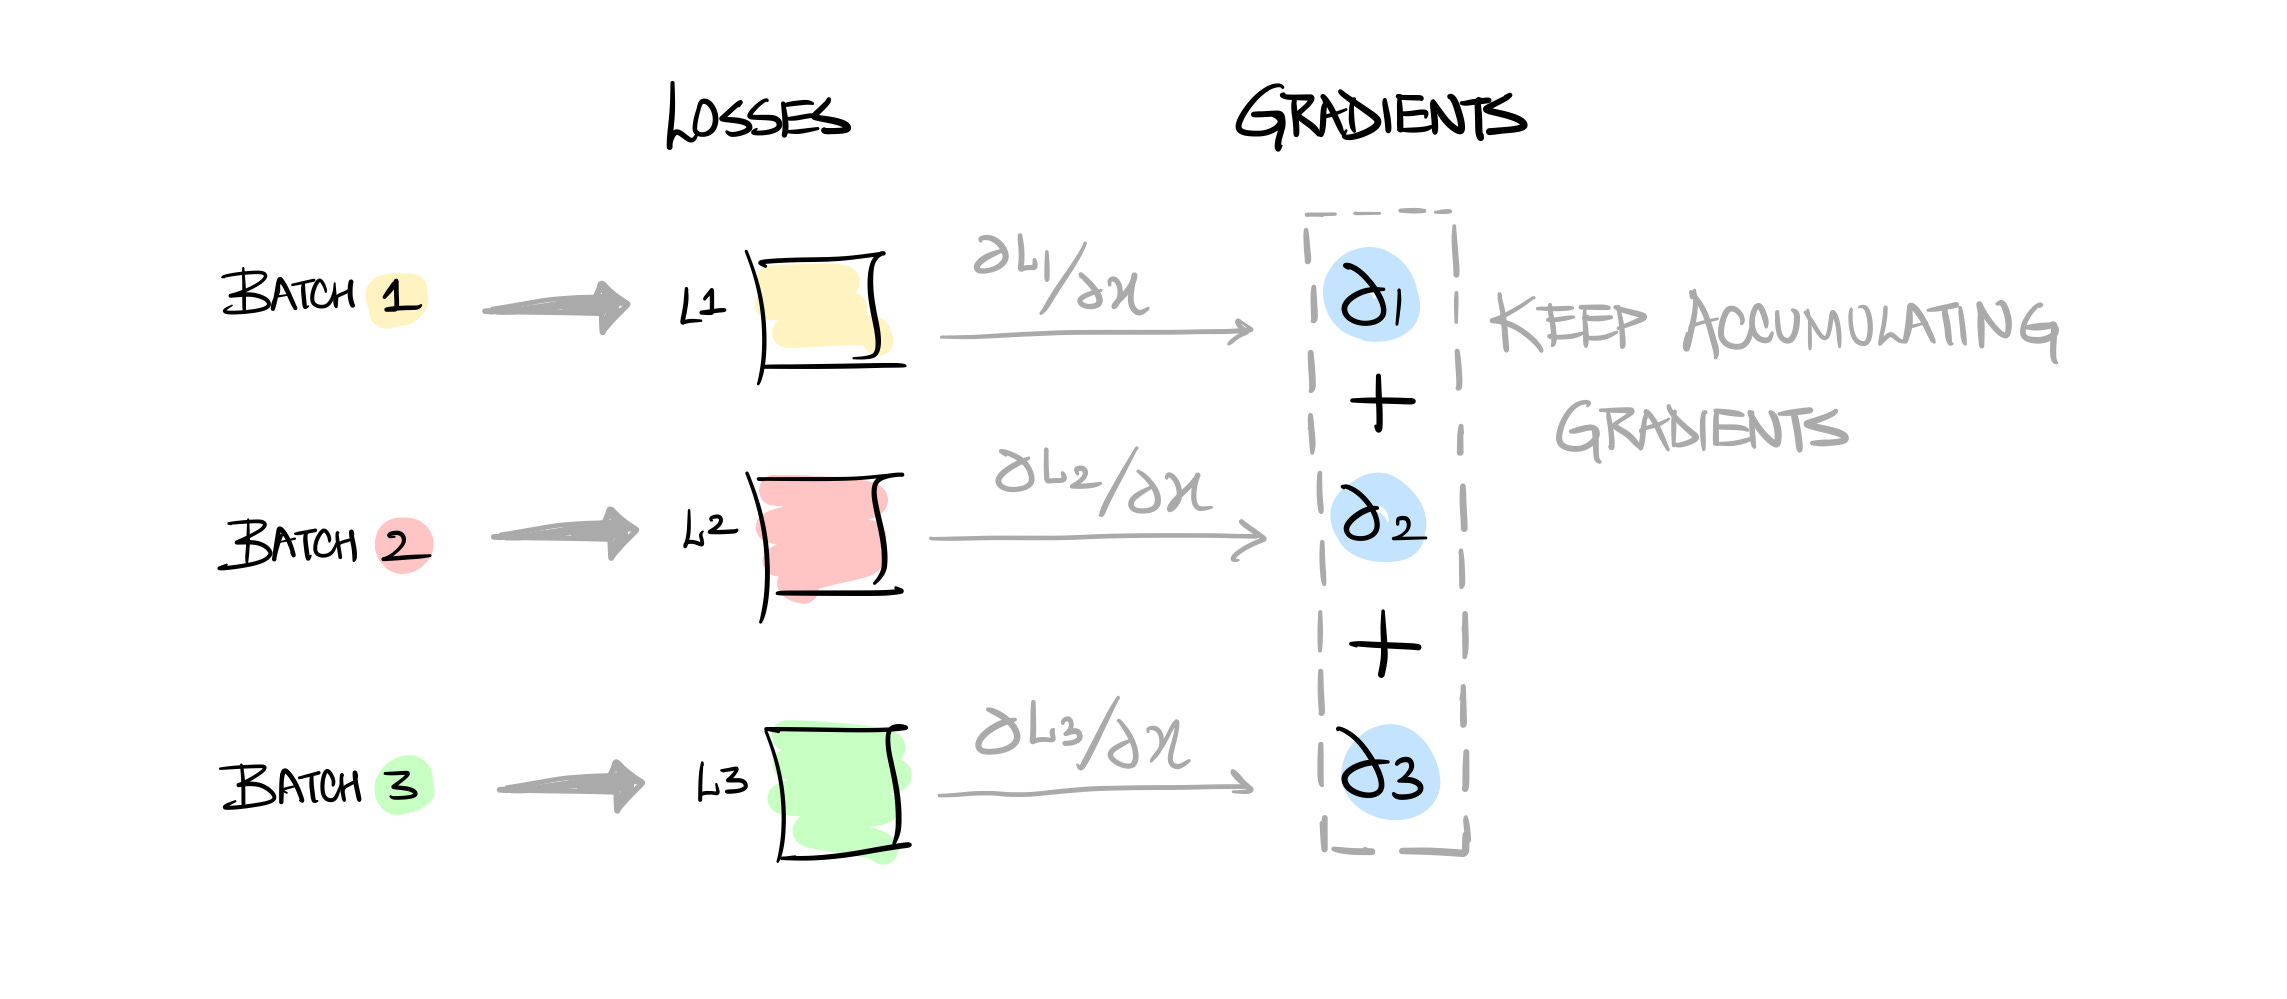
#7 | What is Gradient Accumulation ? - by Harshit Sharma
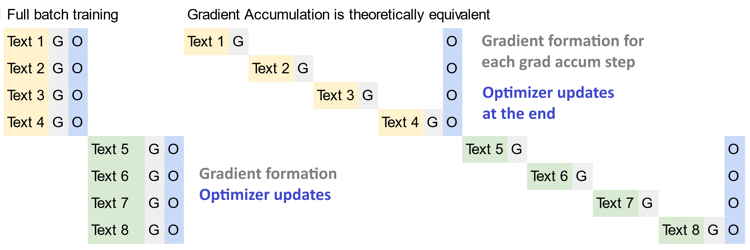
Bug Fixes in LLM Training - Gradient Accumulation
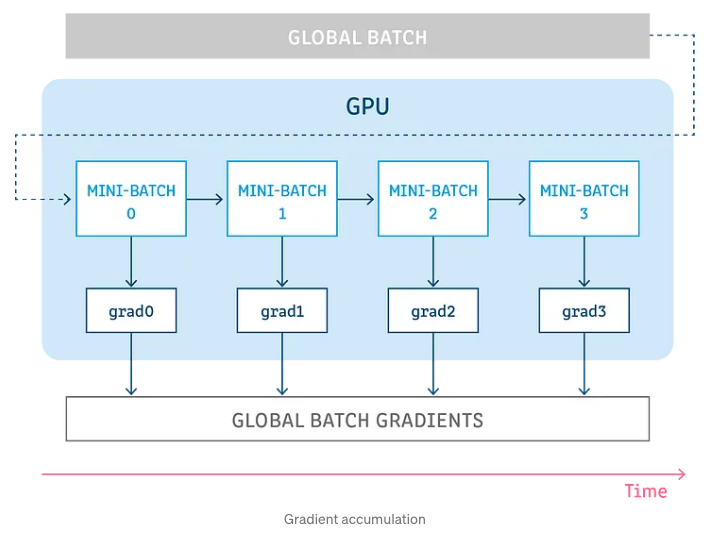
Vinija's Notes • Gradient Accumulation and Gradient Checkpointing
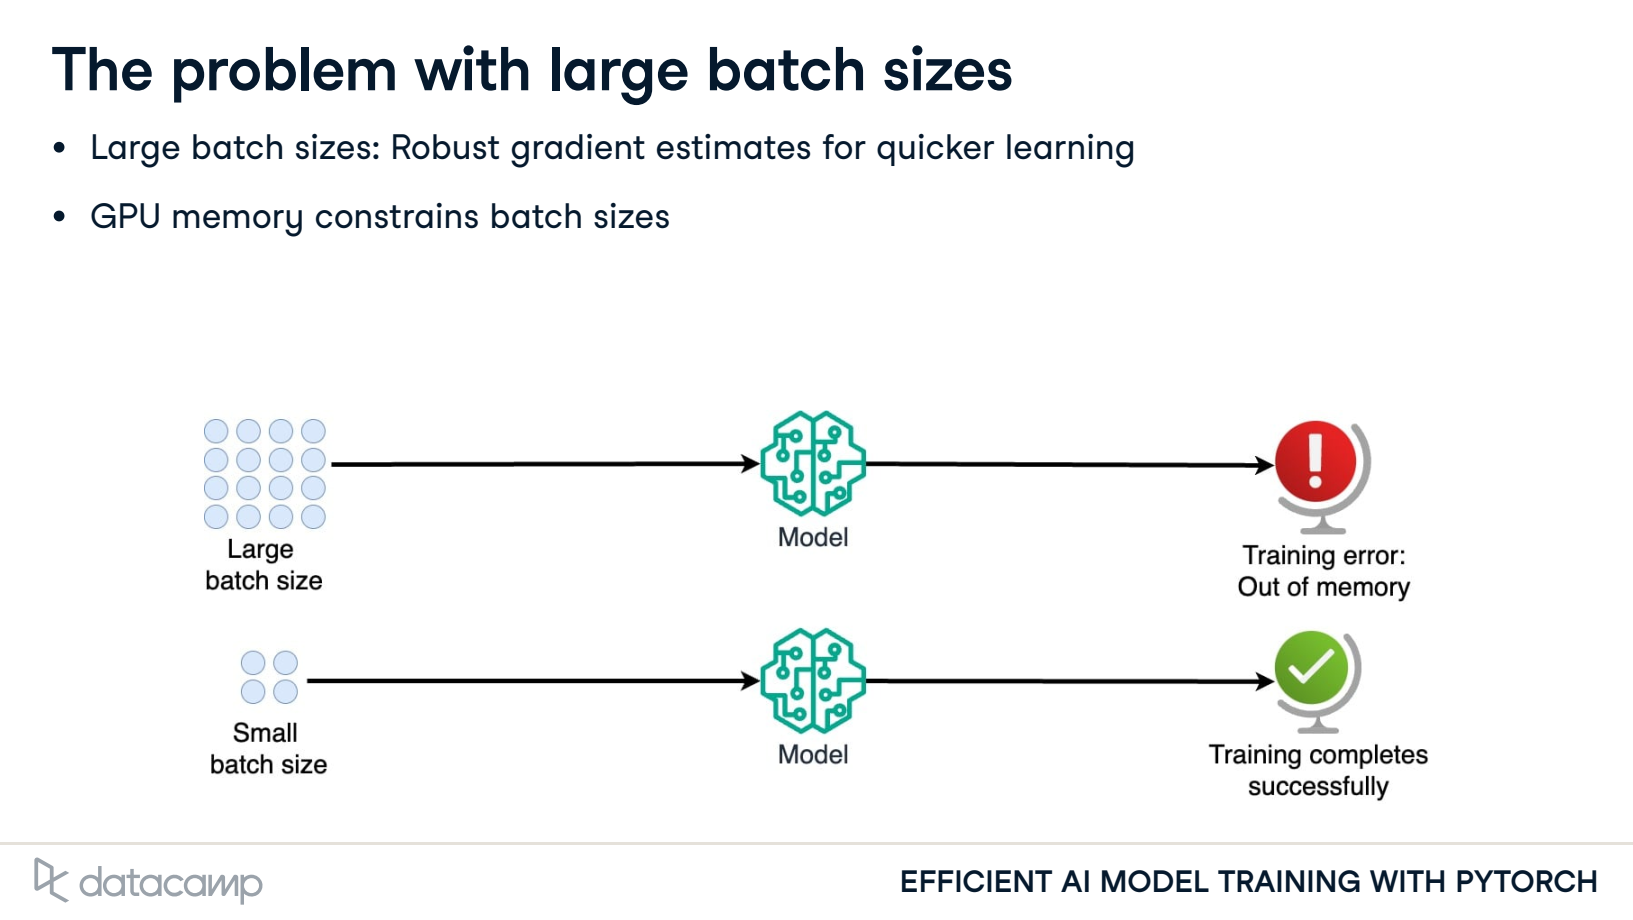
Gradient Accumulation (梯度累积 / 梯度累加) in PyTorch_梯度累计需要变成均值然后再反向传播吗-CSDN博客
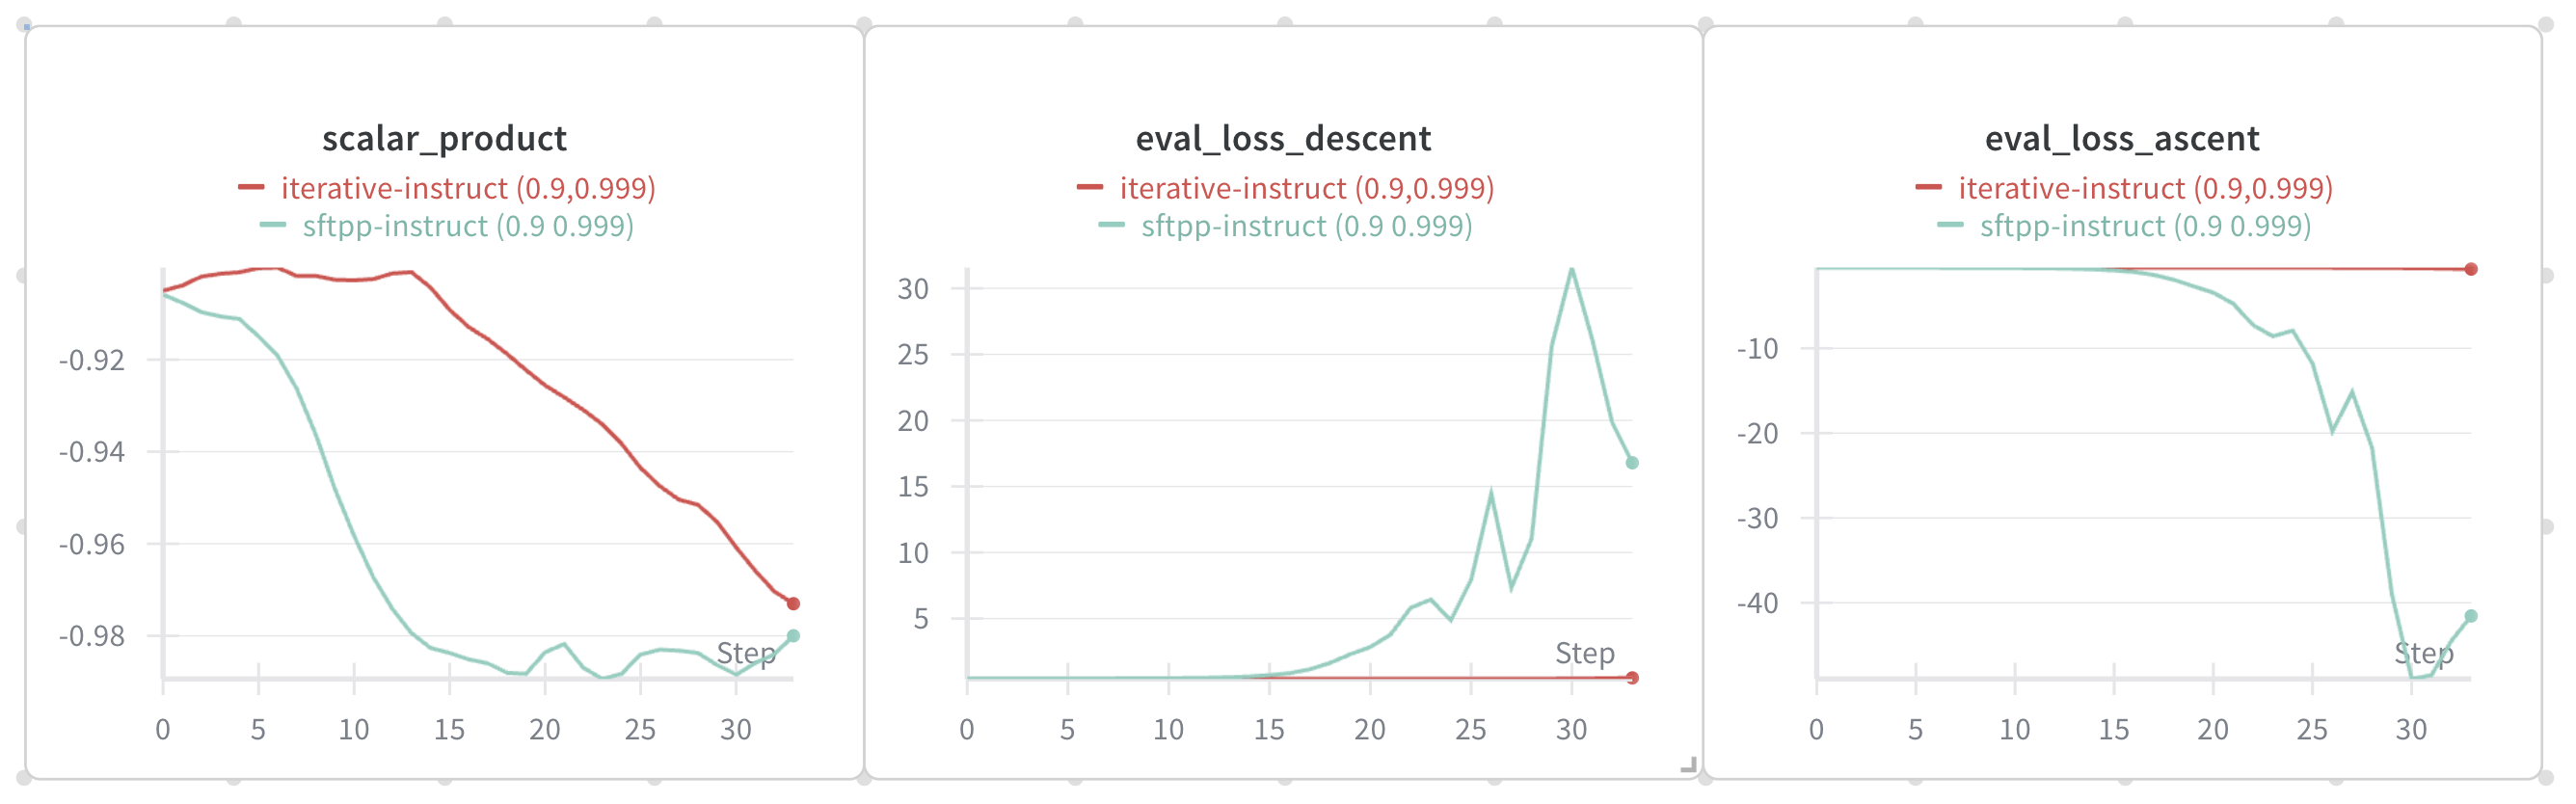
bias of gradient accumulation | Jiatong Yu
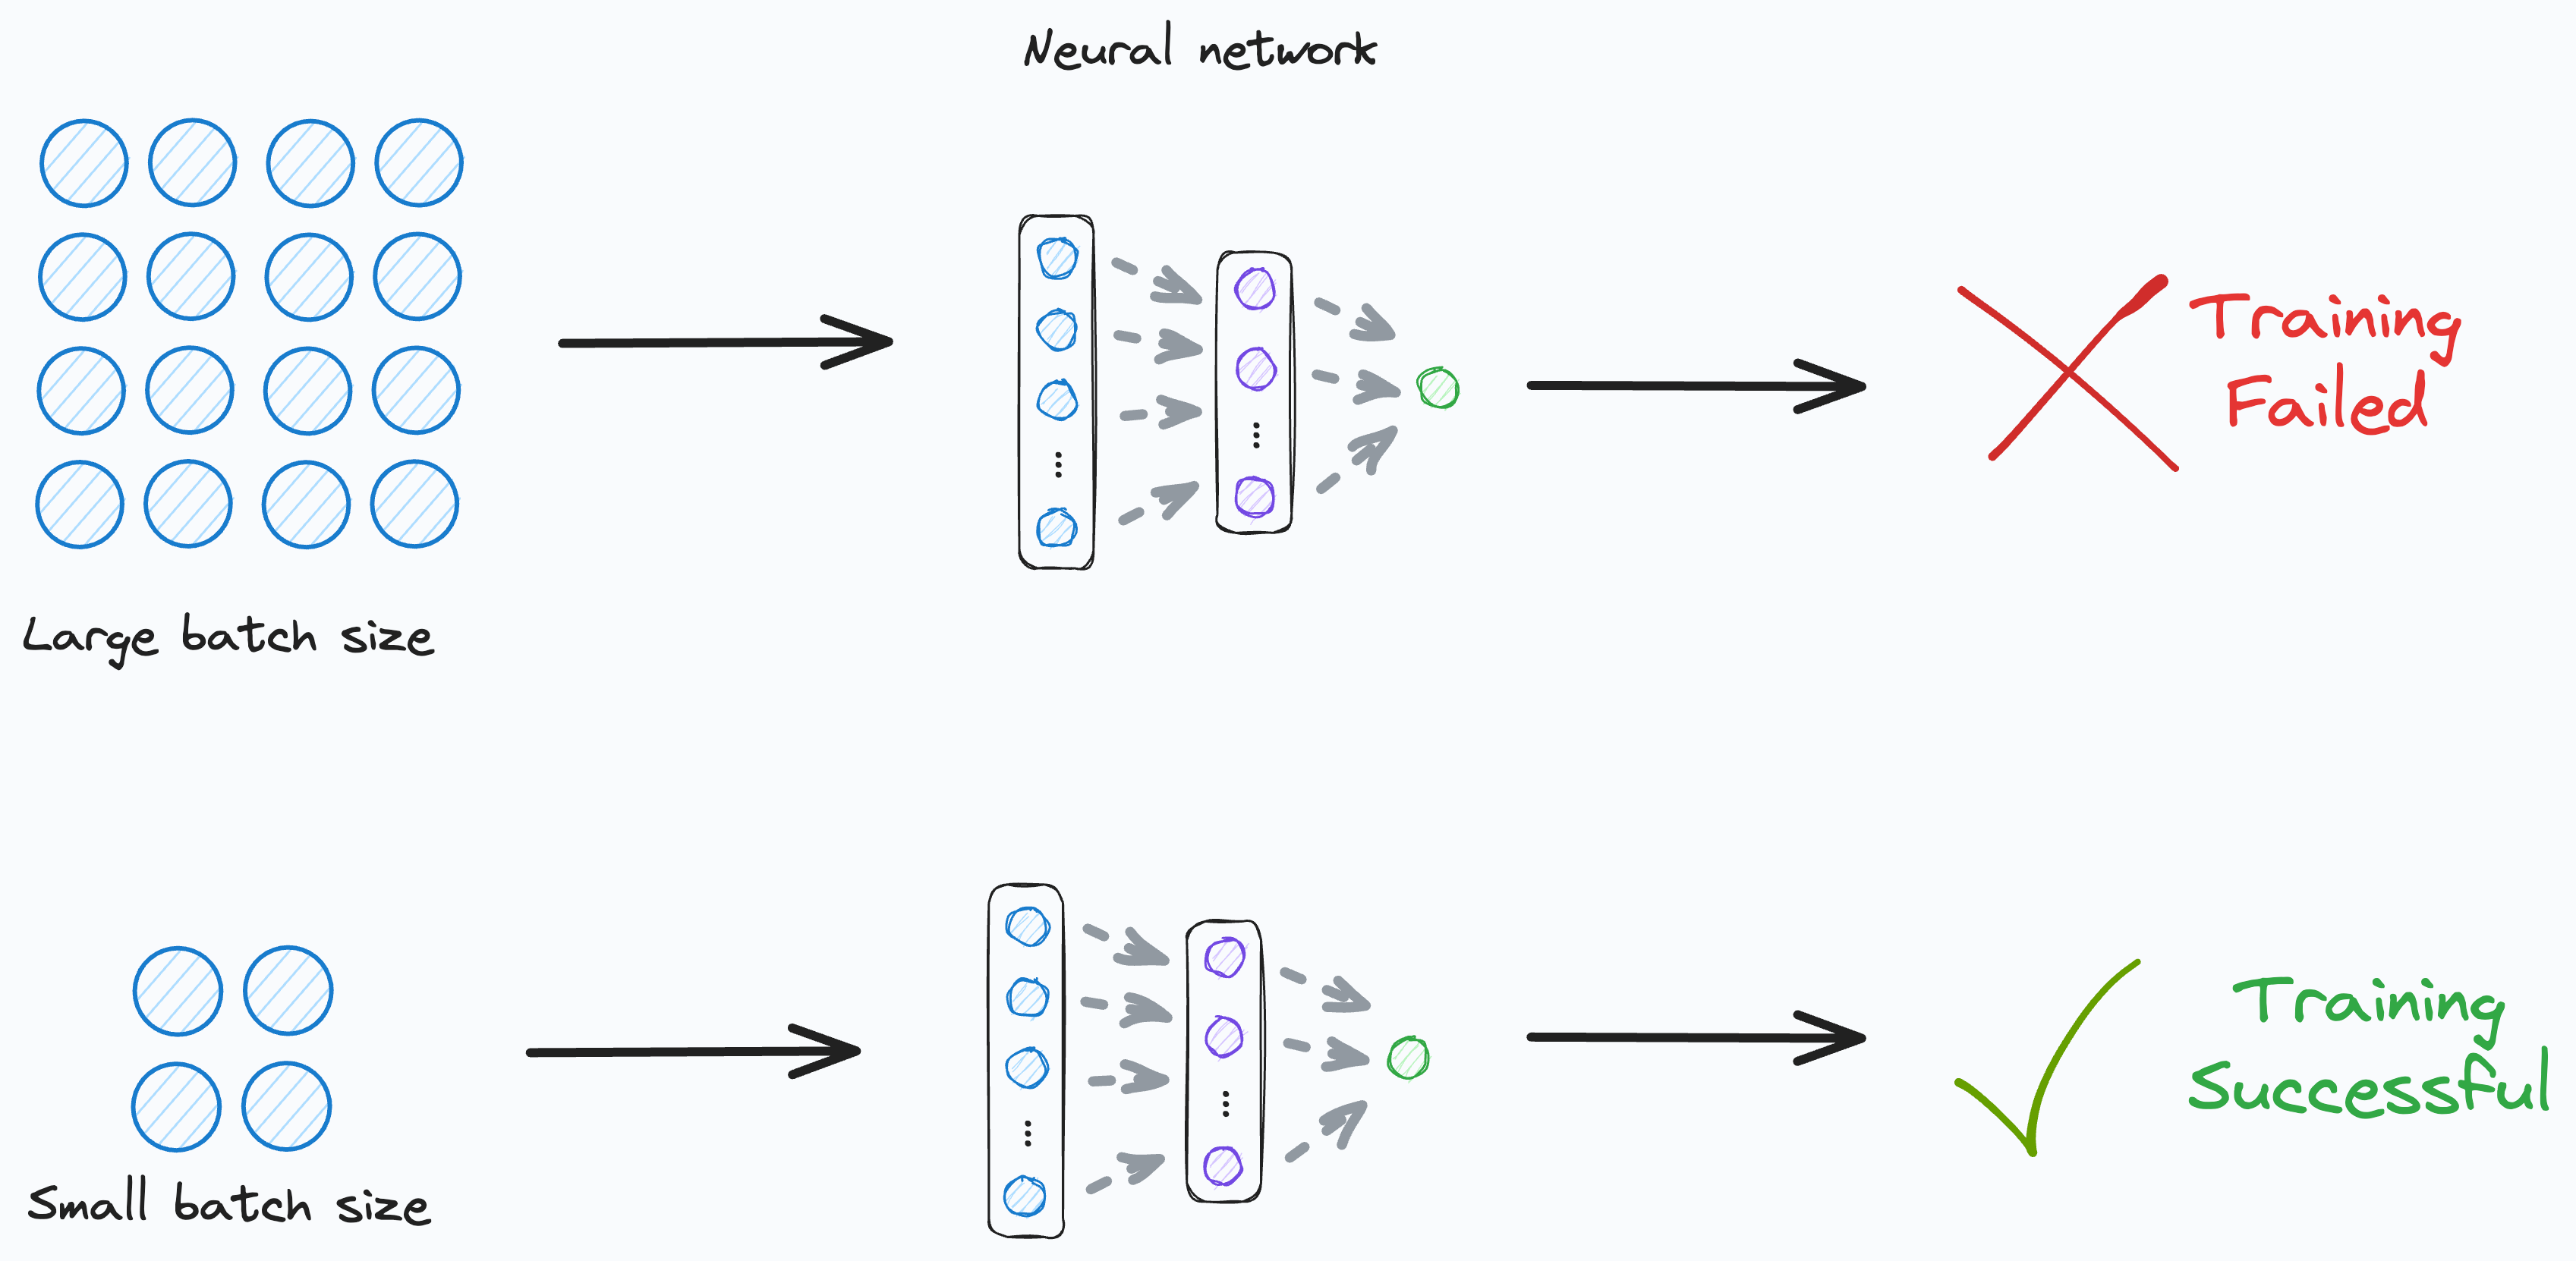
Gradient Accumulation in Neural Networks and How it Works
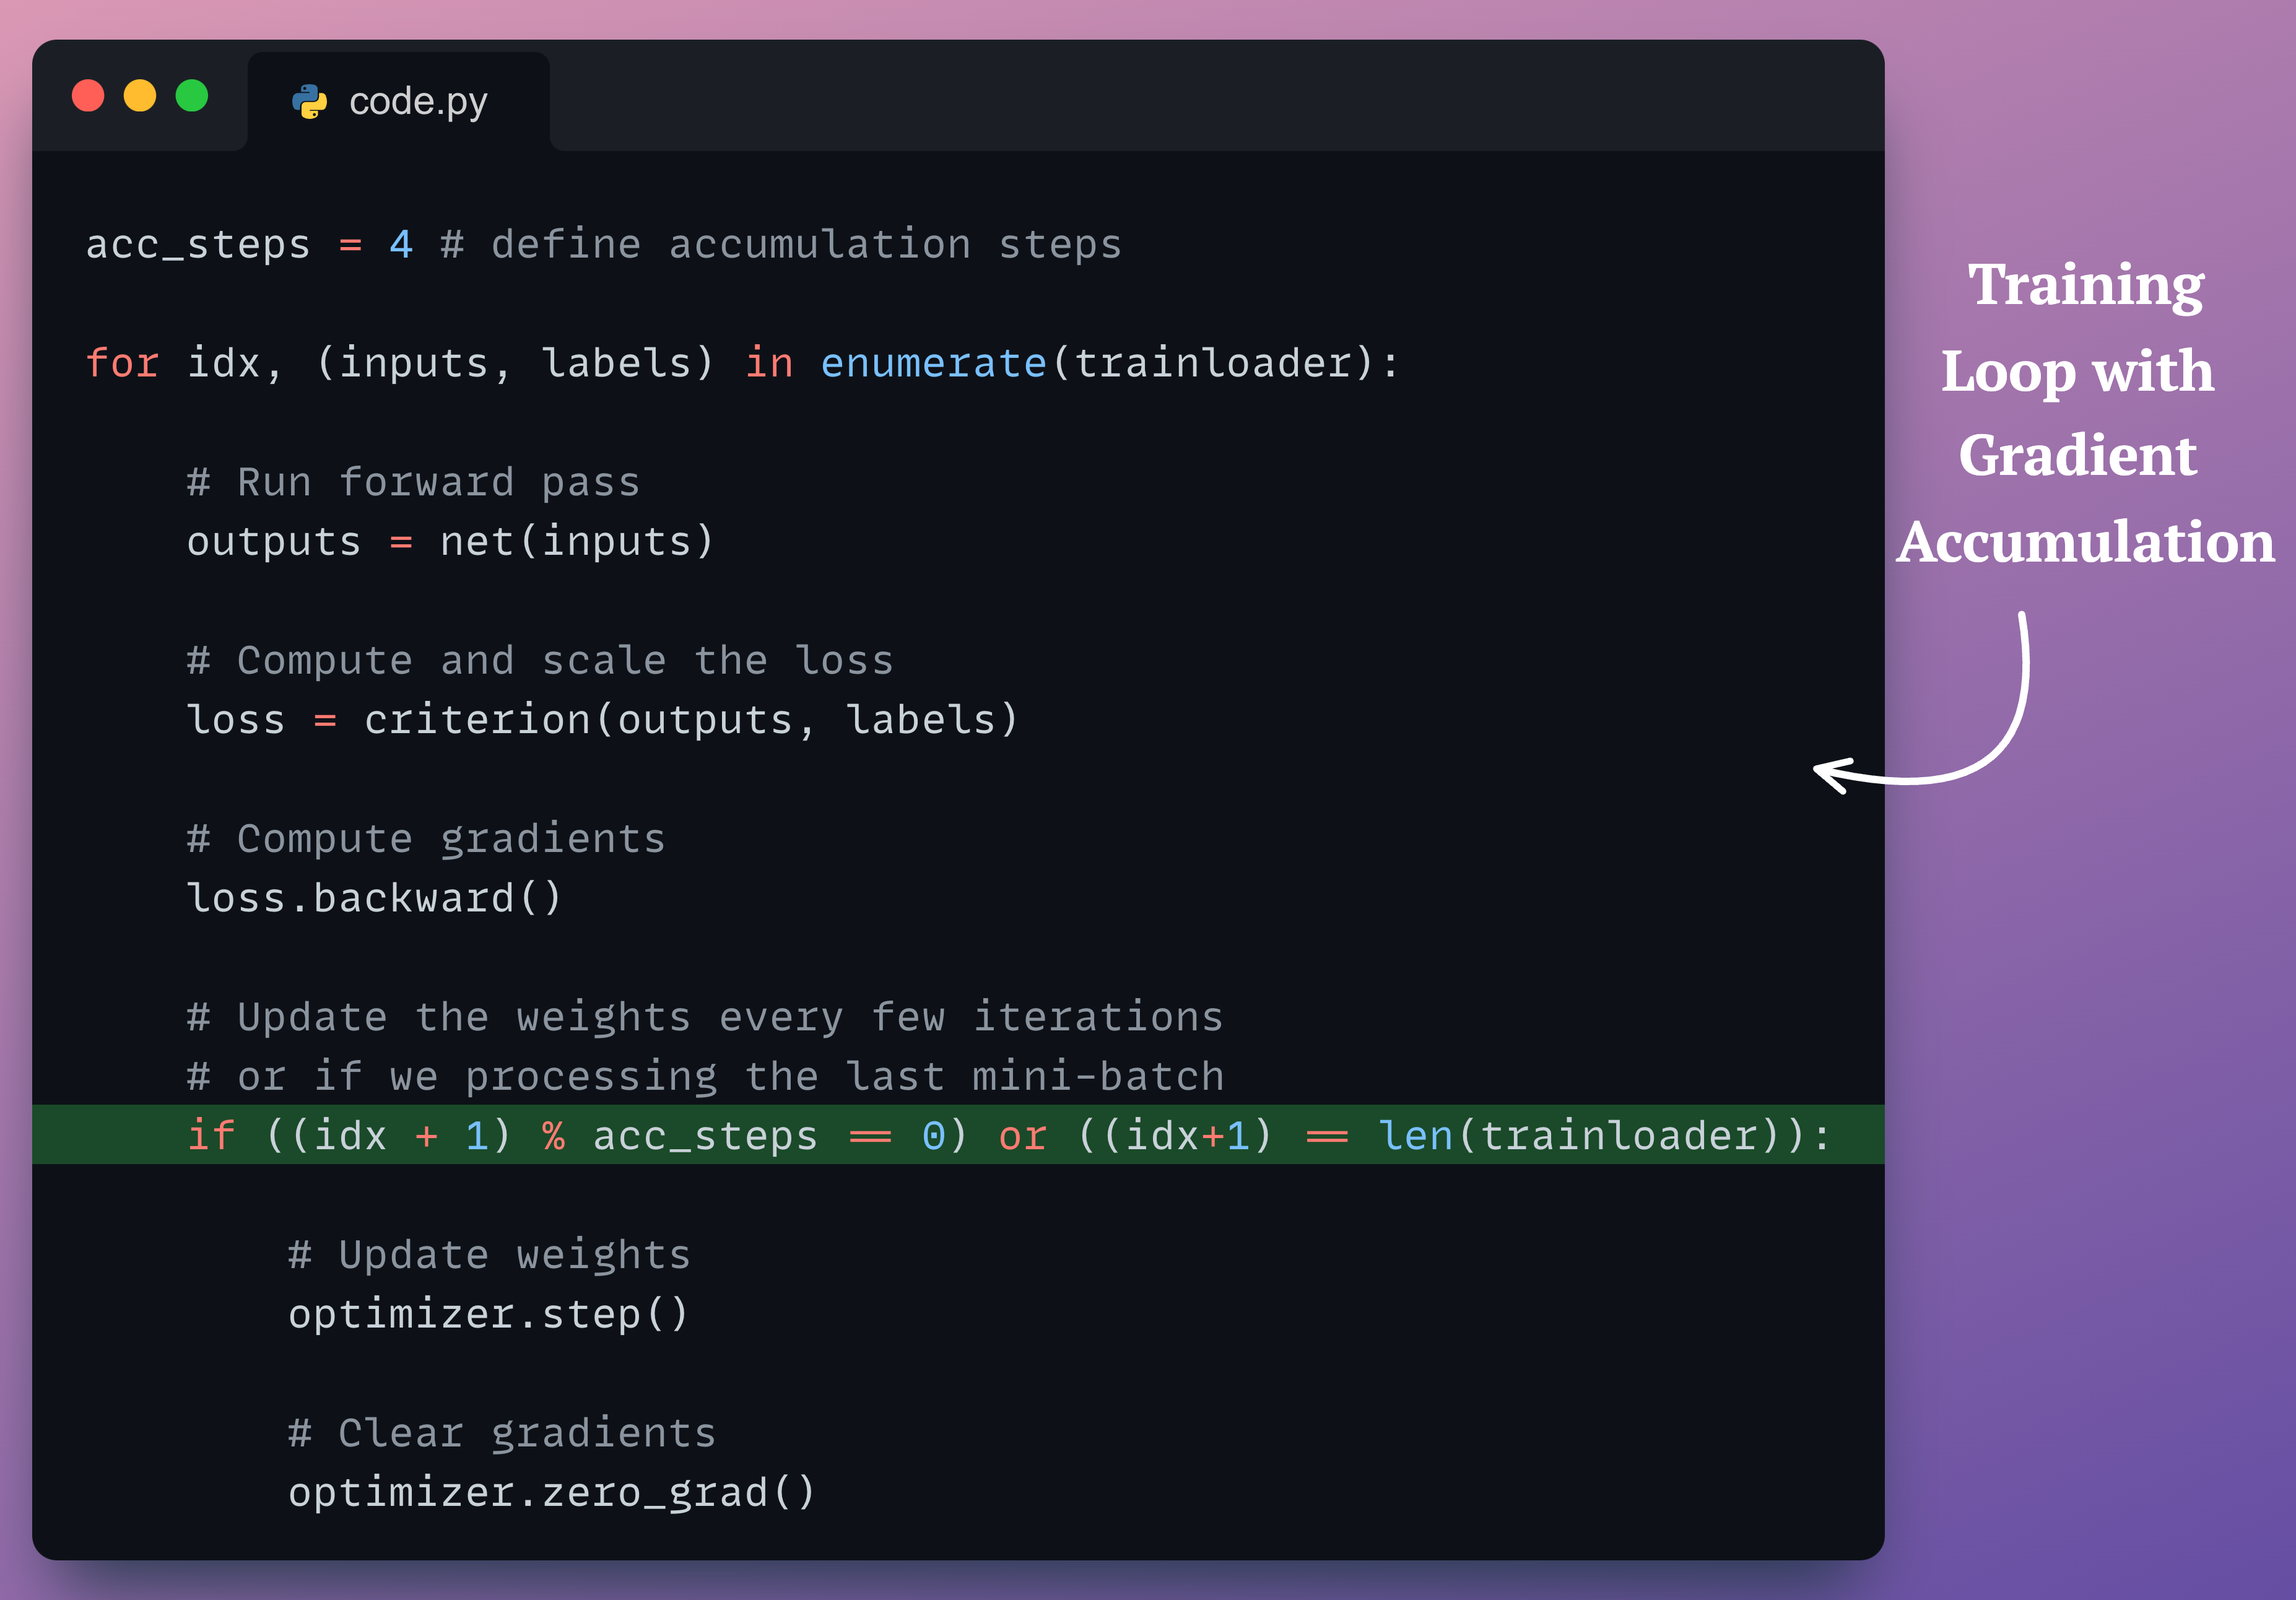
Gradient Accumulation in Neural Networks and How it Works

Gradient Accumulation vs. Batch Size in Deep Learning | by Shaza ...
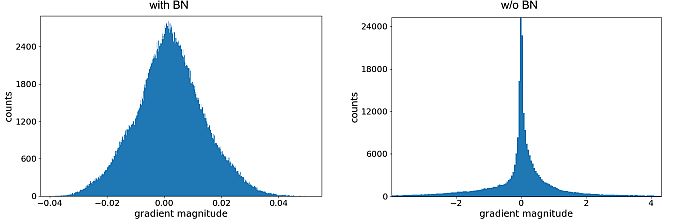
Gradient Accumulation With Batchnorm2D Layers – PJLM
Advertisement Space (336x280)

Short #7 | What is Gradient Accumulation
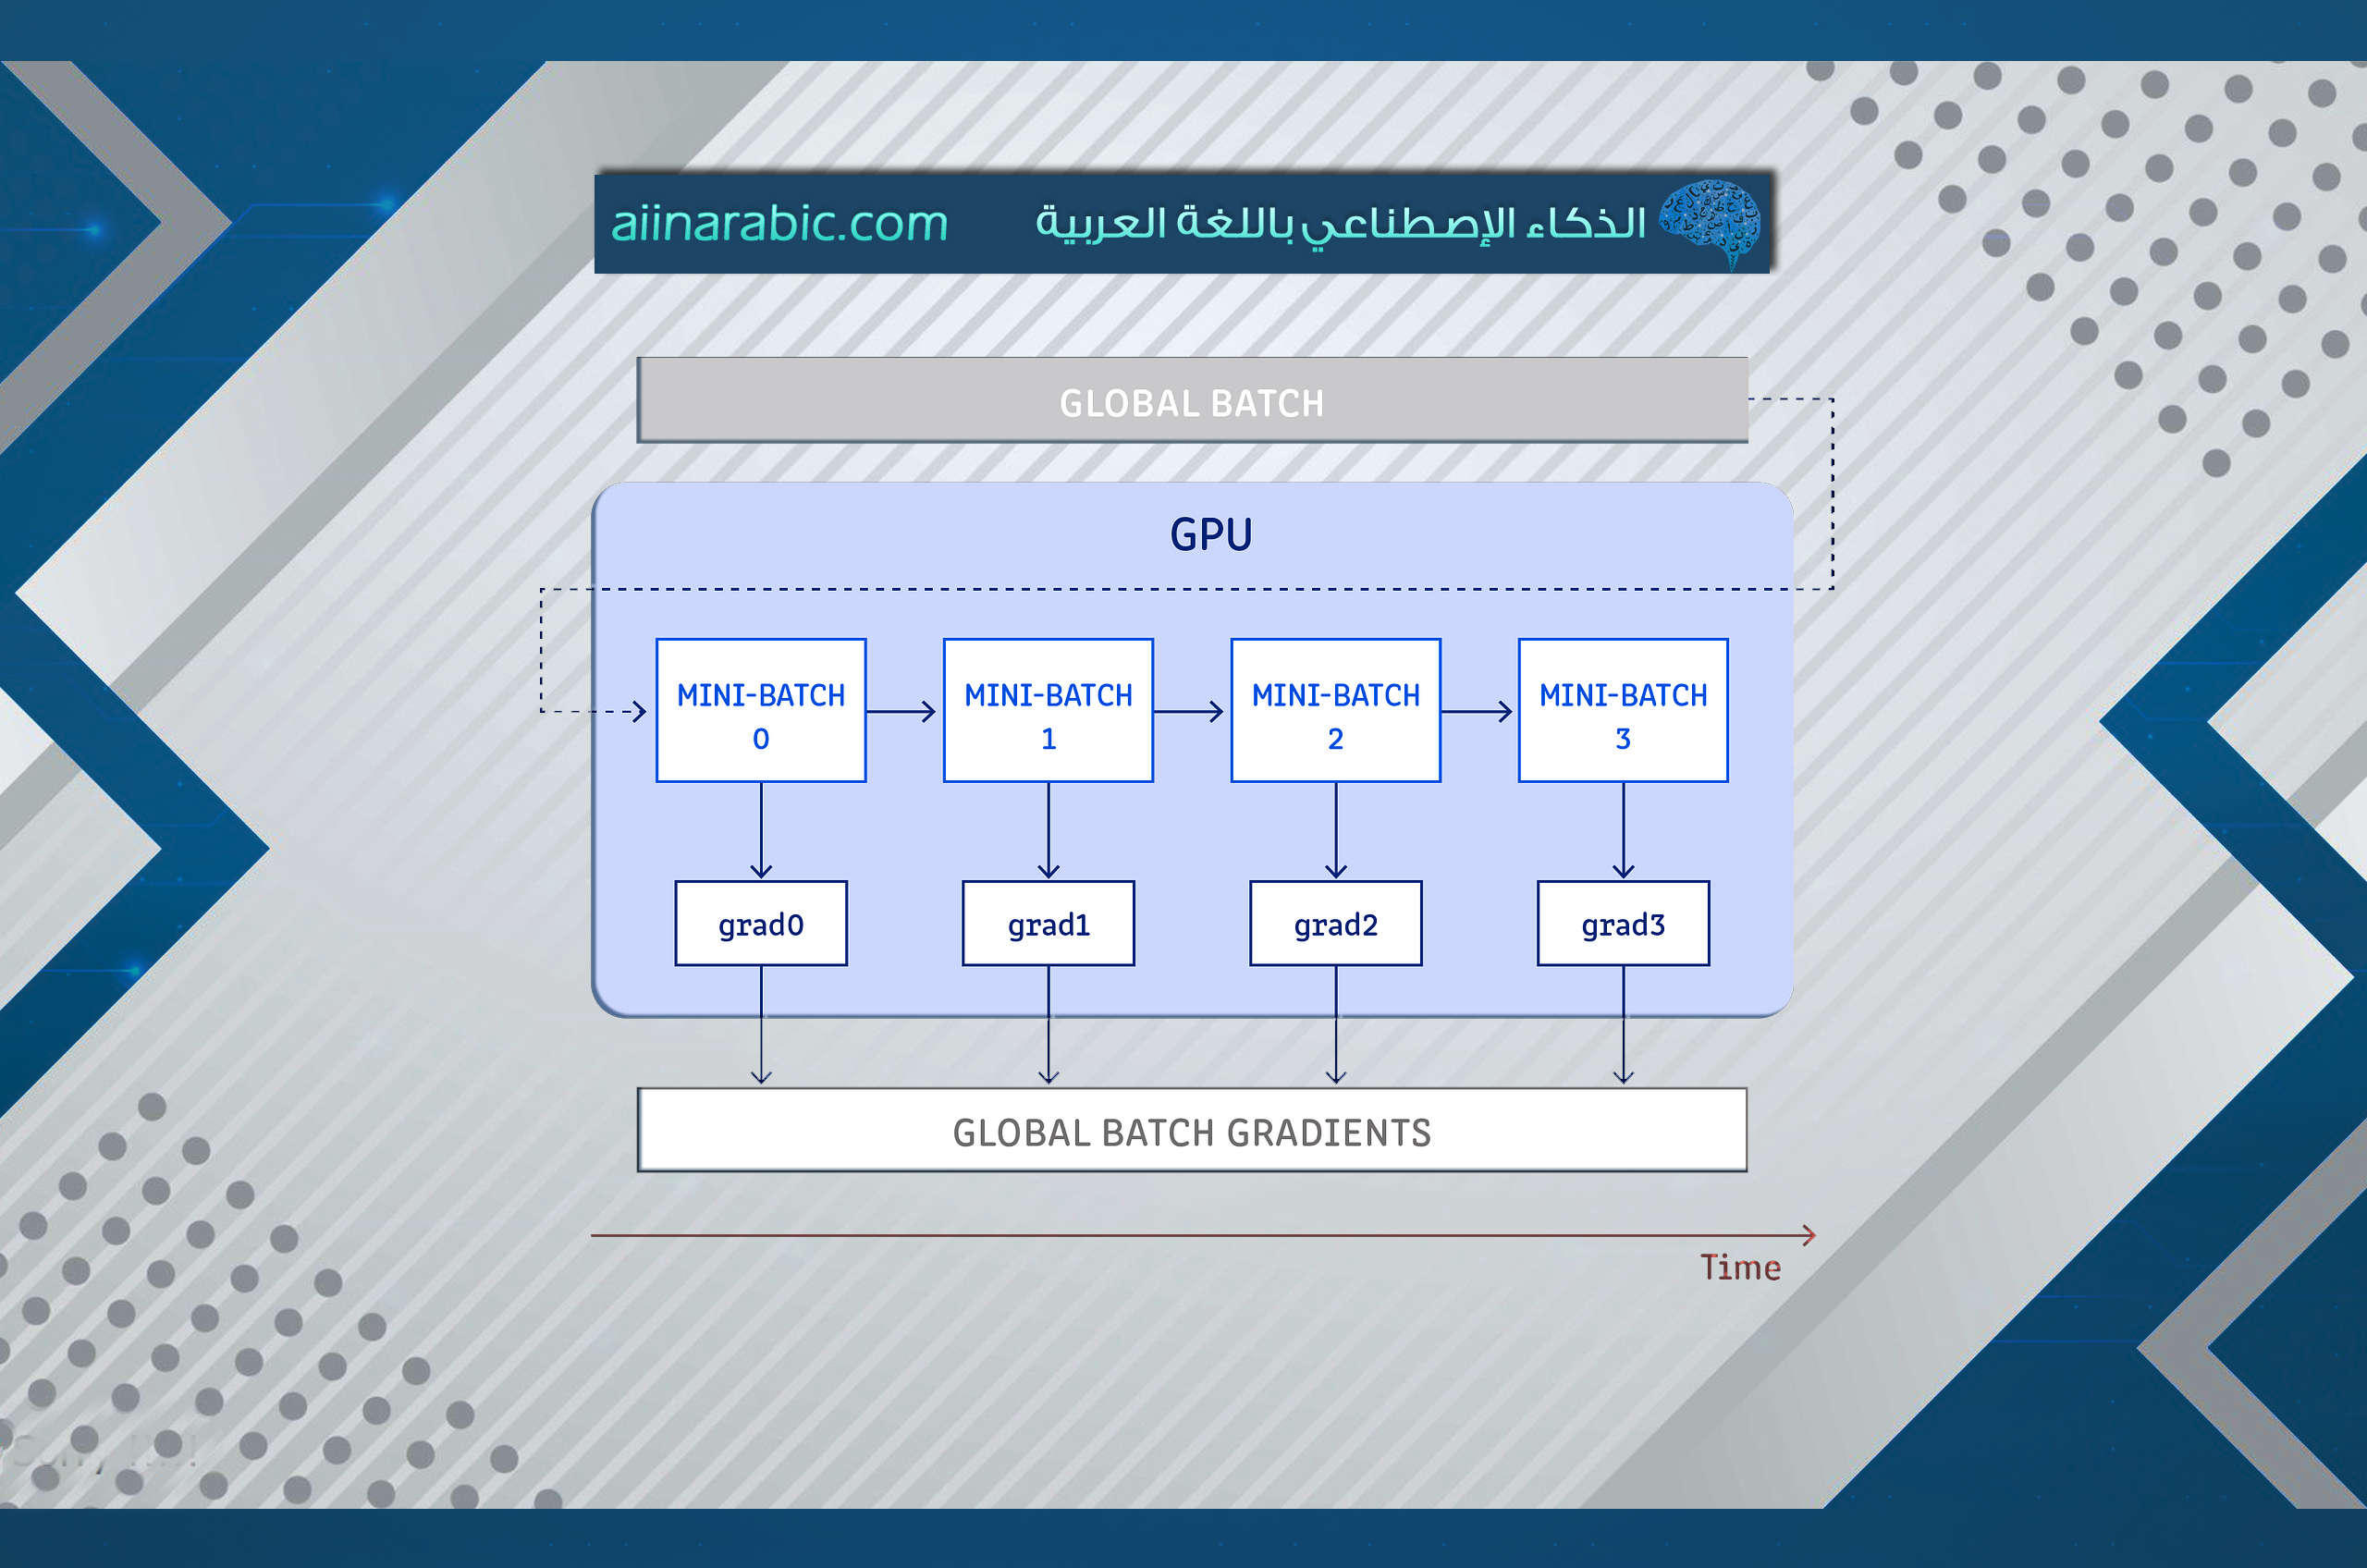
Gradient Accumulation تراكُم التّدرُّج – الذّكاءُ الإصطناعيُّ باللُّغةِ ...
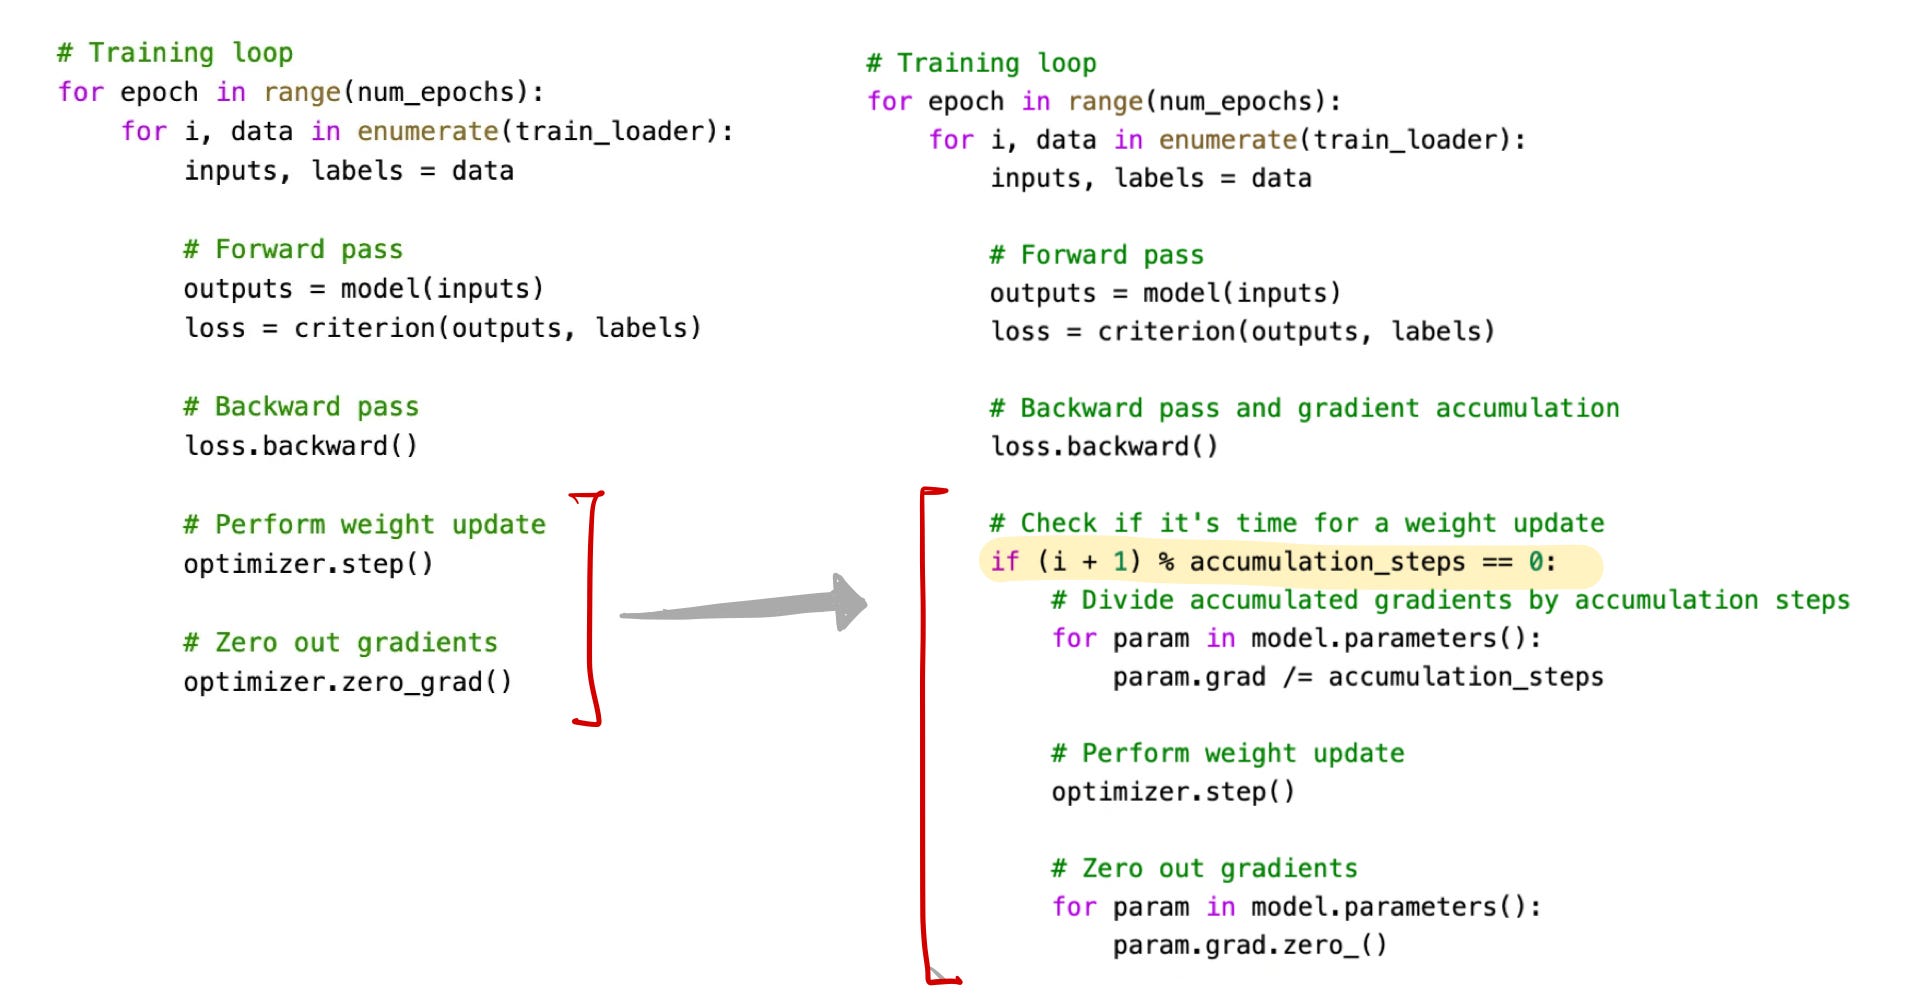
#7 | What is Gradient Accumulation ? - by Harshit Sharma

Gradient Accumulation (梯度累积 / 梯度累加) in PyTorch - 技术栈
Gradient Accumulation

Gradient Accumulation in PyTorch. I understand that learning data ...
Gradient Accumulation vs. Batch Size in Deep Learning | by Shaza ...

Effect of gradient accumulation times on accuracy | Download Scientific ...
PyTorch Gradient Accumulation Technique
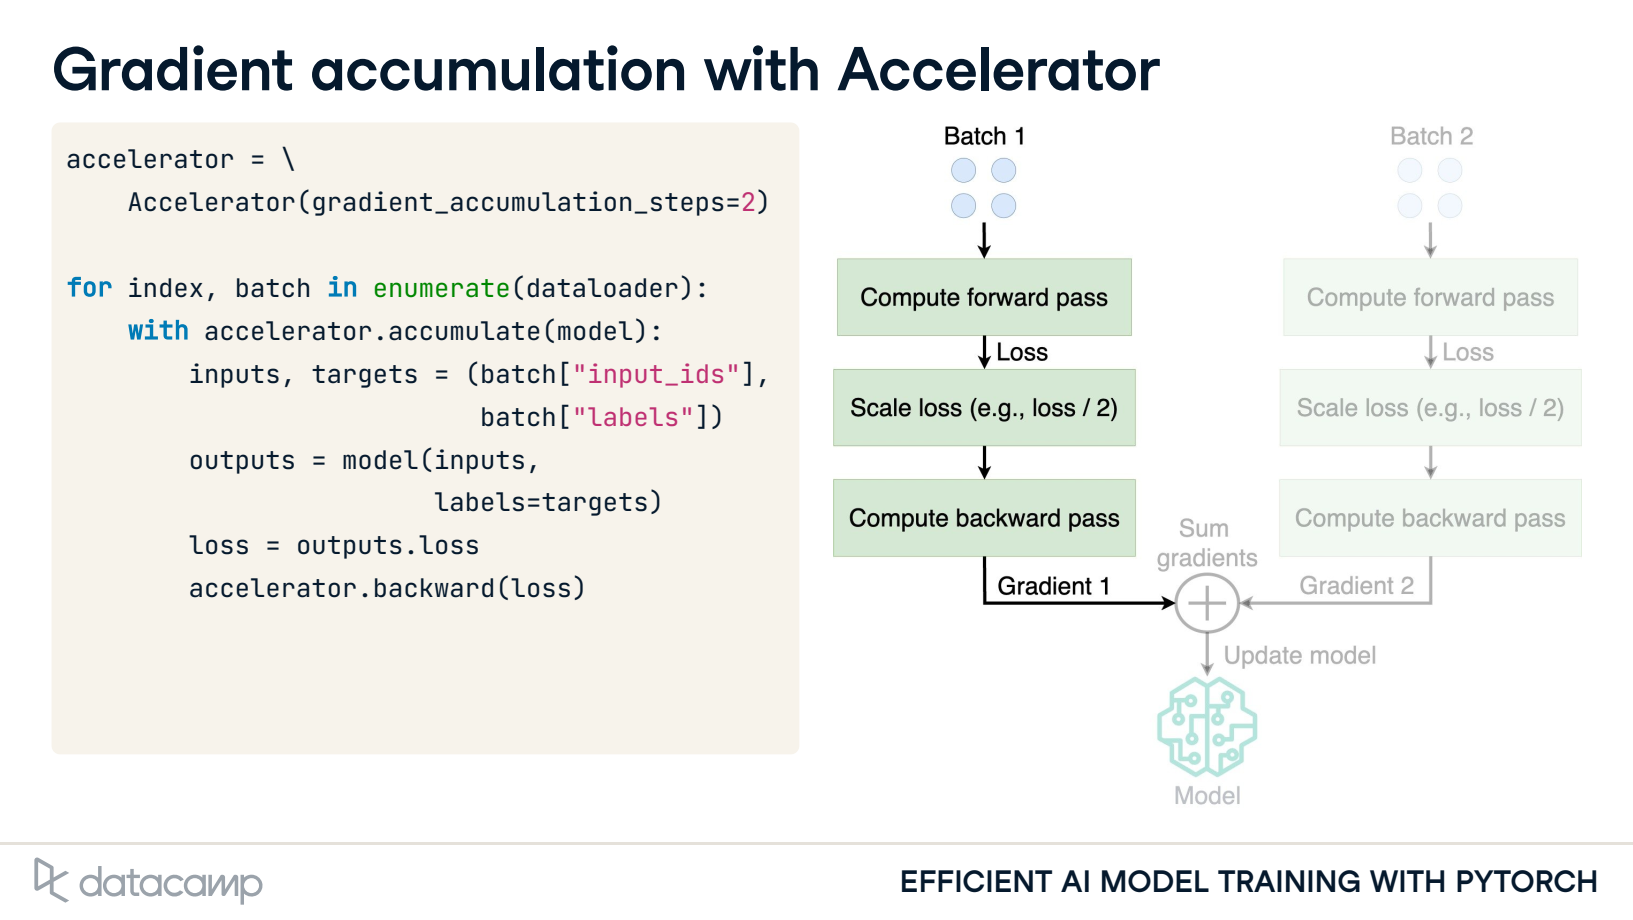
Gradient Accumulation (梯度累积 / 梯度累加) in PyTorch - 技术栈
Advertisement Space (336x280)

Local Gradient Accumulation is slower than the PyTorch implementation ...

Gradient Accumulation (梯度累积 / 梯度累加) in PyTorch - 技术栈
Gradient Accumulation - PyTorch Course
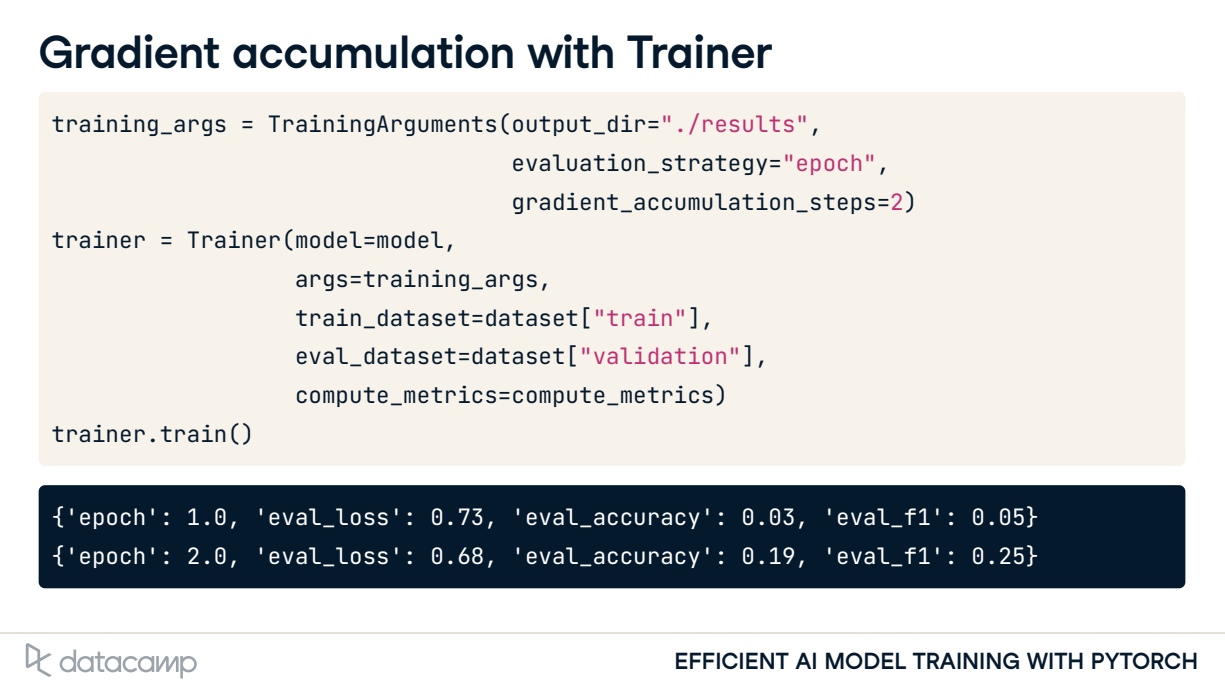
Gradient Accumulation (梯度累积 / 梯度累加) in PyTorch - 技术栈

Gradient Accumulation (梯度累积 / 梯度累加) in PyTorch - 技术栈

Local Gradient Accumulation is slower than the PyTorch implementation ...