
A Simple Framework Uniting Visual In Context Learning With Masked Image

A Simple Framework Uniting Visual In-context Learning with Masked Image ...

Table I from A Simple Framework Uniting Visual In-context Learning with ...

Figure 1 from A Simple Framework Uniting Visual In-context Learning ...
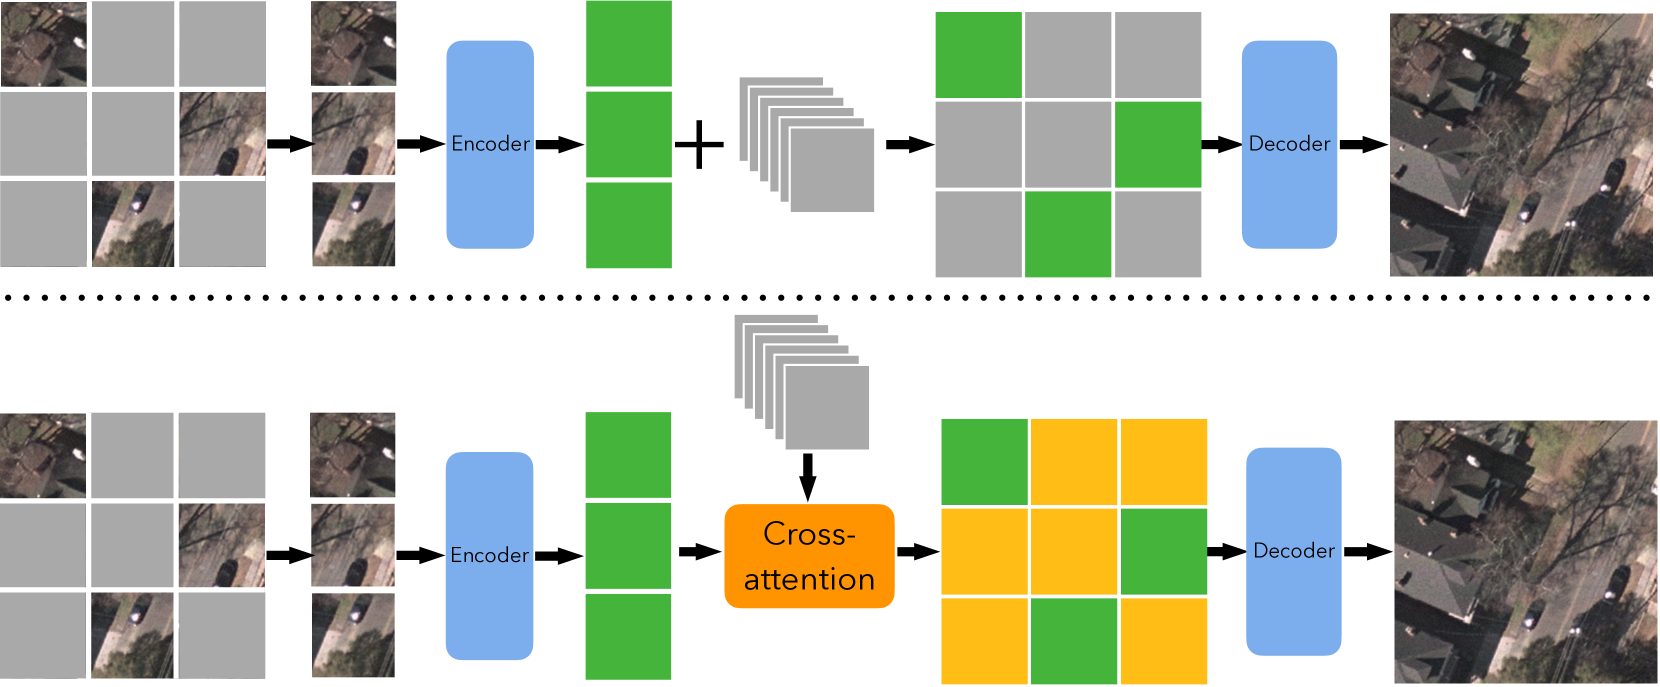
Masked Image Modeling as a Framework for Self-Supervised Learning ...

A Simple Framework for Contrastive Learning of Visual Representations | PDF
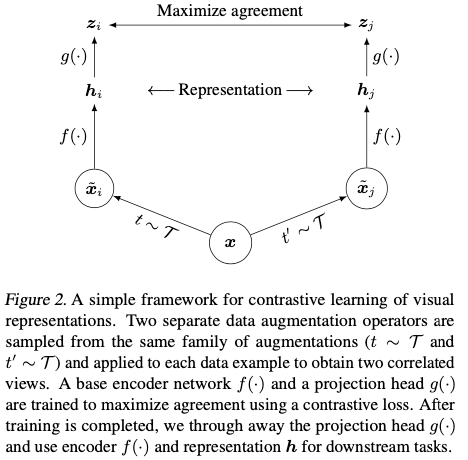
A Simple Framework for Contrastive Learning of Visual Representations ...

A Simple Framework for Contrastive Learning of Visual Representations ...

A simple framework for contrastive learning of visual representations | PDF

A Simple Framework for Contrastive Learning of Visual ... / a-simple ...
A Simple Framework for Contrastive Learning of Visual Representations | PDF
Advertisement Space (300x250)

[Literature Review] A Simple Image Segmentation Framework via In ...

A Simple Framework for Contrastive Learning of Visual Representations | PDF
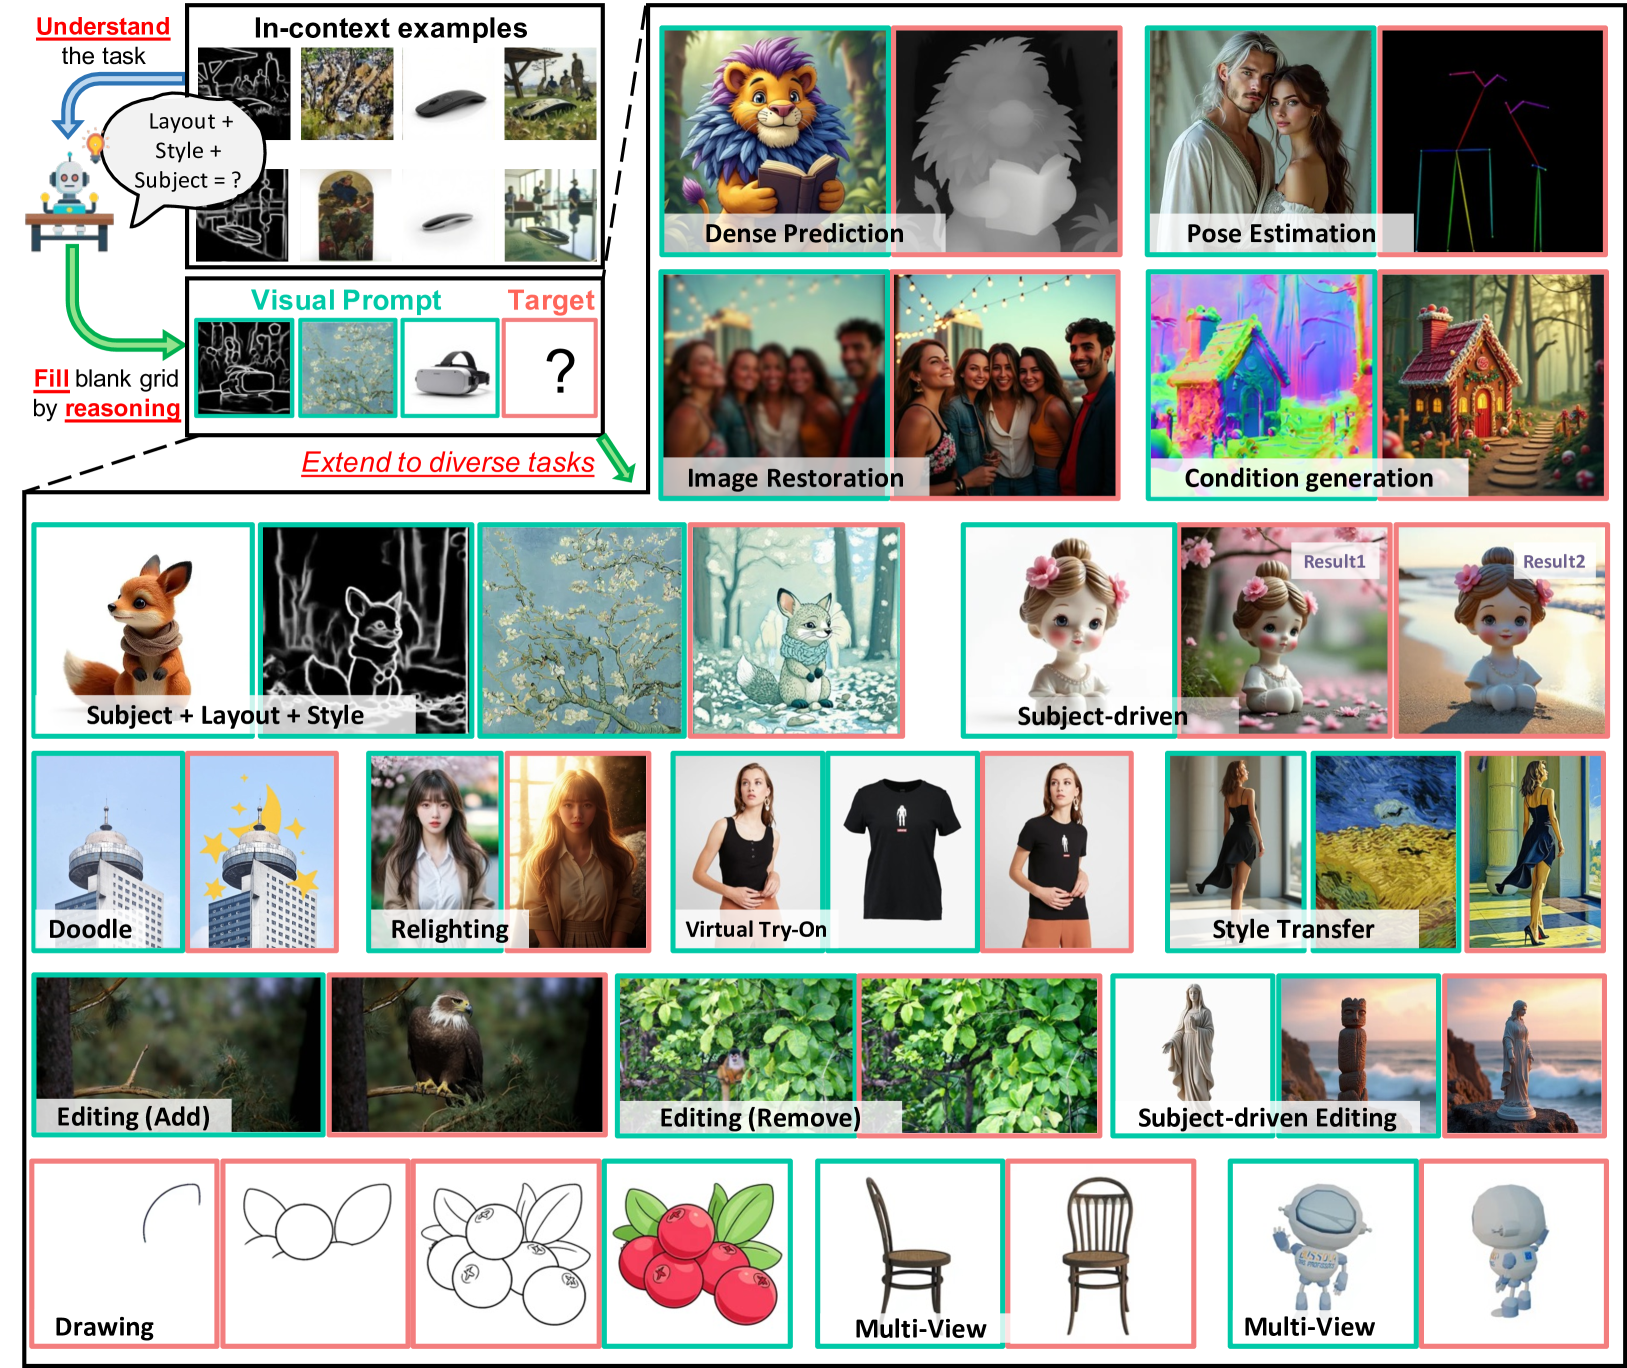
VisualCloze: A Universal Image Generation Framework via Visual In ...
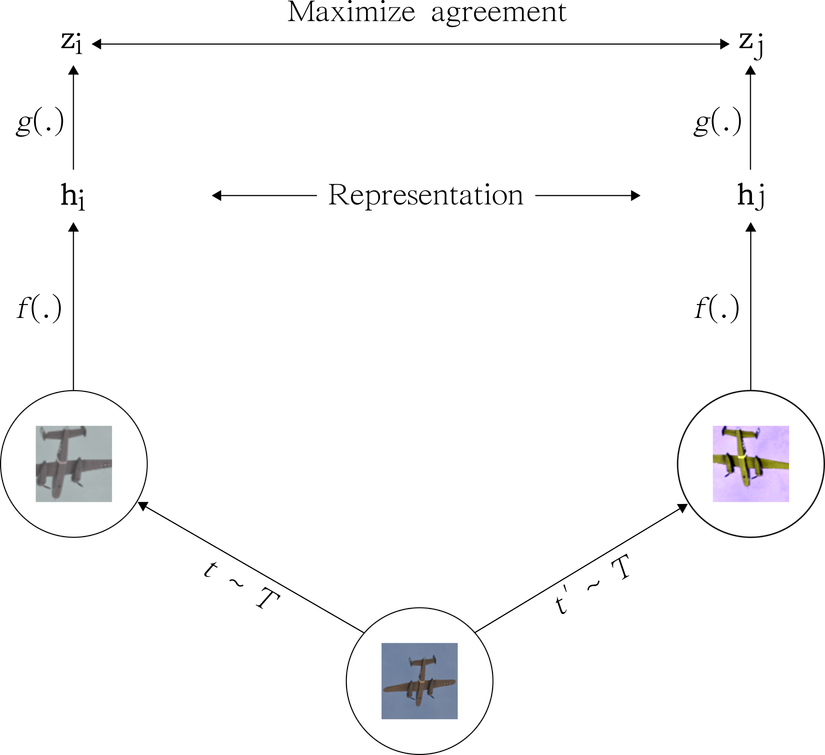
[Paper Explain] A Simple Framework for Contrastive Learning of Visual ...

Improve Supervised Representation Learning with Masked Image Modeling

[논문 리뷰] VisualCloze: A Universal Image Generation Framework via Visual ...

A Deep Learning Framework To Reconstruct Face Under Mask | PDF | Image ...

(PDF) A Simple Image Segmentation Framework via In-Context Examples

Personal Visual Context Learning in Large Multimodal Models

Figure 9 from Training-Free Image Editing with Visual Context ...
Advertisement Space (336x280)

Accelerating Conditional Prompt Learning via Masked Image Modeling for ...

The detailed design of proposed visual context learning module ...
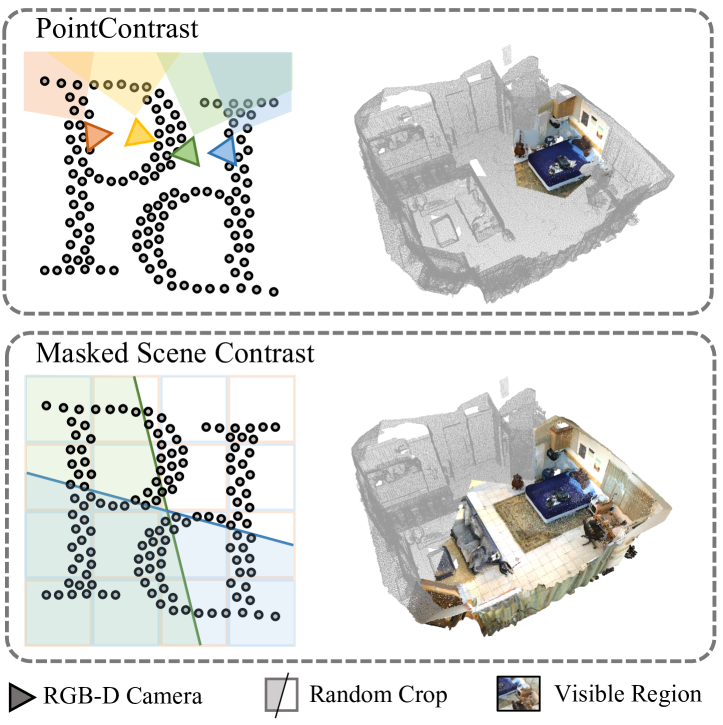
[2303.14191] Masked Scene Contrast: A Scalable Framework for ...

Contextual Image Attack: How Visual Context Exposes Multimodal Safety ...
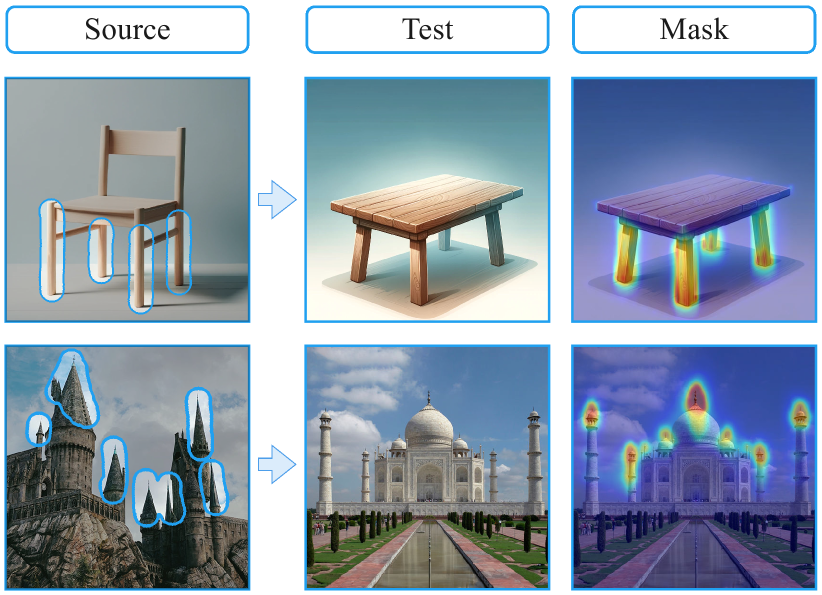
[2311.17083] CLiC: Concept Learning in Context

A Unified View of Masked Image Modeling | DeepAI
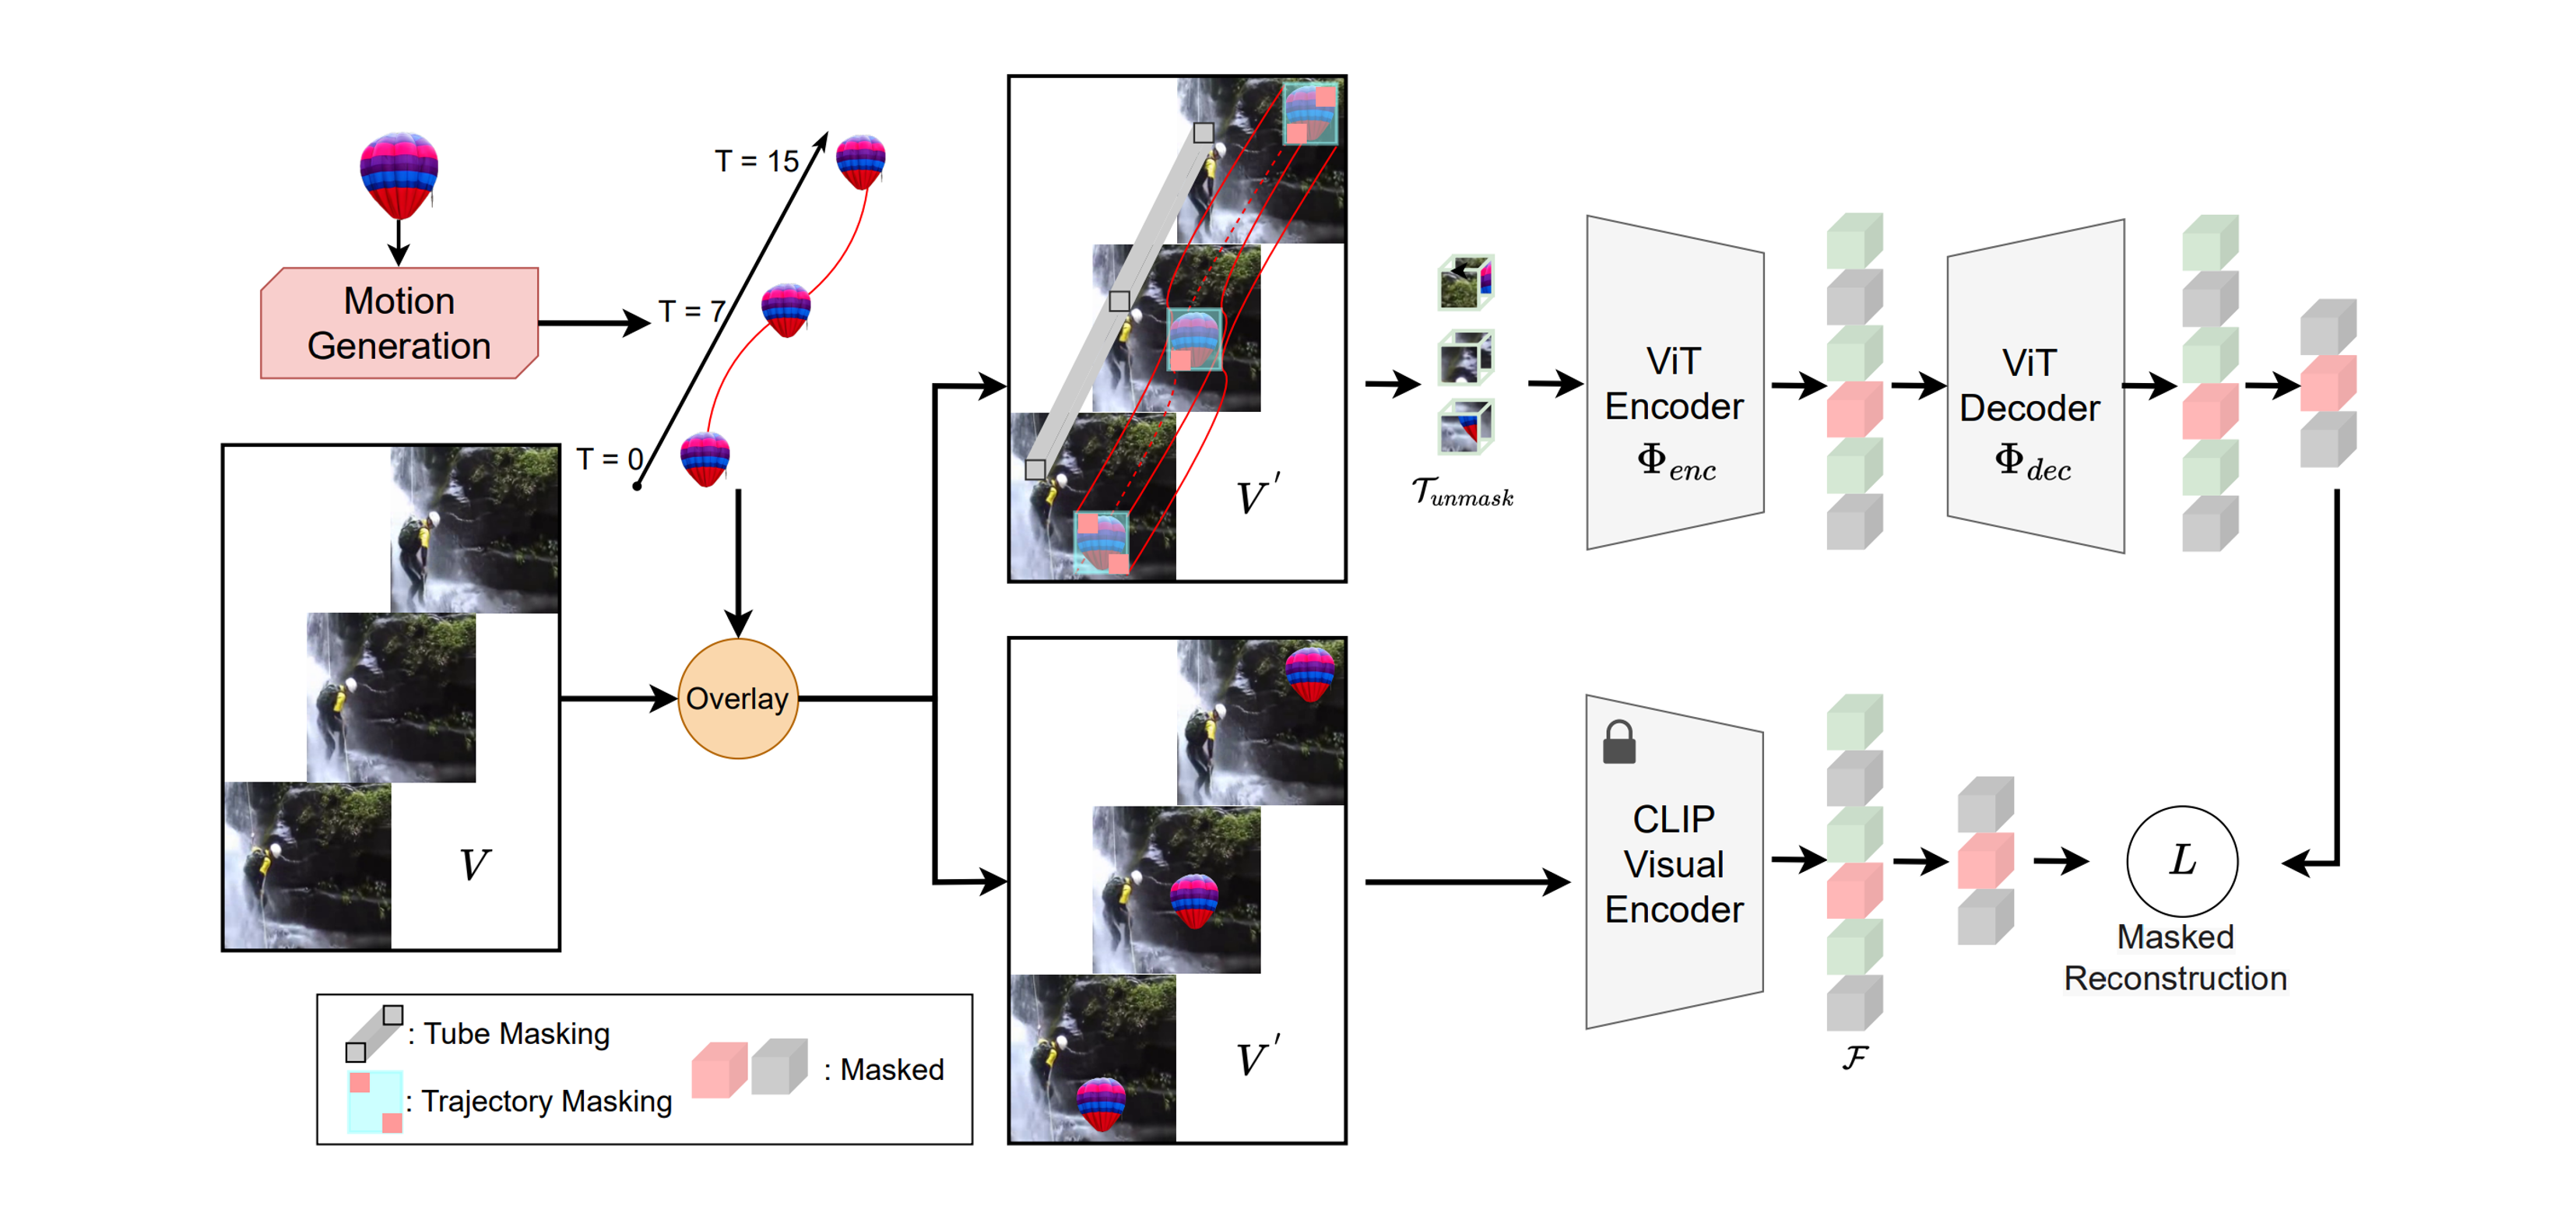
SMILE: Infusing Spatial and Motion Semantics in Masked Video Learning ...

论文阅读 Masked Scene Contrast: A Scalable Framework for Unsupervised 3D ...
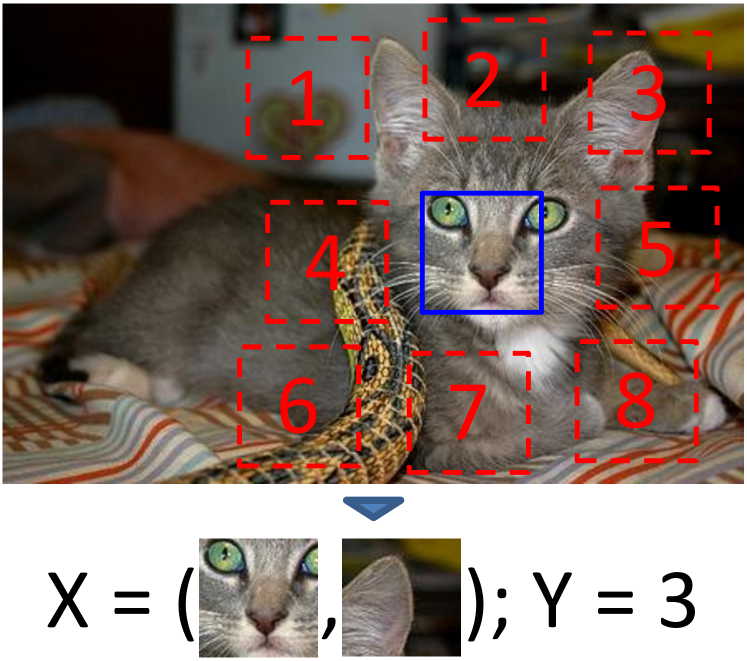
[1505.05192] Unsupervised Visual Representation Learning by Context ...

A Unified View of Masked Image Modeling - 知乎
Advertisement Space (336x280)

Detecting faces in images with the Vision framework

Figure 1 from What Makes Good Examples for Visual In-Context Learning ...
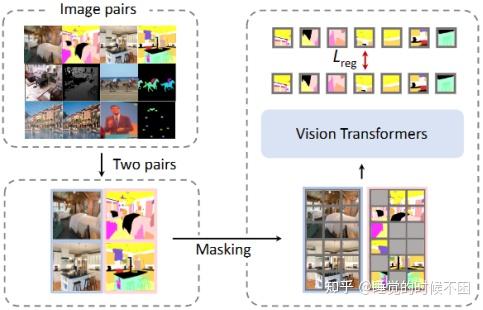
【论文阅读】Images Speak in Images: A Generalist Painter for In-Context ...

Visual Representation Learning from Unlabeled Video using Contrastive ...
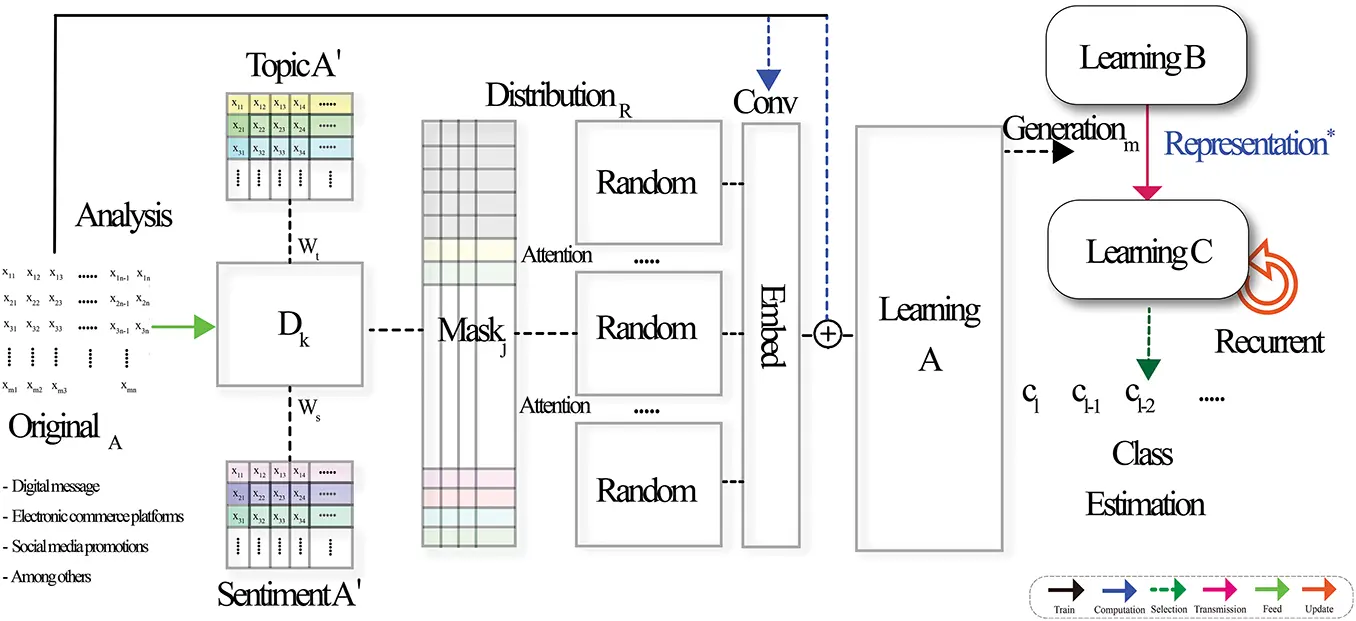
CMC | Free Full-Text | A Dynamic Masking-Based Multi-Learning Framework ...
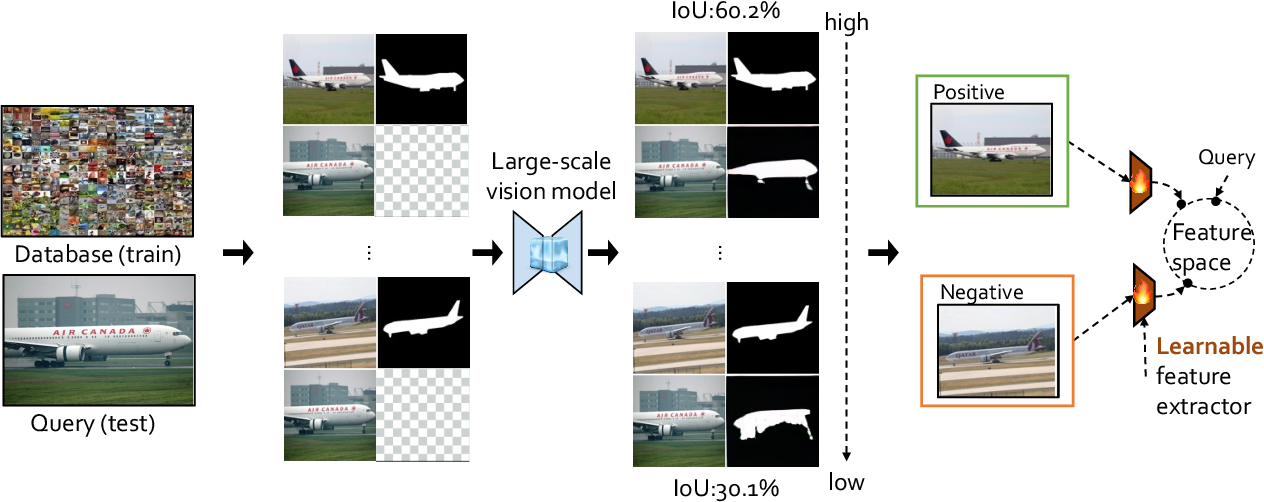
Figure 2 from What Makes Good Examples for Visual In-Context Learning ...