
Accelerate Socket Timeout On Multi Node Llm Training Intermediate

Accelerate socket timeout on multi-node LLM training - Intermediate ...

Accelerate socket timeout on multi-node LLM training - Intermediate ...
Multi node training exited with socket timeout · Issue #1105 · NVIDIA ...

NodeJS : node net socket connection timeout - YouTube

NodeJS : Configuring socket timeout on amqplib connect - YouTube

End-to-end LLM training on instance clusters with over 100 nodes using ...

Multi-node LLM Training on AMD GPUs : r/AMD_Stock

Multi-node LLM Training on AMD GPUs : r/AMD_Stock

How to Cause a TCP Socket Timeout | Baeldung on Linux

How to Cause a TCP Socket Timeout | Baeldung on Linux
Advertisement Space (300x250)
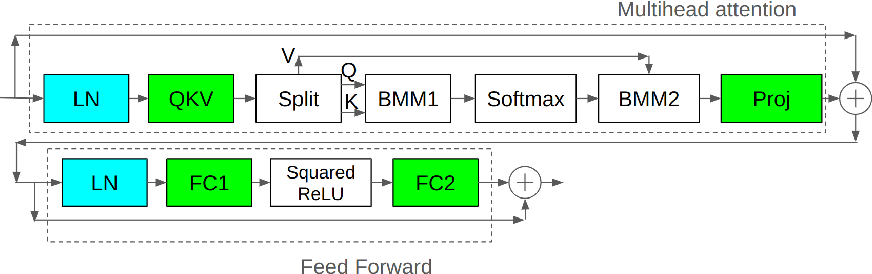
Figure 1 from Methods of improving LLM training stability | Semantic ...

No Time Like the Present: Agentic Test-Time Training for LLM Agents

Scaling LLM Training Using RDMA over Converged Ethernet | Proceedings ...

SOSP 2025 - ByteRobust: Robust LLM Training Infrastructure at ByteDance ...

Scaling LLM Training Using RDMA over Converged Ethernet | Proceedings ...
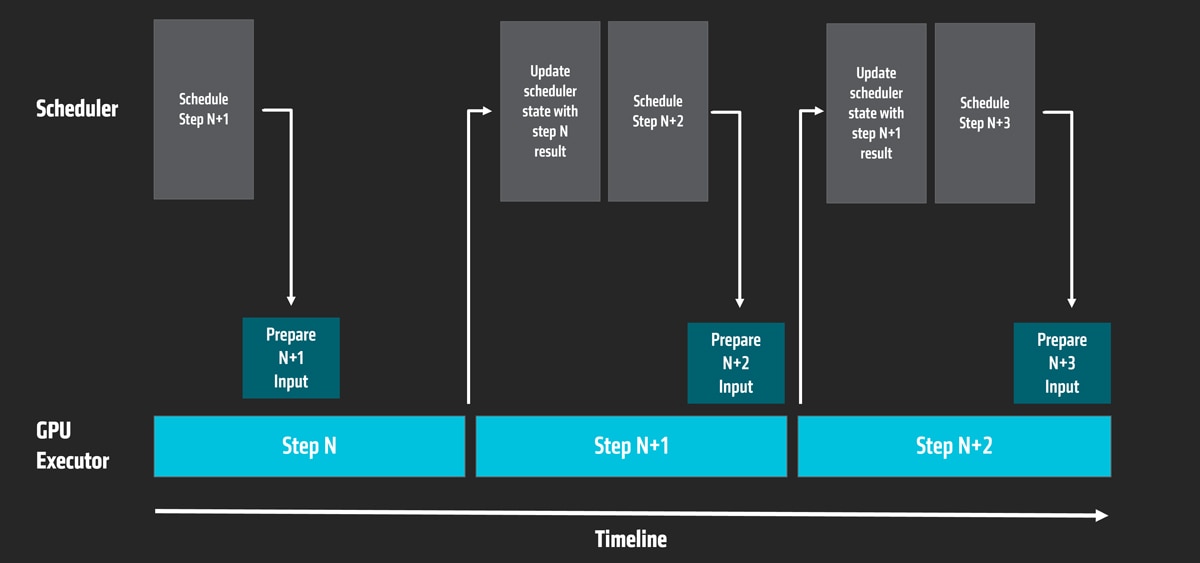
vLLM x AMD: Highly Efficient LLM Inference on AMD Instinct™ MI300X GPUs

Scaling LLM Training Using RDMA over Converged Ethernet | Proceedings ...

LLM Training Pipeline Overview | AI Tutorial | Next Electronics
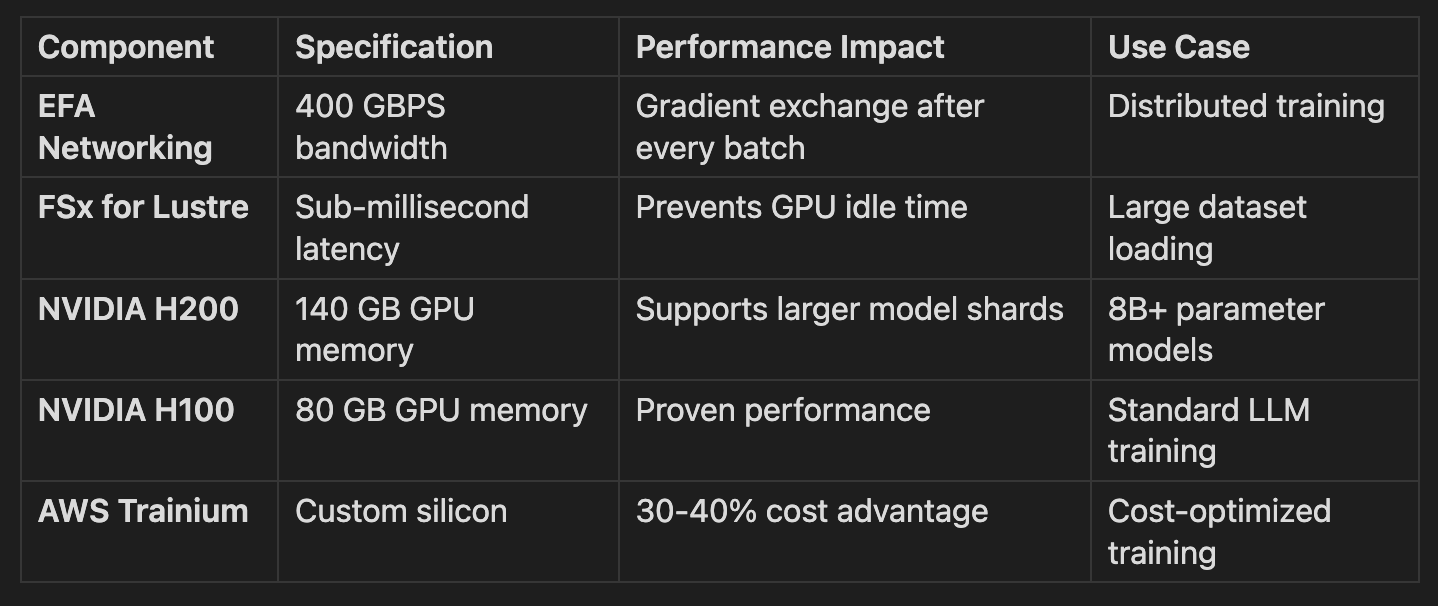
Analysis of LLM Architectures and AWS for Training and Inference Pipelines
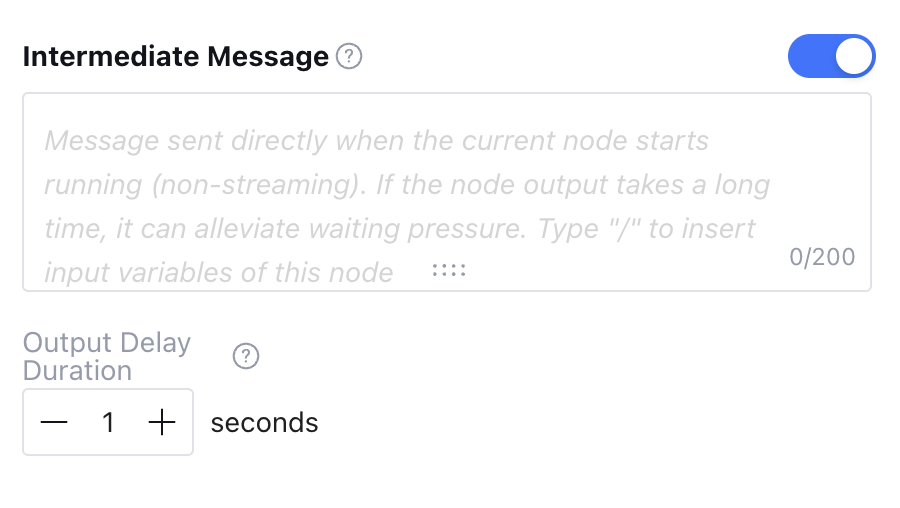
LLM Node
Advertisement Space (336x280)
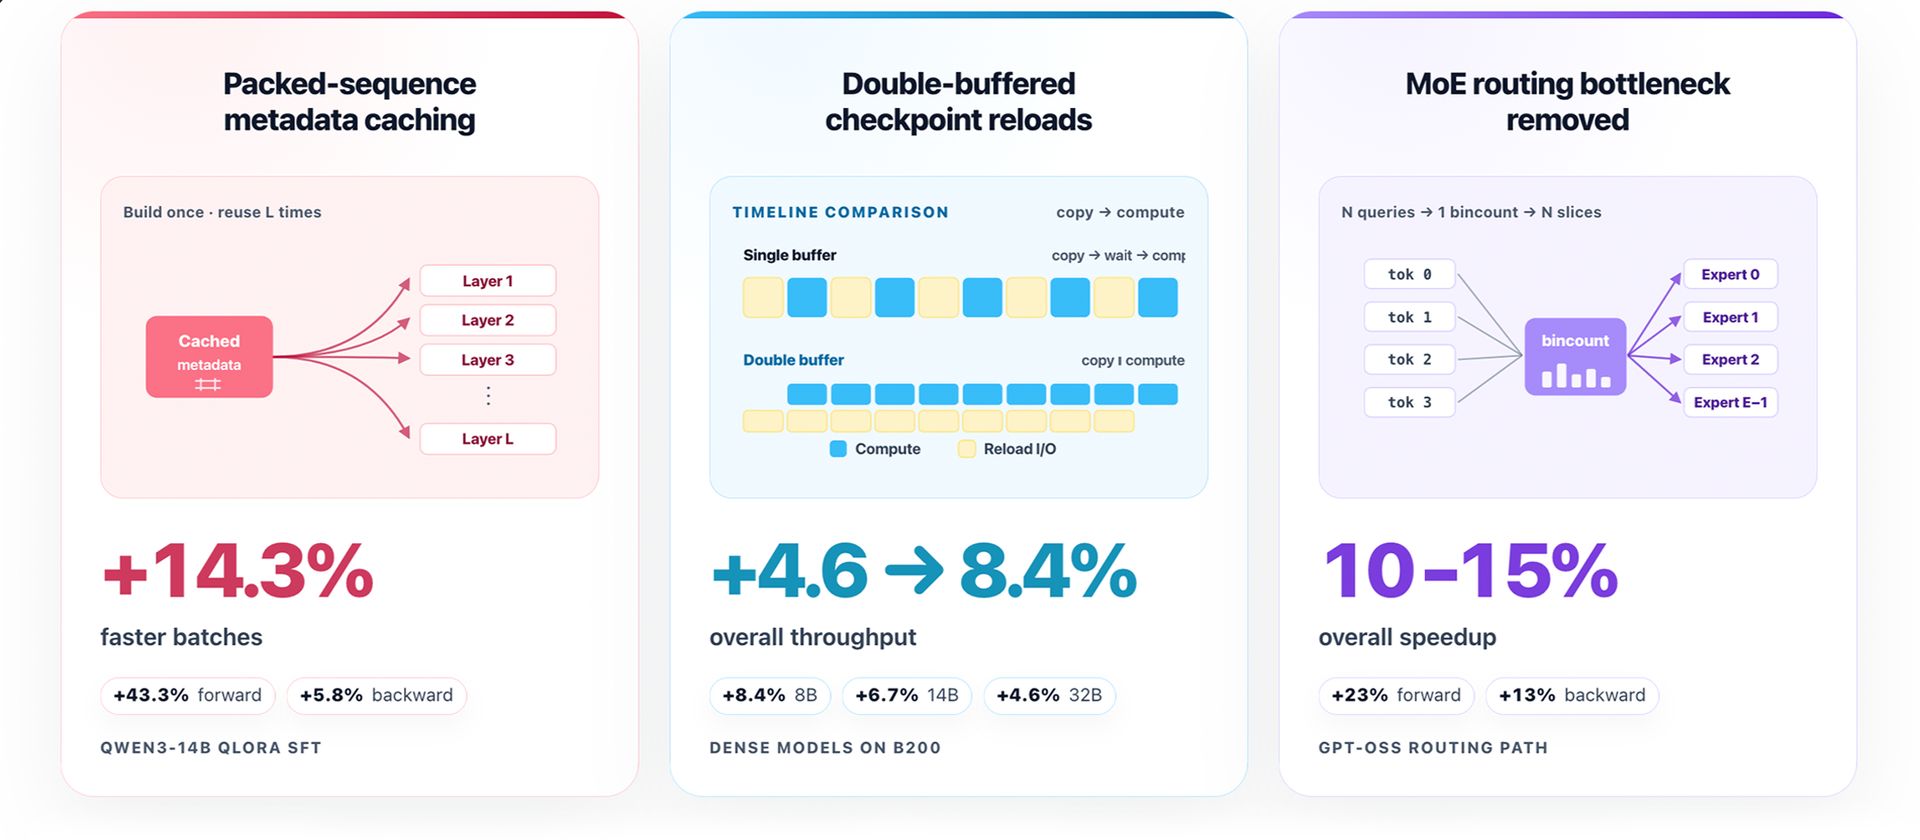
How to Make LLM Training Faster with Unsloth and NVIDIA
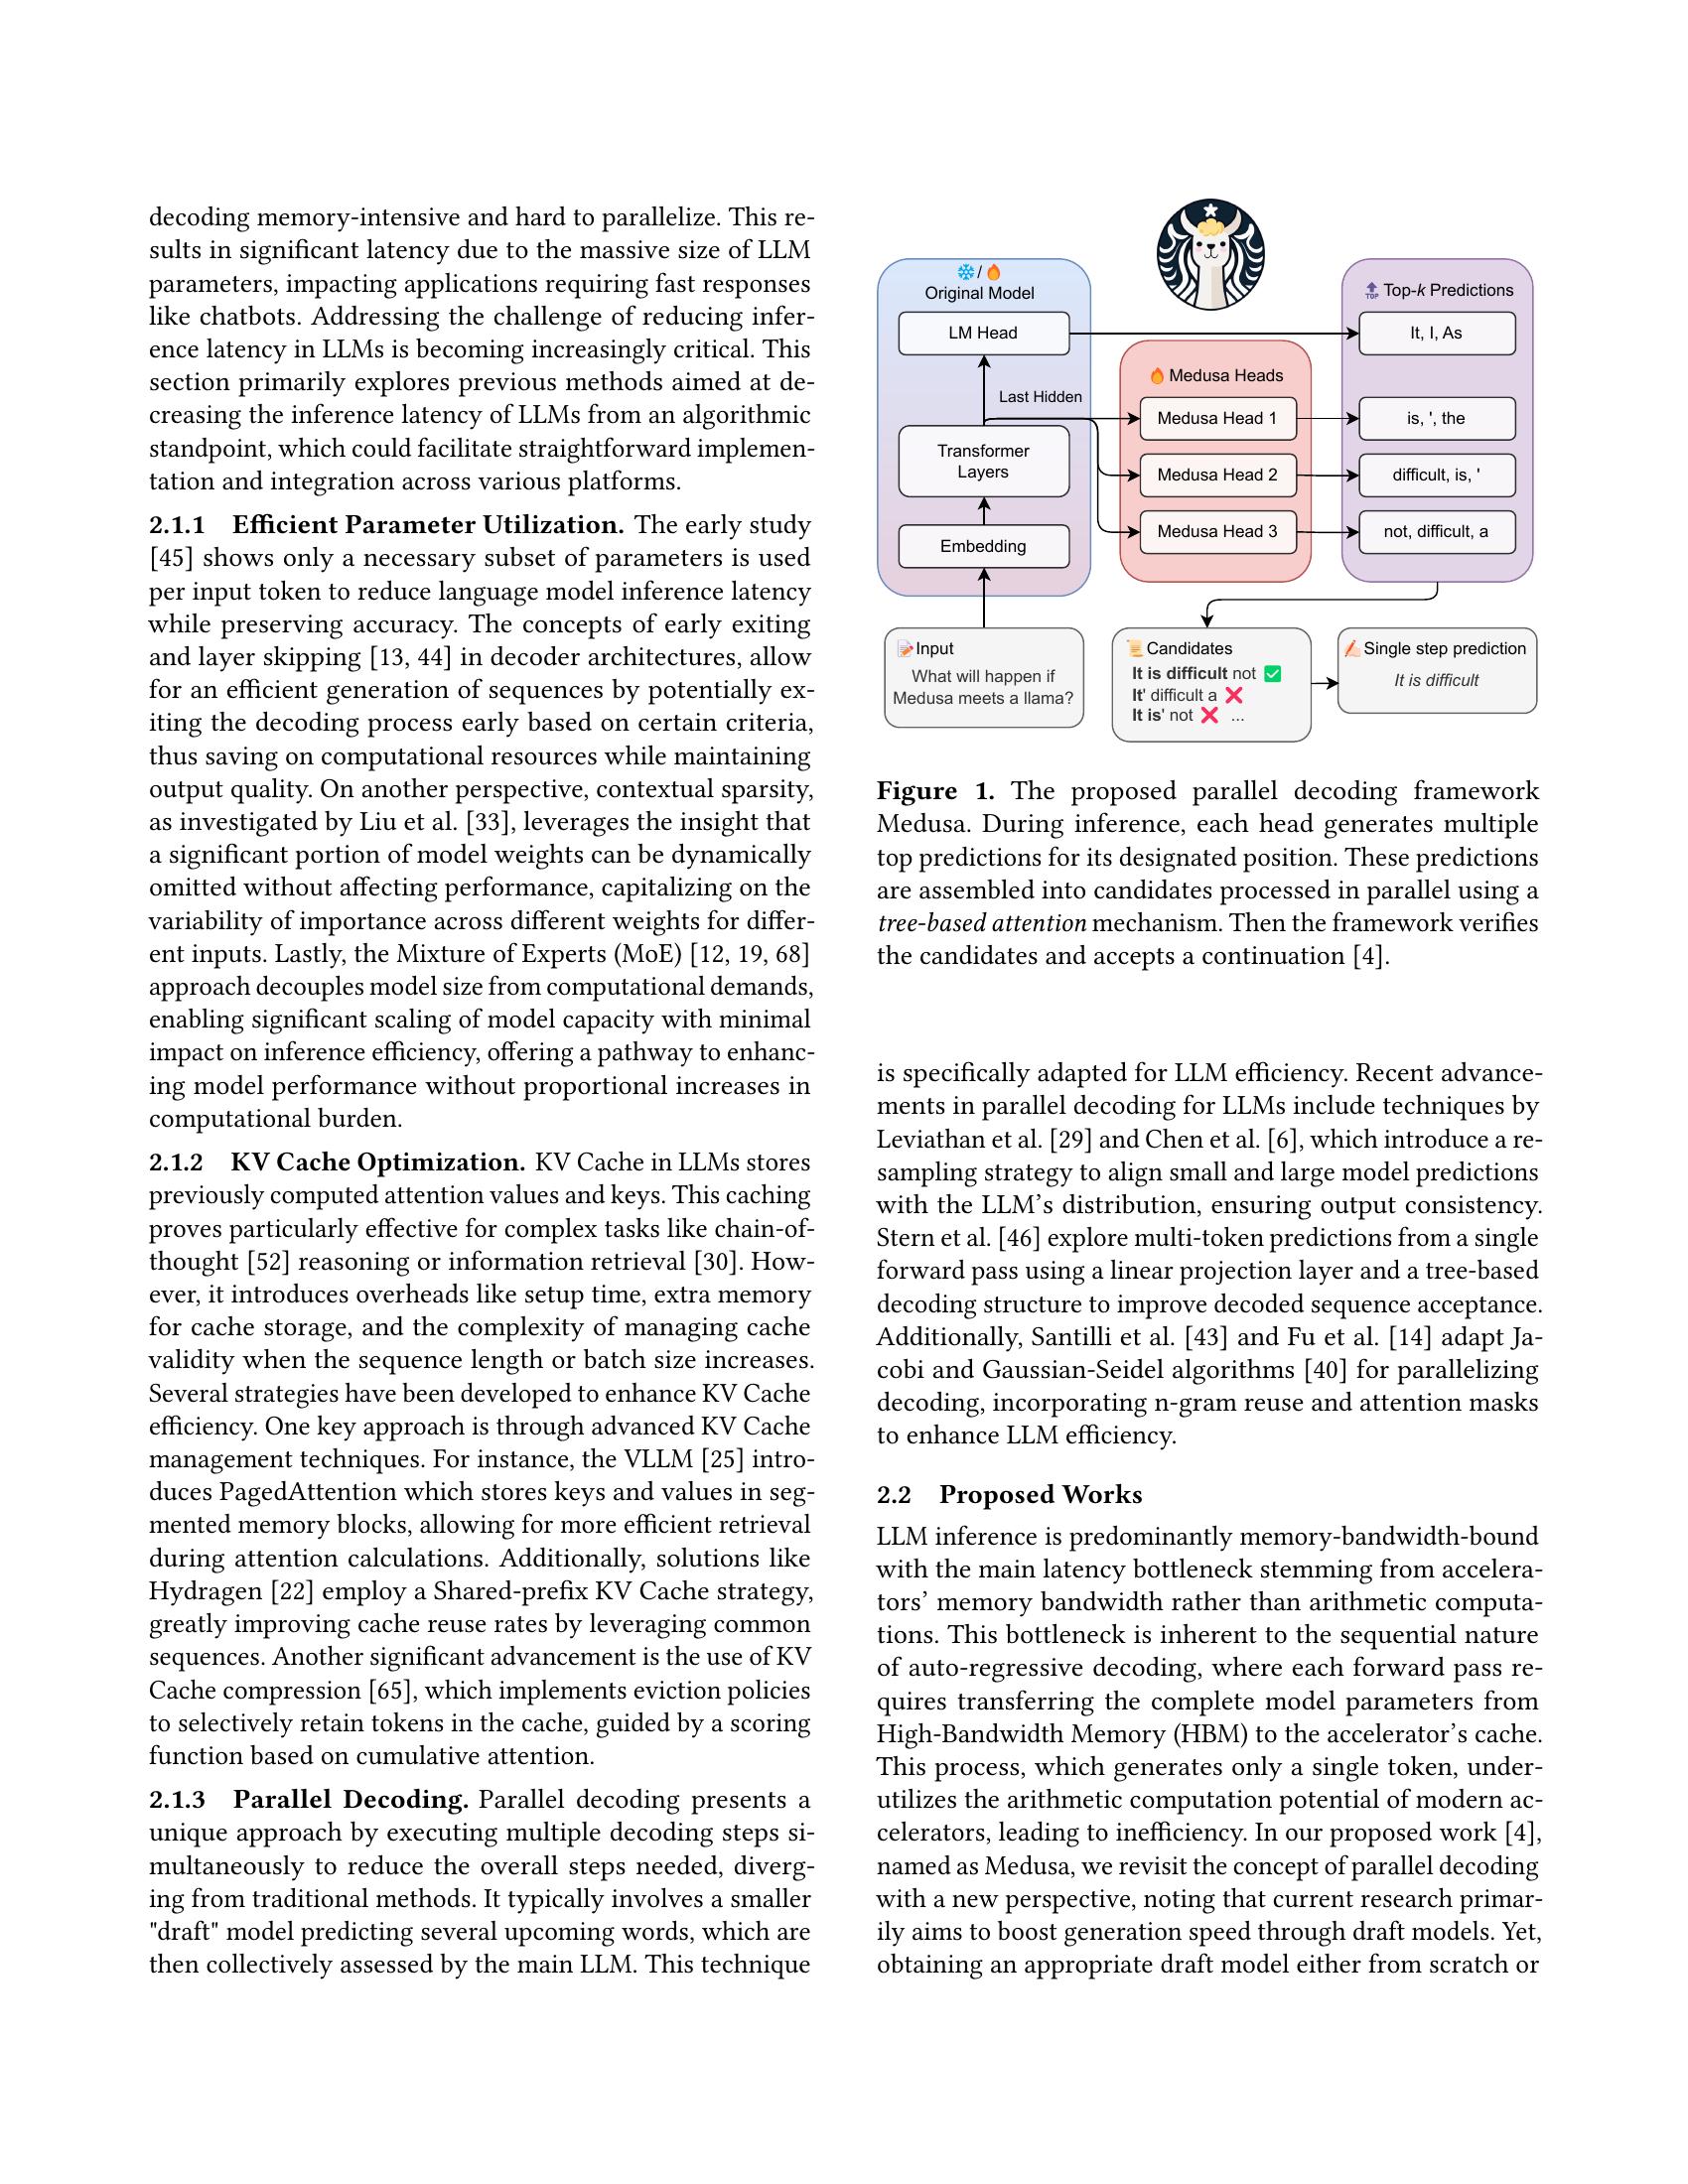
New Solutions on LLM Acceleration, Optimization, and Application - 智源社区论文
How to Make LLM Training Faster with Unsloth and NVIDIA

Pipeline LLM Node token-computing time issue - Ask the Community ...
Discussion on "Building a Low-Latency LLM Inference Pipeline" | Hashnode
Scaling Up LLM Pretraining: Parallel Training | PDF

Error is a socket timeout issue during the npm install process ...
Basic LLM Chain node calling out a model is extremly slow · Issue ...
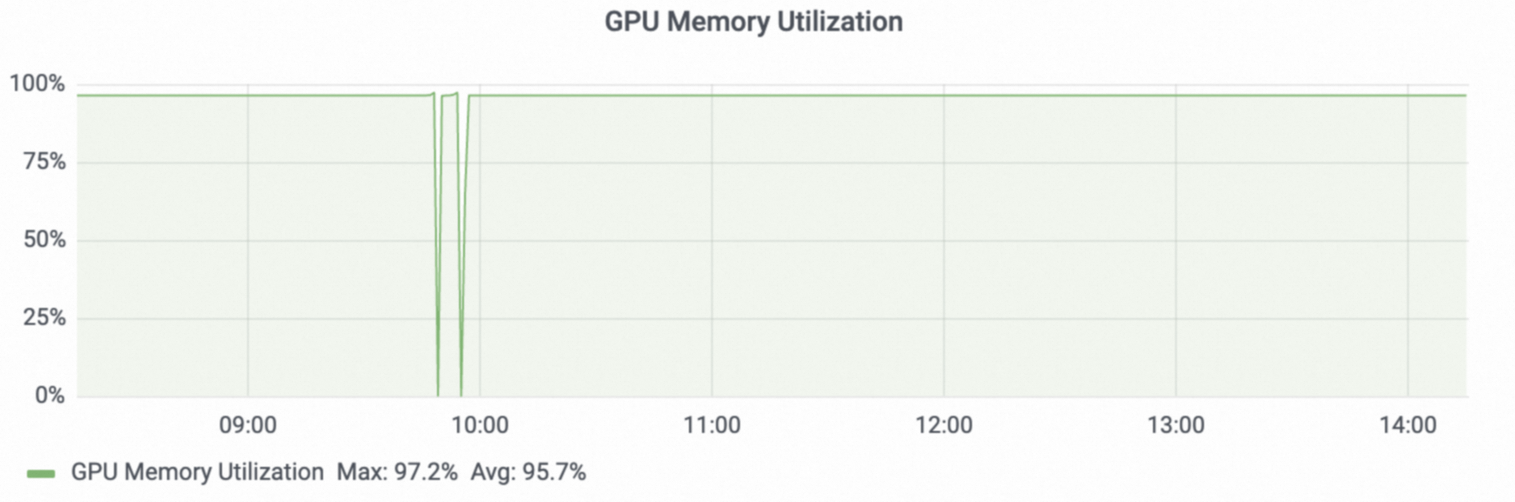
Best Practices for High Availability of LLM Based on AI Gateway ...

C++ : How to set a timeout on blocking sockets in boost asio? - YouTube
Advertisement Space (336x280)
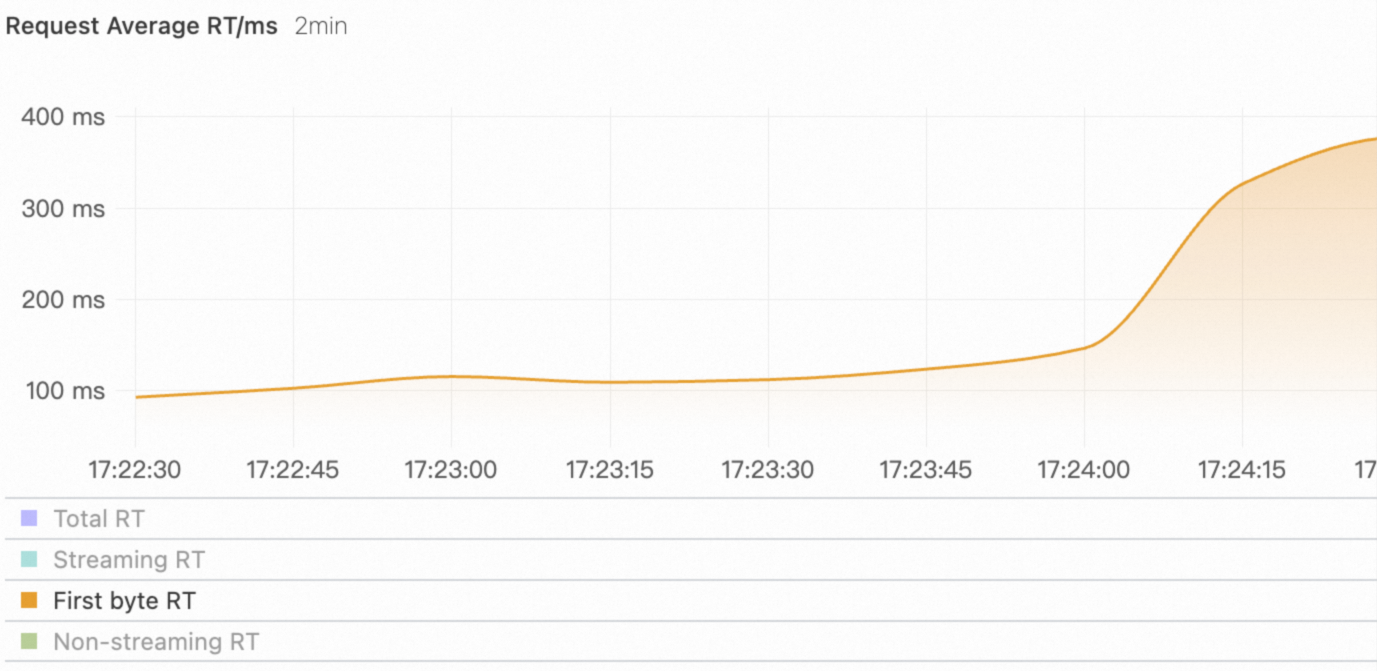
Best Practices for High Availability of LLM Based on AI Gateway ...

CTCCL: Cost-Efficient Joint Device-Network Load Balancing for LLM ...

Multi-stage Flow Scheduling for LLM Serving

LMetric*: Simple is Better – Multiplication May Be All You Need for LLM ...
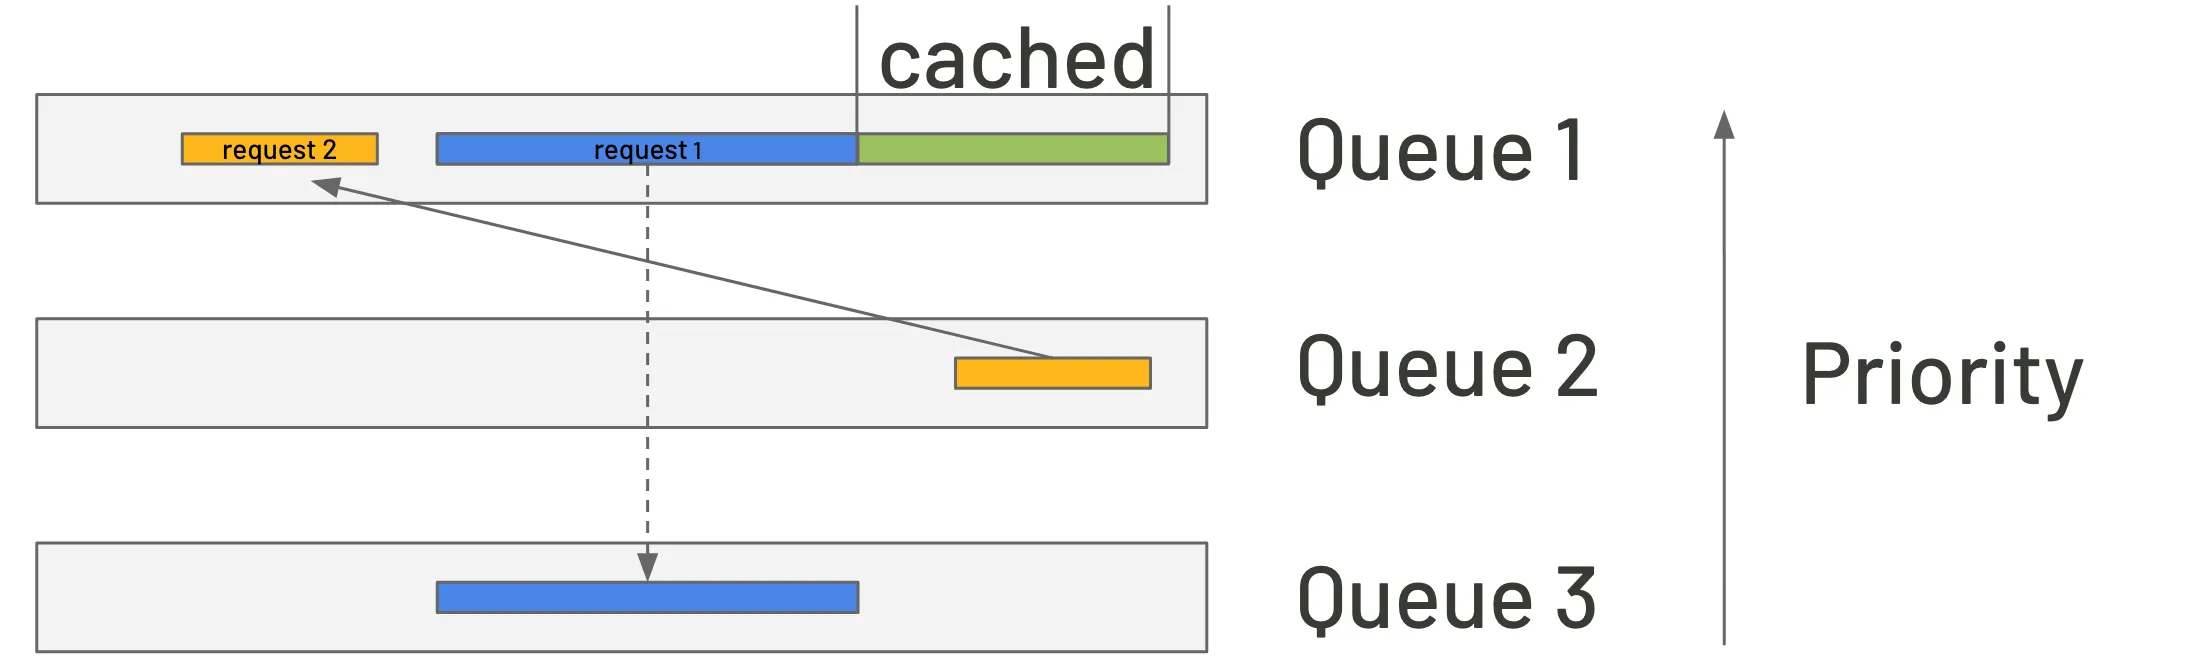
The Art of LLM Inference: Fast, Fit, and Free (PART 2)
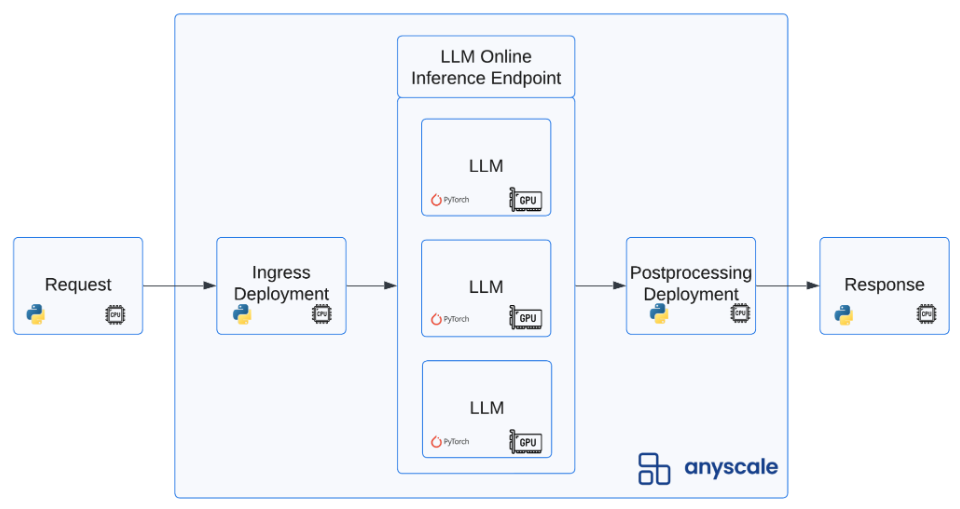
GitHub - anyscale/e2e-llm-workflows: End-to-End LLM Guide