
Accelerating Edge Inference For Distributed Moe Models With Latency

Accelerating Edge Inference for Distributed MoE Models with Latency ...
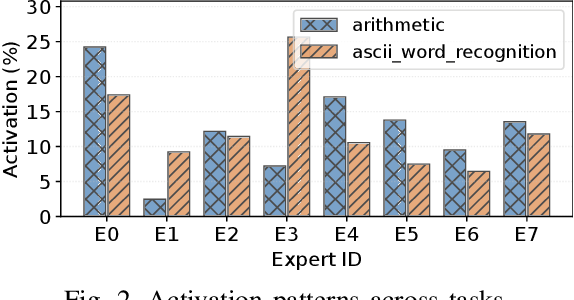
Figure 2 from Accelerating Edge Inference for Distributed MoE Models ...

Accelerating Distributed MoE Training and Inference with Lina | AI ...

Accelerating Distributed MoE Training and Inference with Lina - 知乎

Accelerating Distributed MoE Training and Inference with Lina - 知乎
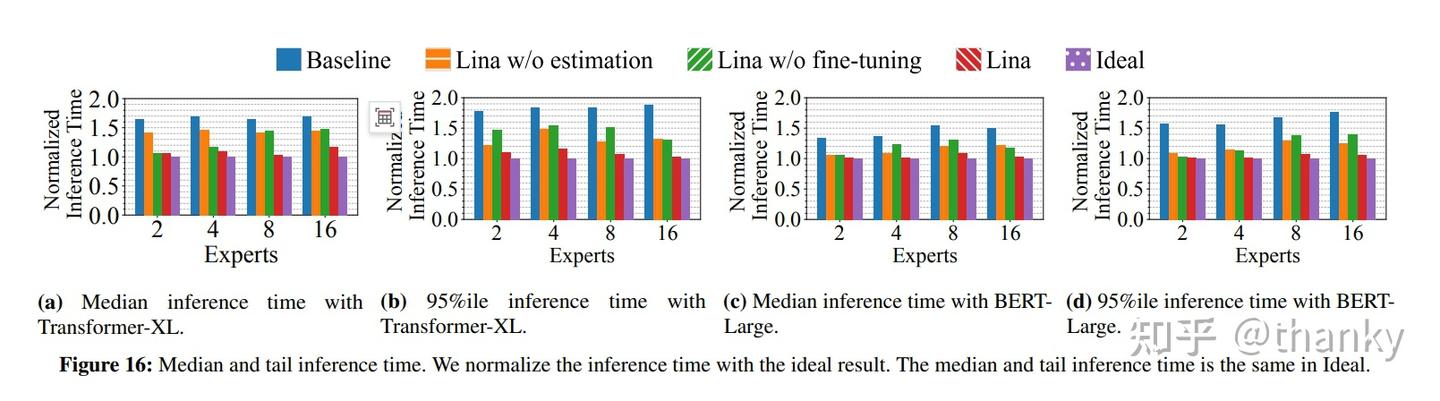
Accelerating Distributed MoE Training and Inference with Lina - 知乎

[PDF] Accelerating Distributed MoE Training and Inference with Lina ...
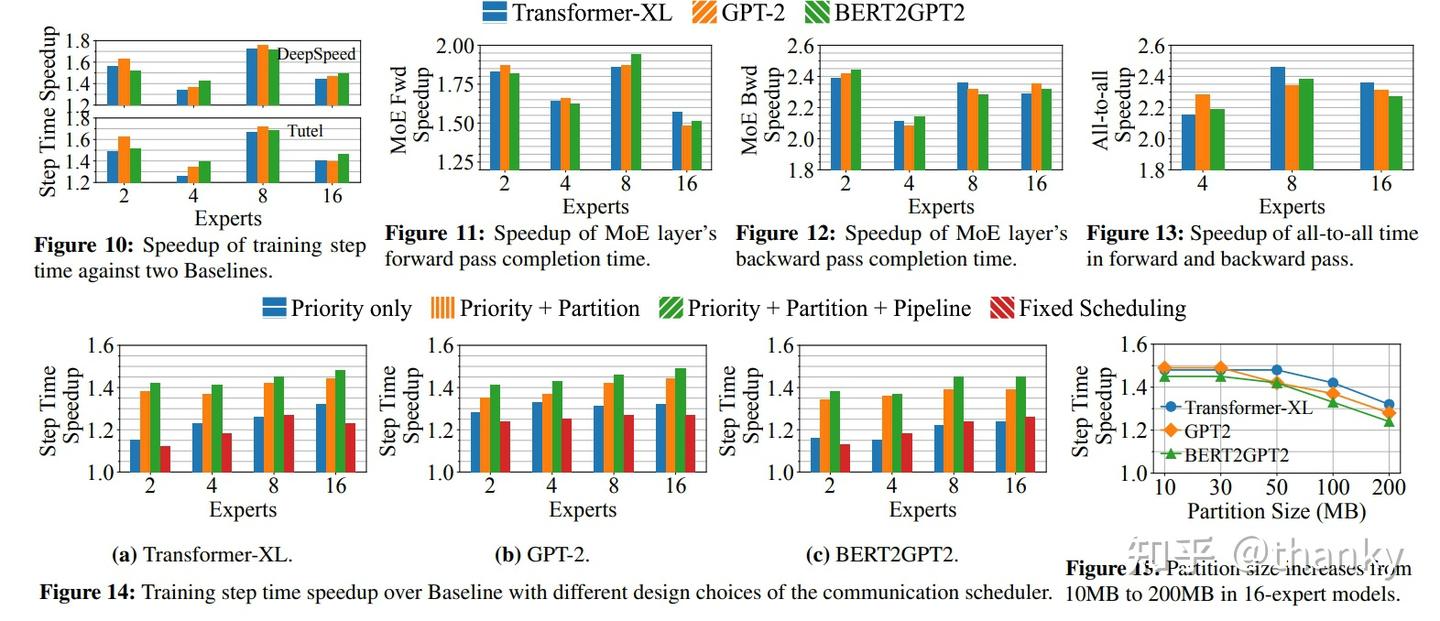
Accelerating Distributed MoE Training and Inference with Lina - 知乎

[PDF] Accelerating Distributed MoE Training and Inference with Lina ...

Figure 2 from Accelerating Distributed MoE Training and Inference with ...
Advertisement Space (300x250)

Accelerating Distributed MoE Training and Inference with Lina - 知乎
Accelerating Distributed MoE Training and Inference with Lina | Awesome ...

Accelerating Distributed MoE Training and Inference with Lina - 知乎

Accelerating Distributed MoE Training and Inference with Lina - 知乎

FlexPie: Accelerate Distributed Inference on Edge Devices with Flexible ...
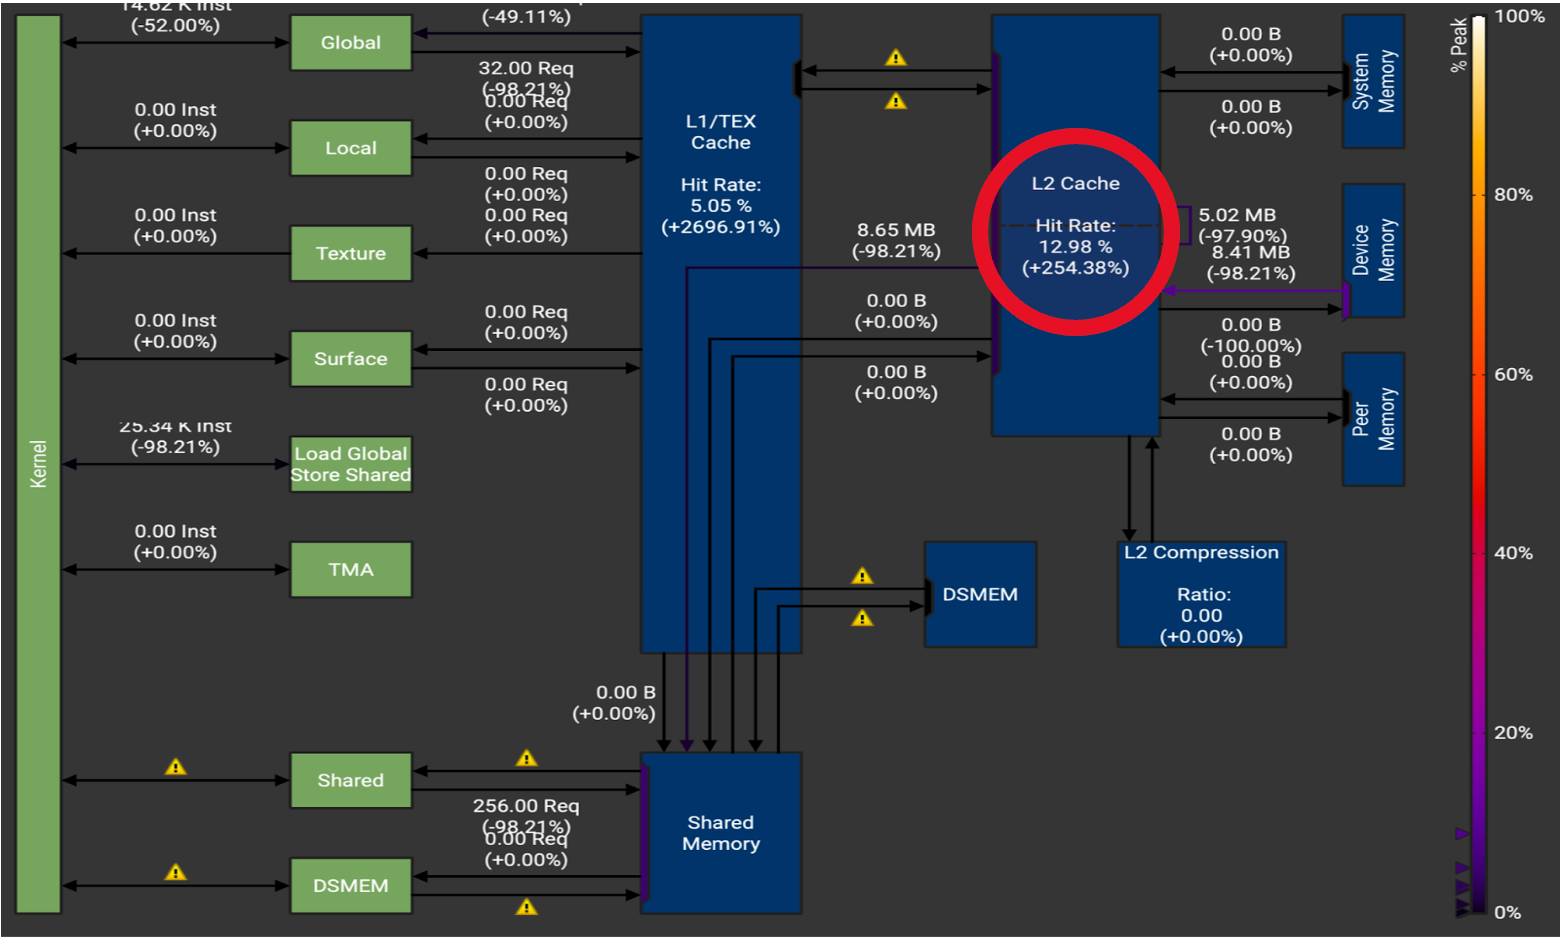
Accelerating MoE model inference with Locality-Aware Kernel Design ...

Normalized inference latency with the SSD-MobileNet model for the ...

(PDF) Low Latency Deep Learning Inference Model for Distributed ...

Figure 2 from LOW LATENCY DEEP LEARNING INFERENCE MODEL FOR DISTRIBUTED ...

Figure 1 from LOW LATENCY DEEP LEARNING INFERENCE MODEL FOR DISTRIBUTED ...
Advertisement Space (336x280)

Figure 4 from LOW LATENCY DEEP LEARNING INFERENCE MODEL FOR DISTRIBUTED ...

Accelerating MoE model inference with Locality-Aware Kernel Design ...

Figure 3 from LOW LATENCY DEEP LEARNING INFERENCE MODEL FOR DISTRIBUTED ...
How to Optimize Edge AI Models for Low Bandwidth | Inference Systems

Accelerating MoE model inference with Locality-Aware Kernel Design ...

Figure 8 from LOW LATENCY DEEP LEARNING INFERENCE MODEL FOR DISTRIBUTED ...

Figure 5 from LOW LATENCY DEEP LEARNING INFERENCE MODEL FOR DISTRIBUTED ...

Figure 1 from A Scheduling Framework for Efficient MoE Inference on ...
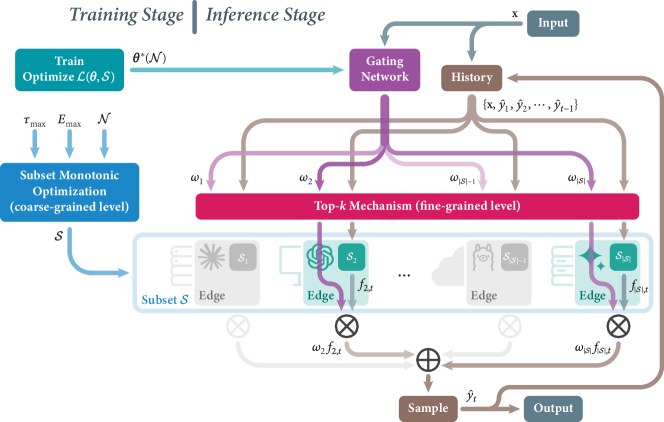
[2501.09410] MoE2: Optimizing Collaborative Inference for Edge Large ...
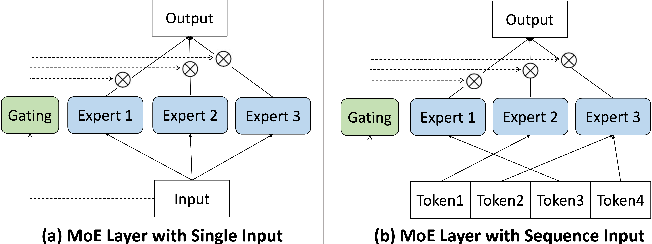
Figure 1 from Serving MoE Models on Resource-Constrained Edge Devices ...
Advertisement Space (336x280)

Empowering Low Latency AI Inference for Enhanced Efficiency
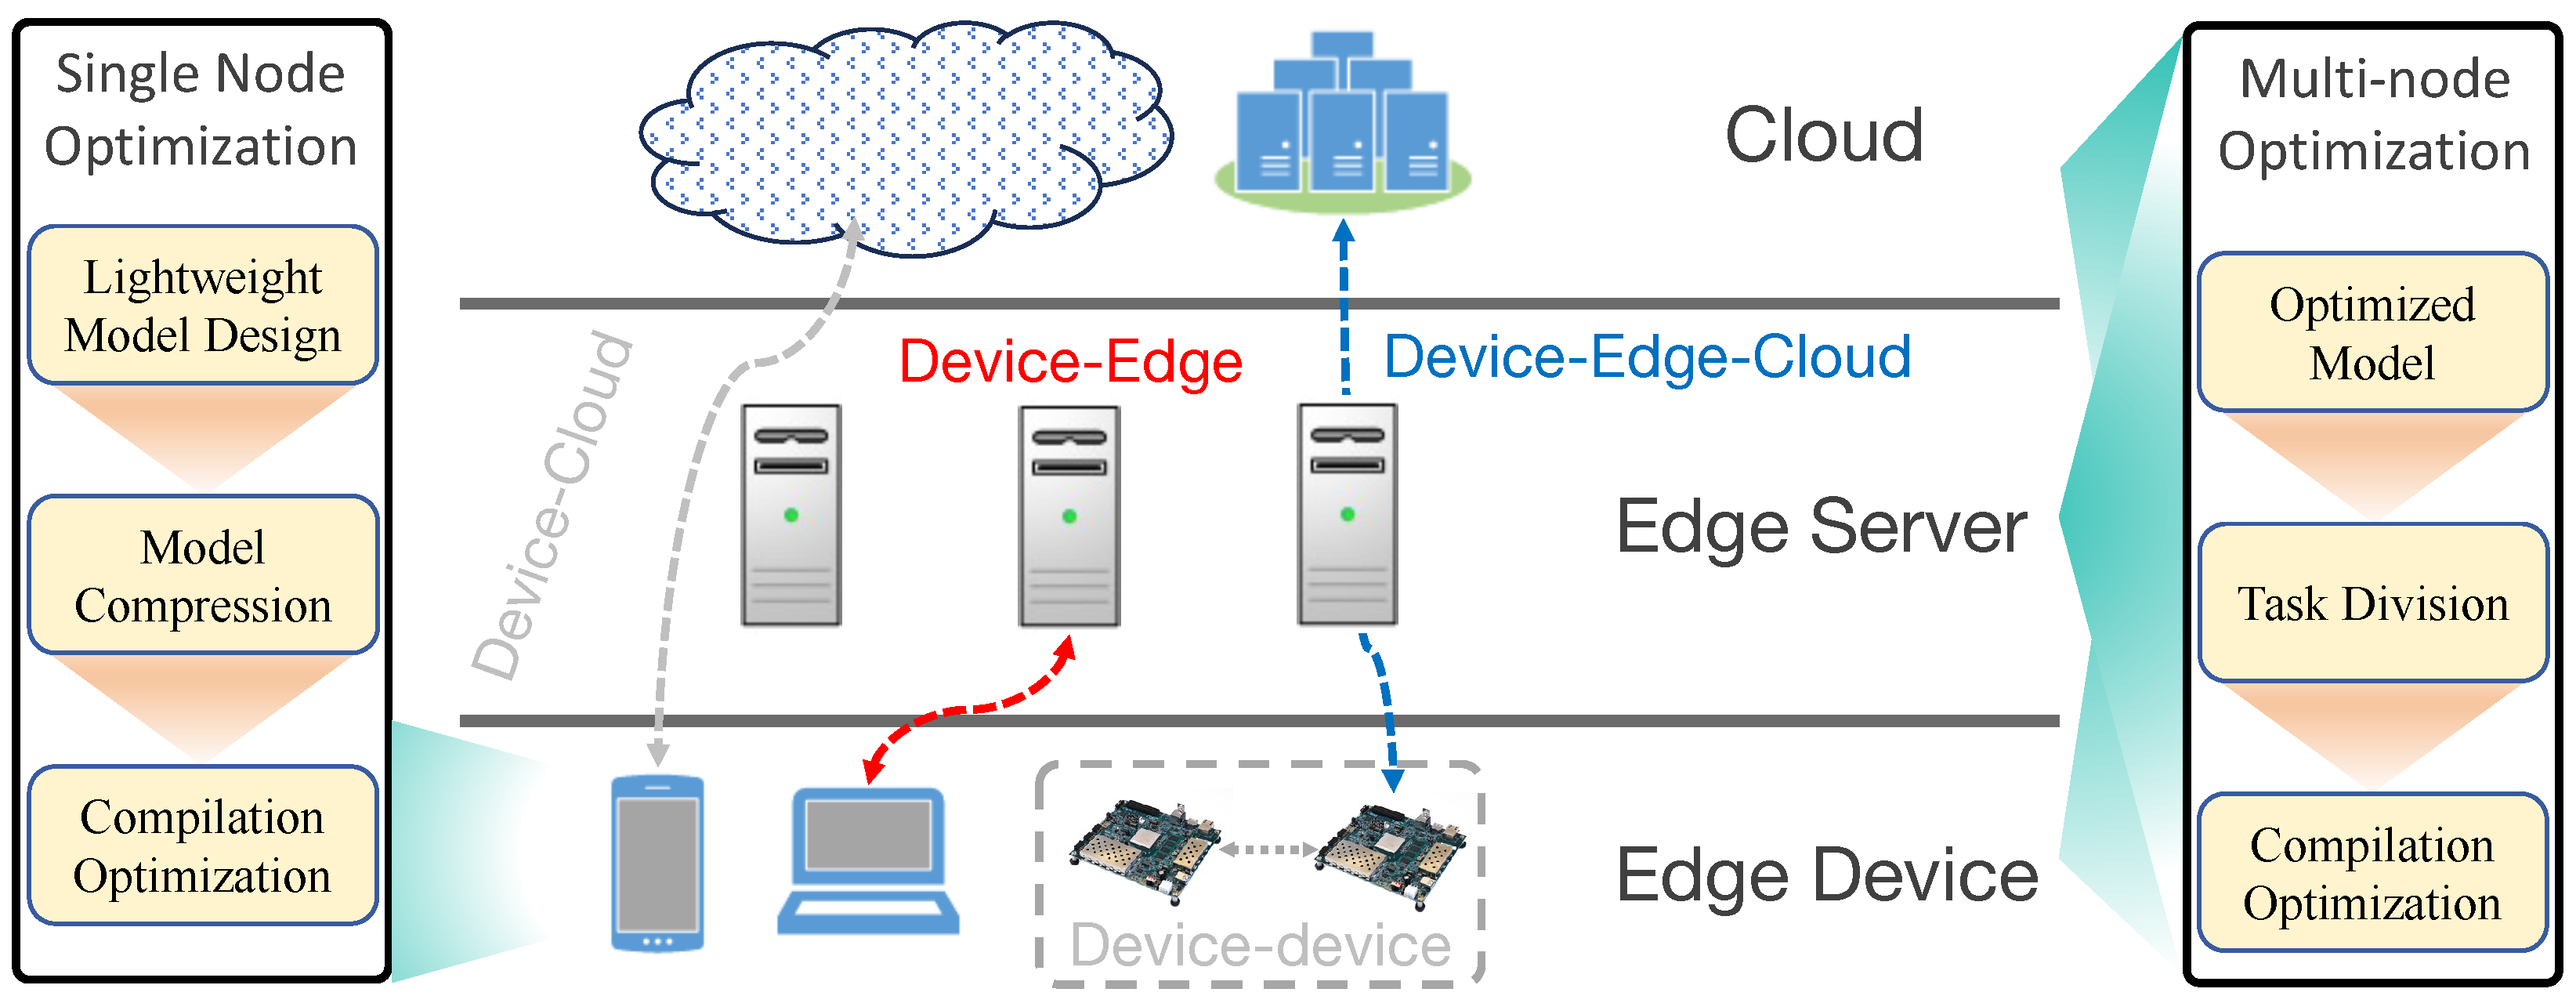
Optimization Methods, Challenges, and Opportunities for Edge Inference ...
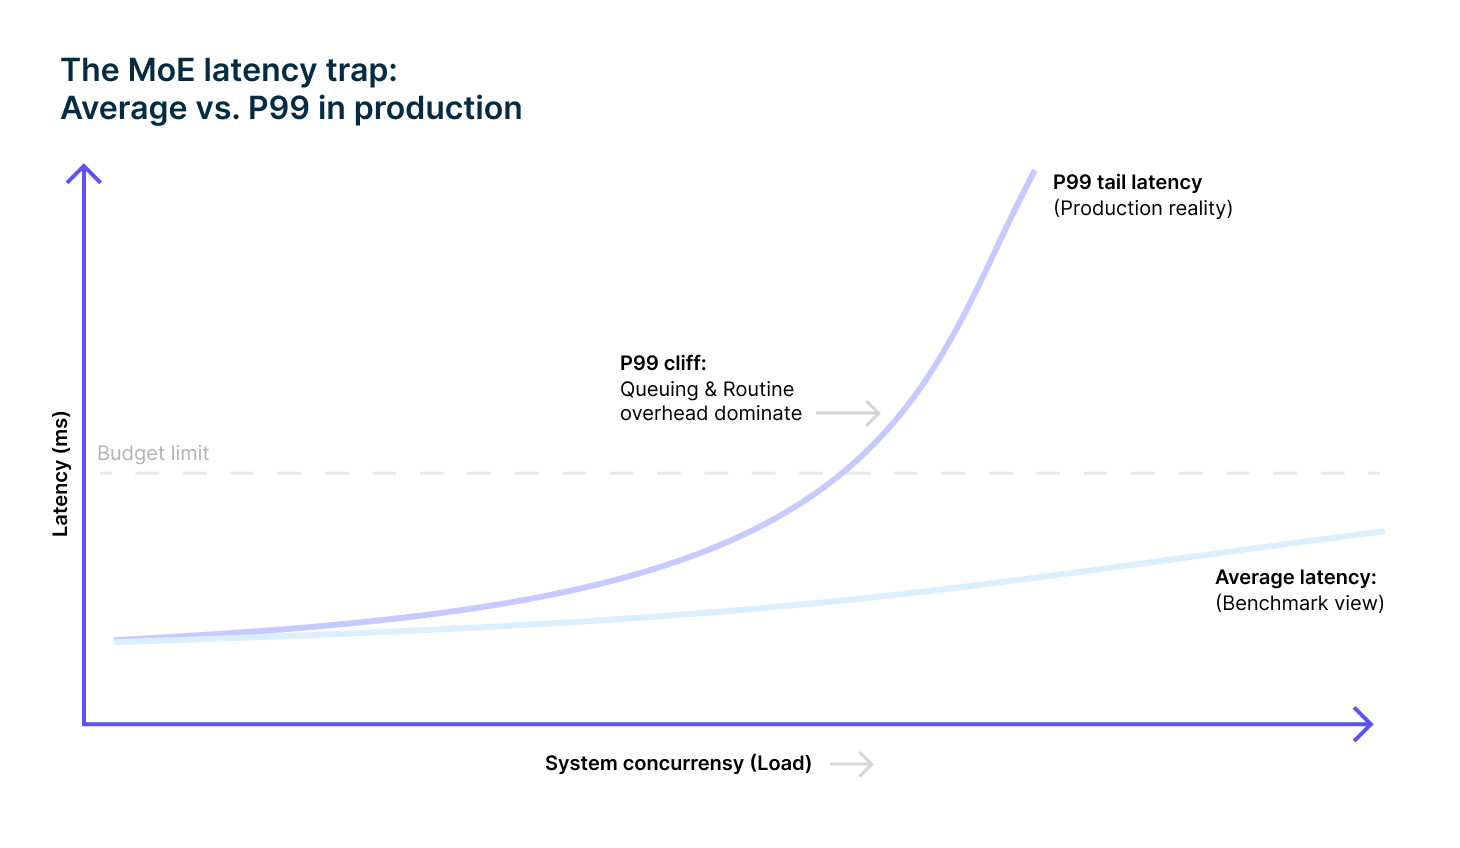
Why large MoE models break latency budgets and what speculative ...
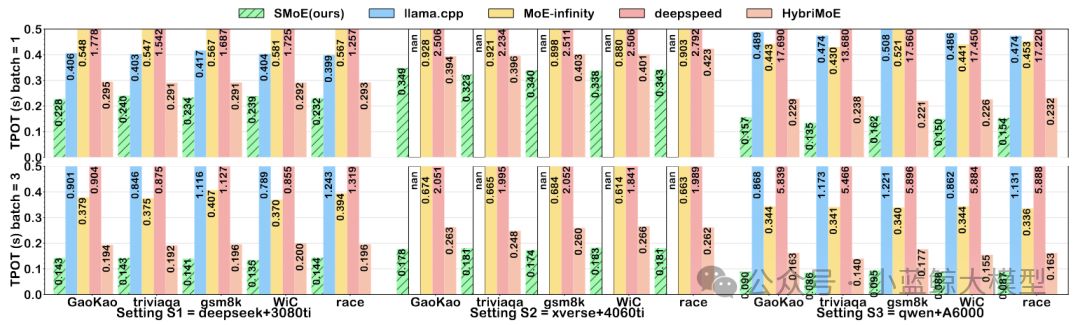
ISCA 2026 | New MoE LLM Edge Inference Acceleration Method Reduces ...

Paper page - MoE^2: Optimizing Collaborative Inference for Edge Large ...
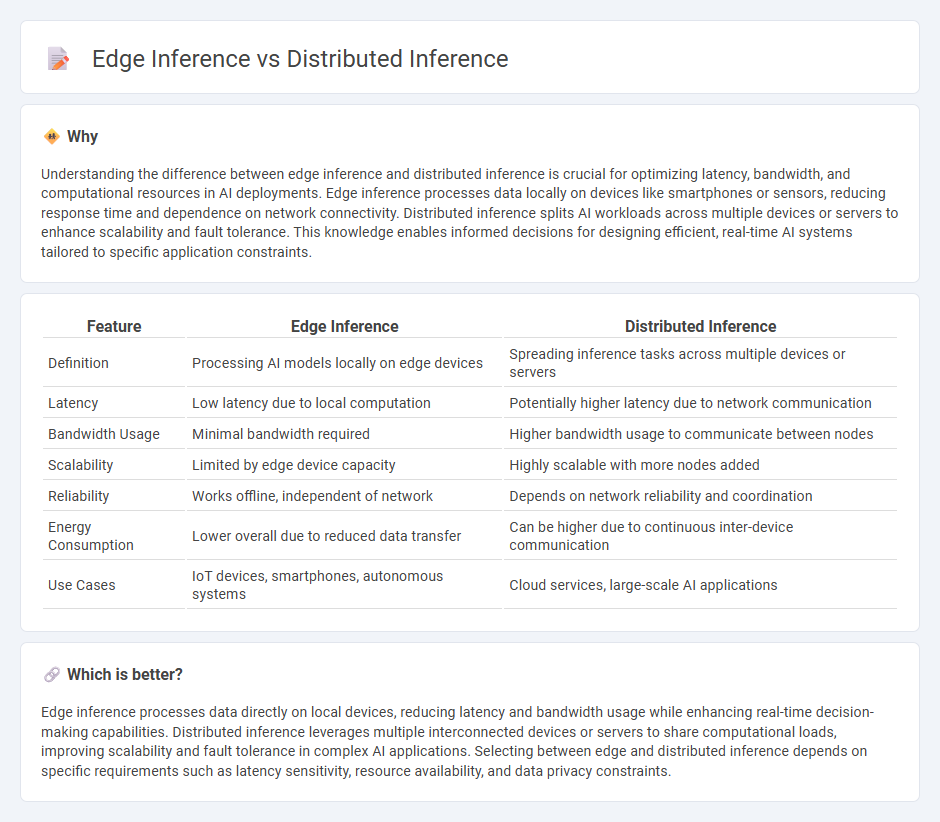
Edge Inference vs Distributed Inference in Technology / dowidth.com