
Accelerating Llm Inference With Staged Speculative Decoding Paper Details
Accelerating LLM Inference with Staged Speculative Decoding - Paper Details

Paper page - Accelerating LLM Inference with Staged Speculative Decoding

(PDF) Accelerating LLM Inference with Staged Speculative Decoding

Accelerating LLM Inference with Staged Speculative Decoding: Paper and ...

[2308.04623] Accelerating LLM Inference with Staged Speculative Decoding
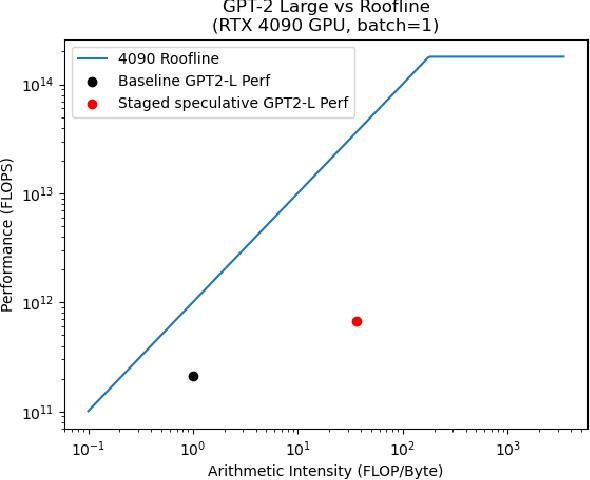
Figure 1 from Accelerating LLM Inference with Staged Speculative ...

(PDF) Accelerating LLM Inference with Lossless Speculative Decoding ...

Table 2 from Accelerating LLM Inference with Staged Speculative ...

Accelerating LLM Inference with Speculative Decoding - LinkedIn ...
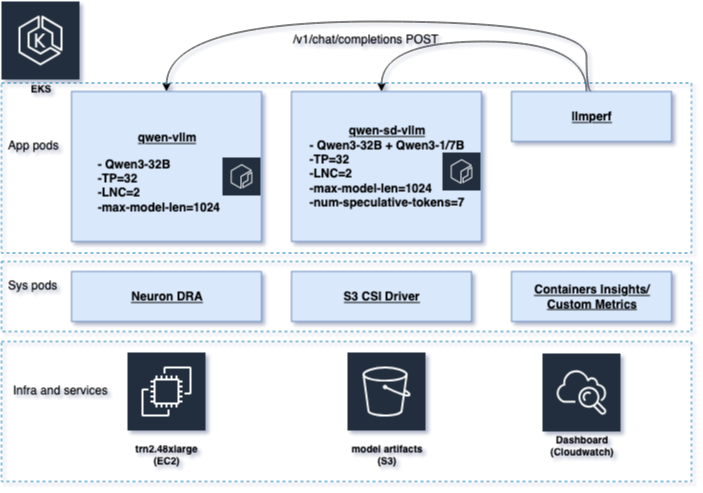
Accelerating decode-heavy LLM inference with speculative decoding on ...
Advertisement Space (300x250)

SDSAT: Accelerating LLM Inference through Speculative Decoding with ...

Speculative Decoding with CTC-based Draft Model for LLM Inference ...
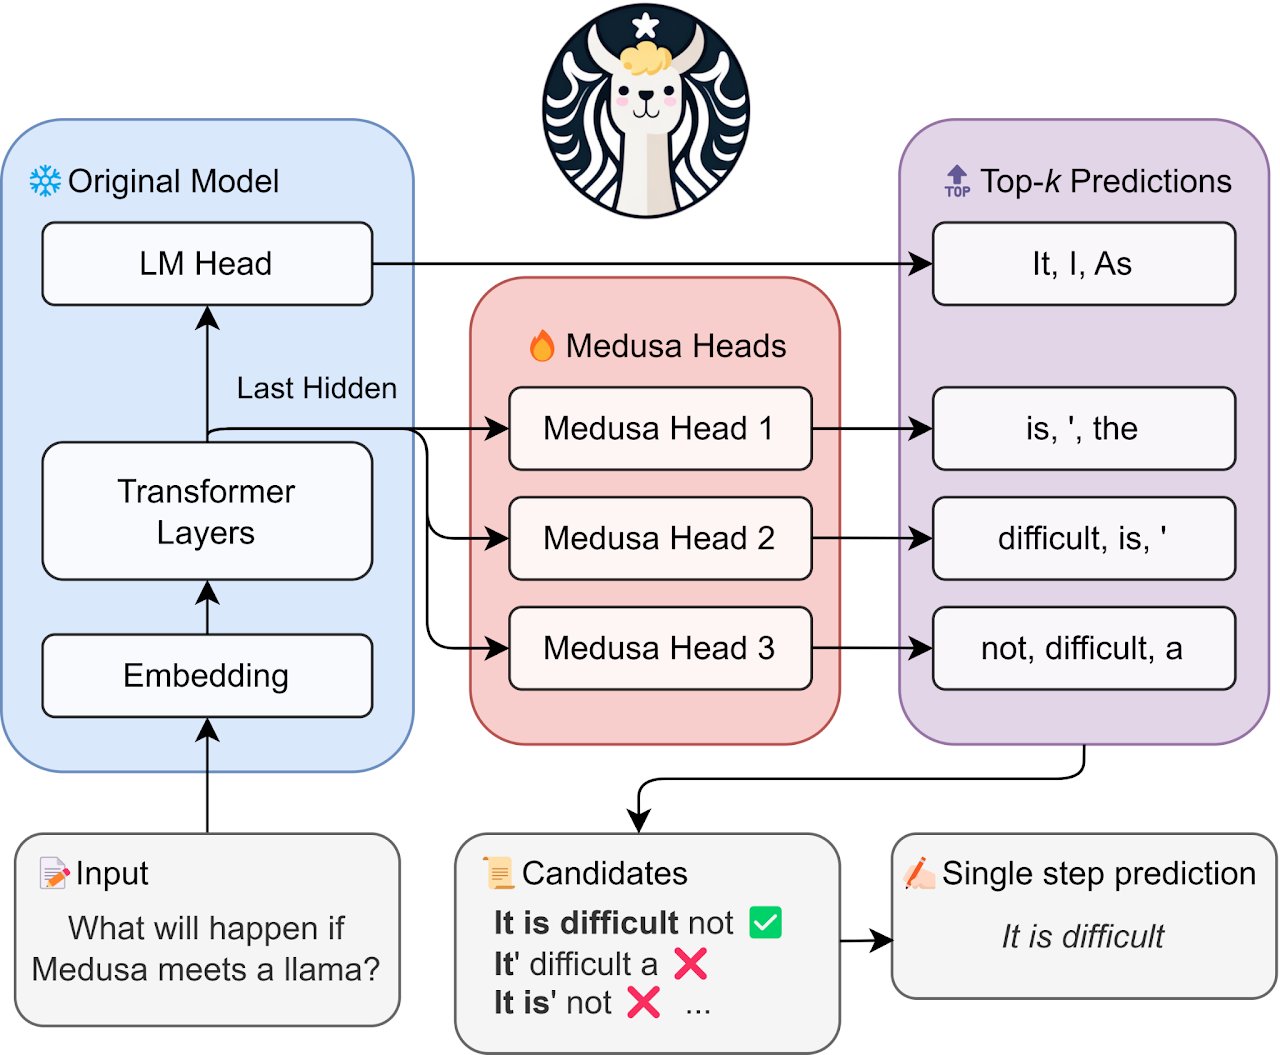
Accelerate LLM Inference with Speculative Decoding | Charles Xu
🚀 Speed Up LLM Inference with Speculative Decoding | by Generative AI ...
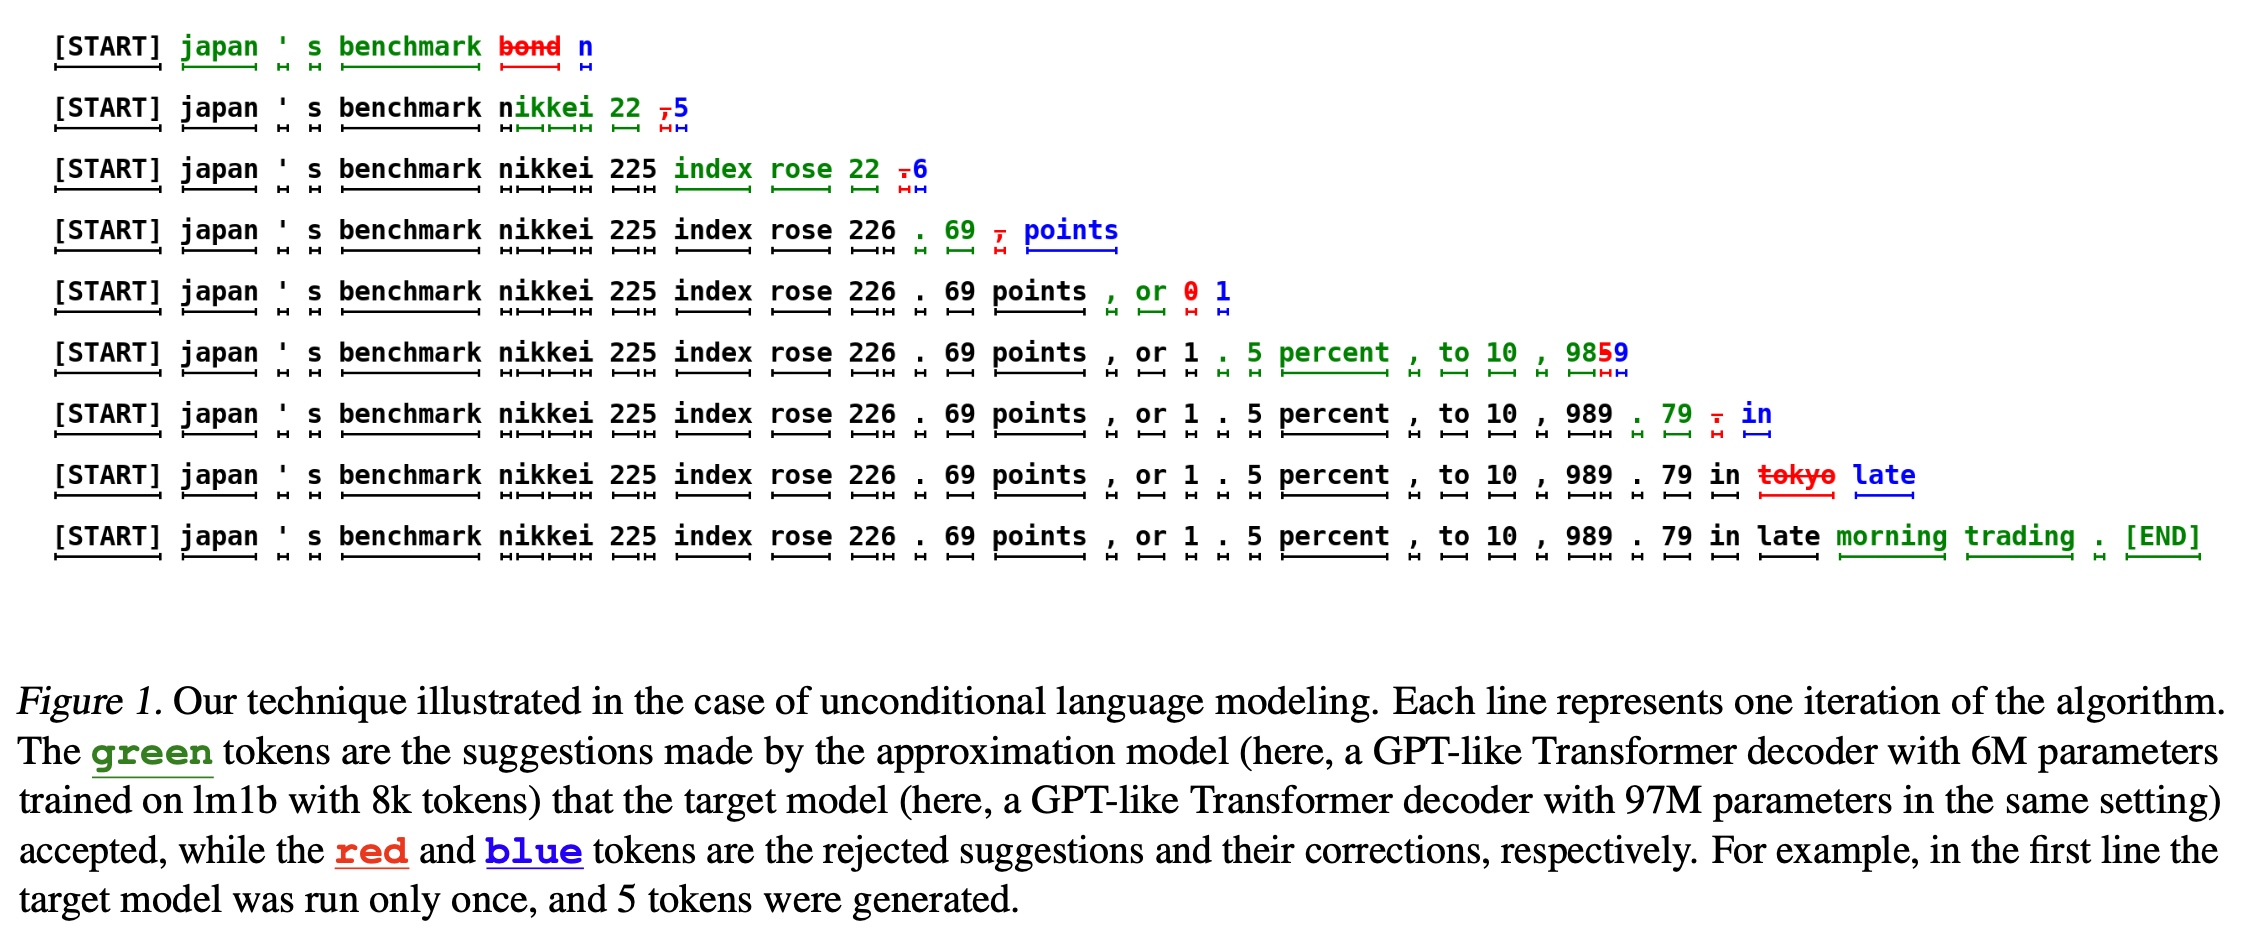
Accelerate LLM Inference with Speculative Decoding | Charles Xu
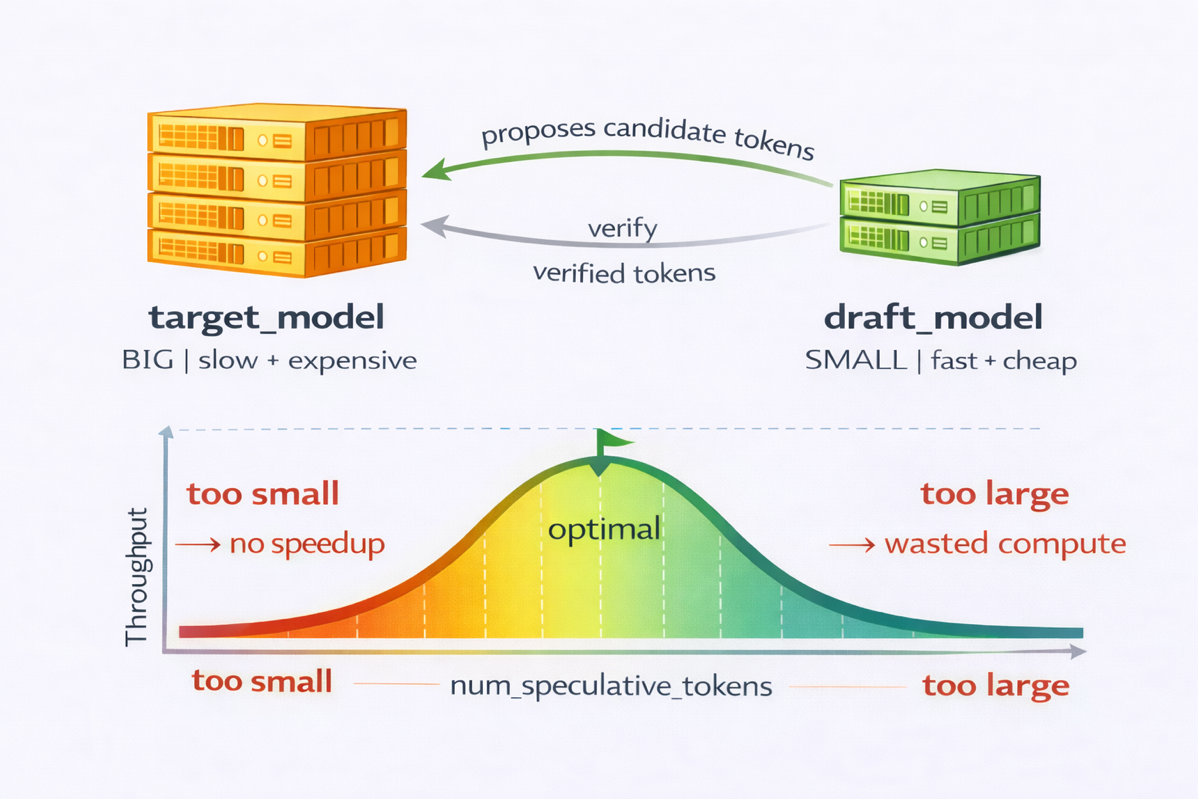
Tuto Startup - Accelerating decode-heavy LLM inference with speculative dec

Paper page - Recursive Speculative Decoding: Accelerating LLM Inference ...

Speculative Decoding via Early-exiting for Faster LLM Inference with ...

[논문 리뷰] SDSAT: Accelerating LLM Inference through Speculative Decoding ...
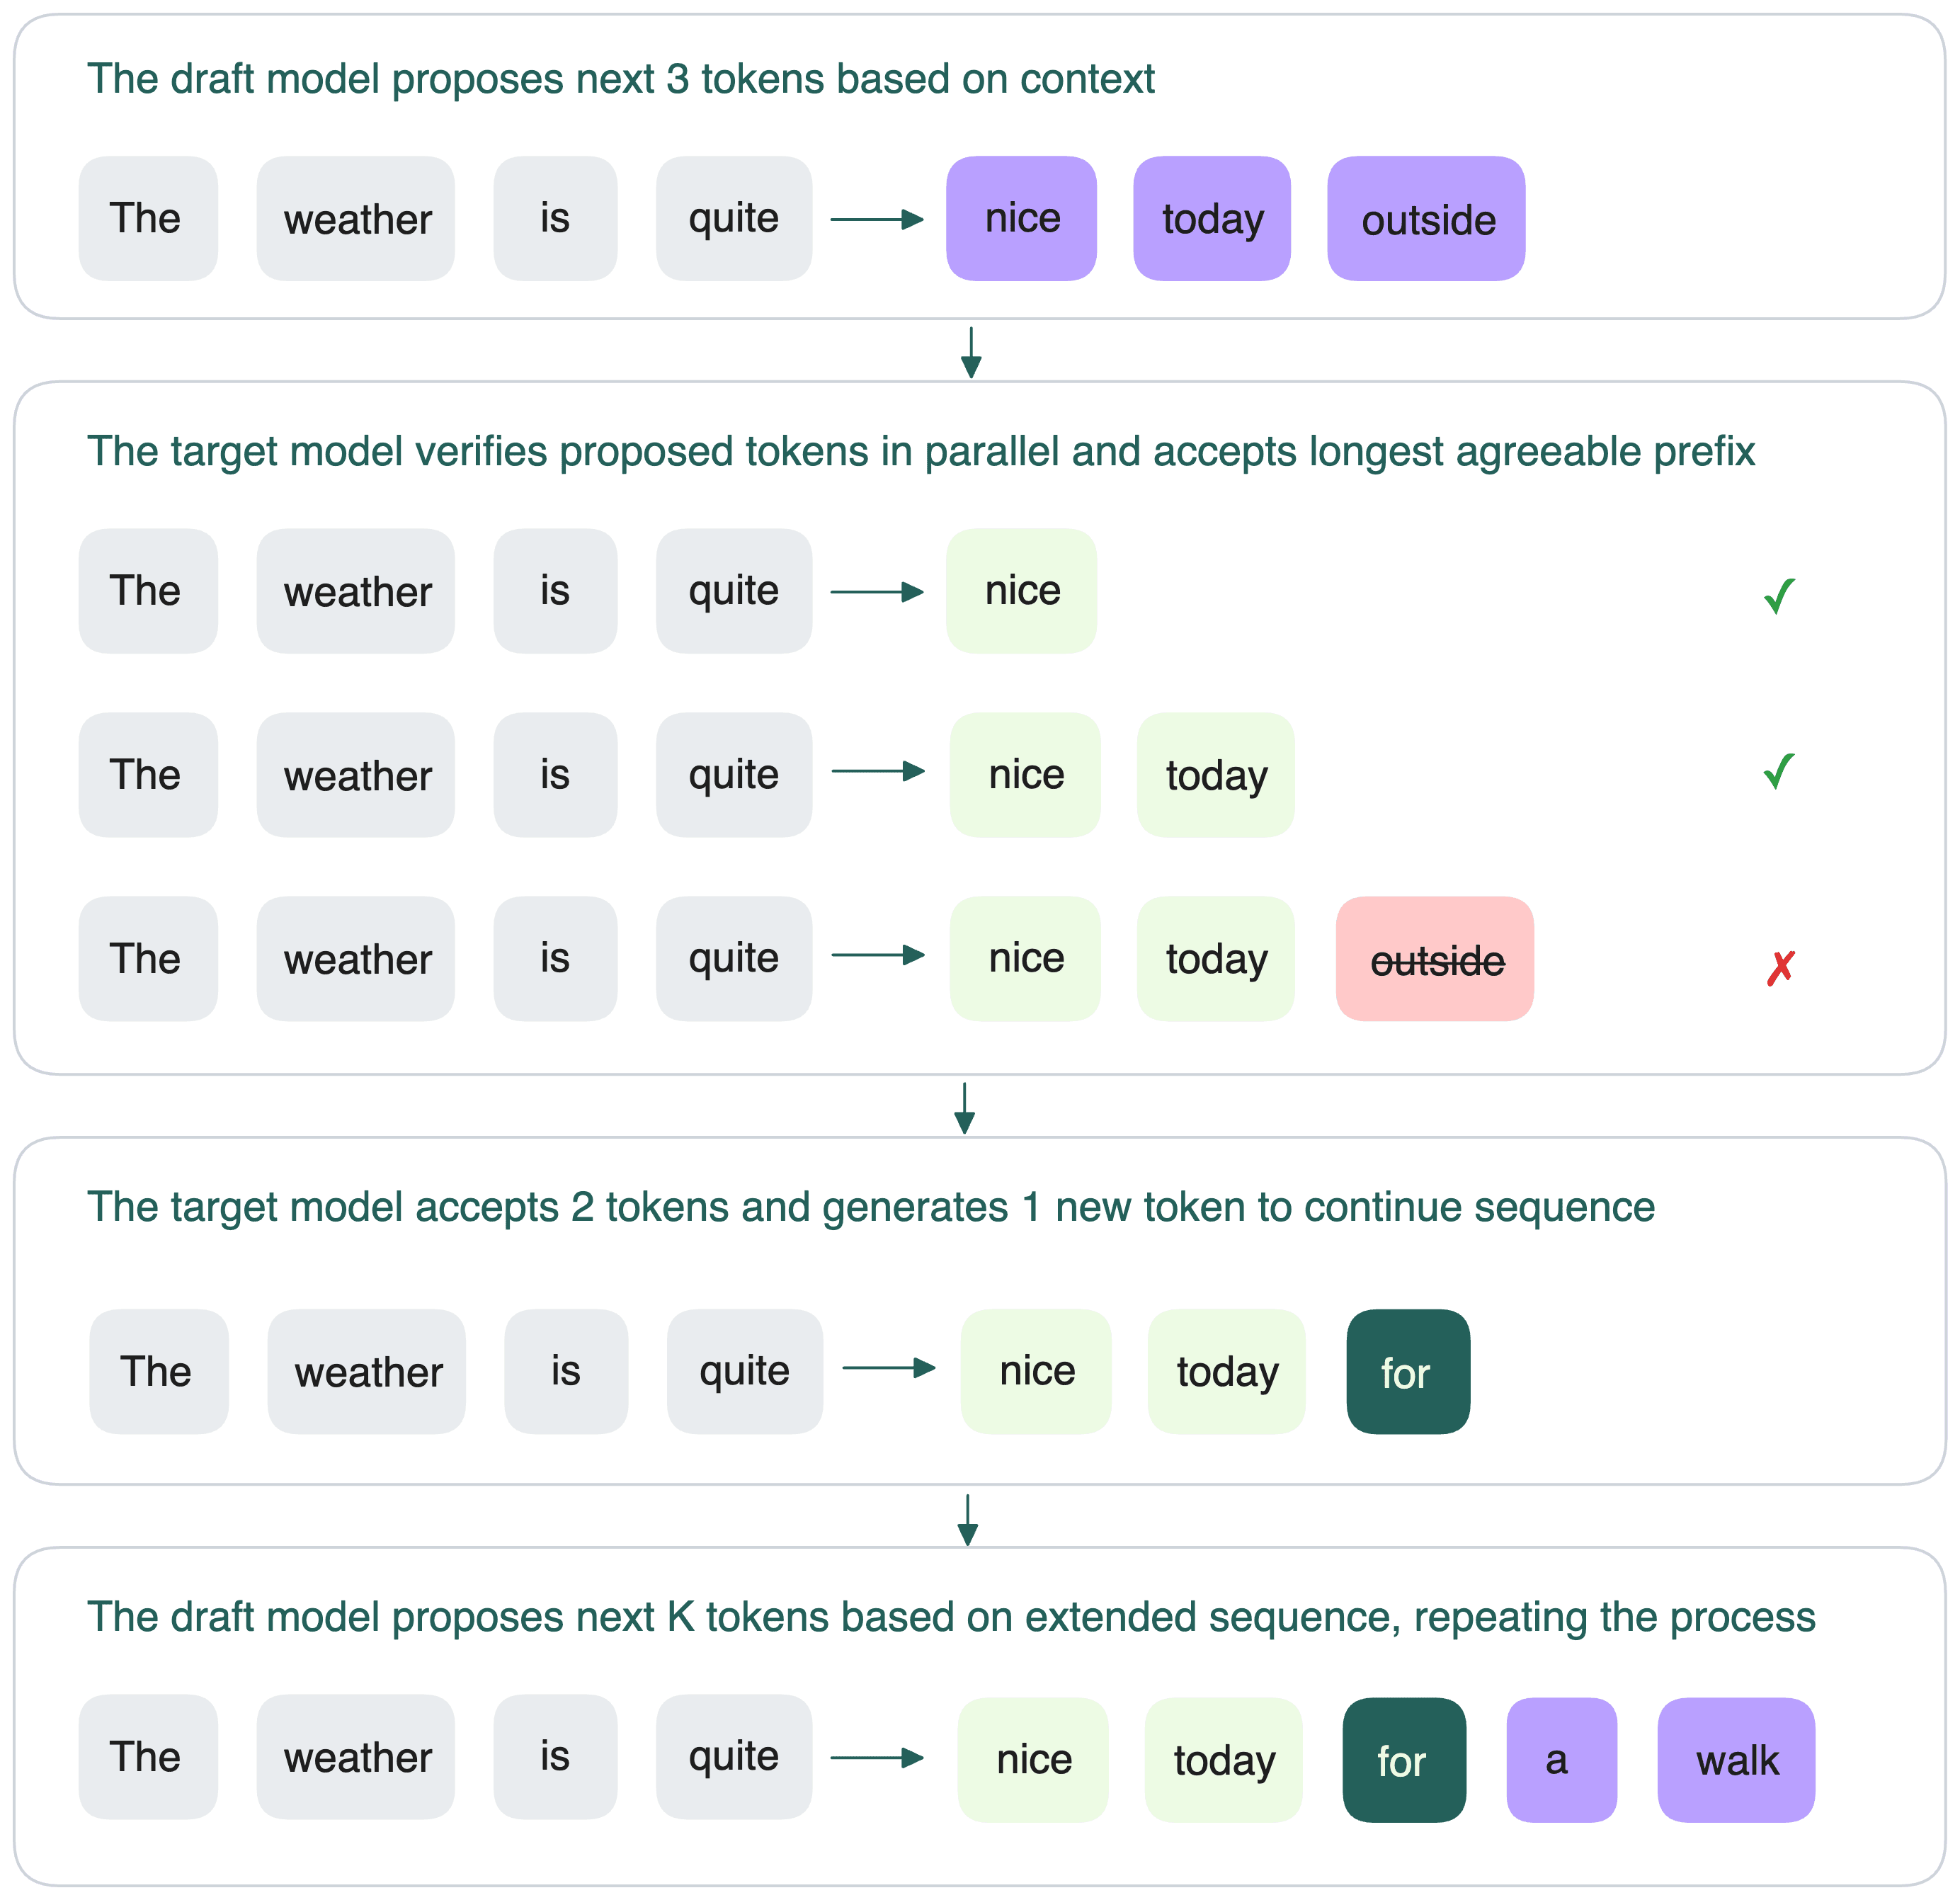
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...
Advertisement Space (336x280)

Speculative Decoding via Early-exiting for Faster LLM Inference with ...
P-EAGLE: Faster LLM inference with Parallel Speculative Decoding in ...

SpecInfer: Accelerating Generative LLM Serving with Speculative ...

SpecEE: Accelerating Large Language Model Inference with Speculative ...
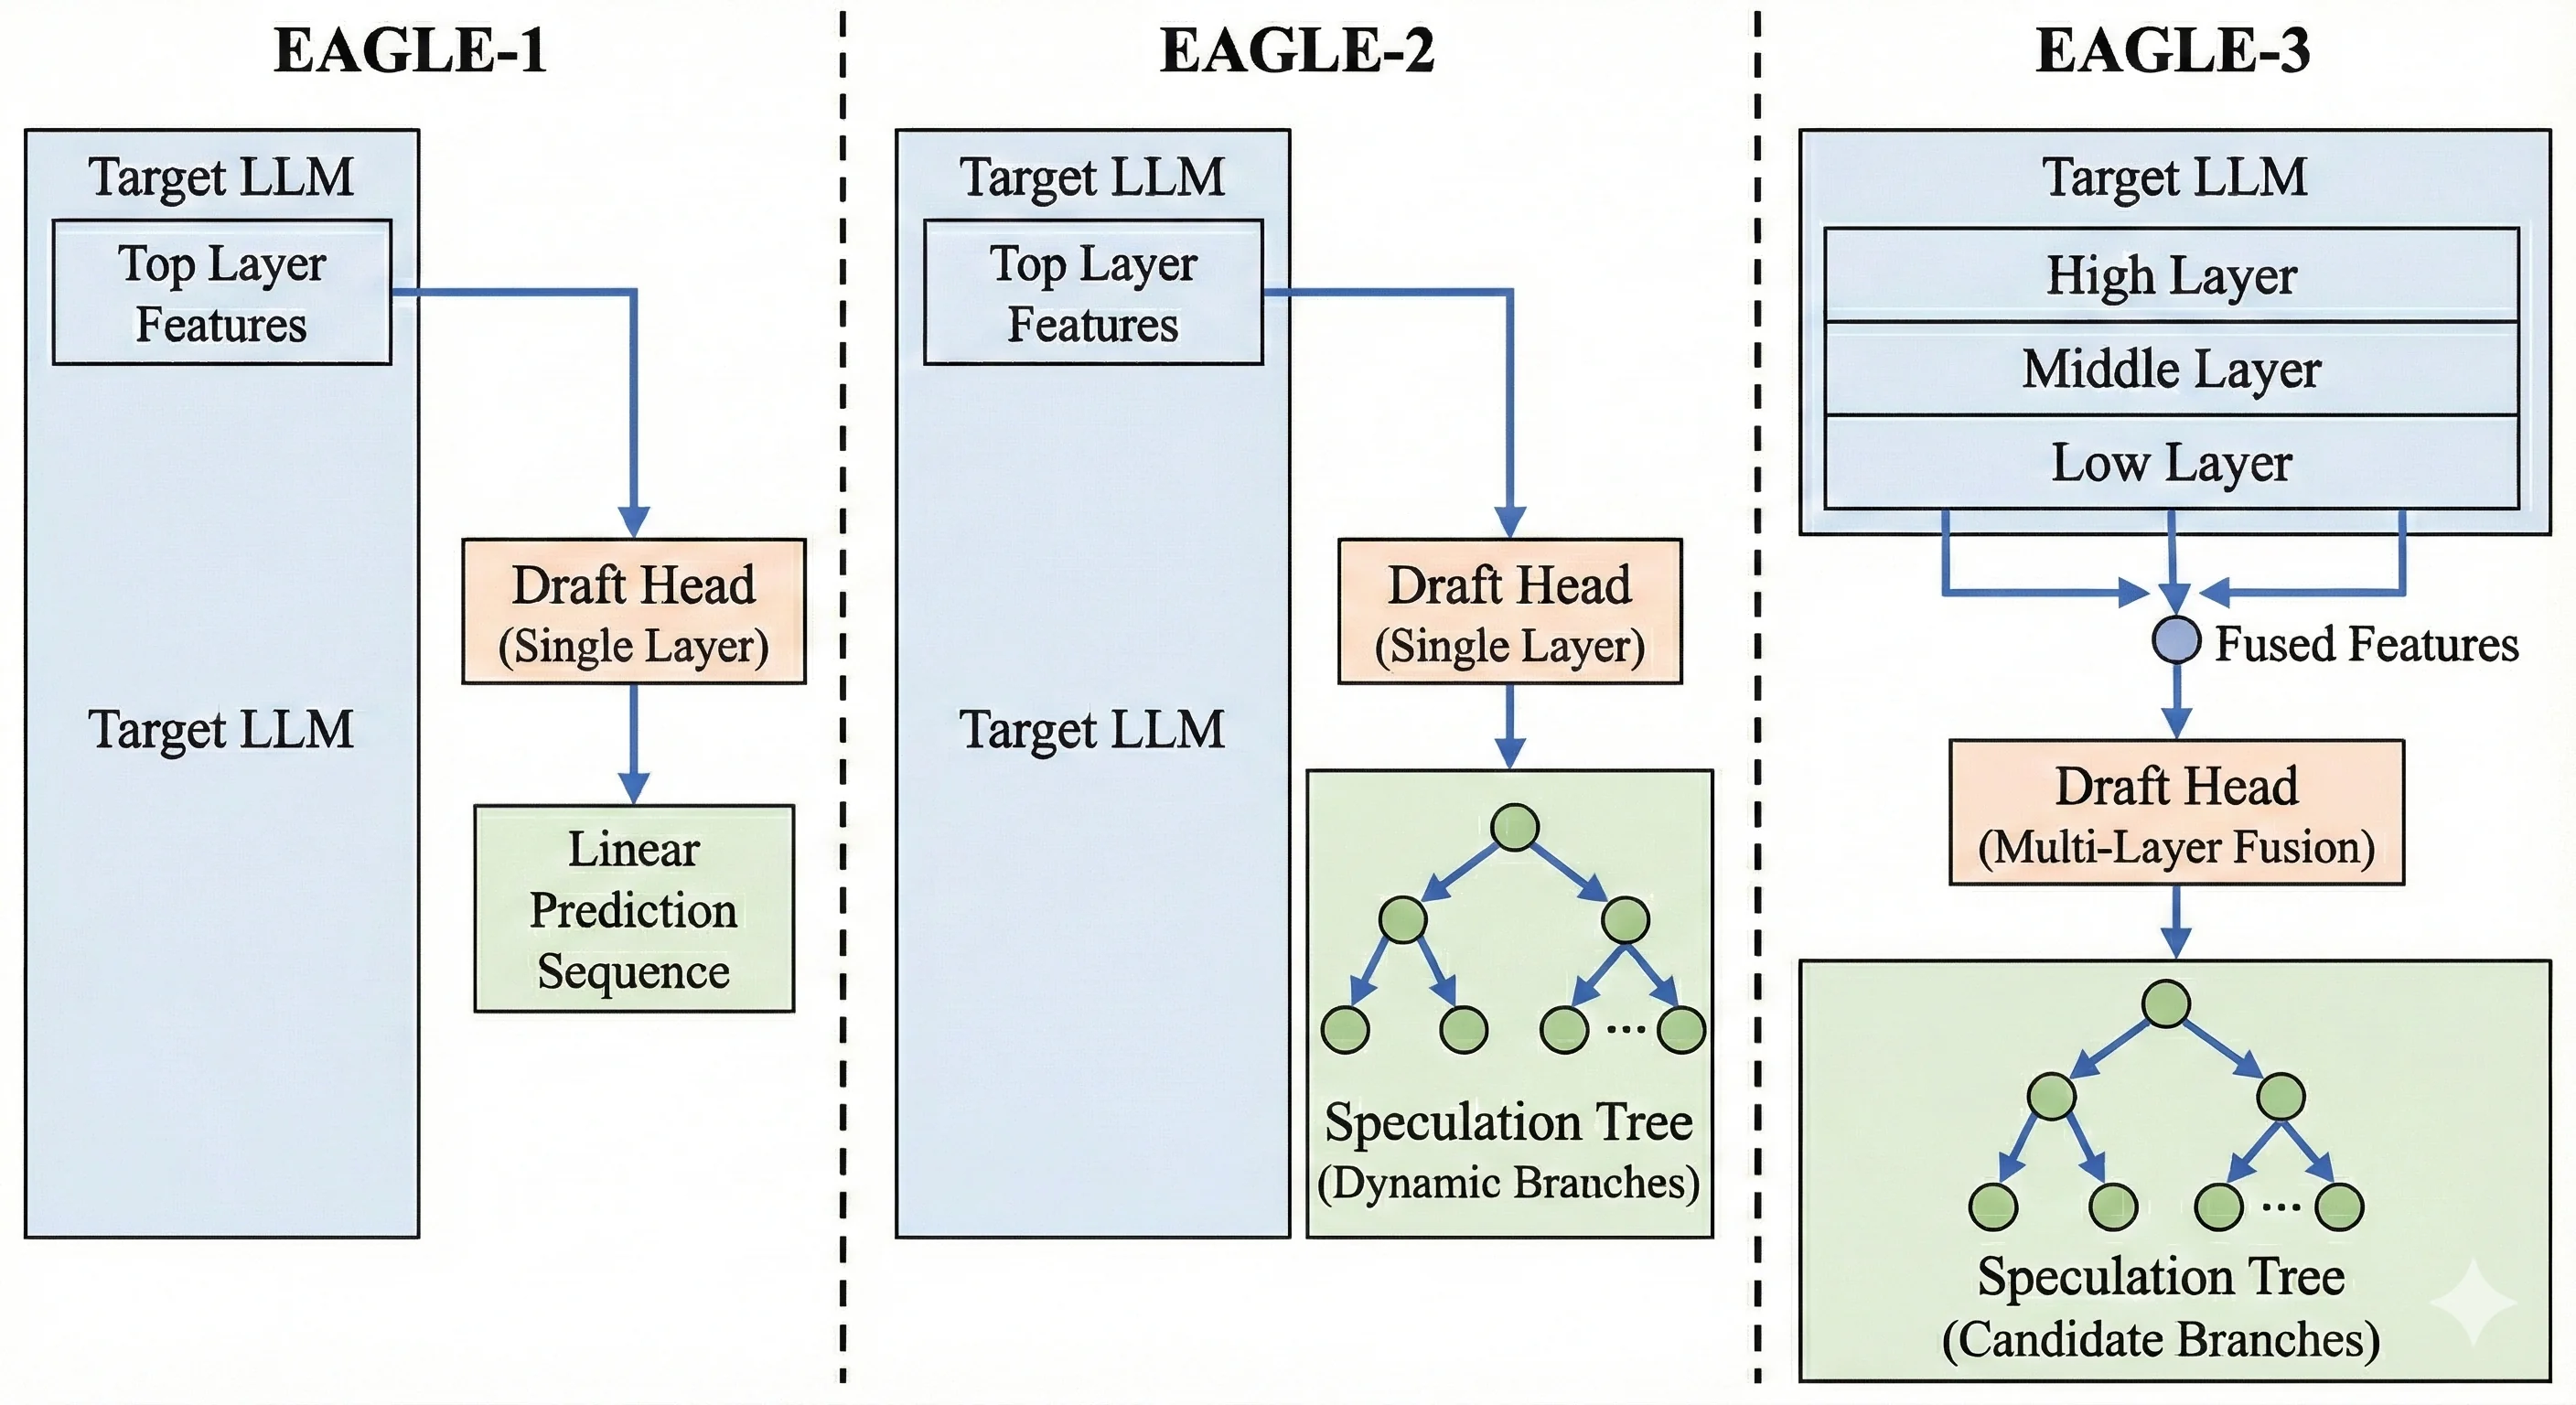
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
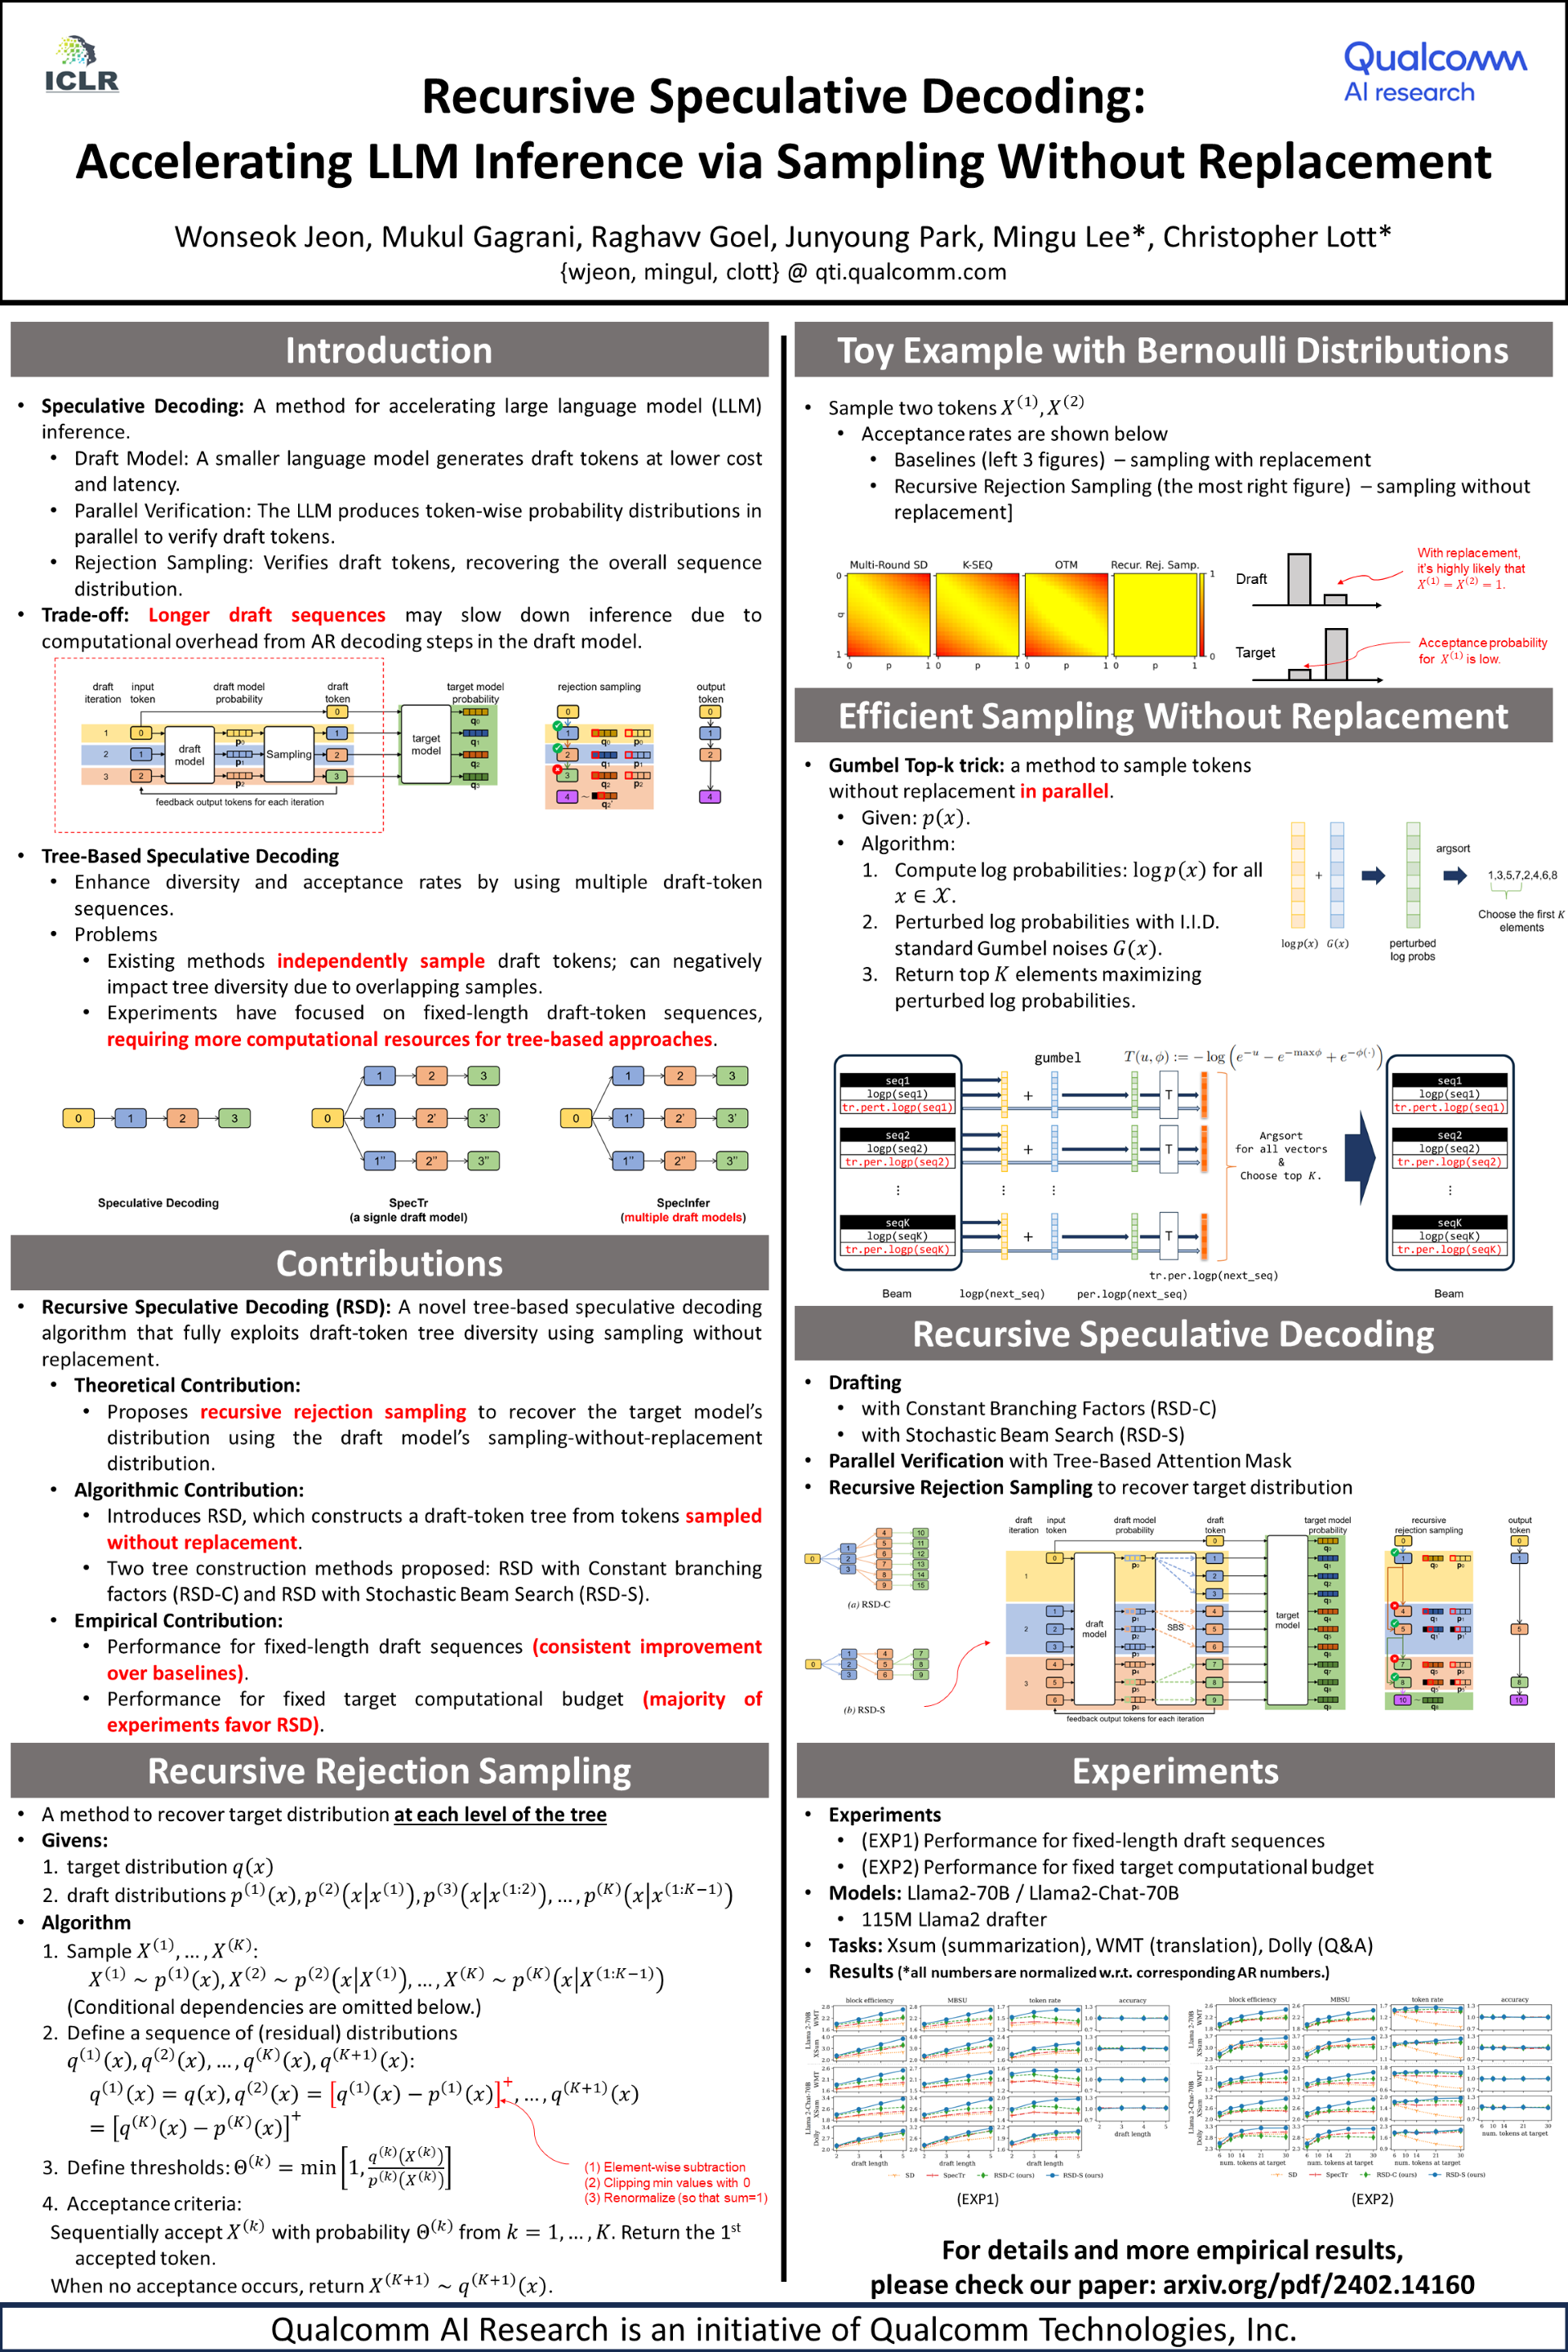
ICLR Recursive Speculative Decoding: Accelerating LLM Inference via ...

SpecInfer: Accelerating Generative LLM Serving with Speculative ...

Paper page - DART: Diffusion-Inspired Speculative Decoding for Fast LLM ...

[Literature Review] SpecFed: Accelerating Federated LLM Inference with ...
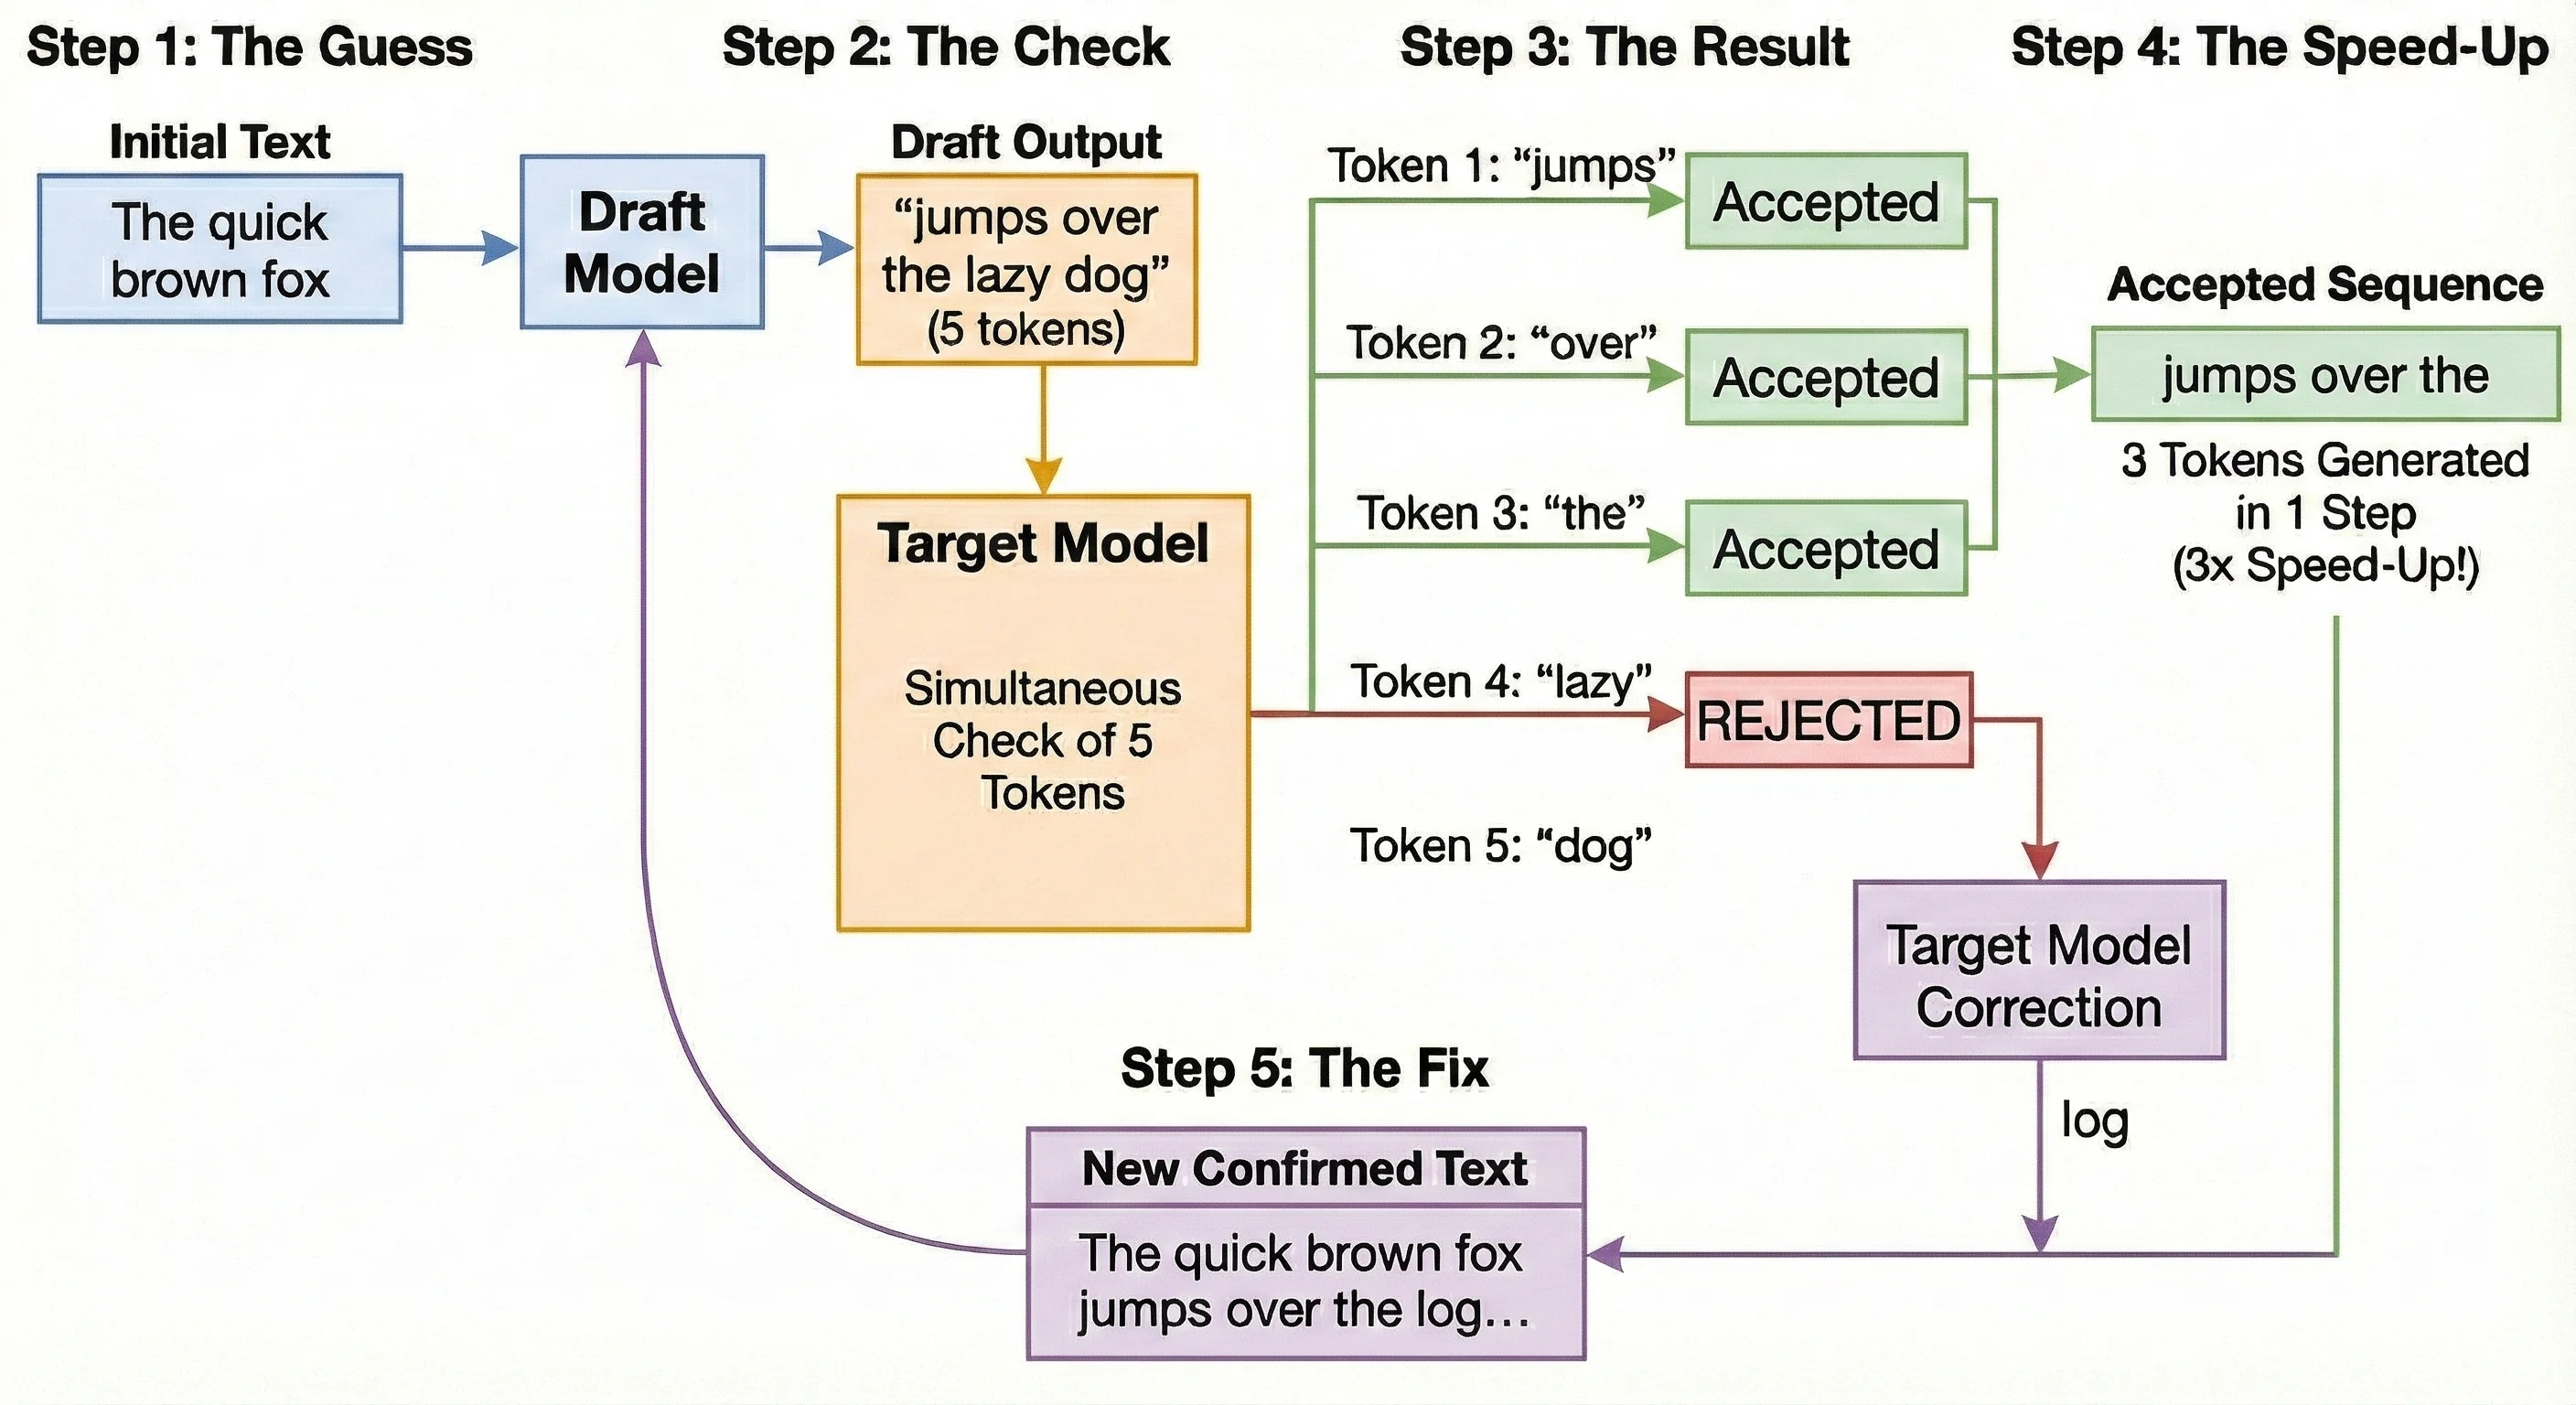
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
Advertisement Space (336x280)

Speculative Decoding: Accelerating LLM Inference Without Quality ...

Paper page - Medusa: Simple LLM Inference Acceleration Framework with ...

(PDF) SpecInfer: Accelerating Generative LLM Serving with Speculative ...

Paper page - SpecInfer: Accelerating Generative LLM Serving with ...

Boosting LLM Inference Speed Using Speculative Decoding | Towards Data ...

Speculative Decoding: Accelerating LLM Inference Without Quality ...