
Adversarial Preference Learning For Robust Llm Alignment Acl Anthology

Adversarial Preference Learning for Robust LLM Alignment - ACL Anthology

(PDF) Adversarial Preference Learning for Robust LLM Alignment

Learning to Paraphrase for Alignment with LLM Preference - ACL Anthology
Adversarial Preference Learning for Robust LLM Alignment | AI Research ...

A Grounded Preference Model for LLM Alignment - ACL Anthology

Instantly Learning Preference Alignment via In-context DPO - ACL Anthology
LIRE: listwise reward enhancement for preference alignment - ACL Anthology

Deep Reinforcement Learning for Entity Alignment - ACL Anthology

UniAPL: A Unified Adversarial Preference Learning Framework for ...

Active Learning for Robust and Representative LLM Generation in Safety ...
Advertisement Space (300x250)

CURATRON: Complete and Robust Preference Data for Rigorous Alignment of ...

Robust Encodings: A Framework for Combating Adversarial Typos - ACL ...
Reinforcement Learning with Supervised Alignment - ACL Anthology
A Reinforcement Learning Framework for Robust and Secure LLM ...

Robust Semantic Parsing with Adversarial Learning for Domain ...
Preference-Aware Memory Update for Long-Term LLM Agents - ACL Anthology

LLM Alignment for the Arabs: A Homogenous Culture or Diverse Ones - ACL ...

GAN-BERT: Generative Adversarial Learning for Robust Text ...

Learning Robust Representations of Text - ACL Anthology
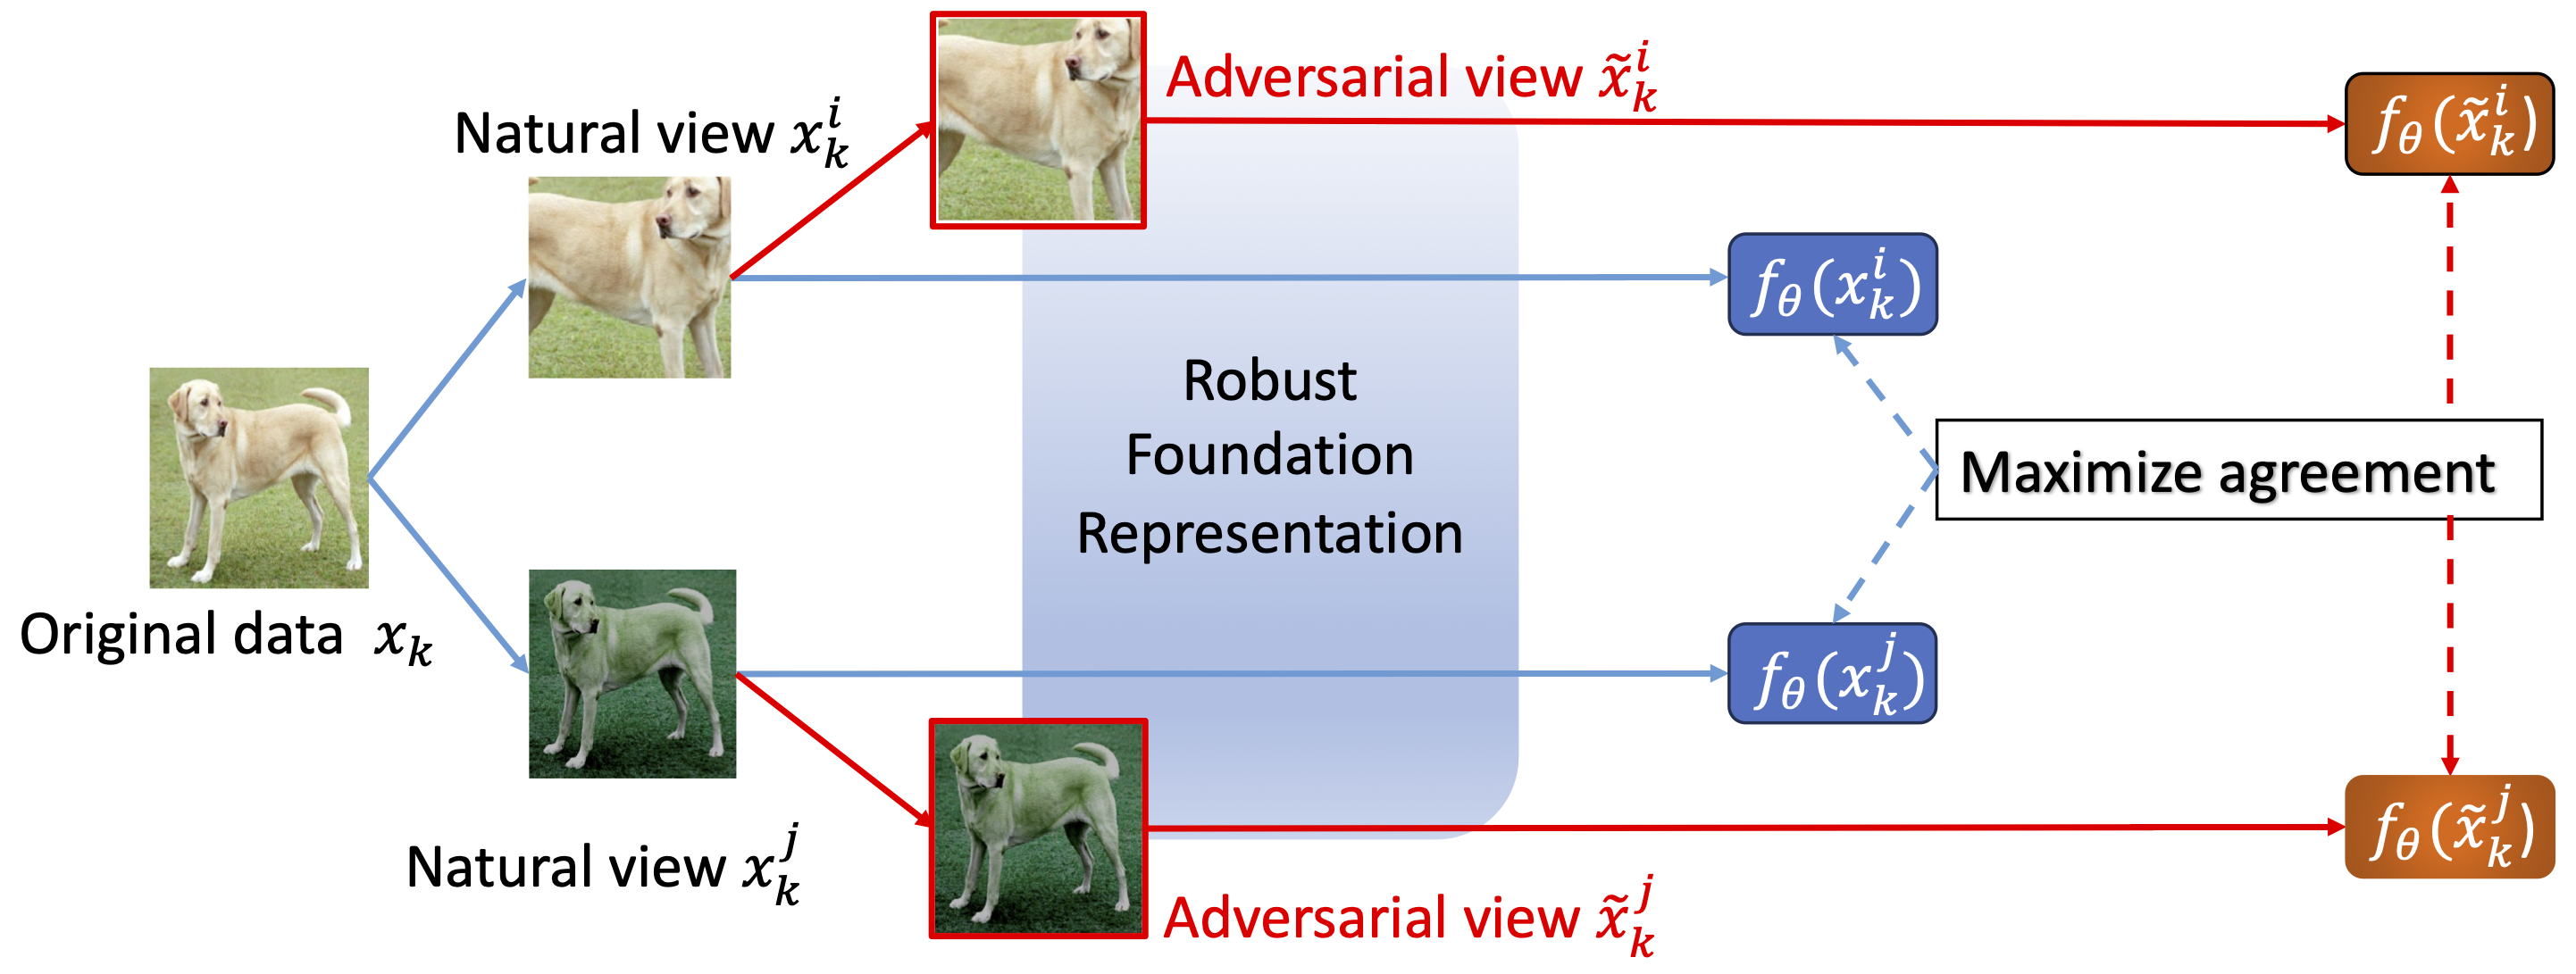
Towards Robust Foundation Models: Adversarial Contrastive Learning ...
Advertisement Space (336x280)

Knowledgeable Preference Alignment for LLMs in Domain-specific Question ...

Adversarial Preference Optimization: Enhancing Your Alignment via RM ...

Re-evaluating Automatic LLM System Ranking for Alignment with Human ...
Investigating Adversarial Robustness in LLM-based AES - ACL Anthology

Learning Robust Representations for Continual Relation Extraction via ...
CA-GAR: Context-Aware Alignment of LLM Generation for Document ...

Comparison-based Active Preference Learning for Multi-dimensional ...

Attention-Focused Adversarial Training for Robust Temporal Reasoning ...

Improving Preference Alignment of LLM with Inference-Free Self ...
APLOT: Robust Reward Modeling via Adaptive Preference Learning with ...
Advertisement Space (336x280)

Multi-perspective Preference Alignment of LLMs for Programming ...

On Committee Representations of Adversarial Learning Models for ...
Can You Trick the Grader? Adversarial Persuasion of LLM Judges - ACL ...

RPO: Retrieval Preference Optimization for Robust Retrieval-Augmented ...

Adversarial Tokenization - ACL Anthology

Personalized LLM Decoding via Contrasting Personal Preference - ACL ...