
Ai Inference Systems Optimize For Real Time With Speculative Decoding
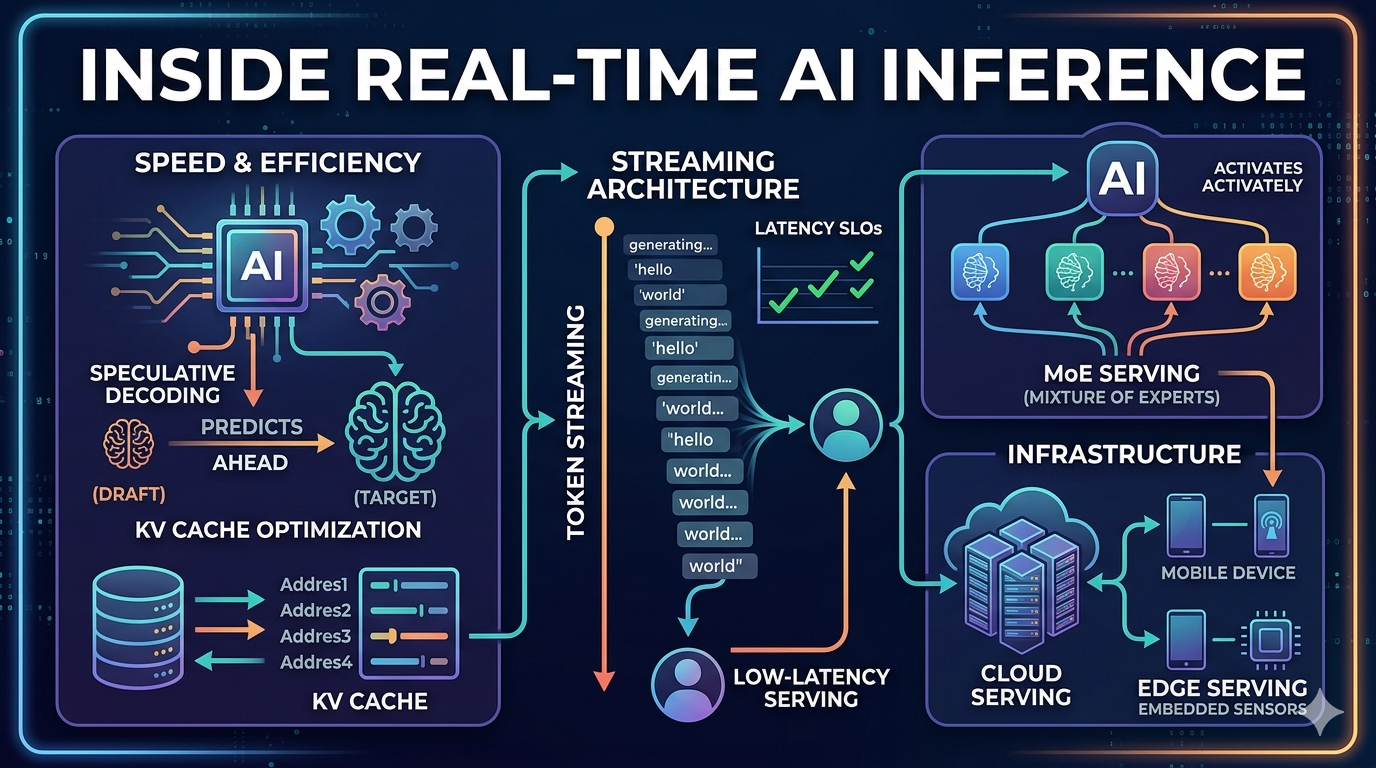
AI Inference Systems Optimize for Real-Time with Speculative Decoding ...
Best AI Inference Analytics with Real Time Insights for B2B
How to Optimize Confidential AI for Real-Time Inference | Inference Systems
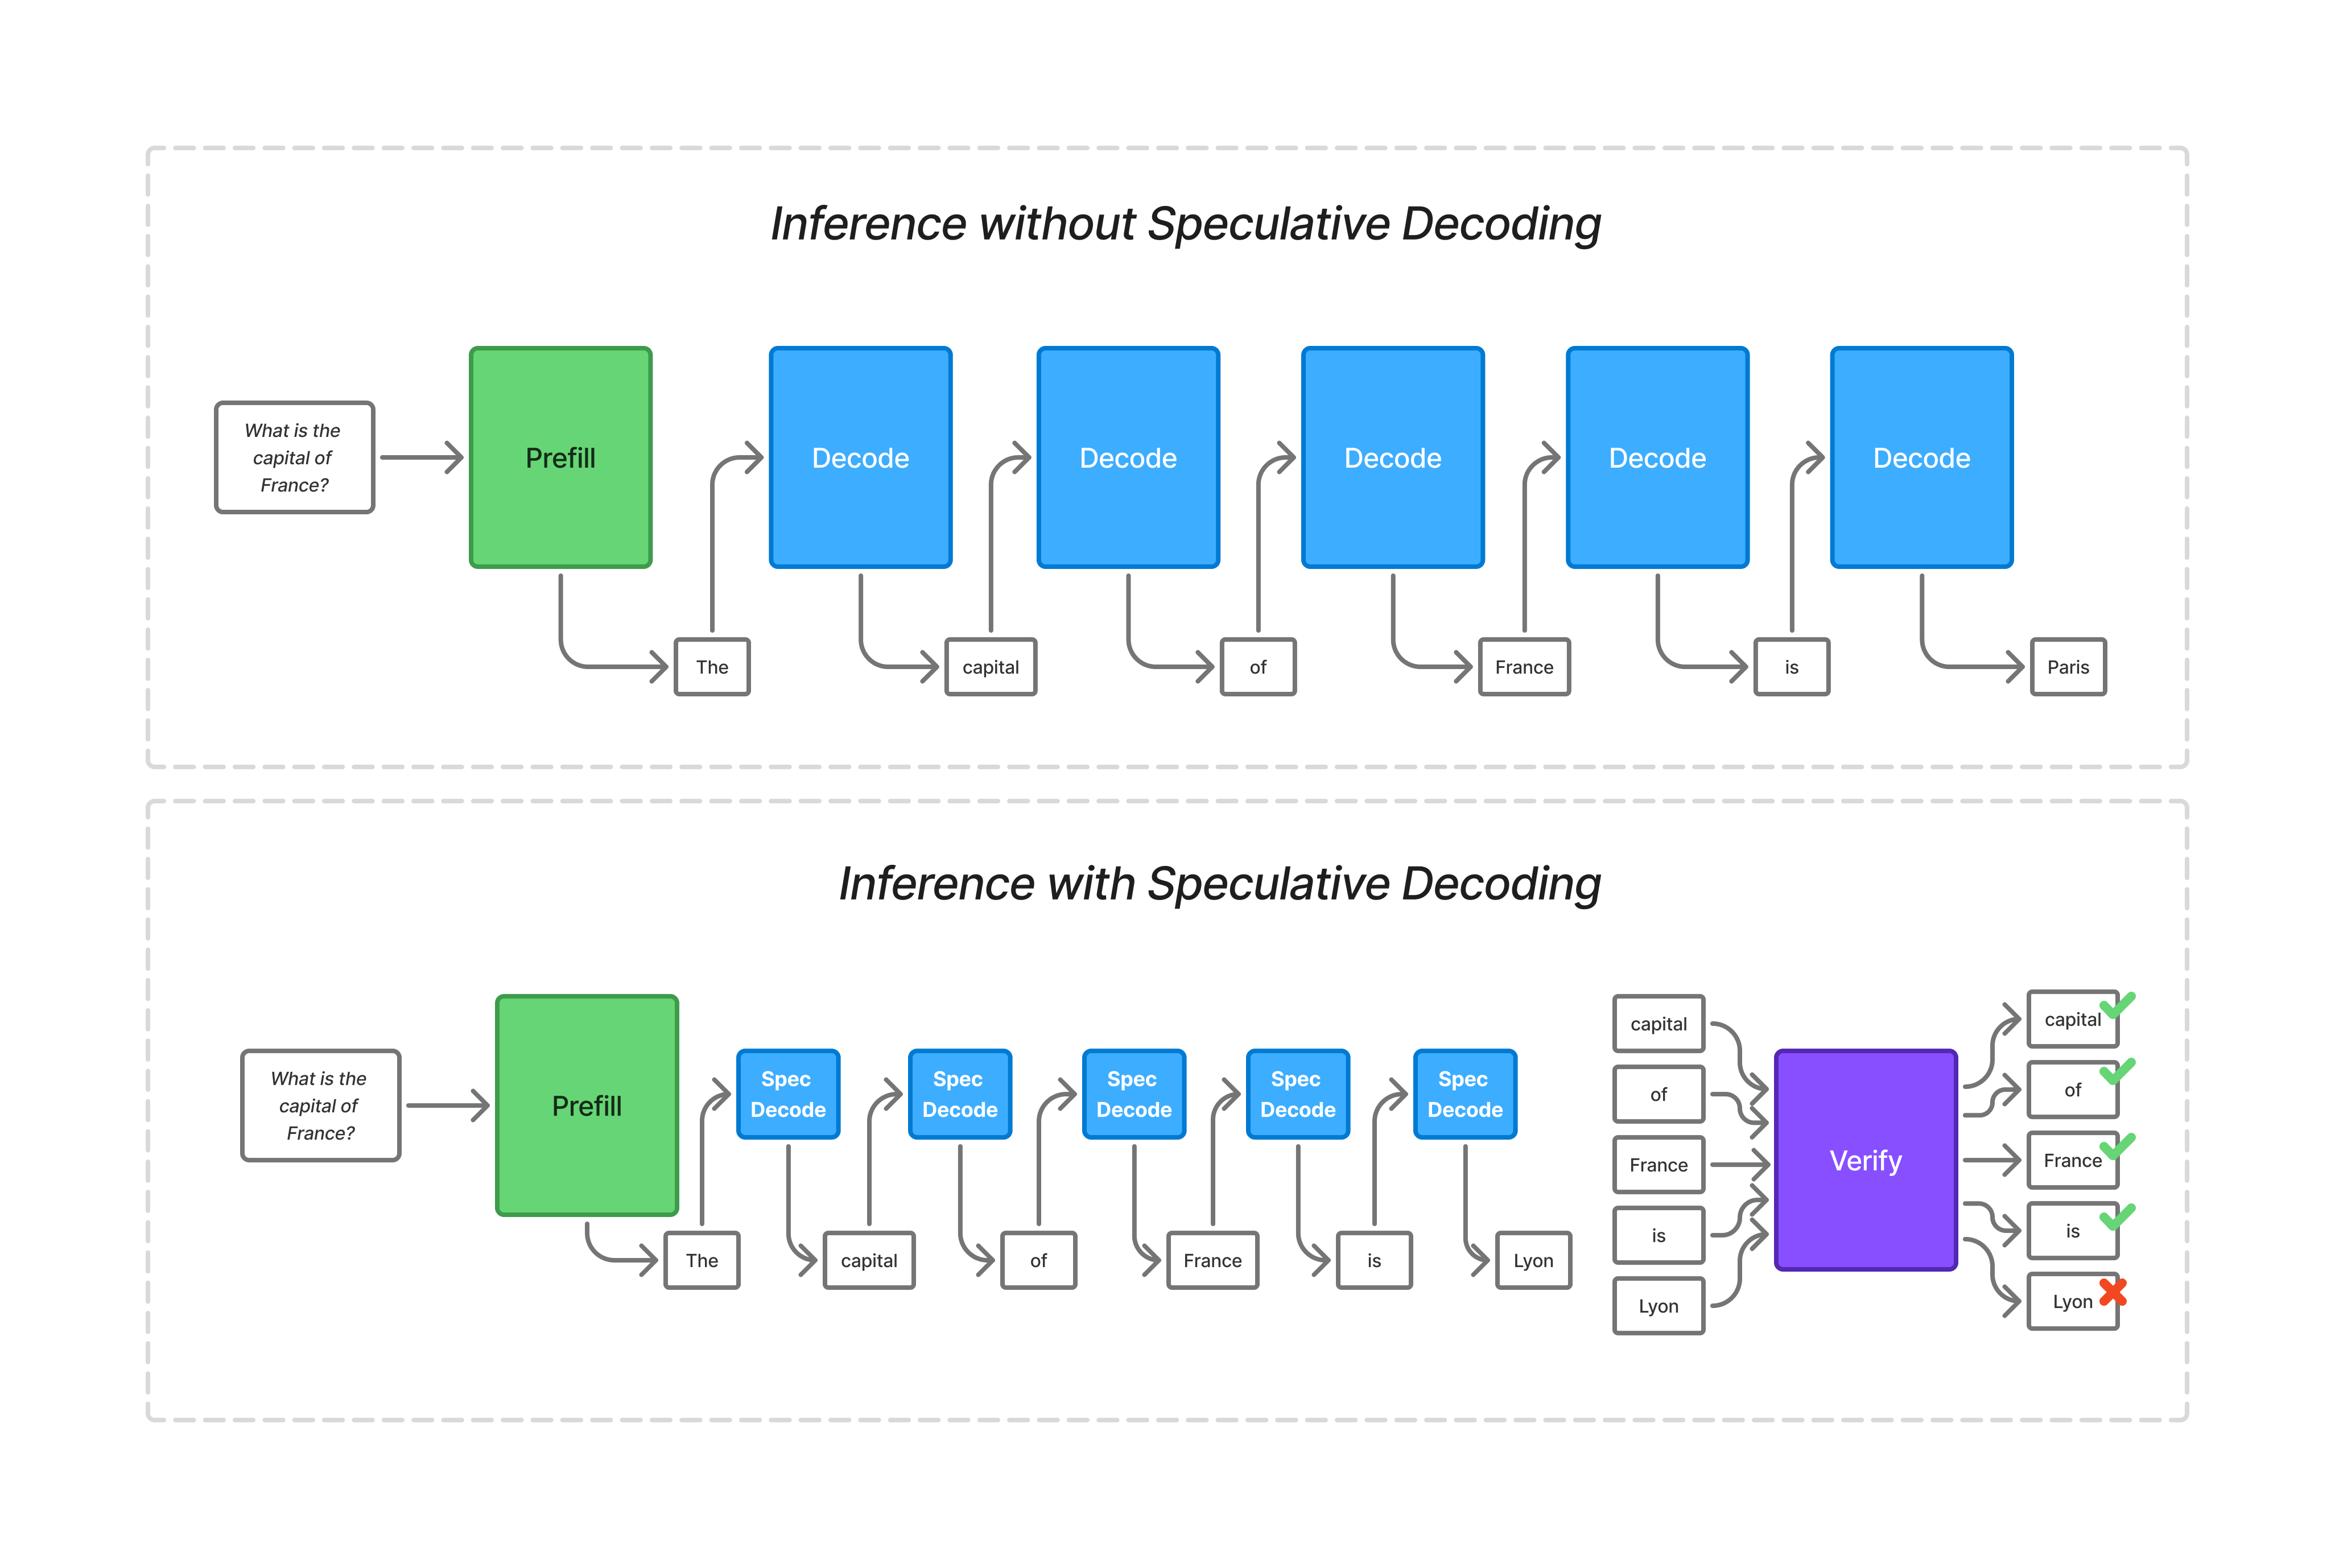
Low-Latency Inference with Speculative Decoding on d-Matrix Corsair and ...
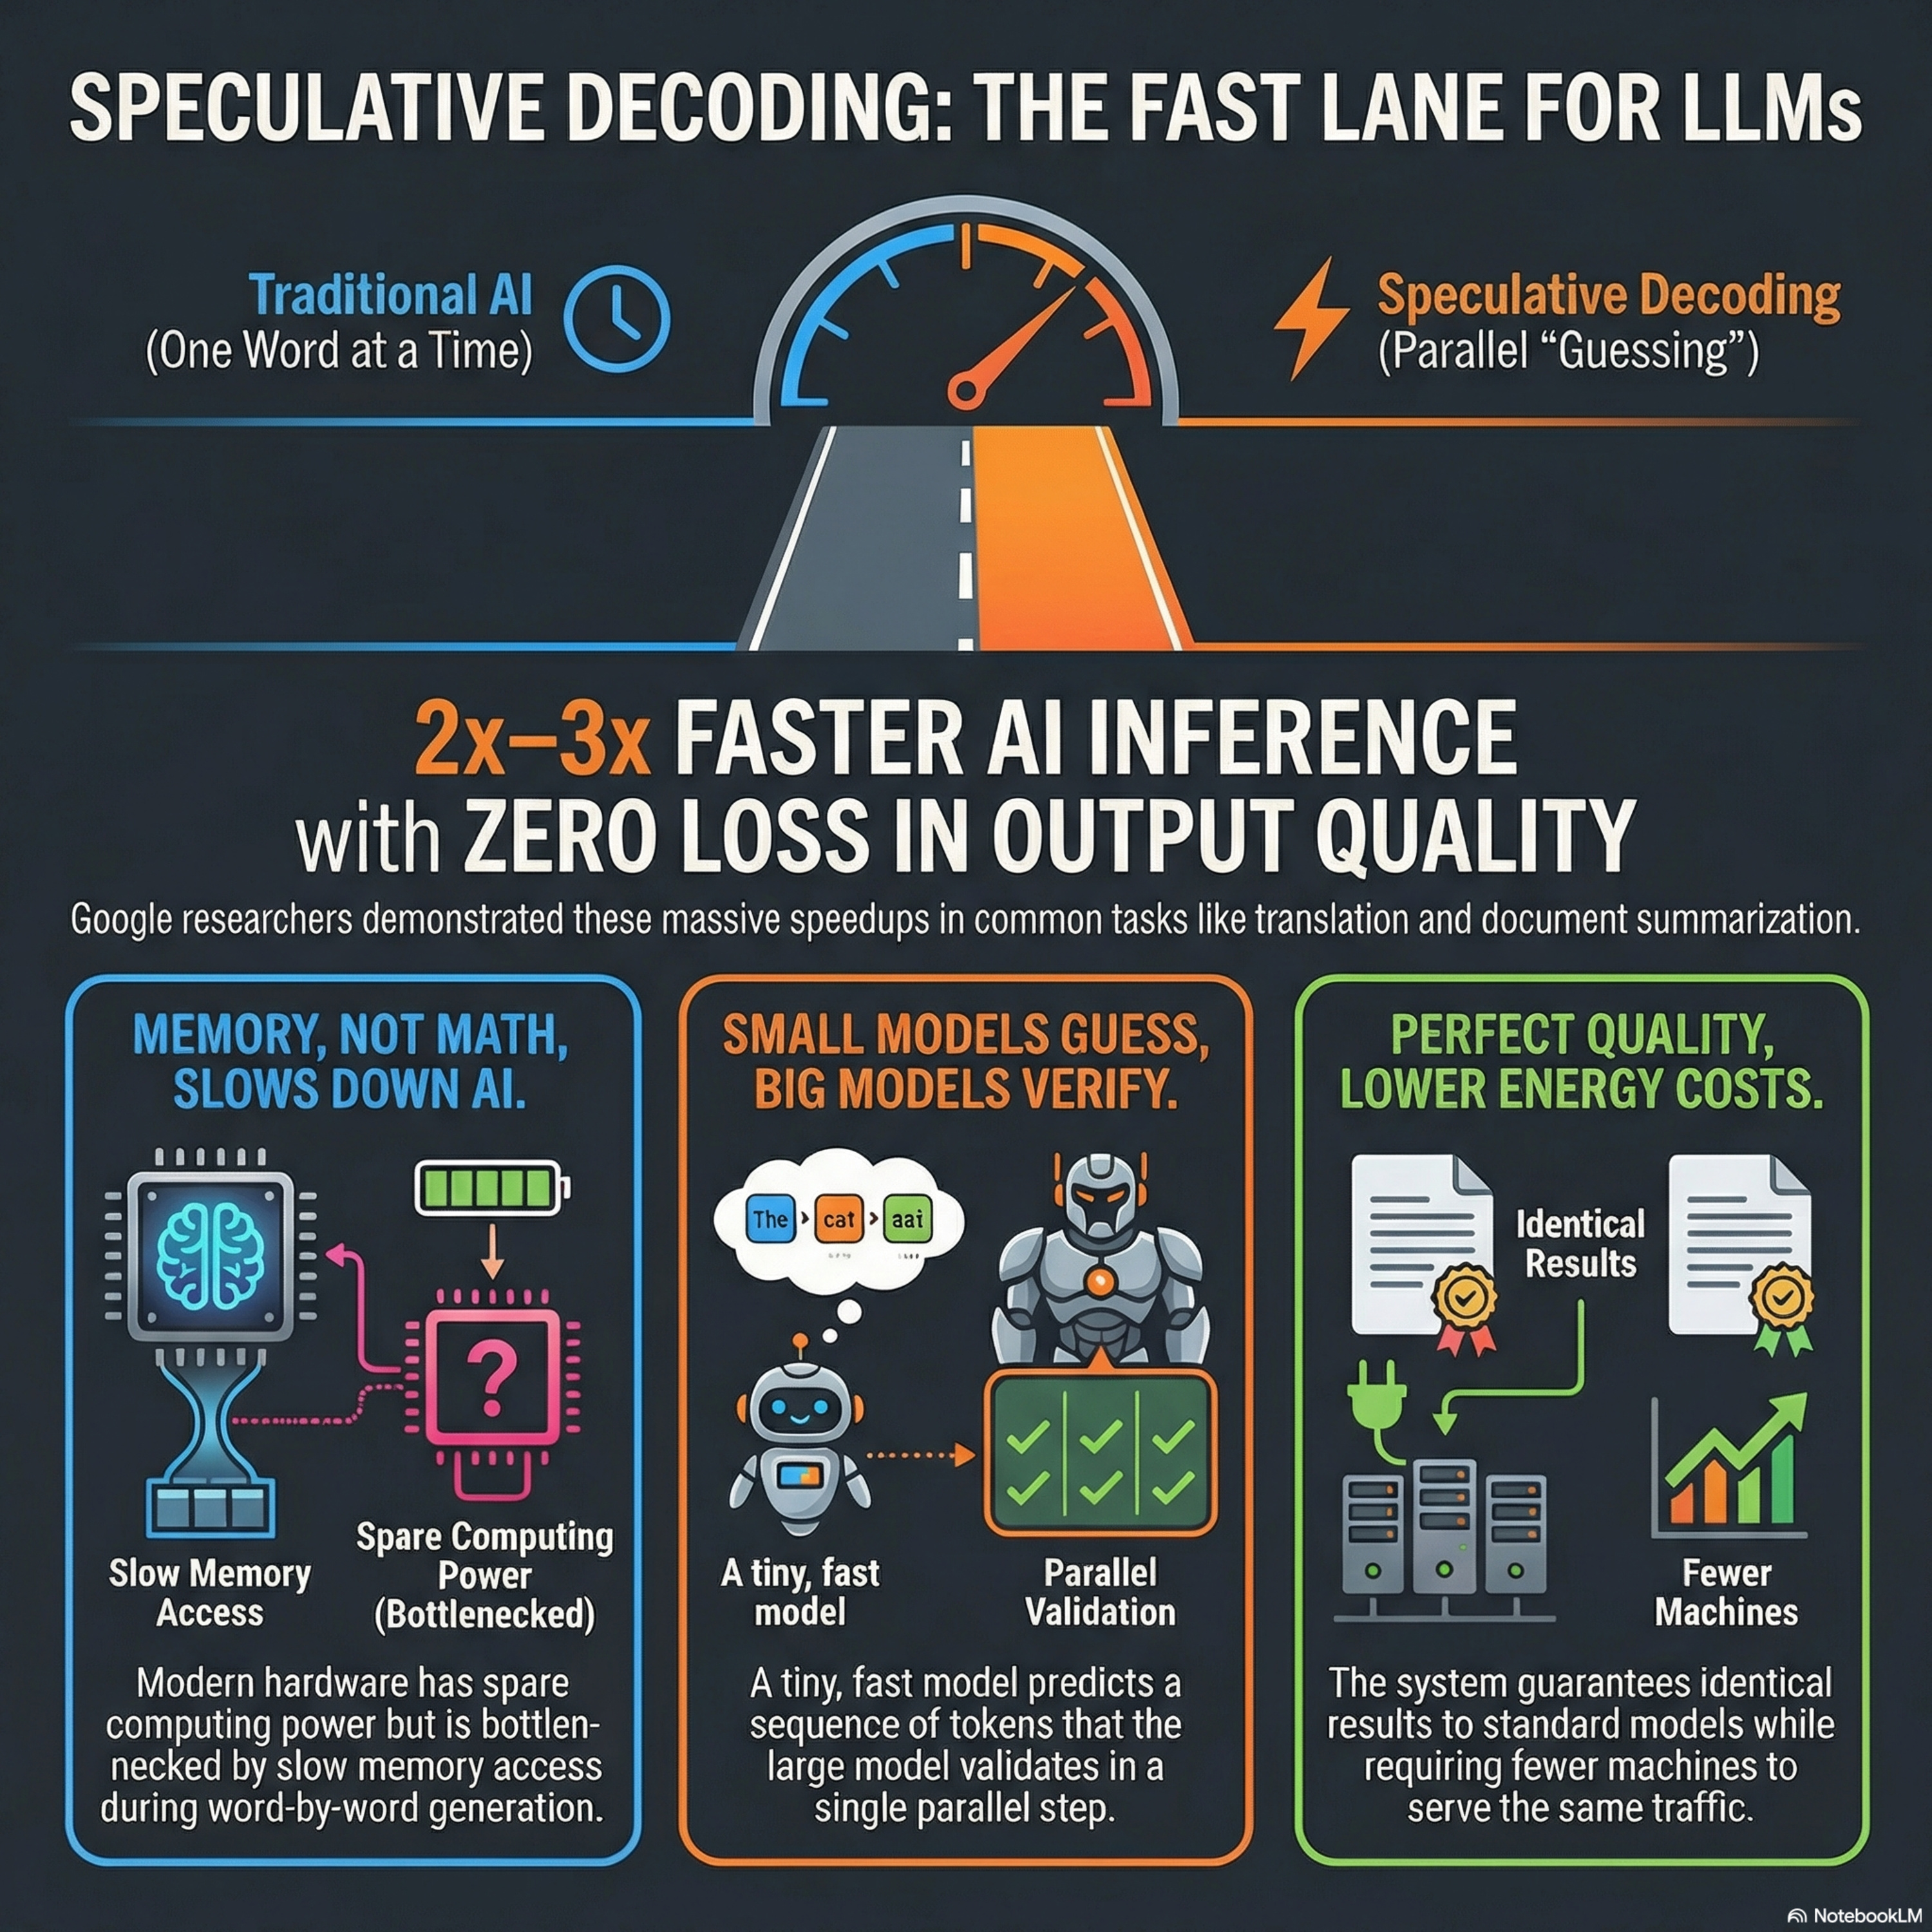
Fast Inference from Transformers via Speculative Decoding — AI Post ...
Speculative Decoding: AI Inference Speedup Technique | Inference Systems

Boosting AI Speed with Speculative Decoding
Edge AI Inference Optimization Reduces Latency for Real-Time Systems ...

Real-Time Model Inference with Apache Kafka and Flink for Predictive AI ...

This AI Paper Unveils the Potential of Speculative Decoding for Faster ...
Advertisement Space (300x250)

Boosting AI Speed with Speculative Decoding
How speculative decoding supercharged AI inference in disaggregated ...
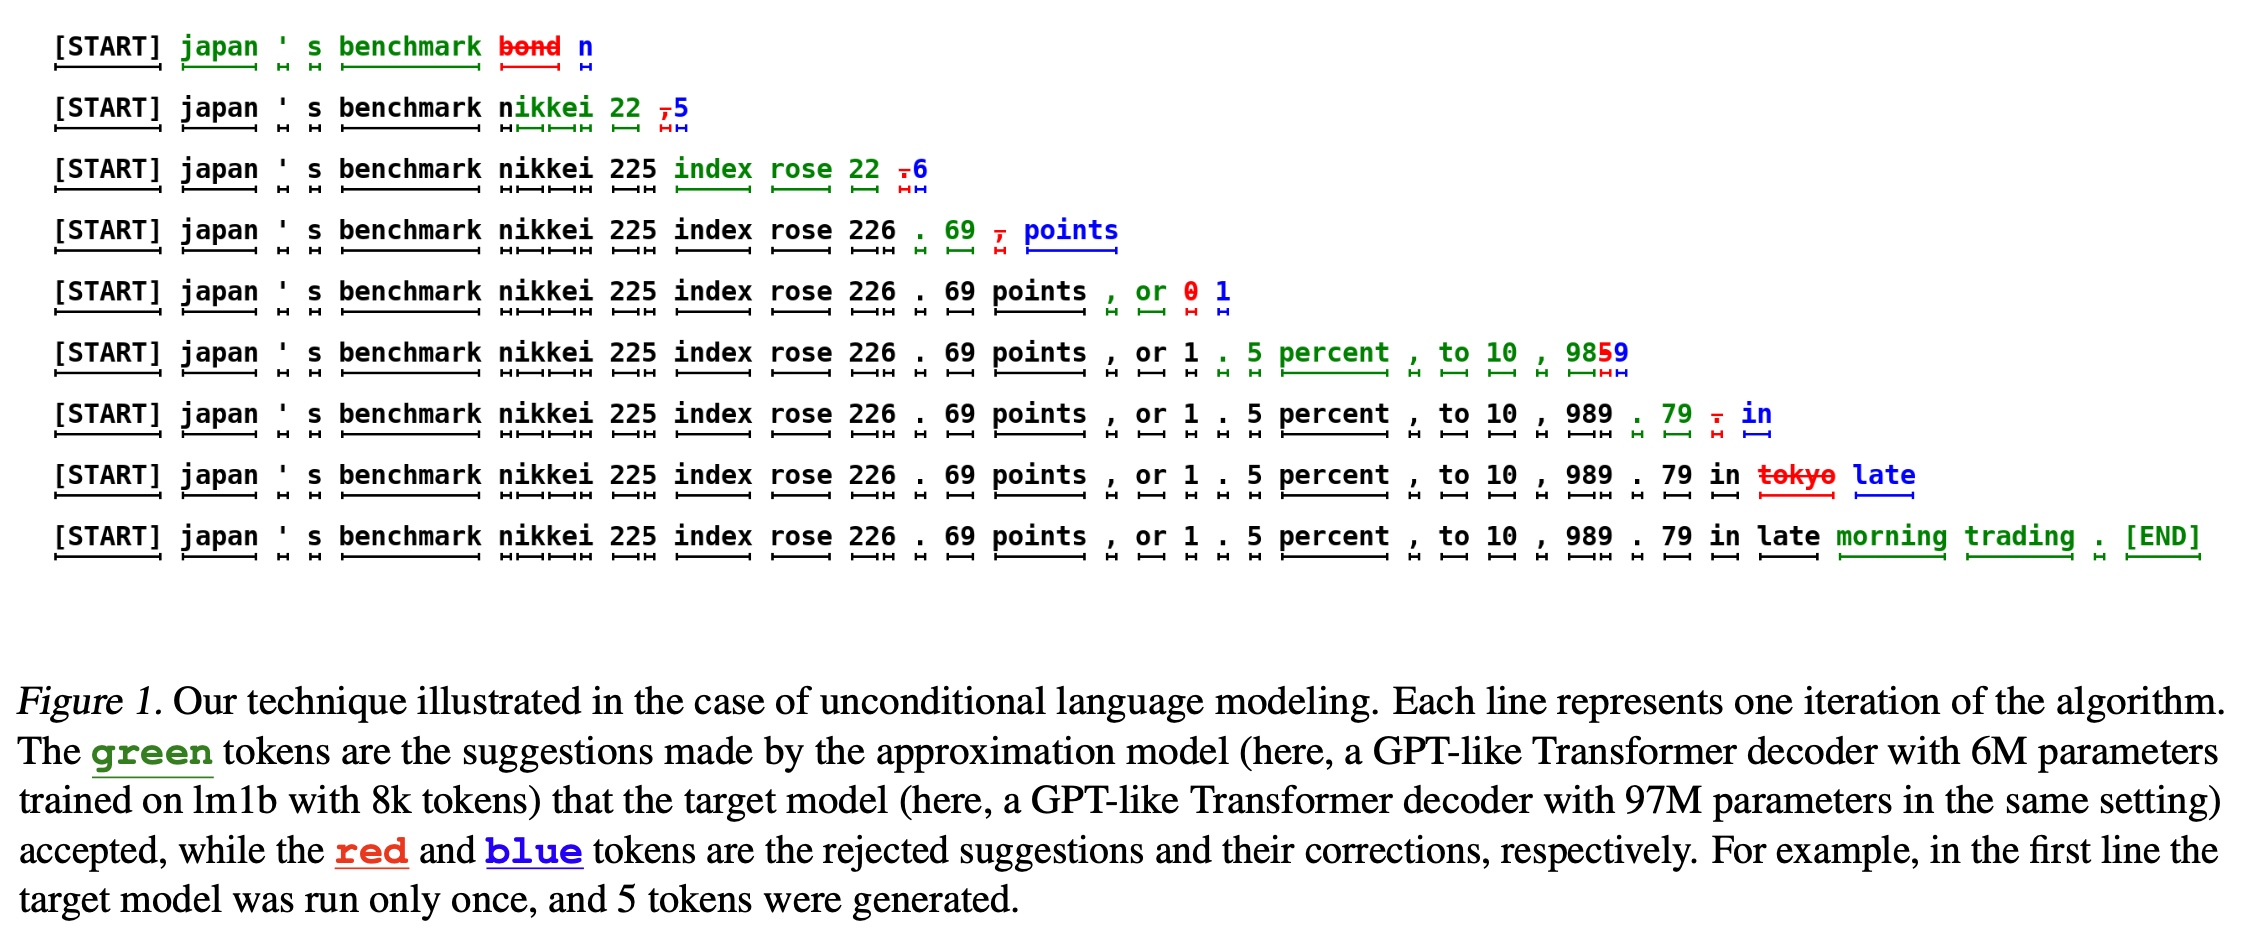
Accelerate LLM Inference with Speculative Decoding | Charles Xu

How to Optimize Inference Endpoints for Real-Time AI - YouTube
AI Integration for AI-Driven Space Optimization | Inference Systems

An Introduction to Speculative Decoding for Reducing Latency in AI ...

An Introduction to Speculative Decoding for Reducing Latency in AI ...
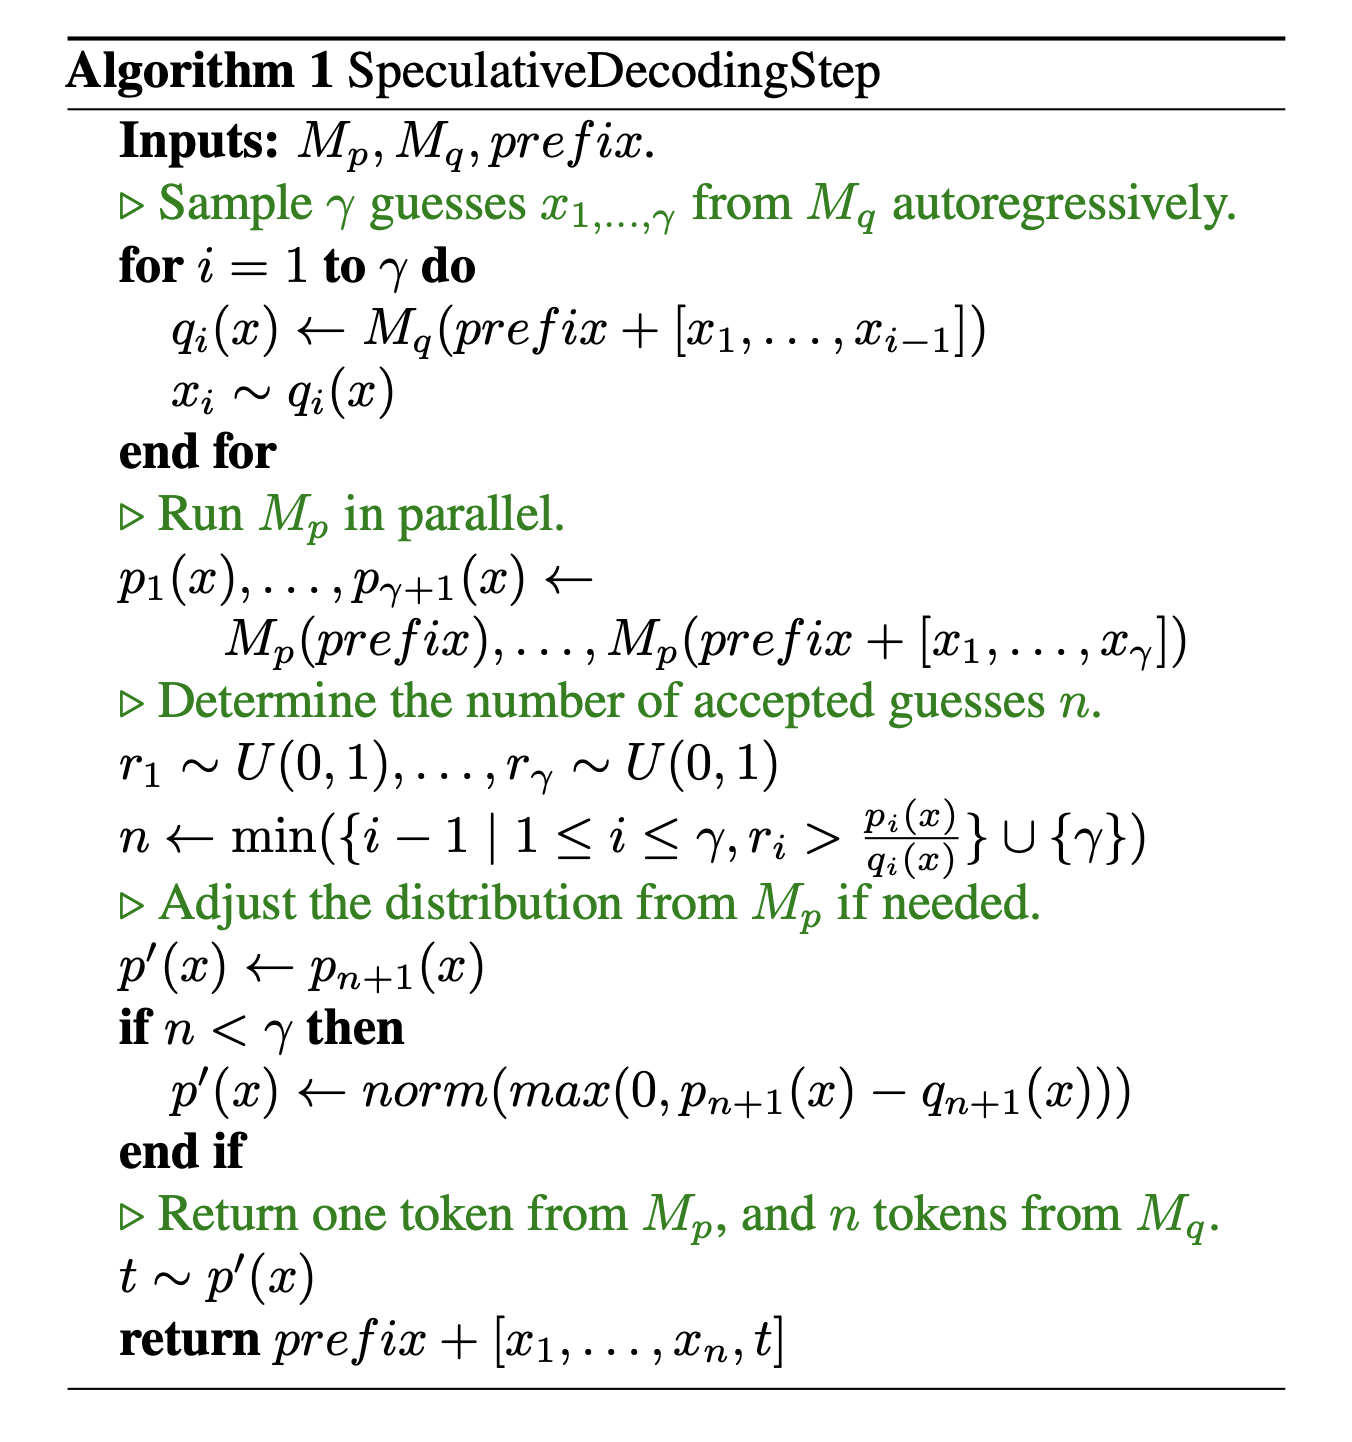
Accelerating large model inference with speculative decoding - 6.s898 ...

An Introduction to Speculative Decoding for Reducing Latency in AI ...

How to Optimize AI Agent Systems for Inference, Memory, and Tool-Call ...
Advertisement Space (336x280)
Speculative Decoding Explained: Faster Inference Without Quality Loss
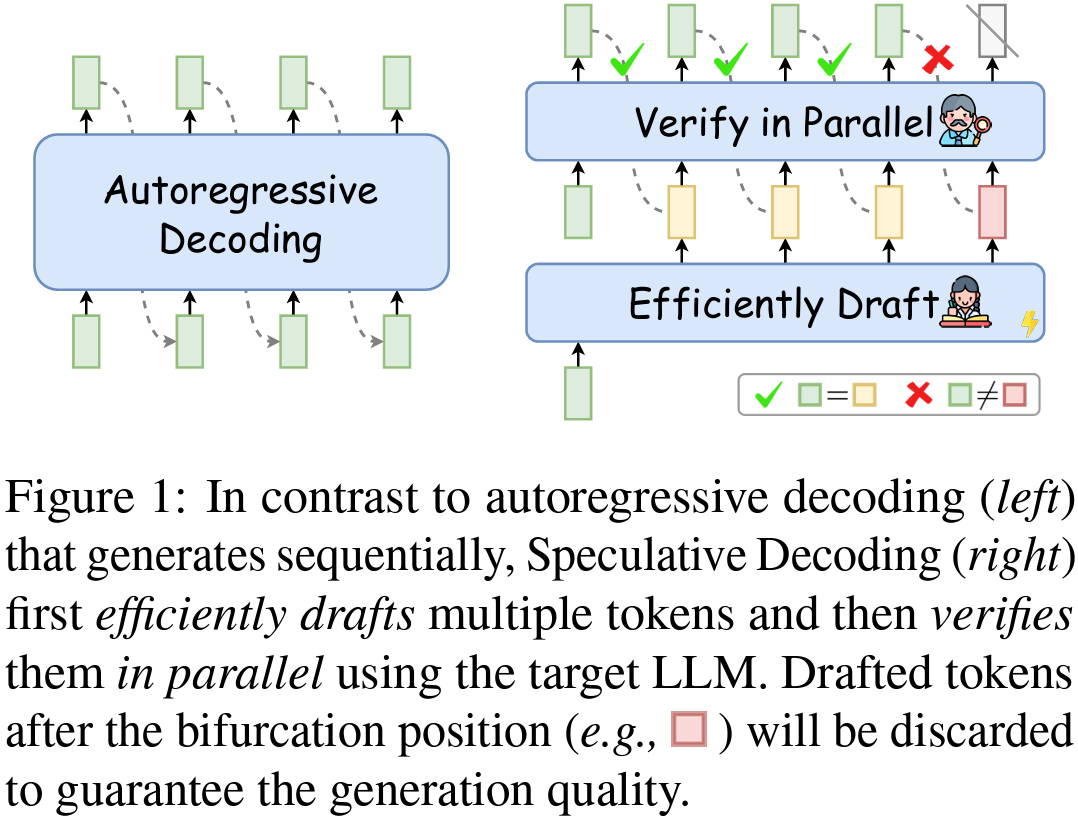
Speculative decoding — papers and benchmarks | Papers with Code
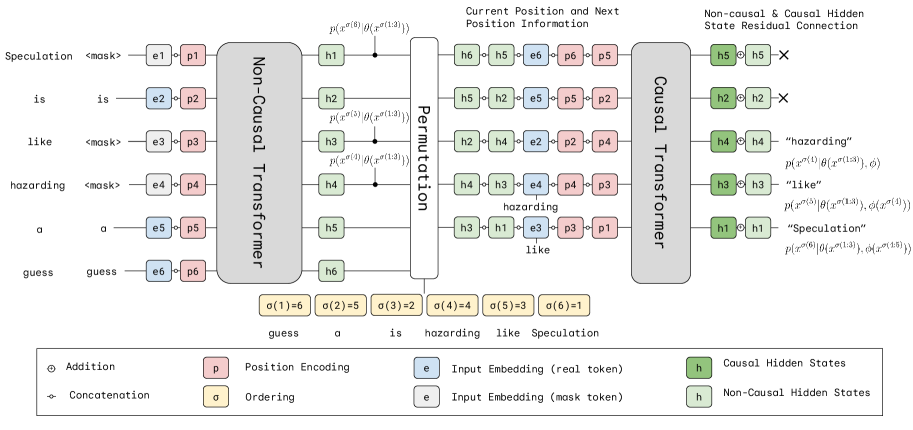
Speculative decoding | AI Research Papers

Speculative Decoding and Beyond: An In-Depth Review of Techniques | AI ...

Boosting LLM Inference Speed Using Speculative Decoding | Towards Data ...

Aman's AI Journal • Primers • Speculative Decoding
TensorRT-LLM Speculative Decoding Boosts Inference Throughput by up to ...
Real-Time AI Precision: Accelerating Inference with Composable GPU ...
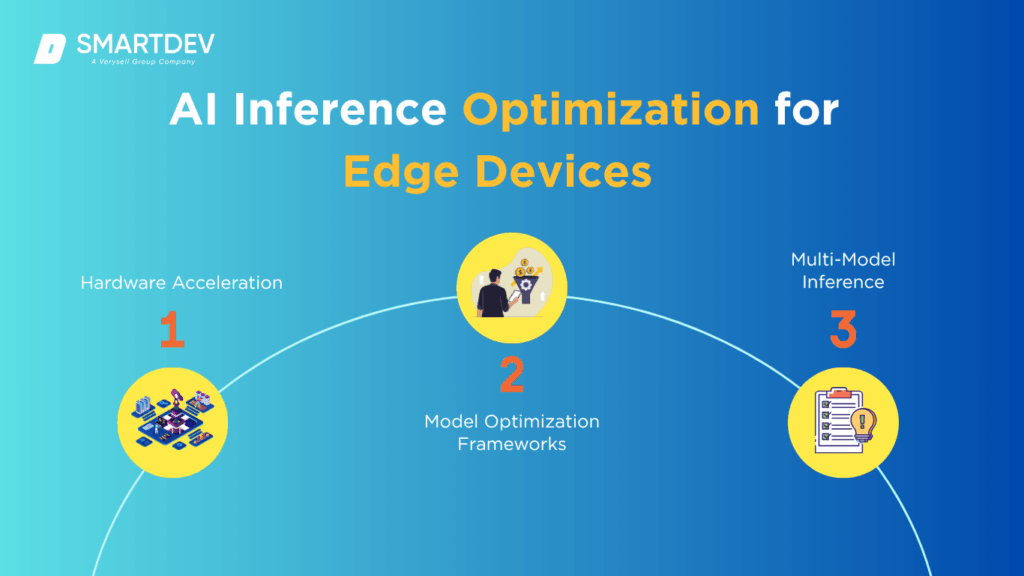
How to Optimize AI Model Performance for Edge Deployment in IoT and ...
Inference at the Edge: Optimizing AI Compute for Real-Time Performance ...
Advertisement Space (336x280)

Speculative Decoding for Production LLMs | TURION.AI

Continuous Speculative Decoding for Autoregressive Image Generation ...

Real-Time Inference for Distributed Multimodal Systems under ...

Low-Latency Inference Systems: How Modern AI Platforms Optimize Speed ...

Why Inference Costs Dominate Real AI System Economics (And Why Most ...
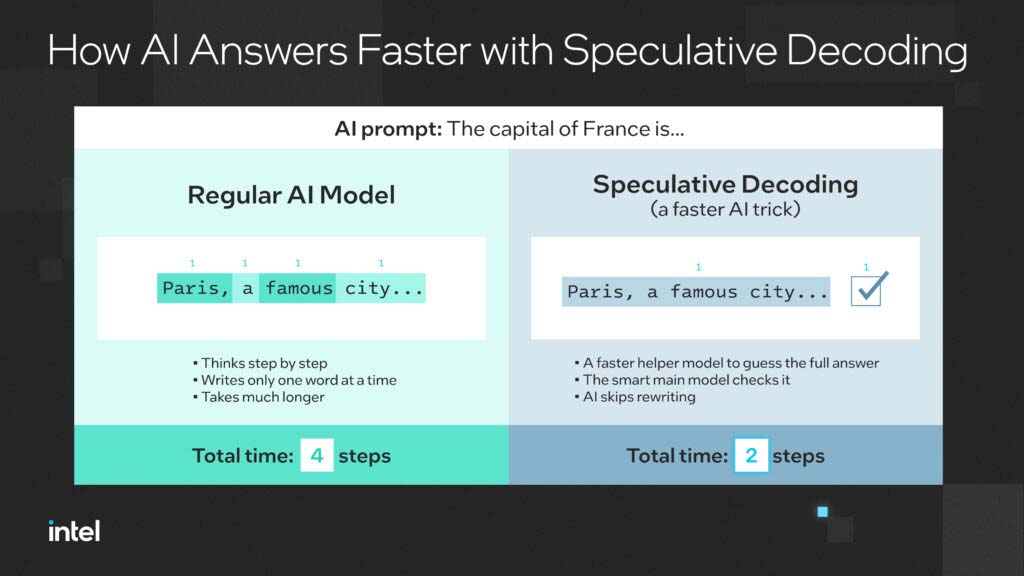
Advance in speculative decoding speeds AI - IT-Online