
Artificial Analysis Long Context Reasoning Benchmark Leaderboard
Artificial Analysis Long Context Reasoning Benchmark Leaderboard ...

Announcing Artificial Analysis Long Context Reasoning (AA-LCR)
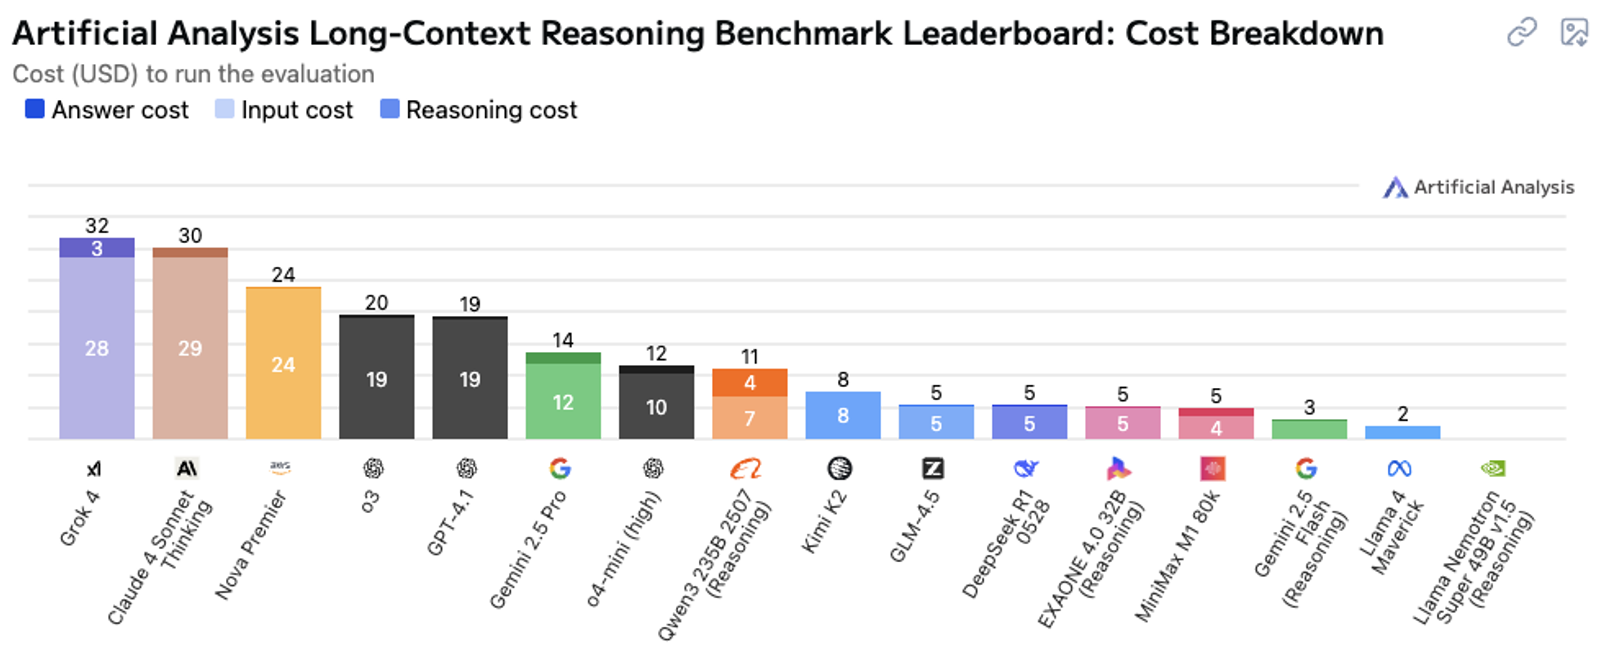
Announcing Artificial Analysis Long Context Reasoning (AA-LCR)

Announcing Artificial Analysis Long Context Reasoning (AA-LCR)

(PDF) DebateBench: A Challenging Long Context Reasoning Benchmark For ...

Best reasoning LLM in 2026: ARC-AGI-2 benchmark leaderboard
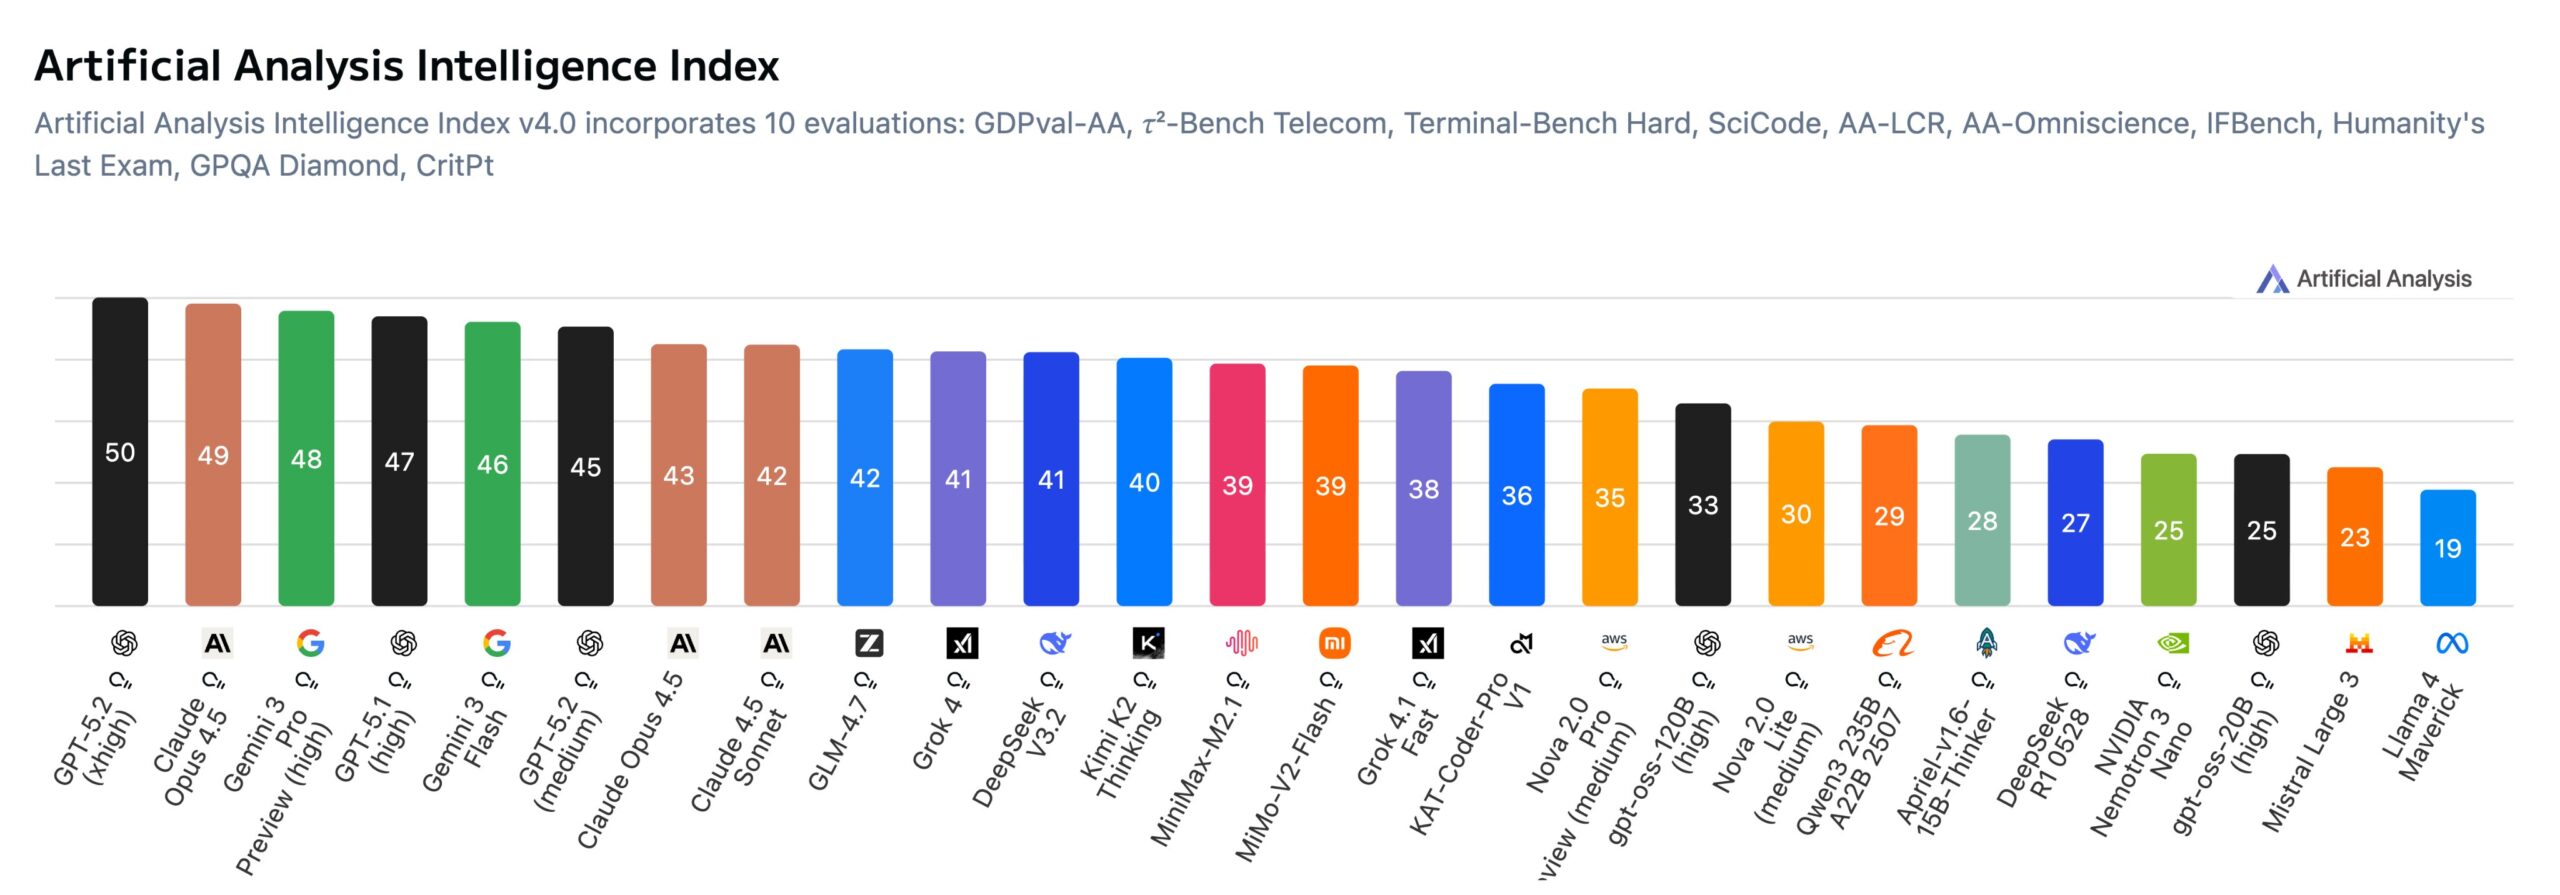
New Artificial Analysis benchmark shows OpenAI, Anthropic, and Google ...
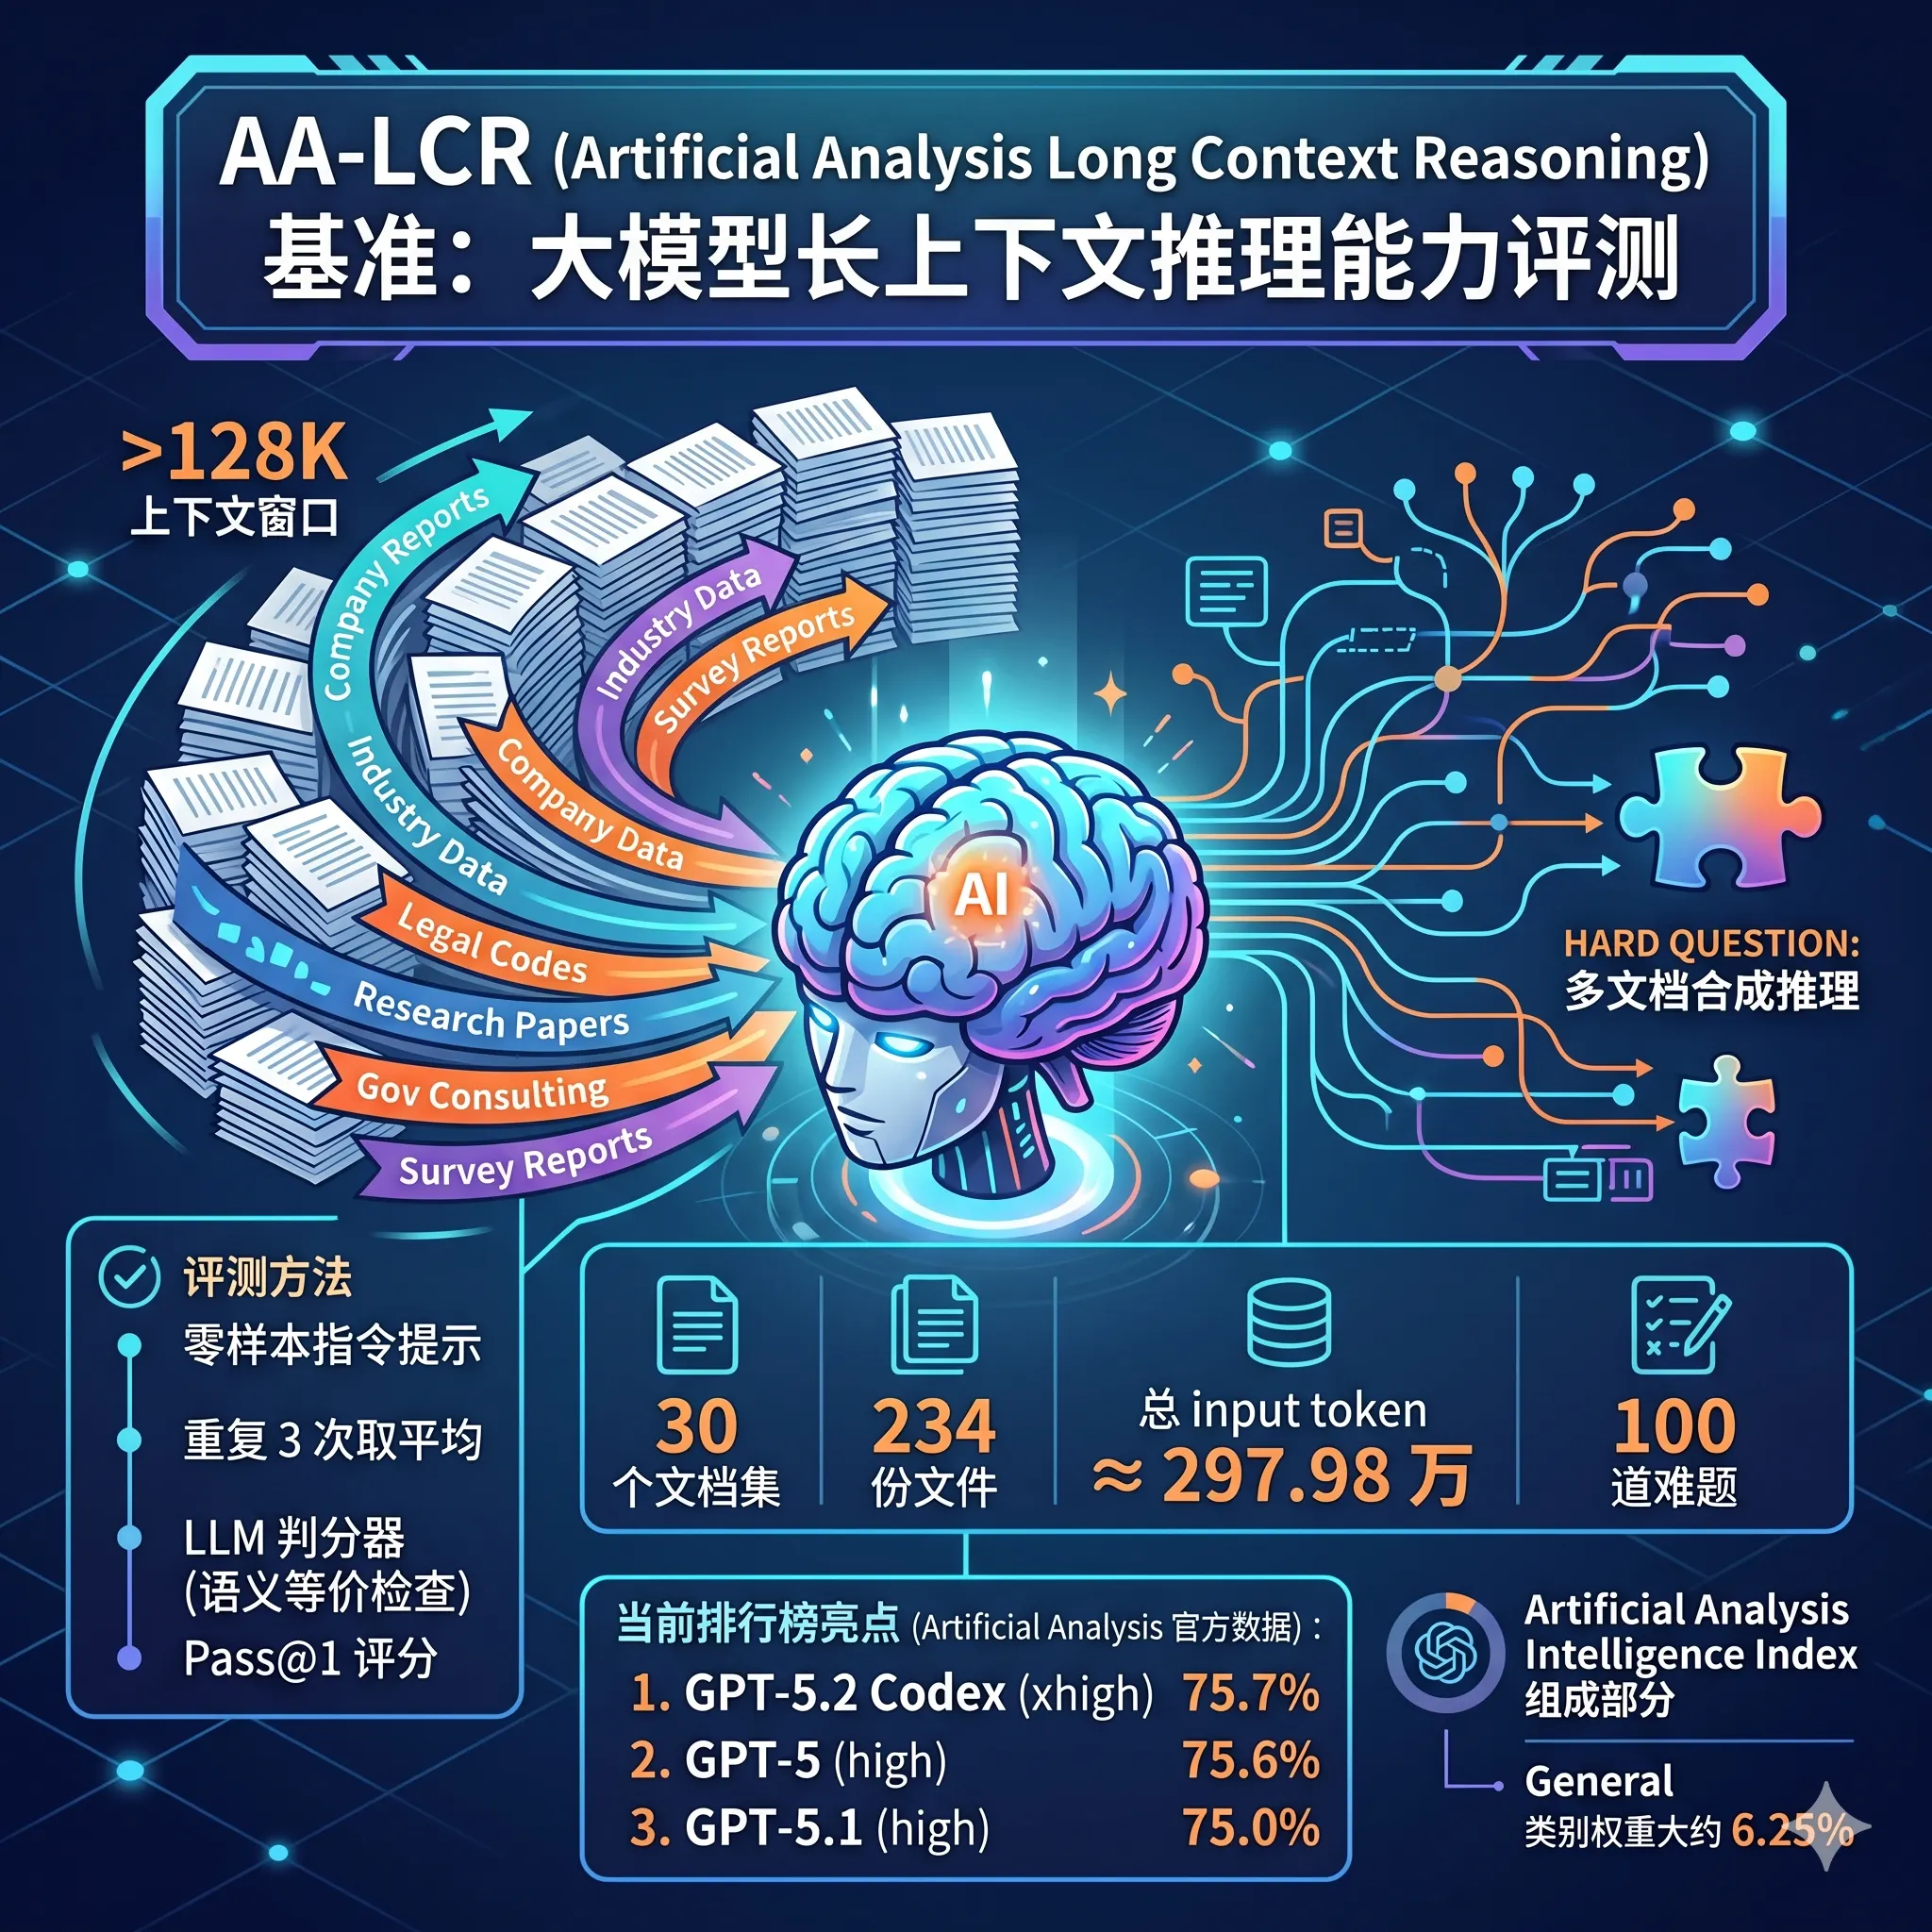
AA-LCR:大模型长上下文推理能力的权威评测基准(Artificial Analysis Long Context Reasoning)是 ...
LLMs Long Context Comprehension Benchmark

@georgewritescode on Hugging Face: "Announcing Artificial Analysis Long ...
Advertisement Space (300x250)

Alibaba releases QwenLong-L1-32B: Long Context Reasoning Model Stuns ...

Reasoning Degradation in LLMs with Long Context Windows: New Benchmarks ...
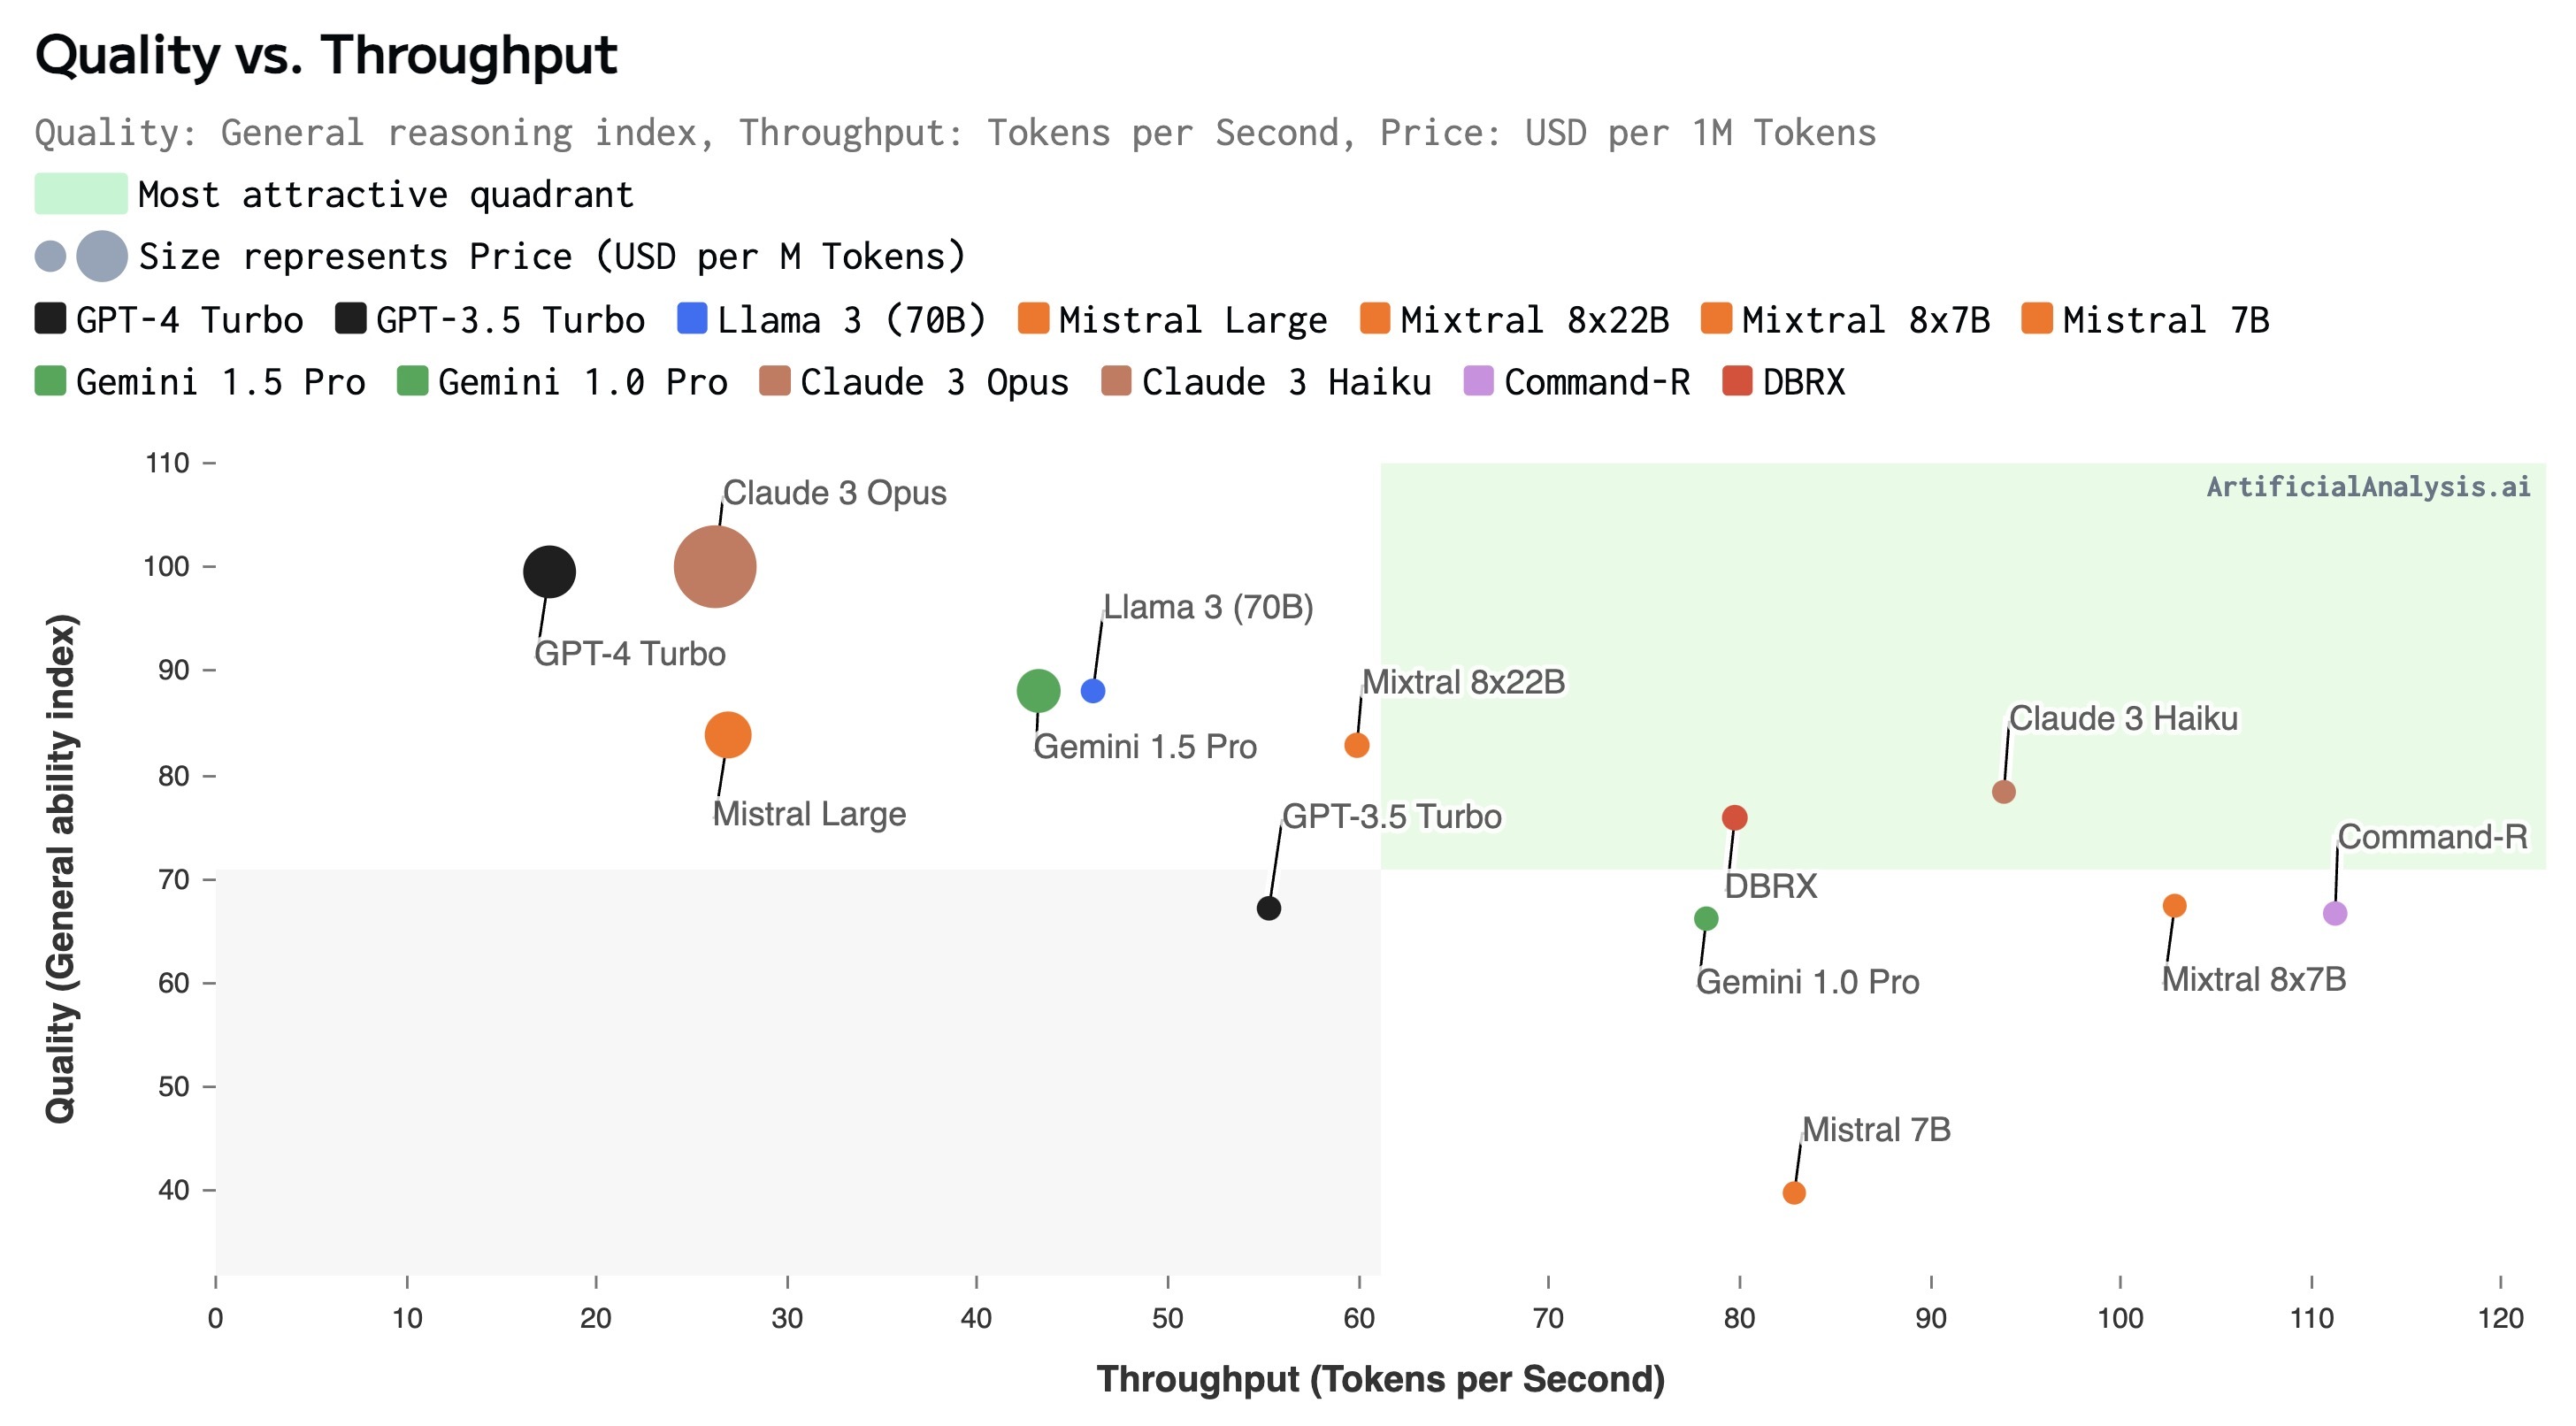
Bringing the Artificial Analysis LLM Performance Leaderboard to Hugging ...

Reasoning Degradation in LLMs with Long Context Windows: New Benchmarks ...

Multilingual Evaluation of Long Context Retrieval and Reasoning | AI ...

Reasoning Degradation in LLMs with Long Context Windows: New Benchmarks ...

Reasoning Degradation in LLMs with Long Context Windows: New Benchmarks ...

Evaluating Long Context (Reasoning) Ability | wh

LoCoBench-Agent: An Interactive Benchmark for LLM Agents in Long ...

Evaluating Long Context (Reasoning) Ability | wh
Advertisement Space (336x280)

Evaluating Long Context (Reasoning) Ability | wh

将 Artificial Analysis LLM 性能排行榜引入 Hugging Face - Hugging Face 文档

Evaluating Long Context (Reasoning) Ability | wh

Table 1 from LongReason: A Synthetic Long-Context Reasoning Benchmark ...

Long Context AI Models Explained (2026 Guide)

Michelangelo: An Artificial Intelligence Framework for Evaluating Long ...

Artificial Analysis - AI Model Benchmarking Platform | EveryDev.ai
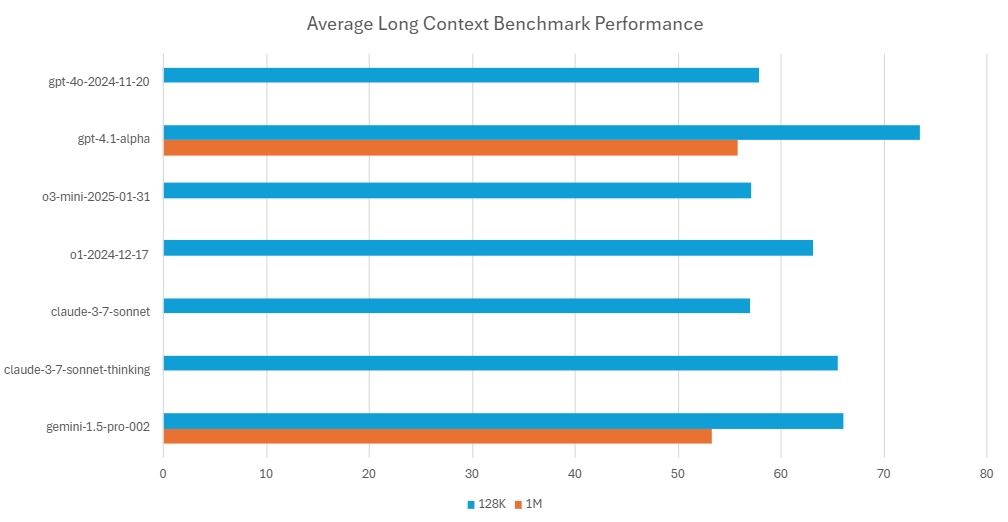
Legal AI Benchmarking: Evaluating Long Context Performance for LLMs ...

Michelangelo: An Artificial Intelligence Framework for Evaluating Long ...
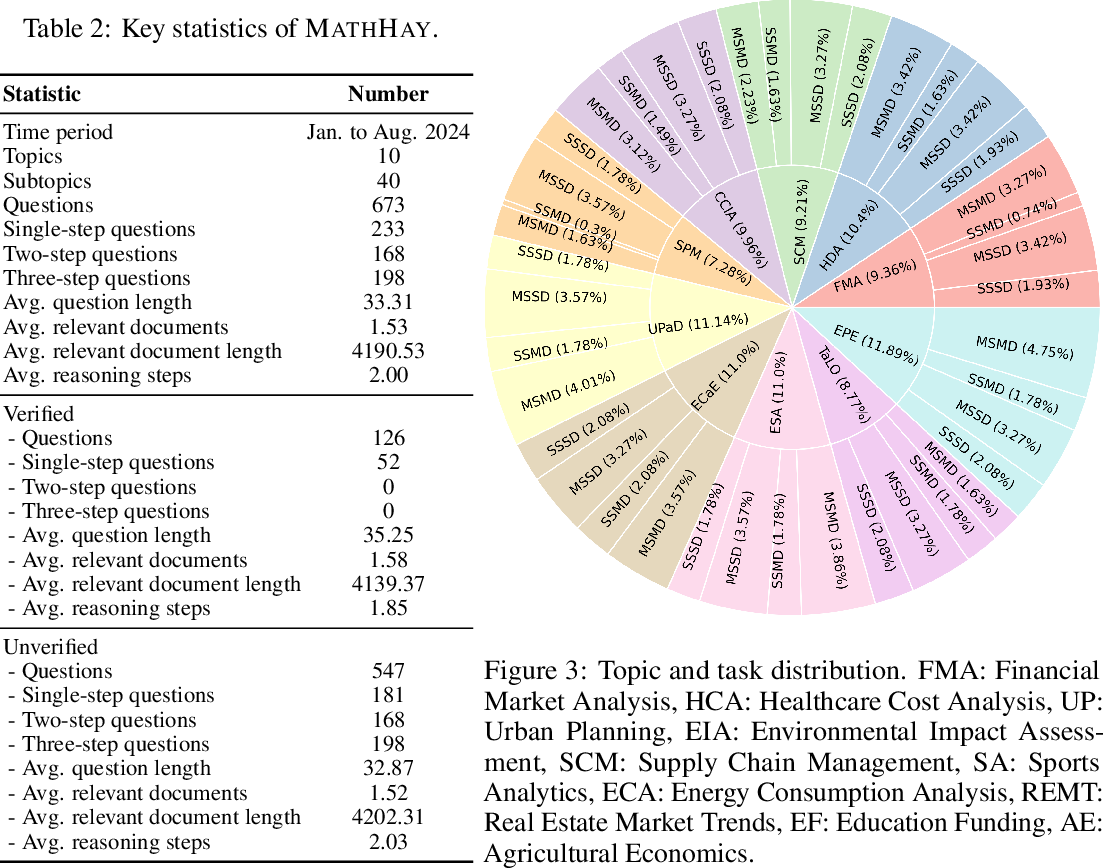
MathHay: An Automated Benchmark for Long-Context Mathematical Reasoning ...
Advertisement Space (336x280)
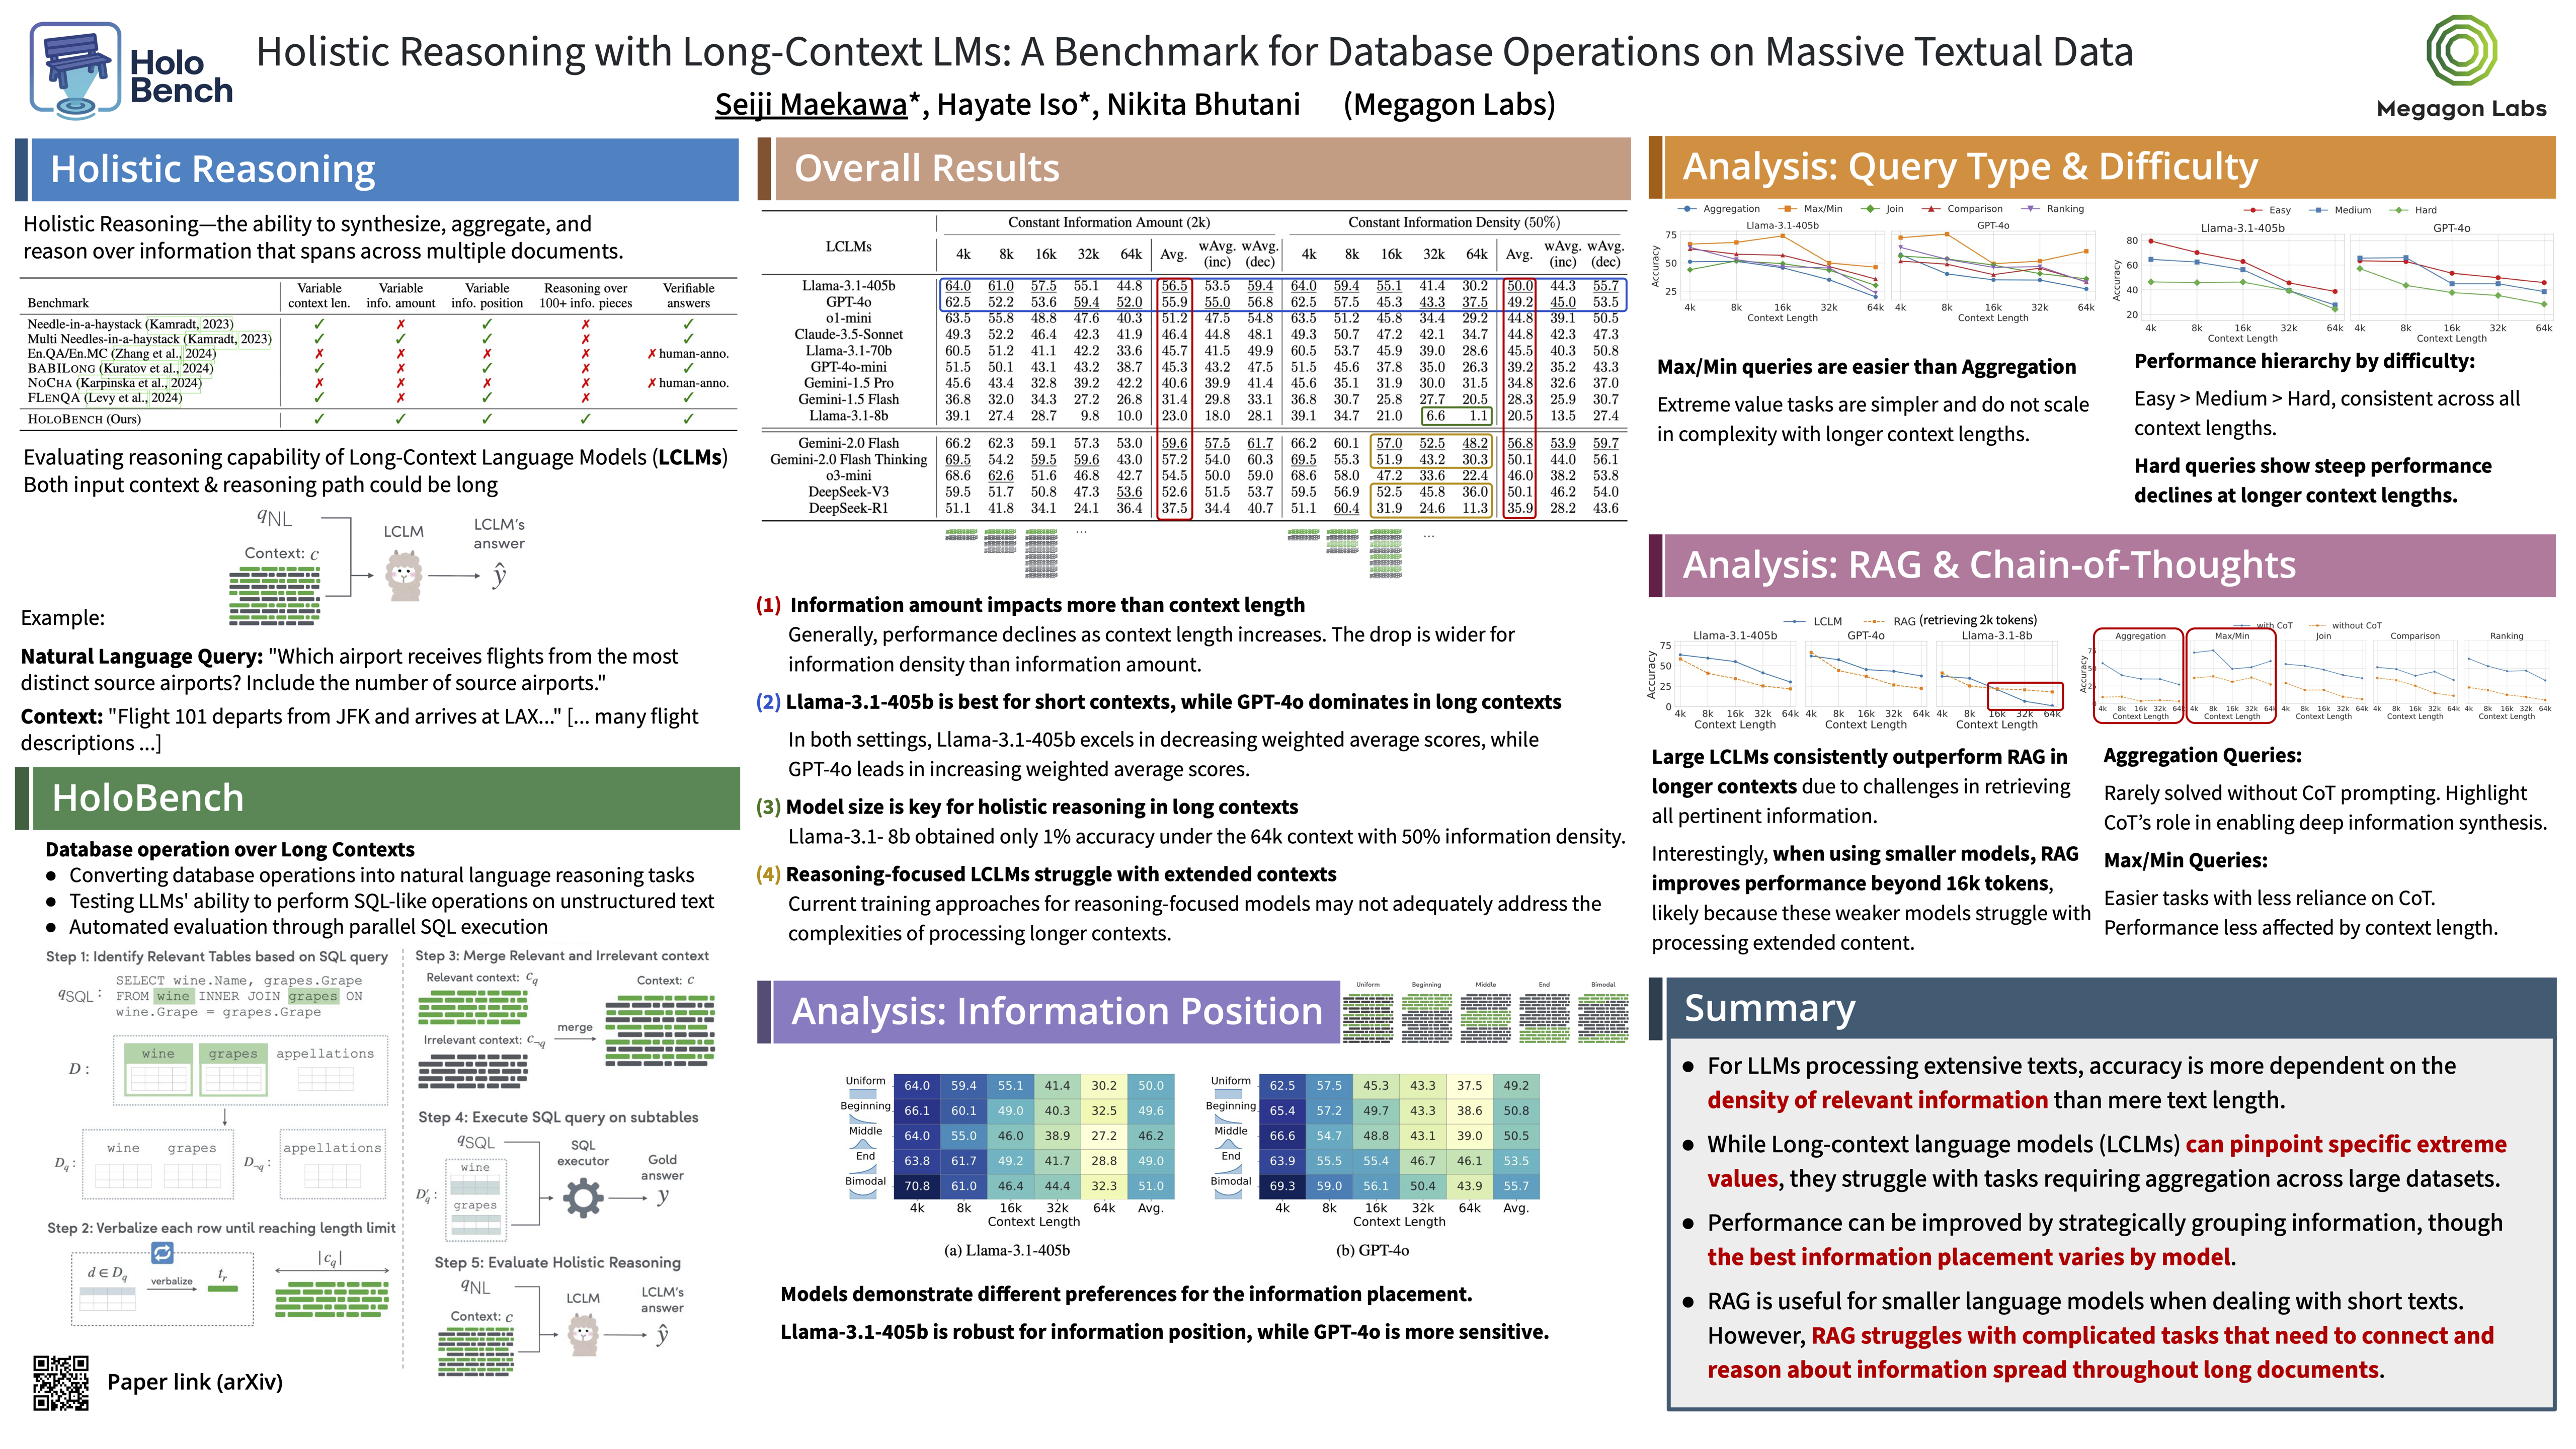
ICLR Poster Holistic Reasoning with Long-Context LMs: A Benchmark for ...
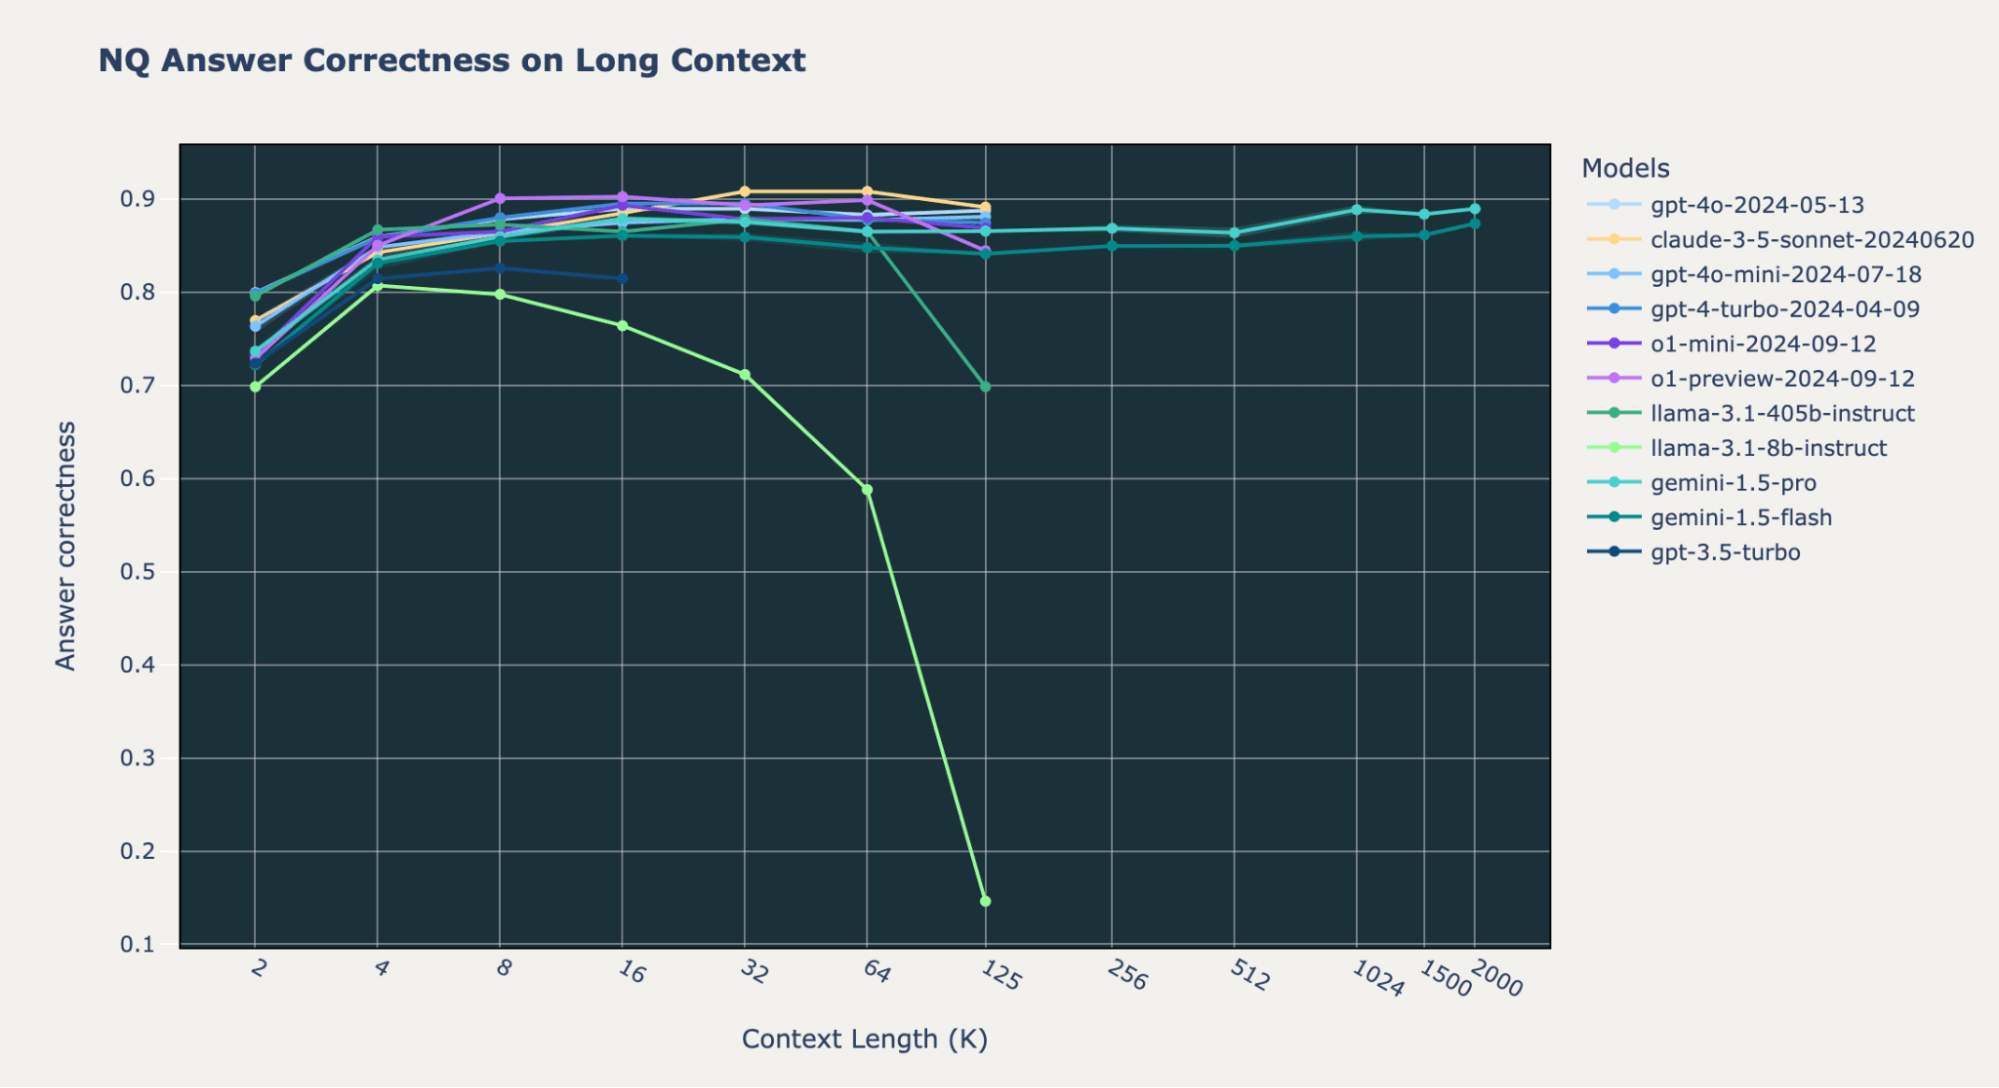
The Long Context RAG Capabilities of OpenAI o1 and Google Gemini ...
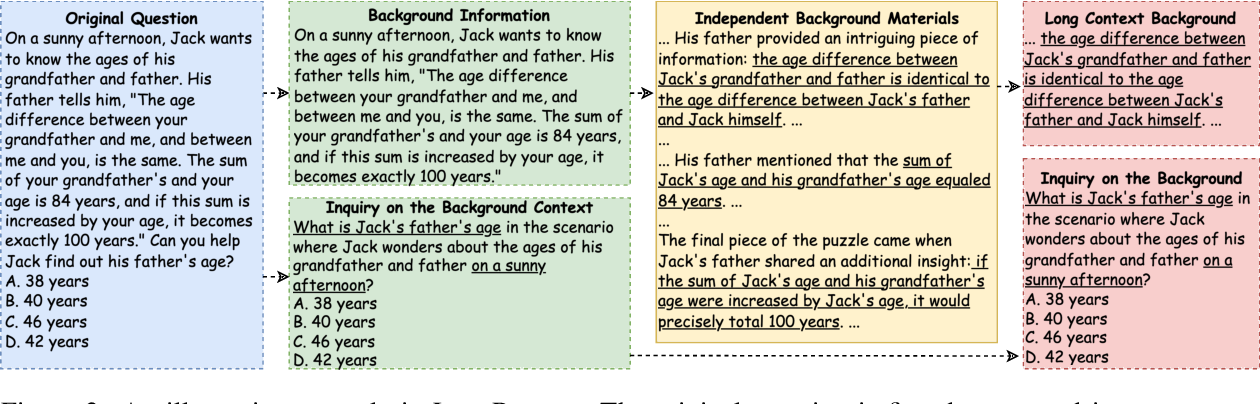
Figure 2 from LongReason: A Synthetic Long-Context Reasoning Benchmark ...

Figure 1 from LongReason: A Synthetic Long-Context Reasoning Benchmark ...

Today we're releasing Context-Bench, a benchmark (and live leaderboard ...

[논문 리뷰] LMAct: A Benchmark for In-Context Imitation Learning with Long ...