
Attention Maps From The Encoder And Decoder Under Different Masks The

Attention maps from the encoder and decoder under different masks. The ...

The attention maps obtained from the attention network under different ...

Attention maps [3] from the last layer of the transformer encoder under ...

The attention maps resulted from different encoder's layers | Download ...

The class attention maps resulted from different encoder's layers for ...

The class attention maps resulted from different encoder's layers for ...
Attention heat maps generated by the first, sixth, and last layers of ...

Exemplar attention maps from second MHA sub-layer of the decoder. (a ...
Attention heat maps generated by the first, sixth, and last layers of ...

Visualization of attention maps from the transformer encoder/decoder ...
Advertisement Space (300x250)

Illustration for examples of the attention maps and masked images ...

the proposed network with encoder and decoder layers in the end-to-end ...

Attention Module A i in our proposed model. U i and V i are the ...
MemTransformer 10 encoder attention maps. As the model encodes an input ...

Comparison of feature maps generated in the encoder pathway. (a) Input ...

Mask of different modules. The first mask is the encoder mask, which is ...
MemTransformer 10 decoder attention maps. Every layer of the decoder ...

Schematic diagram of Attention gate.The feature map from encoder and ...
The encoder-decoder attention and channel attention modules. | Download ...

MemTransformer 10 decoder attention maps. Every layer of the decoder ...
Advertisement Space (336x280)

Schematic diagram of Attention gate.The feature map from encoder and ...

Schematic diagram of Attention gate.The feature map from encoder and ...

An example of semantic gap between encoder and decoder. The feature ...

The architecture of a β-VAE consists of an encoder and a decoder. The ...
MemBottleneck 20 decoder attention maps. At the decoding phase, almost ...

Visualization of the attention maps produced by the 4-th layer for ...
Results of the encoder process. From top to bottom are the original ...

Channel attention structure: Xe is the encoder module feature map, Xd ...

Encoder self-attention. We visualize the self-attention maps for four ...

The encoder-decoder attention and channel attention modules. | Download ...
Advertisement Space (336x280)

Attention gate with gating signal (g) from encoder and current level ...

Overview of the encoder-decoder approach. First the encoder maps the ...
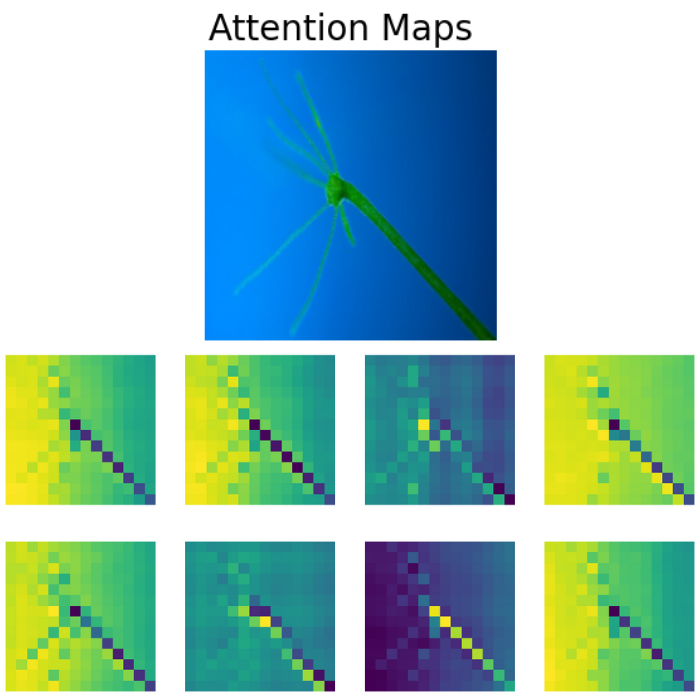
Fine Tuning Vision Transformer and Visualizing Attention Maps
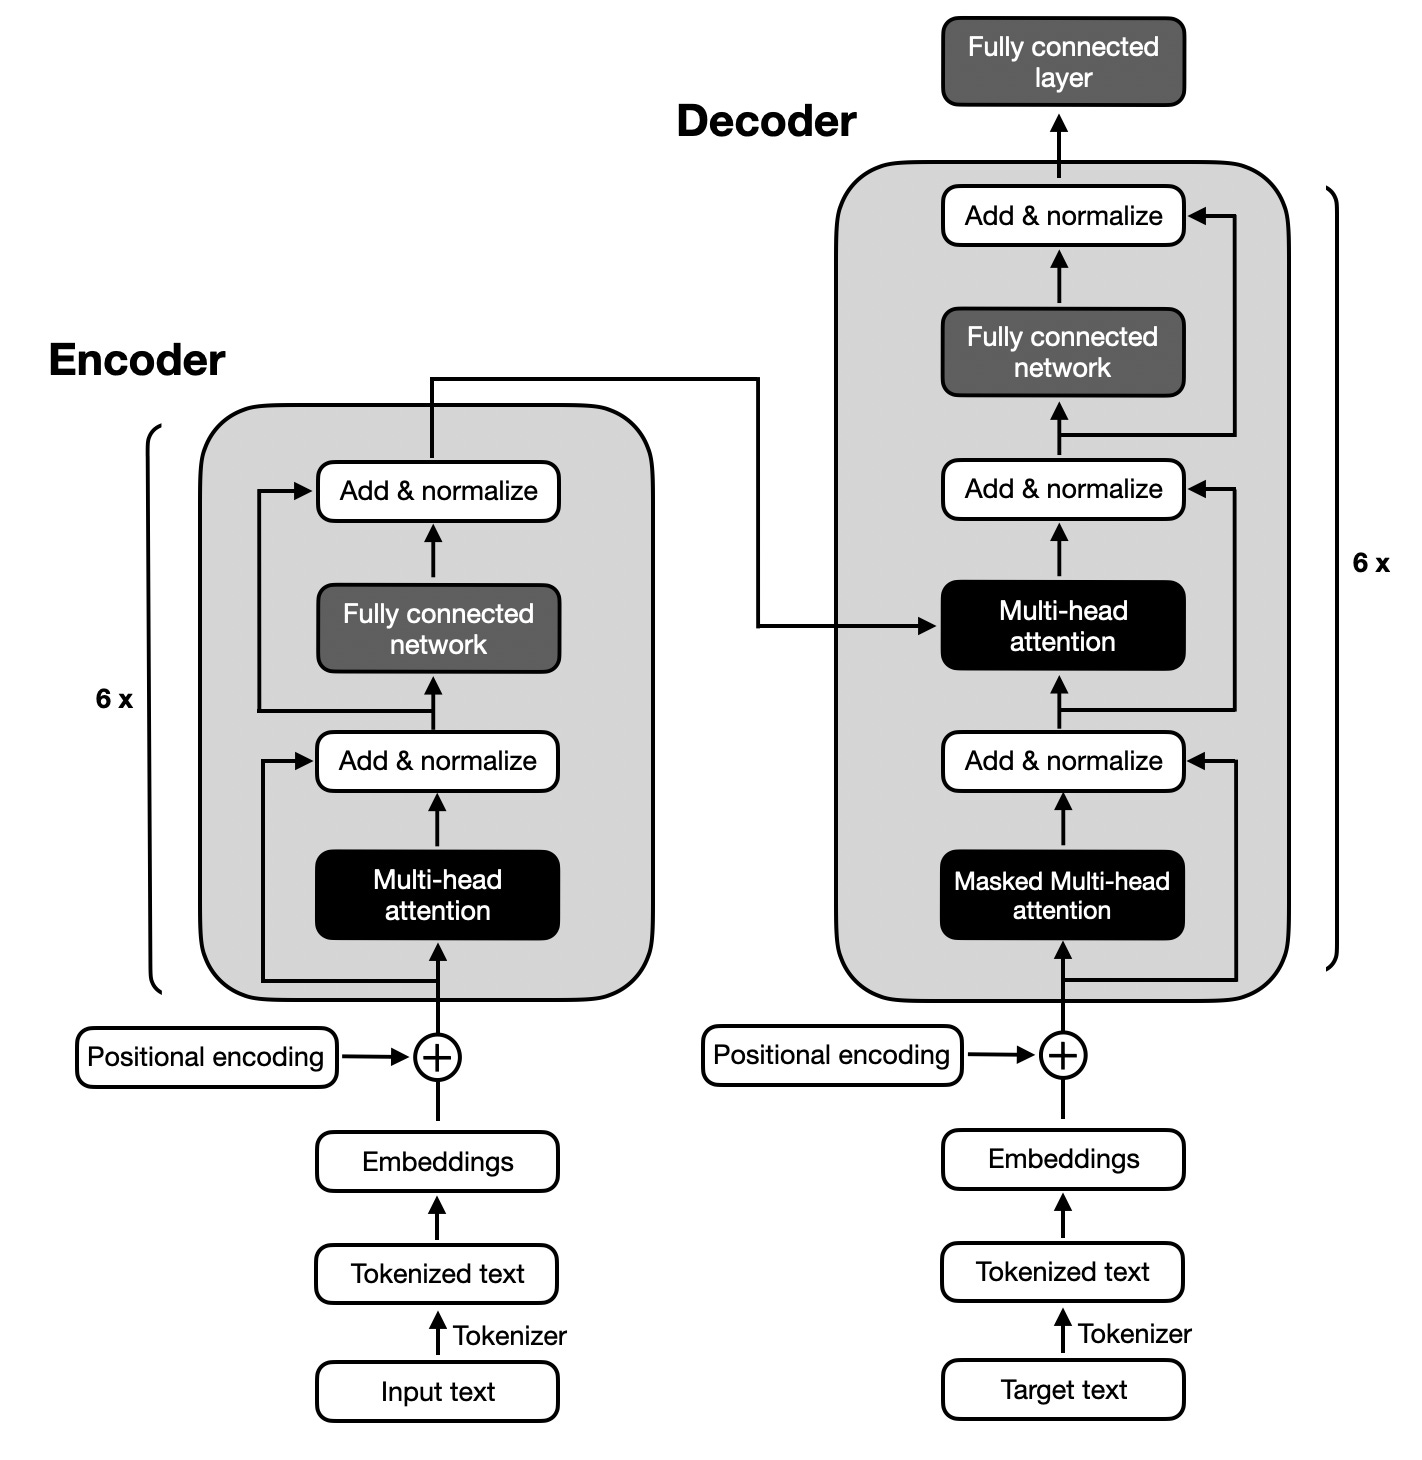
Understanding Encoder And Decoder LLMs

Overview of proposed method showing that a mask obtained from the class ...
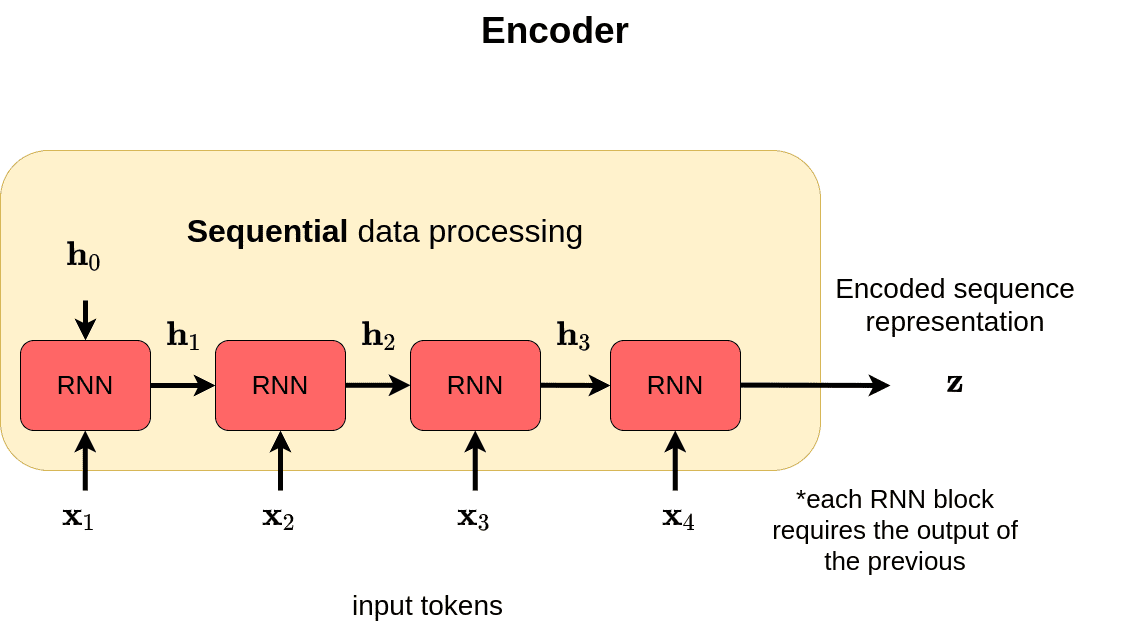
How Attention works in Deep Learning: understanding the attention ...