
Average Reward Over Time For The Epsilon Greedy And Ucb Strategies With
Average reward over time for the epsilon-greedy and UCB strategies with ...

Average reward over time for the epsilon-greedy and UCB strategies with ...

Average reward over time for epsilon-greedy and UCB strategies ...

Average reward over time for each algorithm over 100 steps using the ...

Average reward over time for each algorithm over 100 steps using the ...

Average reward over time for ε-greedy and SoftMax over 1000 steps using ...

Average reward over time for ε-greedy and SoftMax over 1000 steps using ...
Estimated value of each bandit over time for the epsilon-greedy ...

Average achieved rewards (50 runs) over time for different planner ...

Comparison of epsilon greedy training with the multinomial approach ...
Advertisement Space (300x250)

Comparison of epsilon greedy training with the multinomial approach ...

Evolution of the episode reward over the episodes for a value of ...

7: The figure shows the average reward over 10 runs in the scenario SCN ...
Cumulative average rewards for ϵ-greedy, UCB, Exp3, Exp3.M, and Exp3.M ...

List of the figures showing the average increase in rewards with ...

Epsilon Greedy Selector - Documentation for Calvera
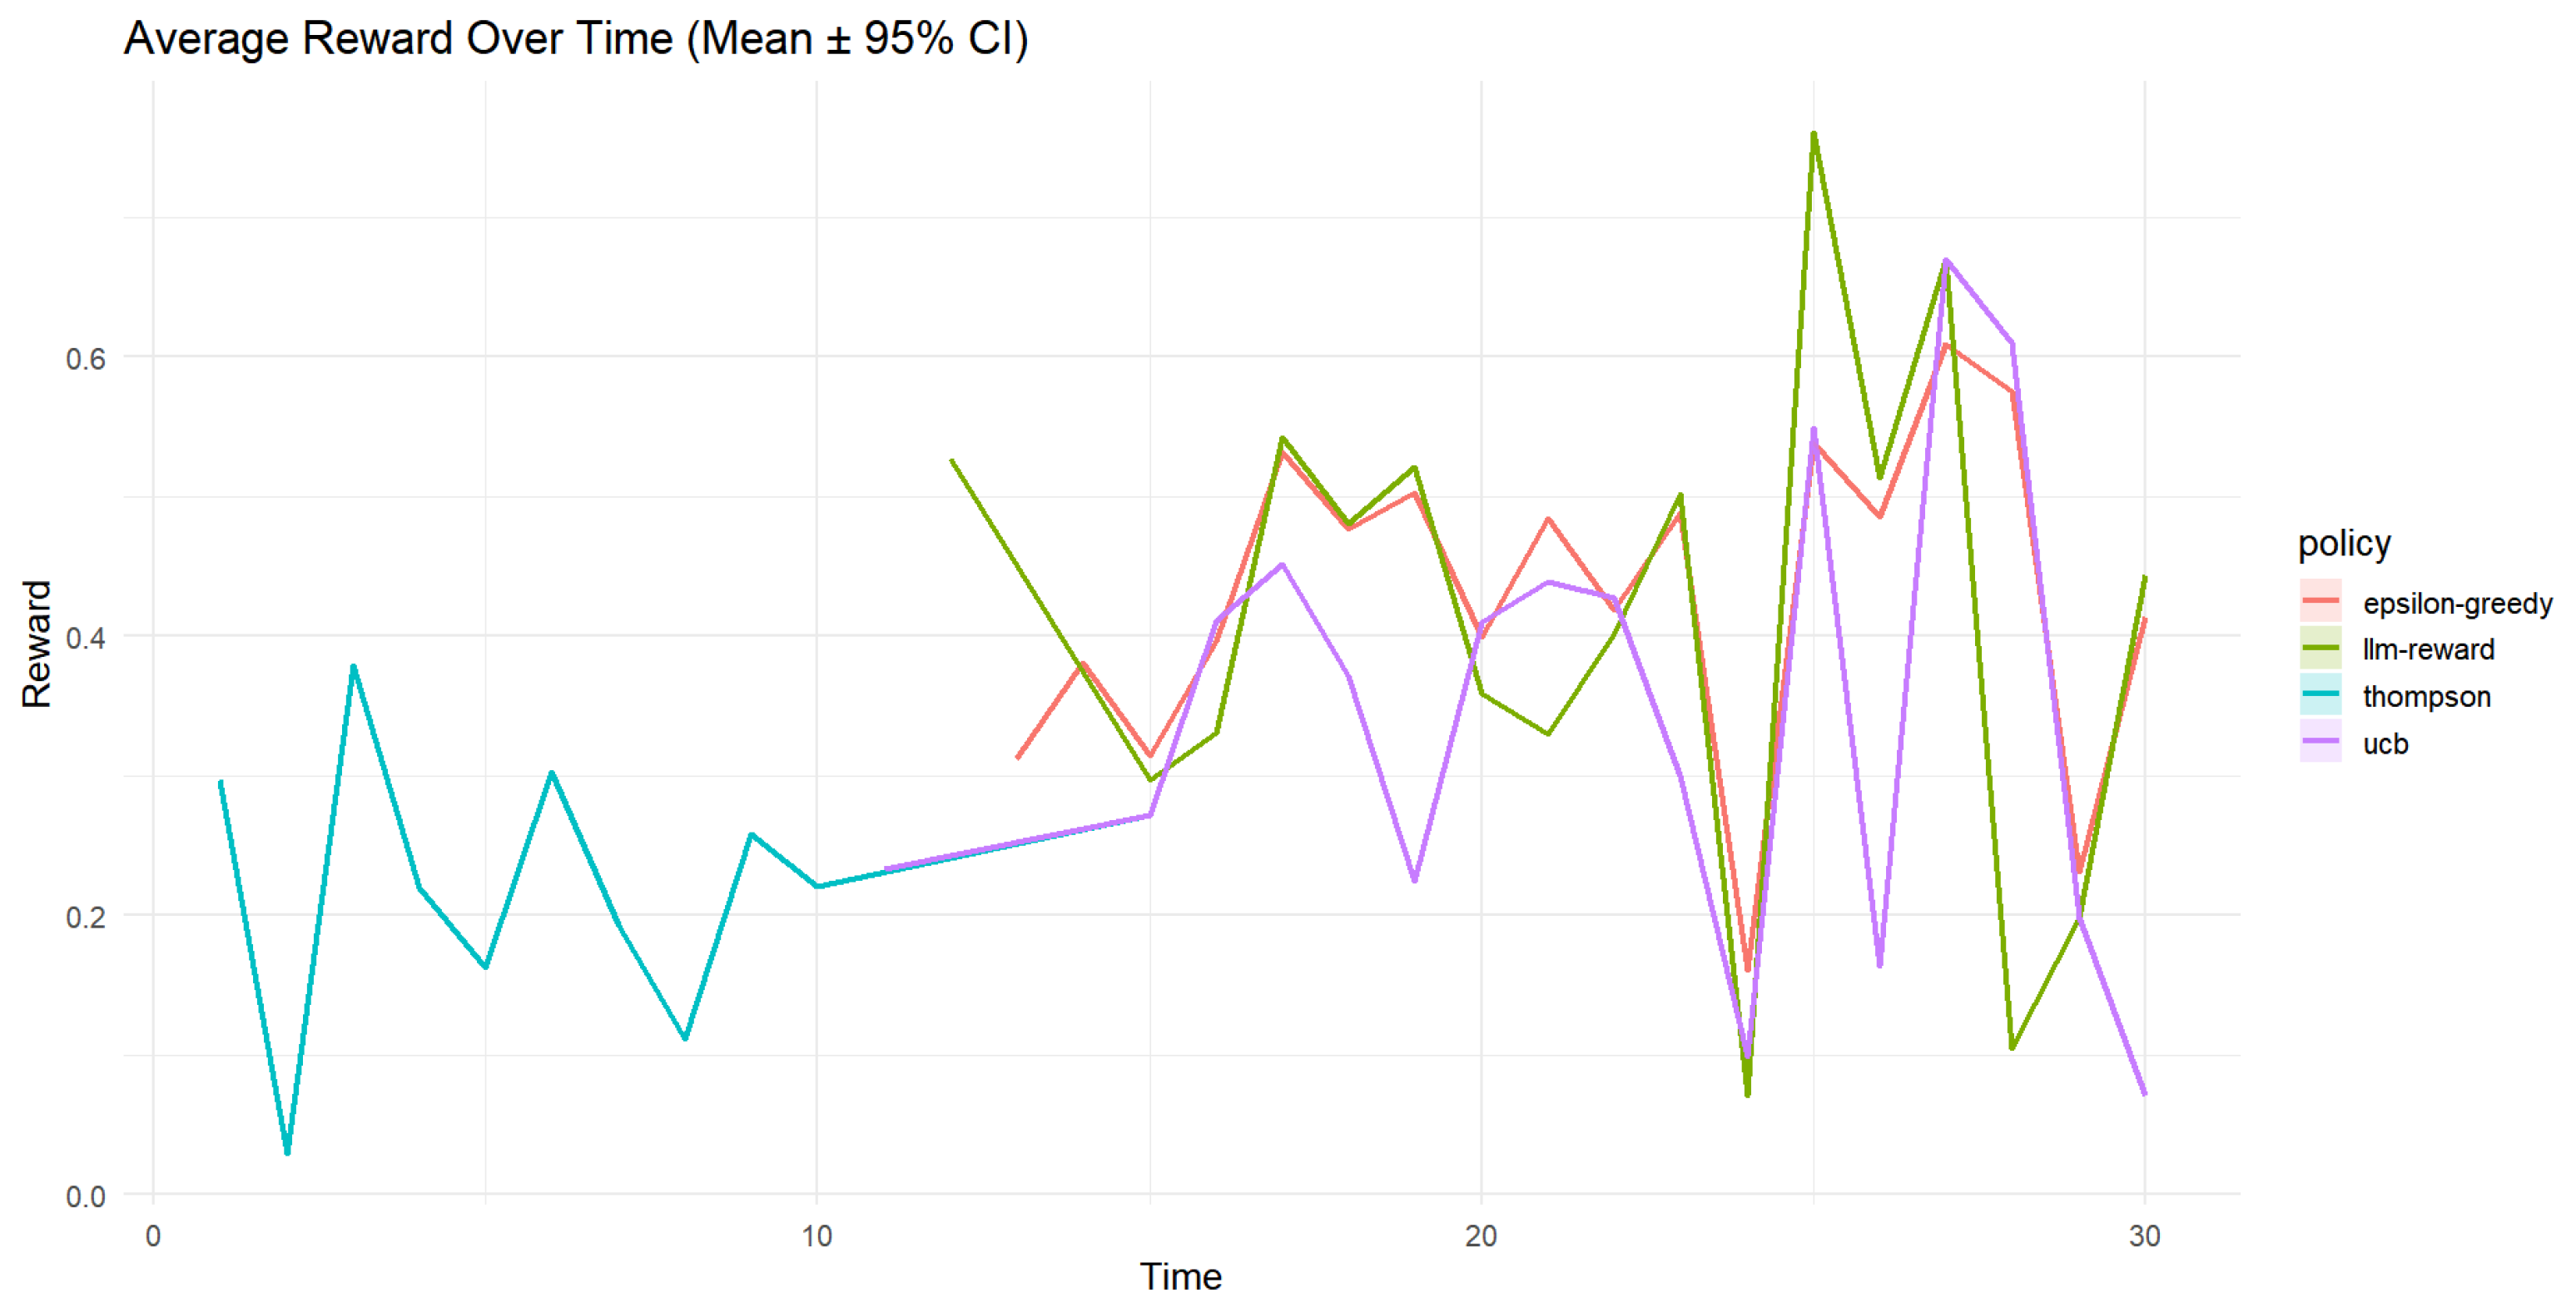
LLM-Guided Ensemble Learning for Contextual Bandits with Copula and ...

Top: Average population reward with independent epsilon-greedy agents ...

Top: Average population reward with independent epsilon-greedy agents ...
Top: Average population reward with independent epsilon-greedy agents ...
Advertisement Space (336x280)
Histogram of average time per epoch of epsilon-greedy algorithm. The ...

Histogram of average time per epoch of epsilon-greedy algorithm. The ...

LLM-Informed Multi-Armed Bandit Strategies for Non-Stationary Environments

LLM-Informed Multi-Armed Bandit Strategies for Non-Stationary Environments
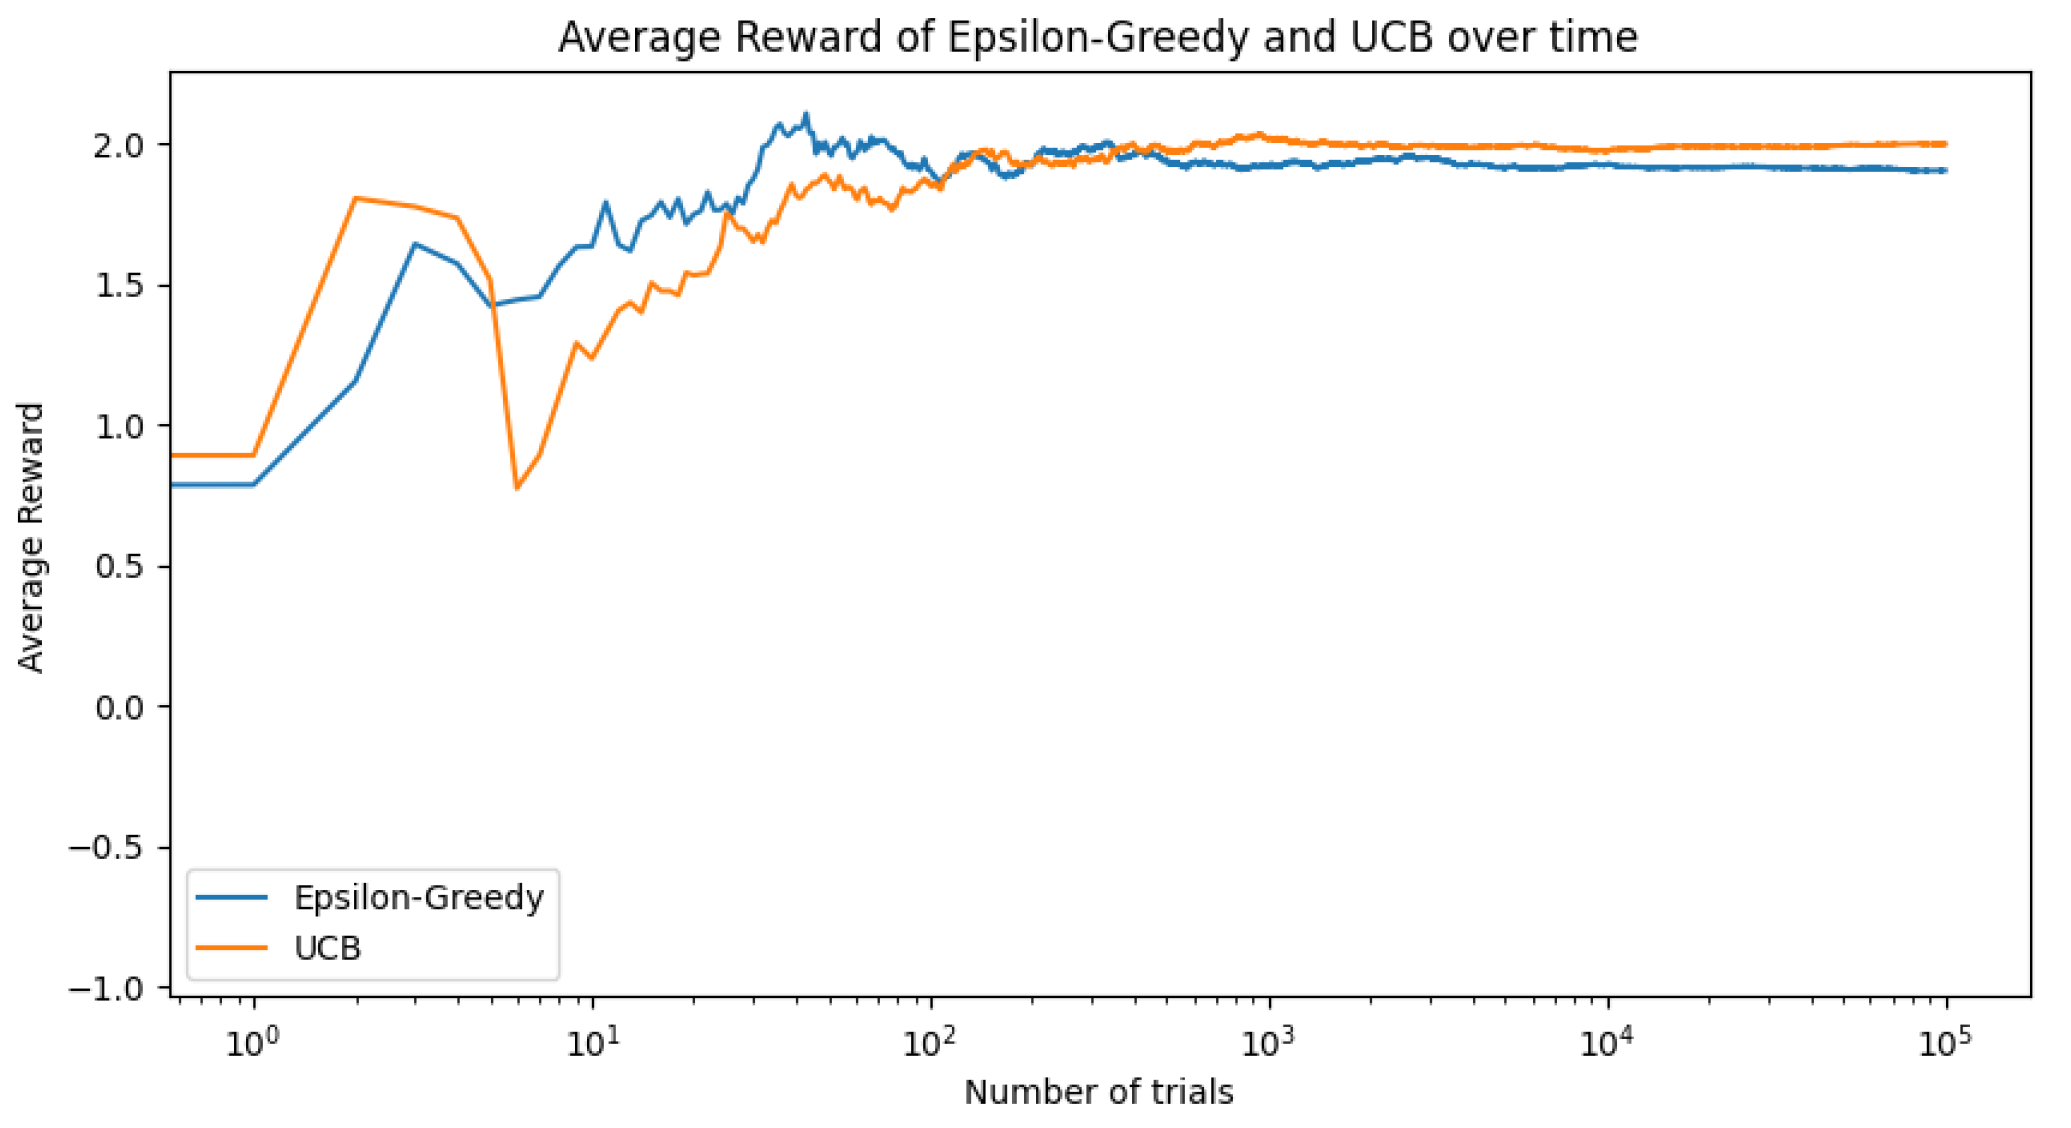
LLM-Informed Multi-Armed Bandit Strategies for Non-Stationary Environments

LLM-Informed Multi-Armed Bandit Strategies for Non-Stationary Environments

LLM-Informed Multi-Armed Bandit Strategies for Non-Stationary Environments

LLM-Informed Multi-Armed Bandit Strategies for Non-Stationary Environments

LLM-Informed Multi-Armed Bandit Strategies for Non-Stationary Environments

LLM-Informed Multi-Armed Bandit Strategies for Non-Stationary Environments
Advertisement Space (336x280)
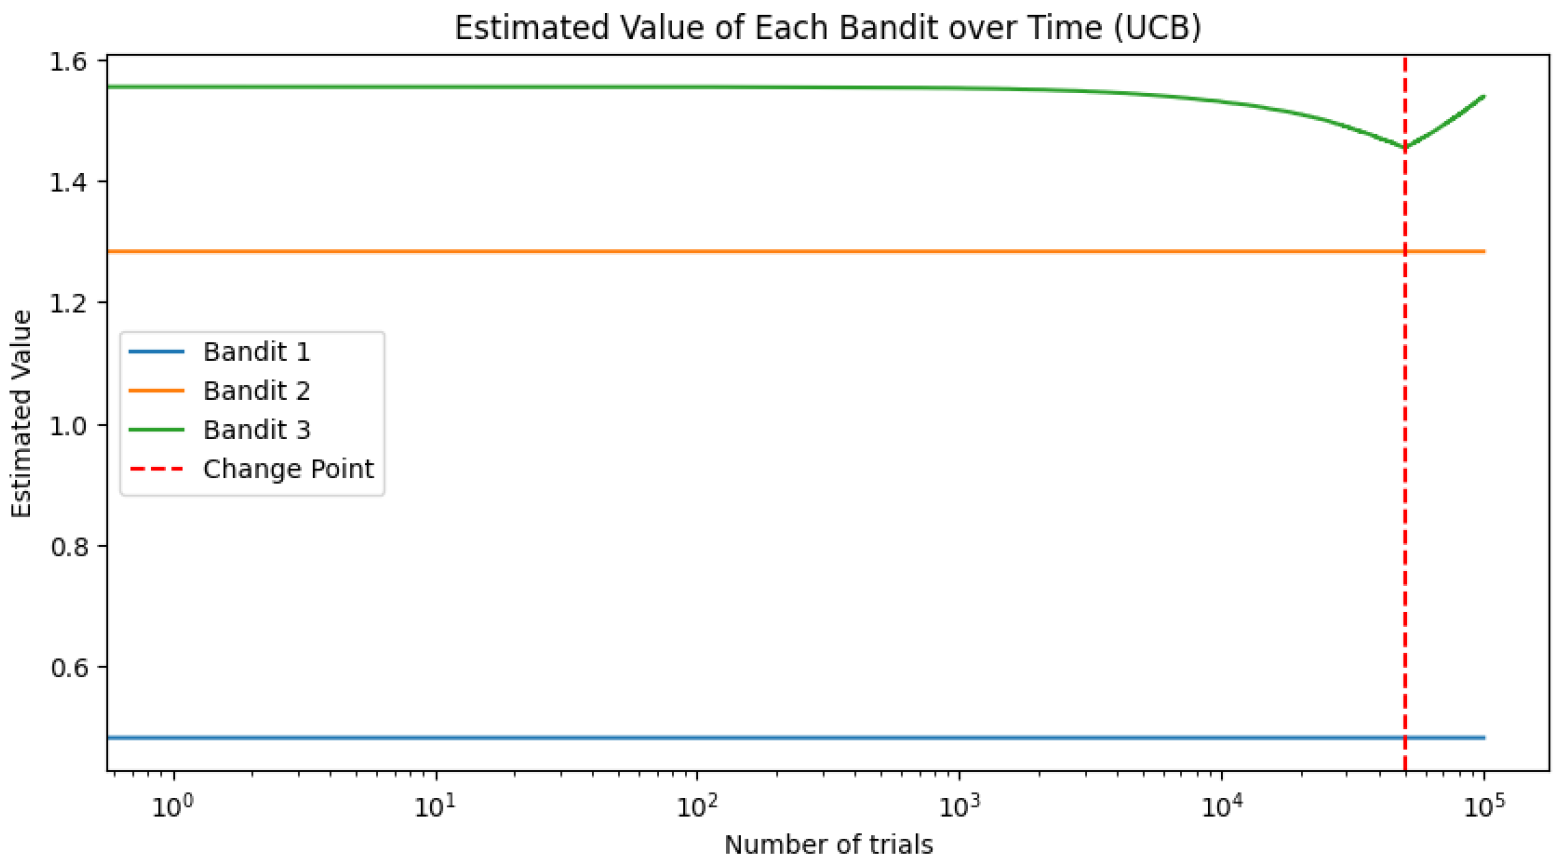
LLM-Informed Multi-Armed Bandit Strategies for Non-Stationary Environments

normal distribution - Why is the expected reward of this $\epsilon = 0 ...
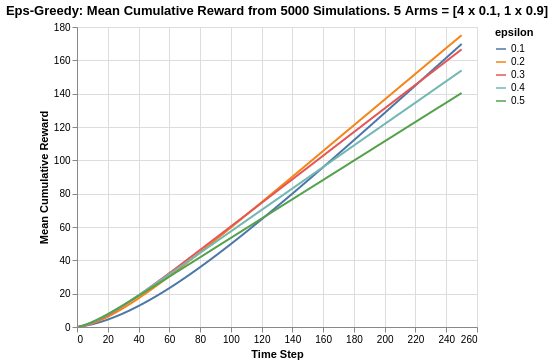
MAB Analysis of Epsilon Greedy Algorithm - Kenneth Foo - Portfolio

Comparison of the regret of the UCB, GLM-UCB and the-greedy ( = 0.1 ...

Comparing Simple Exploration Techniques: ε-Greedy, Annealing, and UCB

What is Epsilon Greedy Algorithm?