
Building A Vision And Language Guided Multimodal Whole Slide Foundation

Building a Vision and Language-guided Multimodal Whole Slide Foundation ...

(PDF) Vision and Multimodal Foundation Models in Medical Imaging: A ...

Development and Validation of a Multimodal Multitask Vision Foundation ...

MLLM-HWSI: A Multimodal Large Language Model for Hierarchical Whole ...

ELEV-VISION-SAM: Integrated Vision Language and Foundation Model for ...

Multimodal Whole Slide Foundation Model for Pathology

Multimodal Whole Slide Foundation Model for Pathology

[논문 리뷰] CPath-Omni: A Unified Multimodal Foundation Model for Patch and ...

(PDF) A multimodal vision foundation model for clinical dermatology

(PDF) Multimodal Whole Slide Foundation Model for Pathology
Advertisement Space (300x250)

Figure 3 from Multimodal Whole Slide Foundation Model for Pathology ...

Multimodal Whole Slide Foundation Model for Pathology

Frontiers | A Modular Vision Language Navigation and Manipulation ...

PathAlign: A vision-language model for whole slide images in ...

Multimodal & Foundation Vision AI

Main framework of the survey about vision and language related ...

Paige Releases PRISM2: A Whole-Slide Foundation Model for Multimodal AI ...
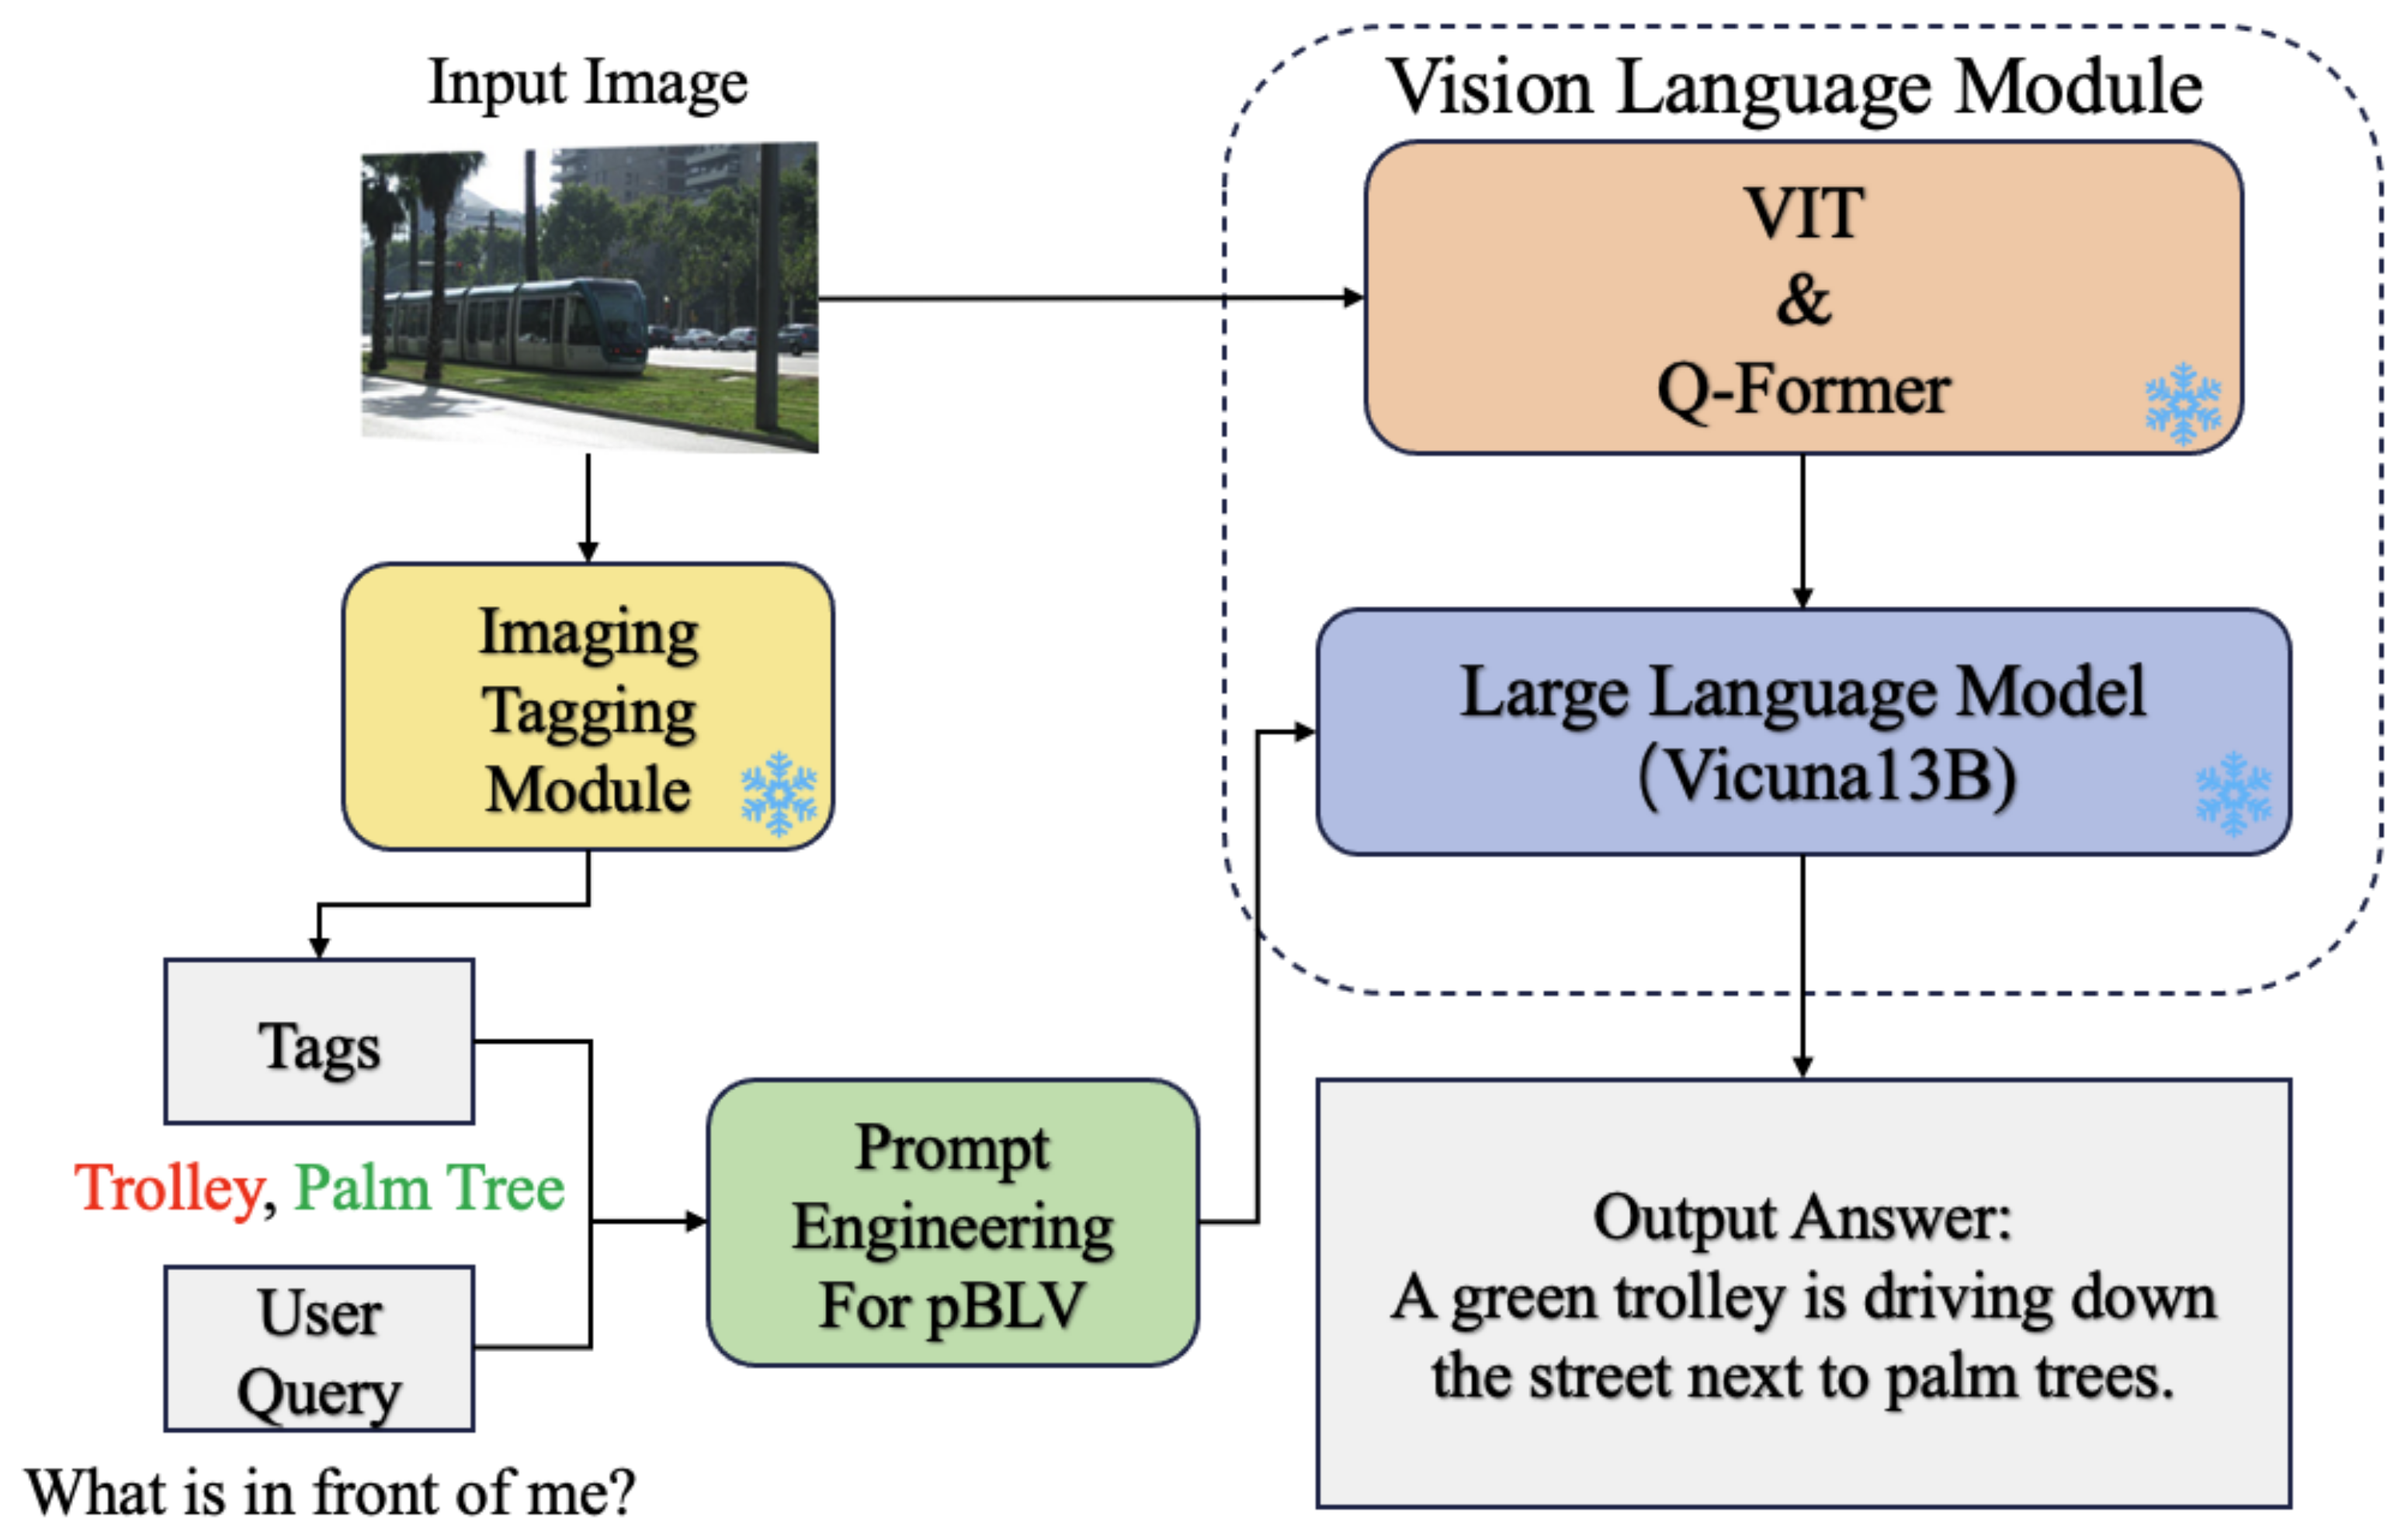
A Multi-Modal Foundation Model to Assist People with Blindness and Low ...

InternVL: Scaling up Vision Foundation Models and Aligning for Generic ...

Paige Releases PRISM2: A Whole-Slide Foundation Model for Multimodal AI ...
Advertisement Space (336x280)
Demystifying Vision Language Models (VLMs): The Core of Multimodal AI

A Comprehensive Guide to Vision Language Models (VLMs)

Multimodal & Foundation Vision AI

(PDF) A multimodal whole-slide foundation model for pathology

Multimodal & Foundation Vision AI
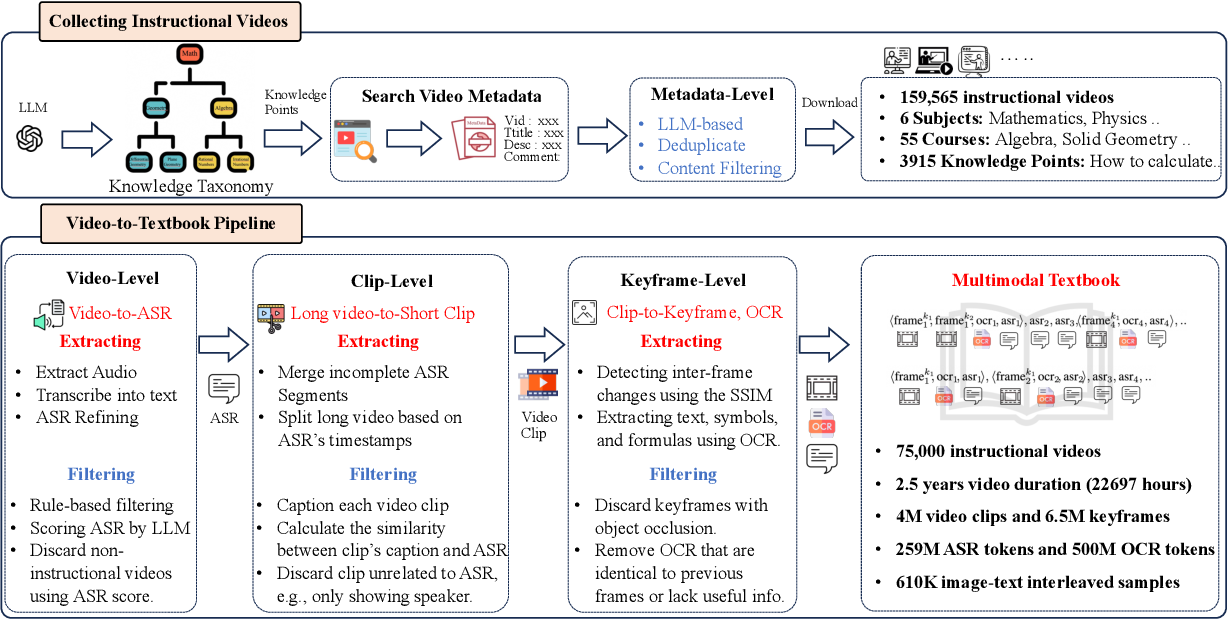
Figure 2 from 2.5 Years in Class: A Multimodal Textbook for Vision ...
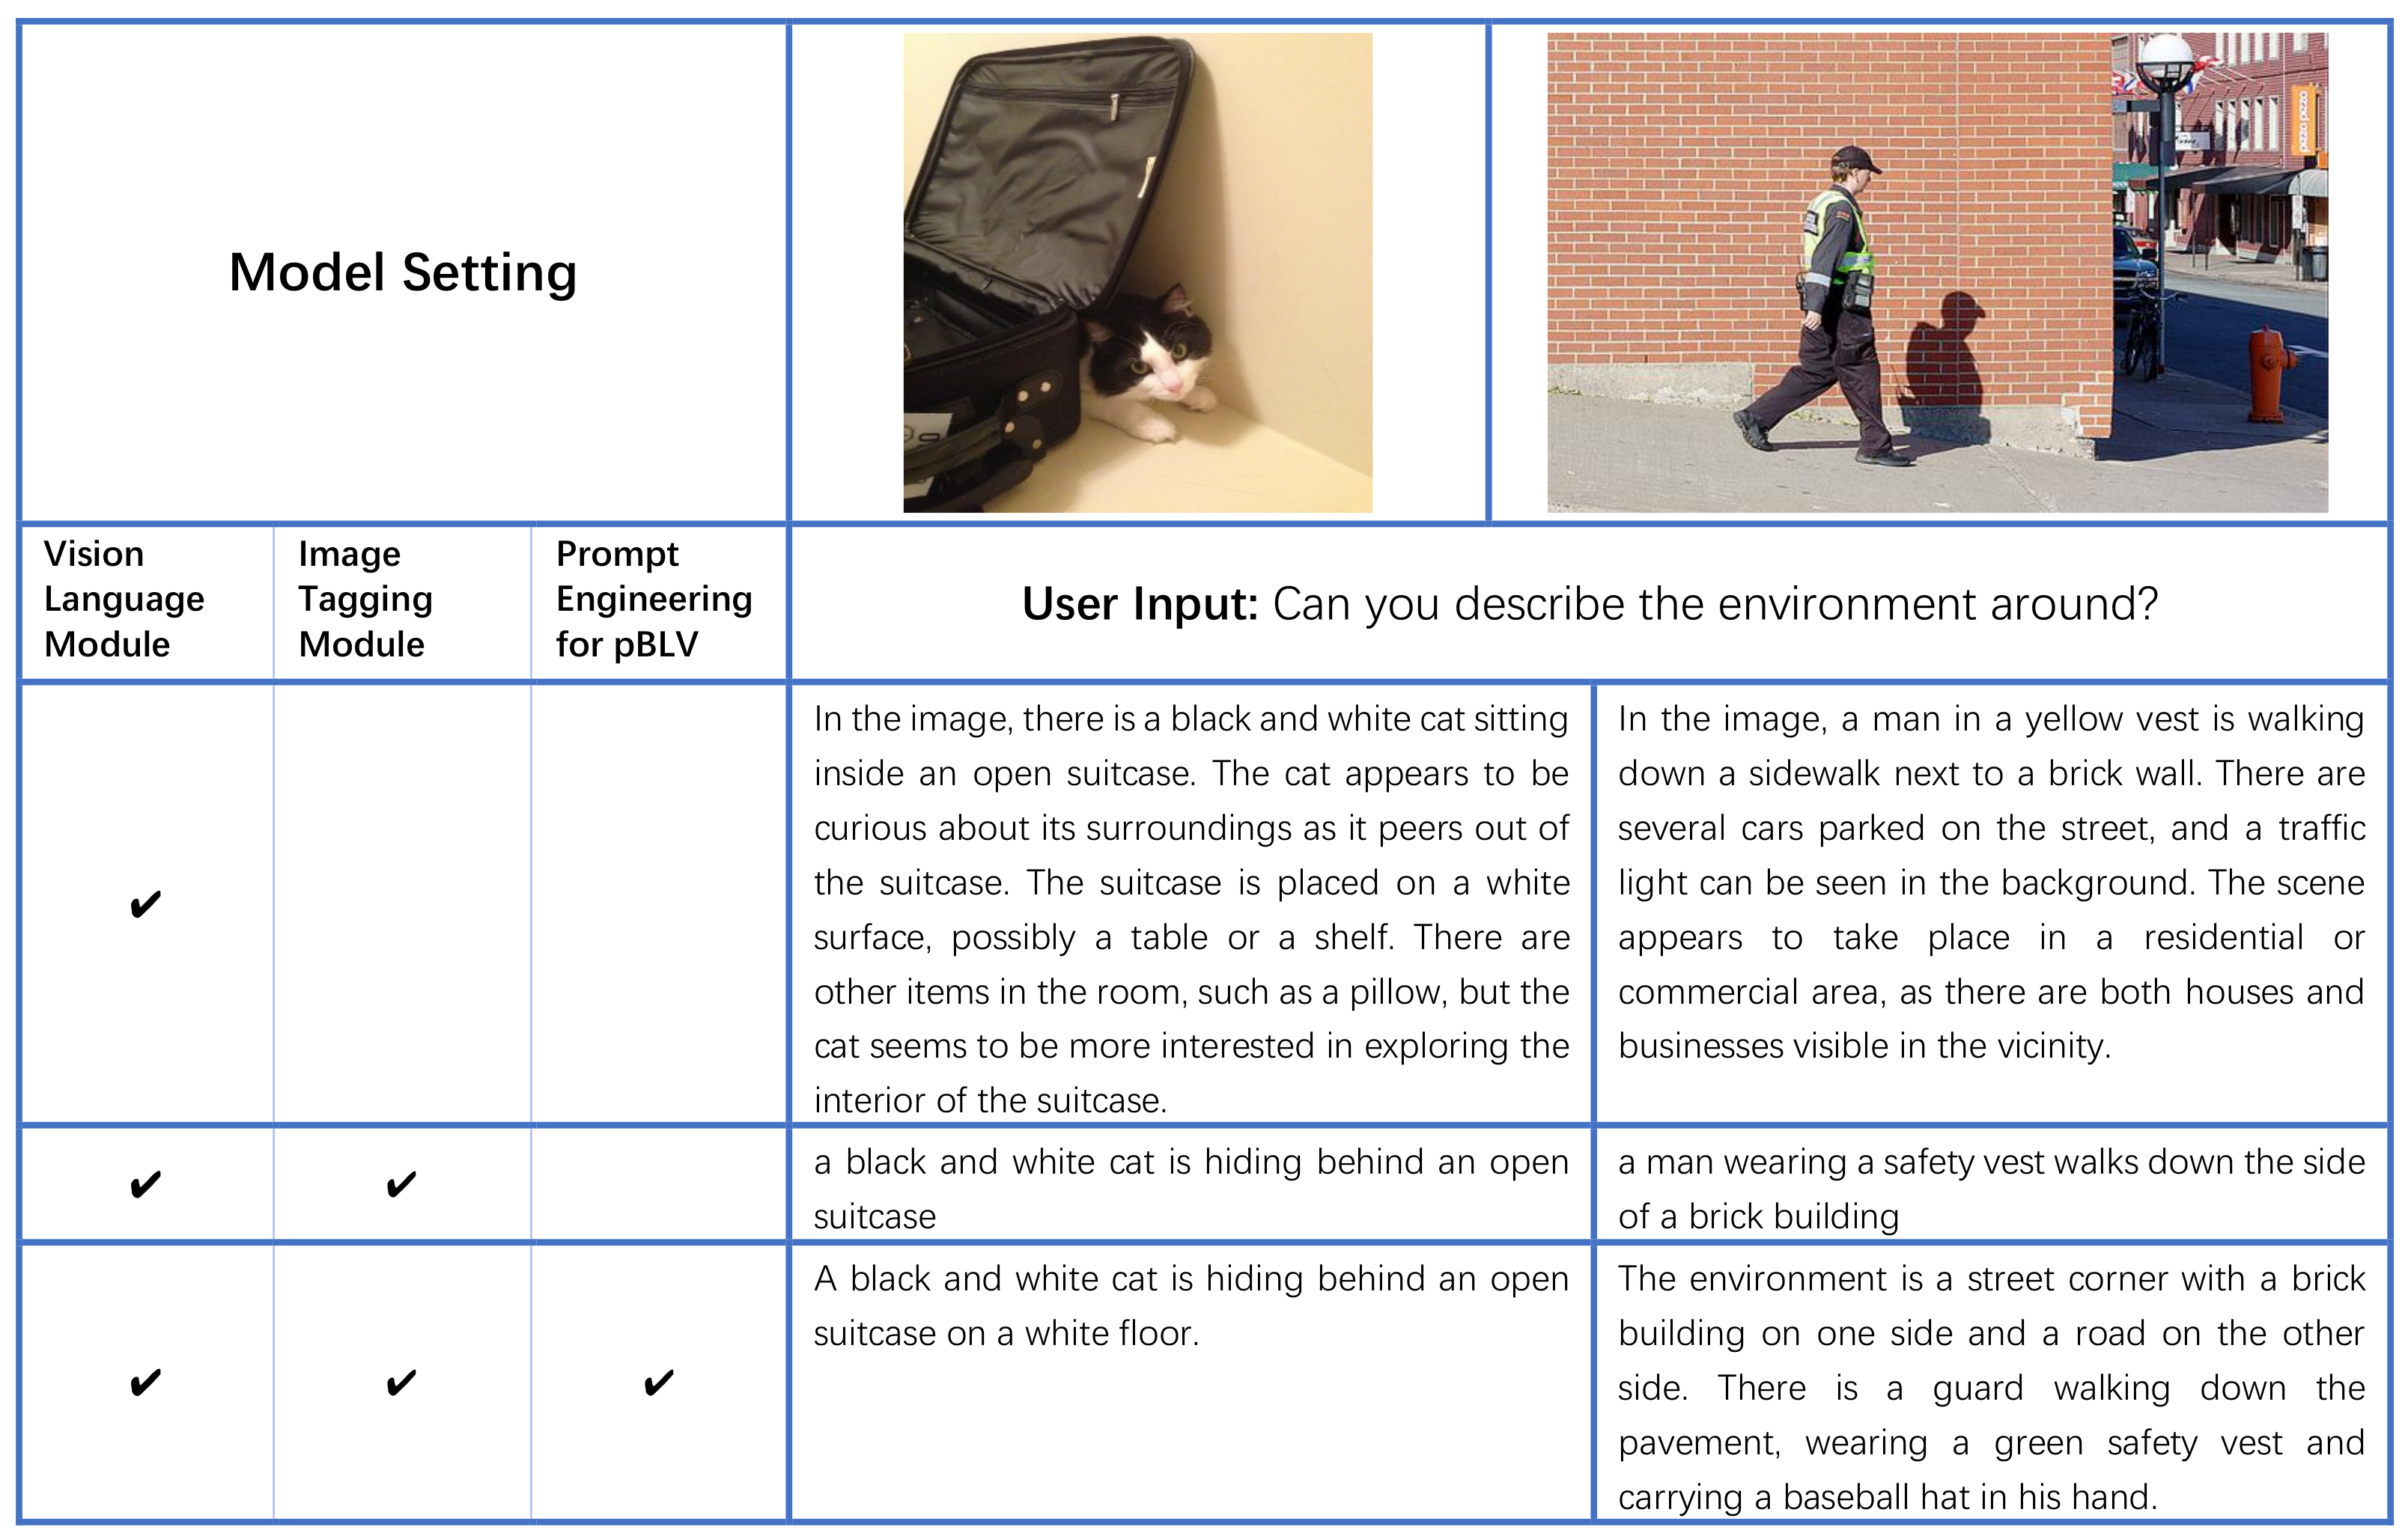
A Multi-Modal Foundation Model to Assist People with Blindness and Low ...

Multimodal & Foundation Vision AI

[论文评述] Show and Guide: Instructional-Plan Grounded Vision and Language ...

A Multi-Modal Foundation Model to Assist People with Blindness and Low ...
Advertisement Space (336x280)
Demystifying Vision Language Models for Multimodal Tasks | Dev News
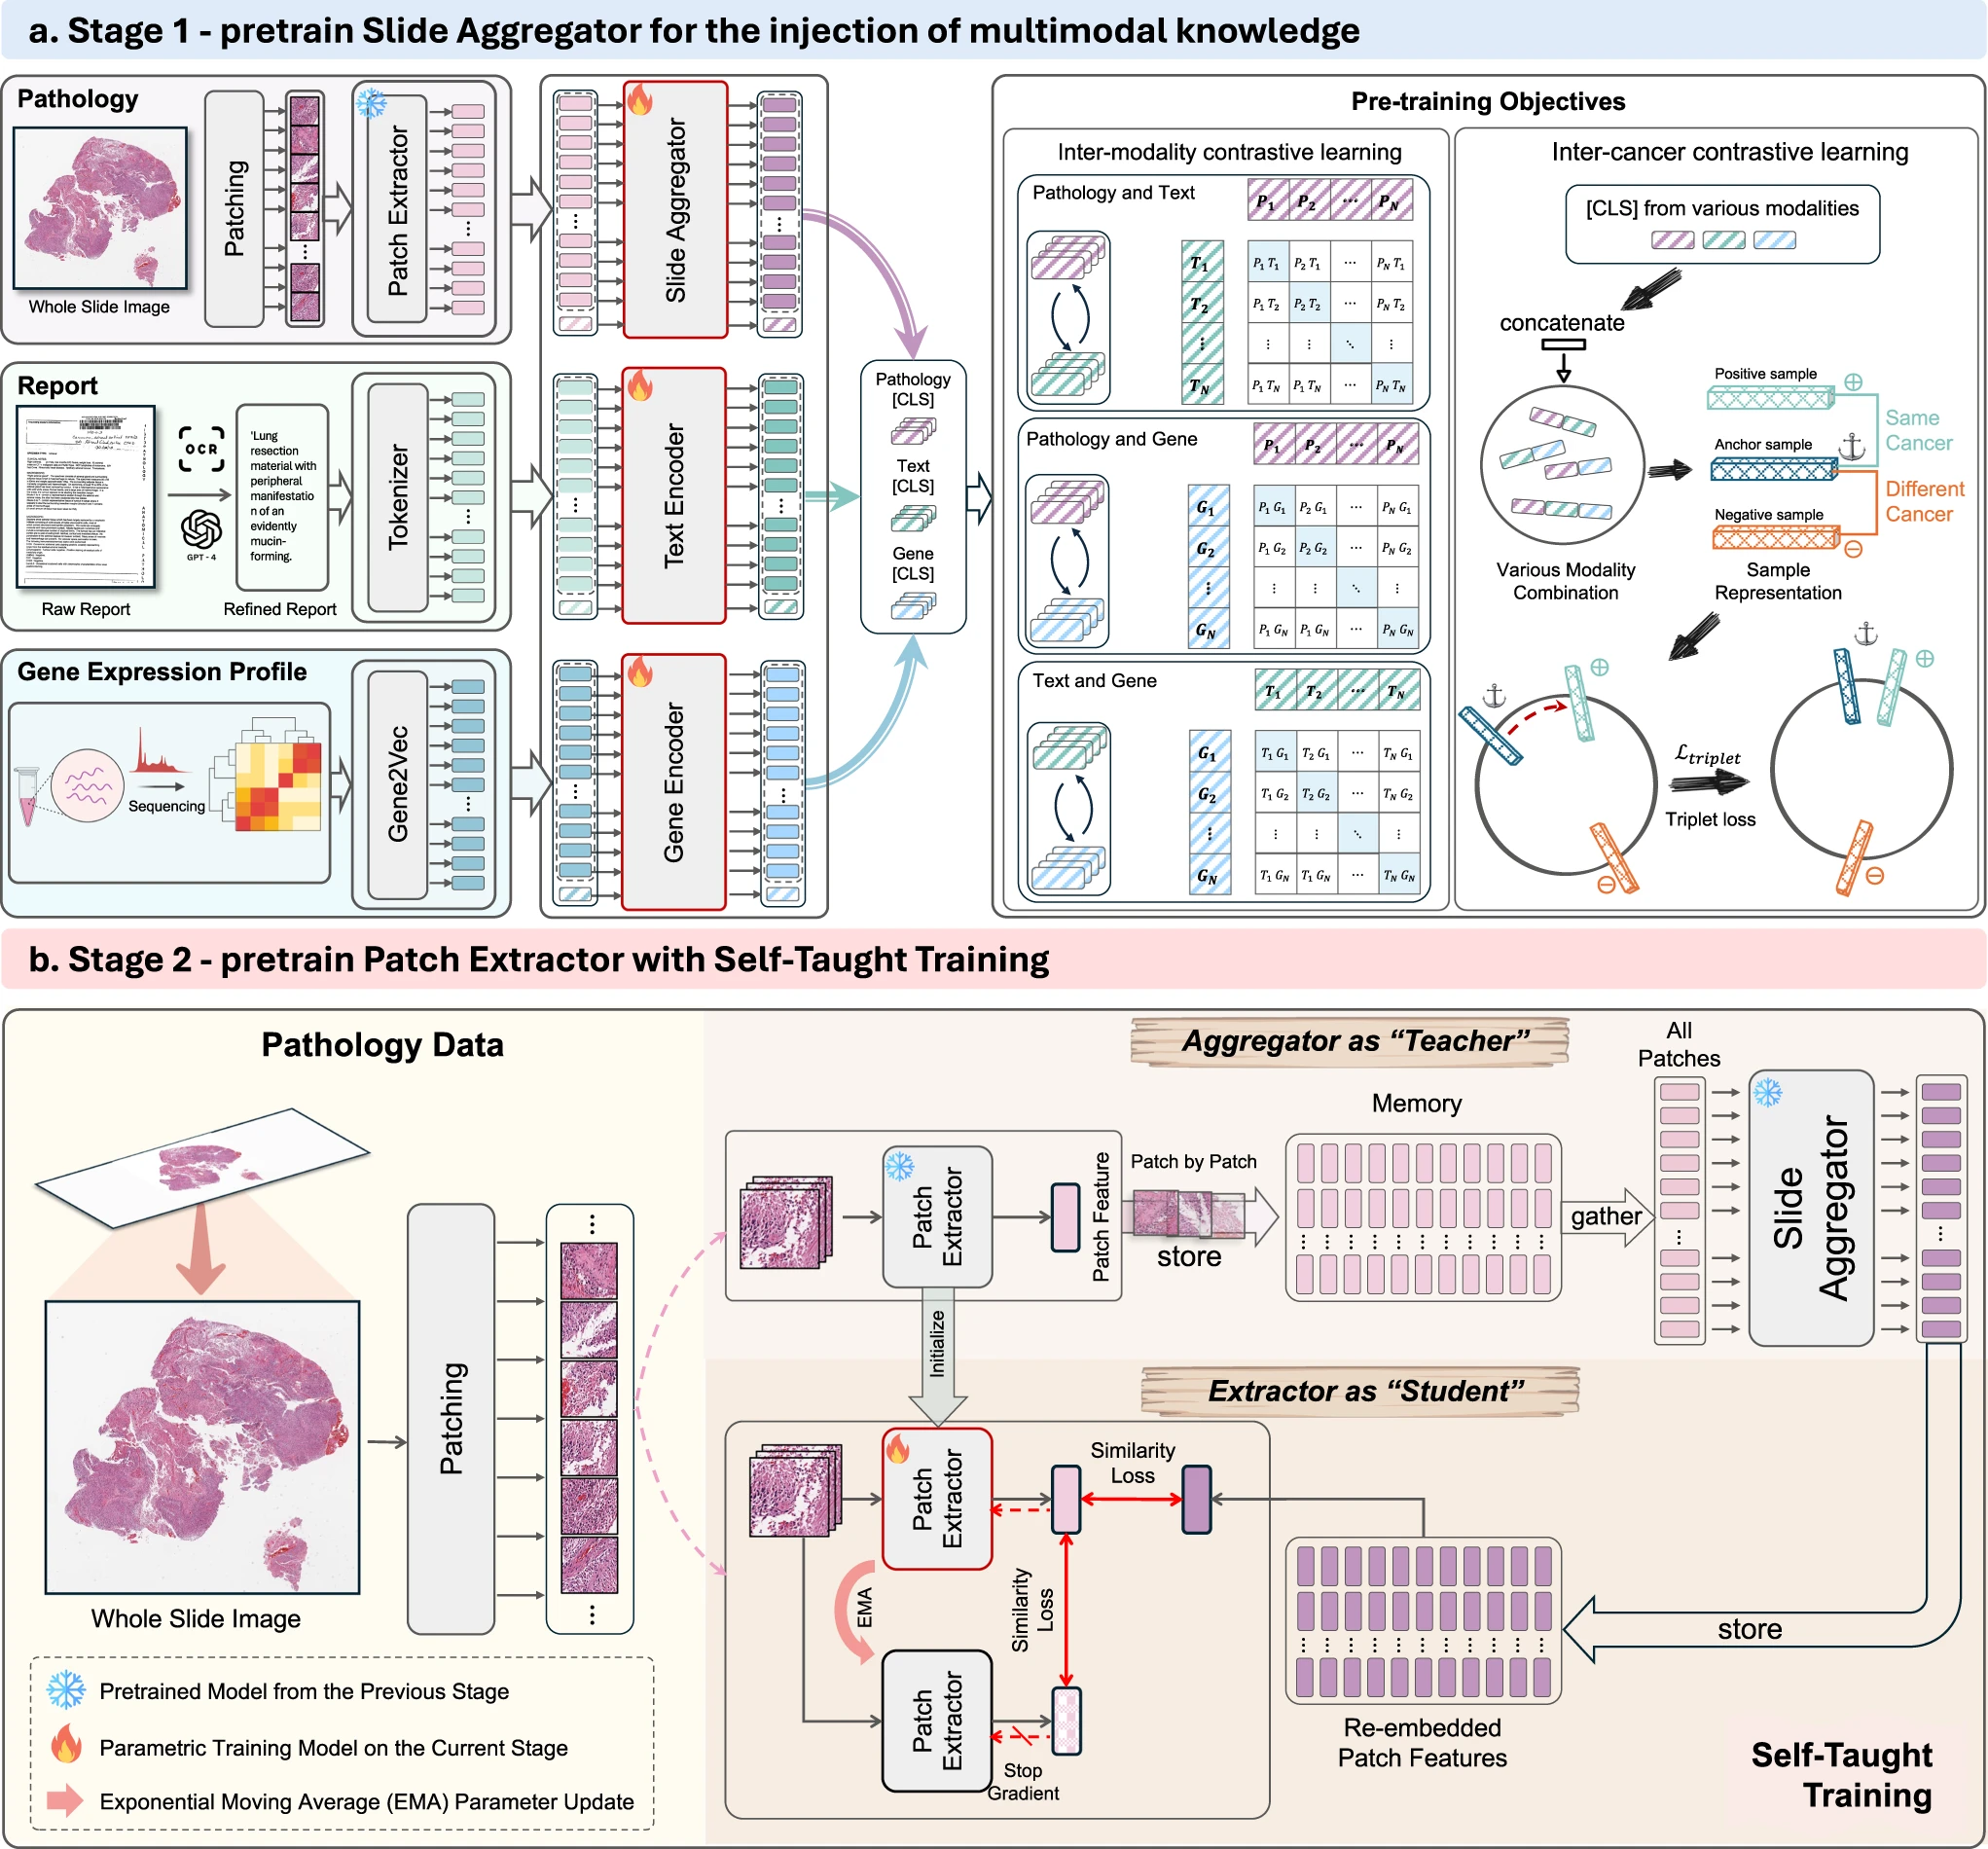
A Multimodal Knowledge-enhanced Whole-slide Pathology Foundation Model ...
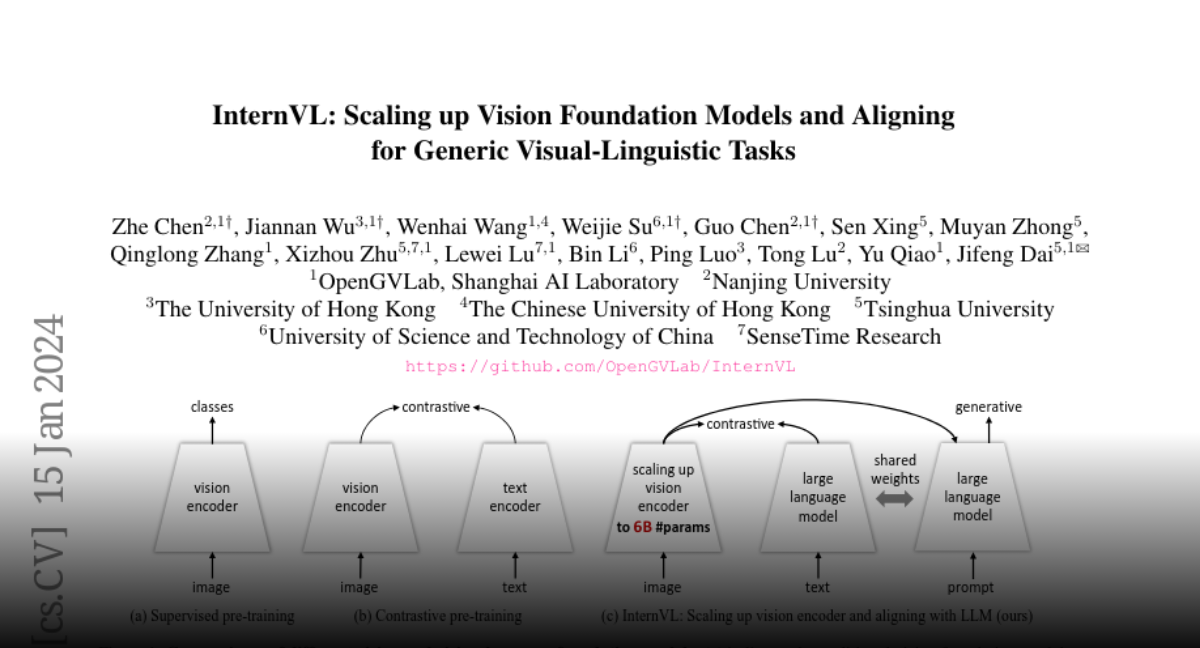
Paper page - InternVL: Scaling up Vision Foundation Models and Aligning ...

GitHub - rickliang-JY/Capstone-Test-TITAN: Multimodal Whole Slide ...

[Nat Med 2025]A multimodal vision foundation model for clinical ...

Show and Guide: Instructional-Plan Grounded Vision and Language Model ...