
Chatglm3 With Triton Inference Server Bad Request Issue 3200
chatglm3 with Triton Inference Server bad request · Issue #3200 ...
Unable to load model.plan in triton inference server · Issue #6059 ...
Triton Inference Server Deploy Problem · Issue #18092 · ultralytics ...
HTTP 400: Bad Request on all HTTP endpoints · Issue #5555 · triton ...
Triton request fails with "Failed to categorical encode column" · Issue ...

Triton Inference Server Inference Request Error on GPU - Jetson Nano ...

Triton Inference Server Inference Request Error on GPU - Jetson Nano ...

Triton Inference Server Inference Request Error on GPU - Jetson Nano ...
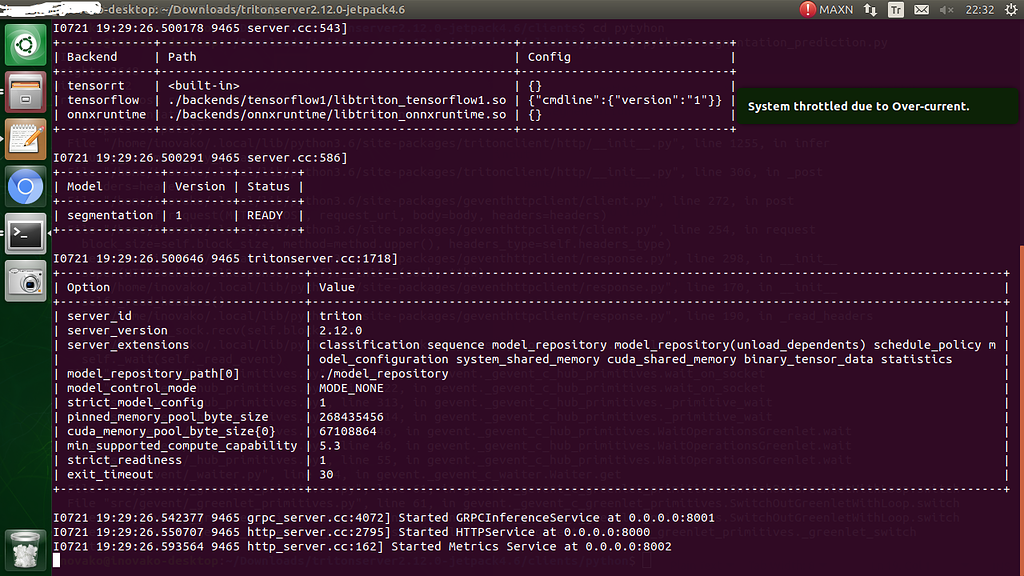
Triton Inference Server Inference Request Error on GPU - Triton ...
Deploy Inference Pipelines with Triton Inference Server and NVIDIA ...
Advertisement Space (300x250)
Feature Request: Llama-2 on Triton Inference Server with TensorRT-LLM ...

Triton inference server with tensorRT, Error code 1 : Cask (Cask ...
Triton Inference server 20.12 start error in Tesla P4. · Issue #2374 ...
Triton Server has performance issues in scenarios with large inputs ...
inference error use triton http client. · Issue #24 · triton-inference ...
Problems when deploying Triton Server according to the readme · Issue ...
Triton Inference Server 23.10 TRT-LLM image missing some libraries to ...
Memory not being released after triton inference - Python · Issue #3758 ...
Trouble sending image data to Triton Server · Issue #2478 · triton ...
How does Triton implement batch inference · Issue #327 · triton ...
Advertisement Space (336x280)
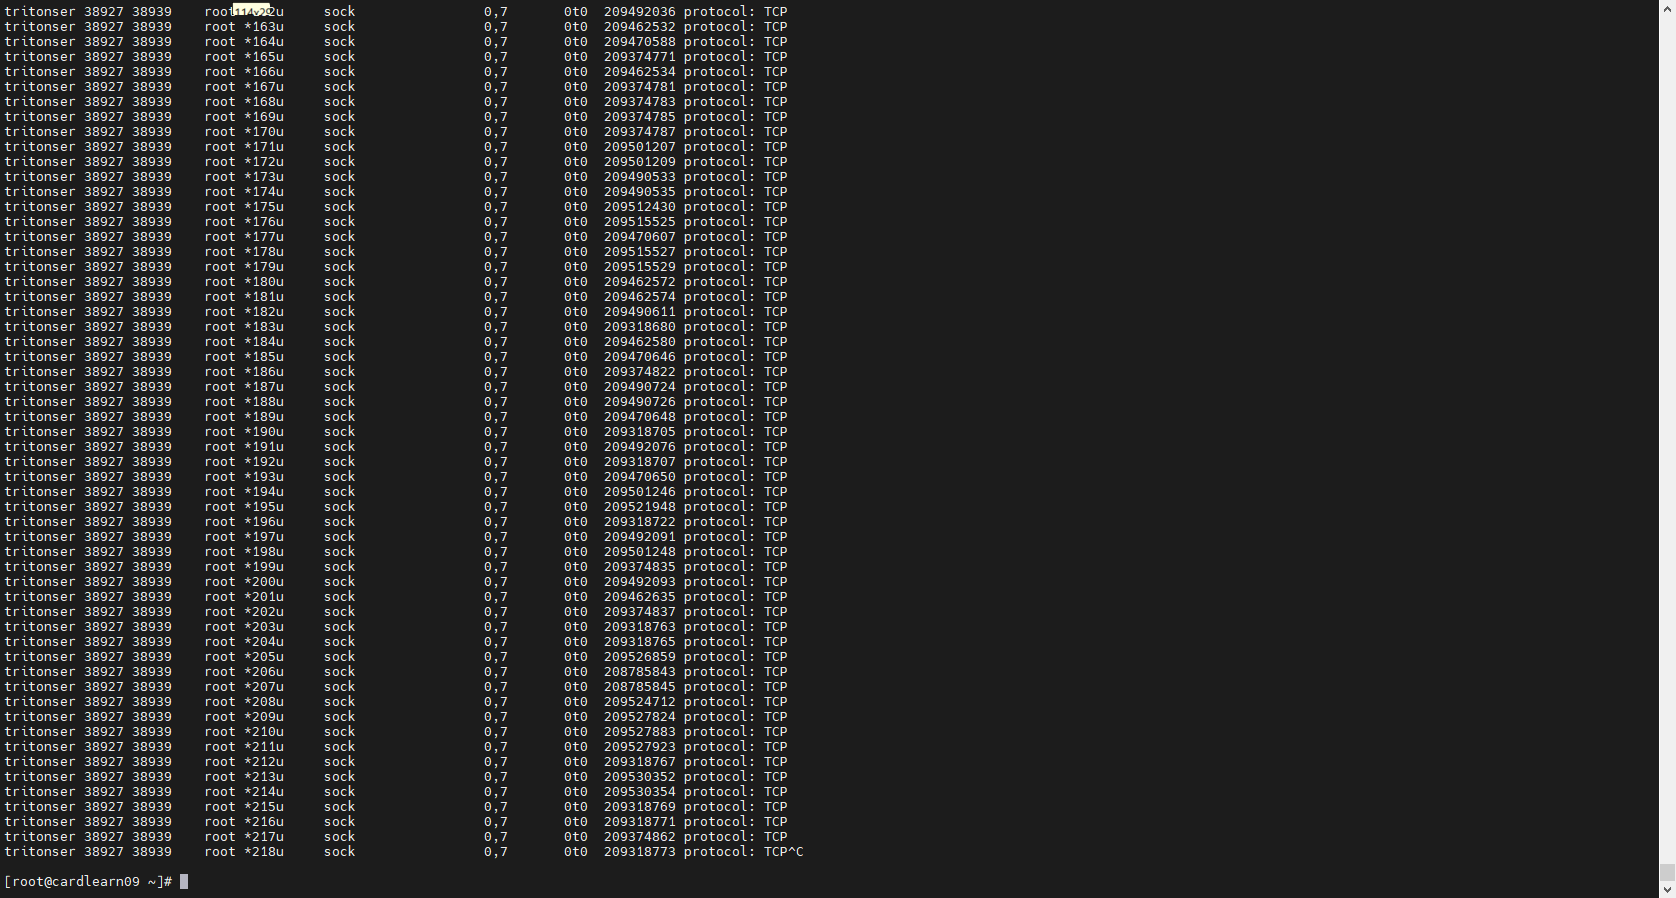
TCP port was full and the triton server could not accept any request ...
Triton Inference Server | Guides | Clore.ai
launch multi-gpu triton server Got Port already in use · Issue #243 ...
Python triton inference – triton inference server – ICDK
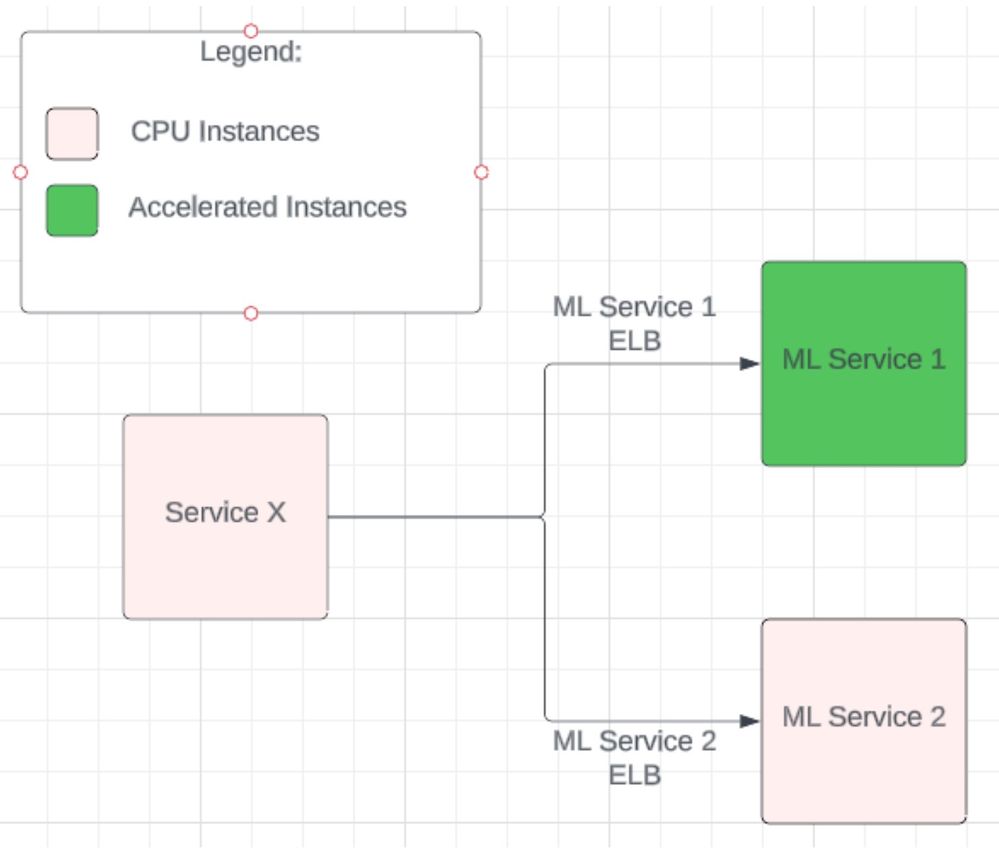
ML inference workloads on the Triton Inference Server | Palo Alto Networks
Performance on triton with python backend · Issue #3274 · triton ...
Triton Inference Server | Grafana Labs
[PyTorch Backend] Triton server consumes too much GPU memory · Issue ...
Triton Server costs too much memory · Issue #5392 · triton-inference ...
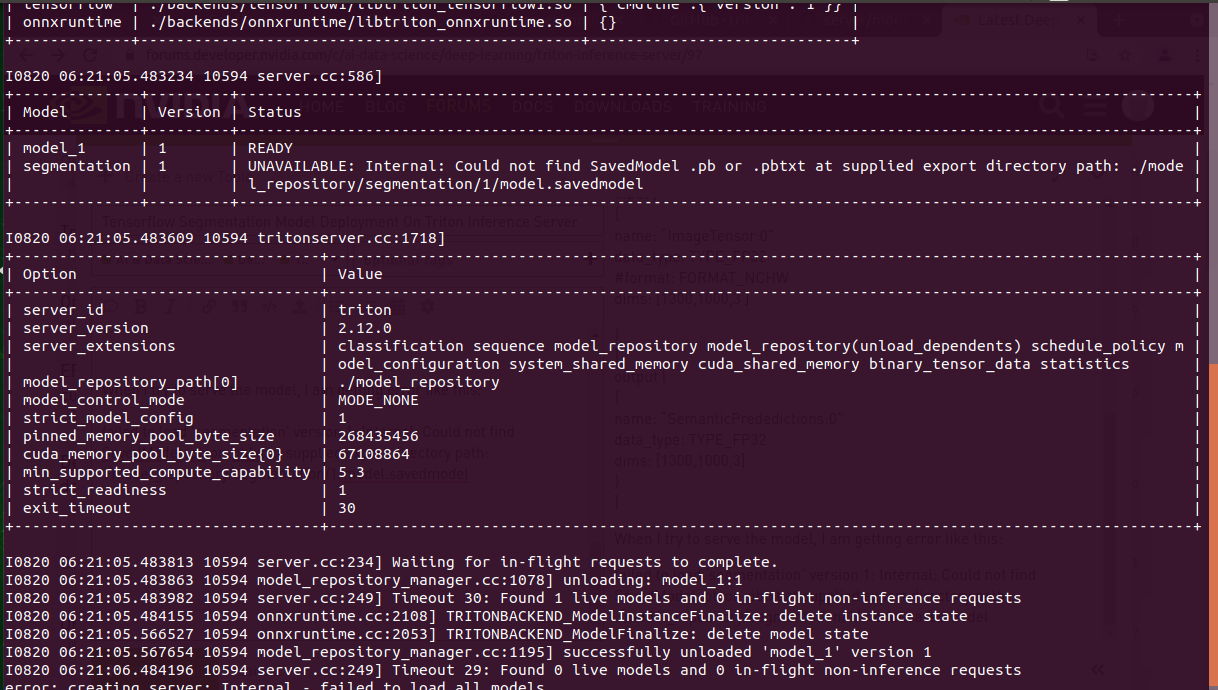
Tensorflow Segmentation Model Deployment On Triton Inference Server ...
Advertisement Space (336x280)

Triton Inference Server Ensemble Lost Intermediate Output - Forum ...
Error occurs when i run the triton server with docker(Quick start ...
[BUG] Triton Server with Kaldi Backend does not return final response ...
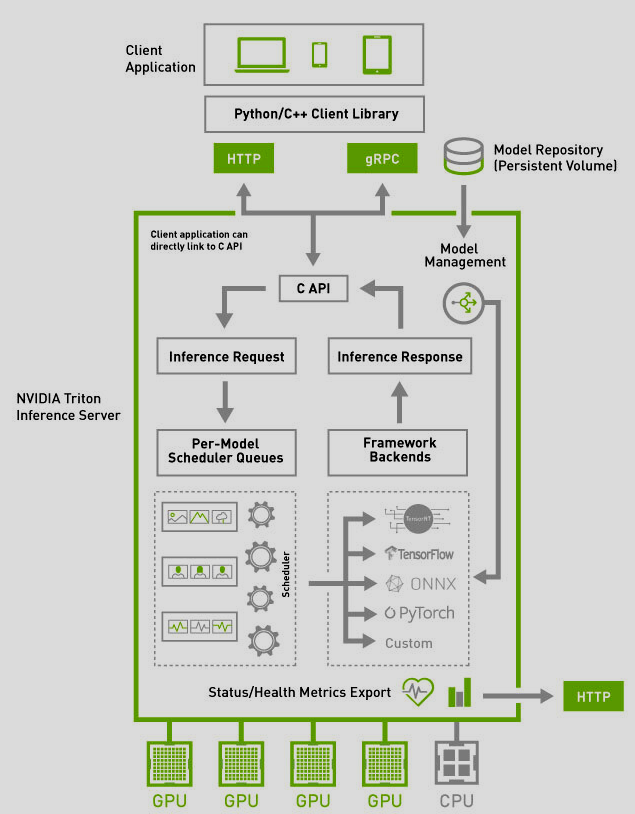
Tổng quan về Triton Inference Server

ML inference workloads on the Triton Inference Server | Palo Alto Networks
Formation Triton Inference Server 2026 - Déployer… | Learni