
Cortex Semantic Knowledge Caching For Low Latency Llm Agents Ai Post
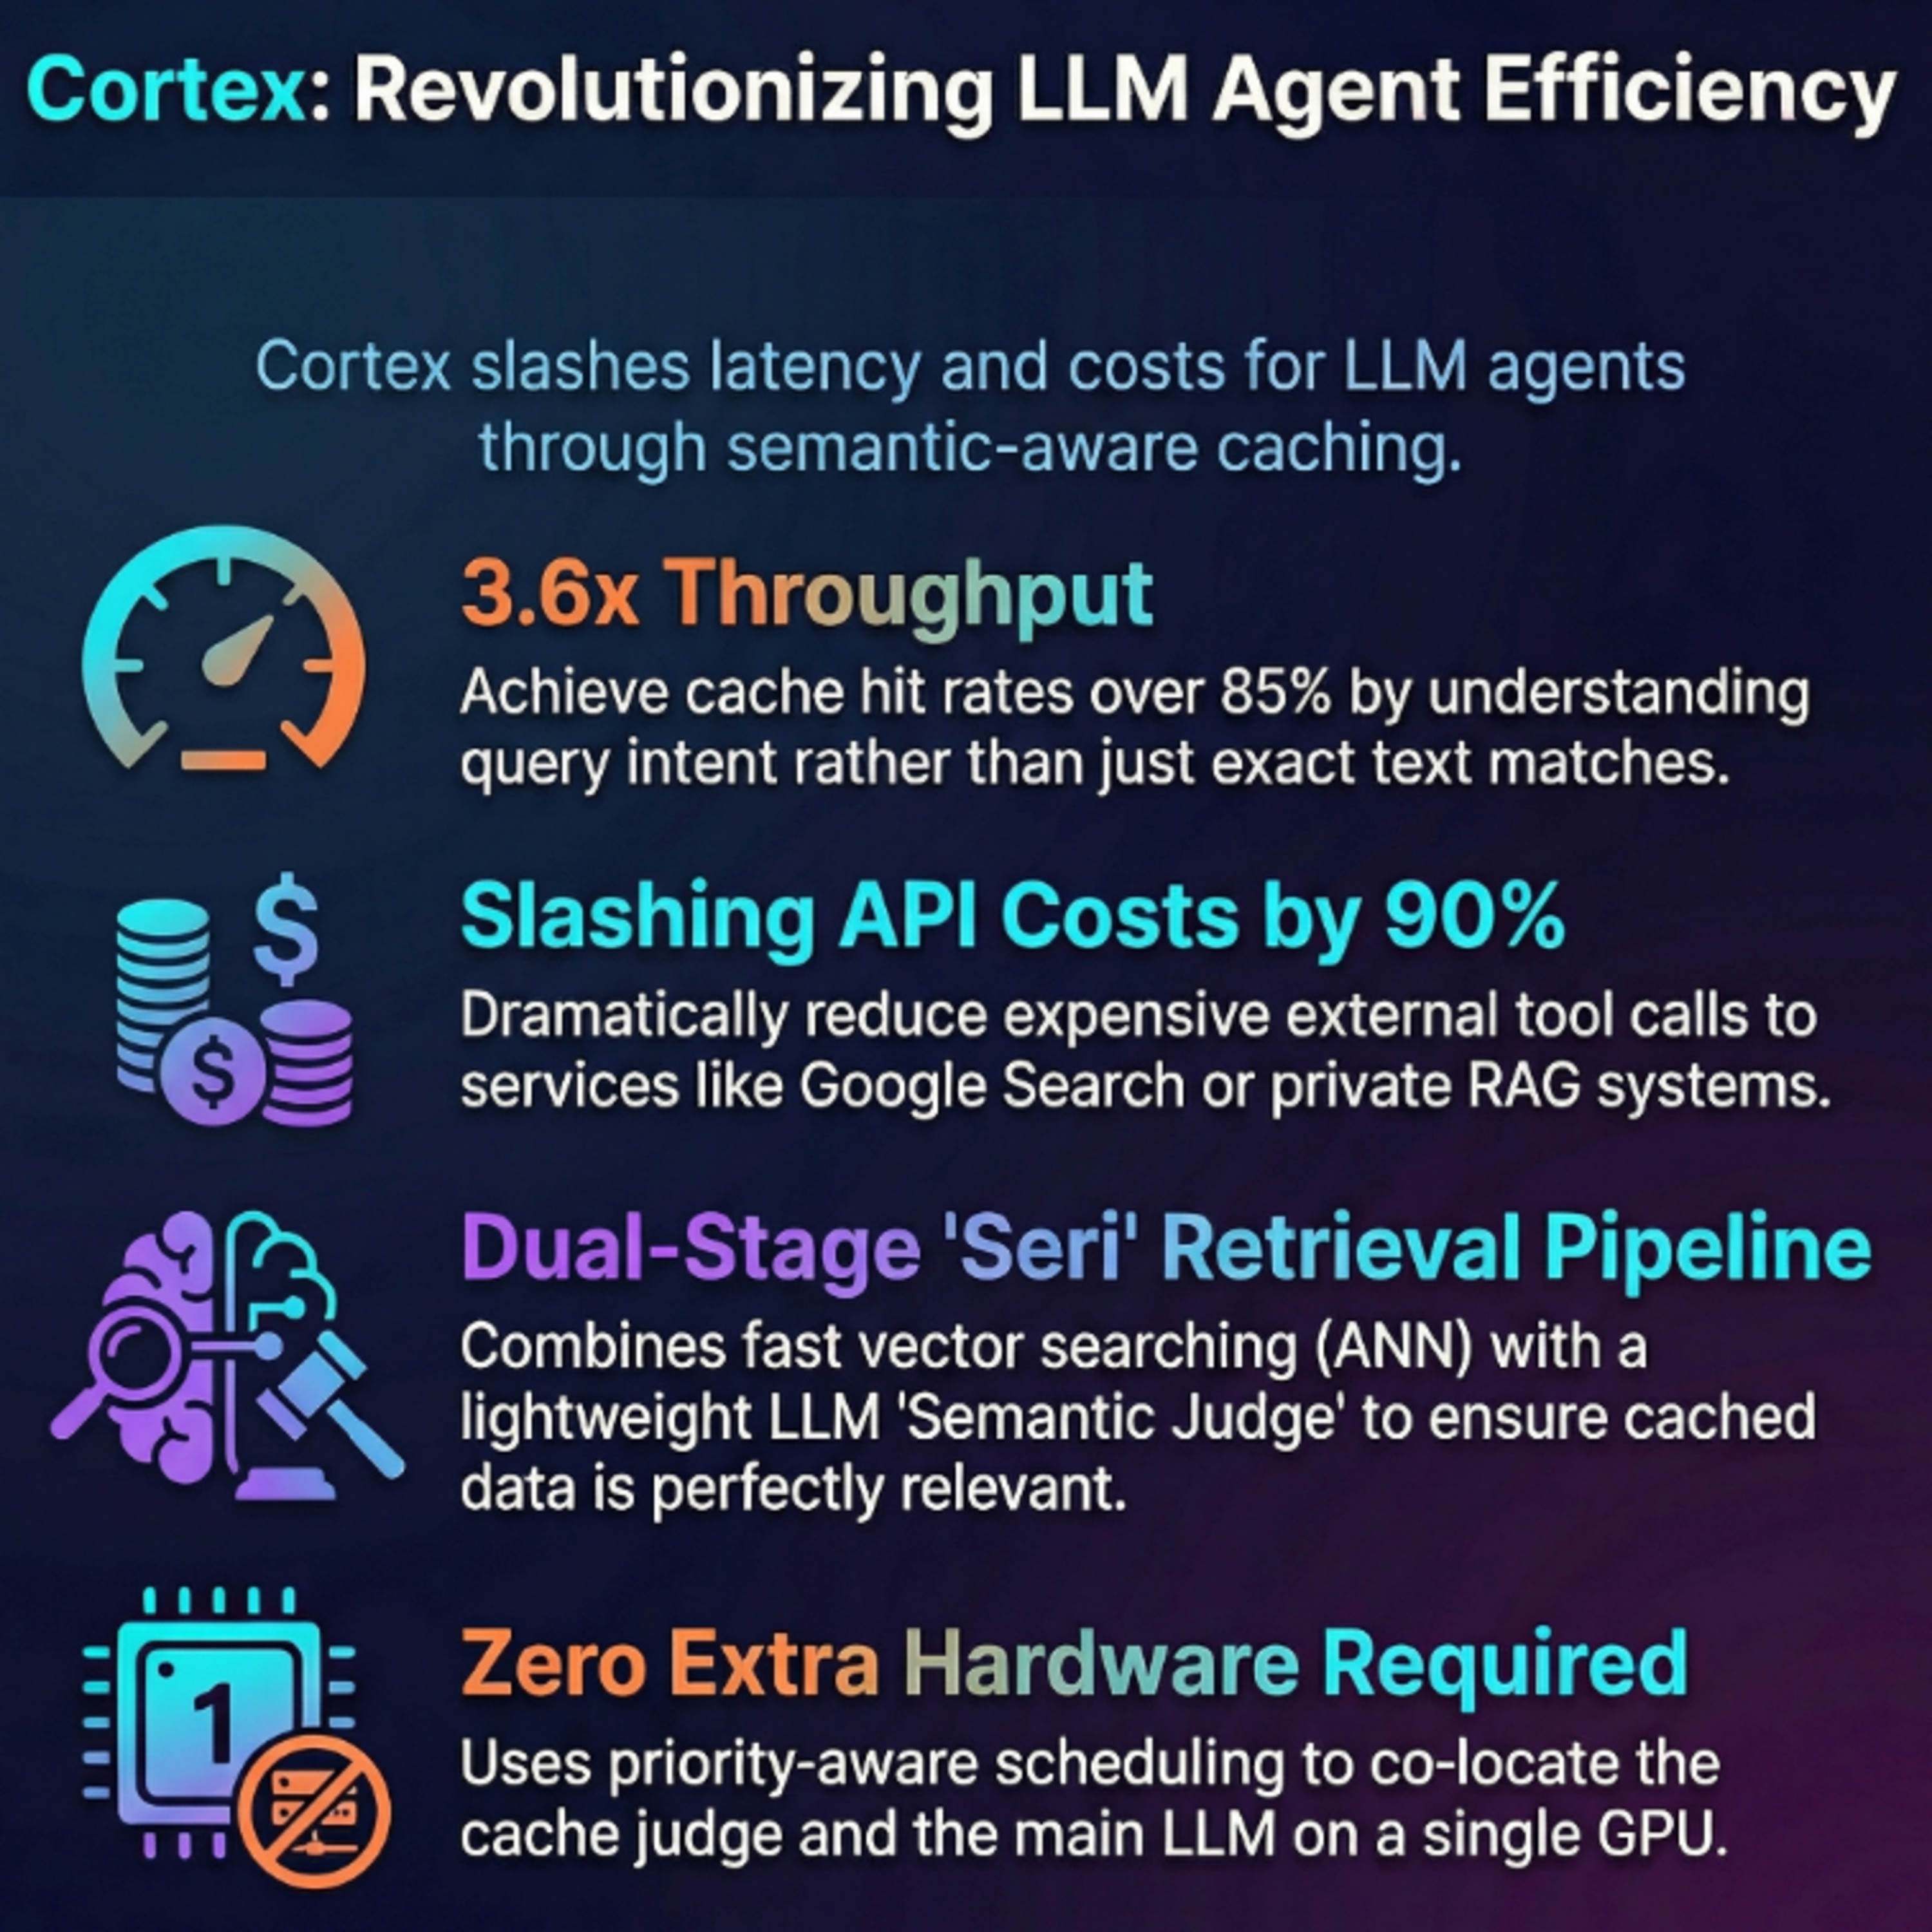
Cortex: Semantic Knowledge Caching for Low-Latency LLM Agents - AI Post ...

Semantic Caching for AI Agents Explained | by @pramodchandrayan ...

Semantic caching for AI Agents

Semantic Caching for AI Agents: Cut LLM Costs 40-80% in 2026

New course: Semantic Caching for AI Agents | Pulse

Semantic Caching for AI Agents: Cut LLM Costs 40-80% in 2026

Semantic Caching for RAG: Cut LLM Cost and Latency - Qdrant

Semantic Caching for AI Agents: Cut LLM Costs 40-80% in 2026

New course! Enroll in Semantic Caching for AI Agents - News and ...

Figure 1 from Semantic Caching for Low-Cost LLM Serving: From Offline ...
Advertisement Space (300x250)

Semantic Caching in RAG Systems & AI Agents - DEV Community
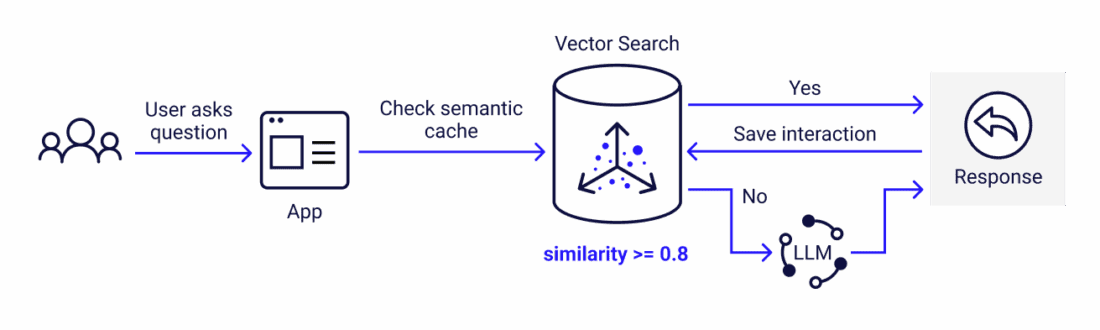
Cut LLM Costs and Latency with ScyllaDB Semantic Caching | ScyllaDB

Cut Your LLM Costs and Latency up to 86% with Semantic Caching ...

[논문 리뷰] Continuous Semantic Caching for Low-Cost LLM Serving

Semantic Caching in RAG Systems & AI Agents - DEV Community

Build Semantic caching for LLM applications
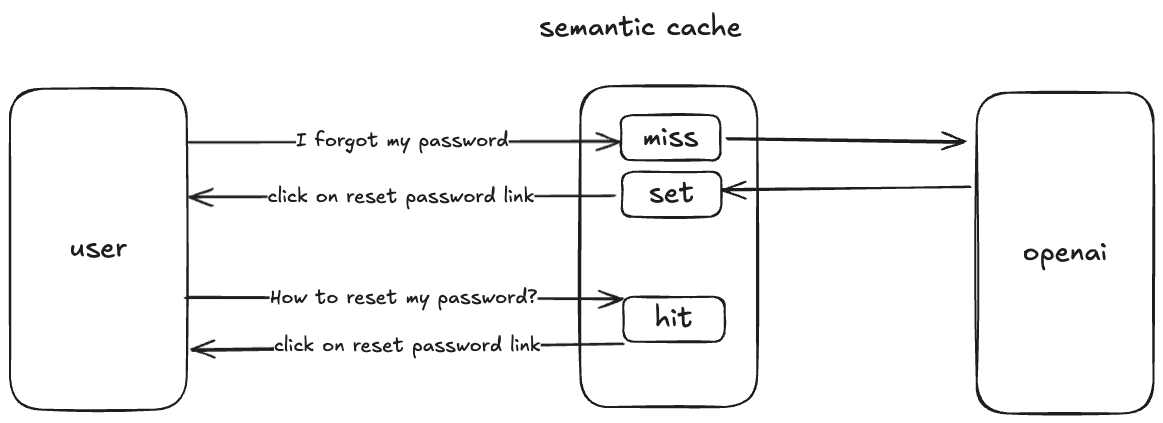
Optimize LLM Applications: Semantic Caching for Speed and Savings ...
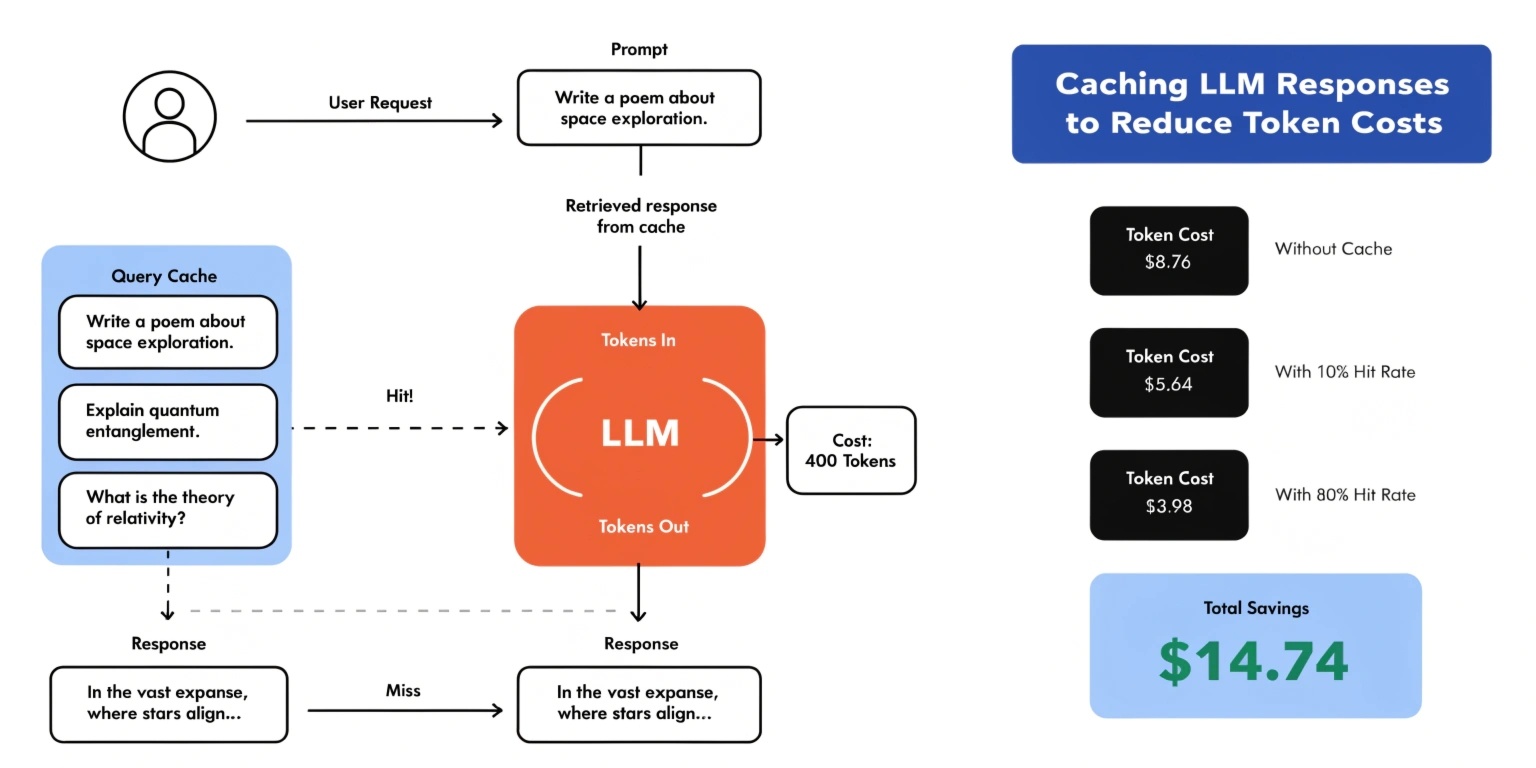
Caching LLM Responses to Reduce Token Costs: A Practical Guide for AI ...

Caching Strategies for LLM Systems: Exact-Match & Semantic Caching ...

AI Safety-First Semantic Caching | LLM Cost Optimization | by kumaran ...
Advertisement Space (336x280)
Boost LLM Performance with Semantic Caching for Speed and Accuracy

Semantic LLM Caching Reduces Cost and Latency in RAG Applications - UBOS

Cut LLM Costs and Latency with ScyllaDB Semantic Caching | ScyllaDB

Semantic Caching in RAG Systems & AI Agents - DEV Community

LLM Architecture for Massive Scale and Low Latency | Prakash Pujari ...

The Beginner’s Guide to Semantic Caching in LLM Systems
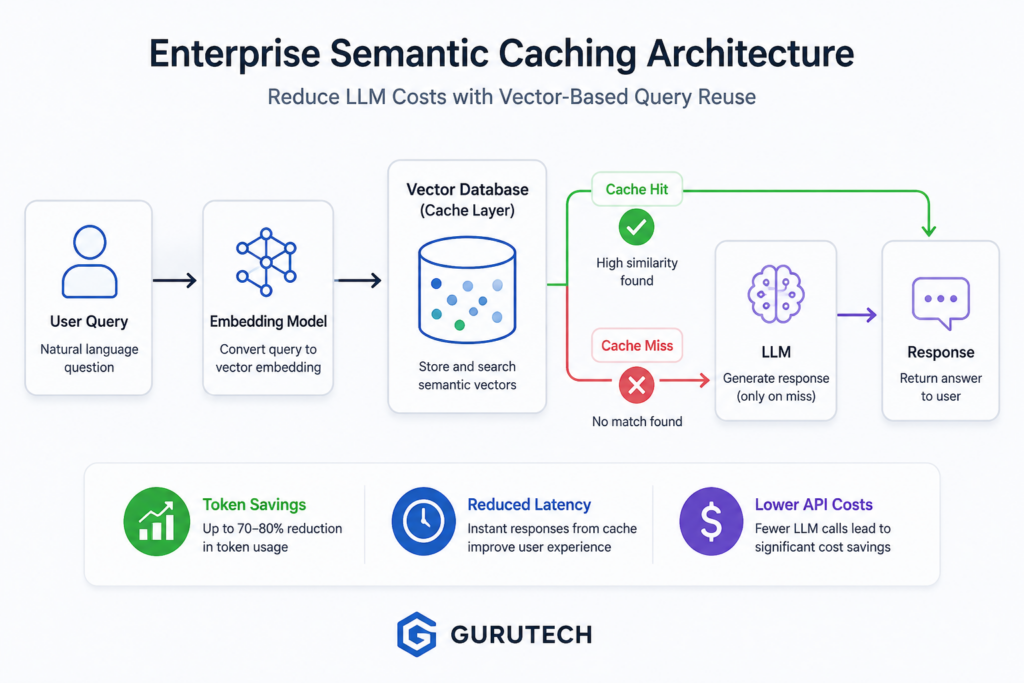
Enterprise Semantic Caching AI: The best Strategy to Reduce LLM Costs ...
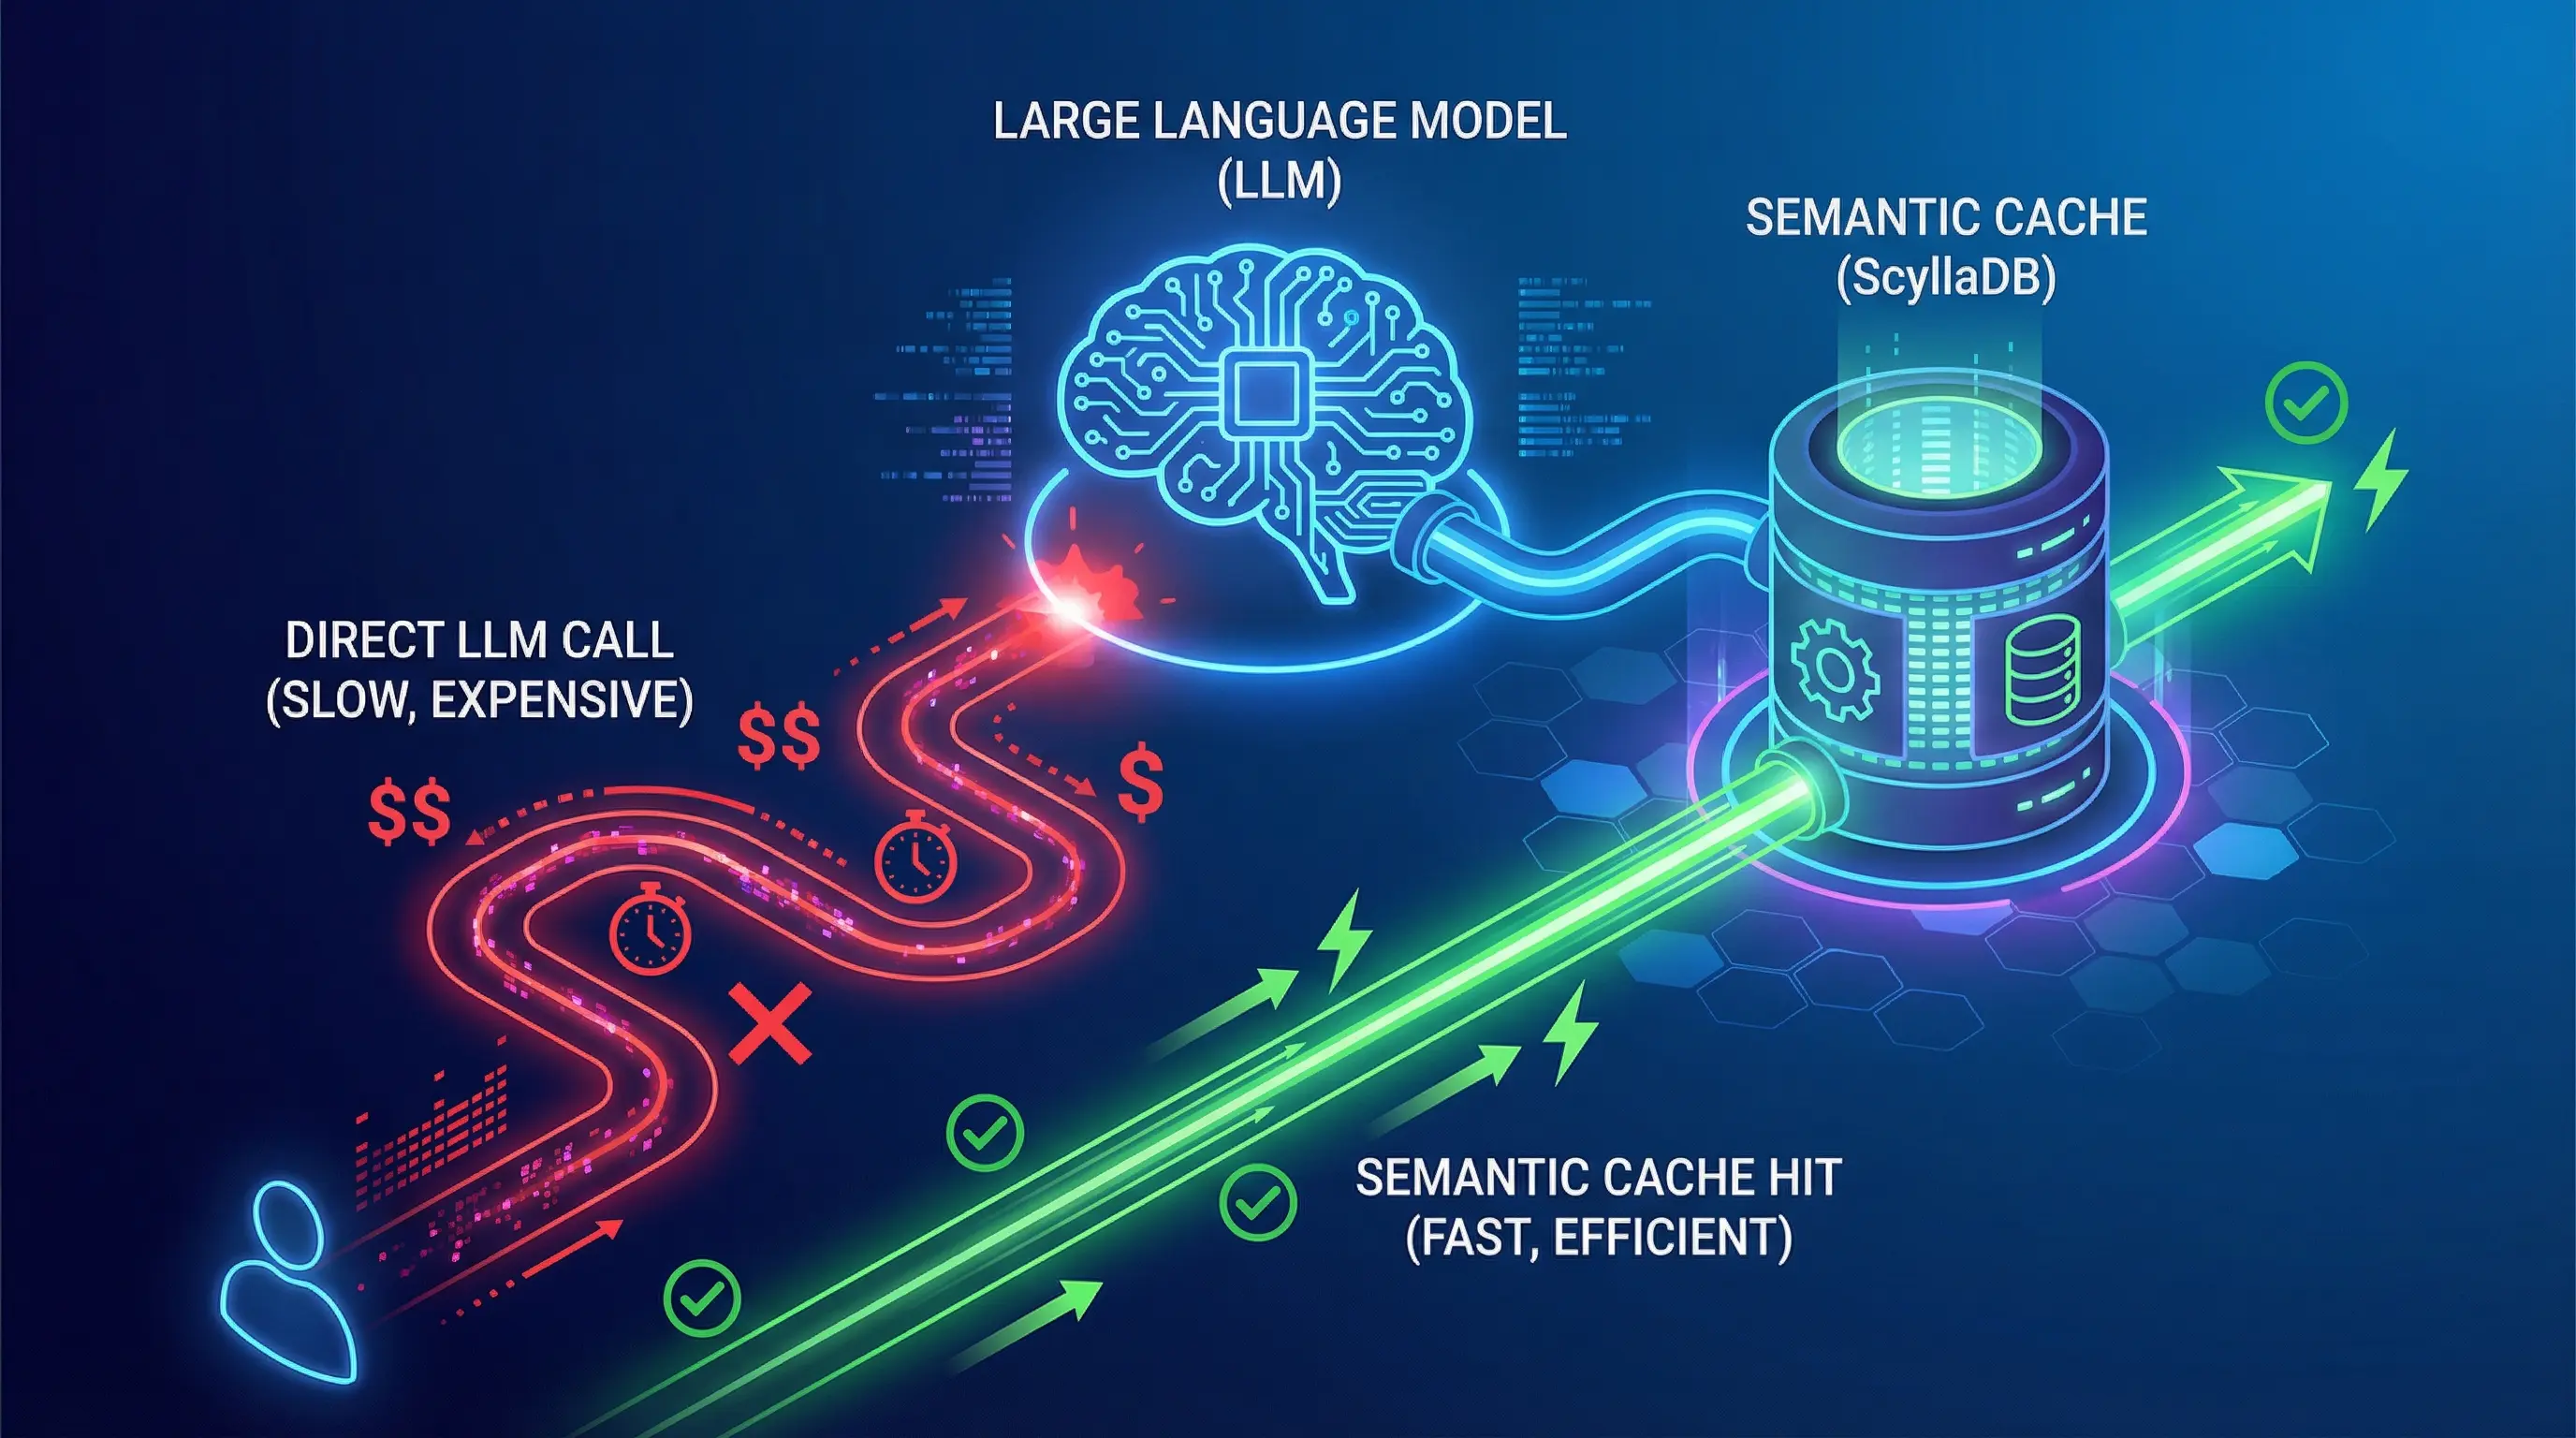
Optimize LLM Costs with ScyllaDB Semantic Caching | TechLife

The Beginner’s Guide to Semantic Caching in LLM Systems
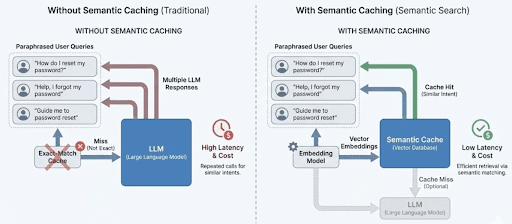
Semantic Caching for LLMs: FastAPI, Redis, and Embeddings - PyImageSearch
Advertisement Space (336x280)
AI Agents in Snowflake for Data Analysis | by Jorge Peñalva | Snowflake ...

The Beginner’s Guide to Semantic Caching in LLM Systems

Giving Your AI Memory That Doesn't Suck: Implementing Semantic Caching ...
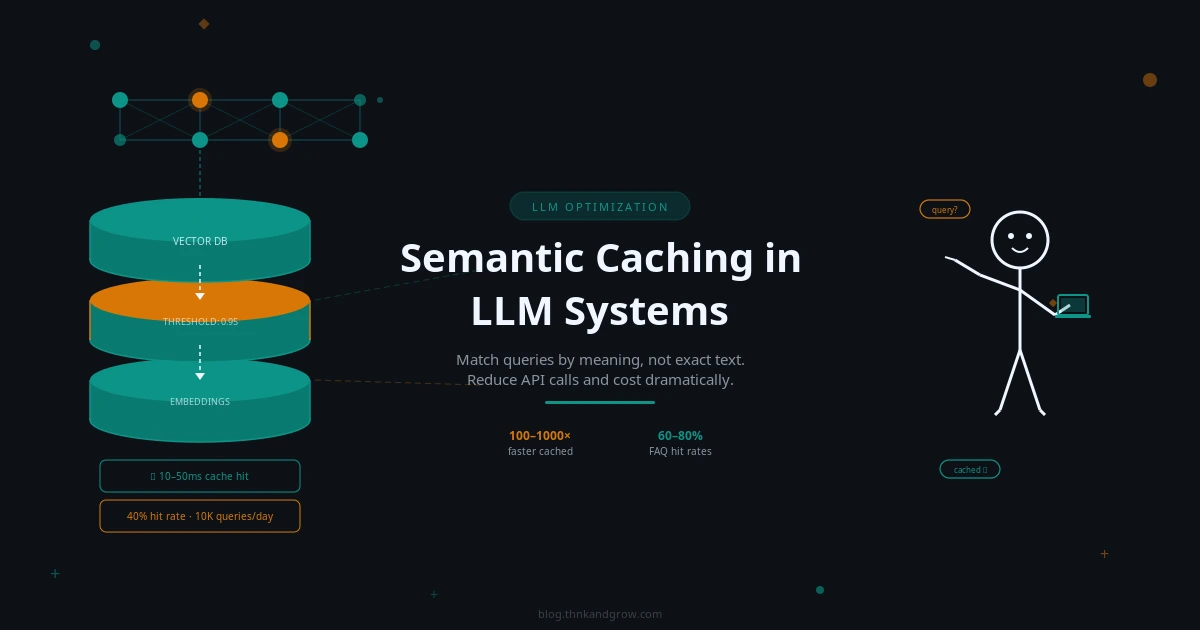
Semantic Caching in LLM Systems: A | Th!nk And Grow

Building an AI Agent with Semantic LLM Caching, AI Guardrails, and ...
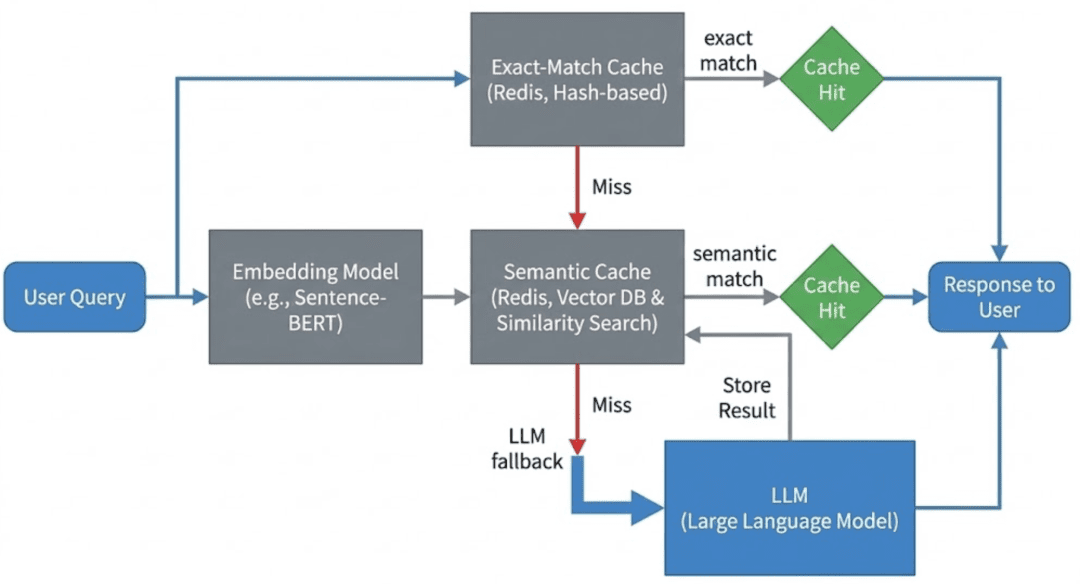
Semantic Caching for LLMs: FastAPI, Redis, and Embeddings - PyImageSearch