
Cuda Graphs In Llm Inference Deep Dive Dev Community

CUDA Graphs in LLM Inference: Deep Dive - DEV Community

Inference Engines - A visual deep dive into the layers of an LLM - DEV ...

KV Cache in LLM Inference - Complete Technical Deep Dive - YouTube

Inference Engines - A visual deep dive into the layers of an LLM - DEV ...

🚀 Deep Dive: CUDA Optimization for LLM & GenAI Inference | by Avivek ...

Julien Simon - Deep Dive - Optimizing LLM Inference | PDF

Deep Dive Into LLM Inference Optimization Techniques | PDF | Cache ...
Accelerate Deep Learning and LLM Inference with Apache Spark in the ...

RTX 5080 Launched, Rust for CUDA, & LLM GPU Scheduling Deep Dive - DEV ...
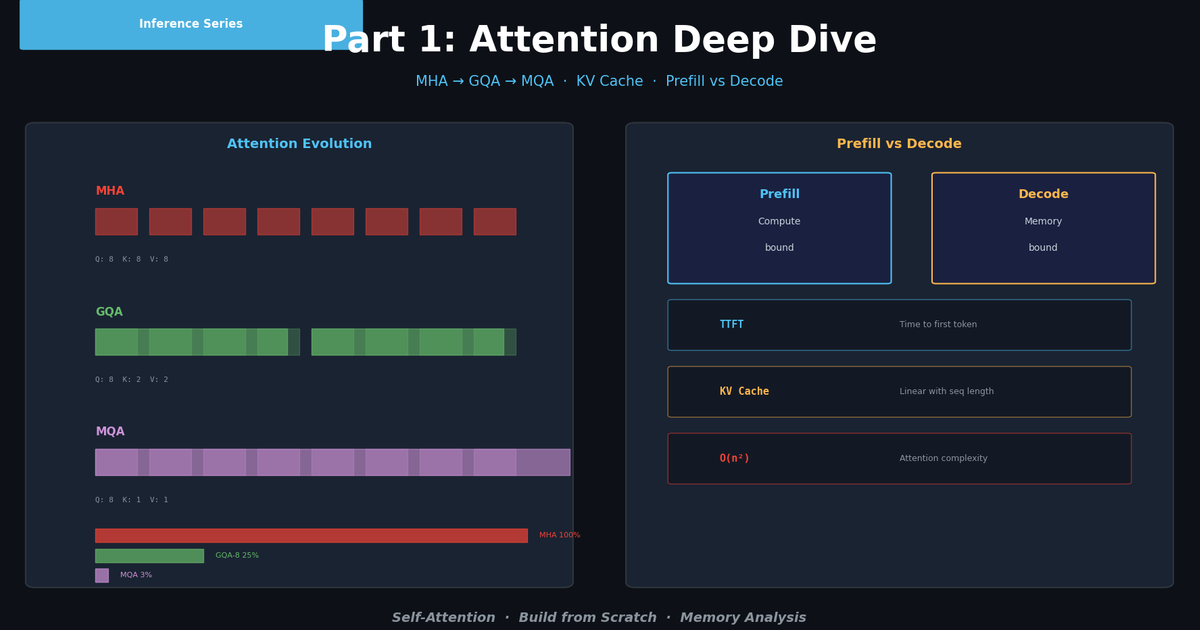
LLM Inference Optimization Part 1 — Attention Mechanism Deep Dive ...
Advertisement Space (300x250)

From KV Caching to PagedAttention: A Deep Dive into GPU Memory in LLM ...

Julien Simon - Deep Dive - Optimizing LLM Inference | PDF
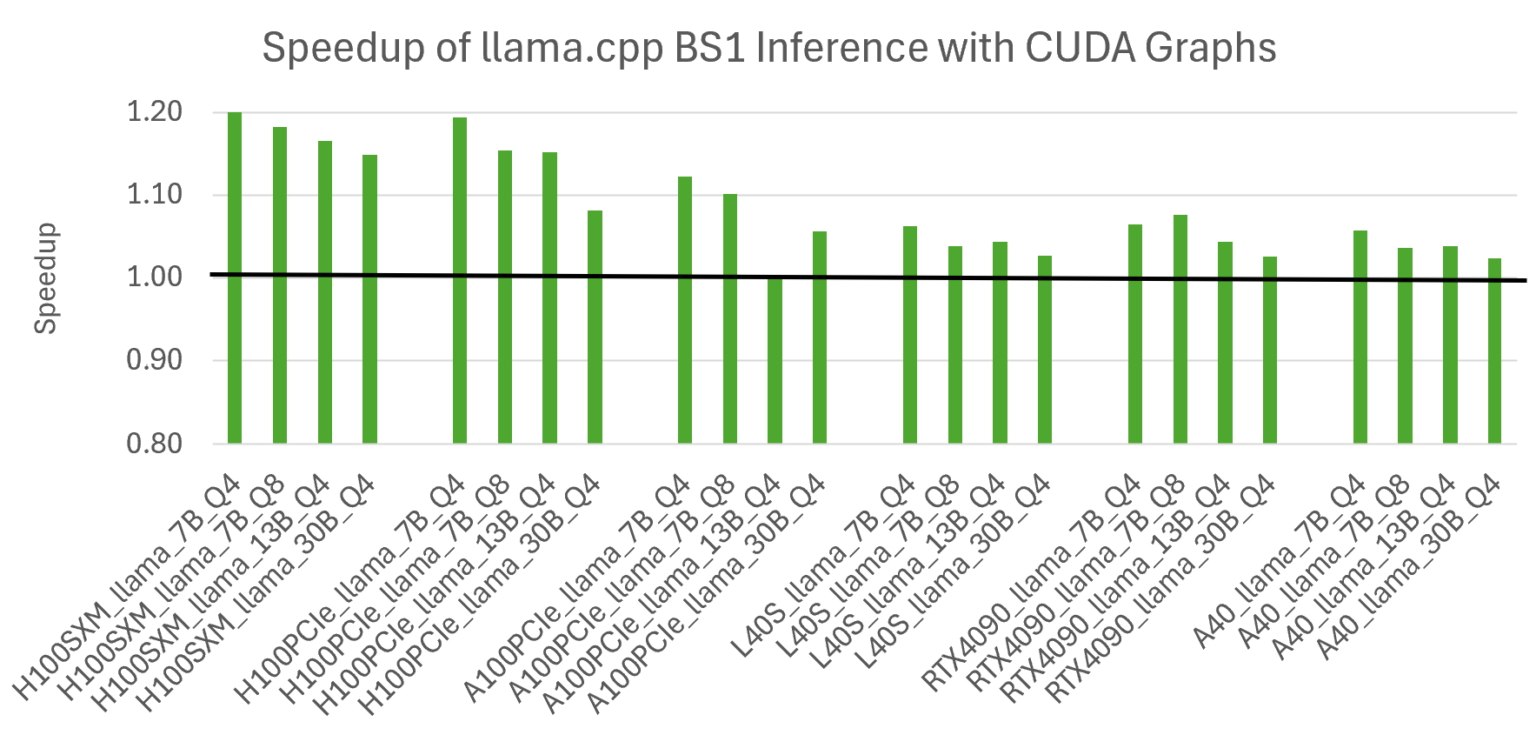
Optimizing llama.cpp AI Inference with CUDA Graphs | NVIDIA Technical Blog
torch.compile and CUDA Graphs for LLM Inference: Production PyTorch 2.6 ...

CUDA Graphs for Inference | NVIDIA/Megatron-LM | DeepWiki
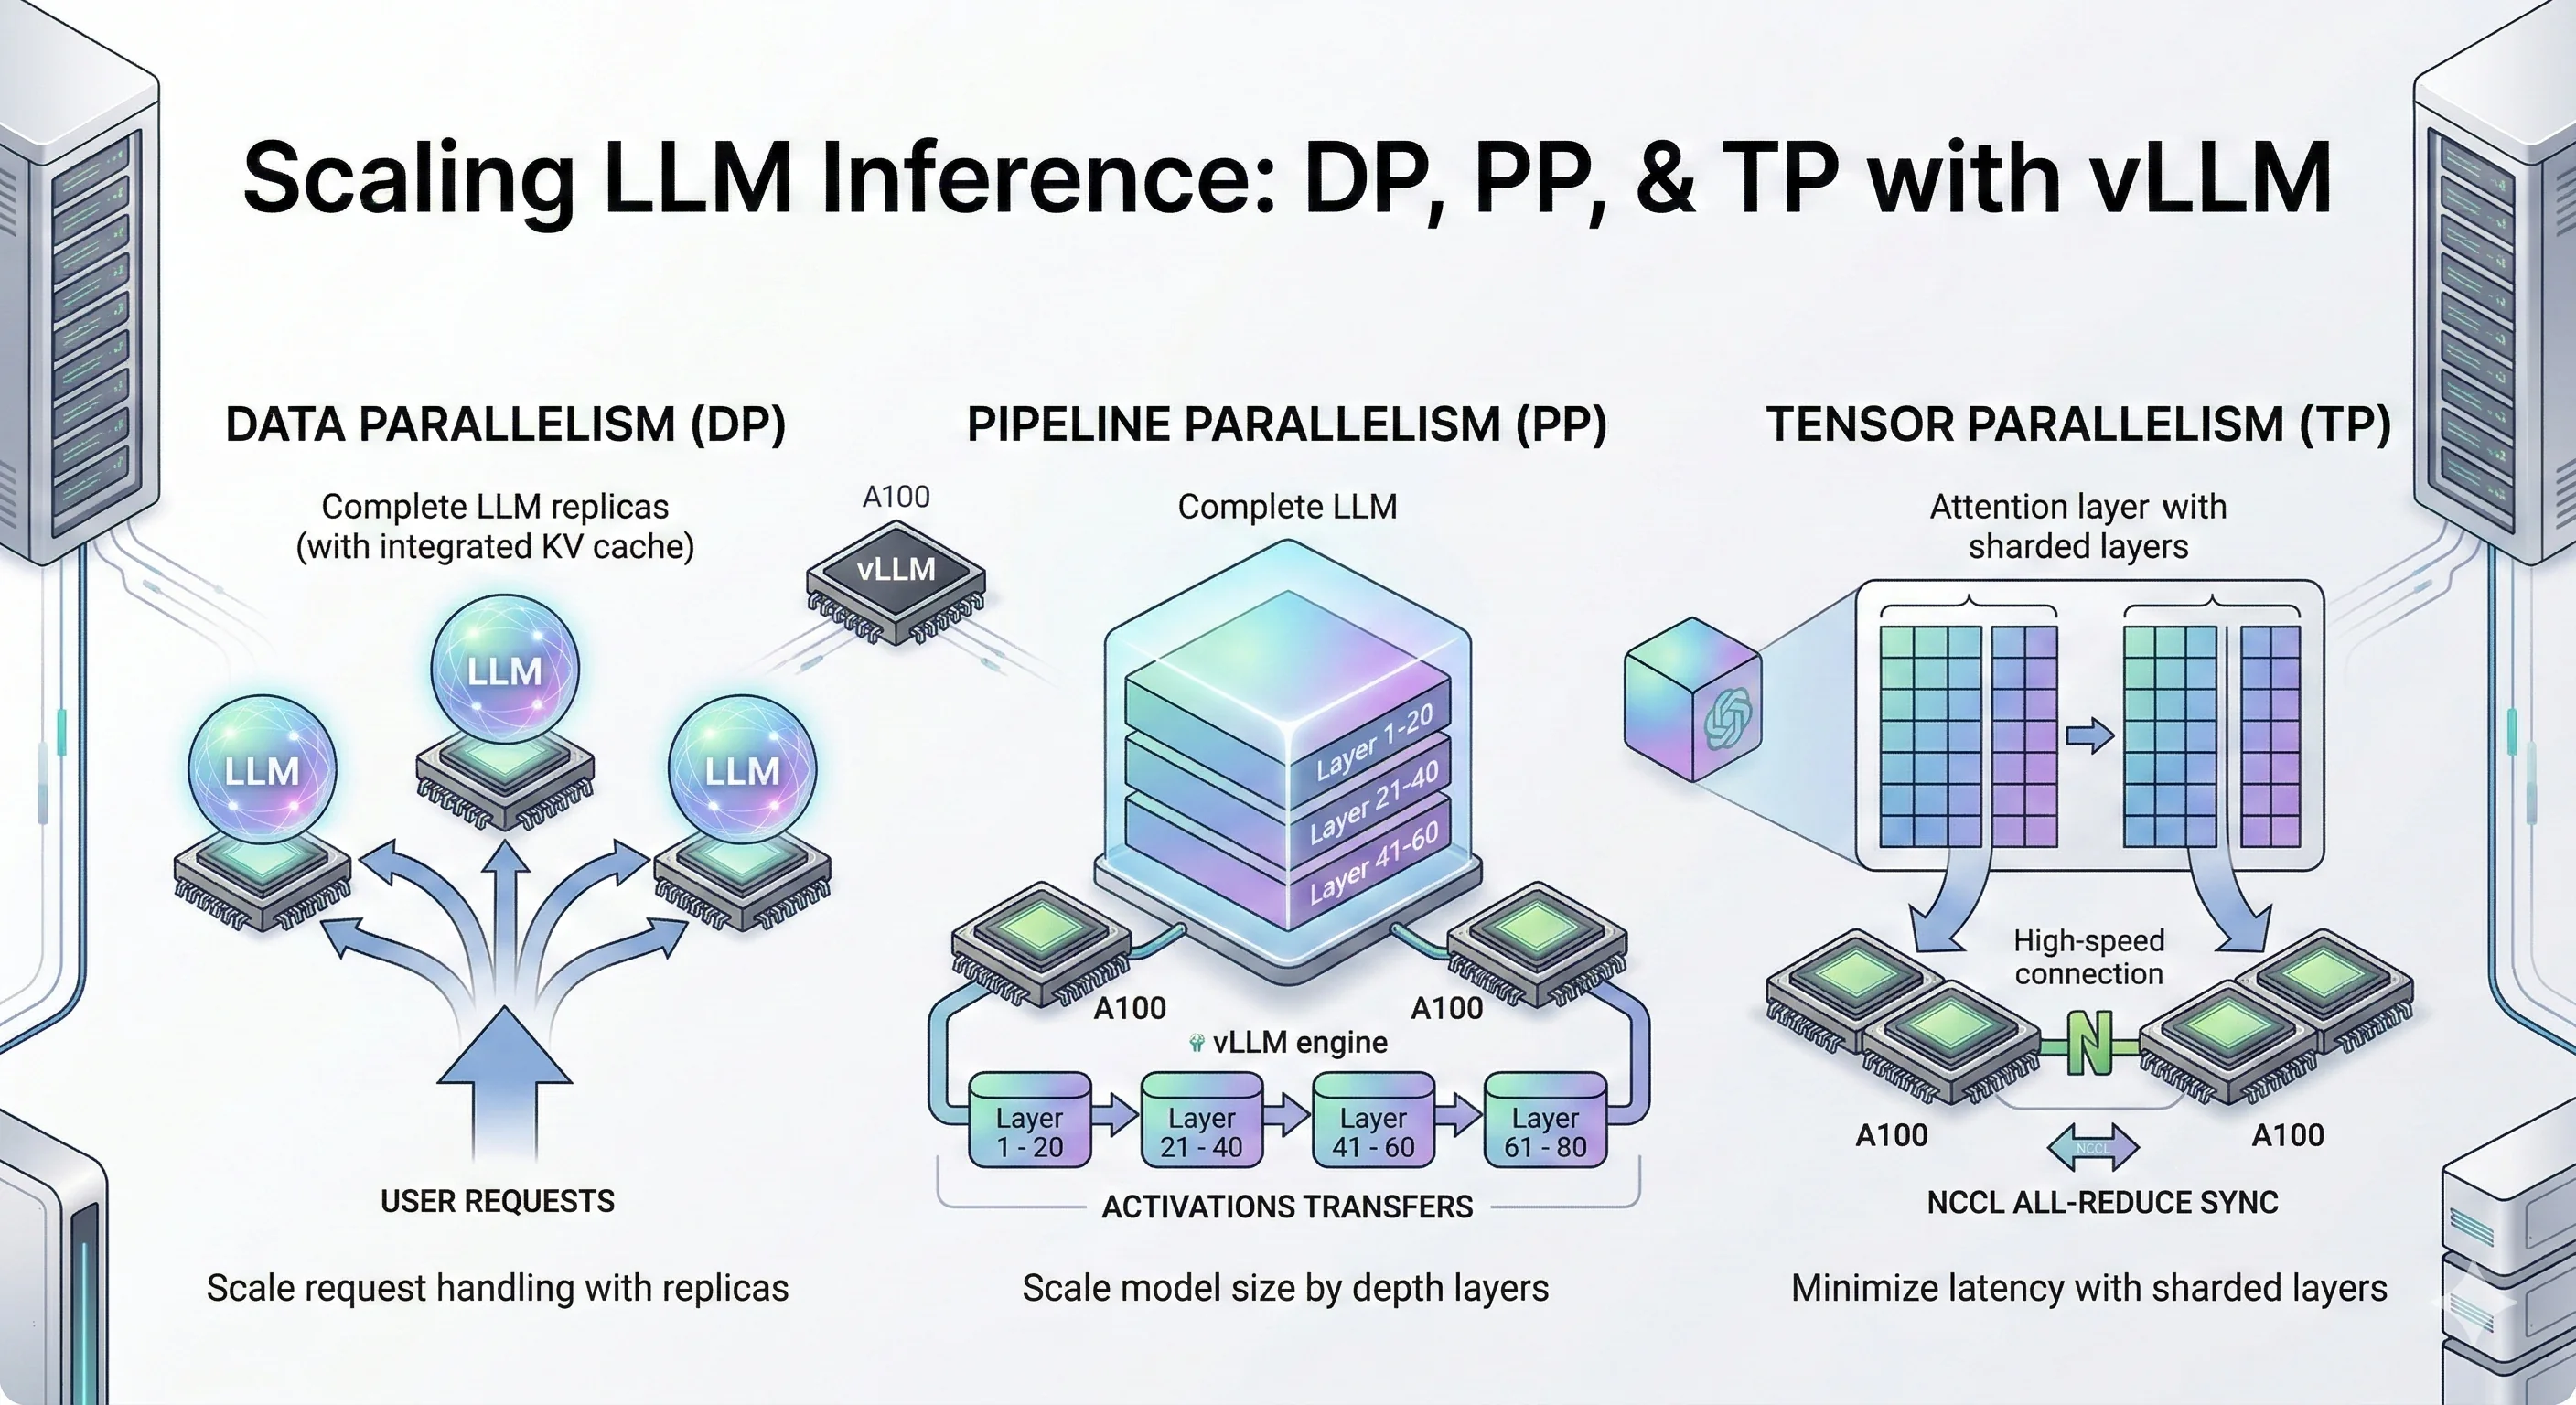
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
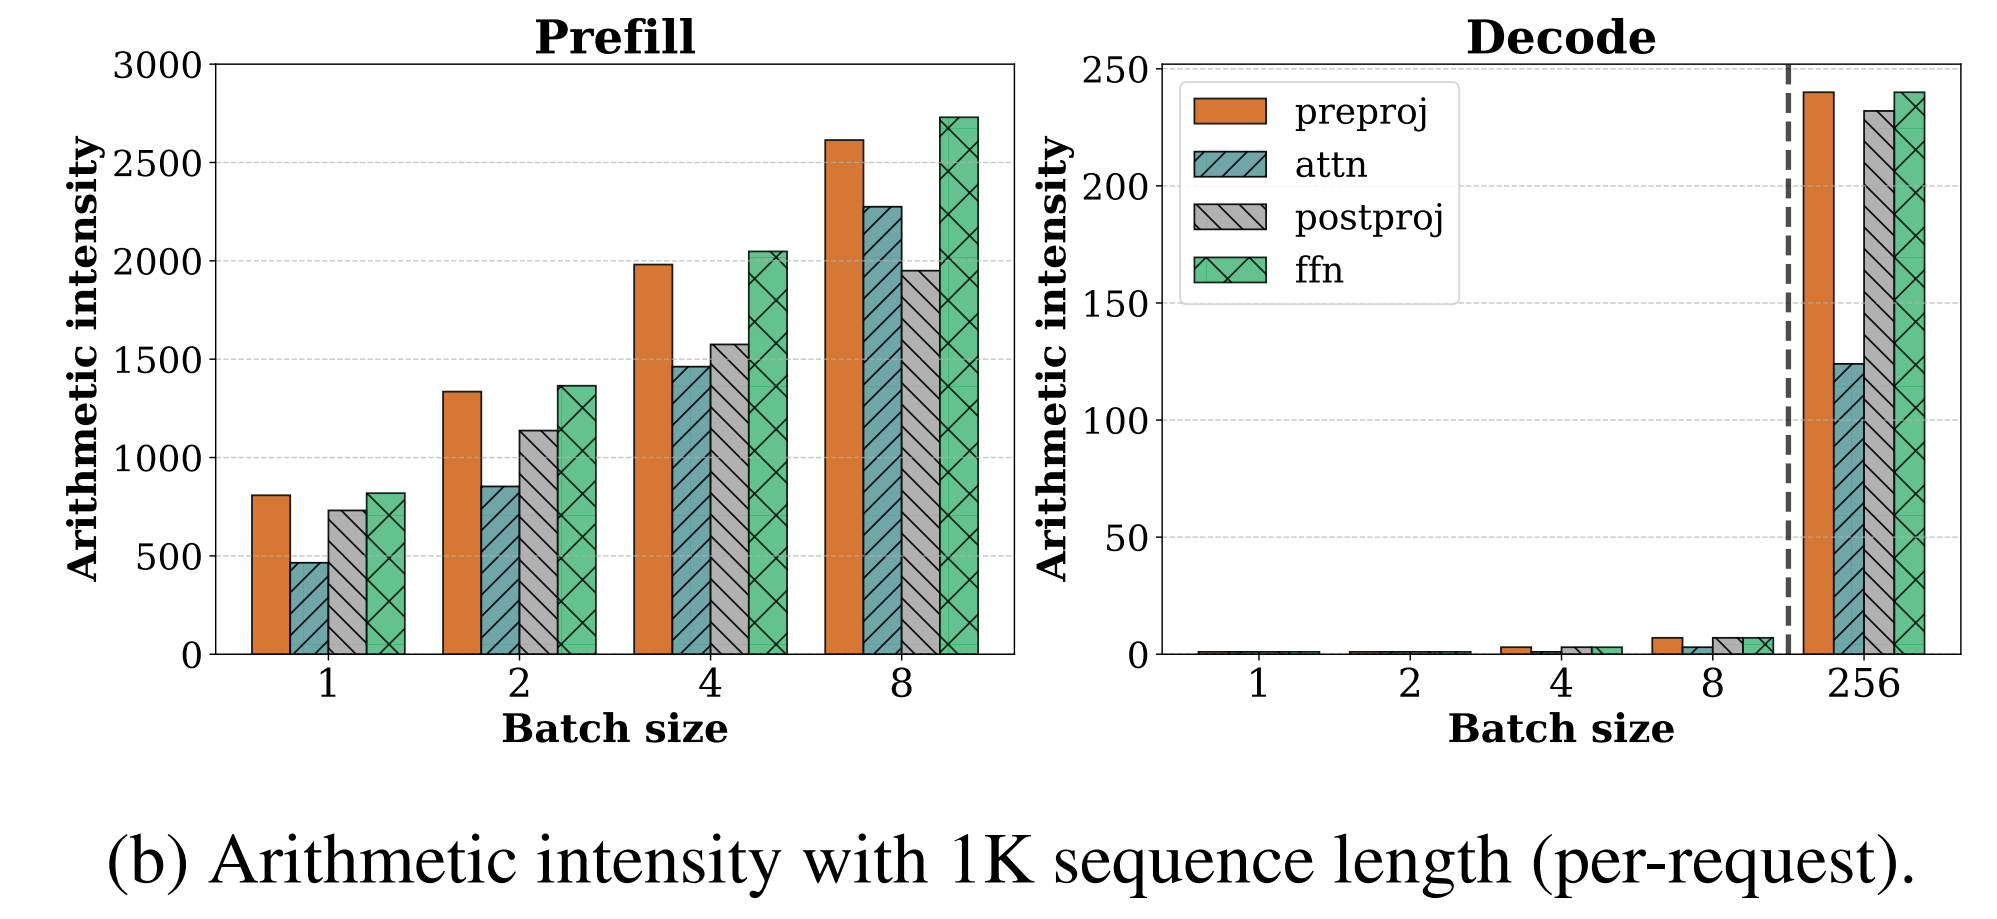
🚀 LLM Inference Deep Dive: Metrics, Batching & GPU Optimization ...
The Best NVIDIA GPUs for LLM Inference in 2025.pdf

Deep Dive: Optimizing LLM inference - YouTube

I Built a GPU Dataset for LLM Inference — Here’s What I Learned - DEV ...
Advertisement Space (336x280)

LLM Inference: A Deep Dive into Optimizations | by Aashutosh Mishra ...

INT4 Decoding GQA CUDA Optimizations for LLM Inference – PyTorch
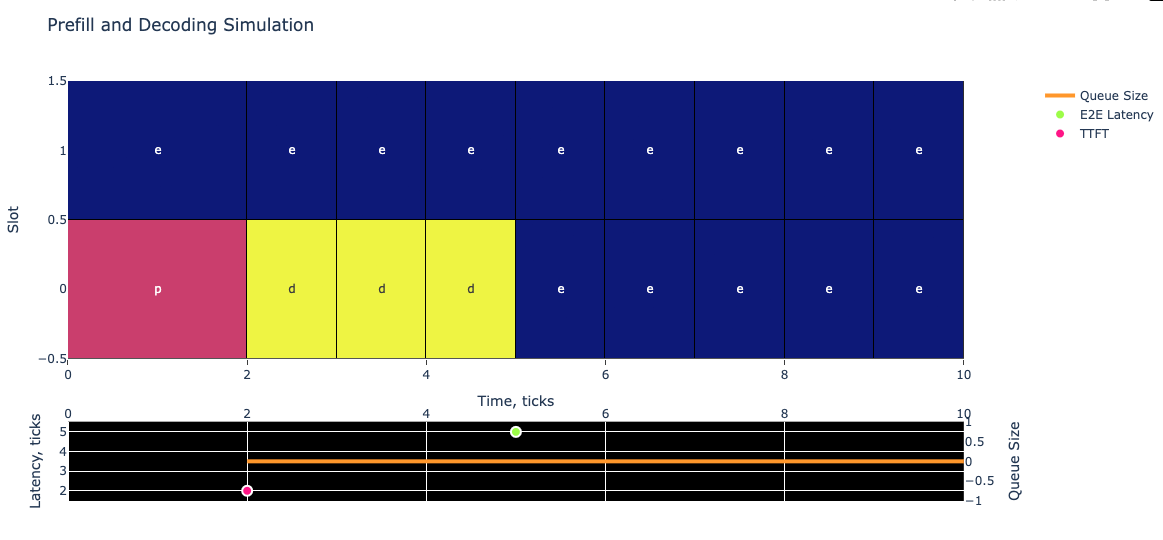
🚀 LLM Inference Deep Dive: Metrics, Batching & GPU Optimization ...
LLM Inference Deep Dive: TensortRT-LLM, KV Cache, Prefill vs Decode ...

INT4 Decoding GQA CUDA Optimizations for LLM Inference – PyTorch

Optimizing llama.cpp AI Inference with CUDA Graphs - NViNiO News & Search
GitHub - DanilloGG-Protq/llama.cpp_CUDA11.7_LEGACY: LLM inference in C ...

Optimizing llama.cpp AI Inference with CUDA Graphs | NVIDIA Technical Blog
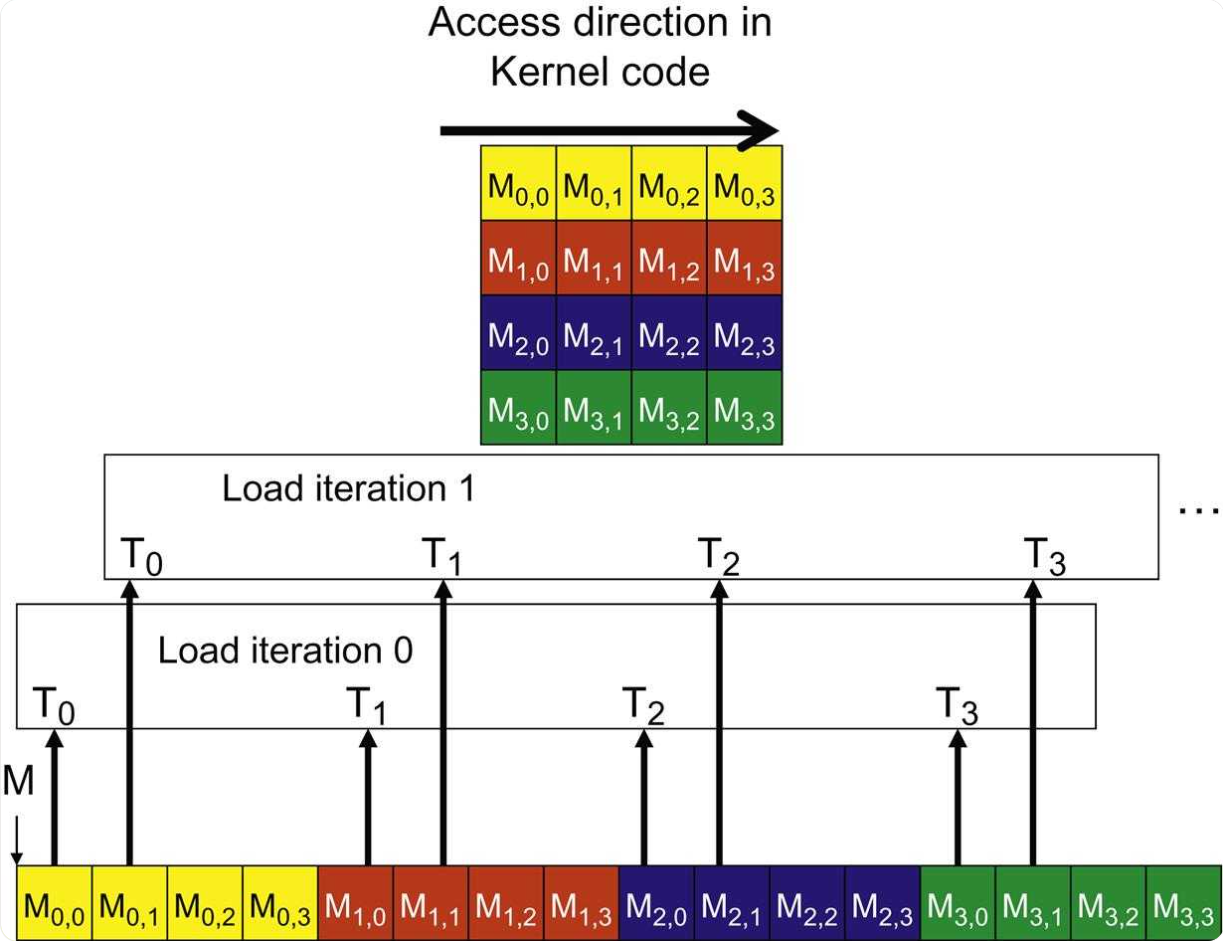
Chapter 4 CUDA Optimization for LLM Inference - LLM Study

CUDA Graphs 加速阿里巴巴本地生活深度学习模型 Inference 流程 | NVIDIA 英伟达博客
Advertisement Space (336x280)
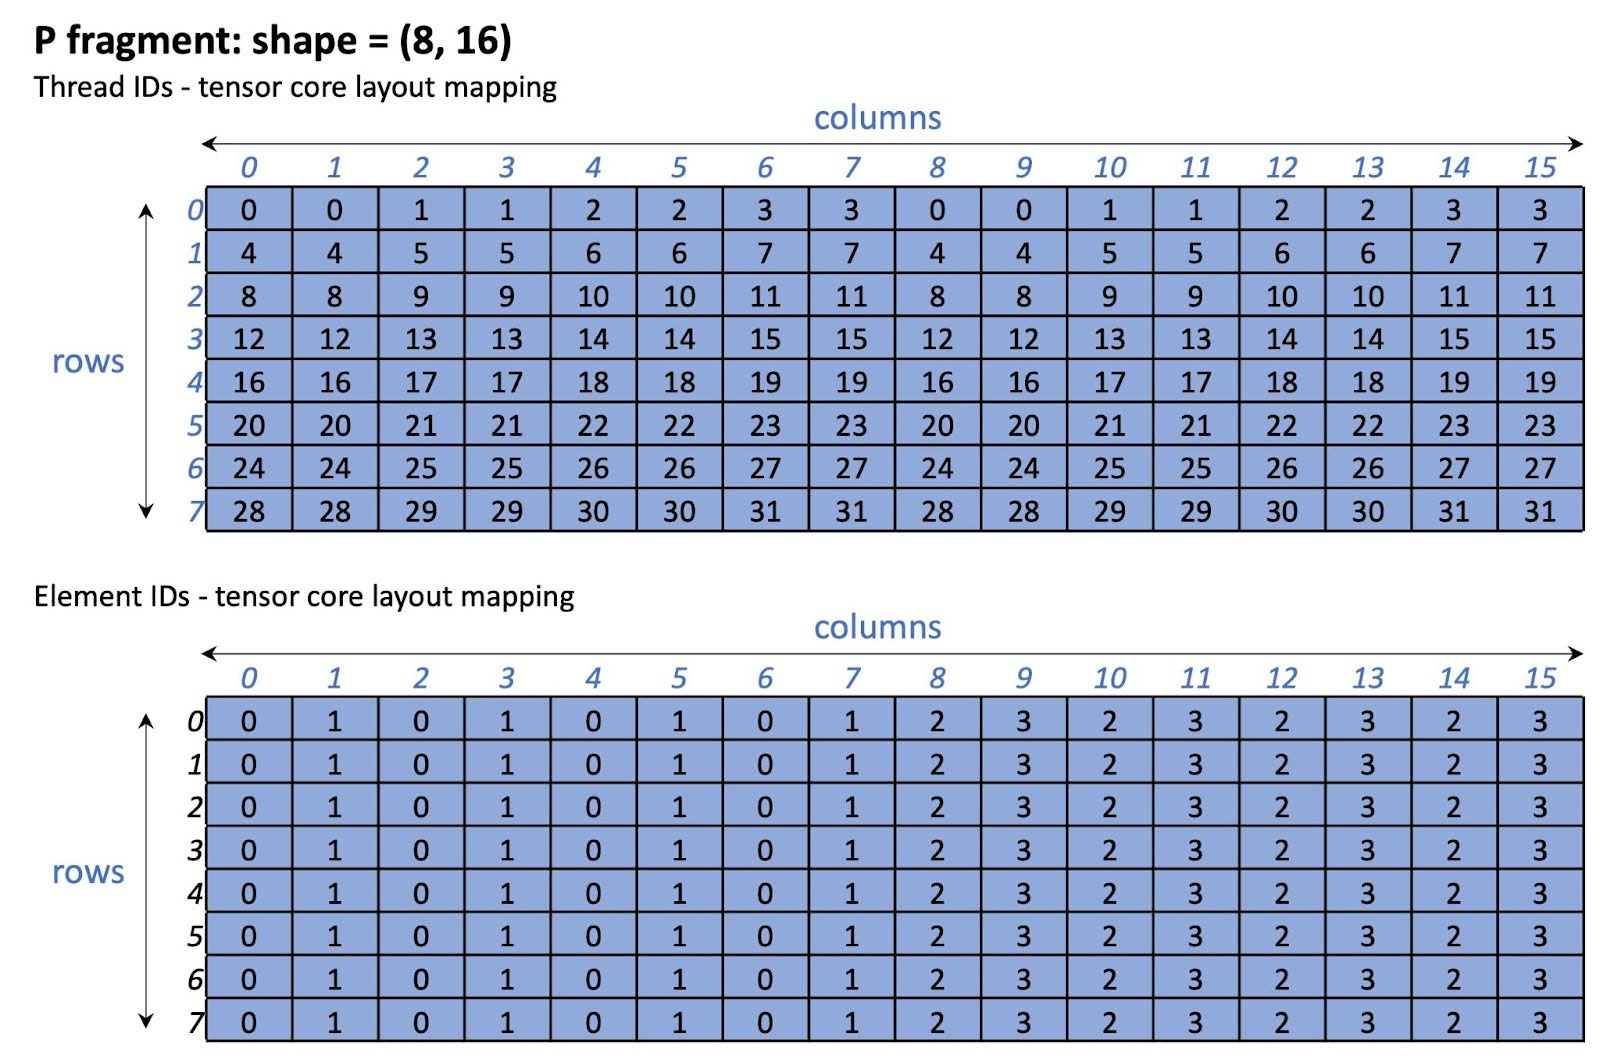
INT4 Decoding GQA CUDA Optimizations for LLM Inference – PyTorch
NVIDIA Blackwell Platform Sets New LLM Inference Records in MLPerf ...
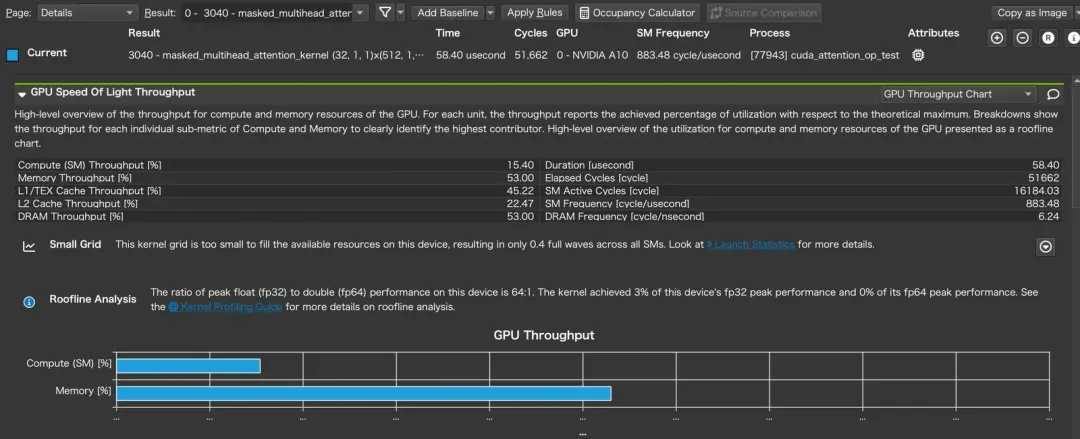
LLM Inference Acceleration: GPU Optimization for Attention in the ...

INT4 Decoding GQA CUDA Optimizations for LLM Inference – PyTorch

Efficiently Serving LLMs (Part 4): How CUDA Graphs make vLLM think faster

CUDA Graphs - vLLM