
Deepspeed Zero 0 3 Stage
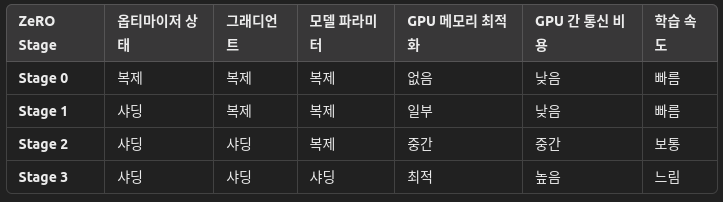
DeepSpeed Zero 0 ~ 3 Stage : 네이버 블로그
Issue of using DeepSpeed with ZeRO Stage 3 optimization · Issue #475 ...
When using pure DeepSpeed ulysses and zero stage 3 to continue pre ...
Deepspeed Zero Stage 3 save a empty model state_dict · Issue #298 ...
Unable to save model while using Deepspeed Zero stage 3 · Issue #378 ...
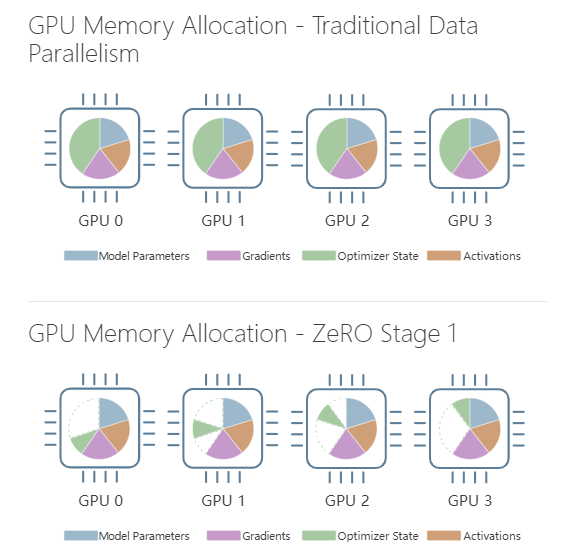
详解 DeepSpeed Zero 的各个 Stage 状态及日常使用_deepspeed zero stage-CSDN博客

DeepSpeed: Performance Degradation with ZERO Stage 3

详解 DeepSpeed Zero 的各个 Stage 状态及日常使用_deepspeed stage-CSDN博客
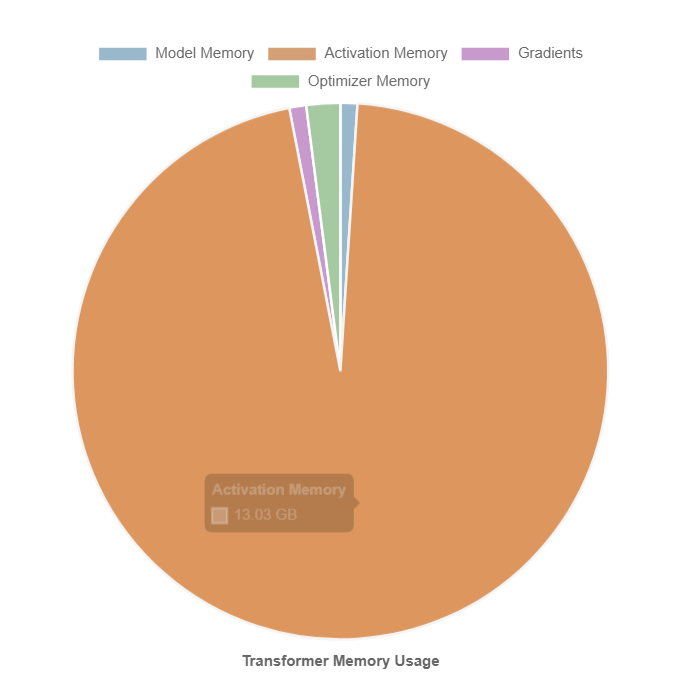
详解 DeepSpeed Zero 的各个 Stage 状态及日常使用_deepspeed zero stage-CSDN博客
[DeepSpeed] ZeRO stage 3 integration: getting started and issues ...
Advertisement Space (300x250)
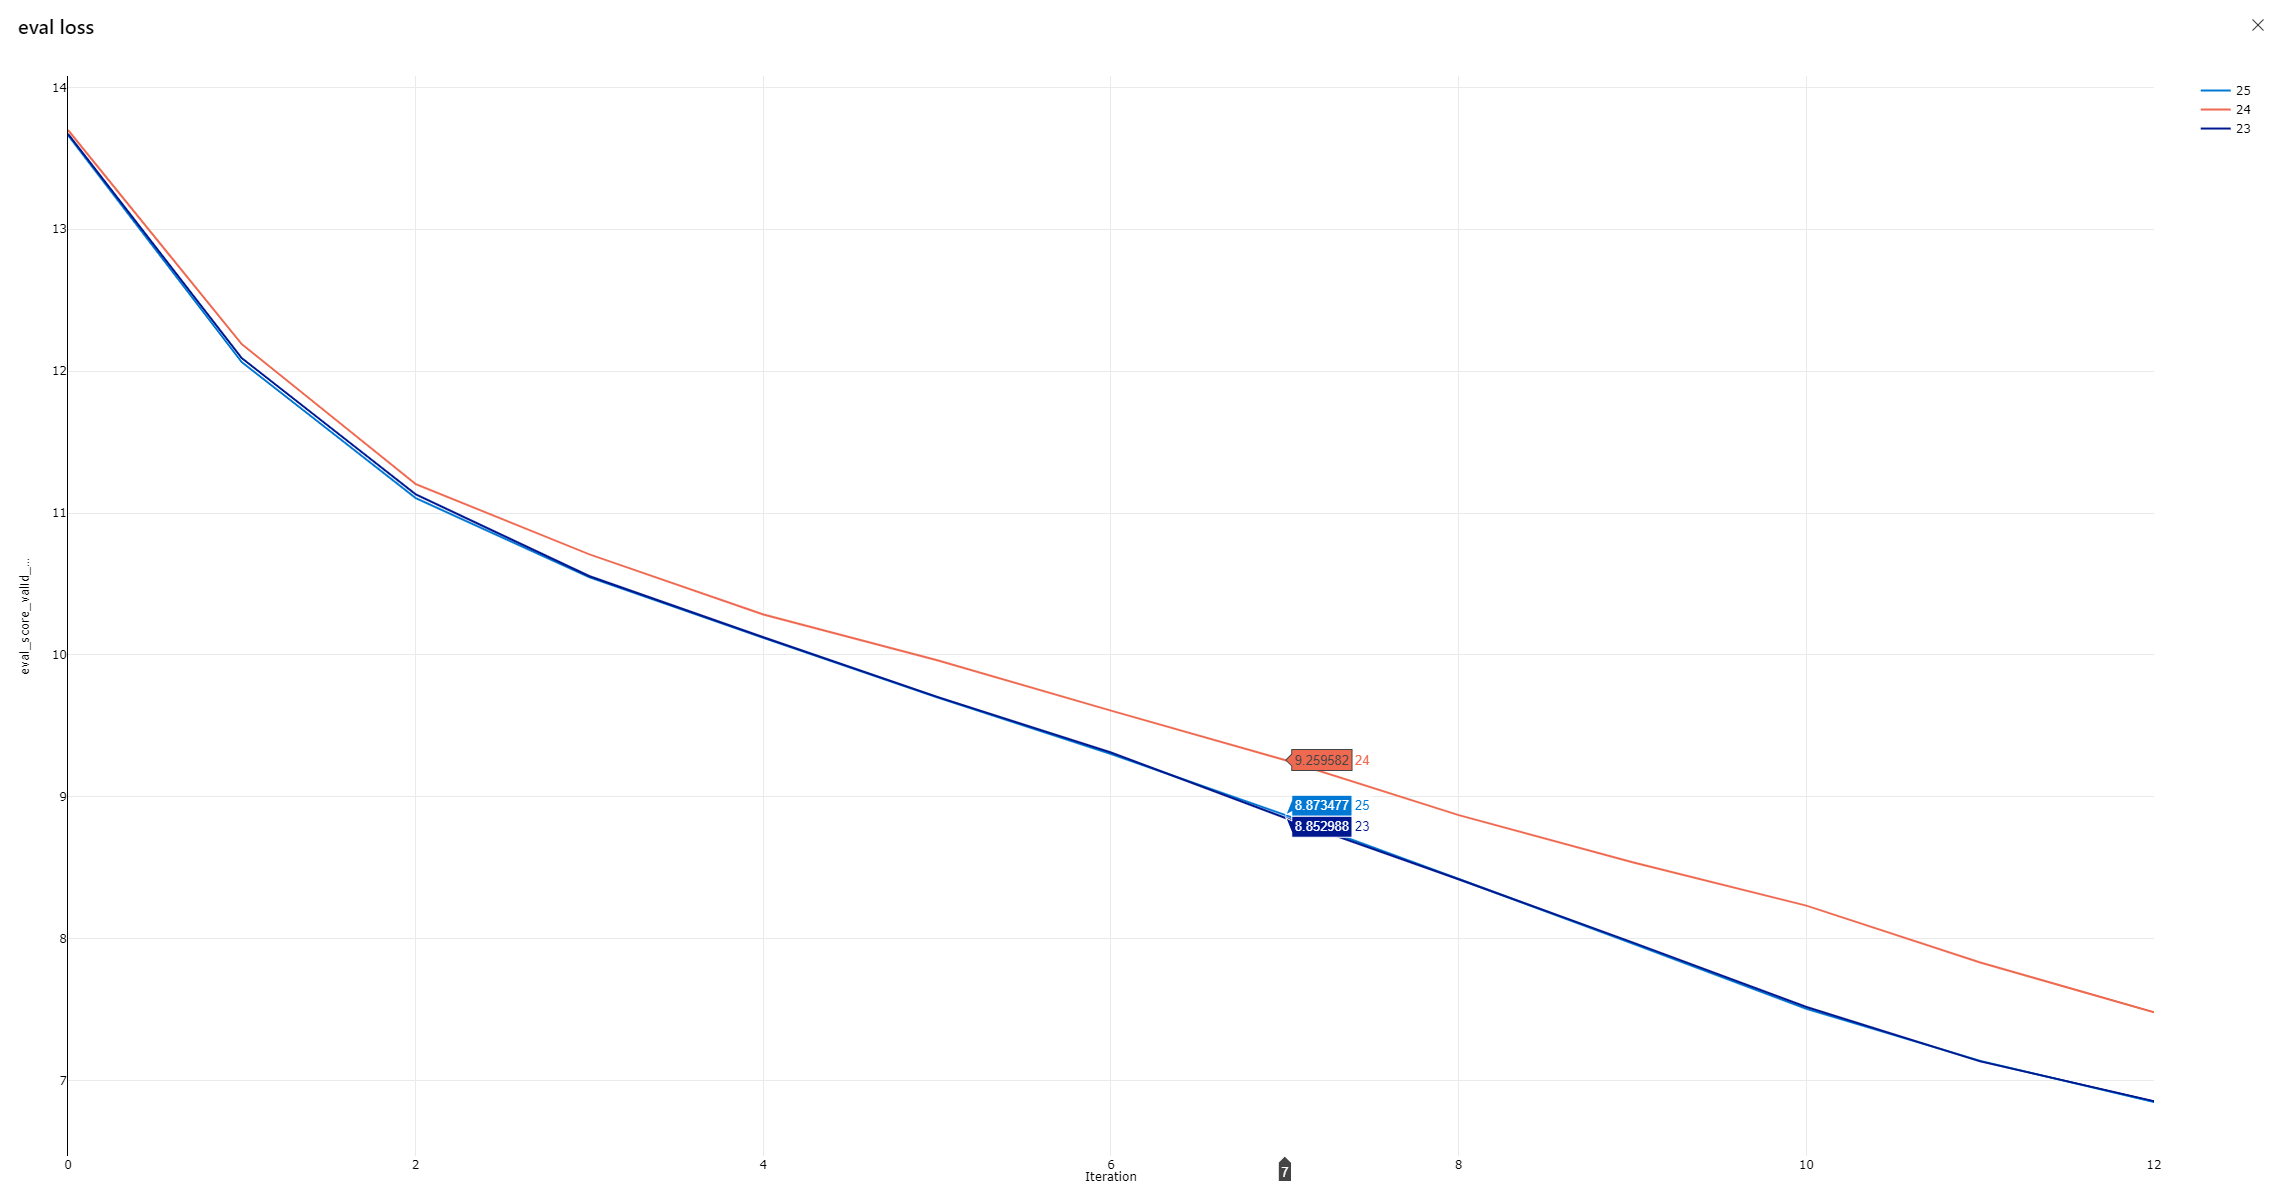
ZeRO stage 1 has different convergence compared to stage 0 and 2 ...

[Bug] Hybrid Engine With Deepspeed Stage 3 Results And Llama – MVDY

DeepSpeed: Performance Degradation with ZERO Stage 3
[BUG] Deepspeed ZeRO Optimizer Stage 2 Memory Leak? How to cleanup ...
High Peak GPU Memory with ZeRO Stage 3 · Issue #3734 · deepspeedai ...

详解 DeepSpeed Zero 的各个 Stage 状态及日常使用_deepspeed stage-CSDN博客

how many partitios will zero stage 3 divide mode · deepspeedai ...

DeepSpeed: Performance Degradation with ZERO Stage 3
DeepSpeed ZeRO 分布式训练架构图 流程图模板_ProcessOn思维导图、流程图
DeepSpeed ZeRO Optimization Stages
Advertisement Space (336x280)

Free Video: Turing-NLG, DeepSpeed and the ZeRO Optimizer from Yannic ...

LLM Training — Enhancing Communication Overhead of DeepSpeed Zero ...
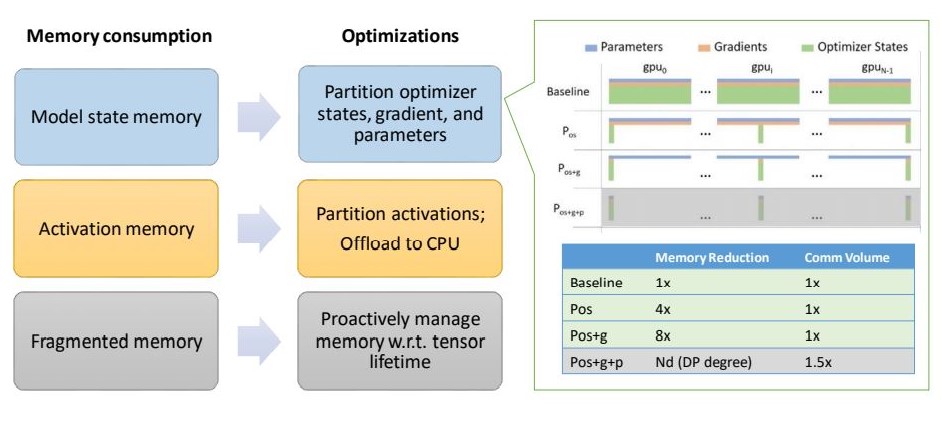
효율적인 분산 학습을 위한 DeepSpeed ZeRO

A Guide to DeepSpeed Zero With the HuggingFace Trainer | ml-news ...

📈 Are you leveraging DeepSpeed Zero with the HuggingFace Trainer to ...

DeepSpeed ZeRO Tutorial: Fine-Tune LLMs Across Multiple GPUs - YouTube
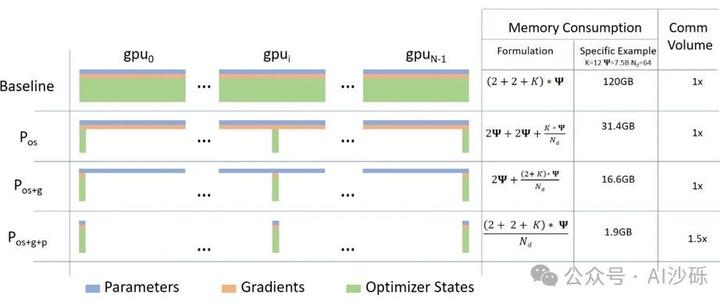
deepspeed 滴 ZERO 介绍 - 知乎

大规模深度学习框架 DeepSpeed 使用指南-CSDN博客
DeepSpeed ZeRO优化器大模型训练提速技巧-CSDN博客
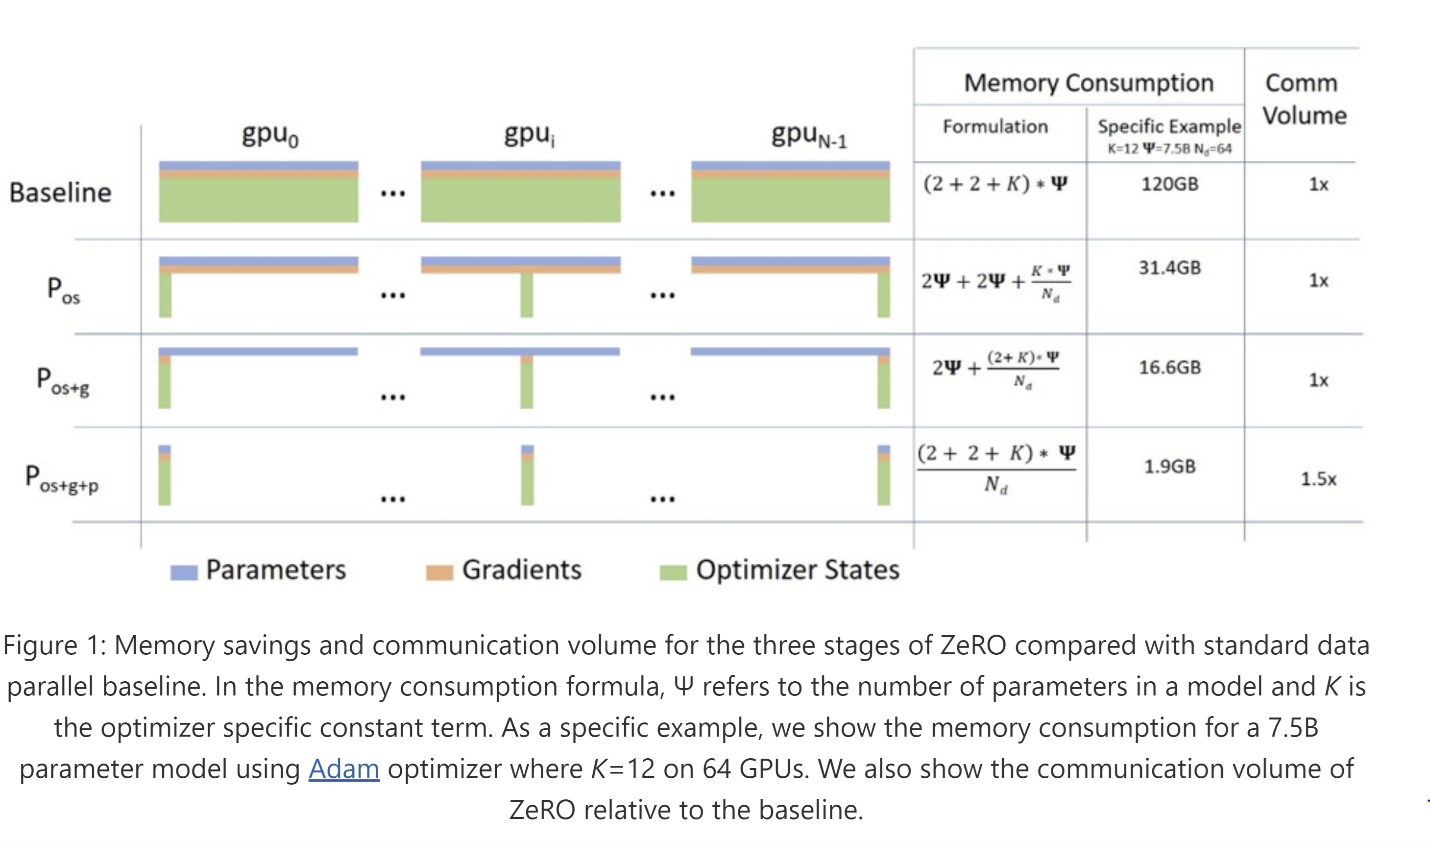
DeepSpeed ZeRO-3 Offload - DeepSpeed
Advertisement Space (336x280)
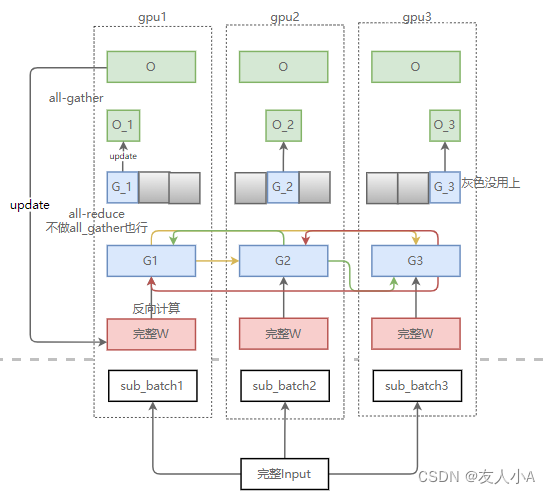
Deepspeed Zero(DP)_zero-dp-CSDN博客
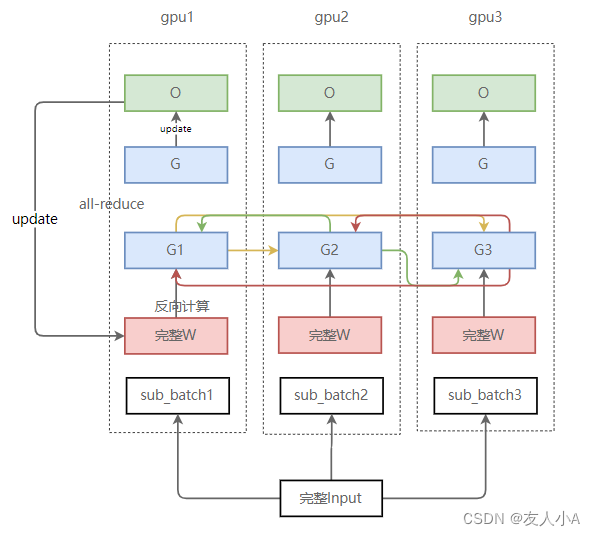
Deepspeed Zero(DP)_zero-dp-CSDN博客
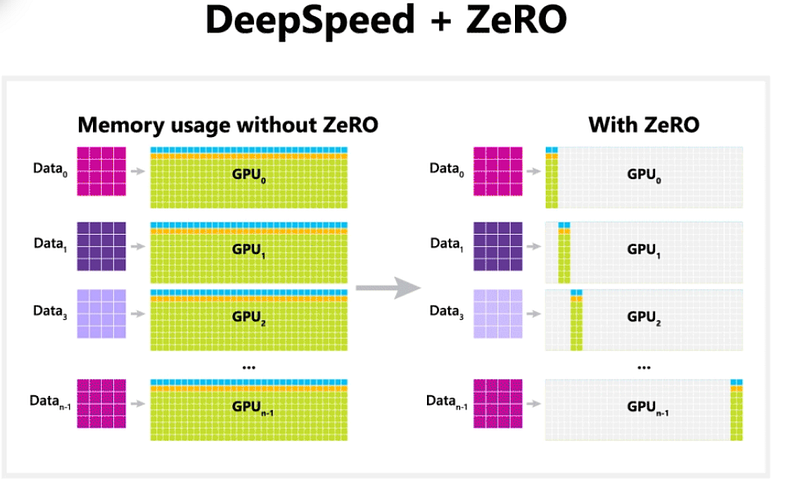
Multi-GPU Training for Llama 3.2 using DeepSpeed and Redundancy ...
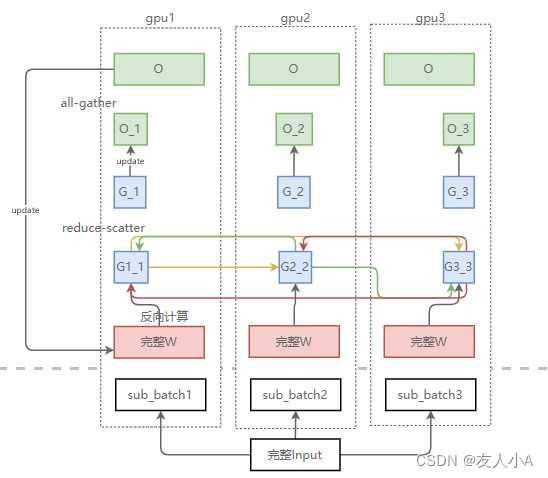
Deepspeed Zero(DP)_zero-dp-CSDN博客

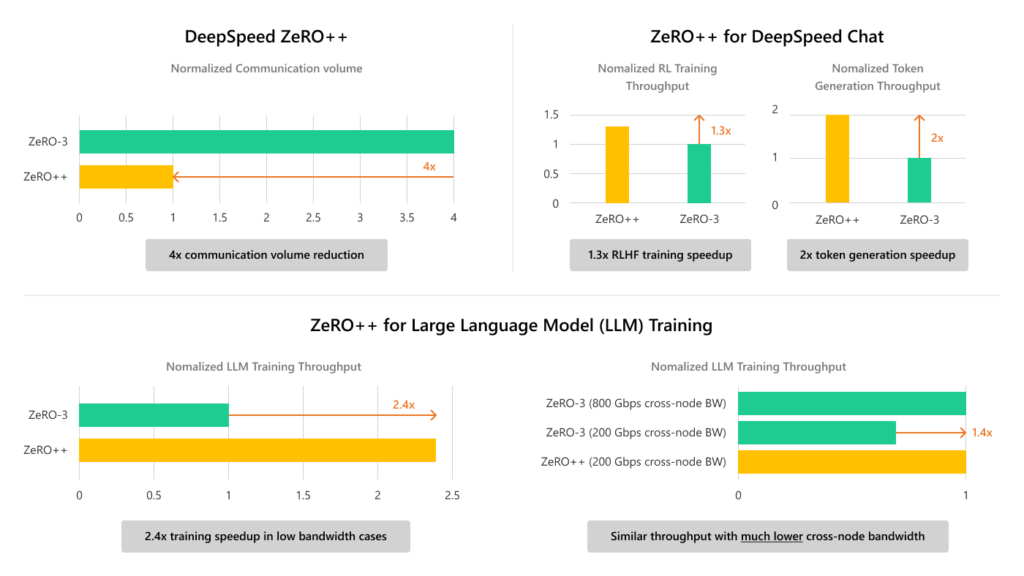
DeepSpeed ZeRO++: A leap in speed for LLM and chat model training with ...
ZeRO & DeepSpeed: New system optimizations enable training models with ...