
Deepspeed Zerovlm
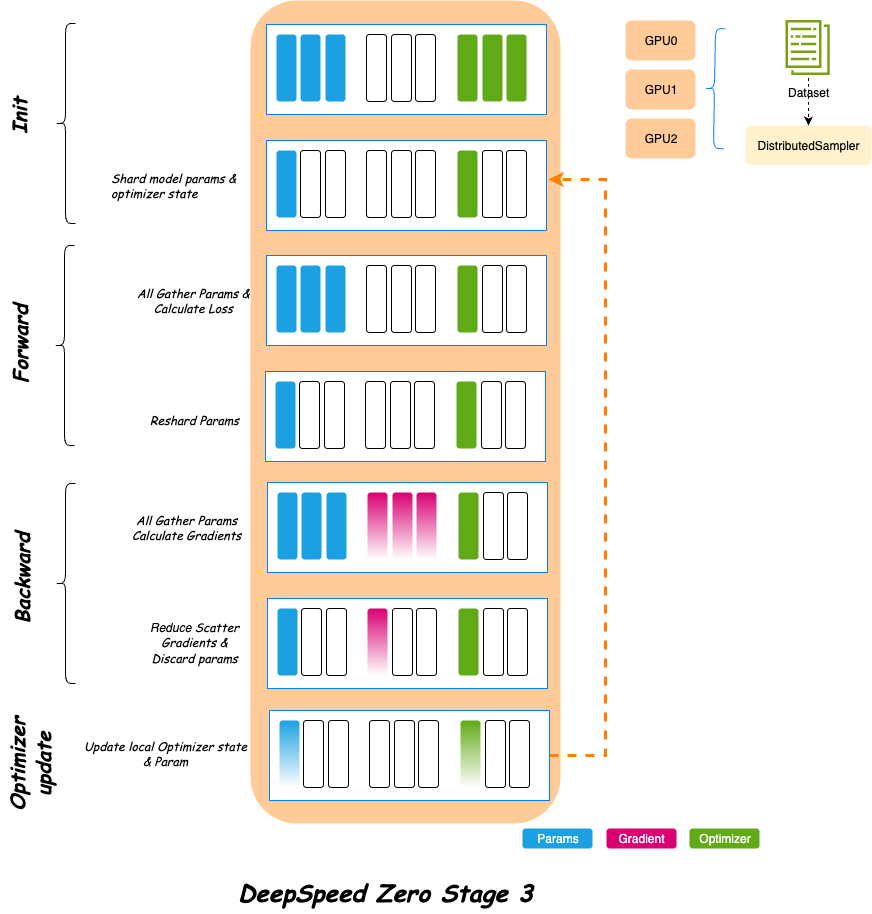
FSDP2 & DeepSpeed ZeRO: Sharding for LLM Training | Medium
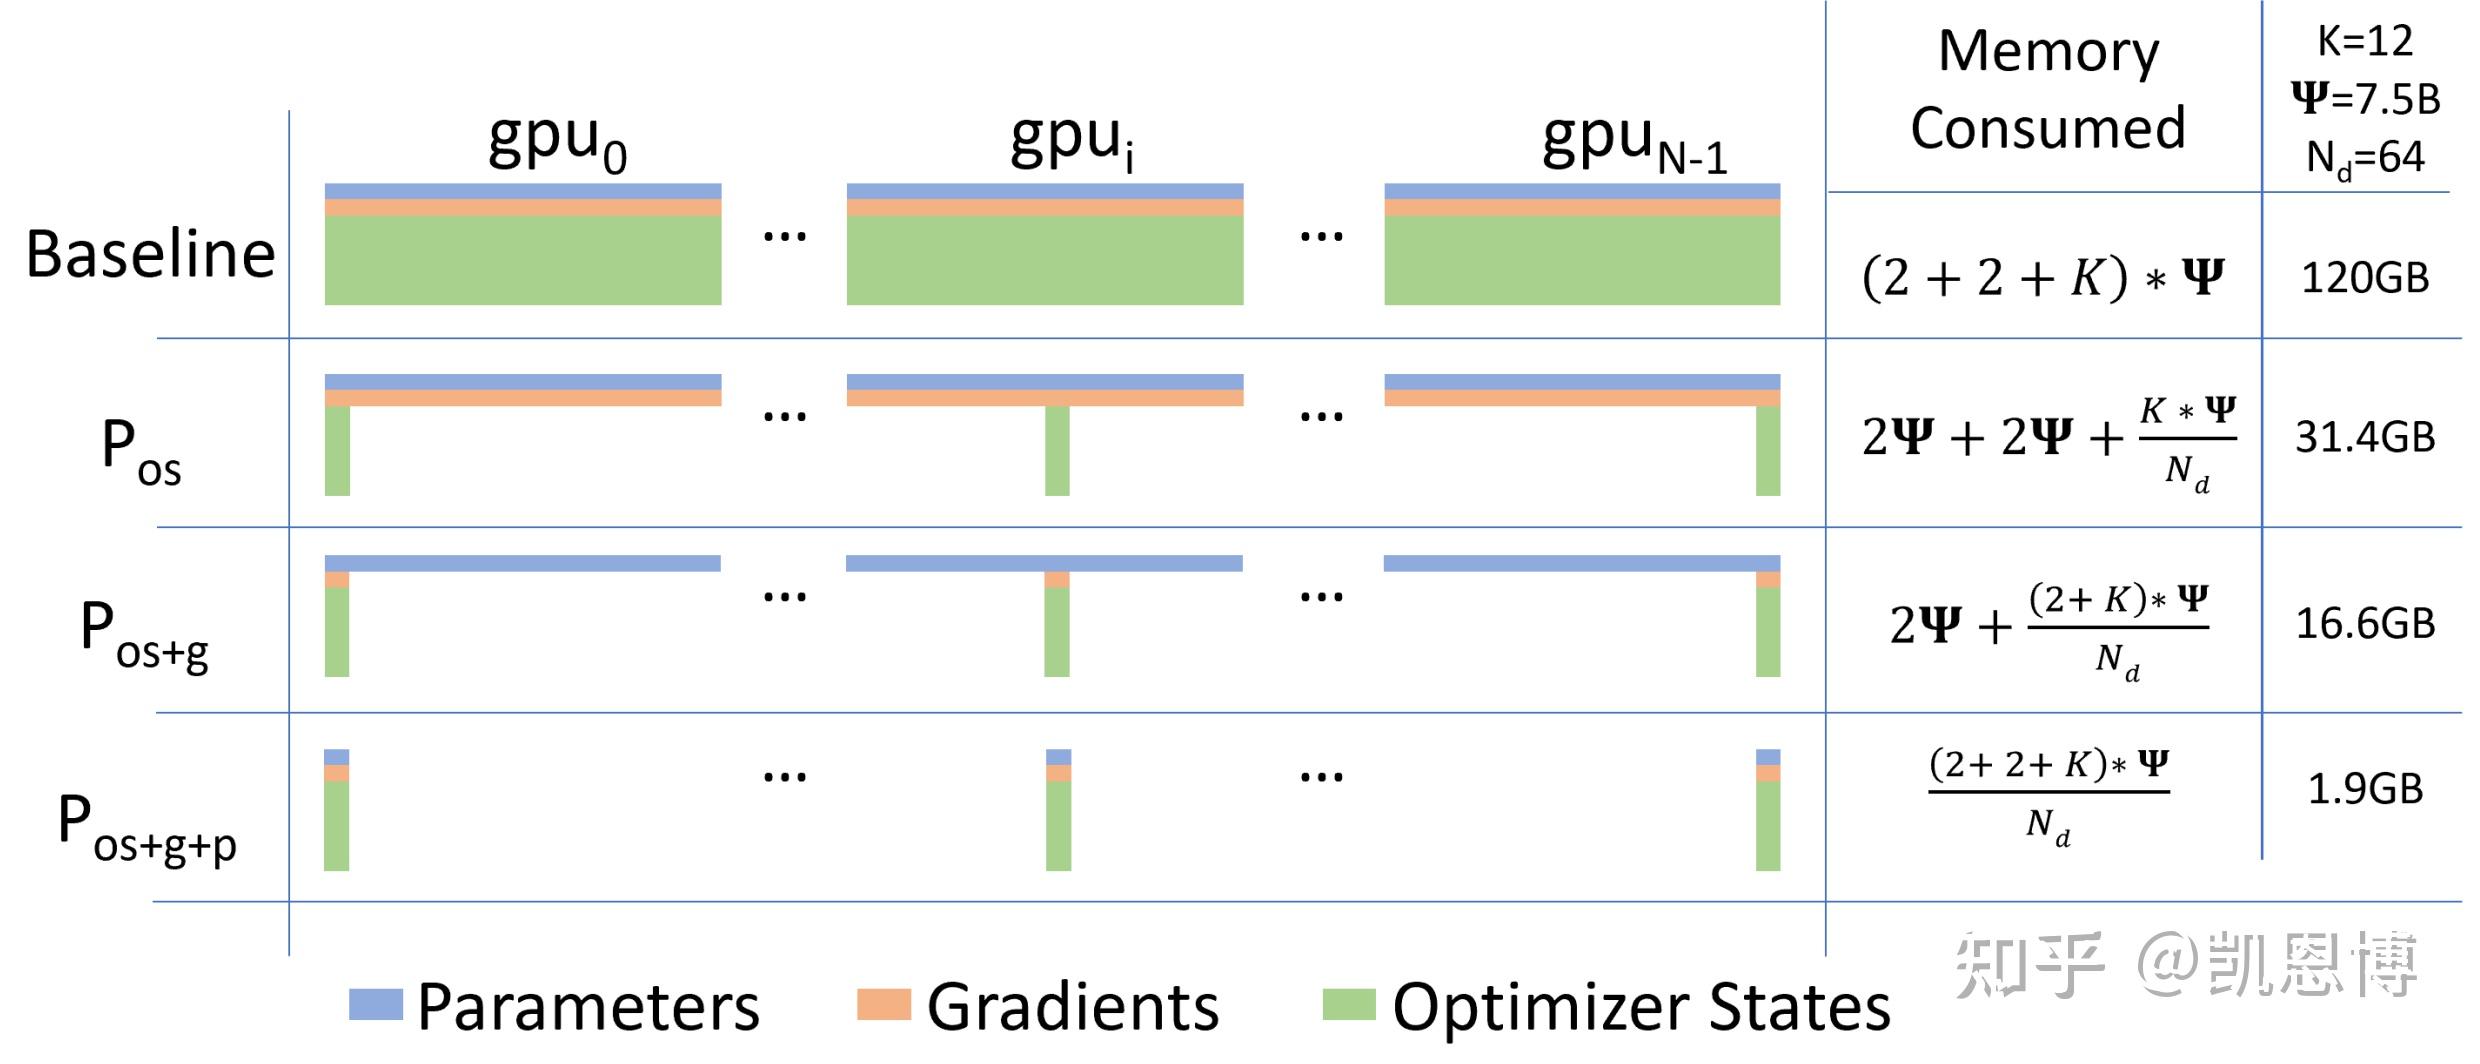
DeepSpeed ZeRO理论与VLM大模型训练实践 - 知乎
DeepSpeed ZeRO++ : 통신량을 4배 줄이면서 LLM과 채팅 모델 트레이닝 속도 | GeekNews
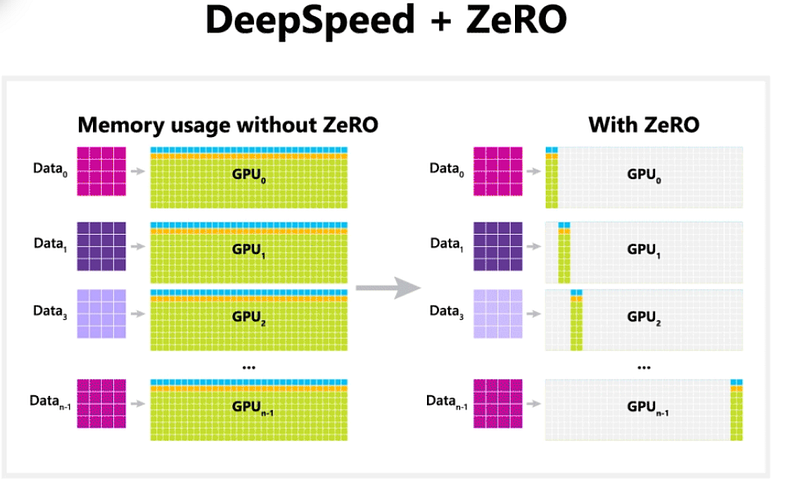
Multi-GPU Training for Llama 3.2 using DeepSpeed and Redundancy ...
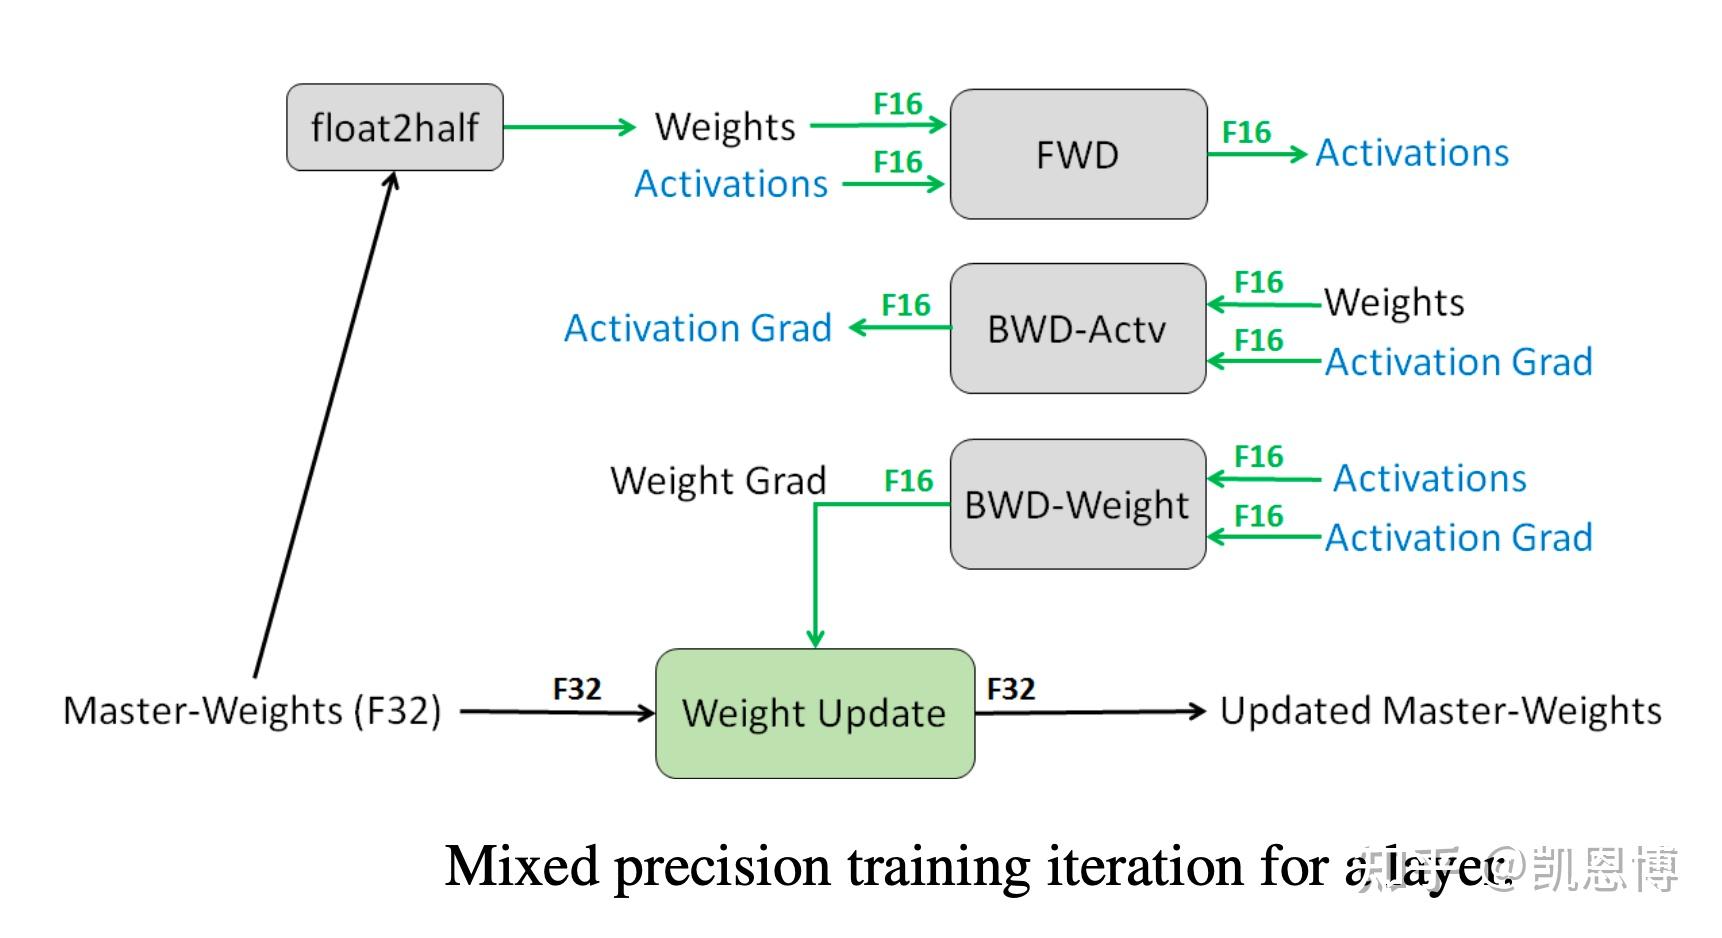
DeepSpeed ZeRO理论与VLM大模型训练实践 - 知乎

DeepSpeed ZeRO++: A leap in speed for LLM and chat model training with ...

DeepSpeed ZeRO Tutorial: Fine-Tune LLMs Across Multiple GPUs - YouTube
DeepSpeed ZeRO理论与VLM大模型训练实践 - 知乎
DeepSpeed ZeRO优化器大模型训练提速技巧-CSDN博客
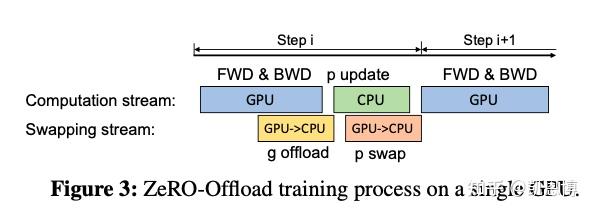
DeepSpeed ZeRO理论与VLM大模型训练实践 - 知乎
Advertisement Space (300x250)
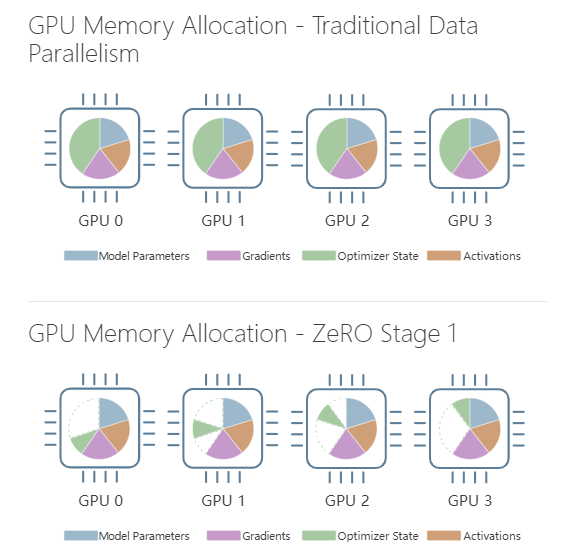
详解 DeepSpeed Zero 的各个 Stage 状态及日常使用_deepspeed zero stage-CSDN博客
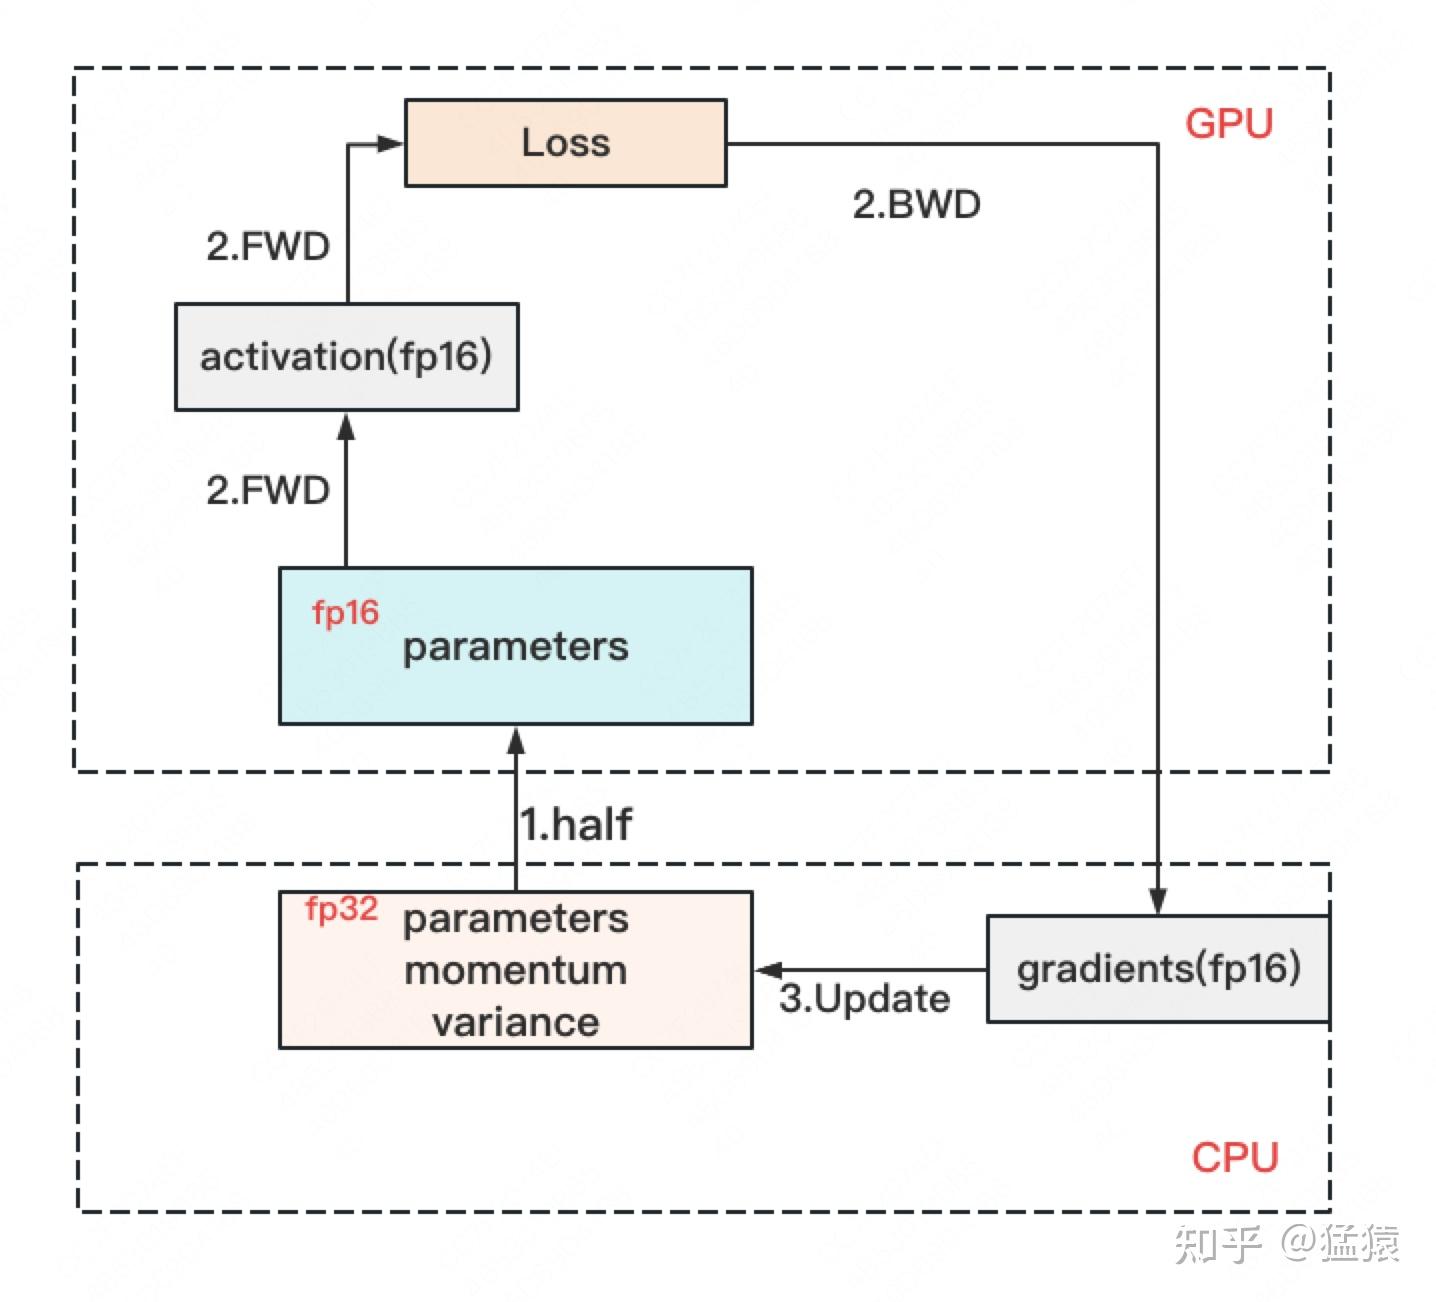
图解大模型训练之:数据并行下篇( DeepSpeed ZeRO,零冗余优化) - 知乎
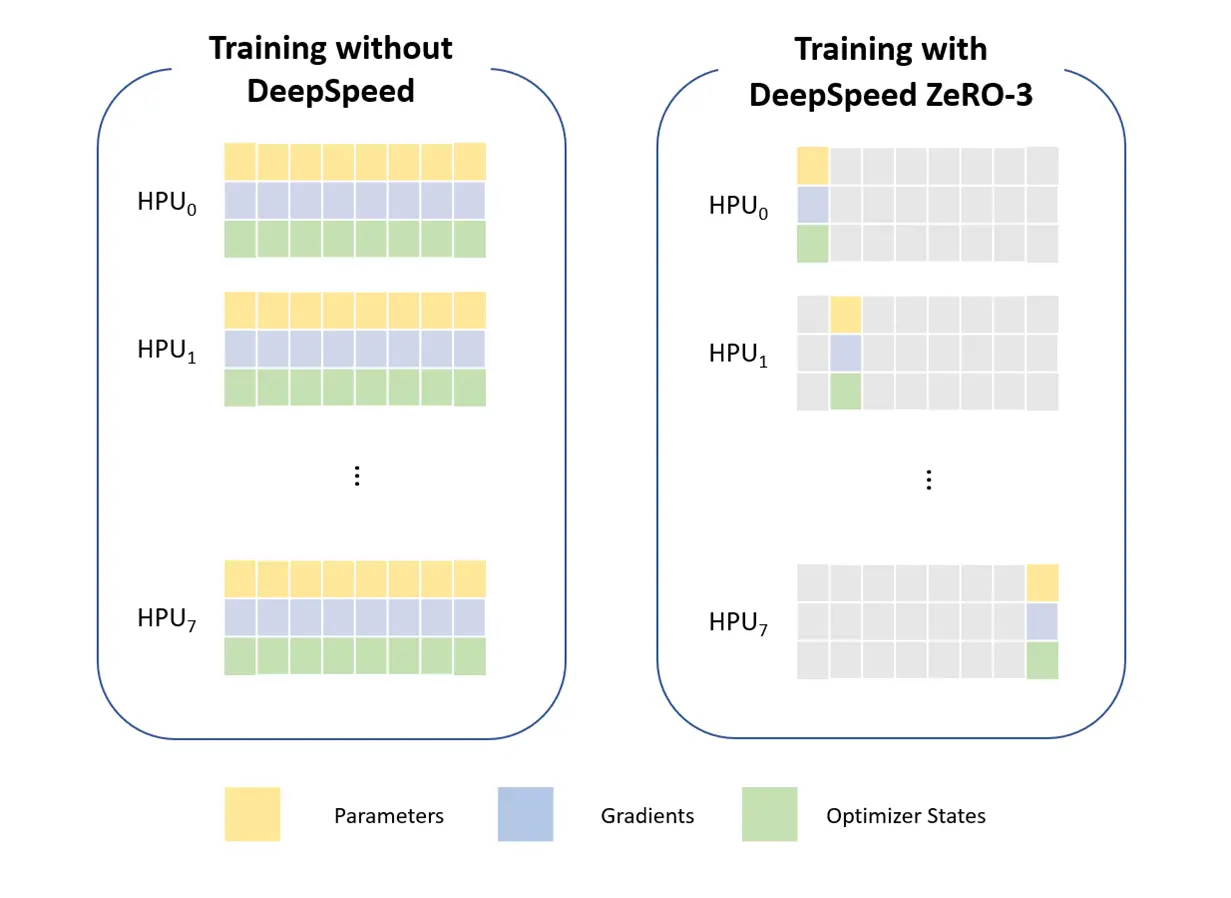
Deepspeed Zero-3 Offload _ Everything about Distributed Training and ...
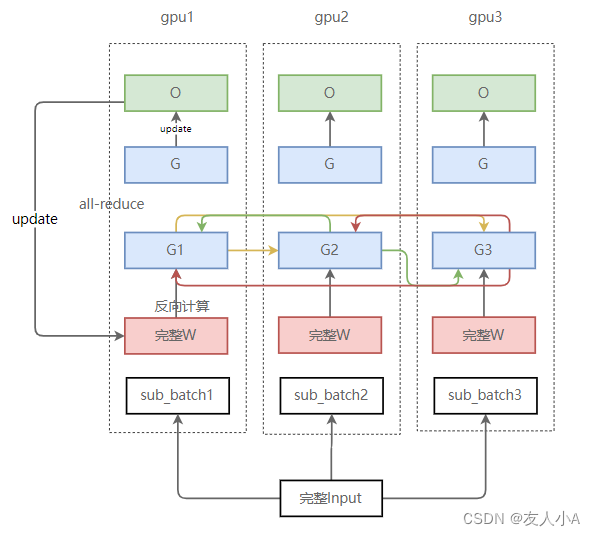
Deepspeed Zero(DP)_zero-dp-CSDN博客
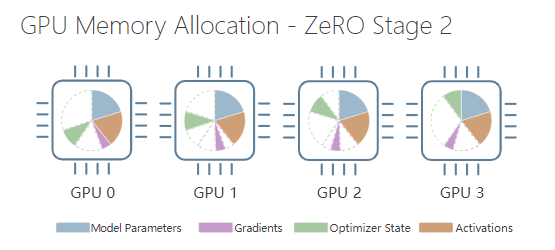
详解 DeepSpeed Zero 的各个 Stage 状态及日常使用详解 DeepSpeed Zero 的各个 Sta - 掘金

deepspeed ZeRO-Inference 可在1-GPU上推理~100B的大模型_踏雪至山巅的技术博客_51CTO博客
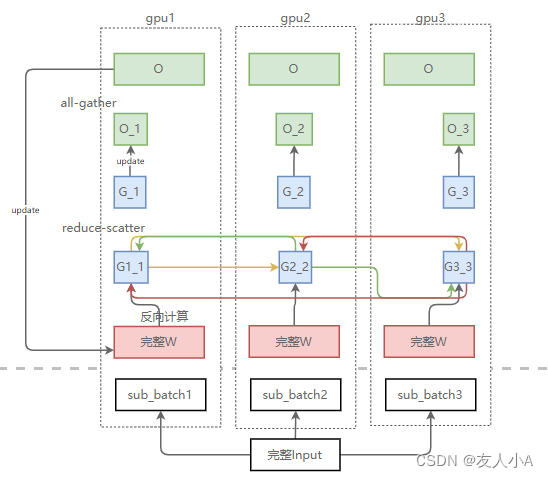
Deepspeed Zero(DP)_zero-dp-CSDN博客

ZeRO-Offload - DeepSpeed 深度学习优化库

A Guide to DeepSpeed Zero With the HuggingFace Trainer | ml-news ...

Deepspeed ZeRO-DP: distributed training for large models | Towards AI
Advertisement Space (336x280)

Free Video: Turing-NLG, DeepSpeed and the ZeRO Optimizer from Yannic ...
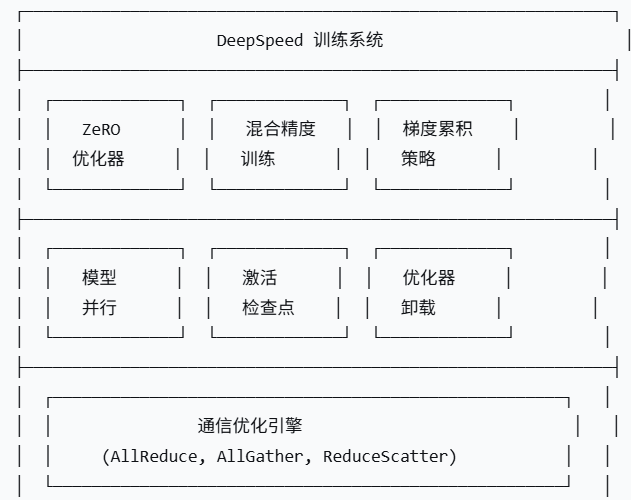
DeepSpeed 分布式训练_deepspeed分布式训练-CSDN博客

DeepSpeed ZeRO++: A leap in speed for LLM and chat model training : r ...

DeepSpeed ZeRO++: A leap in speed for LLM and chat model training with ...

DeepSpeed 如何从存储层优化推理性能?-腾讯云开发者社区-腾讯云
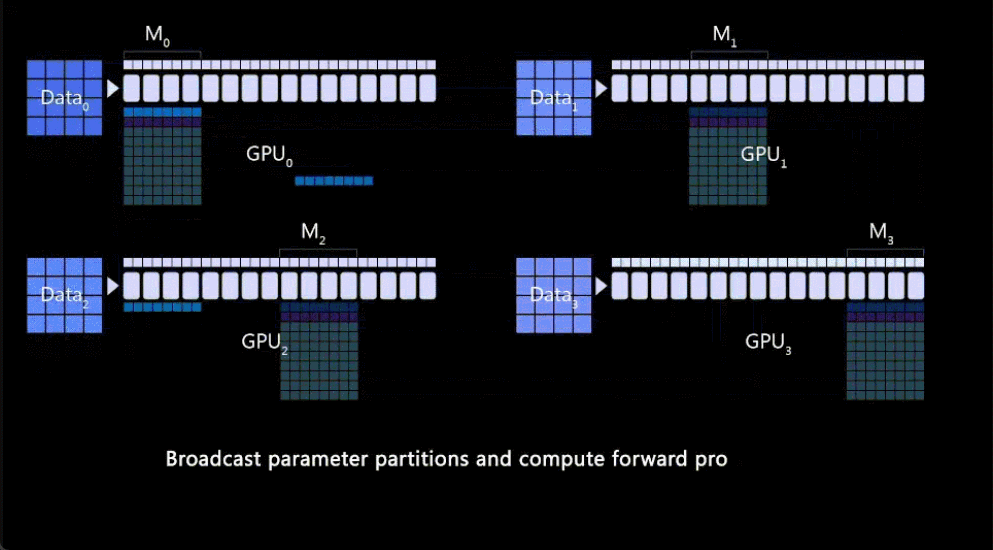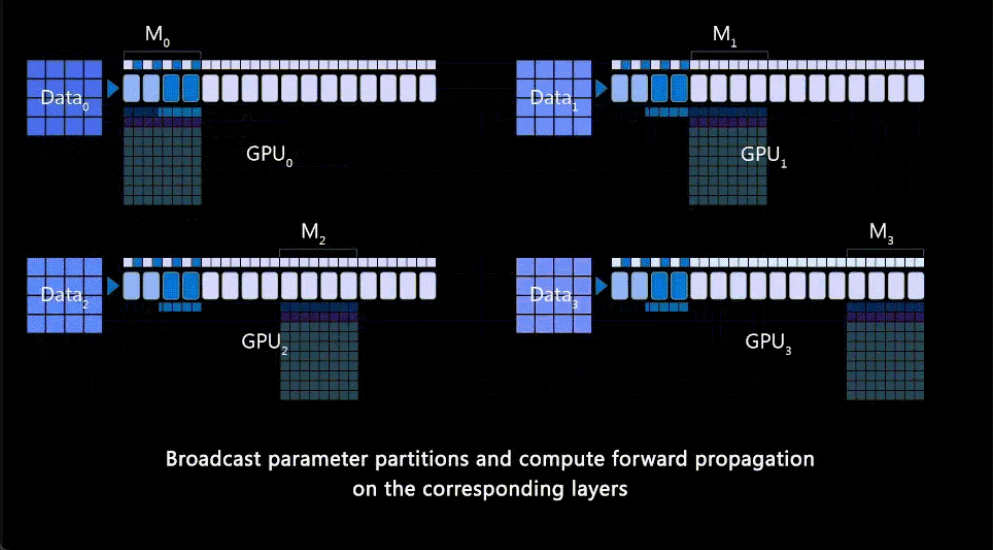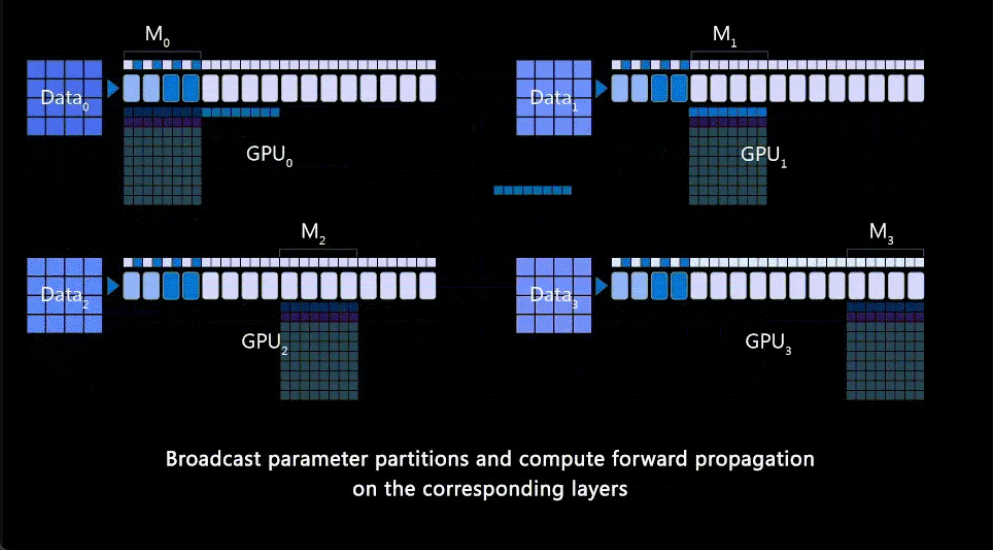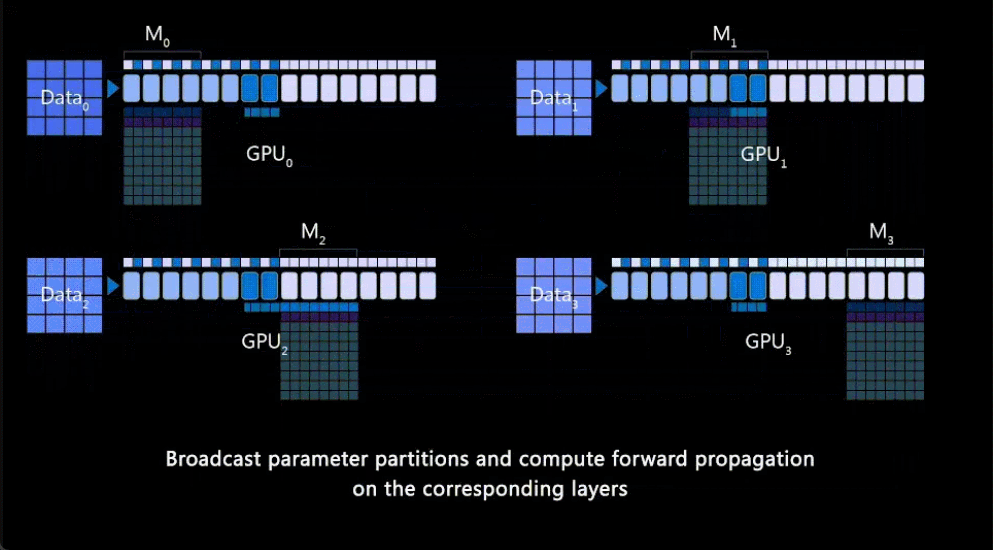
DeepSpeed ZeRO++:降低4倍网络通信,显著提高大模型及类ChatGPT模型训练效率-阿里云开发者社区
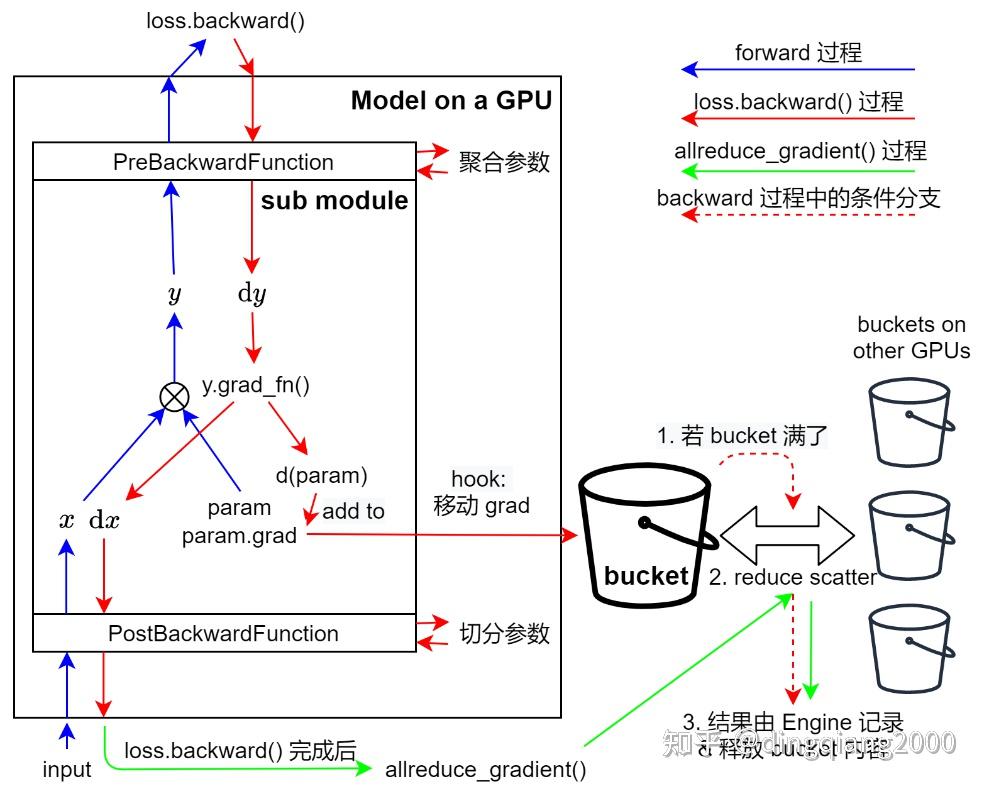
DeepSpeed ZeRO3 的内部实现 - 知乎
DeepSpeed v0.18.5 发布:PyTorch 2.9 适配、ZeRO-3 优化与多项关键修复全面升级!-腾讯云开发者社区-腾讯云
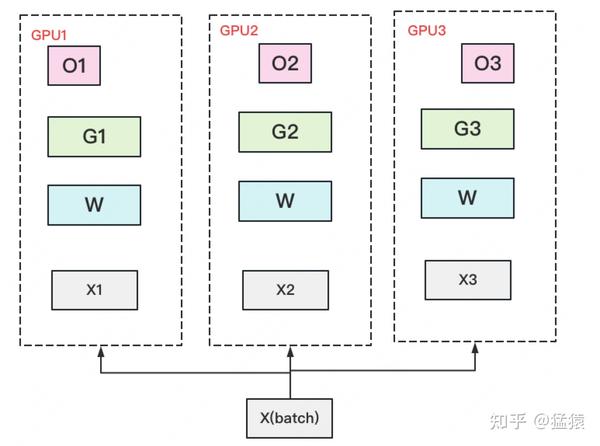
图解大模型训练之:数据并行下篇( DeepSpeed ZeRO,零冗余优化) - 知乎
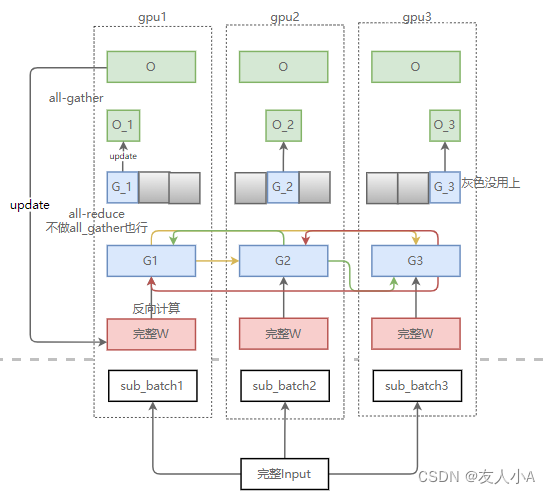
Deepspeed Zero(DP)_zero-dp-CSDN博客
Advertisement Space (336x280)

DeepSpeed ZeRO++: A leap in speed for LLM and chat model training with ...

DeepSpeed ZeRO++: A leap in speed for LLM and chat model training with ...
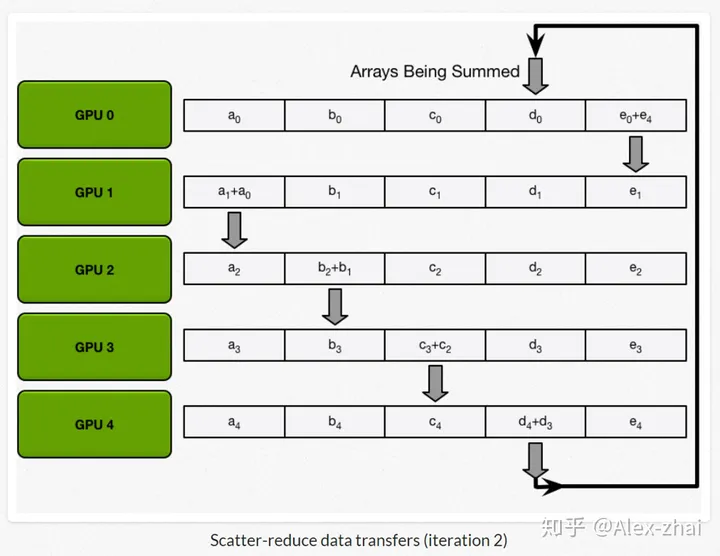
DeepSpeed ZeRO 通信量分析_deepspeed 通信量-CSDN博客
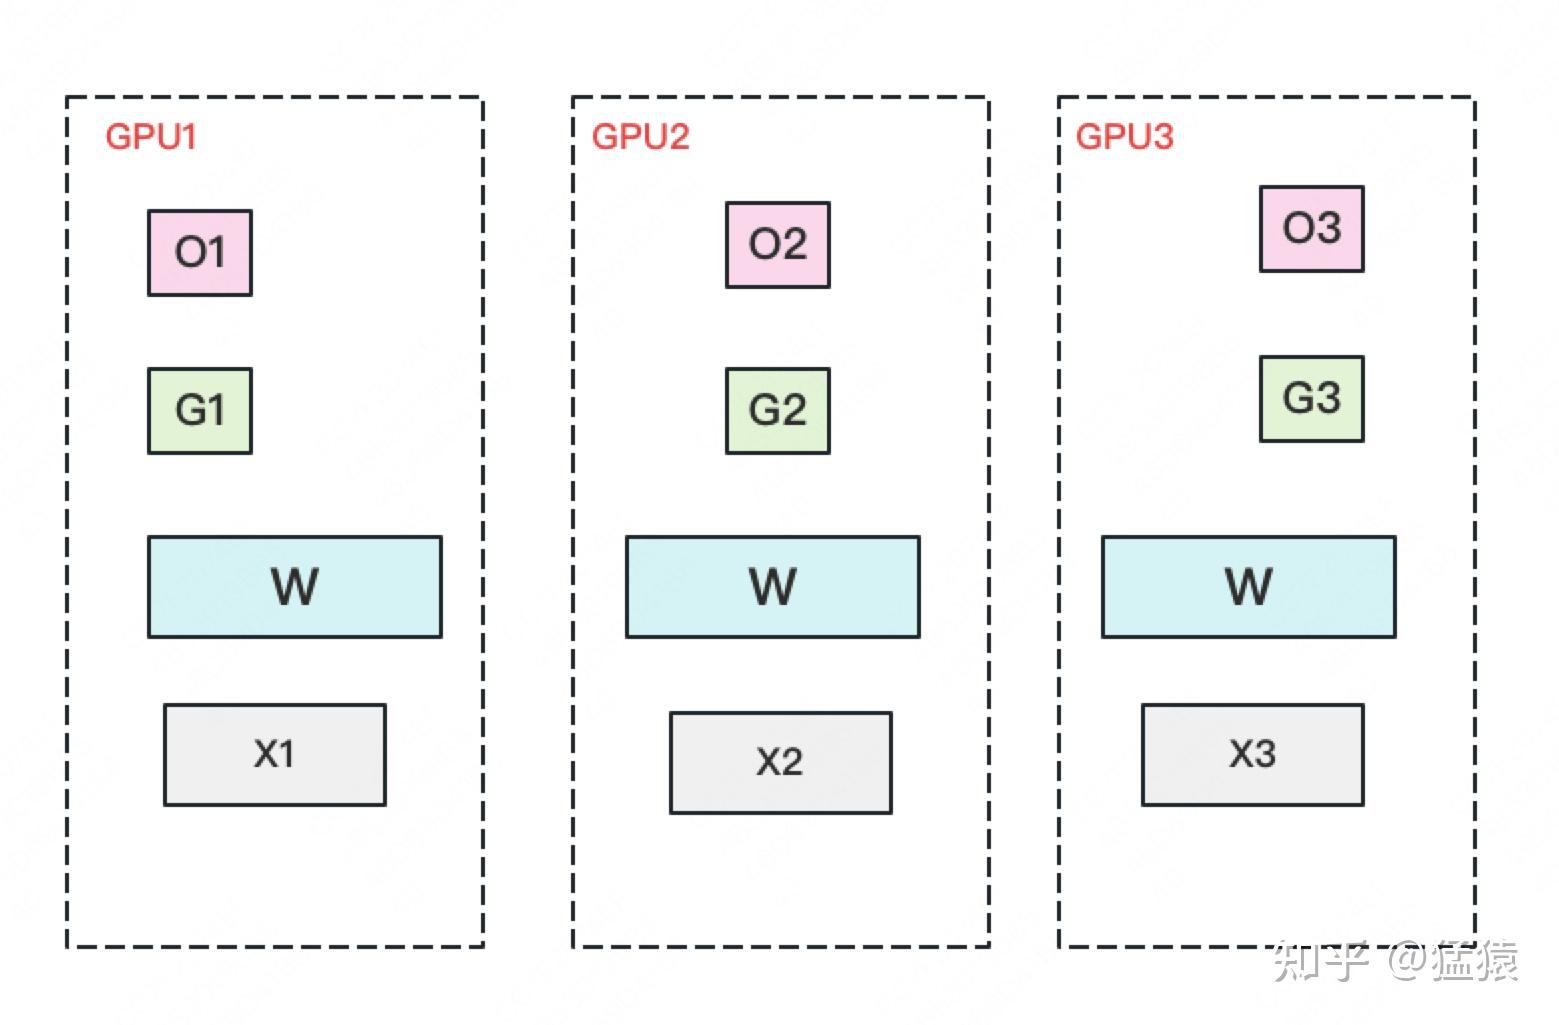
图解大模型训练之:数据并行下篇( DeepSpeed ZeRO,零冗余优化) - 知乎

DeepSpeed ZeRO-3 源码解析:初始化与显存分配_并行策略zero3-CSDN博客

DeepSpeed ZeRO理论与VLM大模型训练实践 - 知乎