
Deploy Dflash Speculative Decoding On Vllm Gemma 4 Ravchat
Deploy DFlash Speculative Decoding on vLLM (Gemma 4) | RavChat
Deploy DFlash Speculative Decoding on vLLM (Gemma 4) | RavChat
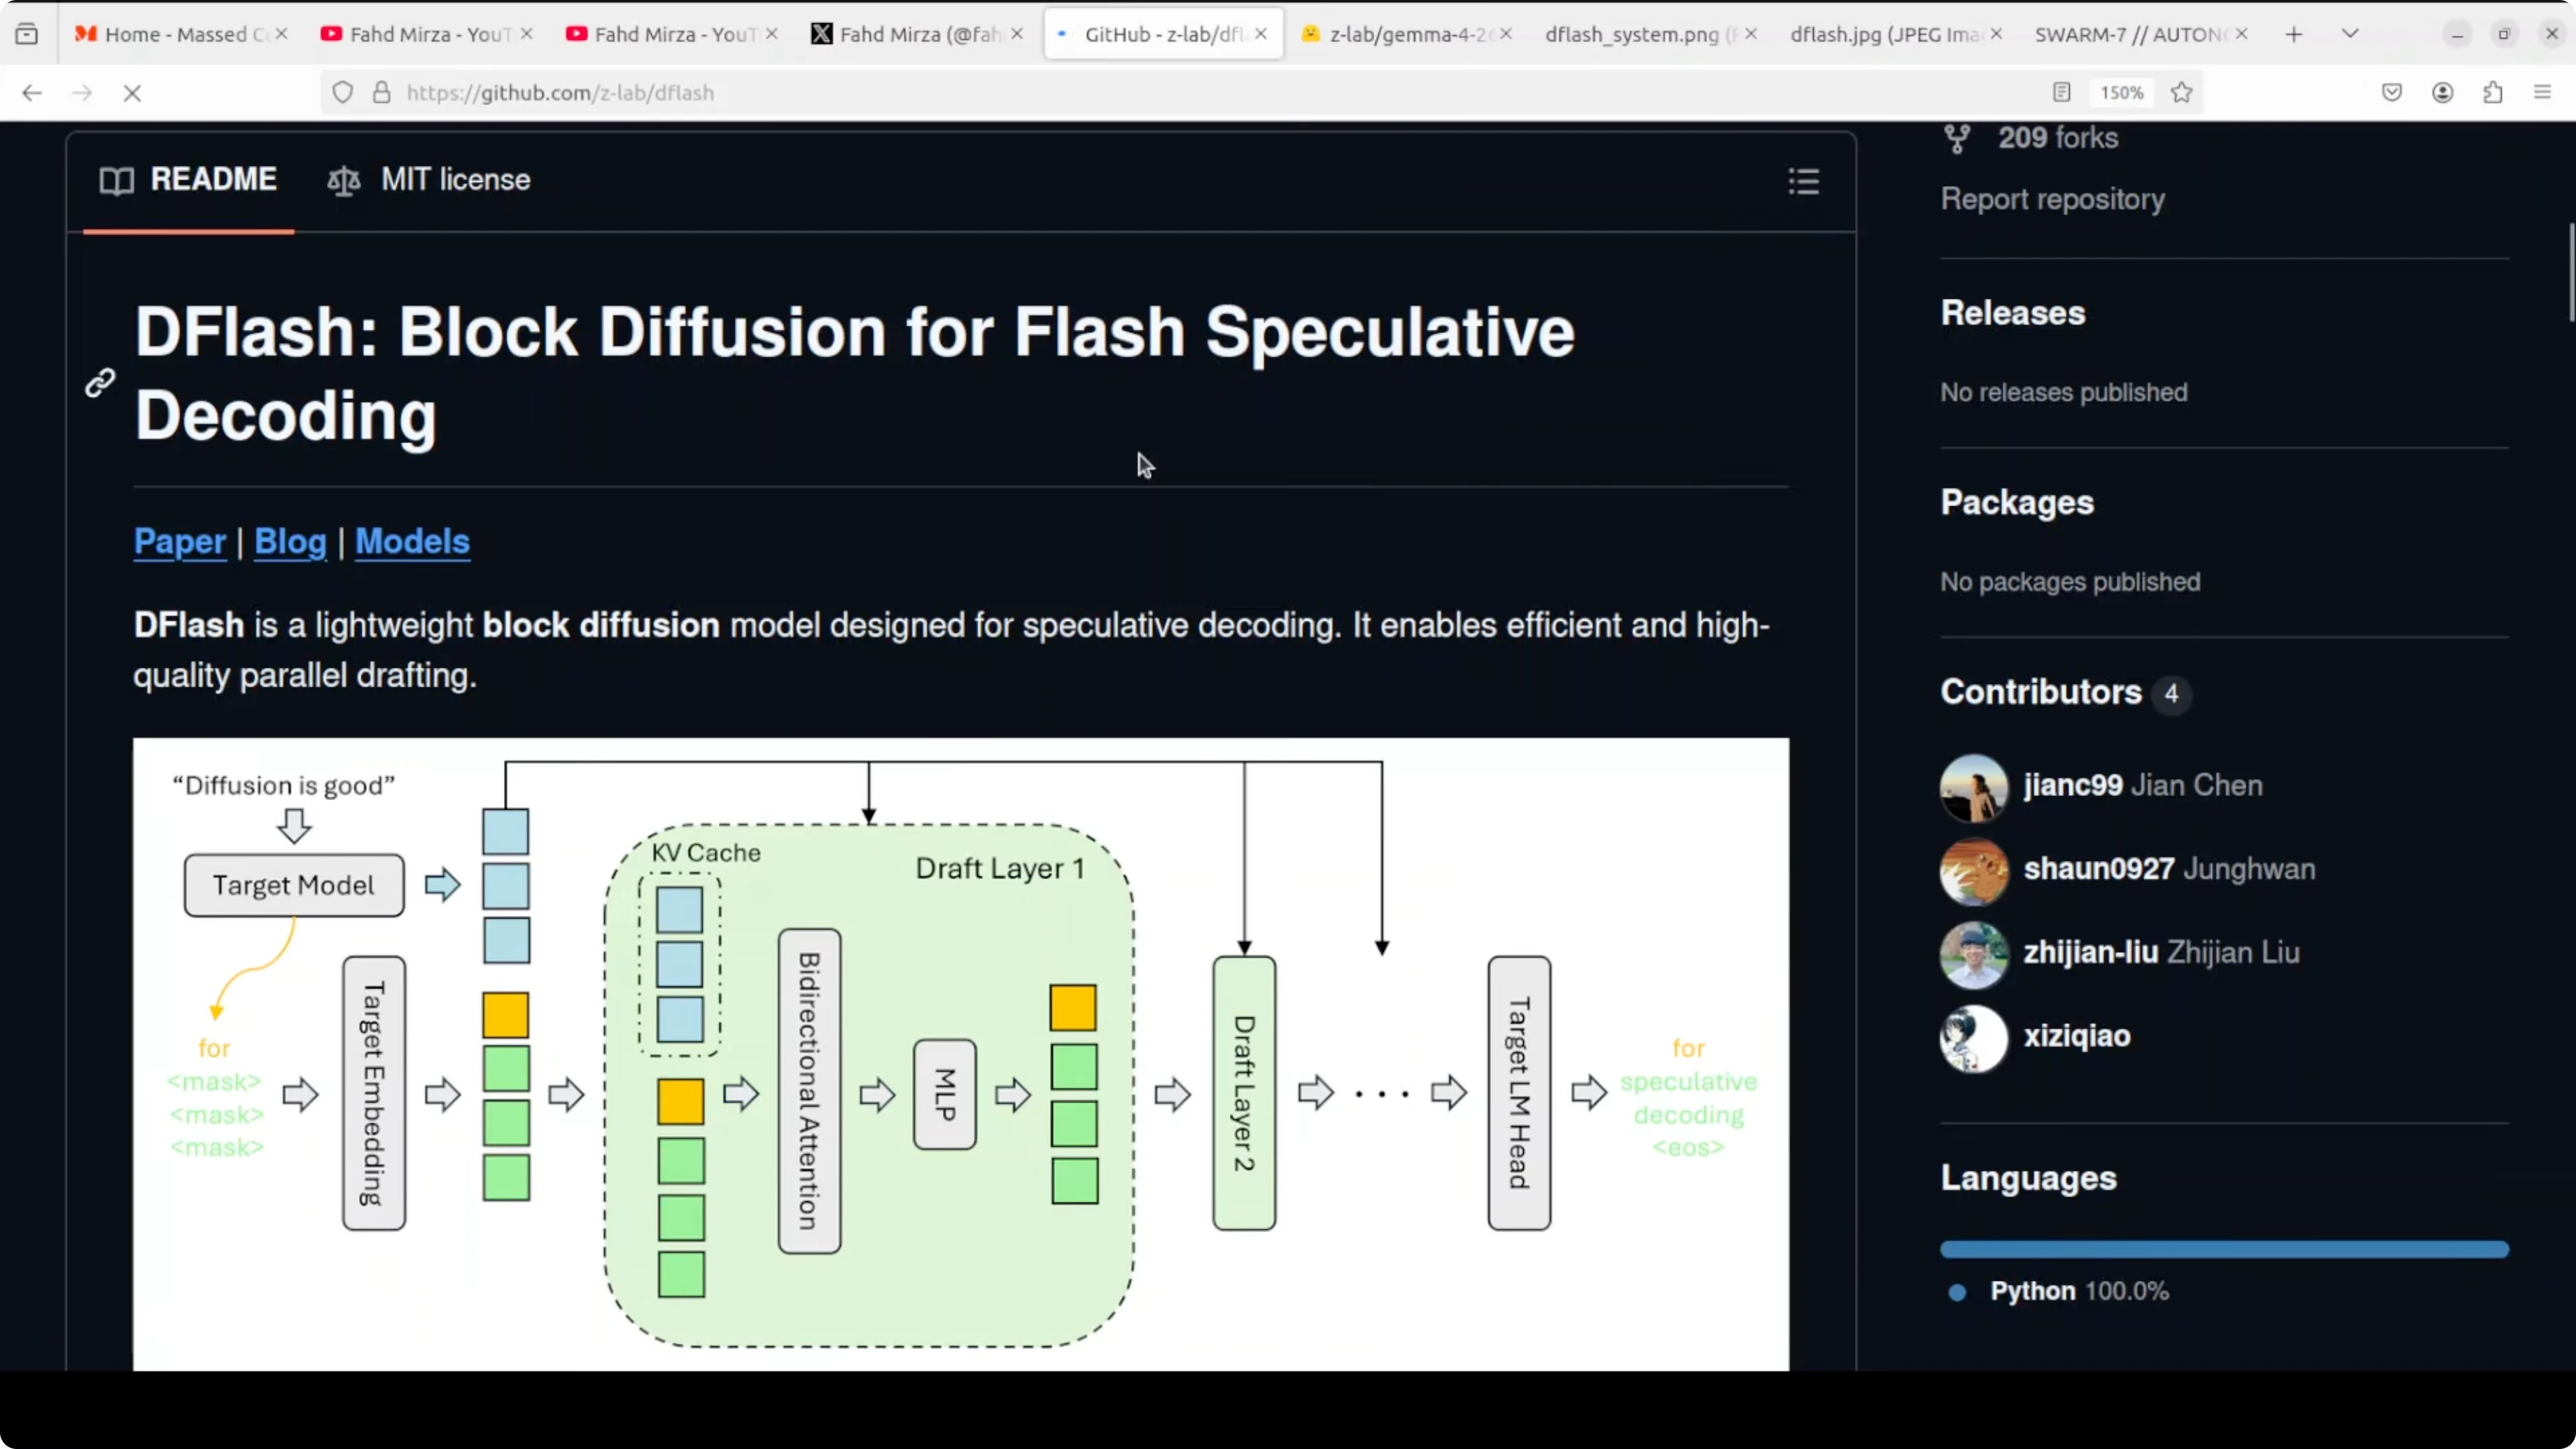
DFlash Drafter for Gemma 4 26B: Run Speculative Decoding Locally
DFlash Drafter for Gemma 4 26B: Run Speculative Decoding Locally
DFlash Drafter for Gemma 4 26B: Run Speculative Decoding Locally
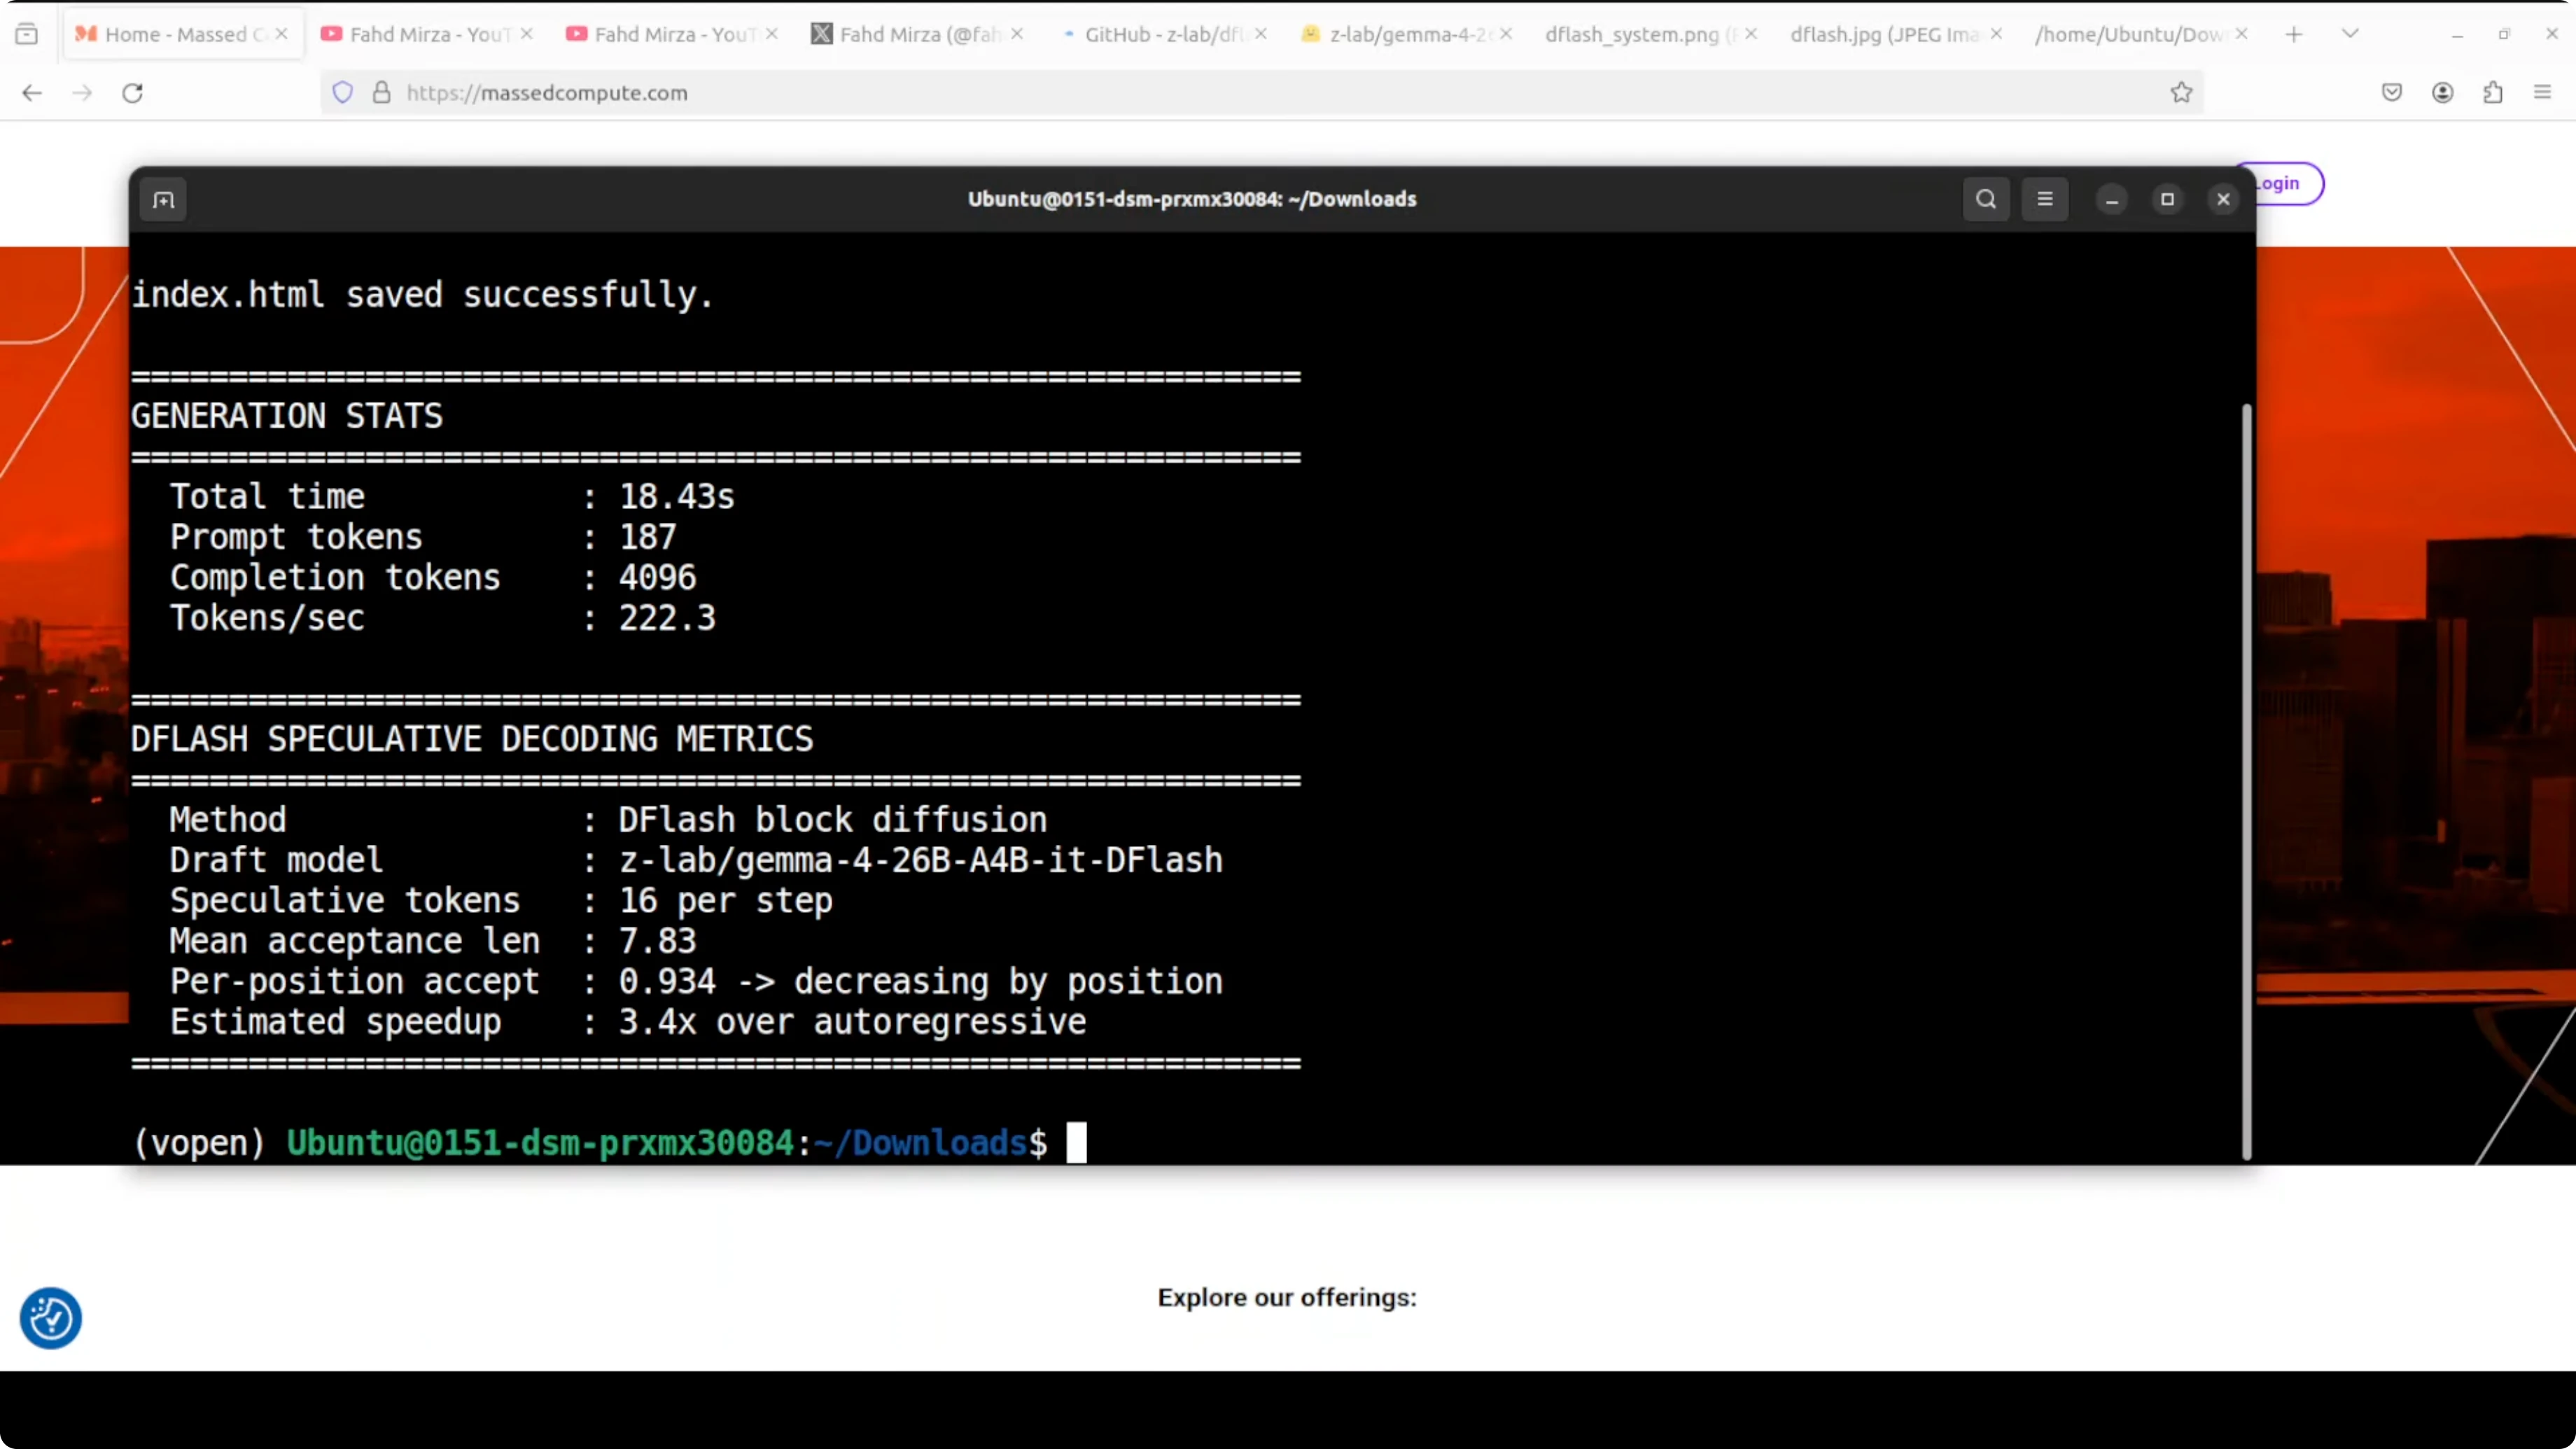
DFlash Drafter for Gemma 4 26B: Run Speculative Decoding Locally

MTP Speculative Decoding with the 12B Gemma 4 QAT Model on NVIDIA L4 ...
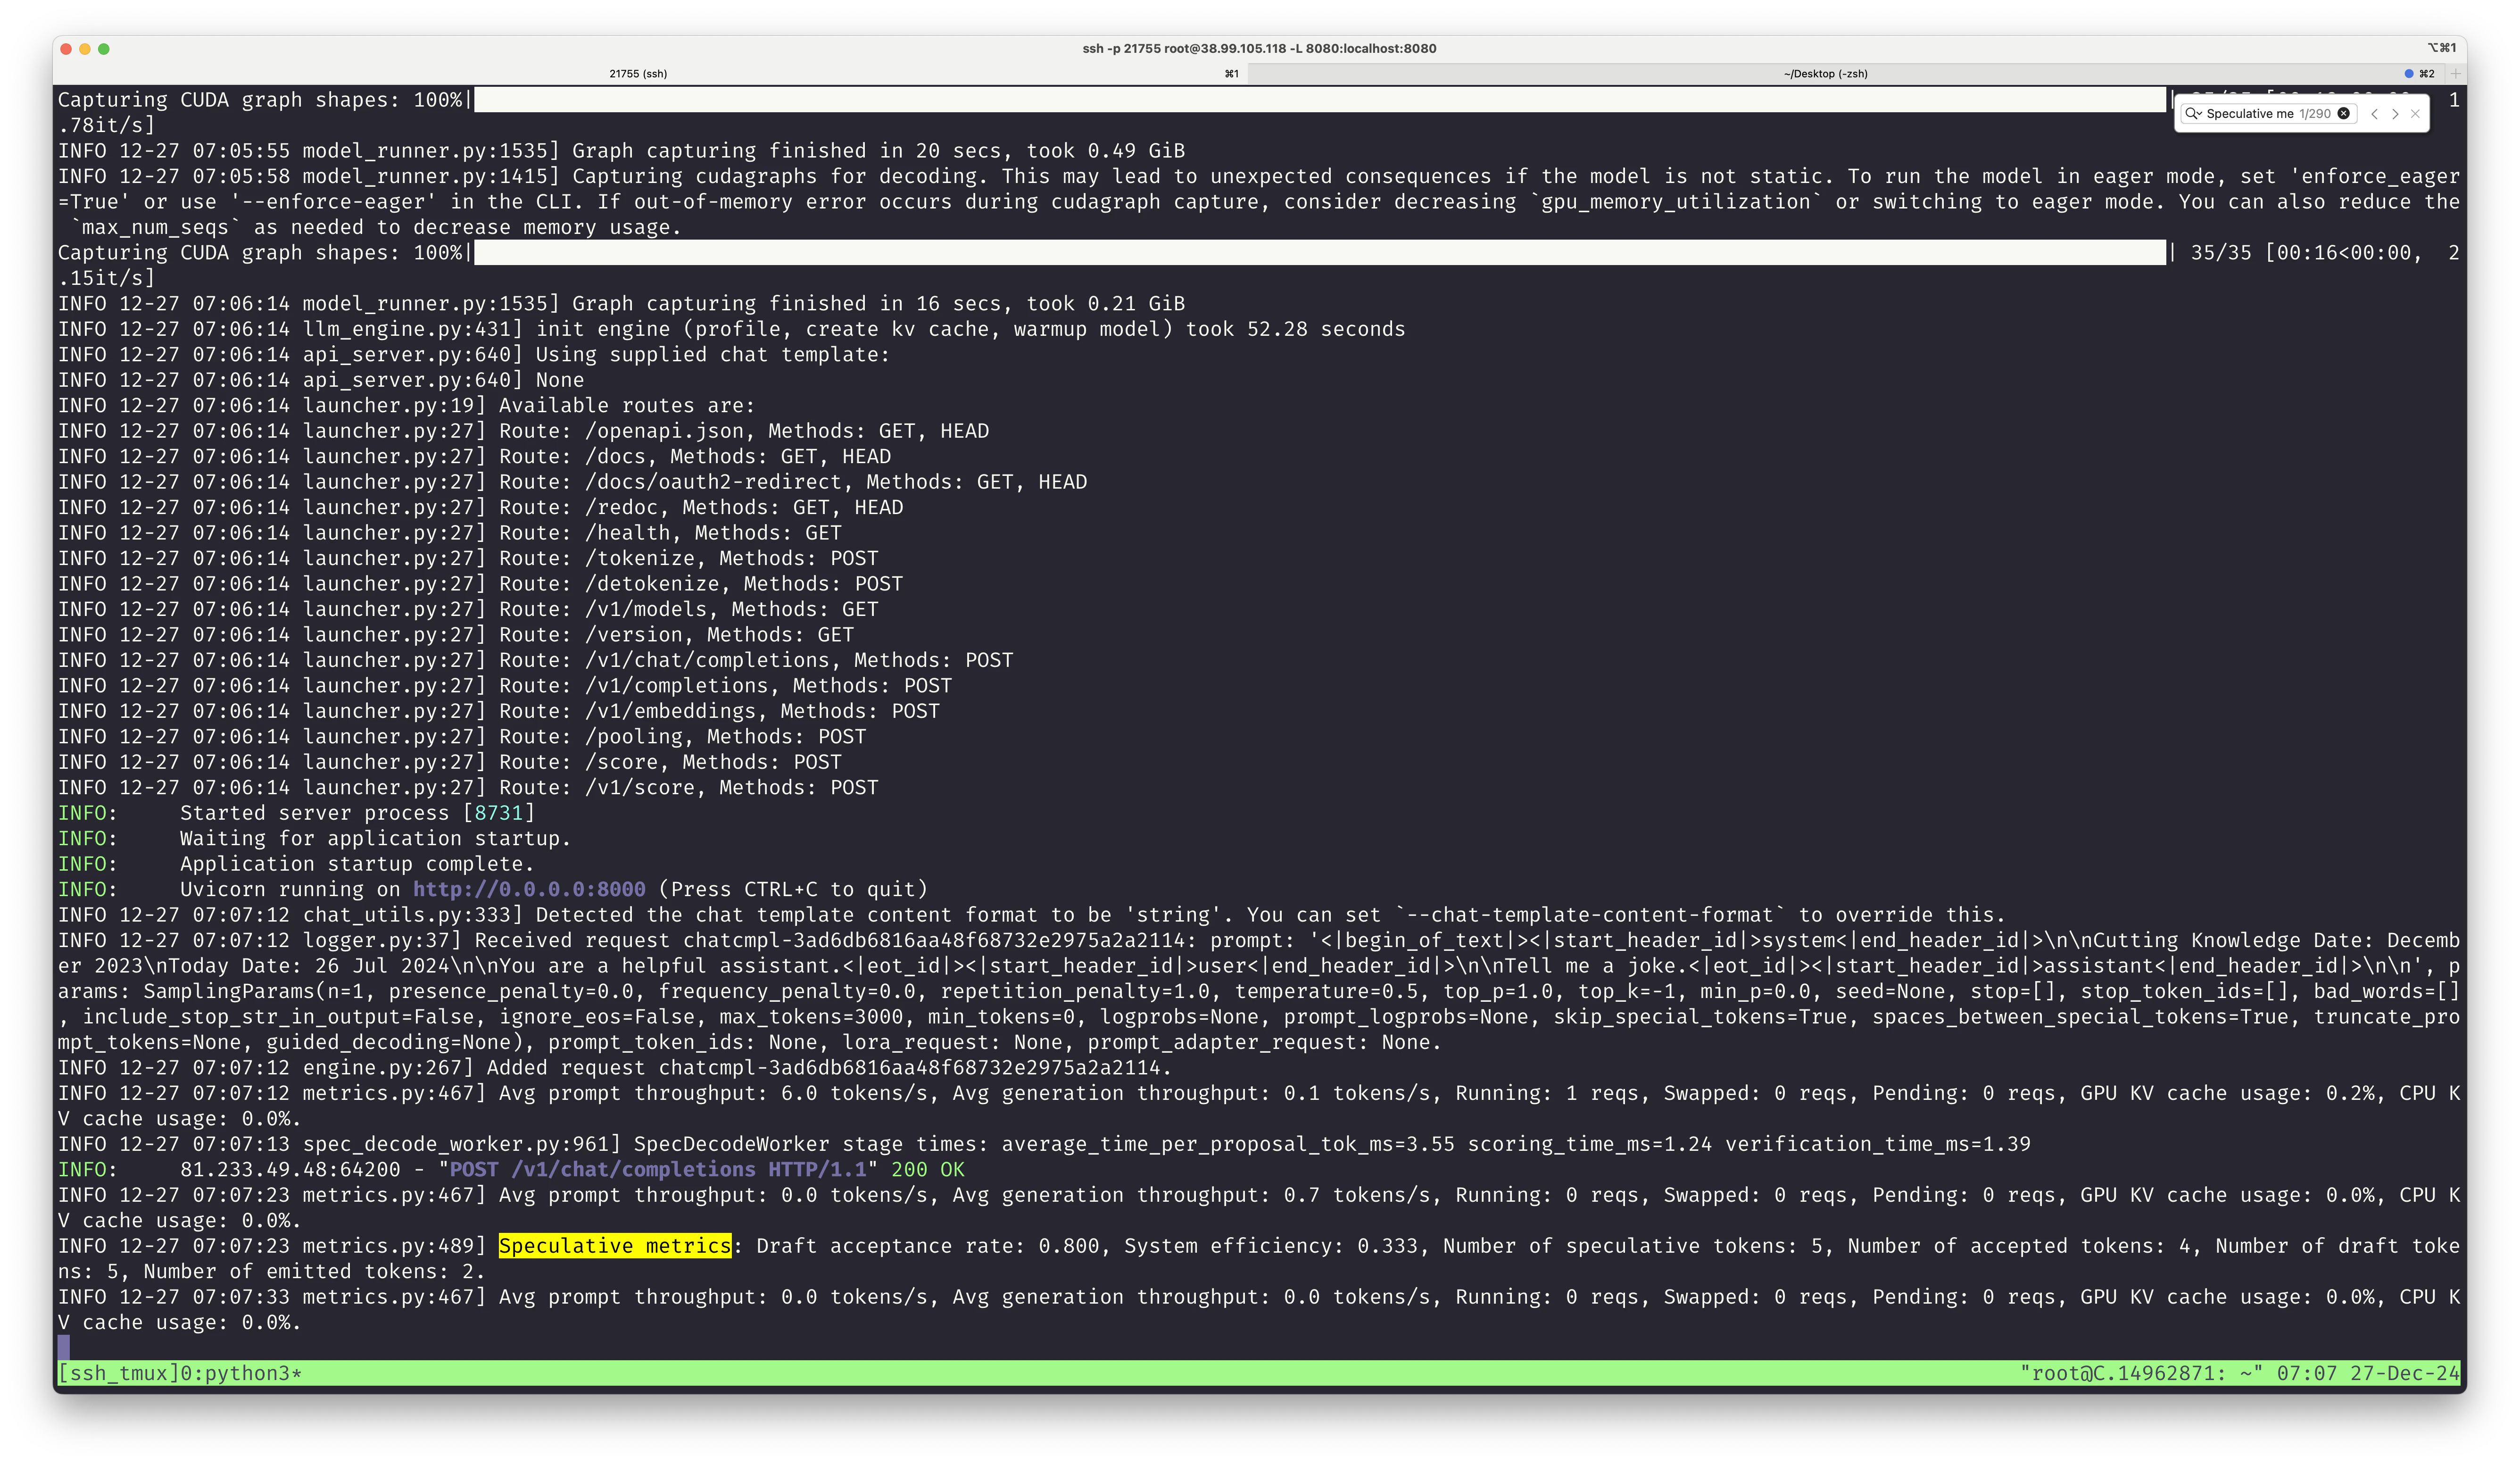
Llama 3.3 on vLLM with Speculative Decoding | olof.tech

DFlash speculative decoding on Apple Silicon: 4.1x on Qwen3.5-9B, now ...
[Feature]: Add Eagle3 Speculative Decoding Support for Gemma 4 Target ...
Advertisement Space (300x250)
Ollama v0.23.1 で Gemma 4 の MTP speculative decoding が Mac 対応|32GB Mac に ...
Diving into speculative decoding training support for vLLM with ...
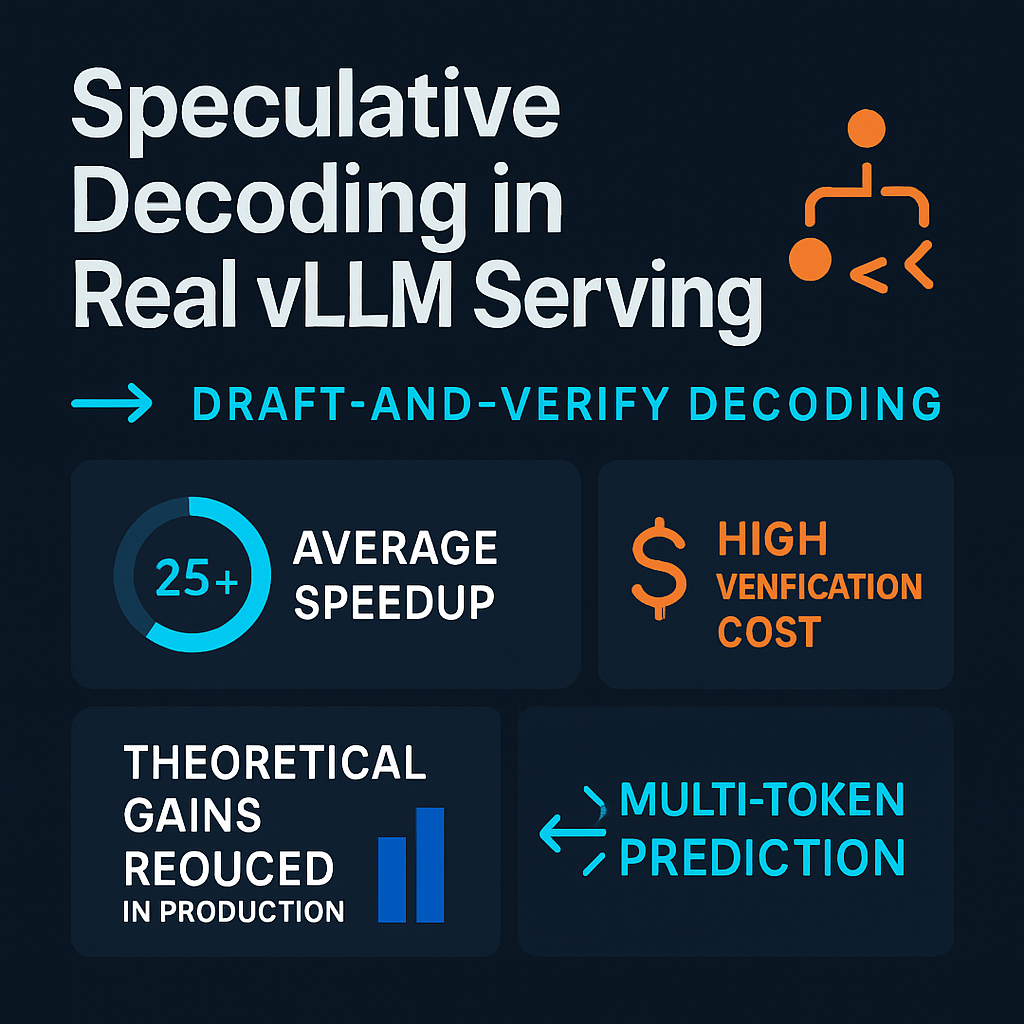
Speculative Decoding in Real vLLM Serving — AI Post Transformers

Lecture 22: Hacker's Guide to Speculative Decoding in VLLM - YouTube
How Speculative Decoding Boosts vLLM Performance by up to 2.8x | vLLM Blog
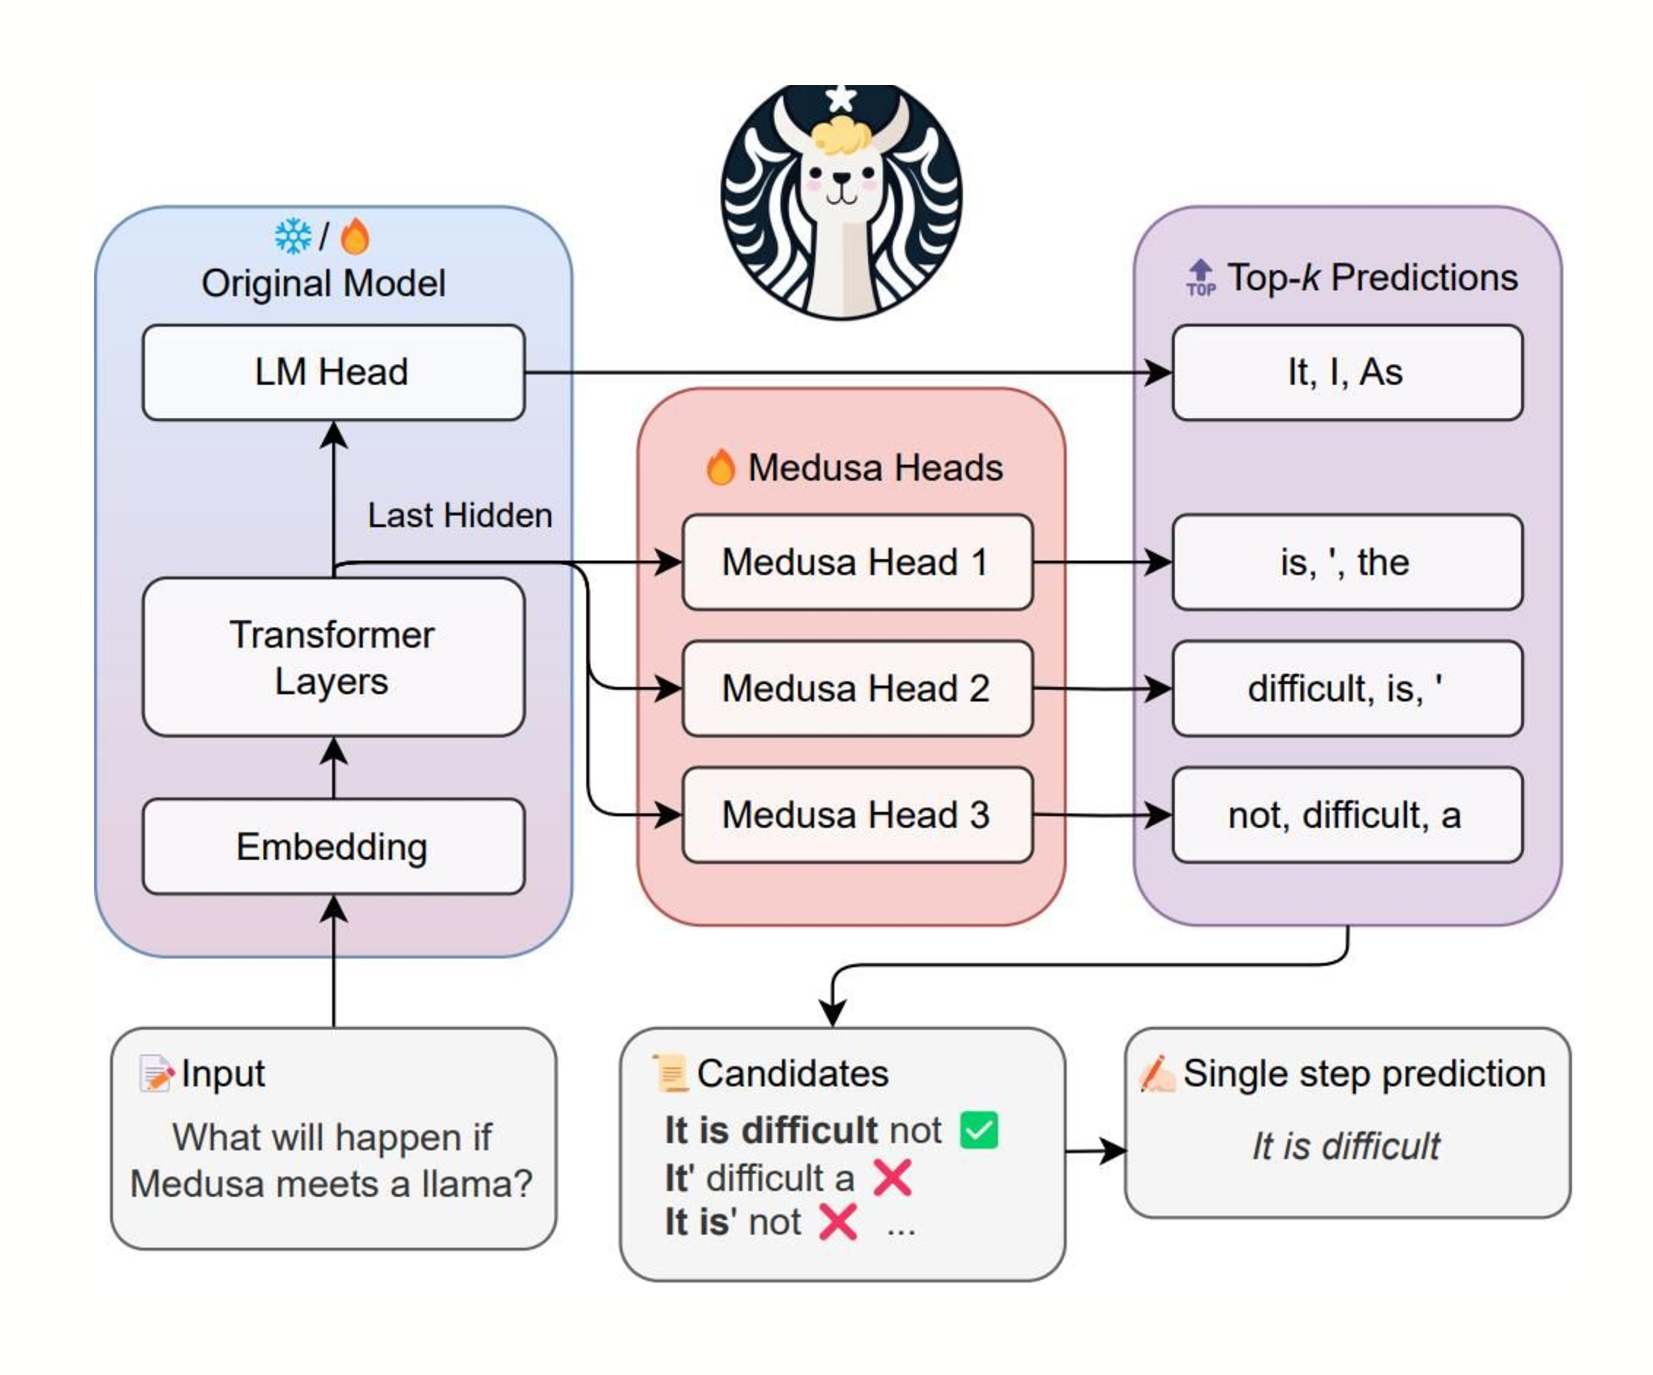
Speculative Decoding in vLLM | OpenLM.ai
[Bug]: Ngram speculative decoding doesn't work in vLLM 0.8.3/0.8.4 with ...
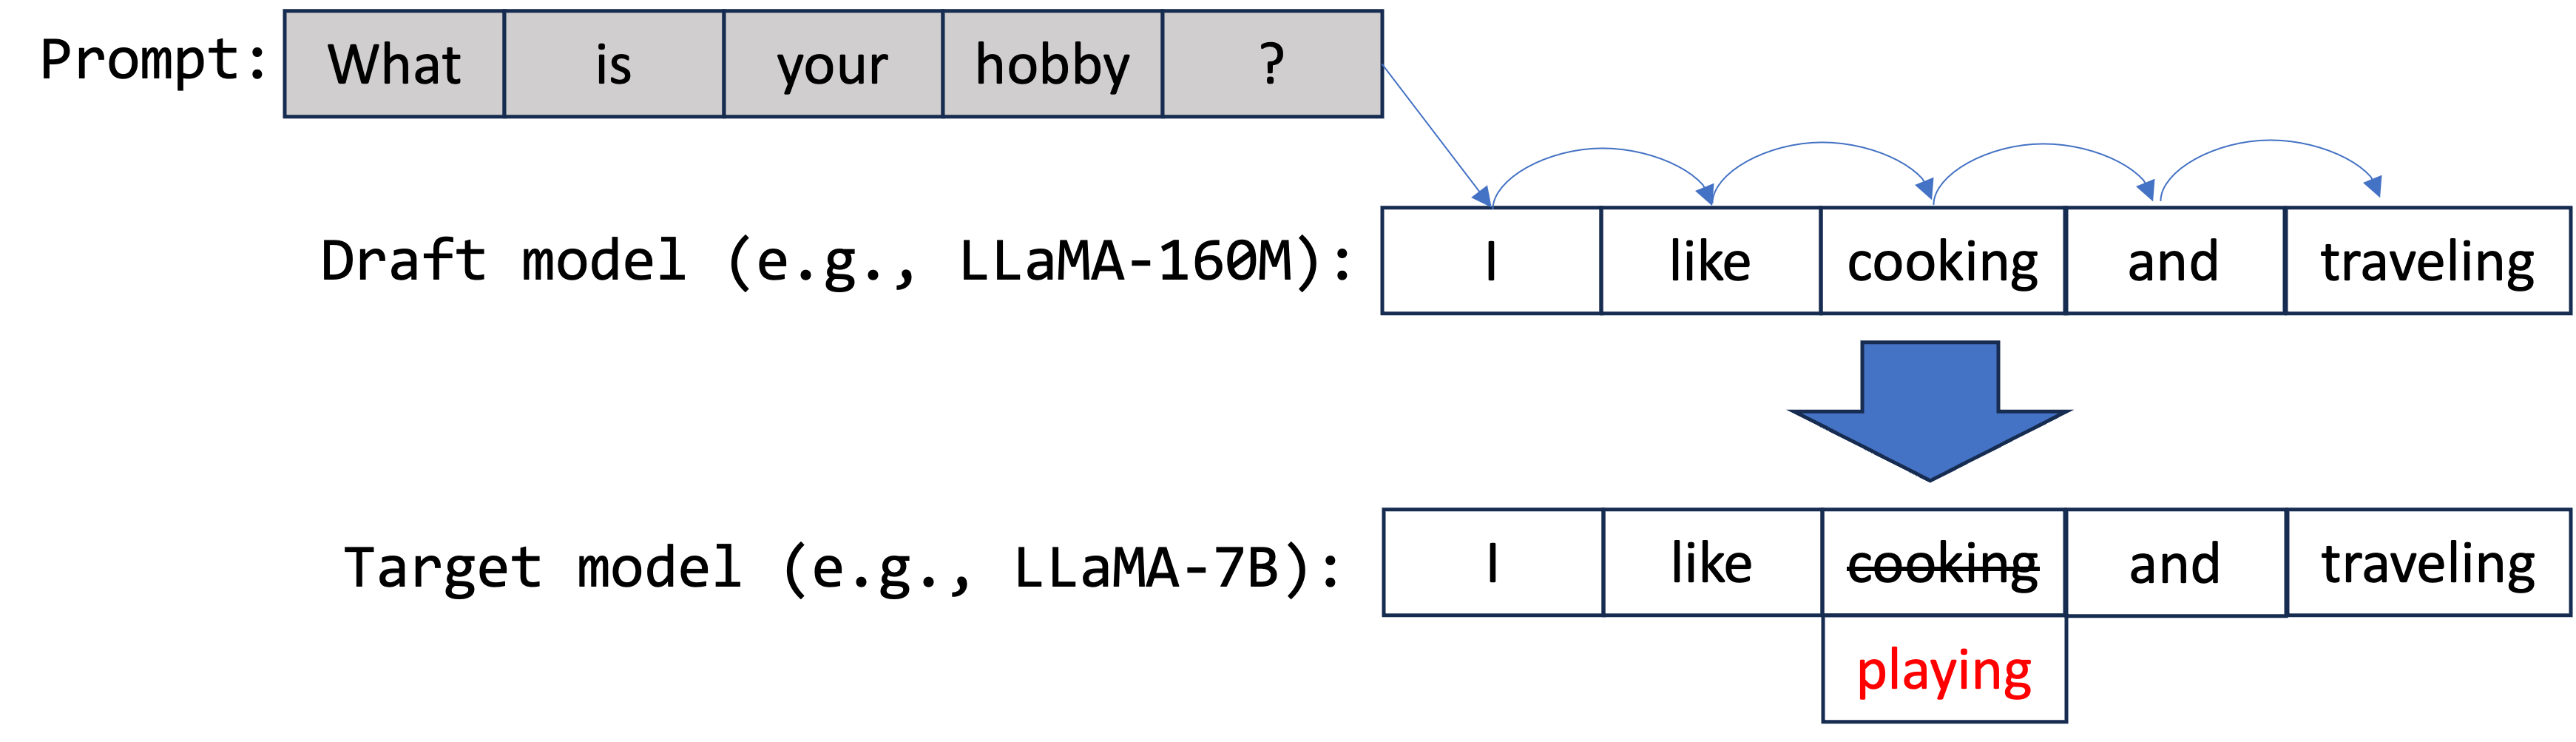
How Speculative Decoding Boosts vLLM Performance by up to 2.8x | vLLM Blog
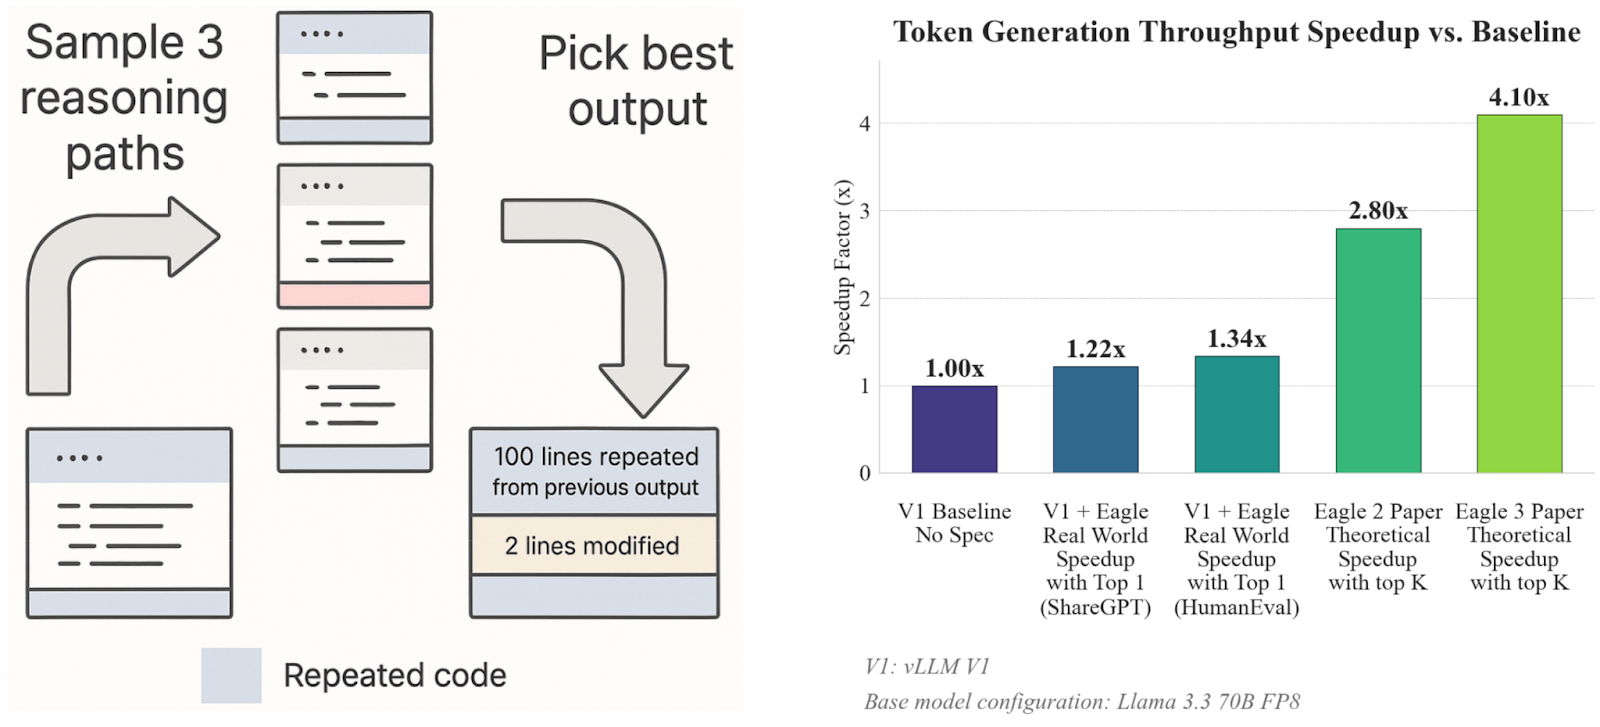
Fastest Speculative Decoding in vLLM with Arctic Inference and Arctic ...
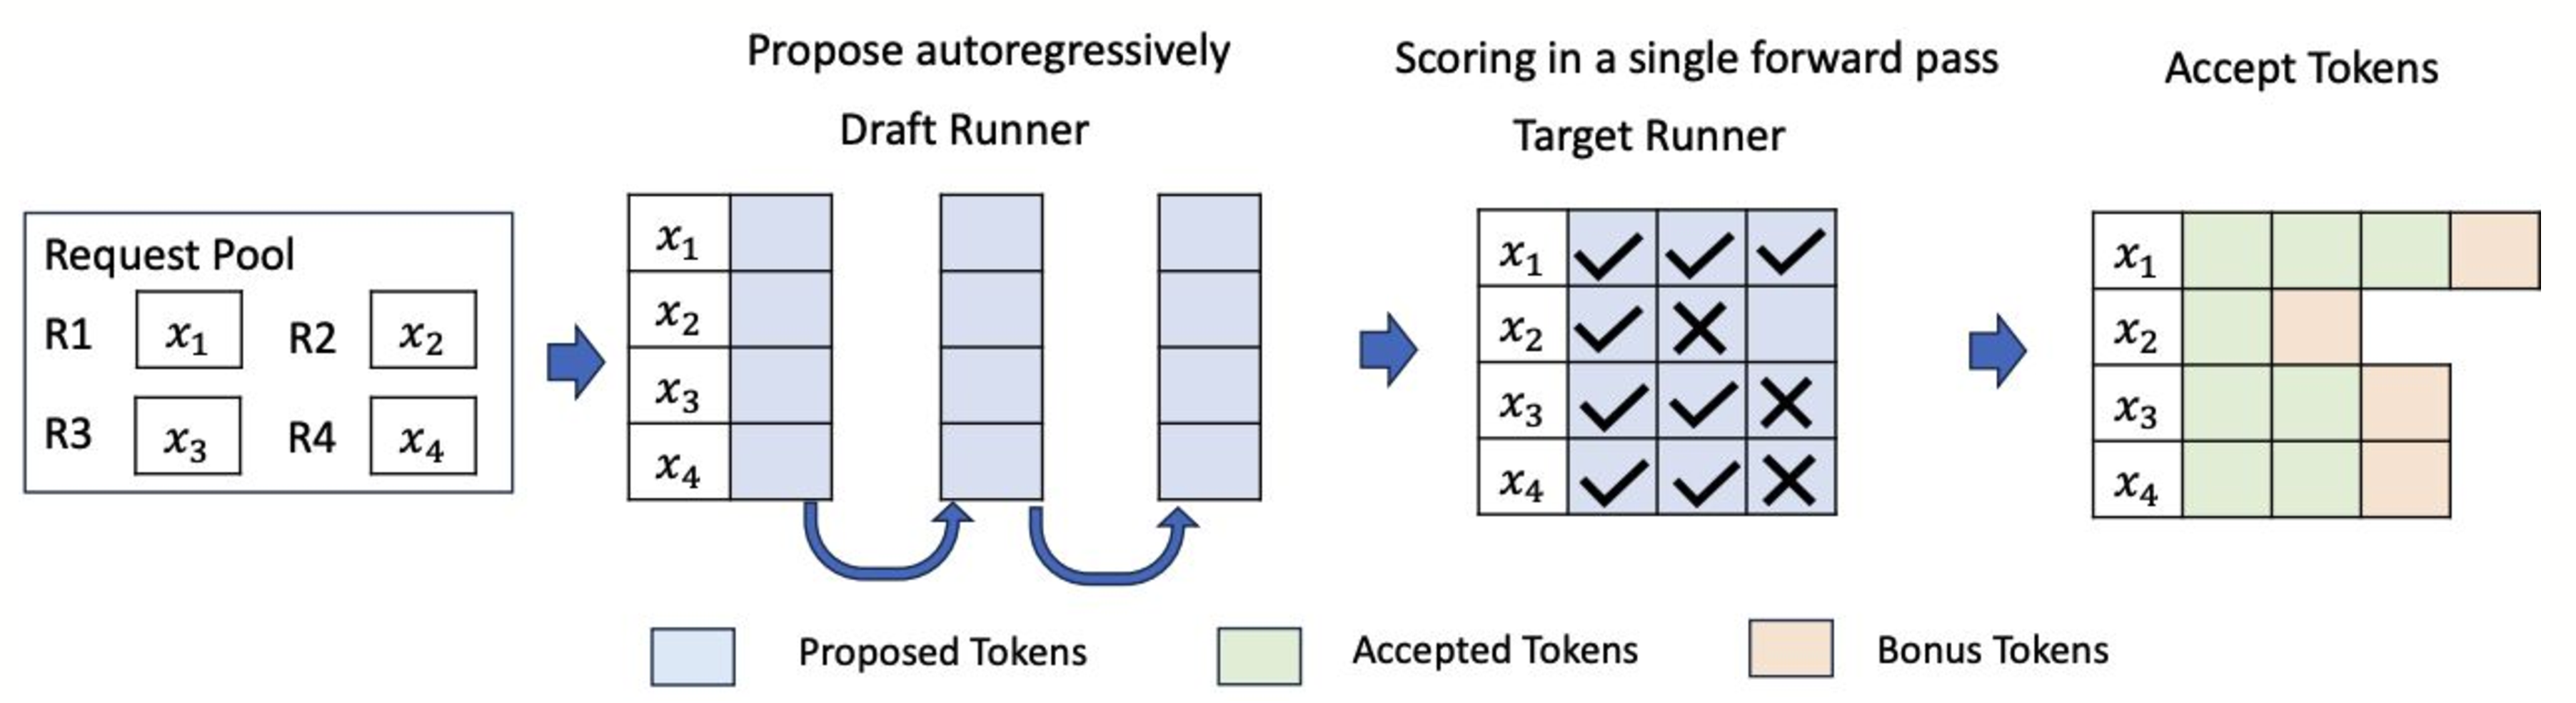
How Speculative Decoding Boosts vLLM Performance by up to 2.8x | vLLM Blog
Advertisement Space (336x280)

Gemma 4 Models - which vLLM version? Any PRs spotted? - #26 by WilliamD ...

Gemma 4 Models - which vLLM version? Any PRs spotted? - DGX Spark ...
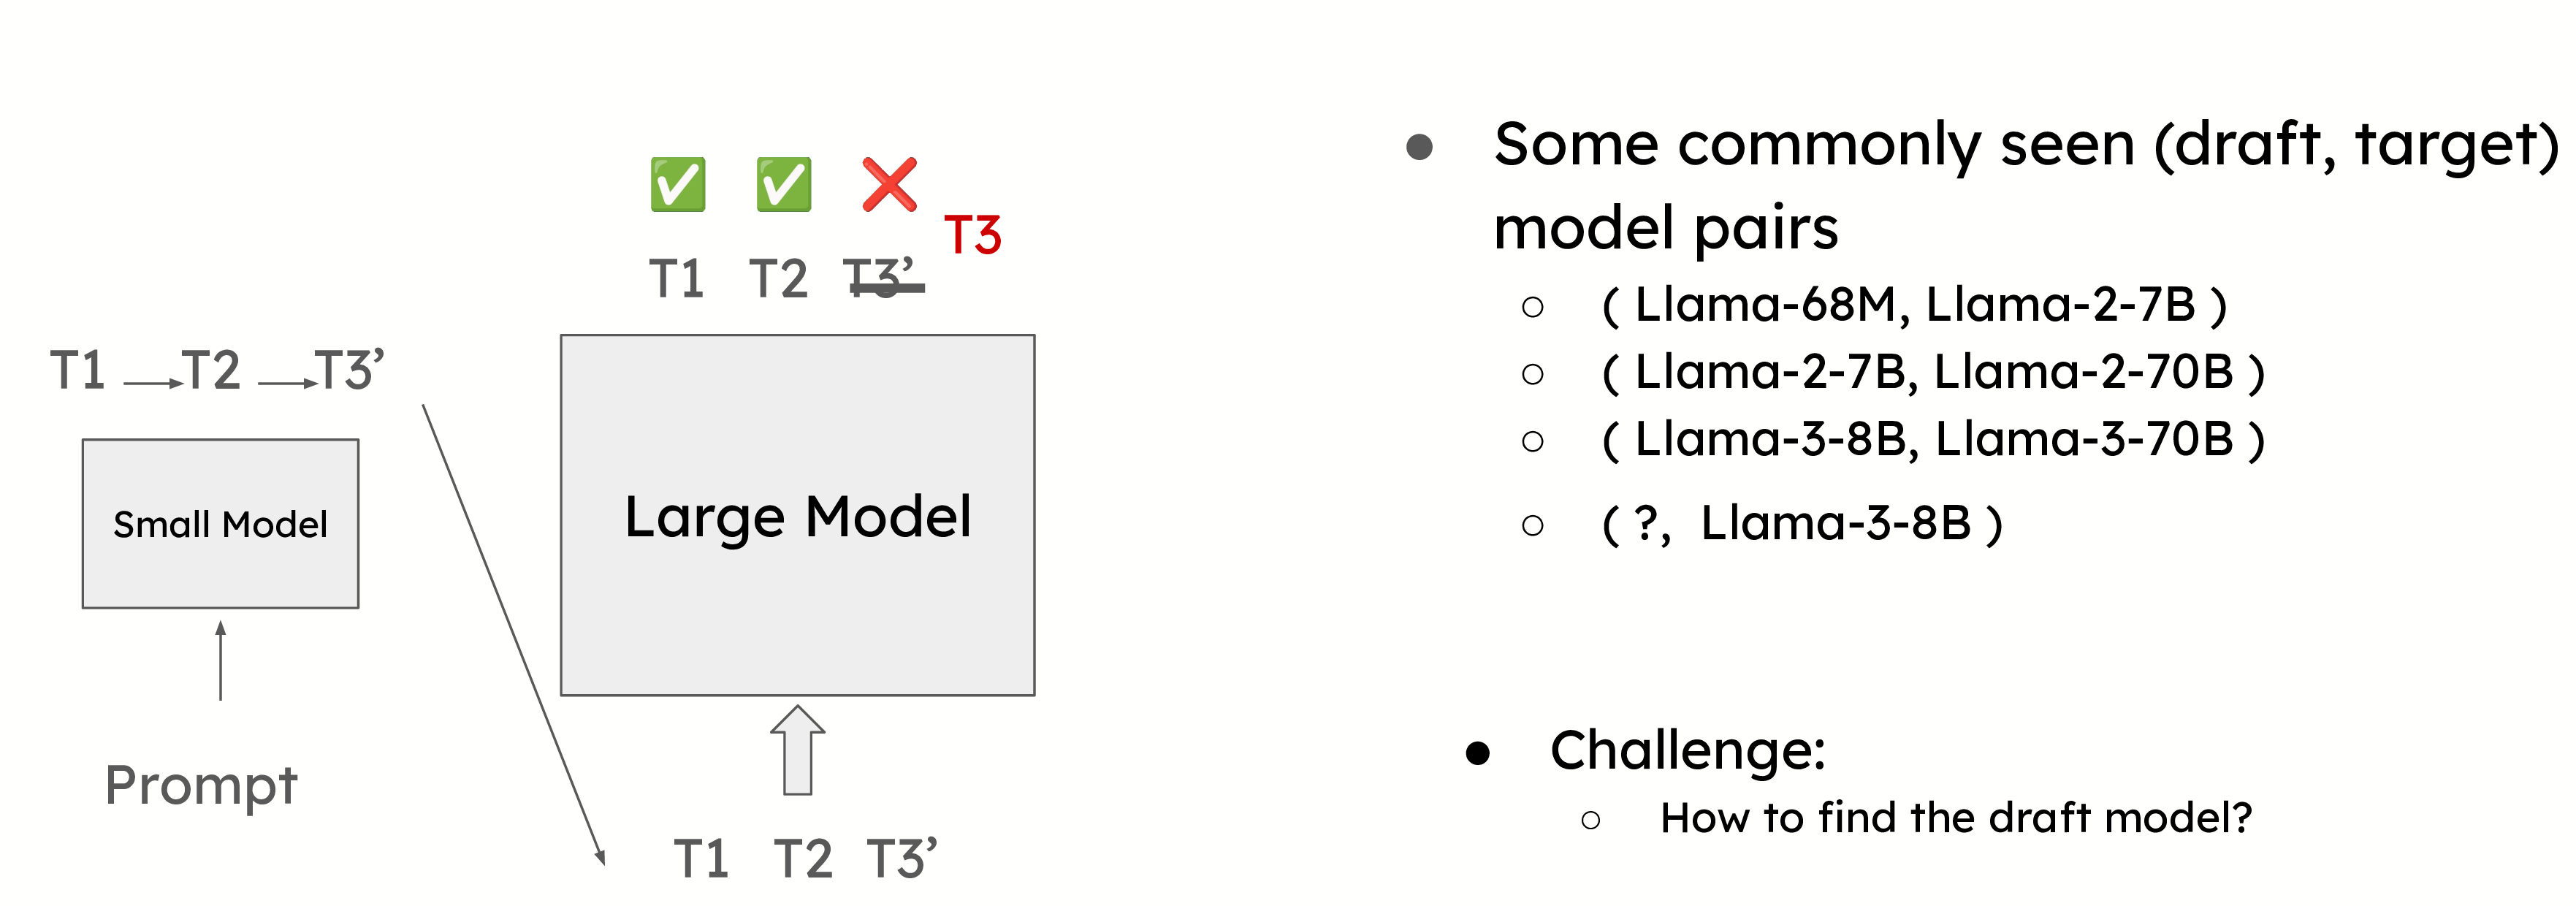
Speculative Decoding in vLLM | OpenLM.ai
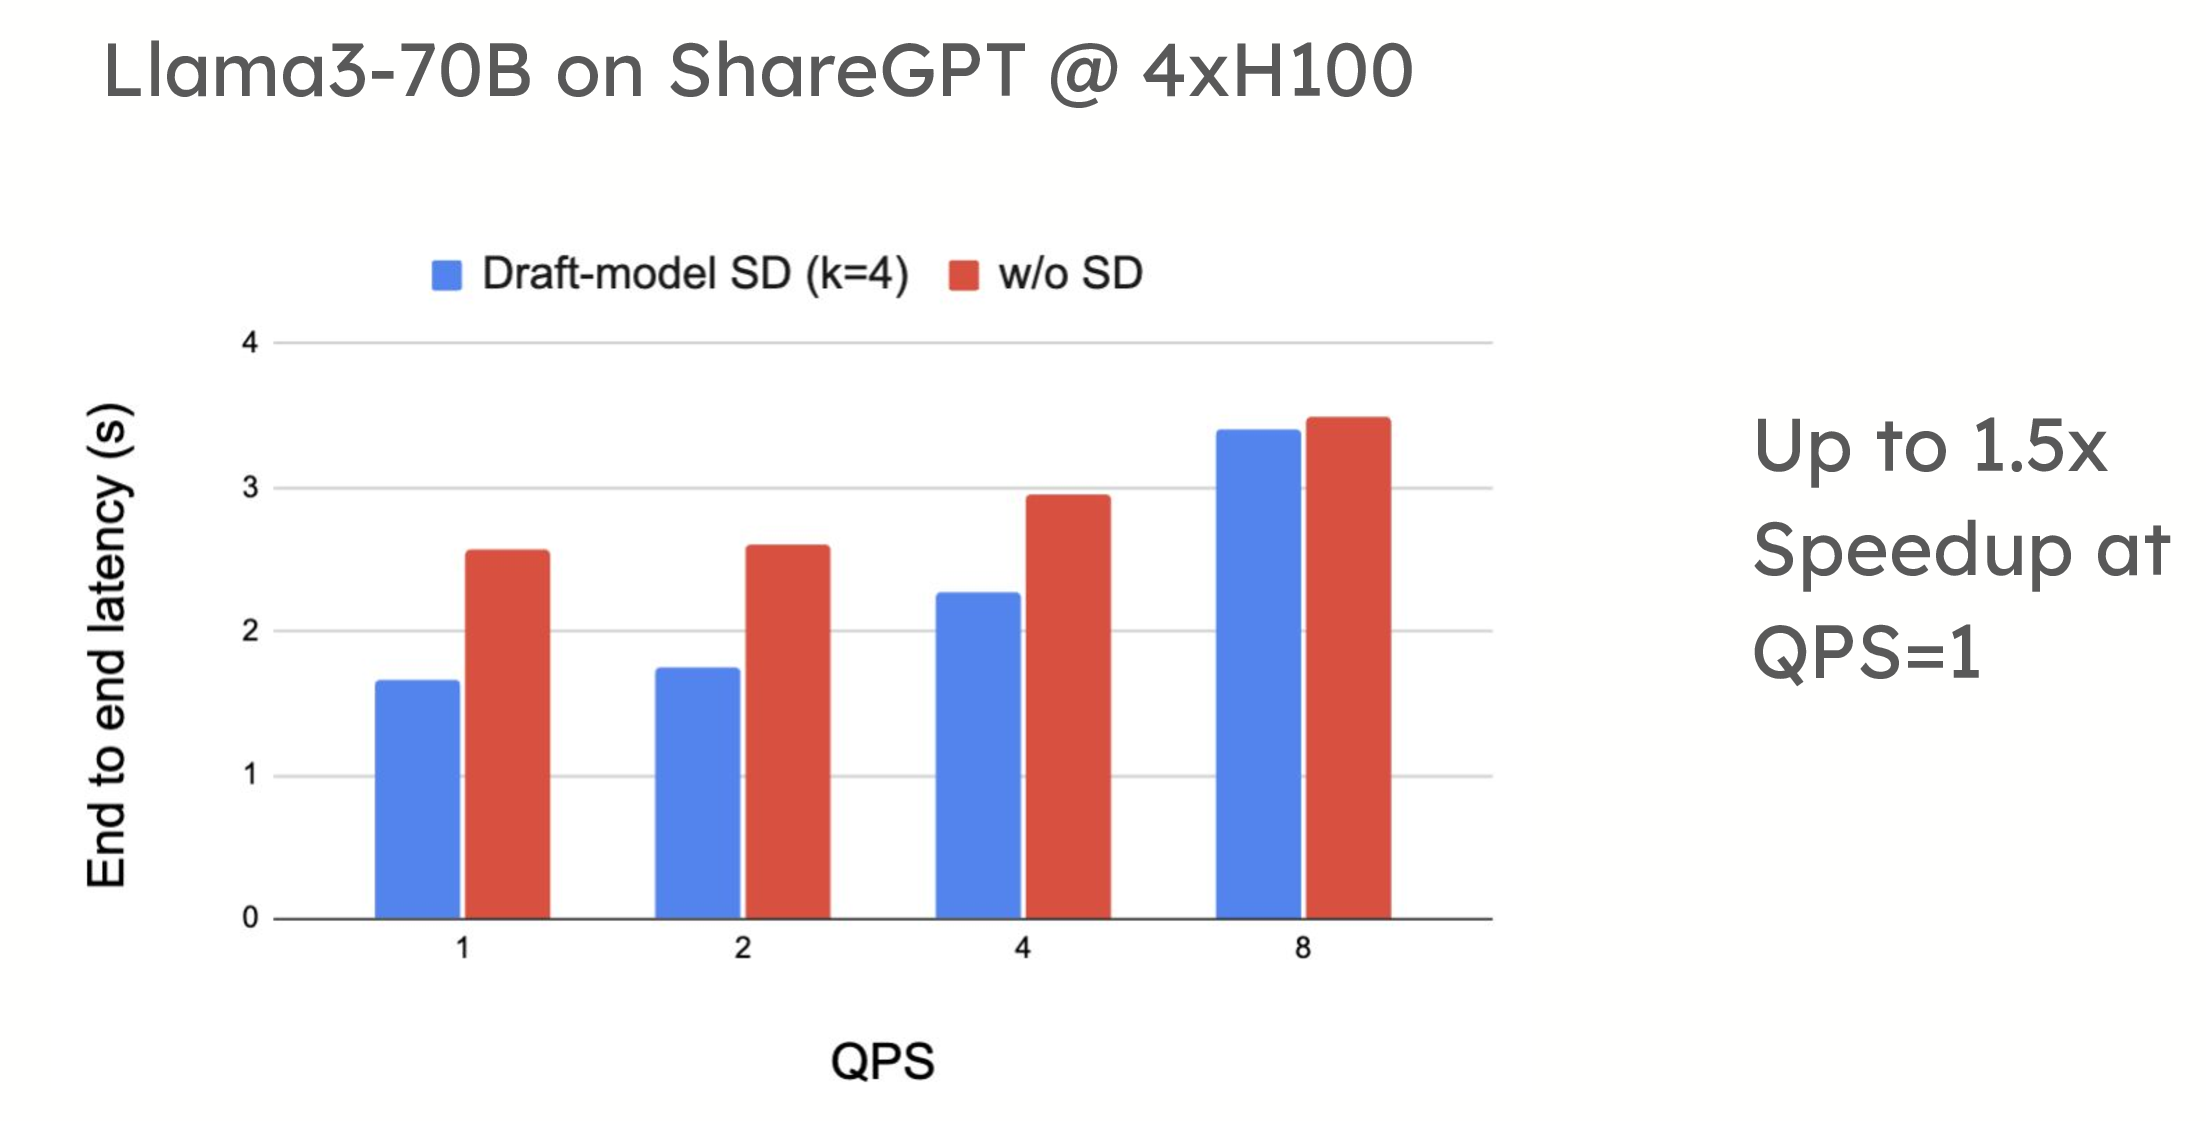
How Speculative Decoding Boosts vLLM Performance by up to 2.8x | vLLM Blog
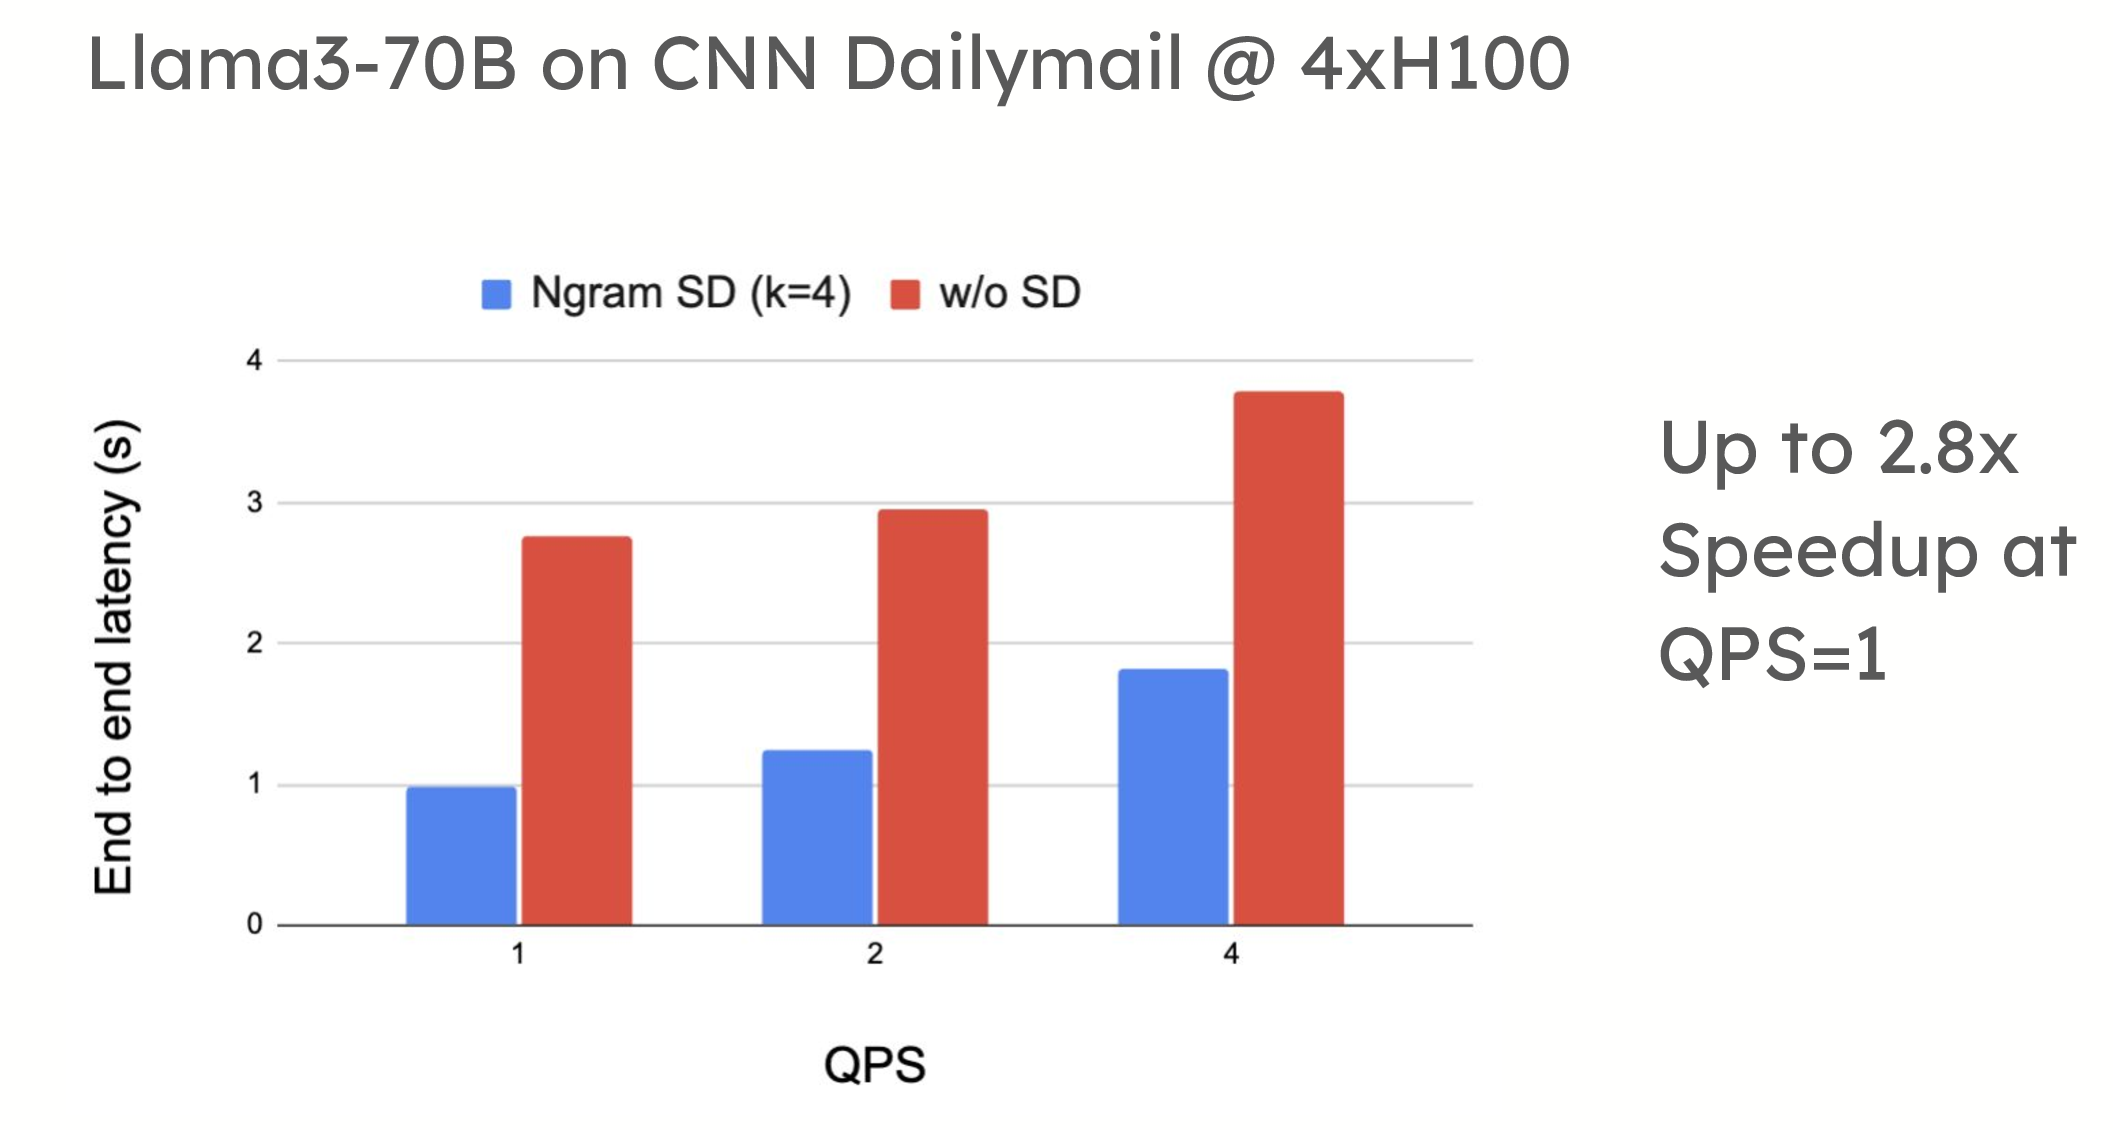
Speculative Decoding in vLLM | OpenLM.ai
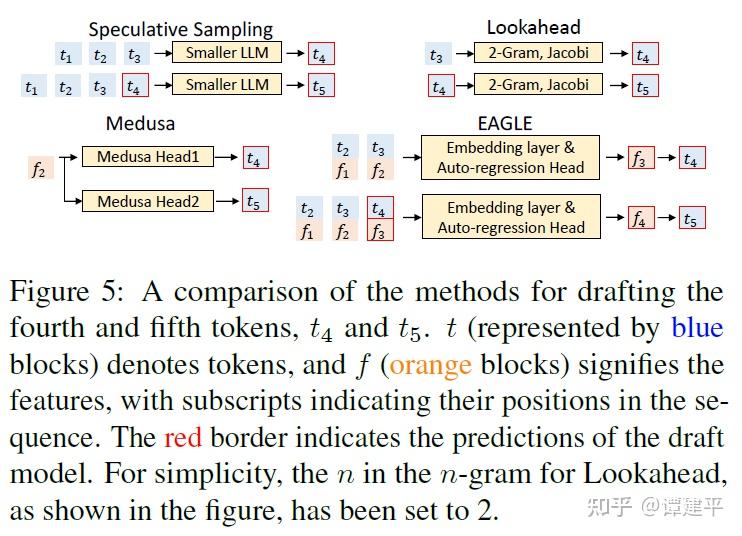
vllm Speculative decoding 论文整理总结 - 知乎
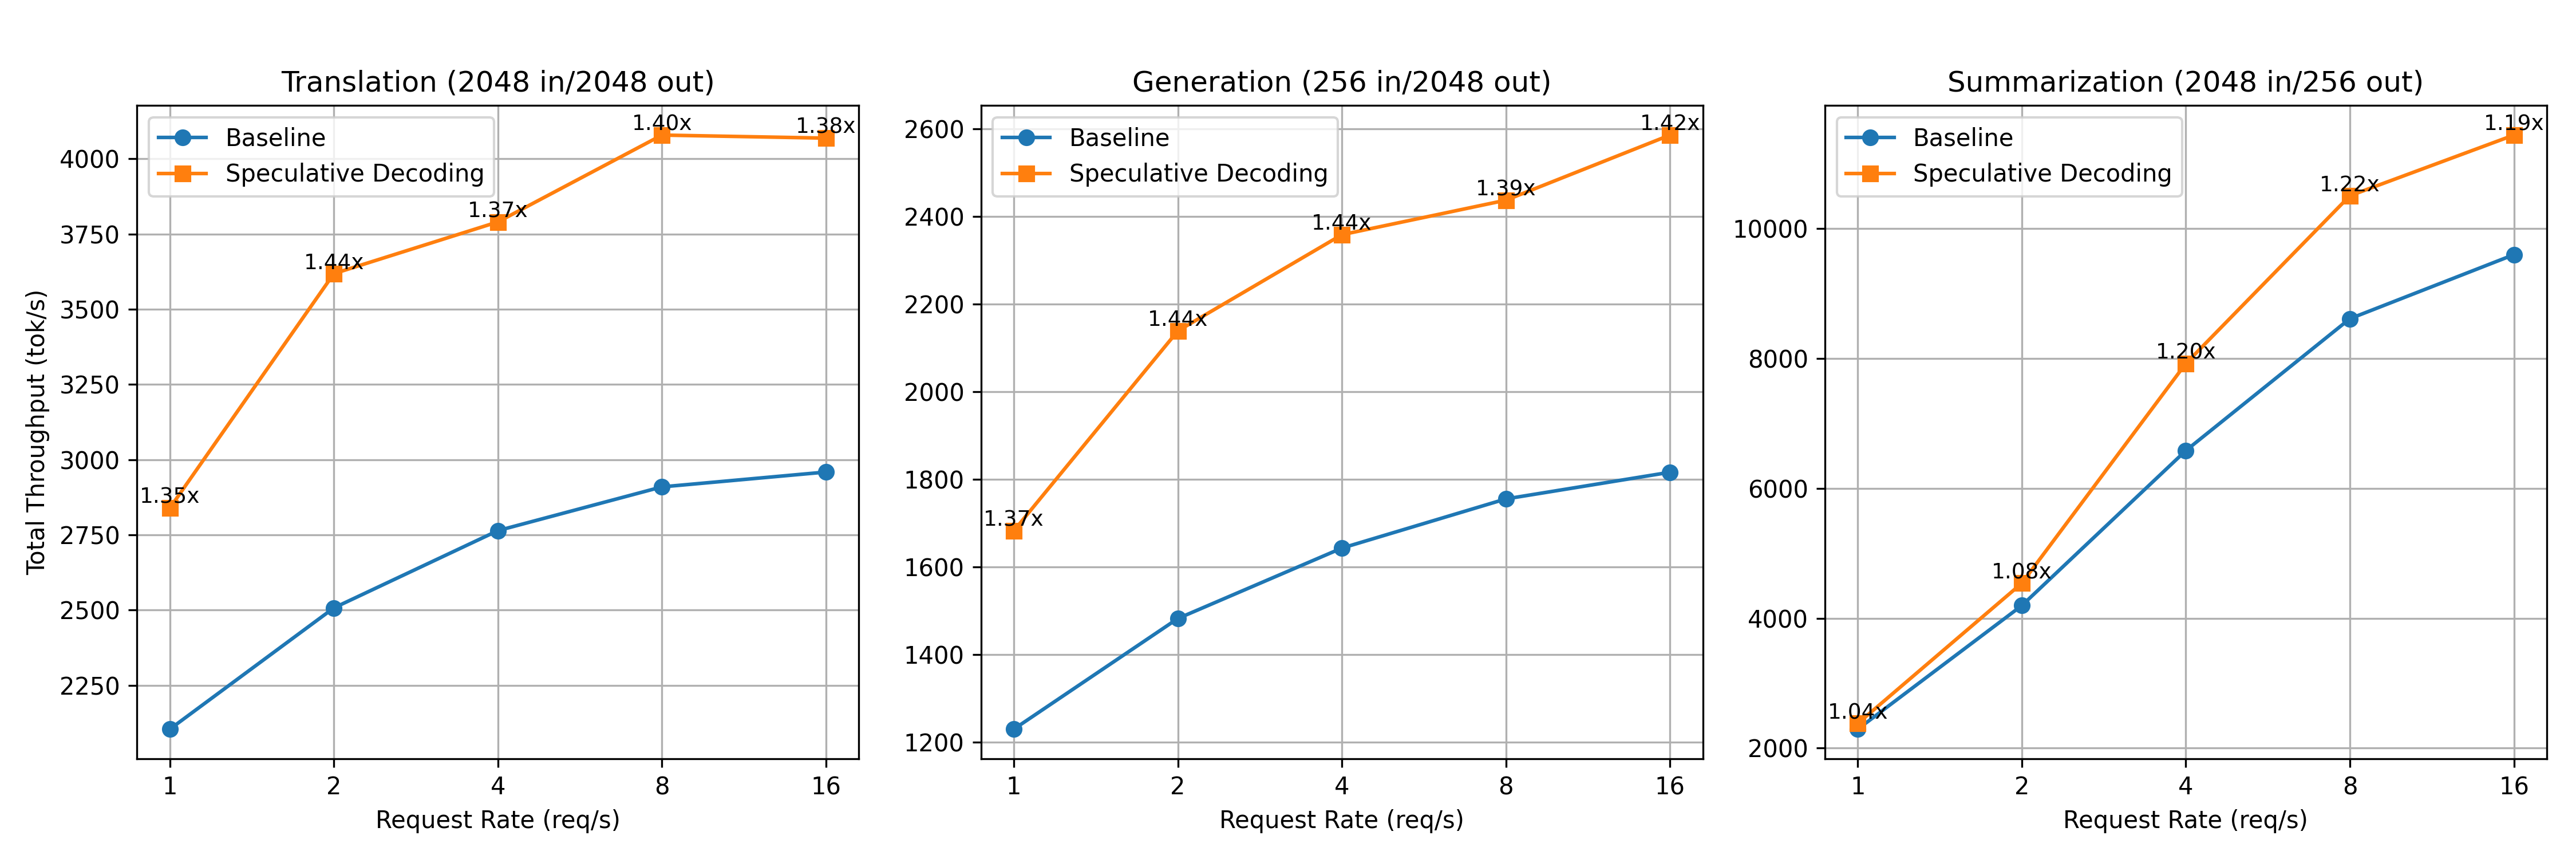
SGLang Speculative Decoding Tutorial: How to Deploy DeepSeek Models and ...
Gemma 4: Split Mode Tensor + Speculative Decoding · ggml-org llama.cpp ...
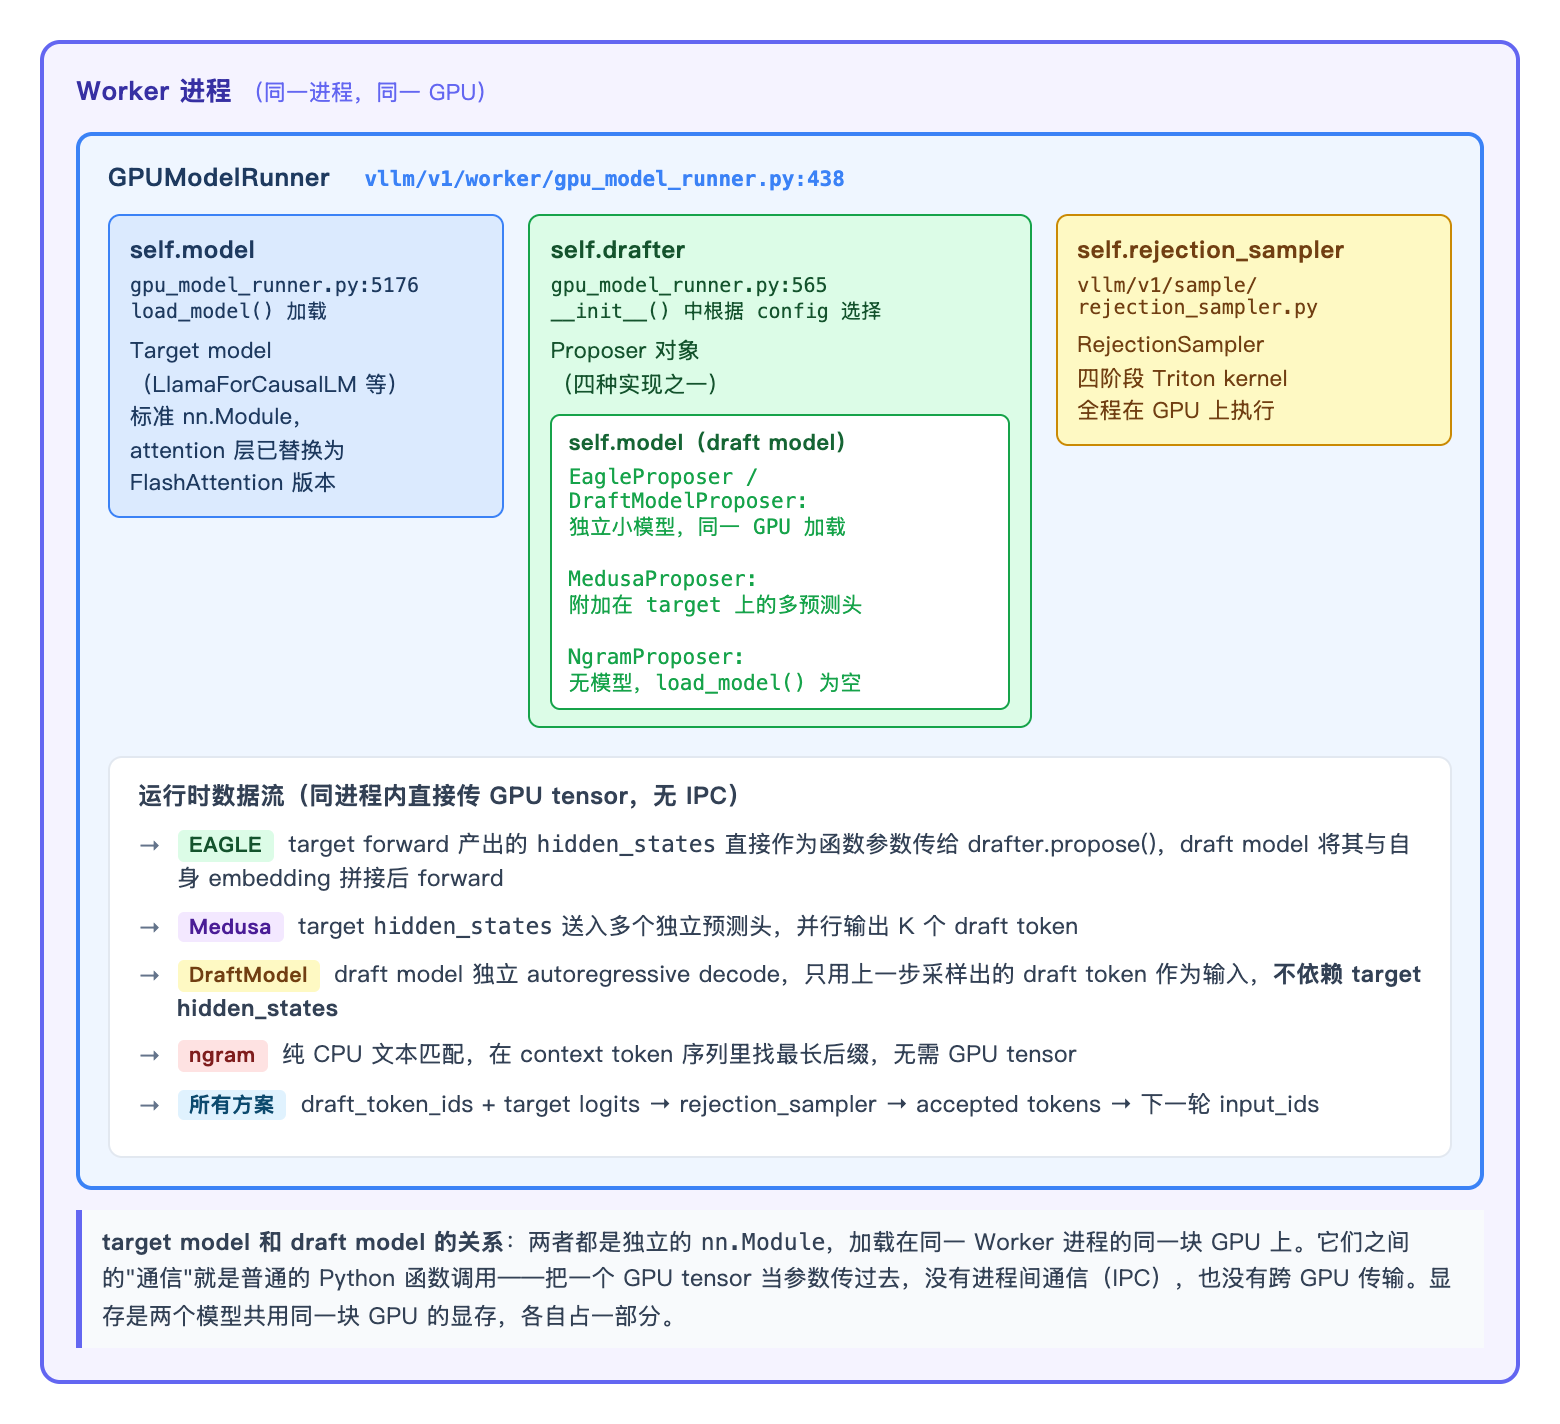
vllm v1 源码精读(五):从 generate() 到 Speculative Decoding 的完整计算流 | HE Xin
[Usage]: Acceptance rate for Speculative Decoding · Issue #7301 · vllm ...
Advertisement Space (336x280)
[Feature]: Per-sequence speculative decoding · Issue #17984 · vllm ...
Speculative Decoding 2026: vLLM ve TensorRT-LLM Hızlandırma Rehberi
How to Speed Up Local LLMs with DFlash Speculative Decoding | DataCamp
How to Speed Up Local LLMs with DFlash Speculative Decoding | DataCamp
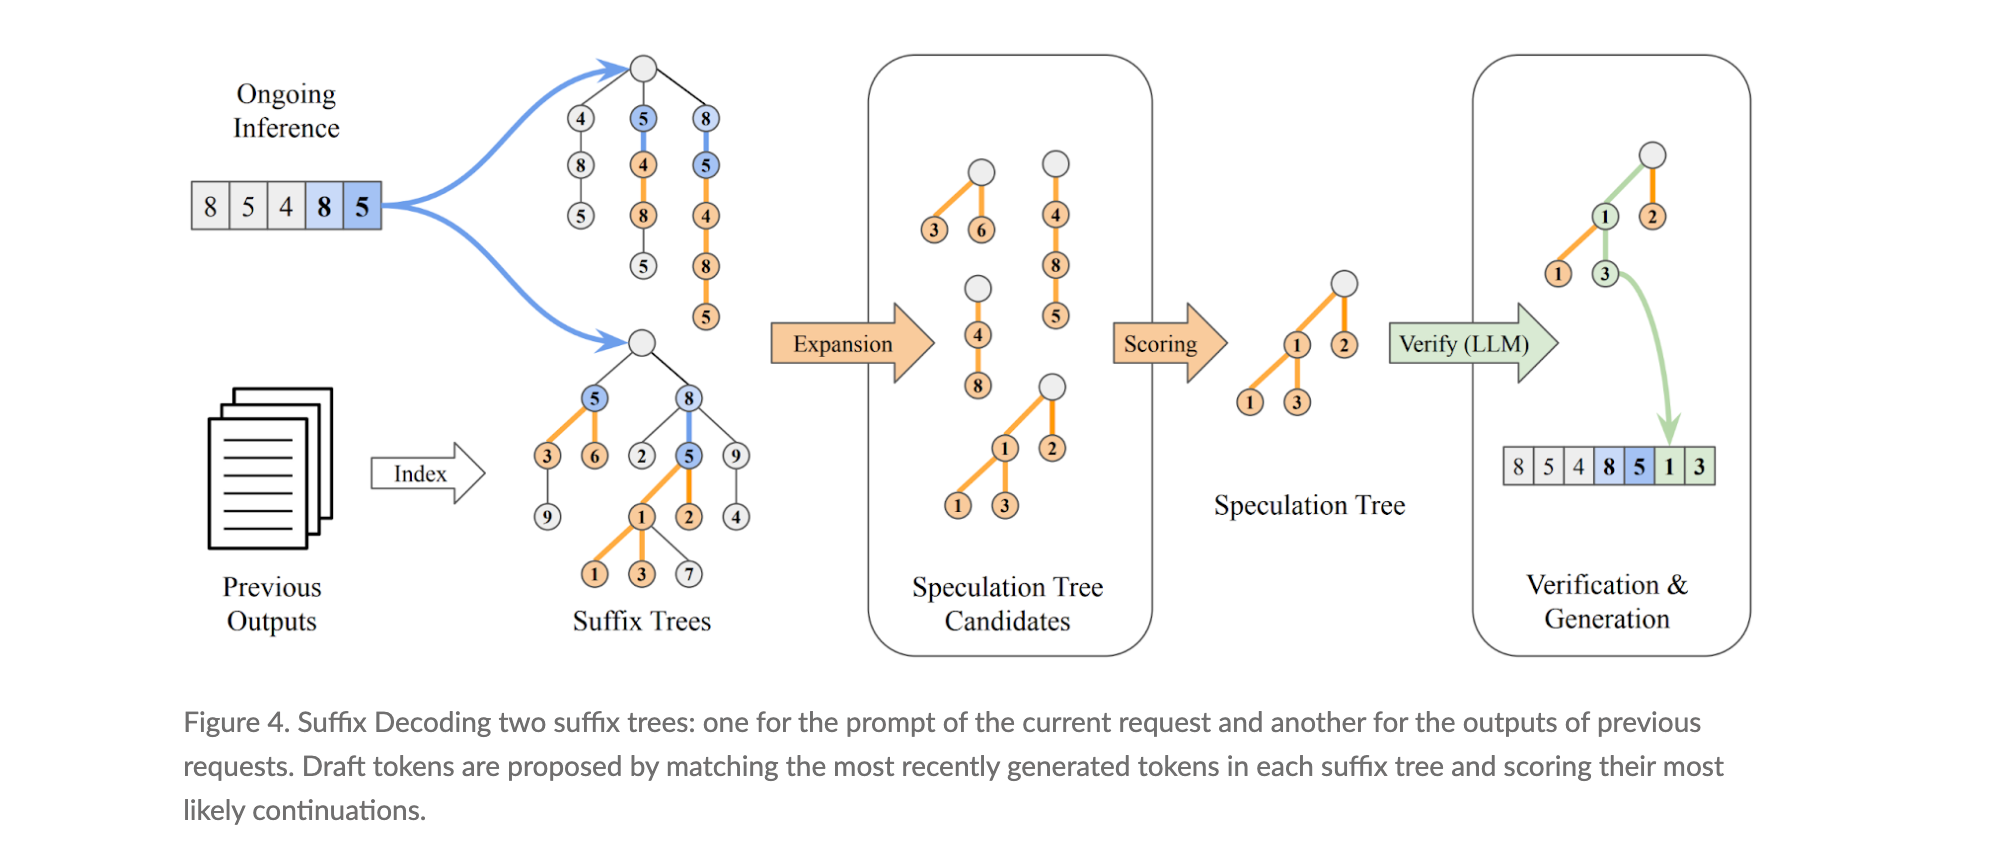
大模型推理加速——Fastest Speculative Decoding in vLLM with Arctic Inference and ...
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...