
Deploy Glm 51 On Gpu Cloud Self Host The 754b Moe Model 2026 Guide
Deploy GLM-5.1 on GPU Cloud: Self-Host the 754B MoE Model (2026 Guide ...
How to Deploy the Massive 754B GLM 5.1 Model for Enterprise Tasks - YouTube
Self-Hosting GLM-5.1 in 2026: True GPU Cost of the 754B MoE That Beat ...

How to Deploy GLM 5.2 with vLLM on Yotta GPU Pods | Yotta Labs

GLM 5.1 just dropped — 754B open-weight MoE model under MIT license ...

How to Deploy GLM 5.2 with SGLang on Yotta GPU Pods | Yotta Labs
Deploy OpenHands on GPU Cloud: Self-Host the Open-Source AI Software ...
Deploy IBM Granite 4.1 on GPU Cloud: Self-Host the Enterprise Hybrid ...
Deploy Ideogram 4 on GPU Cloud: Self-Host the Open-Weight Diffusion ...
Deploy Devstral on GPU Cloud: Self-Host Mistral's Coding Model with ...
Advertisement Space (300x250)
Deploy Microsoft Phi-5 on GPU Cloud: Self-Host the Small-Model Champion ...
Deploy Qwen3-Coder-Next on GPU Cloud: Self-Host Alibaba's 80B MoE ...
Deploy Qwen 3.6 Plus on GPU Cloud: Hybrid MoE with 1M Context (2026 ...
Deploy GLM-OCR on GPU Cloud: High-Accuracy OCR with Novita AI - Novita
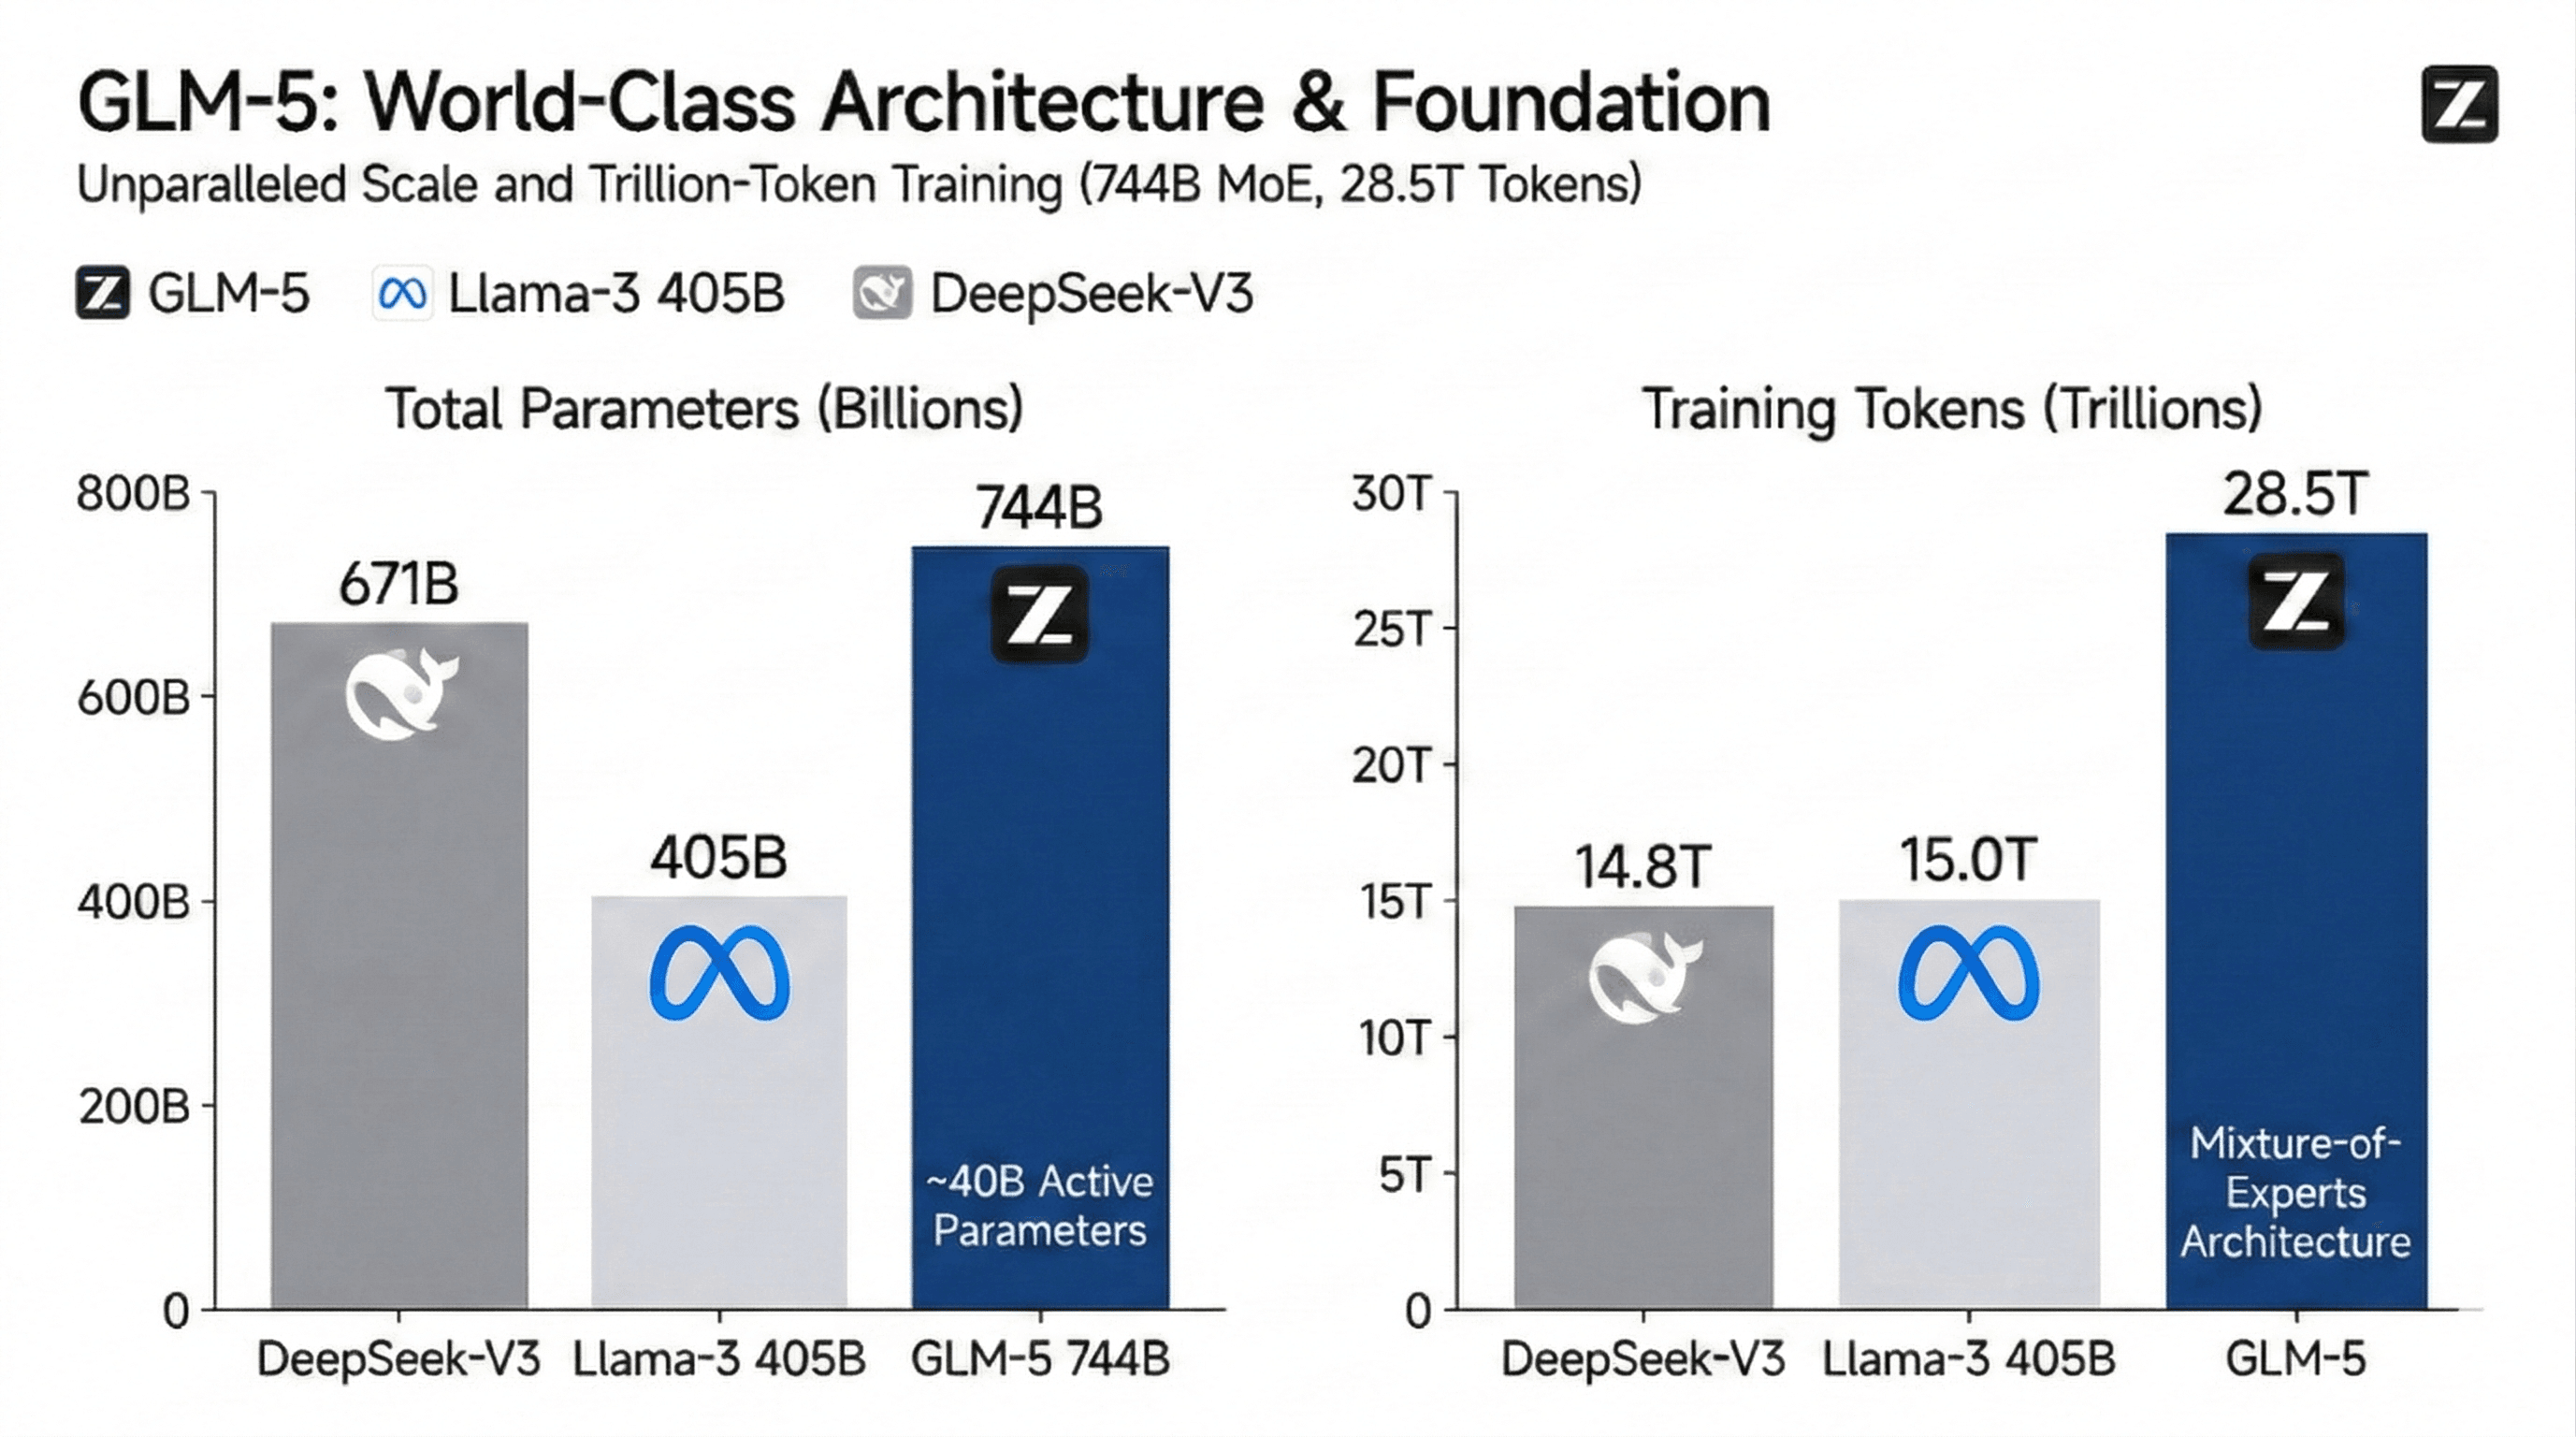
GLM-5 Lands on Atlas Cloud: Access Z.AI’s 744B MoE Model for Coding ...
Deploy DiffusionGemma on GPU Cloud: Self-Host Google's 26B Text ...
Self-Host AI Code Review on GPU Cloud: Deploy Open-Source PR Review ...
Self-Host Perplexity-Style AI Search on GPU Cloud: Deploy Perplexica ...
Deploy SmolAgents on GPU Cloud: Self-Host Hugging Face's Code-Execution ...
Deploy Nemotron Ultra 253B on GPU Cloud: Self-Host NVIDIA's Best Open ...
Advertisement Space (336x280)
Deploy A2A (Agent2Agent) Multi-Agent Systems on GPU Cloud: Cross ...
Self-Host Embeddings and Rerankers: TEI on GPU Cloud (2026) | Spheron Blog
LLM Observability on GPU Cloud: Deploy Langfuse, Arize Phoenix, and ...
How MoE Models Deploy Differently: A Self-Hosting Guide | Prositronic
Deploy LocalAI on Kubernetes — Self-Hosted LLM API Without GPU (2026 ...
Deploy Qwen3.5-Omni on GPU Cloud: Self-Host Real-Time Multimodal AI ...

Deploy MAX on GPU with self-hosted endpoints | Modular
GLM-5 Lands on Atlas Cloud: Access Z.AI’s 744B MoE Model for Coding ...
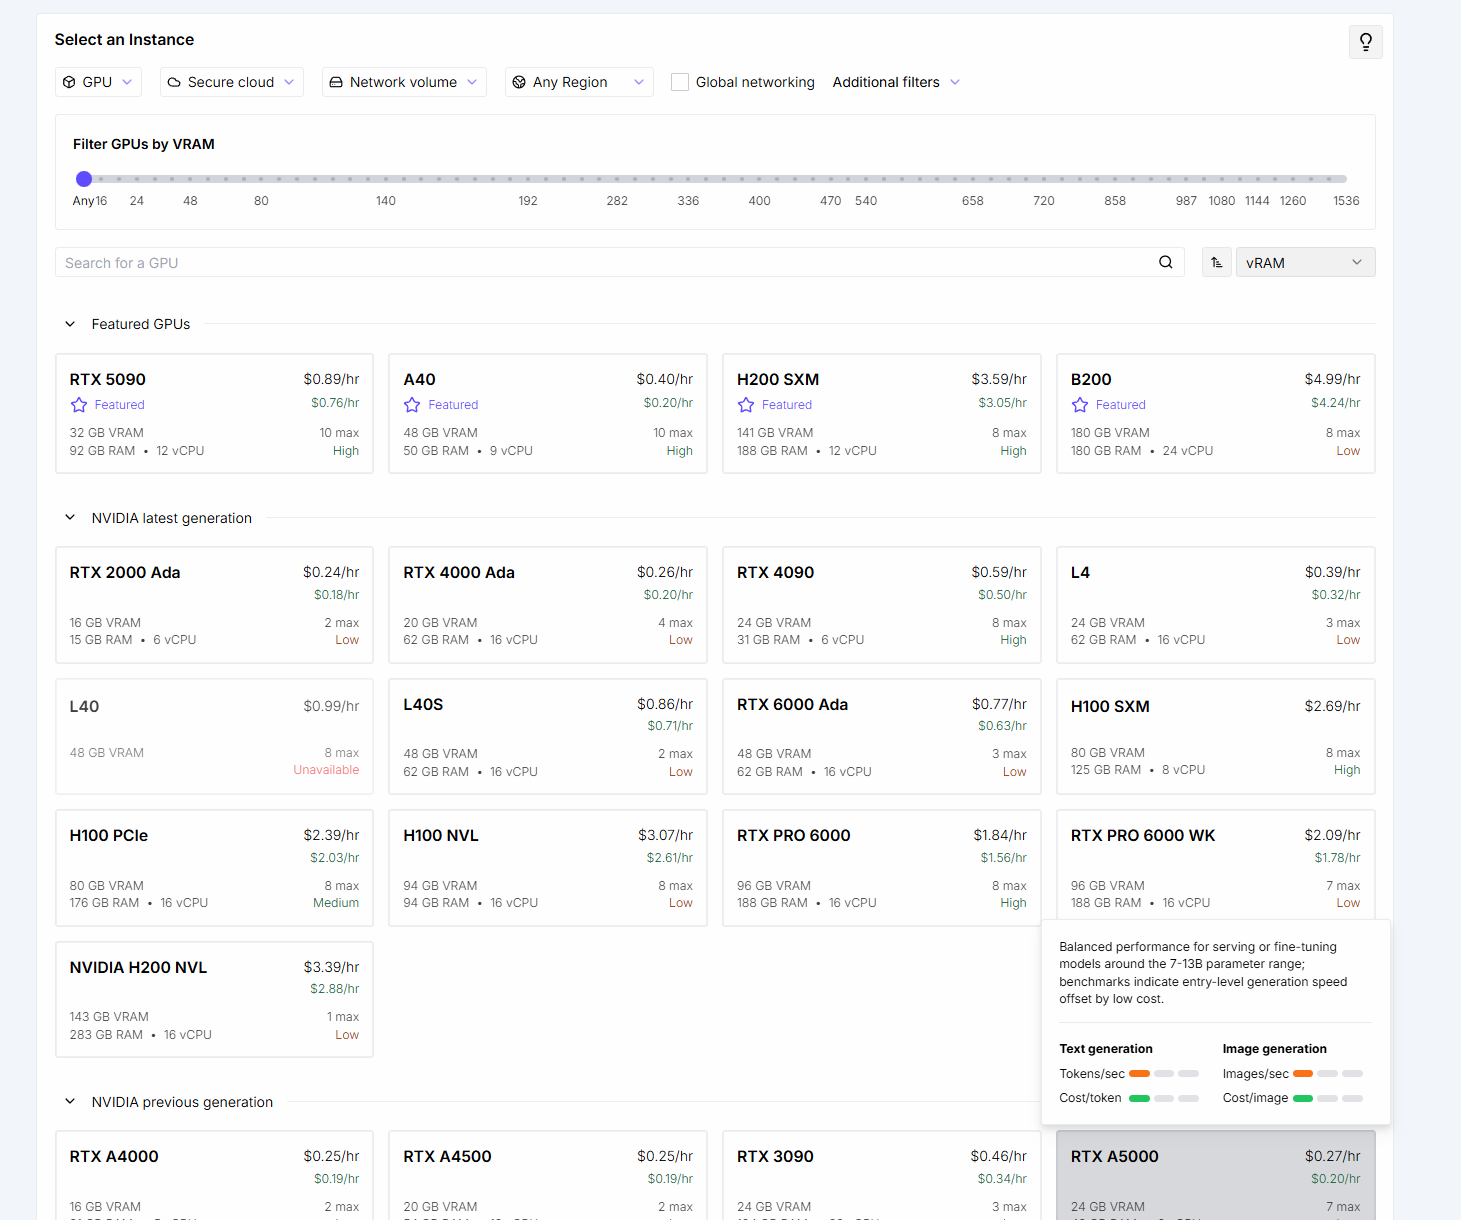
How to Deploy Your LLM in the Cloud - by Benjamin Marie
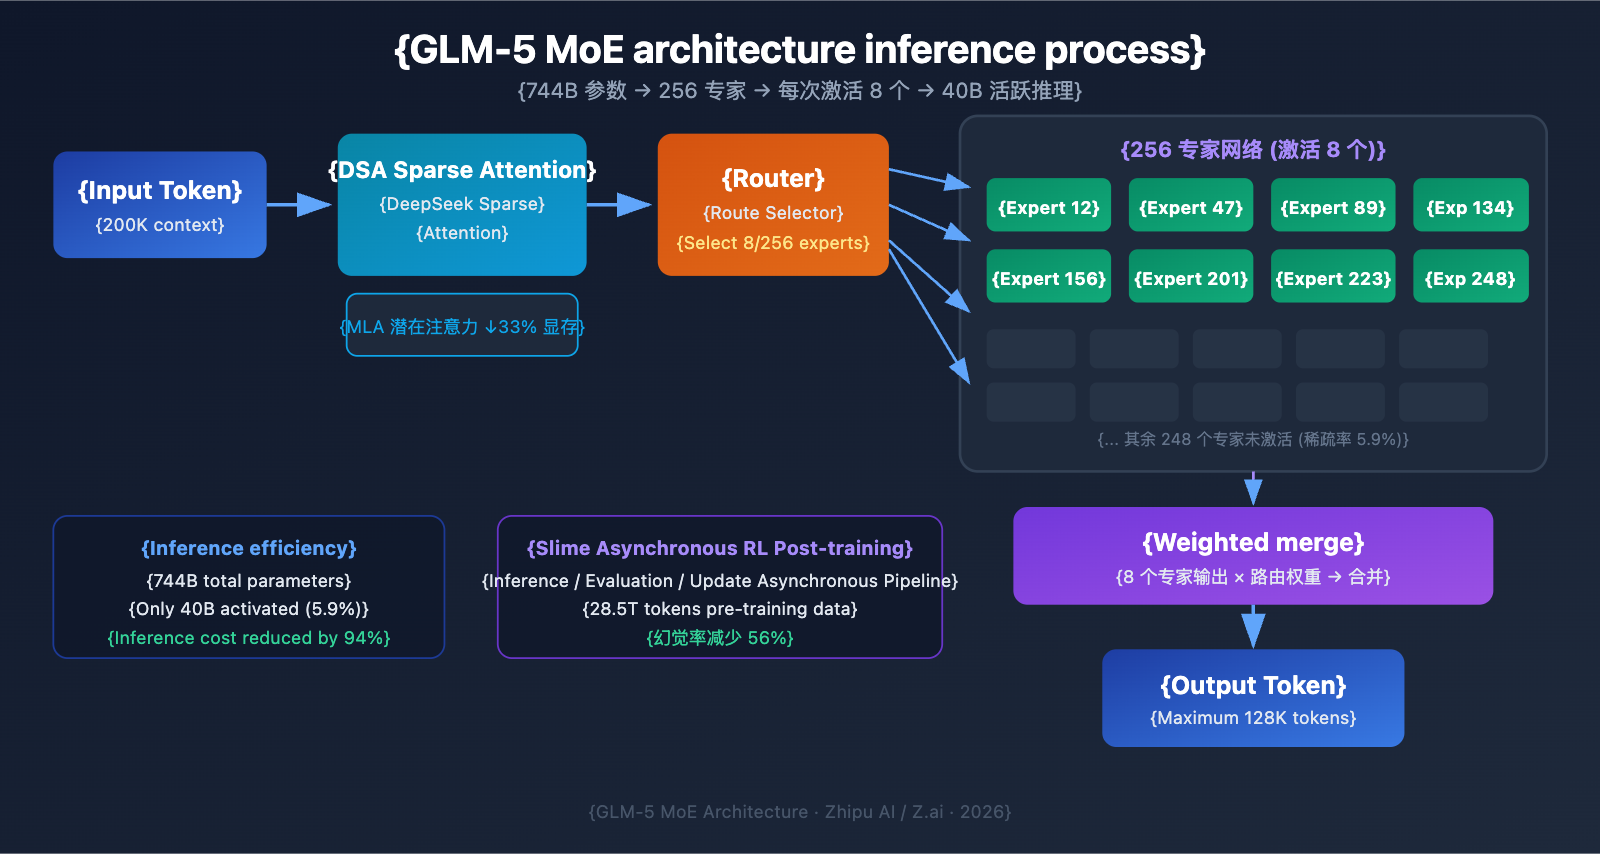
Mastering GLM-5 API Calls: 5-Minute Getting Started Guide for the 744B ...
Advertisement Space (336x280)

Z.ai's GLM-5.1: The 754B Open-Source AI Agent That Works for 8 Hours ...
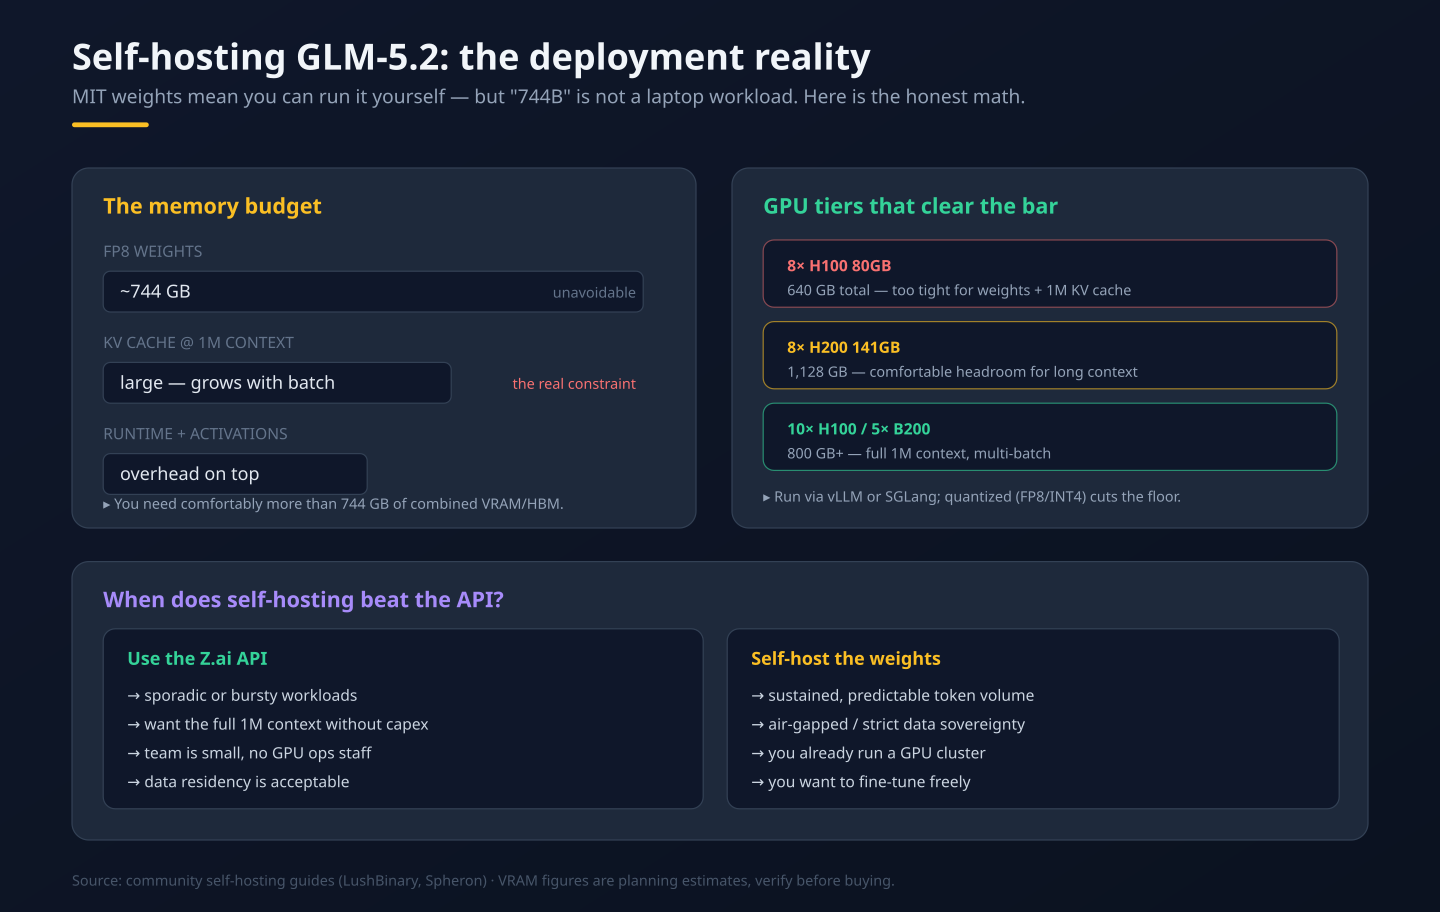
GLM-5.2: The 744B Open-Weight Model With a 1M Context — and Why It ...

Run GLM-5.1 Locally: CPU & GPU Setup Guide
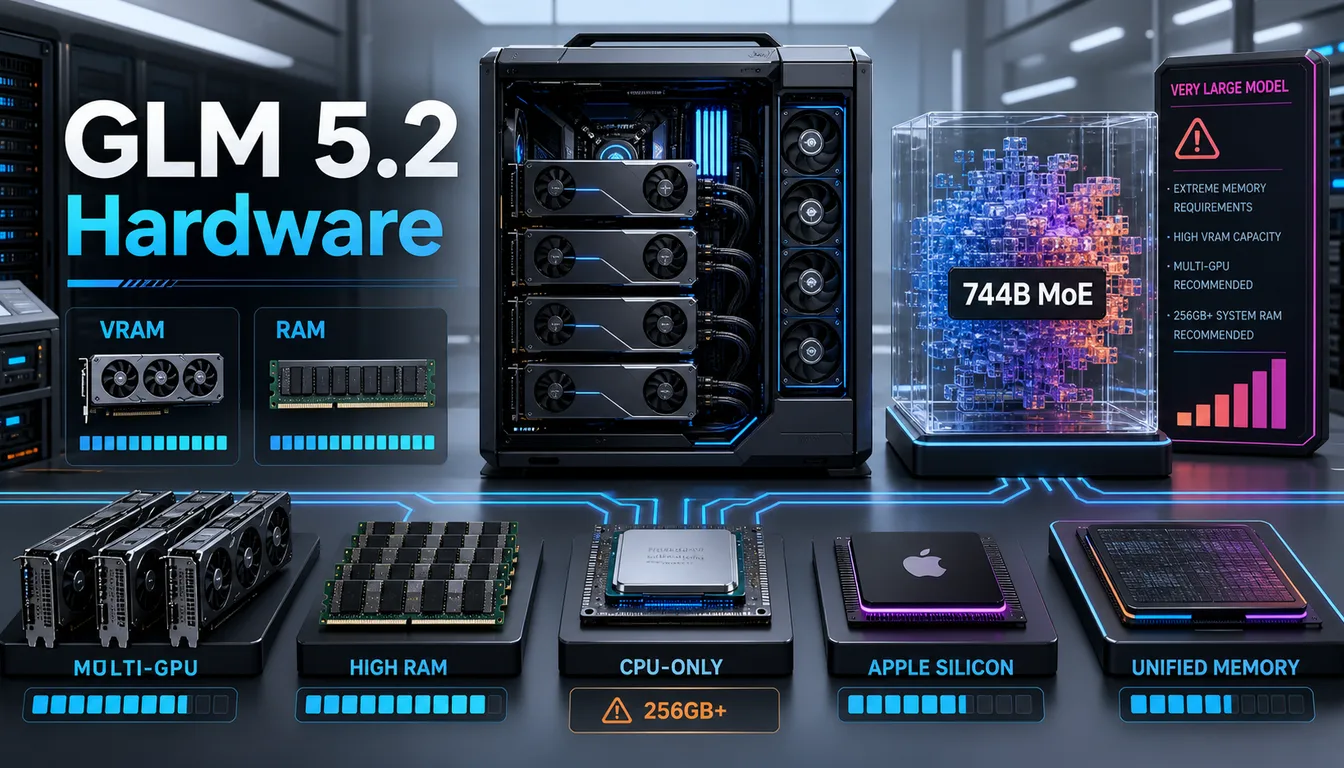
How to Run GLM-5.2 in Ollama: Cloud Tag, Local Setup & API Guide
GLM-5 Released: 744B MoE Model vs GPT-5.2 & Claude 4.5

How to Run 754B Models on a Home PC (GLM-5.1 Quantization Guide) - YouTube