
Deploying Disaggregated Llm Inference Workloads On Kubernetes Nvidia

Deploying Disaggregated LLM Inference Workloads on Kubernetes | NVIDIA ...

Deploying Disaggregated LLM Inference Workloads on Kubernetes | NVIDIA ...

Deploying Disaggregated LLM Inference Workloads on Kubernetes | NVIDIA ...

Deploying Disaggregated LLM Inference Workloads on Kubernetes | NVIDIA ...

Deploying Disaggregated LLM Inference Workloads on Kubernetes | NVIDIA ...

Deploying Disaggregated LLM Inference Workloads on Kubernetes | NVIDIA ...

Deploying Disaggregated LLM Inference Workloads on Kubernetes | NVIDIA ...
Deploying Disaggregated LLM Inference Workloads on Kubernetes | NVIDIA ...

Deploying LLM Inference on Kubernetes with the NVIDIA GPU Operator: A ...
How to Deploy NVIDIA NIM on Kubernetes for Fast LLM Inference | DevOpsBoys
Advertisement Space (300x250)

NVIDIA Advances AI Infrastructure With Disaggregated LLM Inference on ...
Free Video: Scalable LLM Inference on Kubernetes With NVIDIA NIMS ...
Disaggregated LLM Inference on Kubernetes | 2024 Guide | AI News

Free Video: Deploying LLM Workloads on Kubernetes with WasmEdge and ...

Deploying Scalable Serverless LLM Workloads on Kubernetes + Knative ...

Disaggregated Inference on Kubernetes | Prefill Decode
llm-d on Kubernetes: Disaggregated LLM Inference Deployment Guide (2026 ...

Scaling multi-node LLM inference with NVIDIA Dynamo and NVIDIA GPUs on ...

Stop Running LLM Workloads on Vanilla Kubernetes | by Mateen Anjum ...

Deploy llm-d for Distributed LLM Inference on DigitalOcean Kubernetes ...
Advertisement Space (336x280)

Deploy llm-d for Distributed LLM Inference on DigitalOcean Kubernetes ...
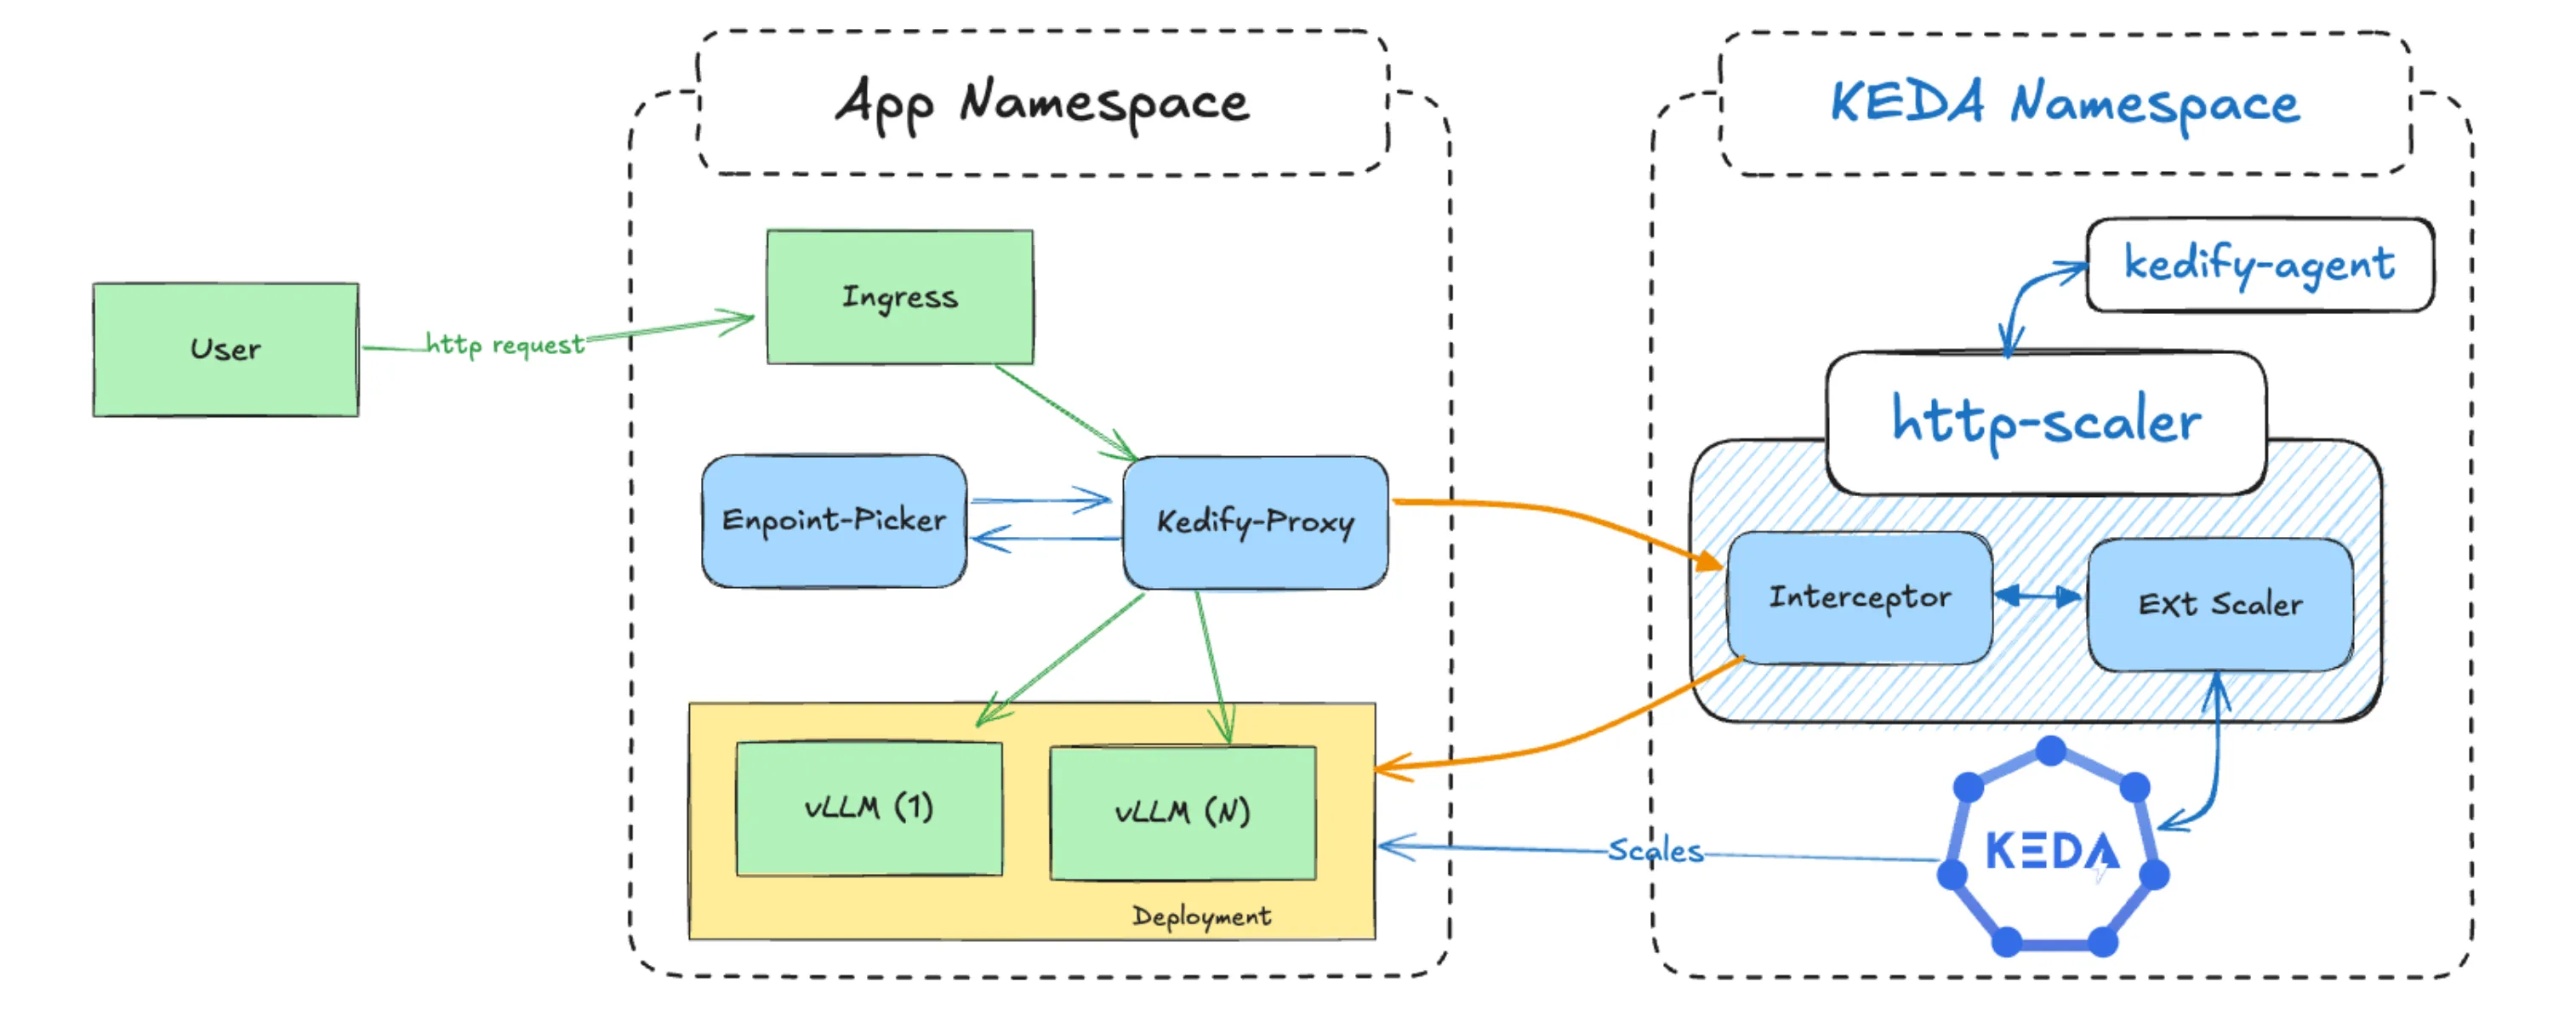
How to Autoscale GPU and LLM Workloads on Kubernetes | Kedify
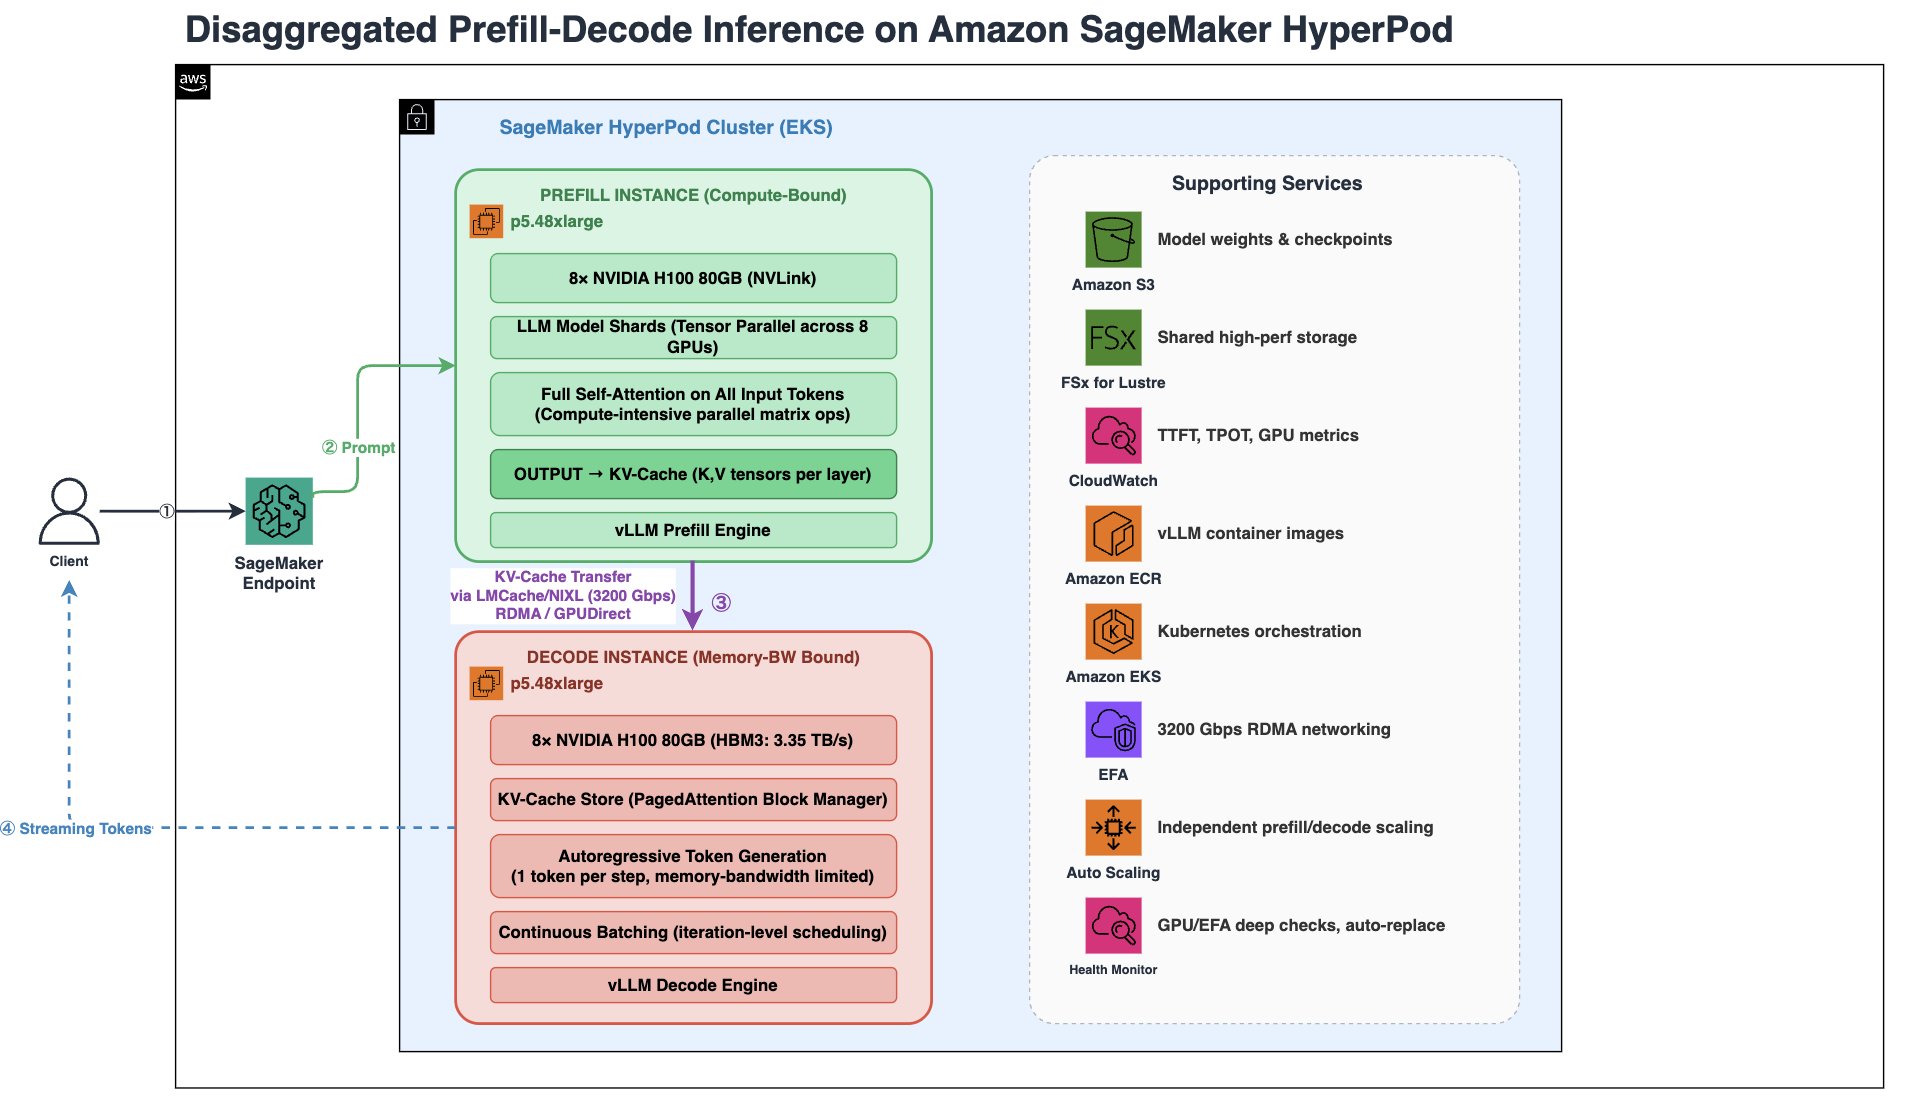
Disaggregated prefill and decode for LLM inference on SageMaker ...

Stop Running LLM Workloads on Vanilla Kubernetes - DEV Community

llm-d: Distributed LLM Inference on Kubernetes | dudarik.com
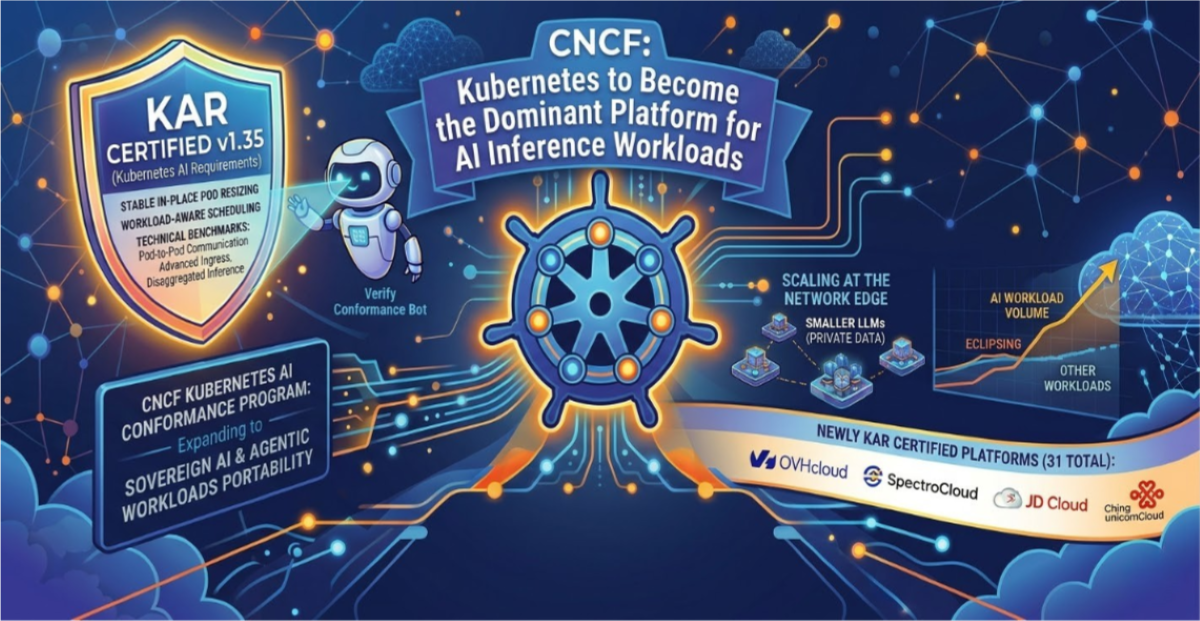
CNCF Expands Efforts to Run AI Inference Workloads on Kubernetes ...

Disaggregated Inference on Kubernetes | Prefill Decode

NVIDIA Dynamo Snapshot: Fast Startup for Inference Workloads on ...

NVIDIA Dynamo Snapshot: Fast Startup for Inference Workloads on ...

Deploying Scalable LLM Tools via Remote MCP on Kubernetes - DEV Community
Advertisement Space (336x280)
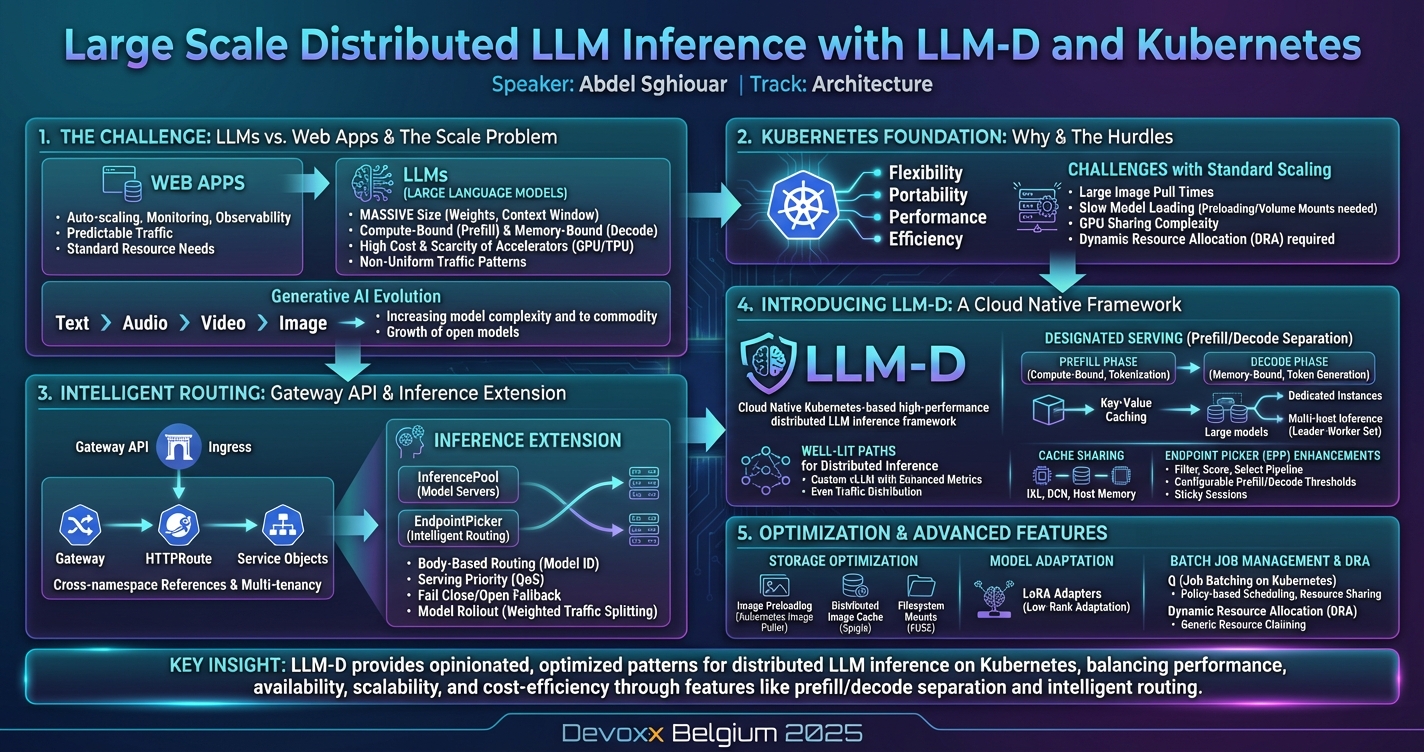
Large Scale Distributed LLM Inference with LLM-D and Kubernetes ...
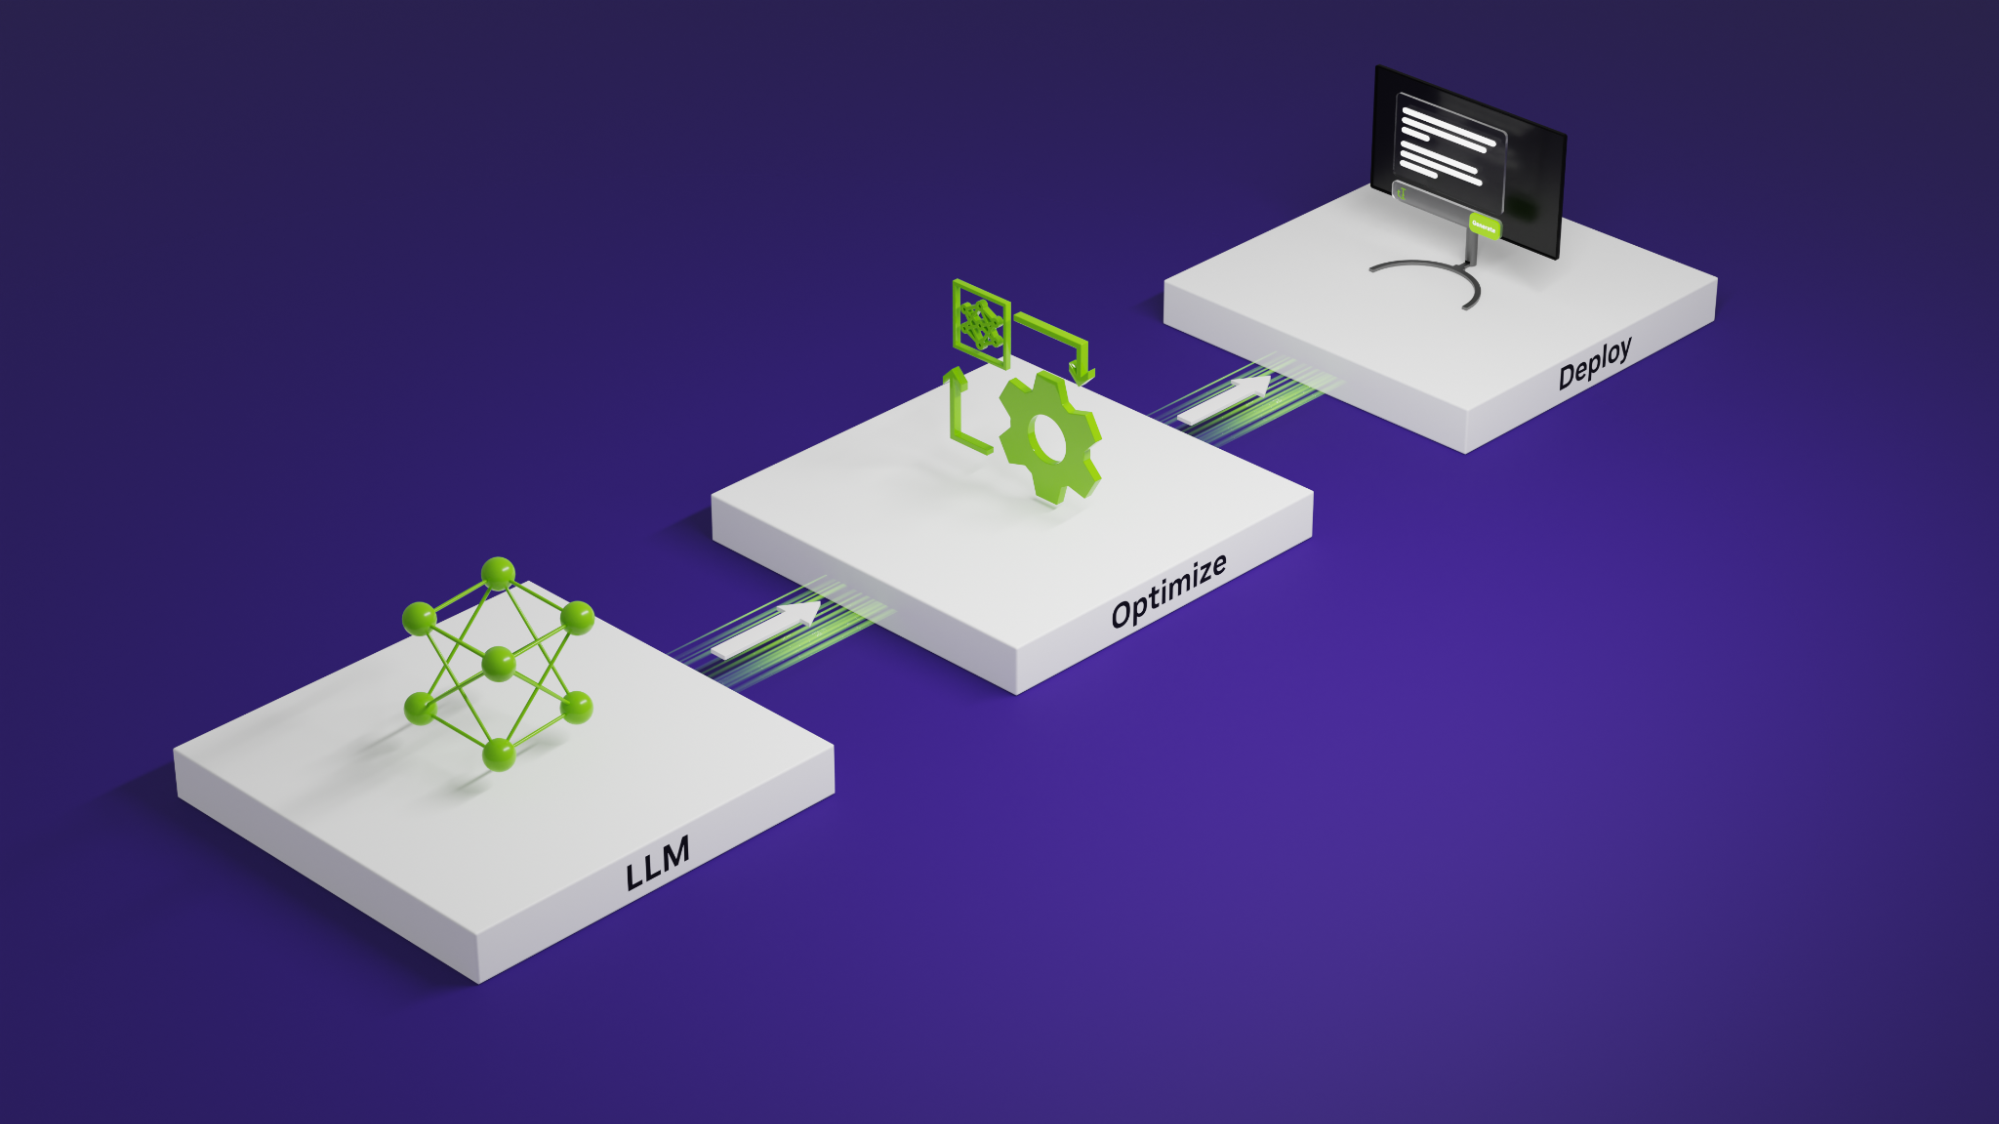
Mastering LLM Techniques: Inference Optimization | NVIDIA Technical Blog
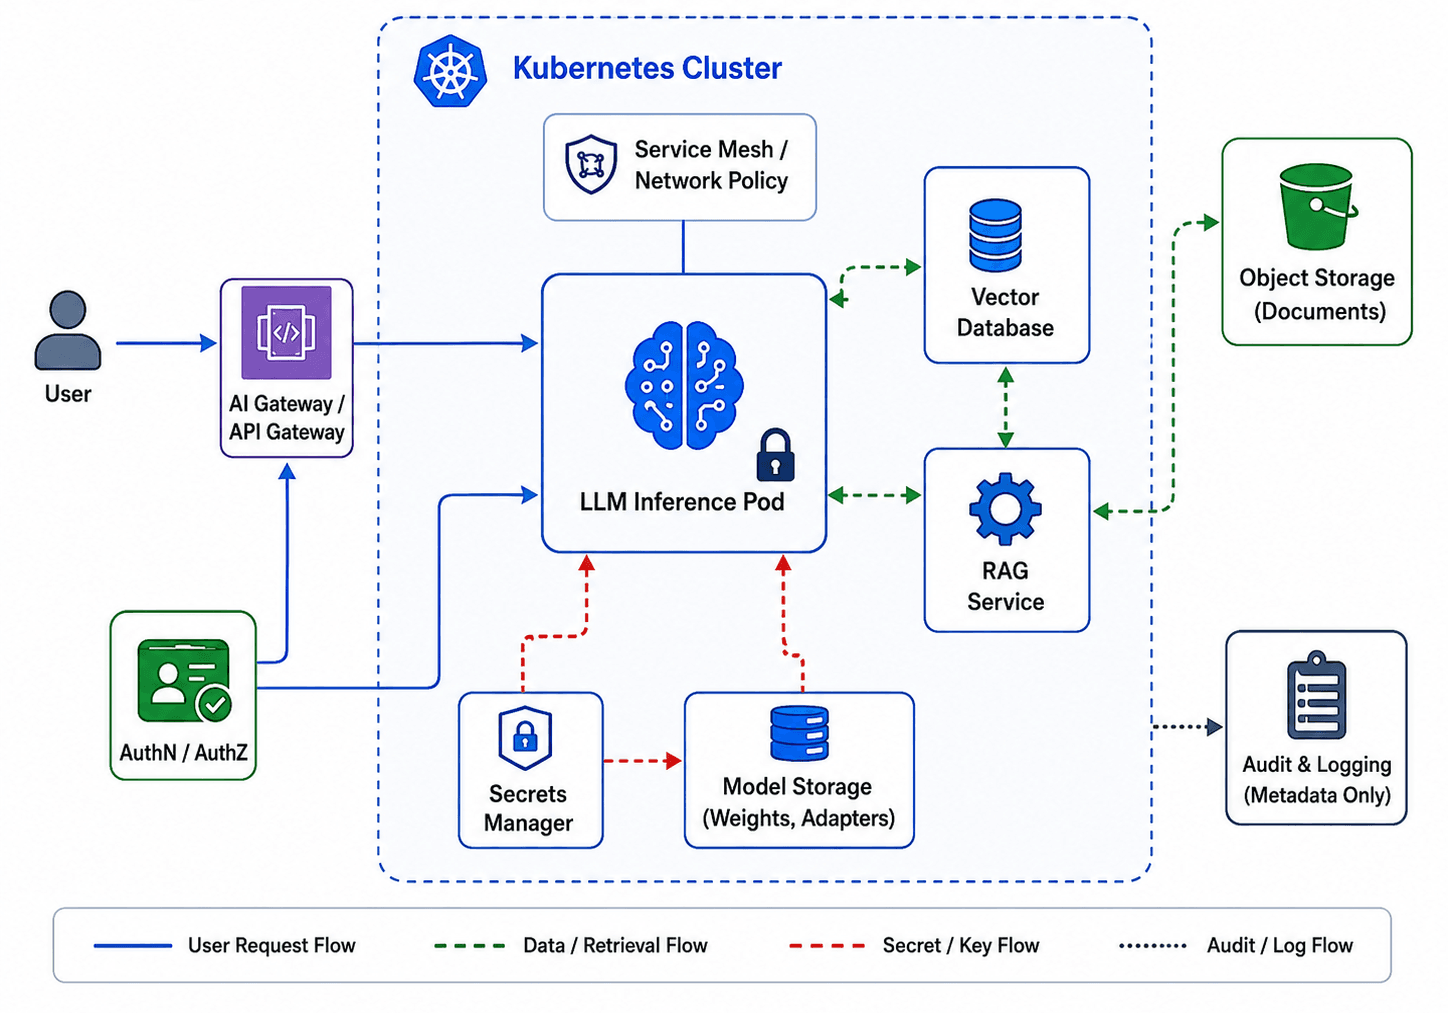
Confidential AI on Kubernetes: Secure LLM Inference

GitHub - sgl-project/rbg: A workload for deploying LLM inference ...

Simplify LLM Deployment and AI Inference with a Unified NVIDIA NIM ...

GitHub - sgl-project/rbg: A workload for deploying LLM inference ...