
Distributed Inference Serving Llms Across Multiple Gpus Tutorialq
Distributed Inference — Serving LLMs Across Multiple GPUs | tutorialQ

Fast Distributed Inference Serving for LLMs - YouTube

Run A Local LLM Across Multiple Computers! (vLLM Distributed Inference ...
Distributed Training of Large Language Models Across Multiple GPUs or ...
Distributed LLM Inference across multiple machines each with multiple ...
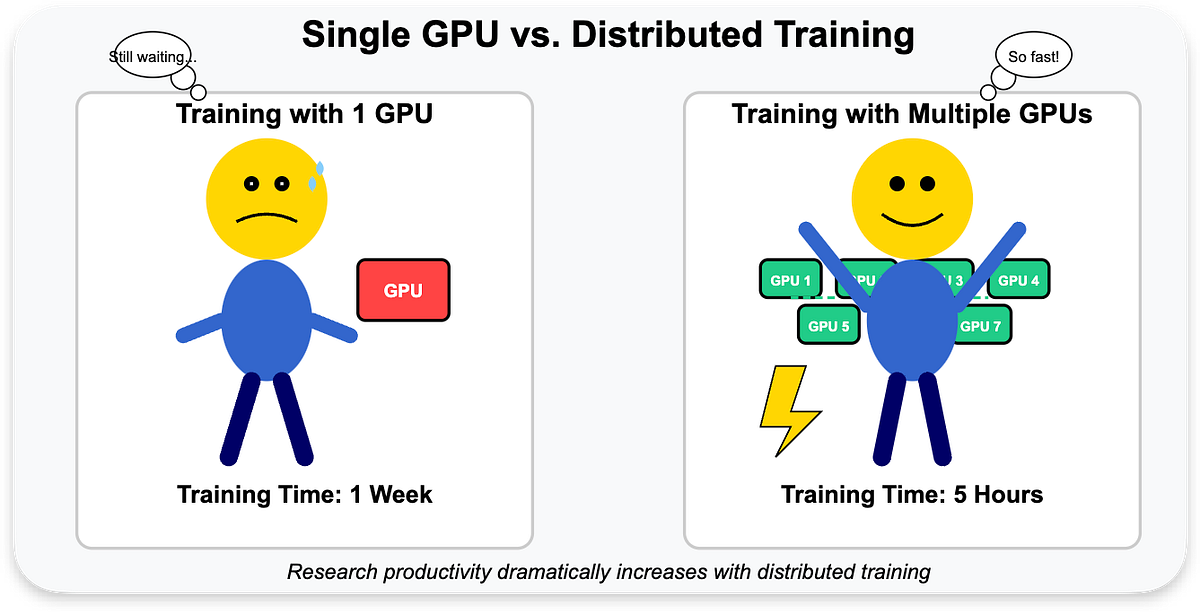
Distributed Training Overview: Scaling PyTorch Across Multiple GPUs ...
Sequence Parallelism — Distributing Long Sequences Across GPUs | tutorialQ
Pipeline Parallelism — Splitting Model Stages Across GPUs | tutorialQ

SLA-Aware Distributed LLM Inference Across Device-RAN-Cloud | AI ...
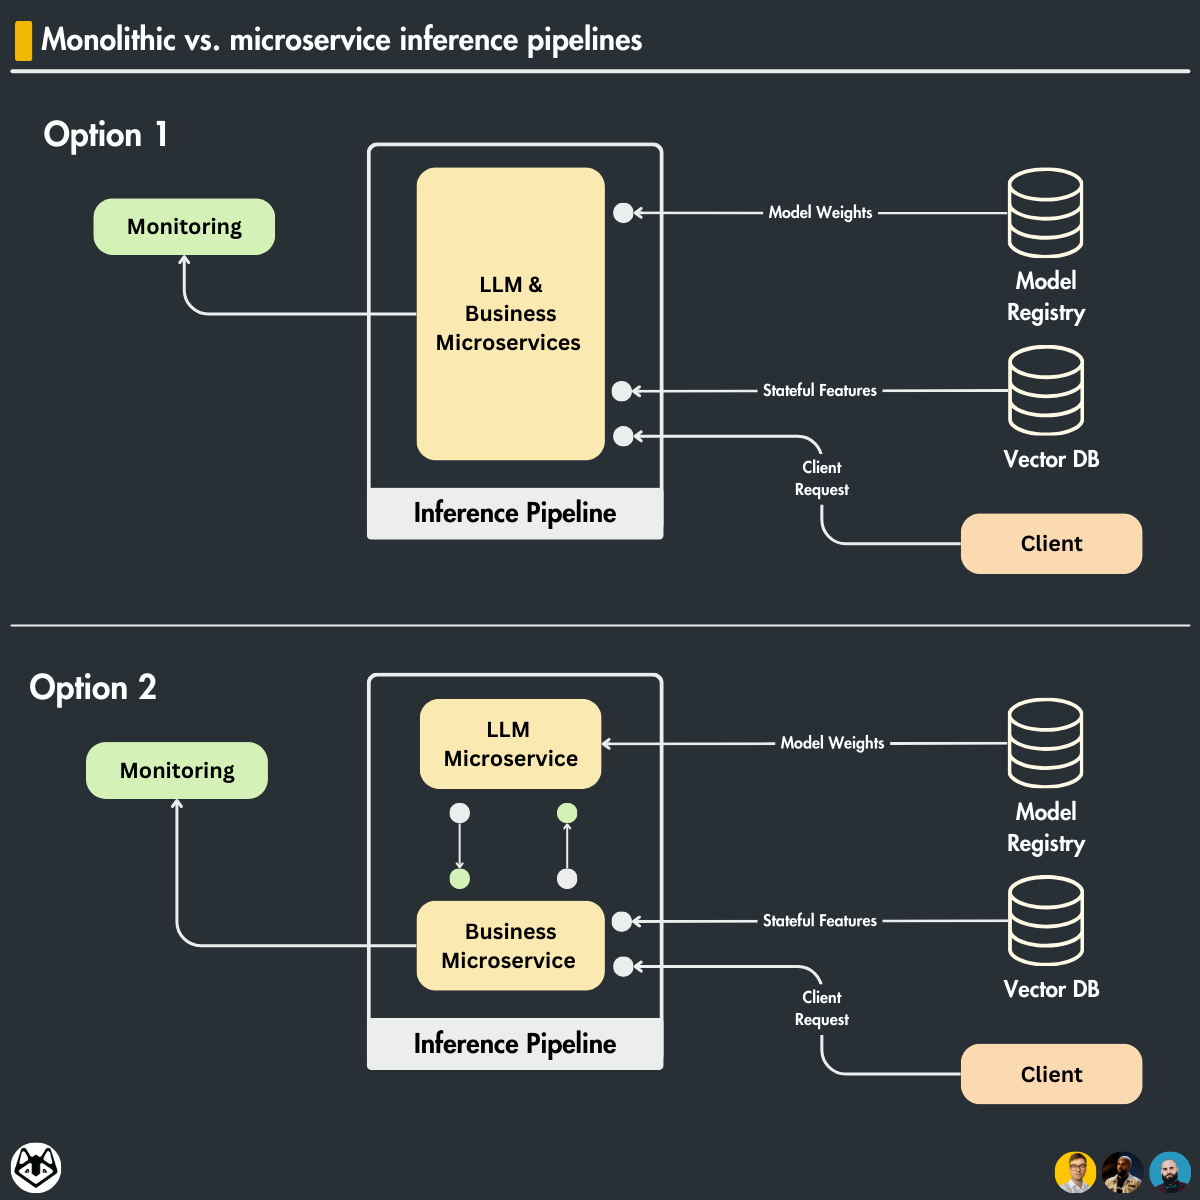
Build a Scalable Inference Pipeline for Serving LLMs and RAG Systems
Advertisement Space (300x250)
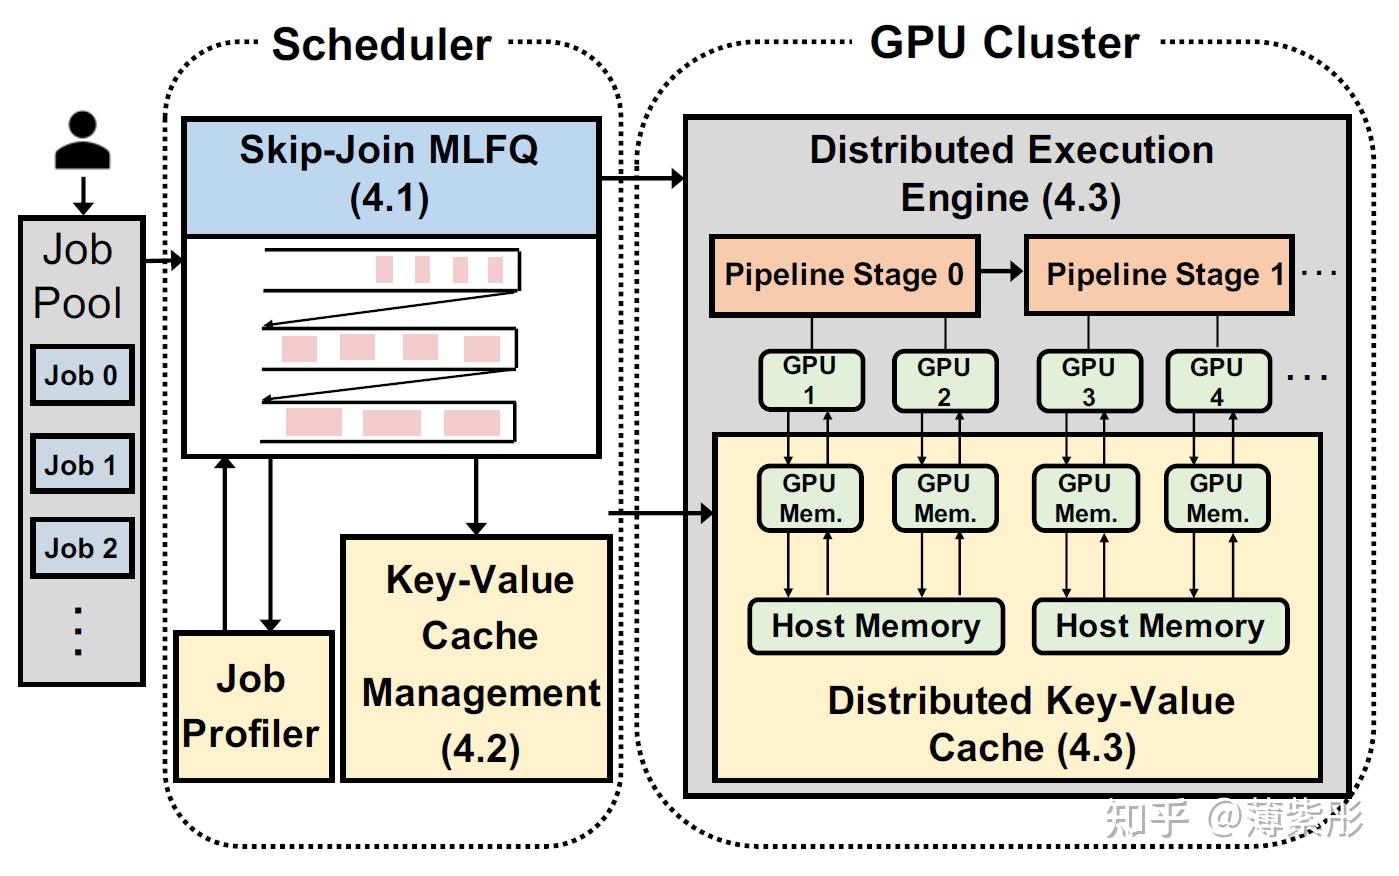
Fast Distributed Inference Serving for Large Language Models - 知乎

How to Scale LLM Inference Across GPUs | Yotta Labs

Distributed Inference Performance Optimization for LLMs on CPUs | AI ...

(PDF) Distributed Inference Performance Optimization for LLMs on CPUs
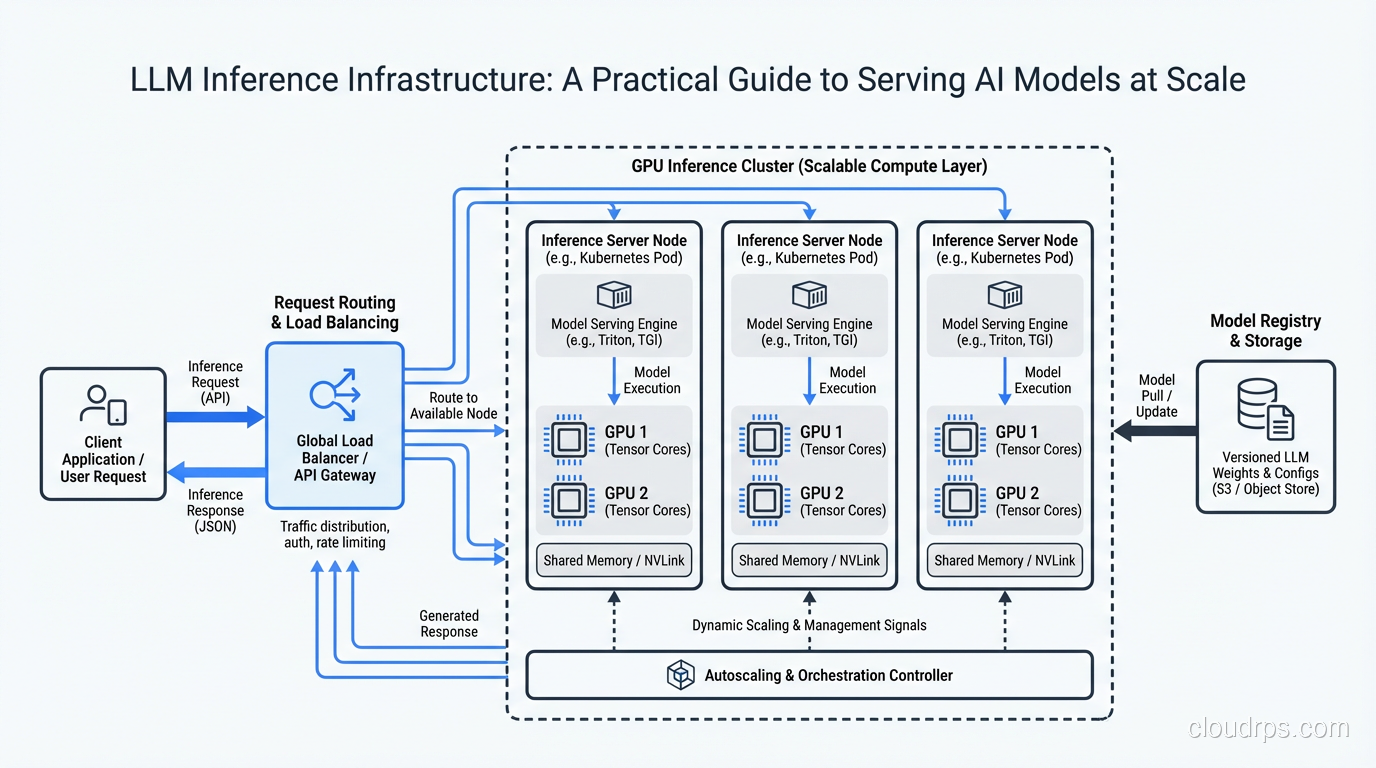
LLM Inference Infrastructure: Serving AI at Scale
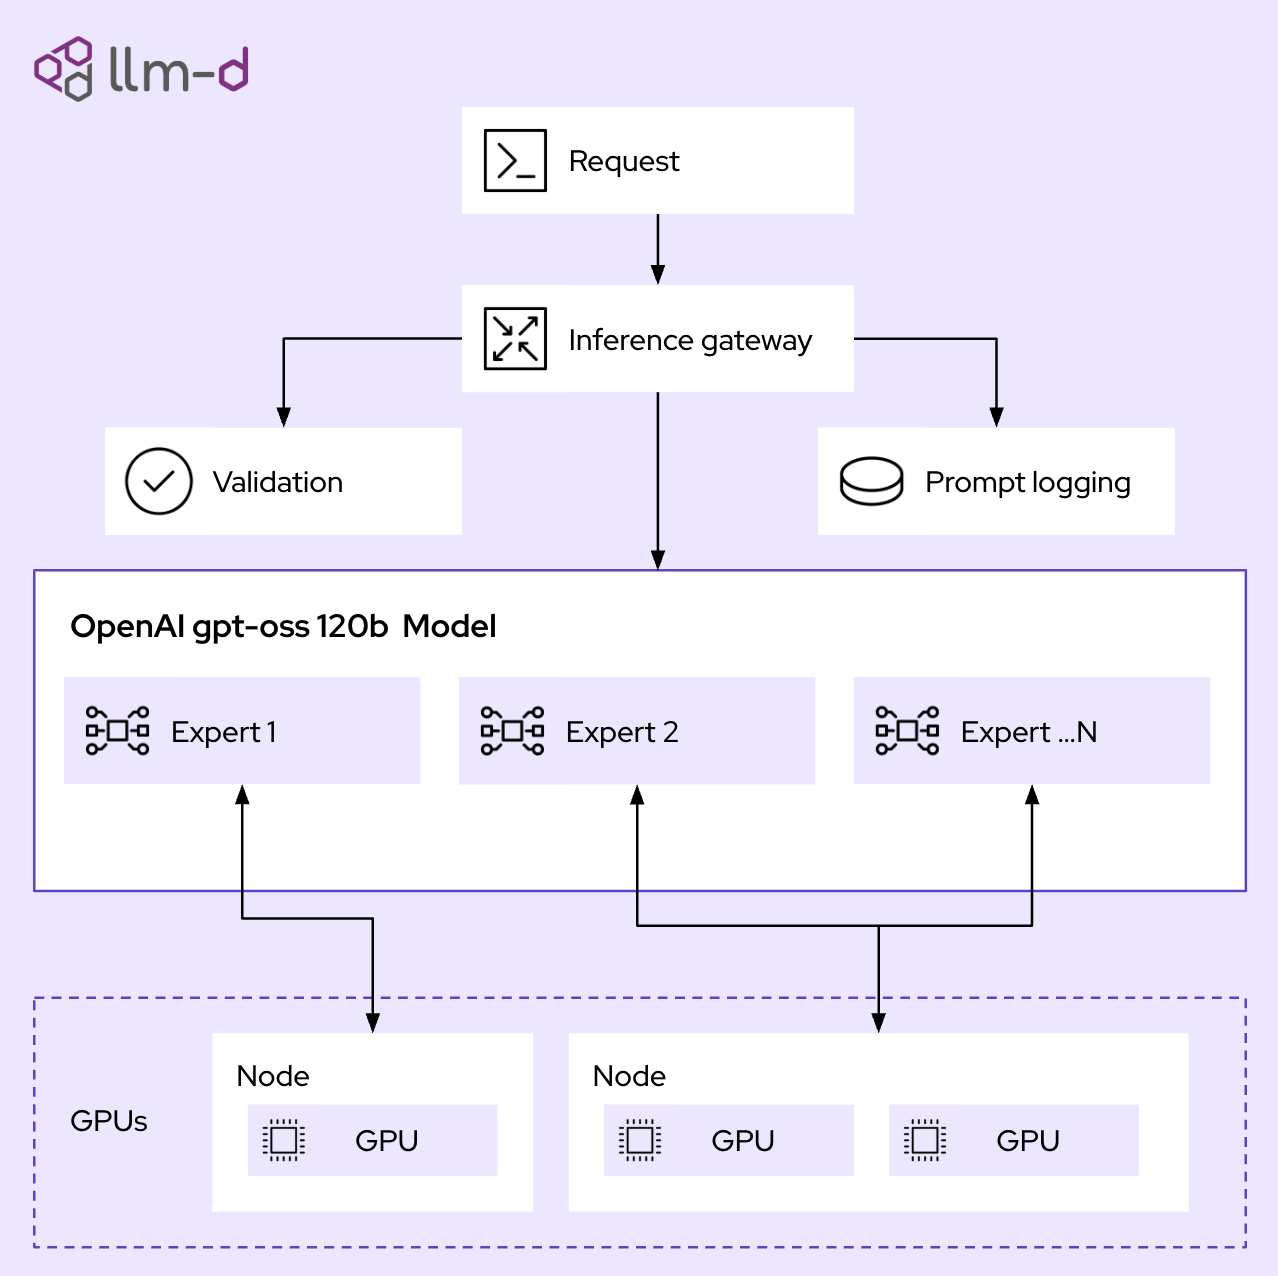
Introduction to distributed inference with llm-d | Red Hat Developer
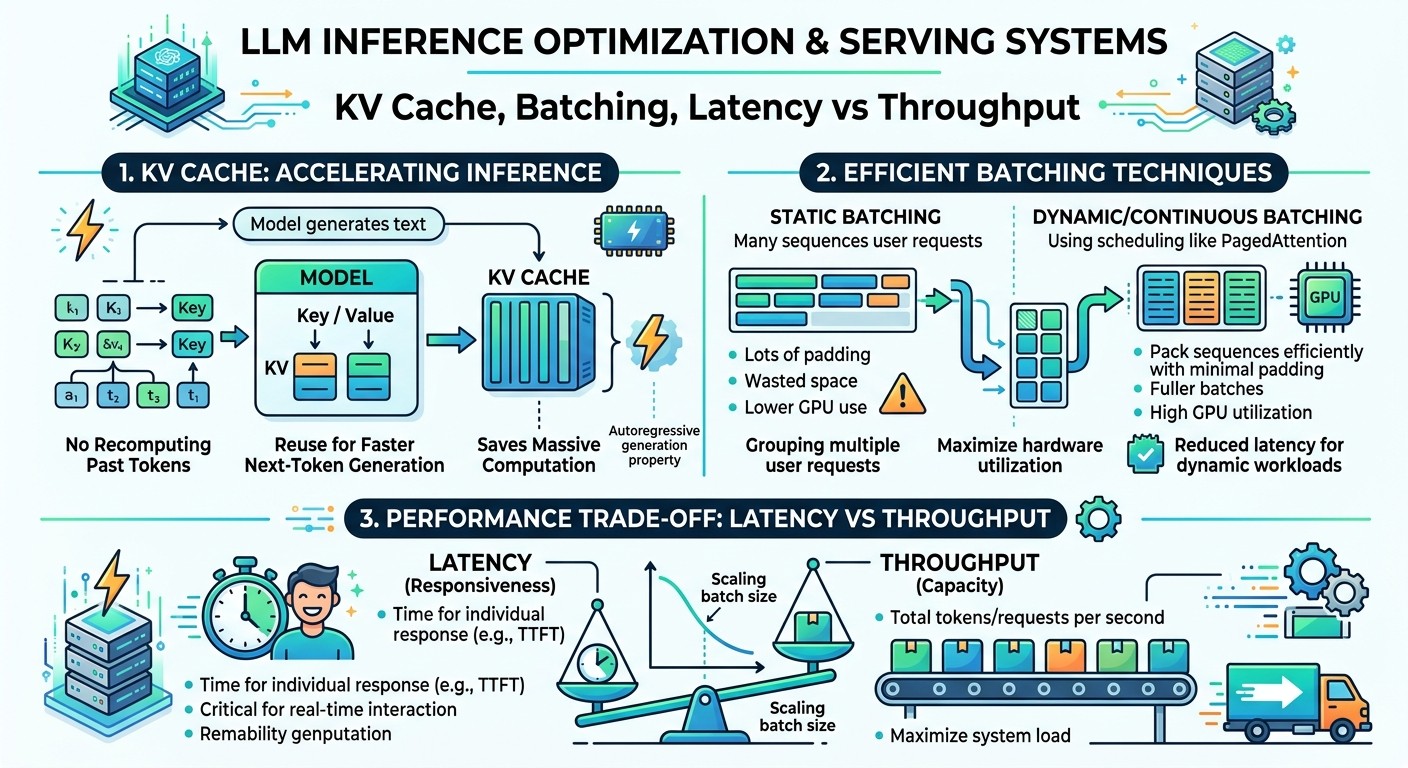
LLM Inference Optimization & Serving Systems – Billion Hopes
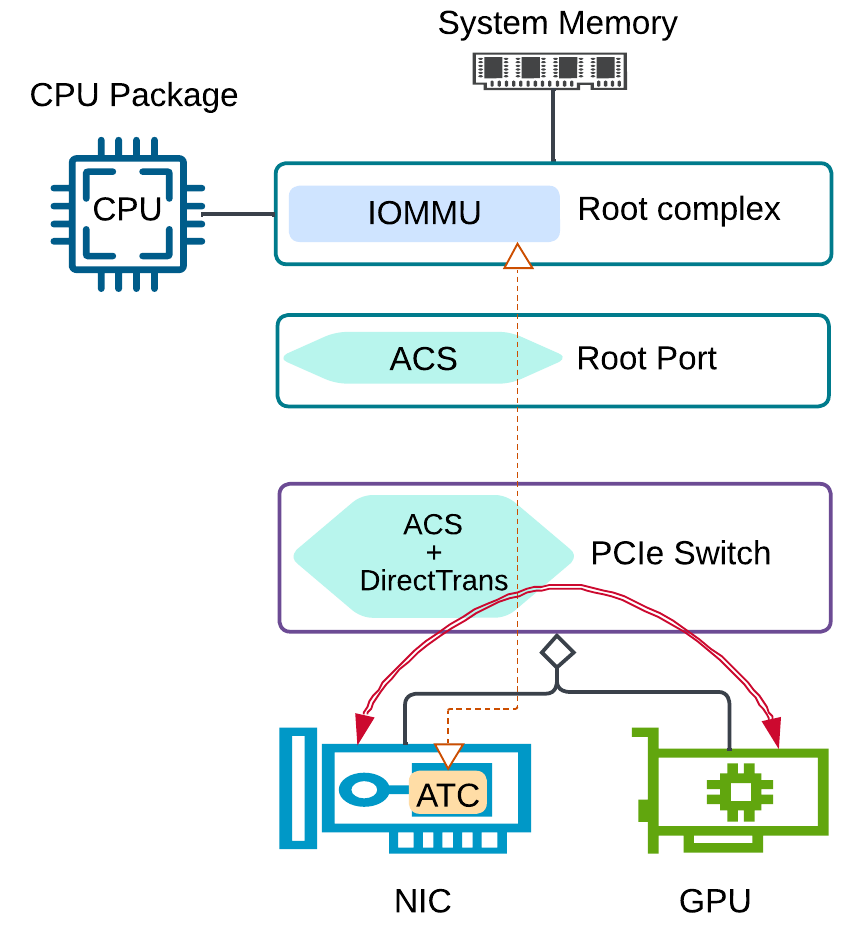
Deploy Distributed LLM Inference with GPUDirect RDMA over InfiniBand in ...

Distributed vLLM Inference - Bristol Centre for Supercomputing ...
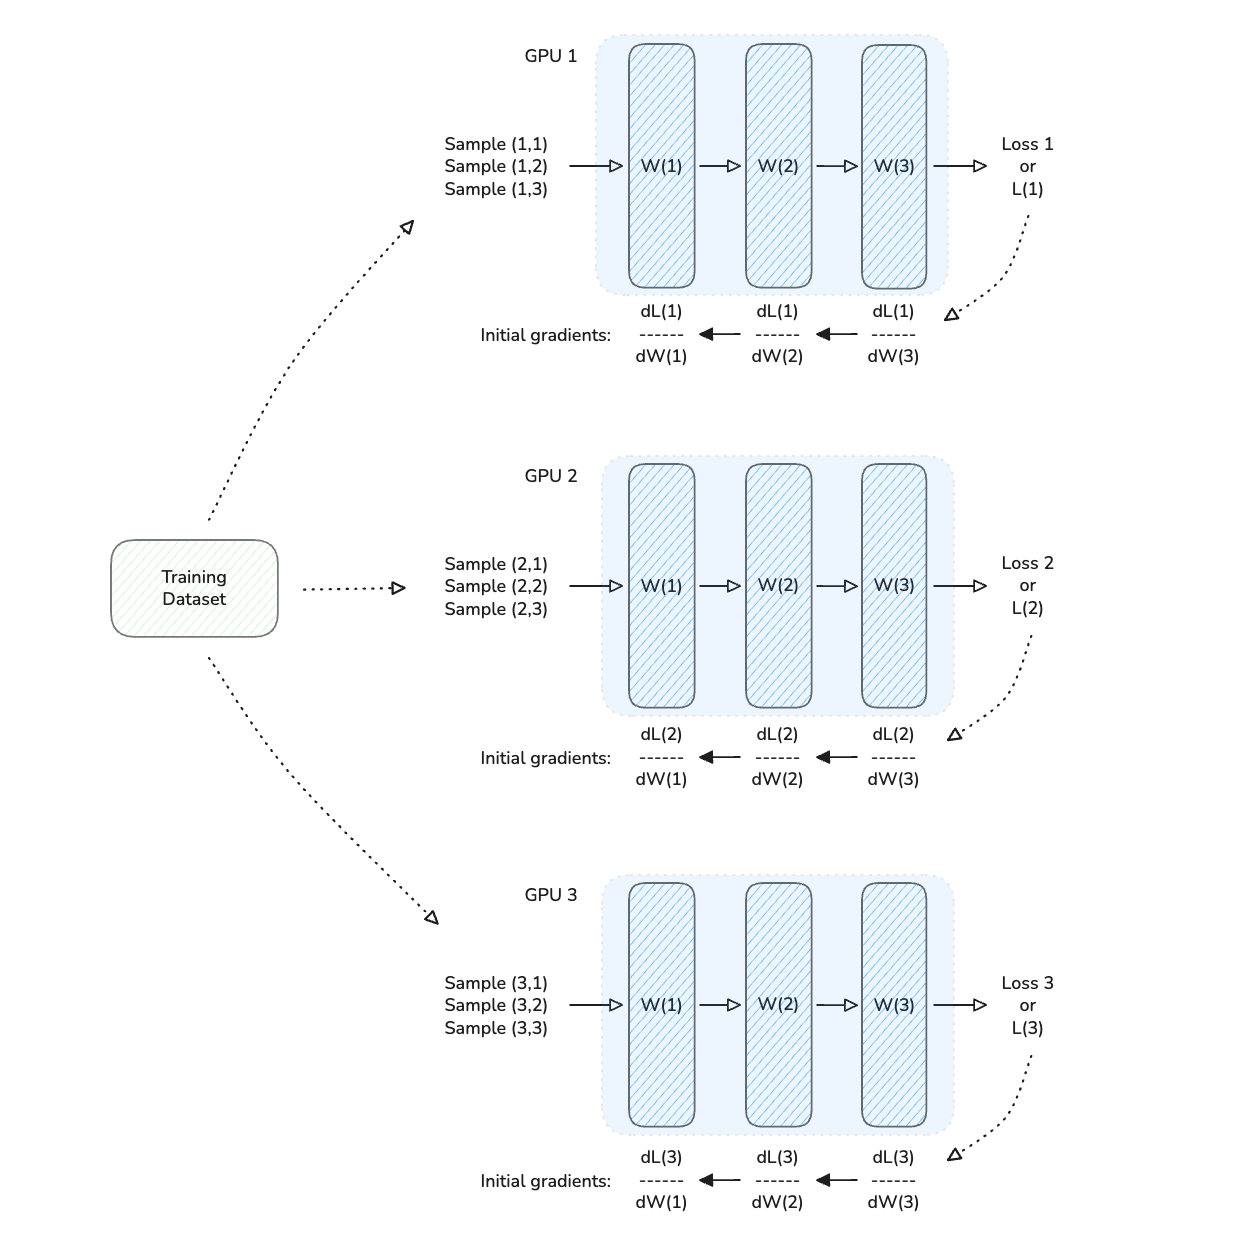
Learn to train deep learning models on multiple GPUs
Advertisement Space (336x280)
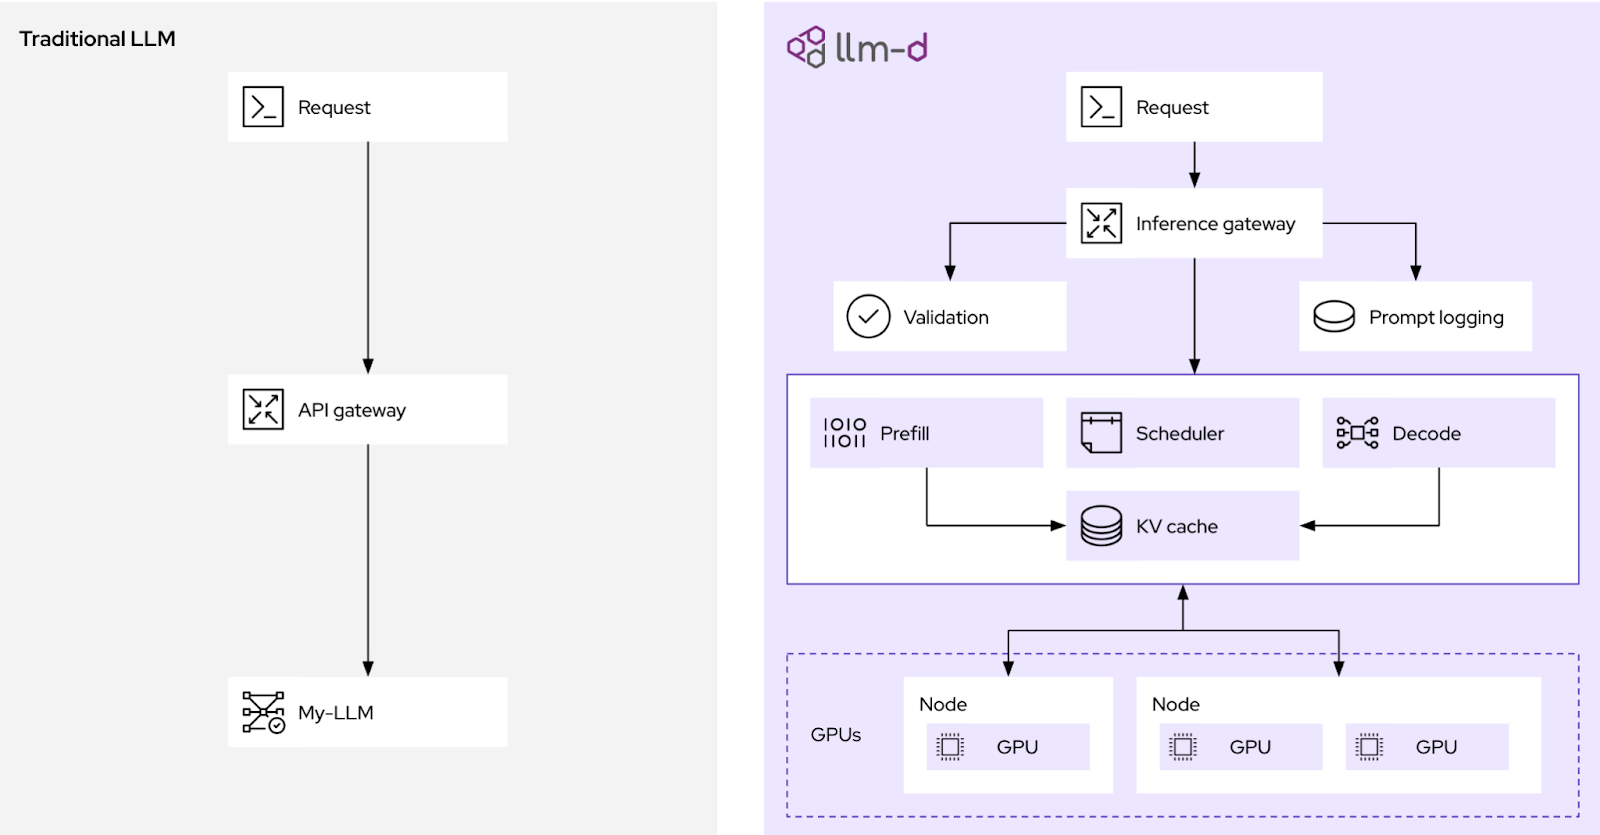
Introduction to distributed inference with llm-d | Red Hat Developer

LLM 推理框架之上:10 种常见 LLM 推理系统总结_helix: distributed serving of large ...

Distributed inference with vLLM | Red Hat Developer
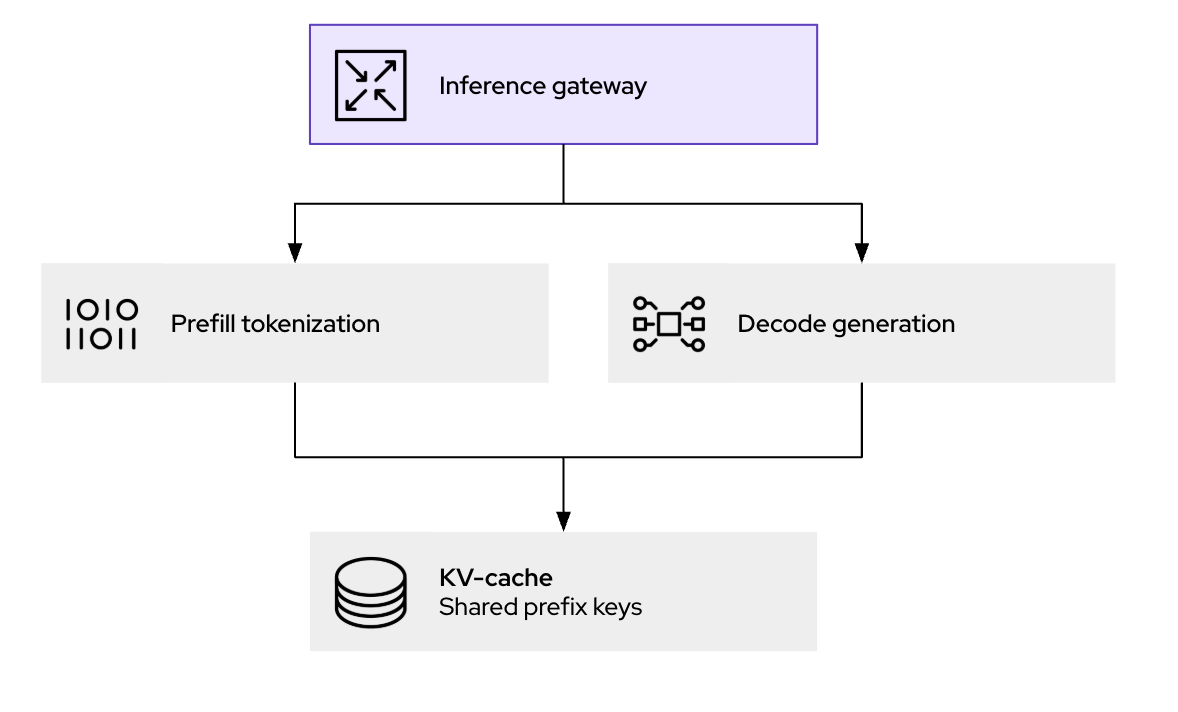
Introduction to distributed inference with llm-d | Red Hat Developer

Chapter 4. Distributed inference workloads | Distributed Inference with ...
Distributed Inference vs Multi-GPU Inference | Luca Berton

LLM 推理框架之上:10 种常见 LLM 推理系统总结_helix: distributed serving of large ...
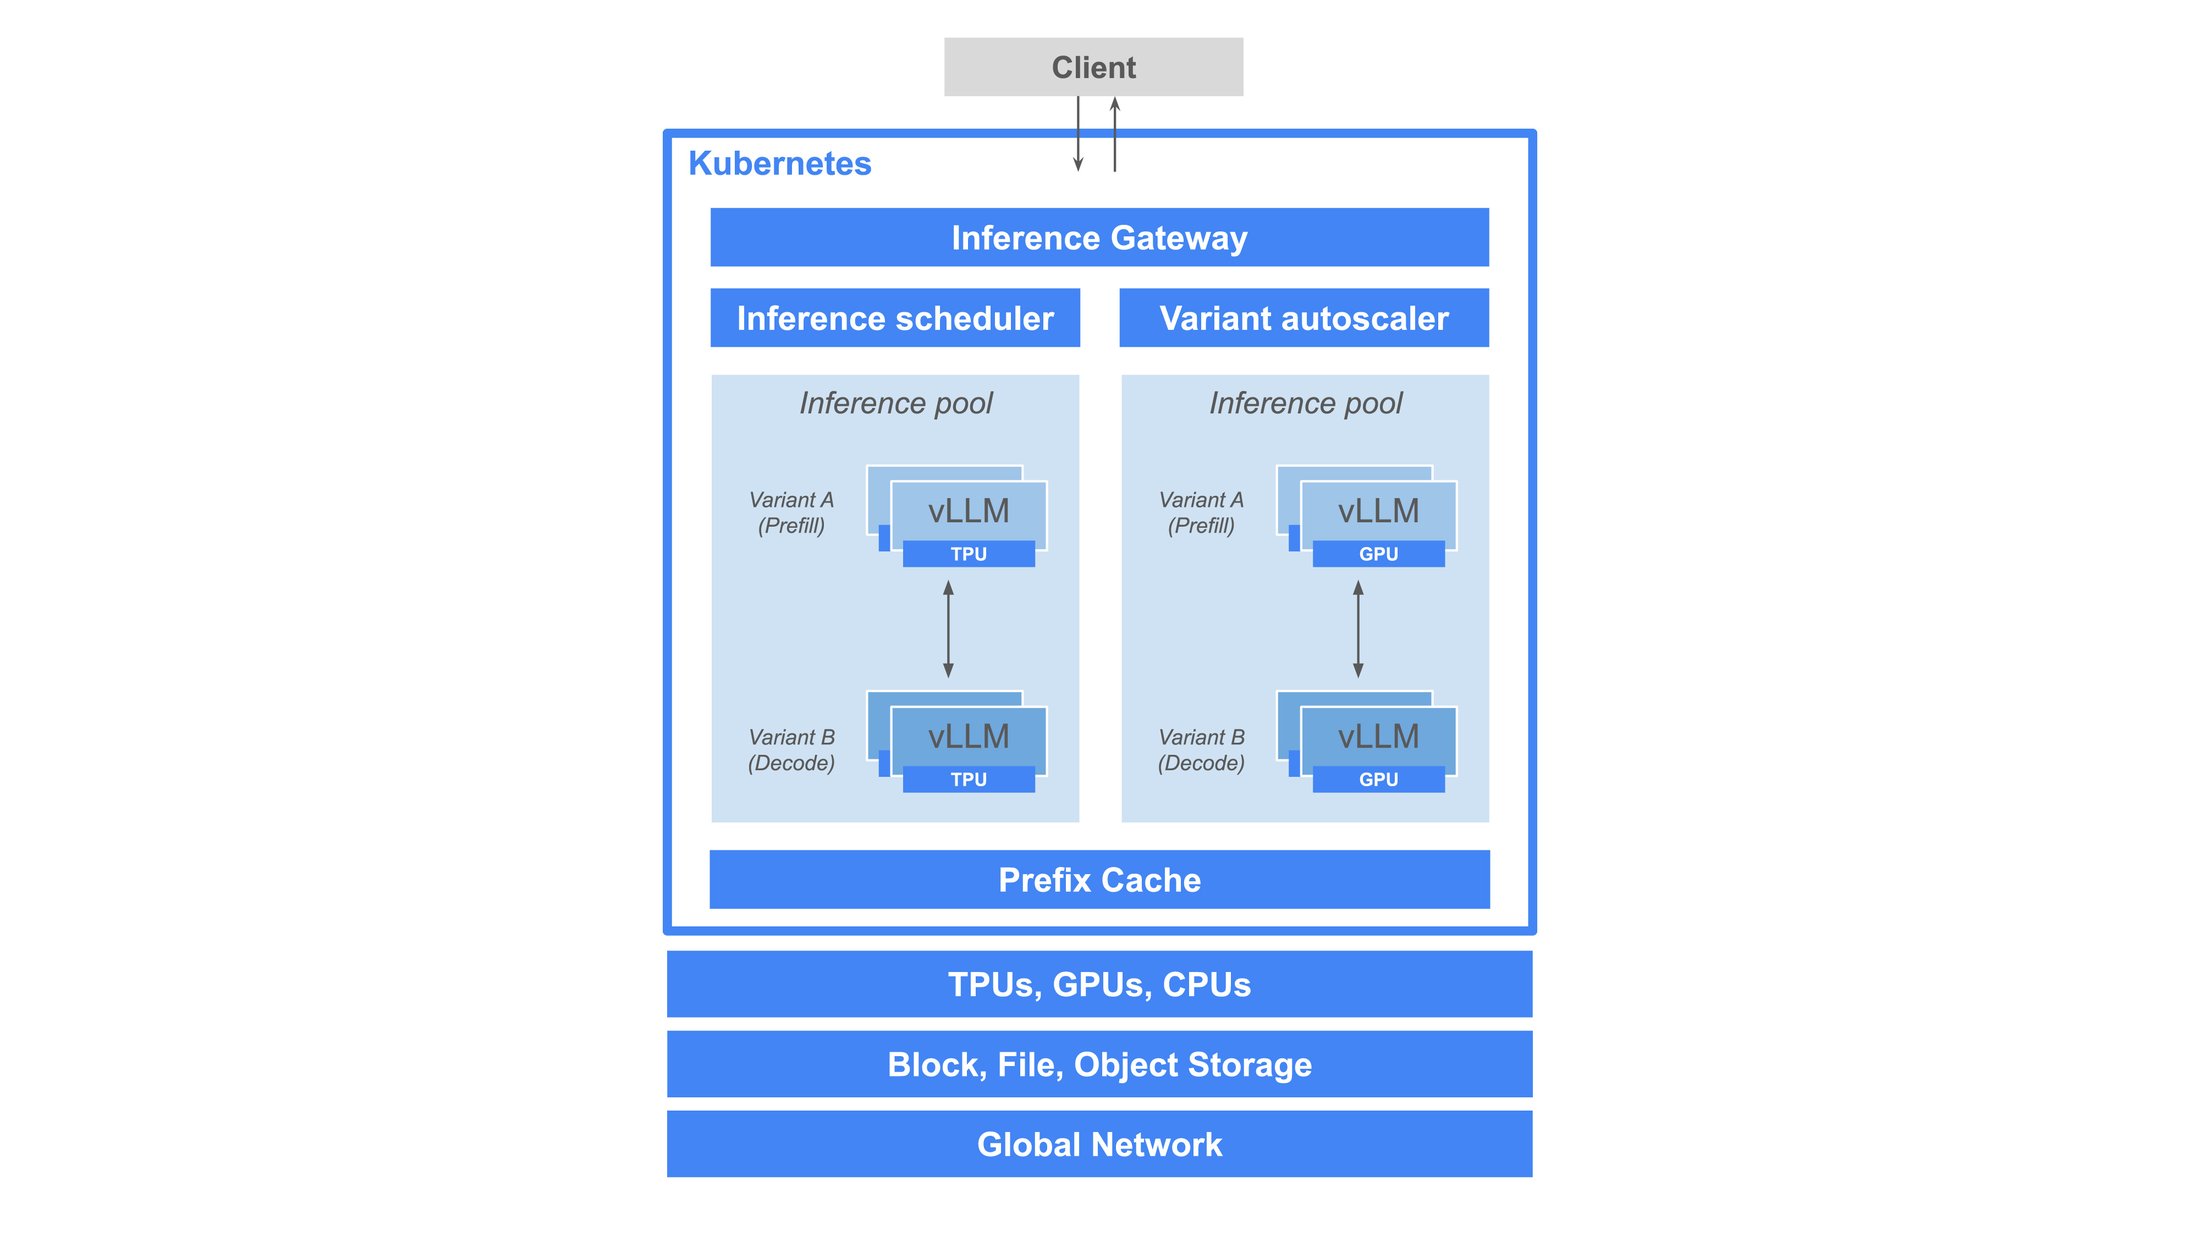
Enhancing vllm for distributed inference with llm-d | Google Cloud Blog
Multi-GPU and Distributed Inference | ipex-llm/ipex-llm | DeepWiki
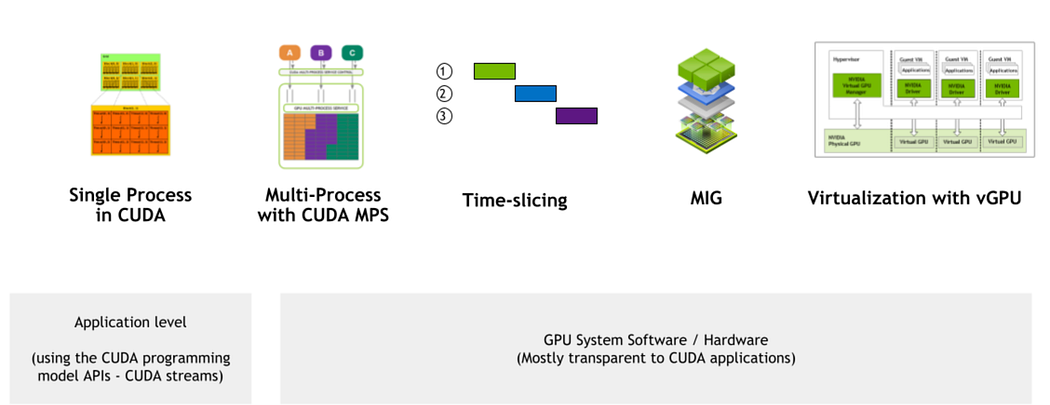
Distributed Training in MLOps: How to Efficiently Use GPUs for ...
Advertisement Space (336x280)
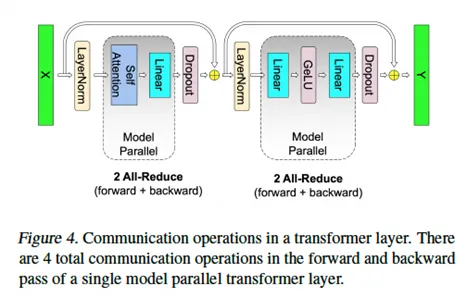
Analyzing the Distributed Inference Process Using vLLM and Ray from the ...

Figure 1 from Demystifying AI Platform Design for Distributed Inference ...

Practical, Fault‑Robust Distributed Inference for DeepSeek on AMD ...

Large-Scale Distributed LLM Inference — Part 2 : Modern Attention ...

Serving Inference for LLMs: A Case Study | CoreWeave
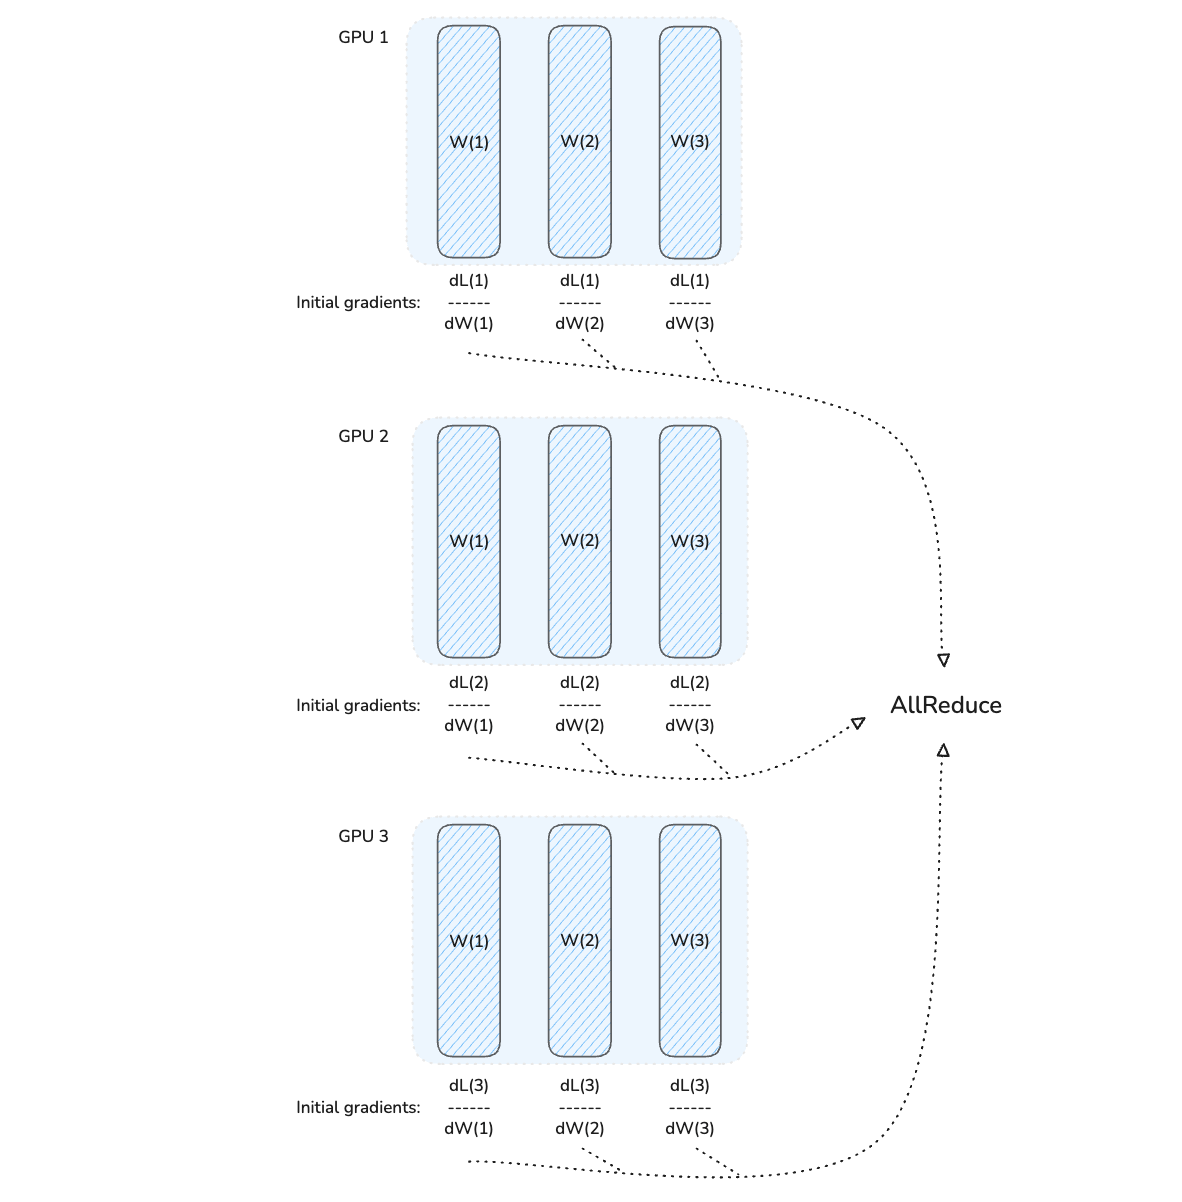
Learn to train deep learning models on multiple GPUs