
Distributed Mixture Of Experts And Expert Parallelism Bruno Magalhaes
Distributed Mixture-of-Experts and Expert Parallelism | Bruno Magalhaes
Distributed Mixture-of-Experts and Expert Parallelism | Bruno Magalhaes
Distributed Mixture-of-Experts and Expert Parallelism | Bruno Magalhaes
Distributed Mixture-of-Experts and Expert Parallelism | Bruno Magalhaes
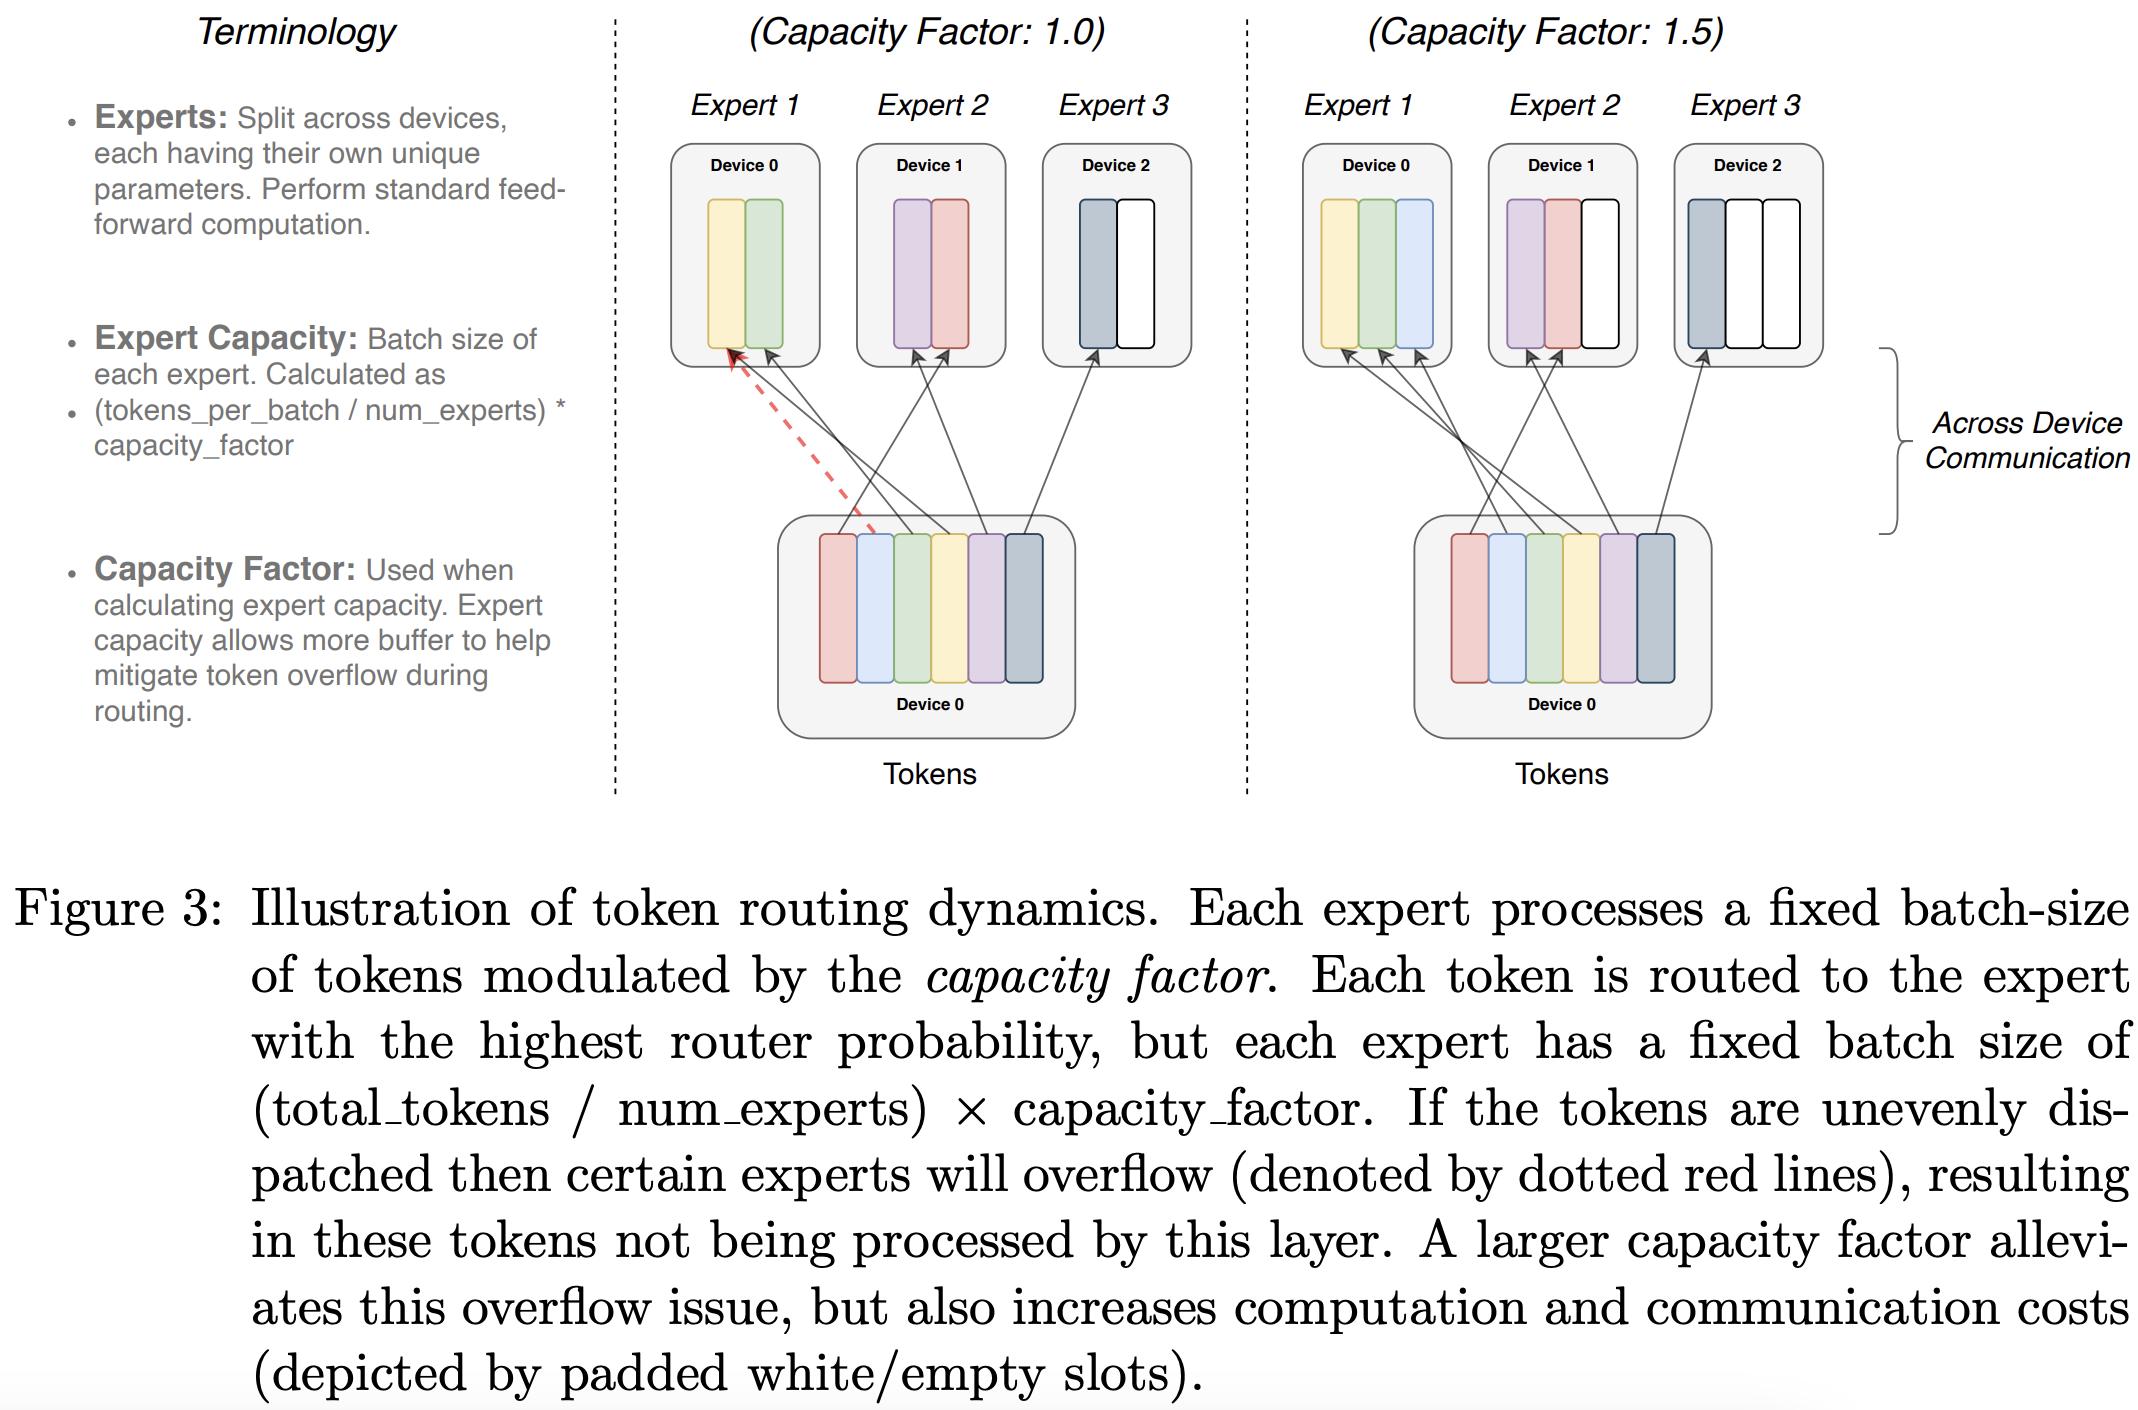
Distributed Mixture-of-Experts and Expert Parallelism | Bruno Magalhaes
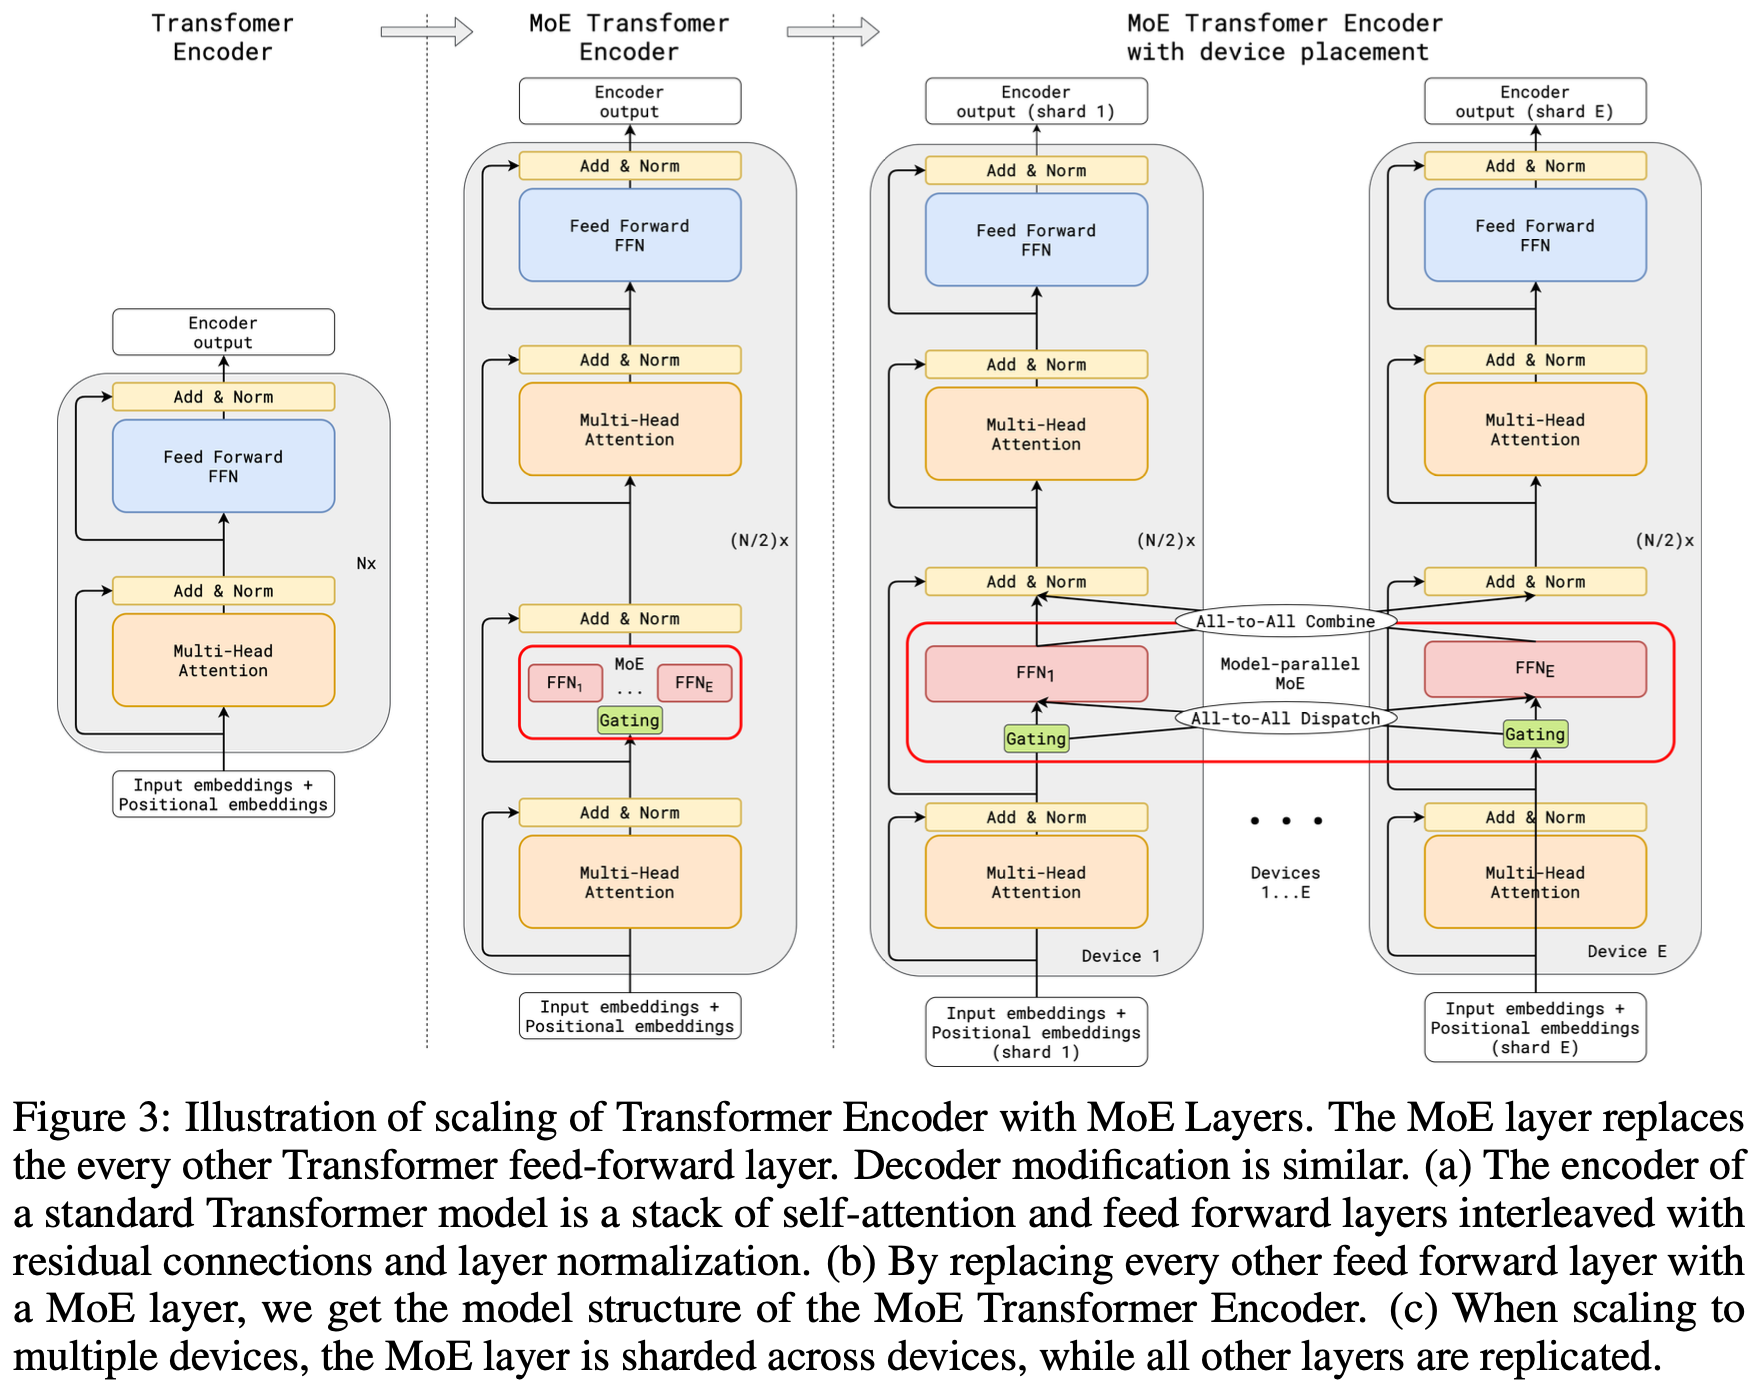
Distributed Mixture-of-Experts and Expert Parallelism | Bruno Magalhaes
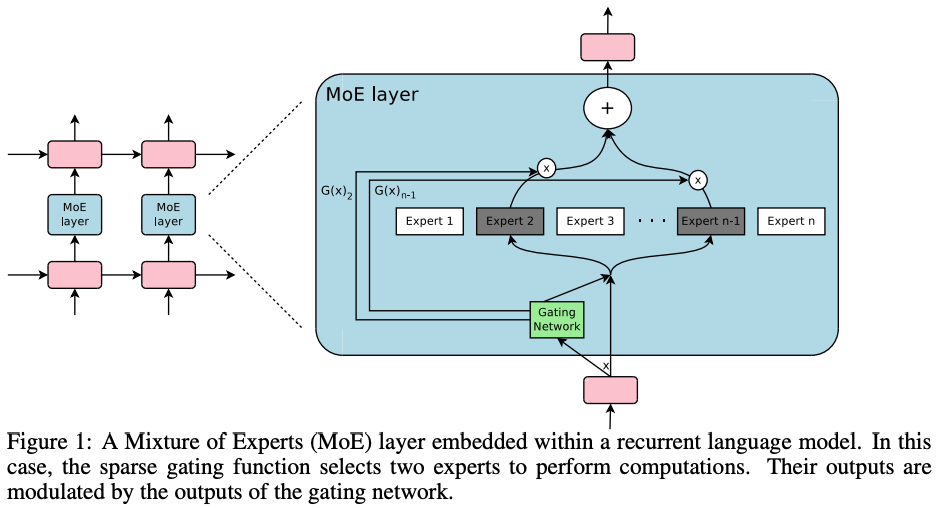
Distributed Mixture-of-Experts and Expert Parallelism | Bruno Magalhaes
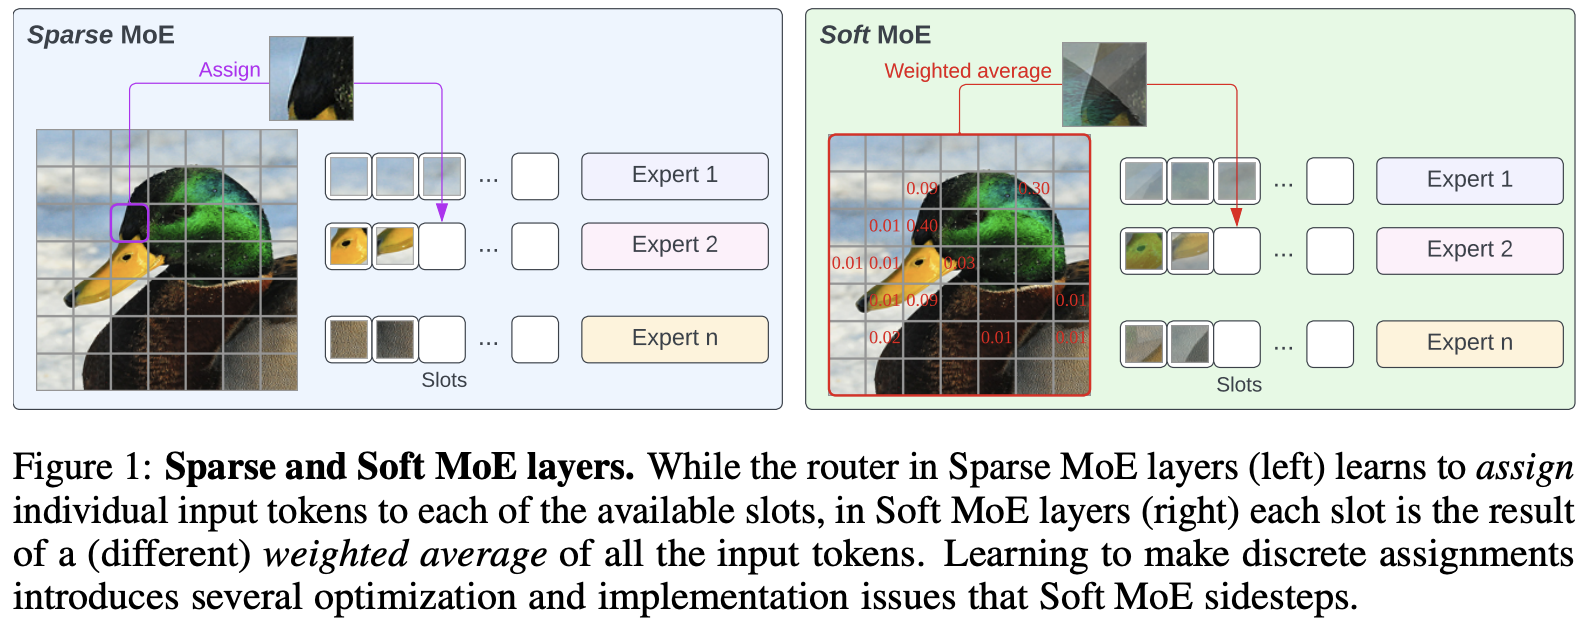
Distributed Mixture-of-Experts and Expert Parallelism | Bruno Magalhaes
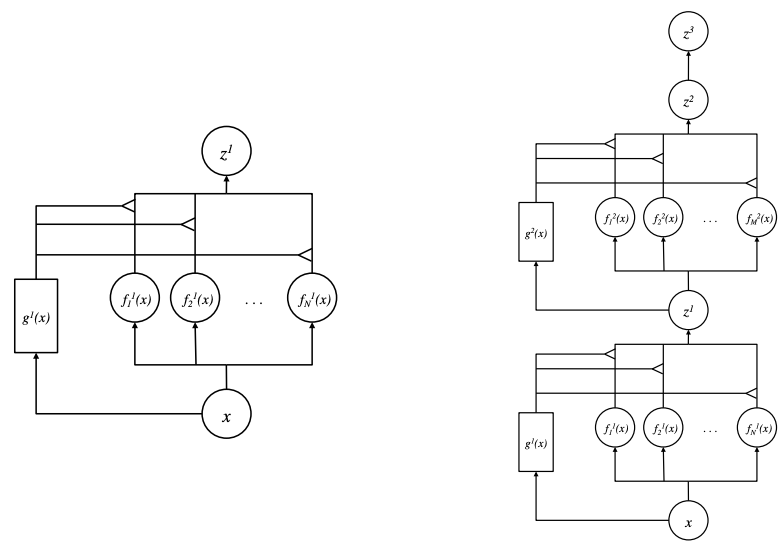
Distributed Mixture-of-Experts and Expert Parallelism | Bruno Magalhaes
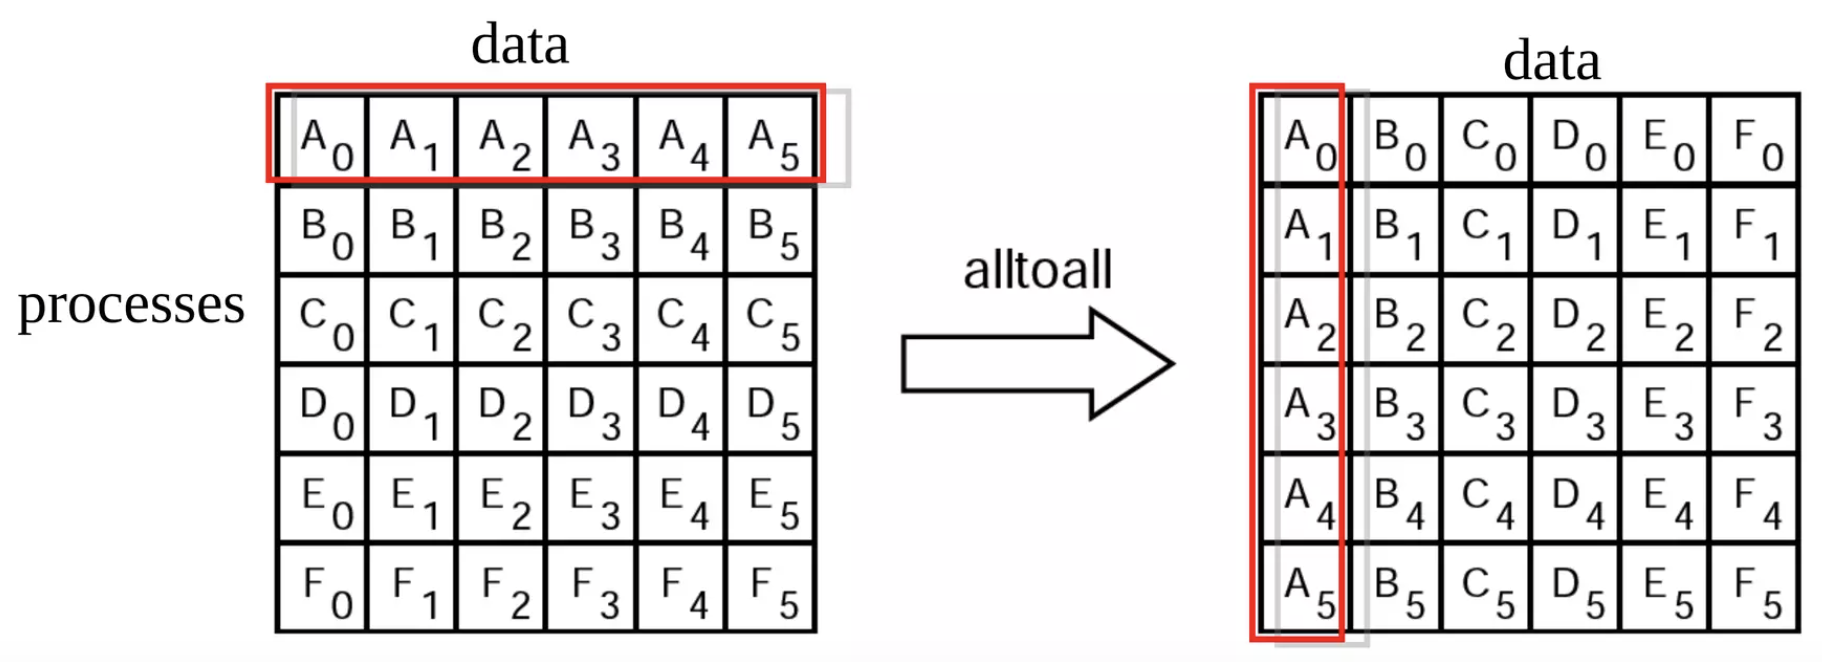
Distributed Mixture-of-Experts and Expert Parallelism | Bruno Magalhaes
Advertisement Space (300x250)
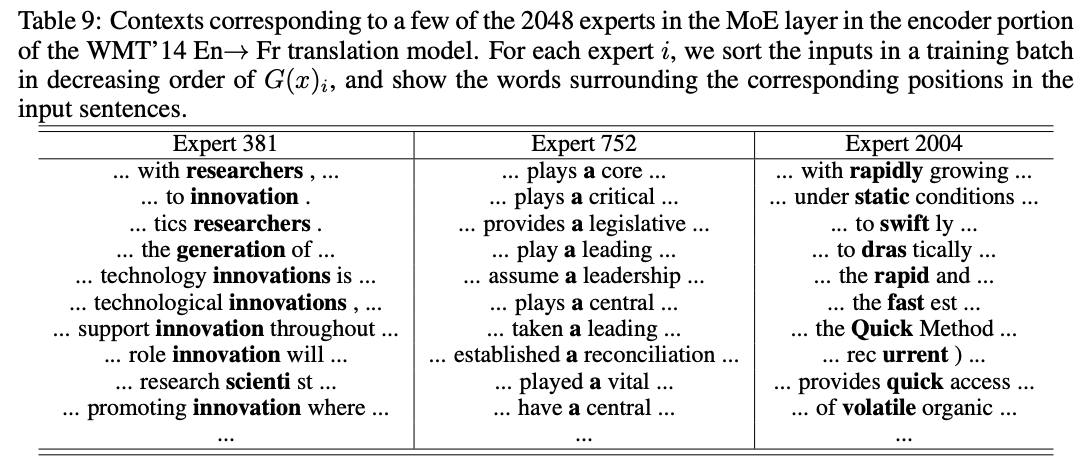
Distributed Mixture-of-Experts and Expert Parallelism | Bruno Magalhaes
Expert Parallelism: Distributed Training for Mixture of Experts ...
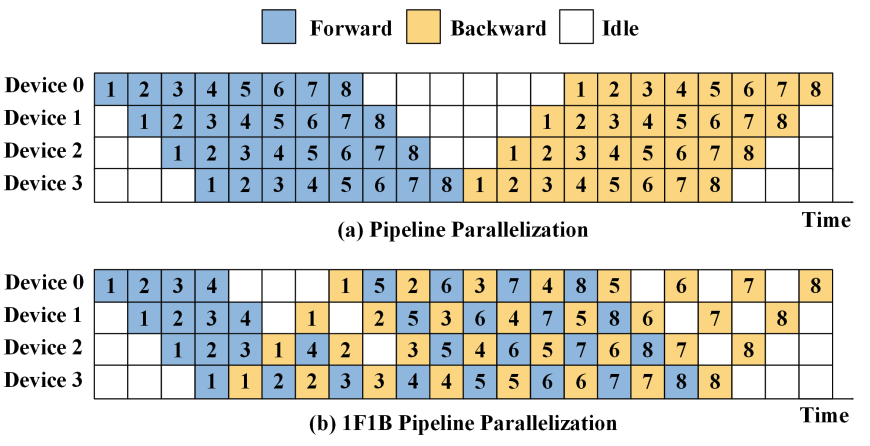
Distributed GPT model (part 2): pipeline parallelism | Bruno Magalhaes
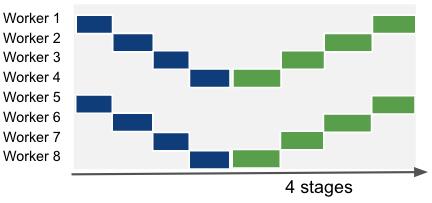
Distributed GPT model (part 2): pipeline parallelism | Bruno Magalhaes

(PDF) WDMoE: Wireless Distributed Mixture of Experts for Large Language ...
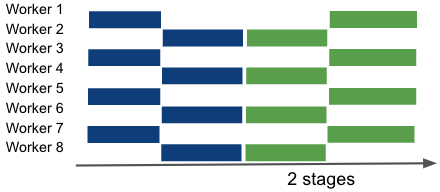
Distributed GPT model (part 2): pipeline parallelism | Bruno Magalhaes

Mixture of Experts with Soft Nearest Neighbor Loss: Resolving Expert ...

WDMoE: Wireless Distributed Mixture of Experts for Large Language Models

WDMoE: Wireless Distributed Mixture of Experts for Large Language Models
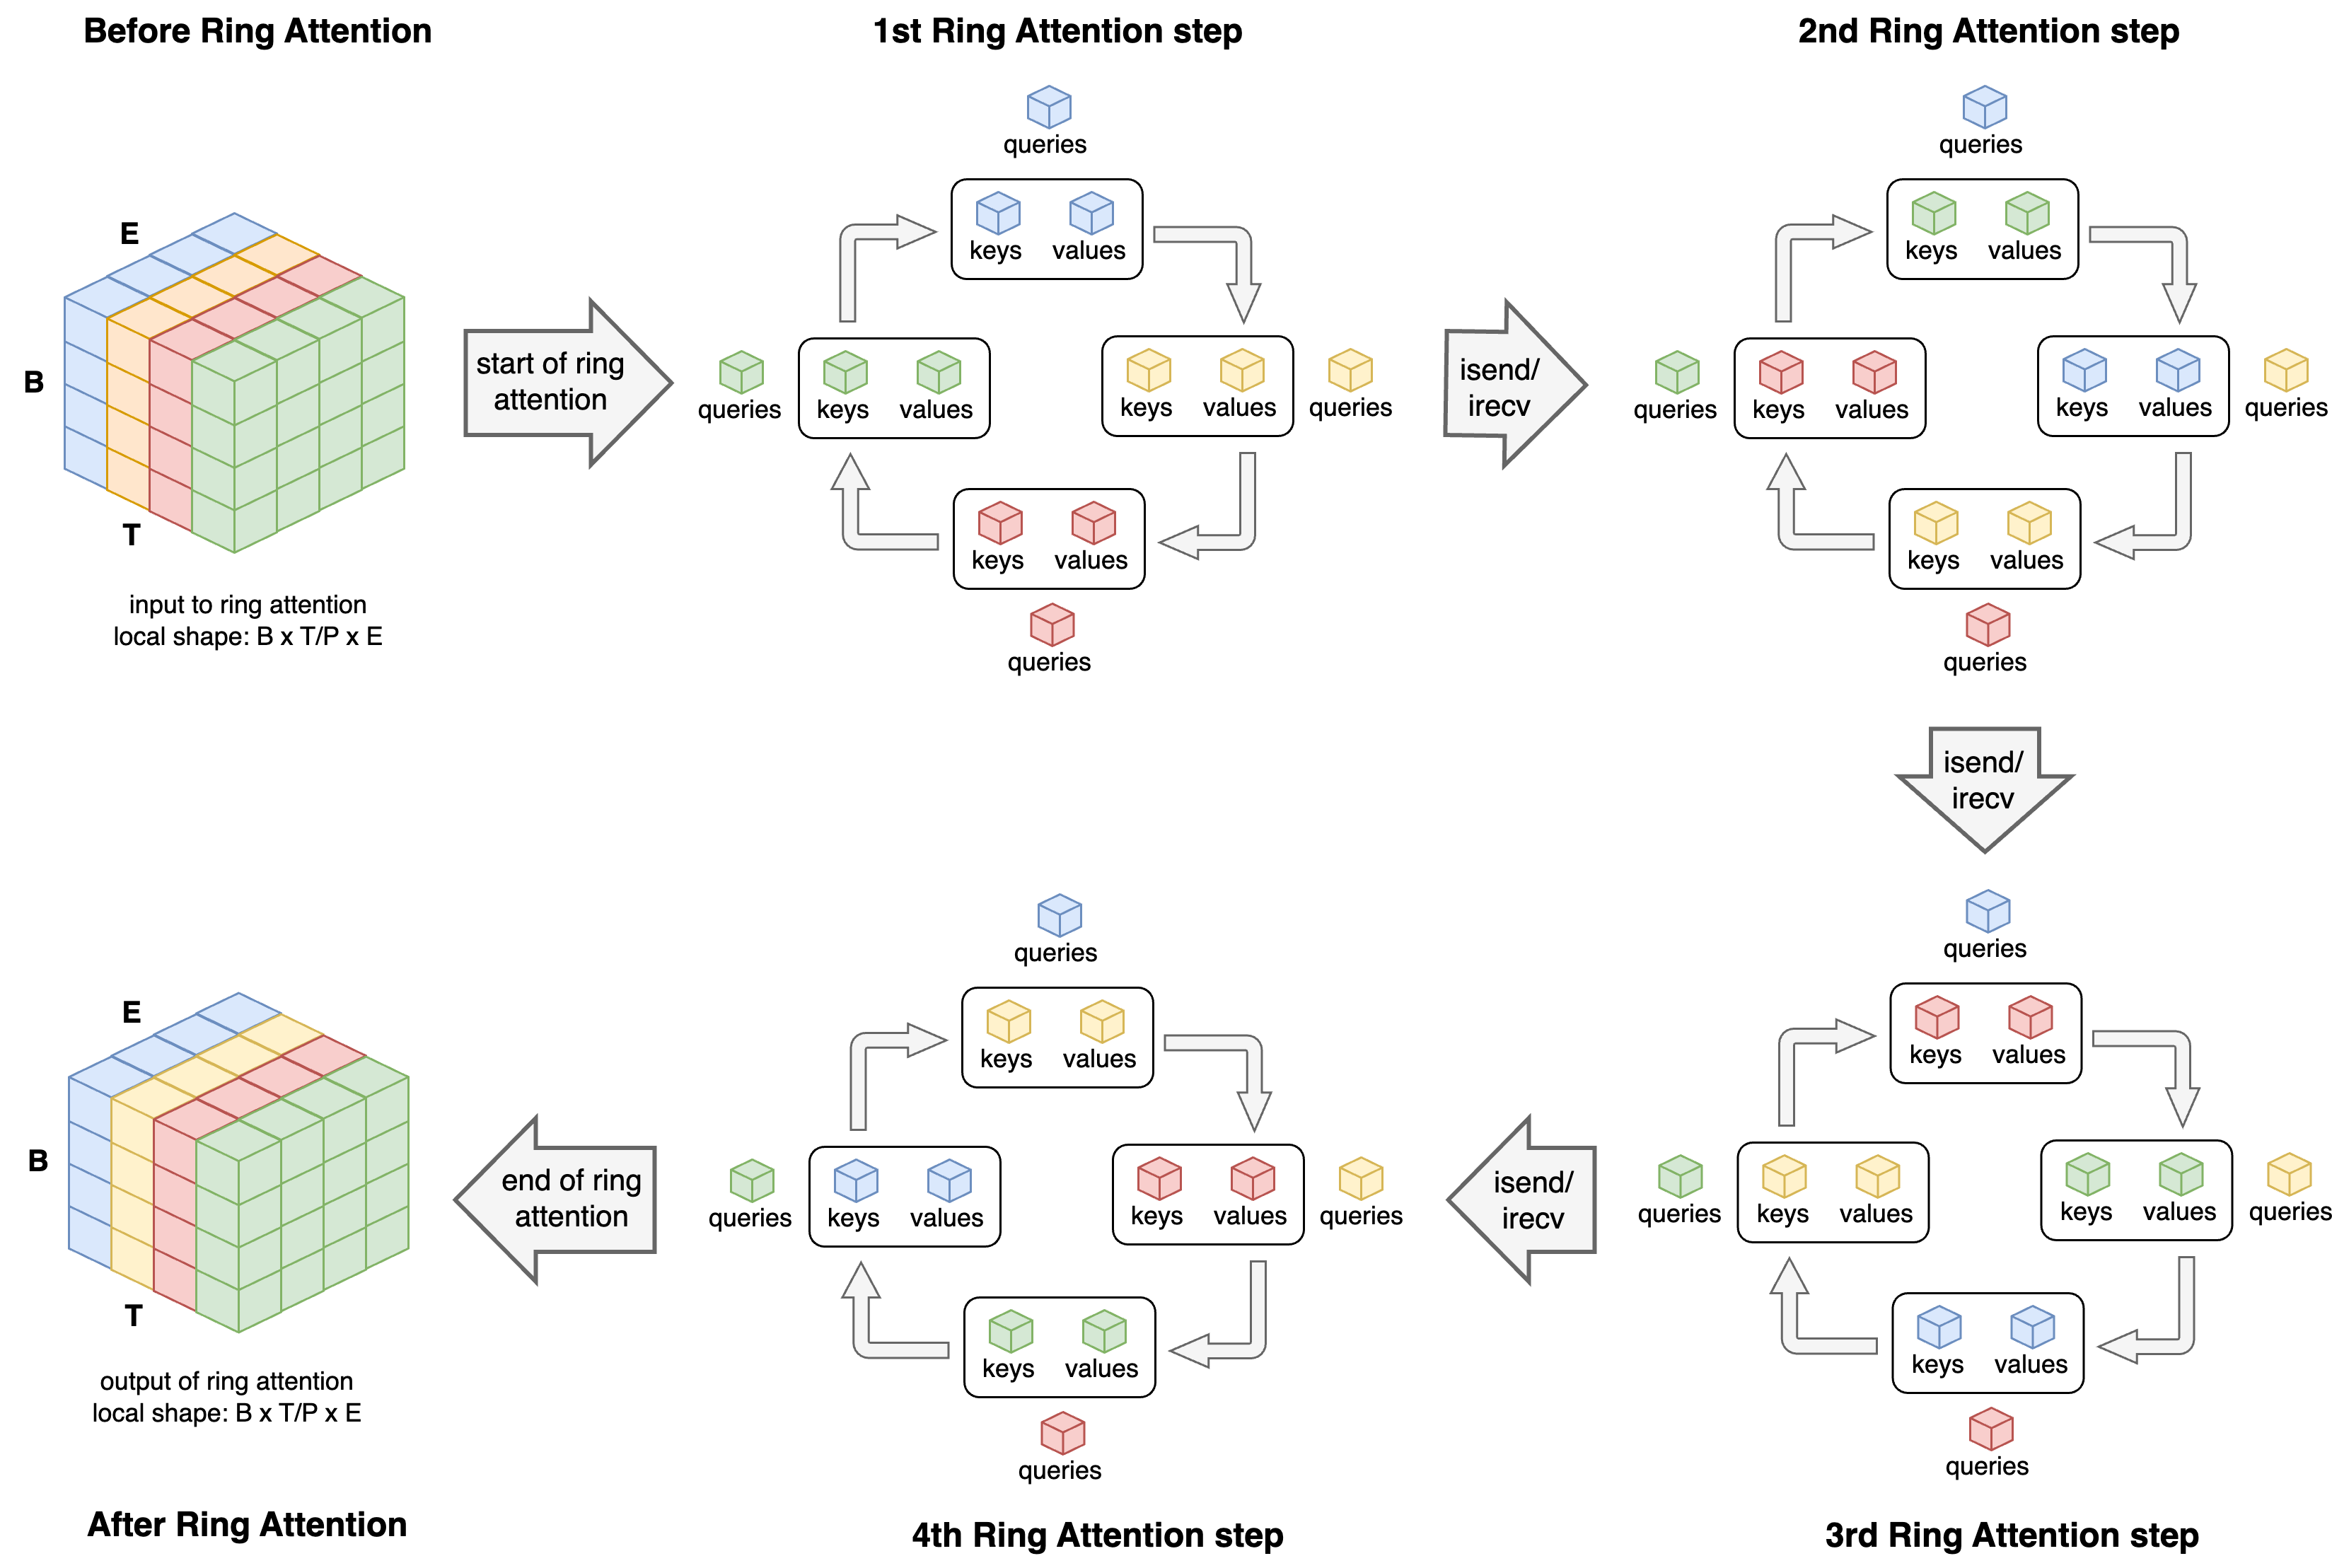
Distributed GPT model (part 4): sequence and context parallelism with ...
Advertisement Space (336x280)
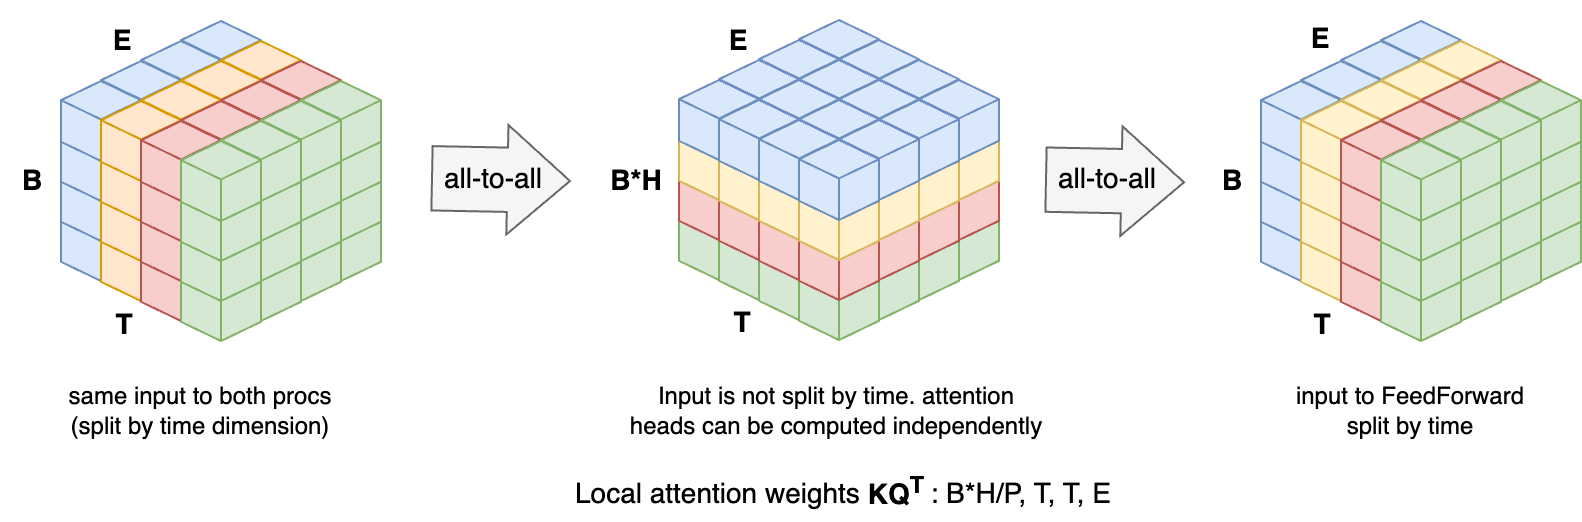
Distributed GPT model (part 4): sequence and context parallelism with ...
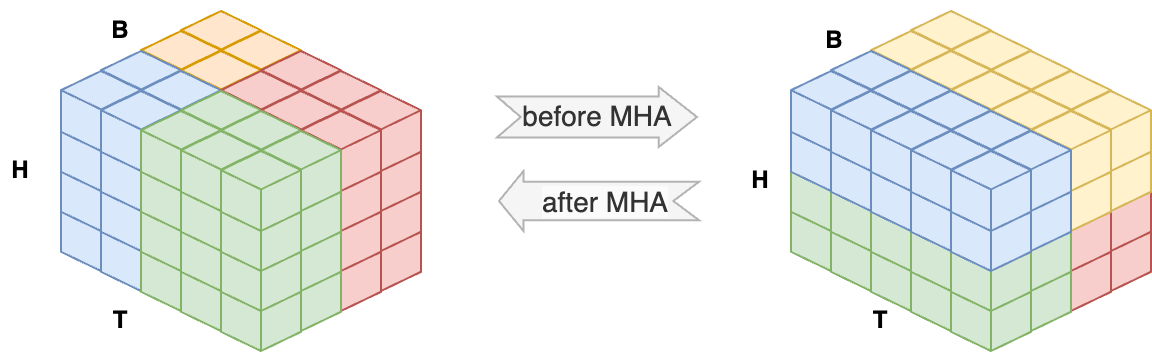
Distributed GPT model (part 4): context and sequence parallelism with ...
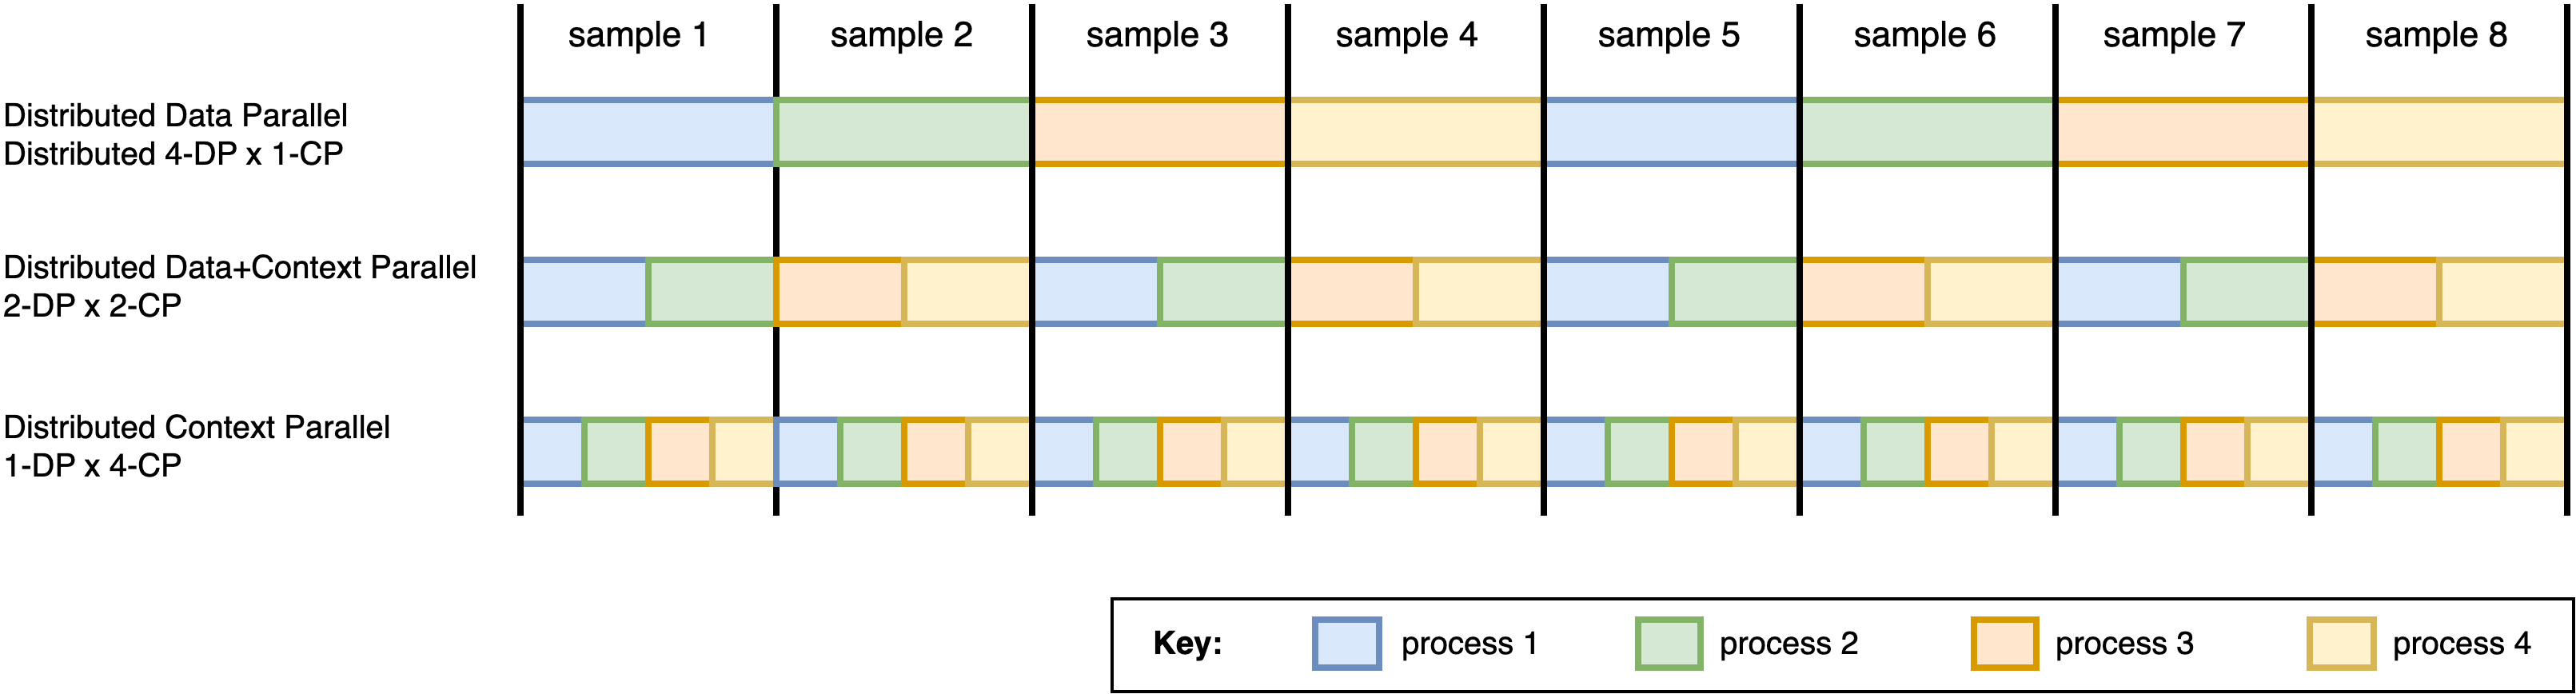
Distributed GPT model (part 4): sequence and context parallelism with ...
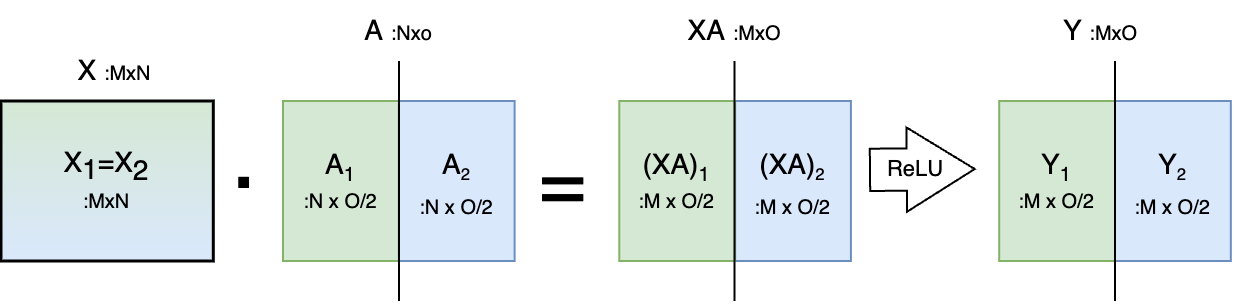
Distributed GPT model (part 3): Megatron-LM tensor parallelism | Bruno ...

Distributed GPT model (part 3): Megatron-LM tensor parallelism | Bruno ...
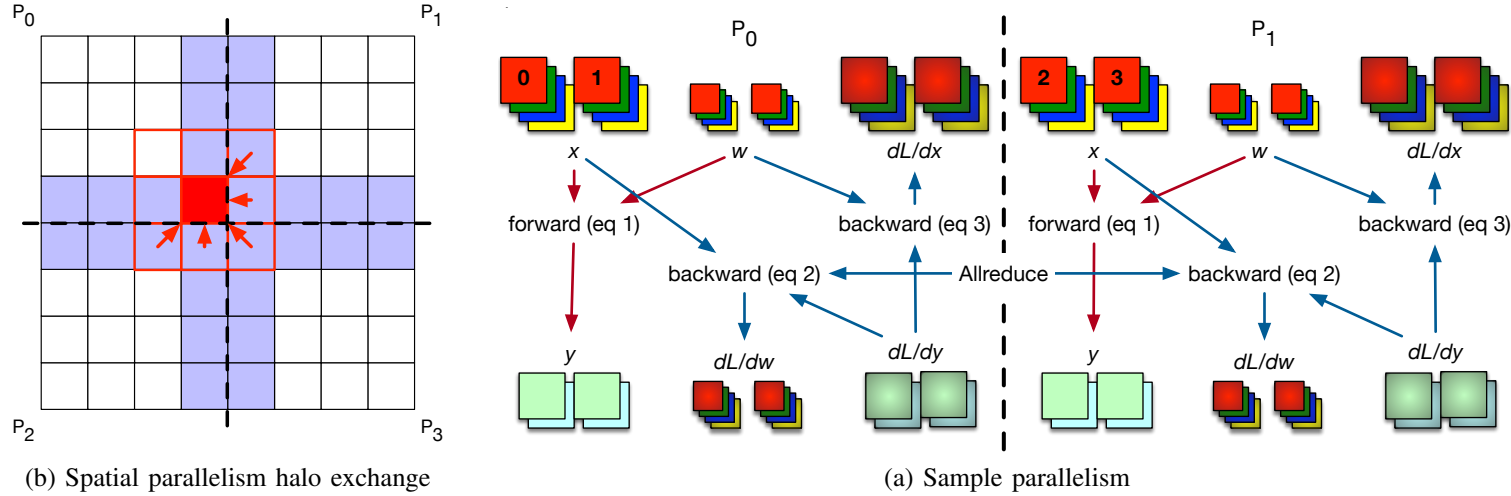
Distributed GPT model (part 3): Megatron-LM tensor parallelism | Bruno ...
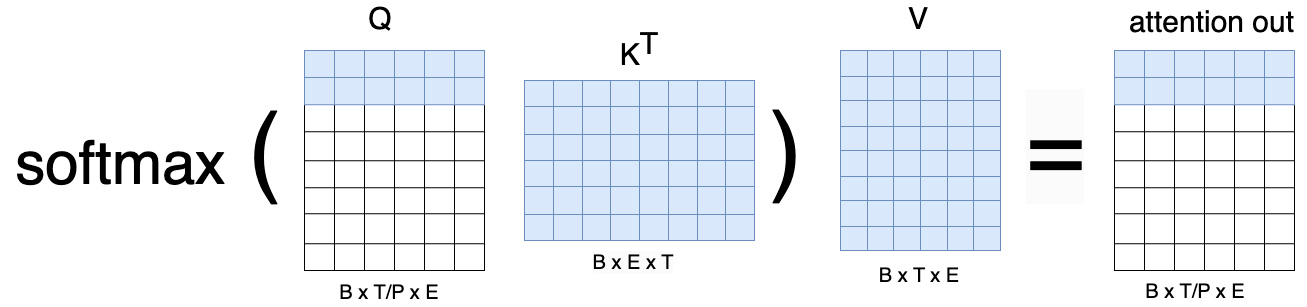
Distributed GPT model (part 4): sequence and context parallelism with ...
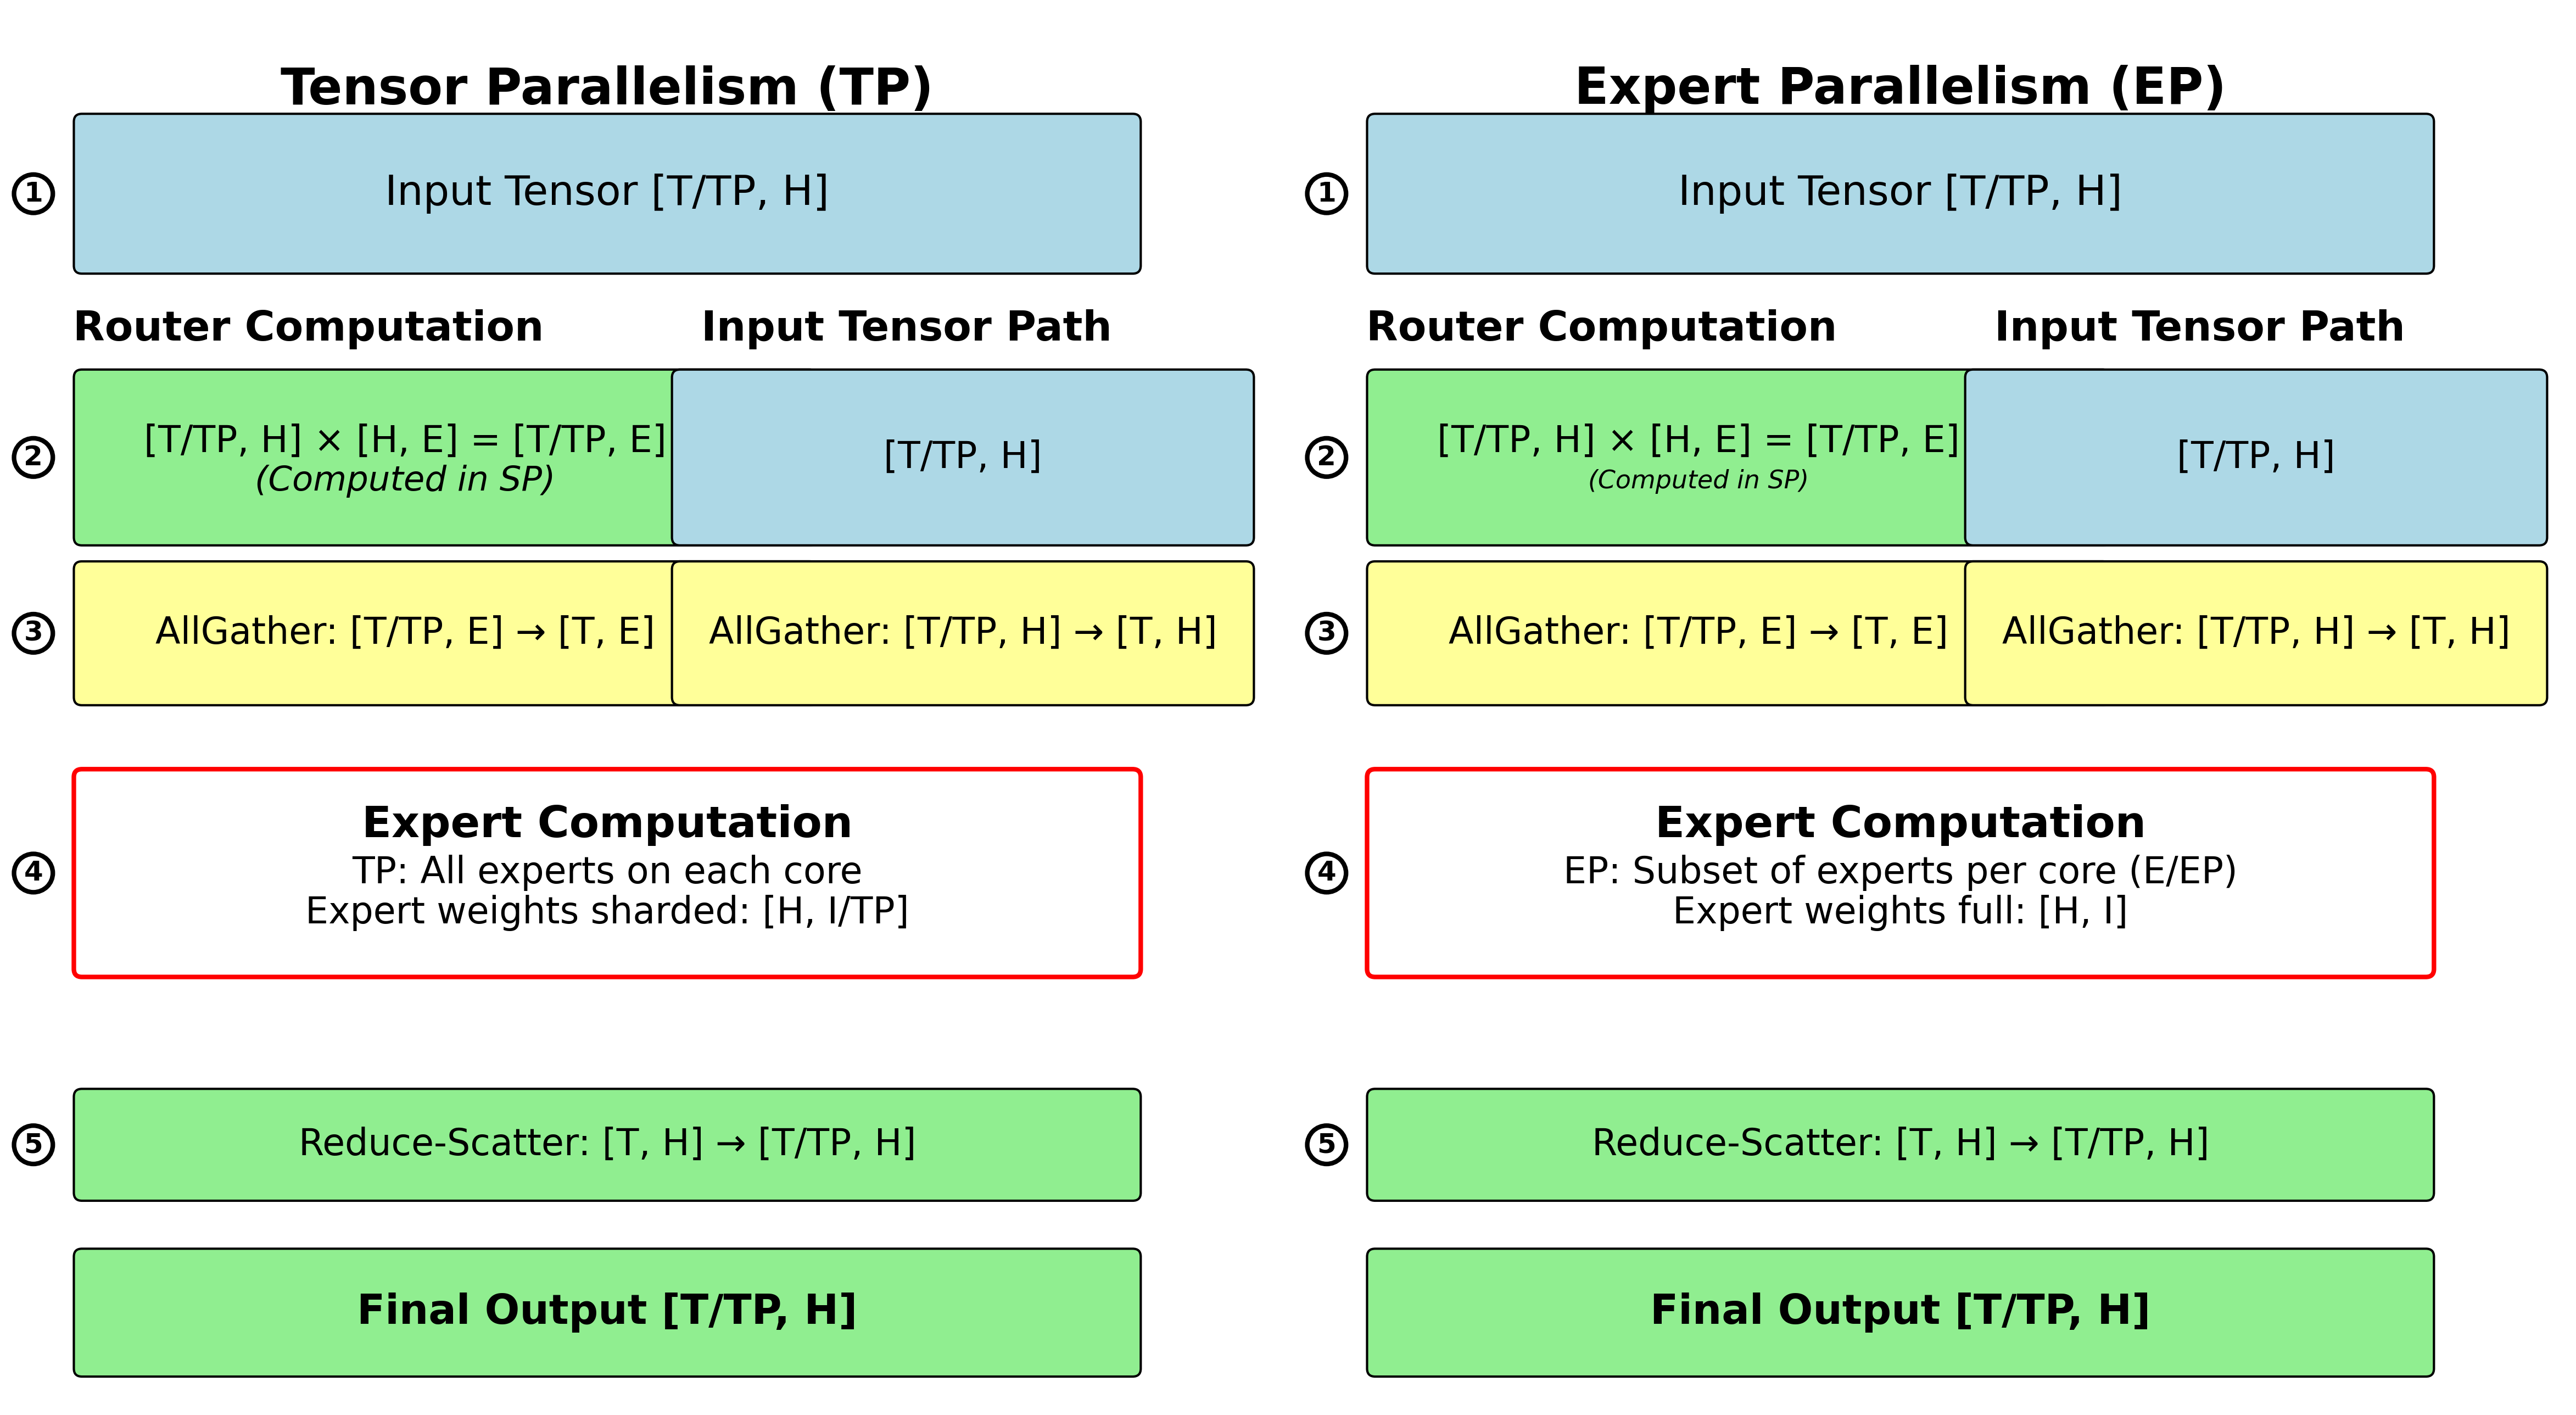
Deep dive: Explore Mixture of Experts (MoE) inference support for ...

Free Mixture of Experts (MoE) Visualizer | Simulations4All

Dynamic Expert Sharing: Decoupling Memory from Parallelism in Mixture ...
Advertisement Space (336x280)

A Survey on Inference Optimization Techniques for Mixture of Experts ...
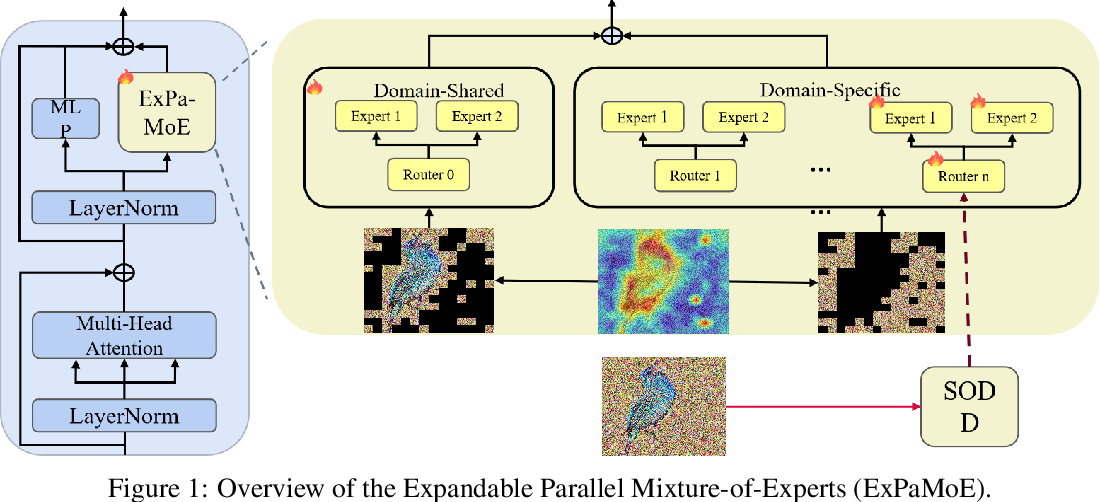
Figure 1 from ExPaMoE: An Expandable Parallel Mixture of Experts for ...
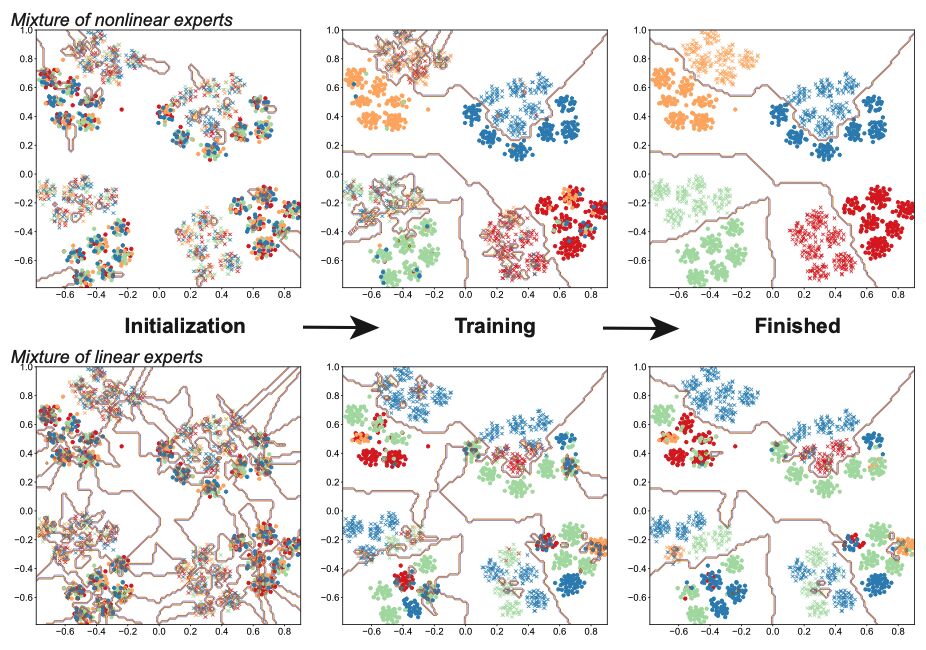
Aman's AI Journal • Primers • Mixture of Experts

A Visual Guide to Mixture of Experts (MoE)
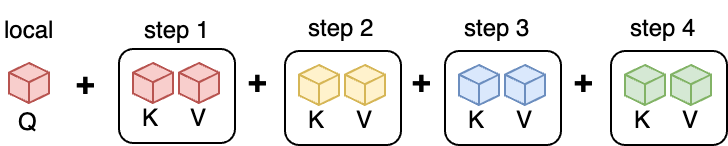
Distributed GPT model (part 4): context and sequence parallelism with ...

A Visual Guide to Mixture of Experts (MoE)