
Dynamic Width Speculative Beam Decoding For Efficient Llm Inference

Dynamic-Width Speculative Beam Decoding for Efficient LLM Inference ...

Reward-Guided Speculative Decoding for Efficient LLM Reasoning

Reward-Guided Speculative Decoding for Efficient LLM Reasoning

[논문 리뷰] SLED: A Speculative LLM Decoding Framework for Efficient Edge ...

PELM: Power Efficient On-Device LLM Inference with Speculative Decoding ...
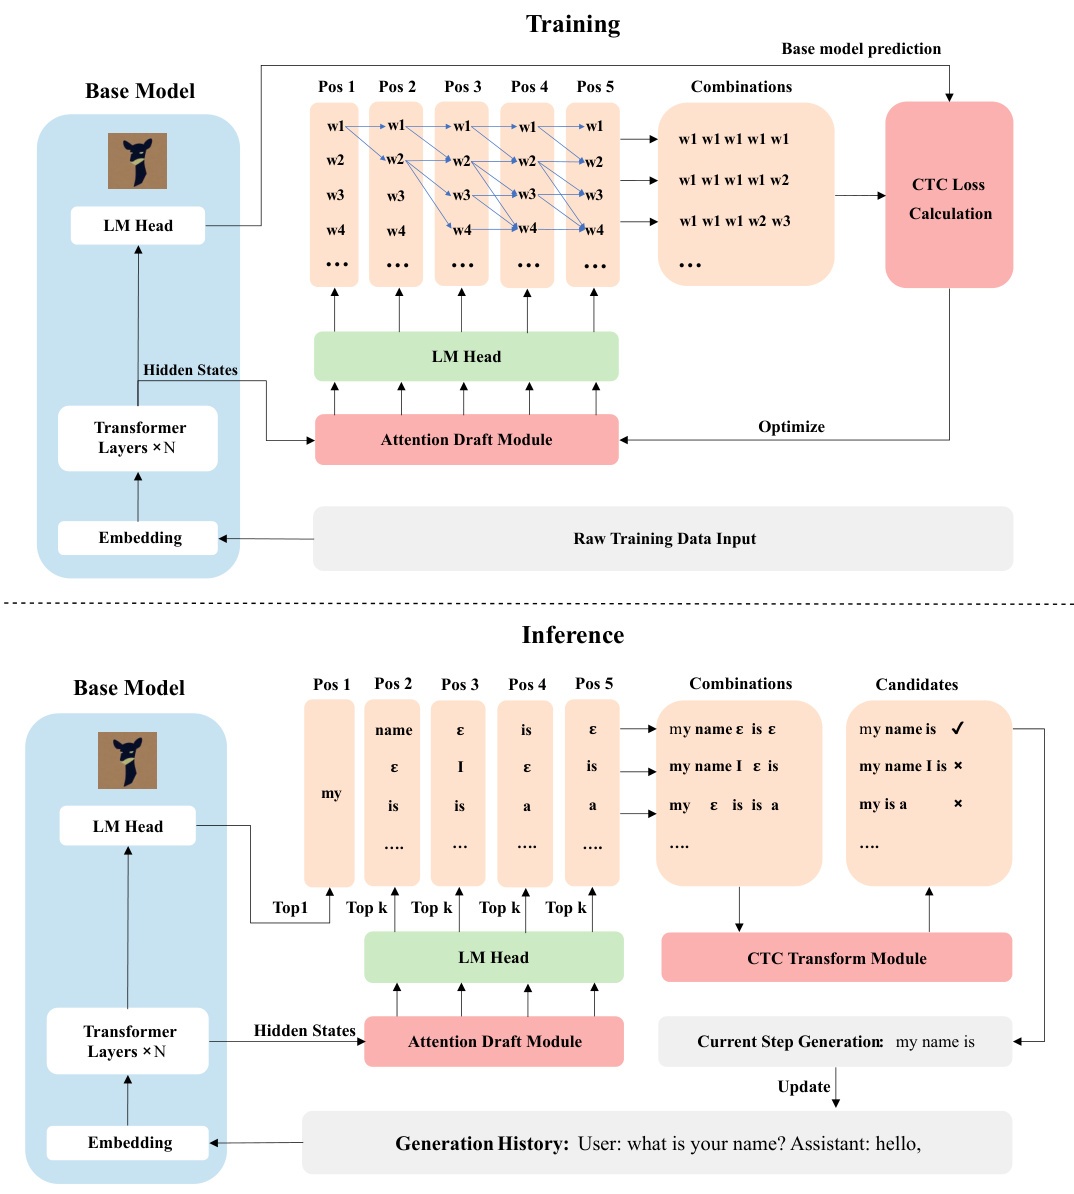
Speculative Decoding with CTC-based Draft Model for LLM Inference ...

PELM: Power Efficient On-Device LLM Inference with Speculative Decoding ...

PELM: Power Efficient On-Device LLM Inference with Speculative Decoding ...

Reward-Guided Speculative Decoding for Efficient LLM Reasoning
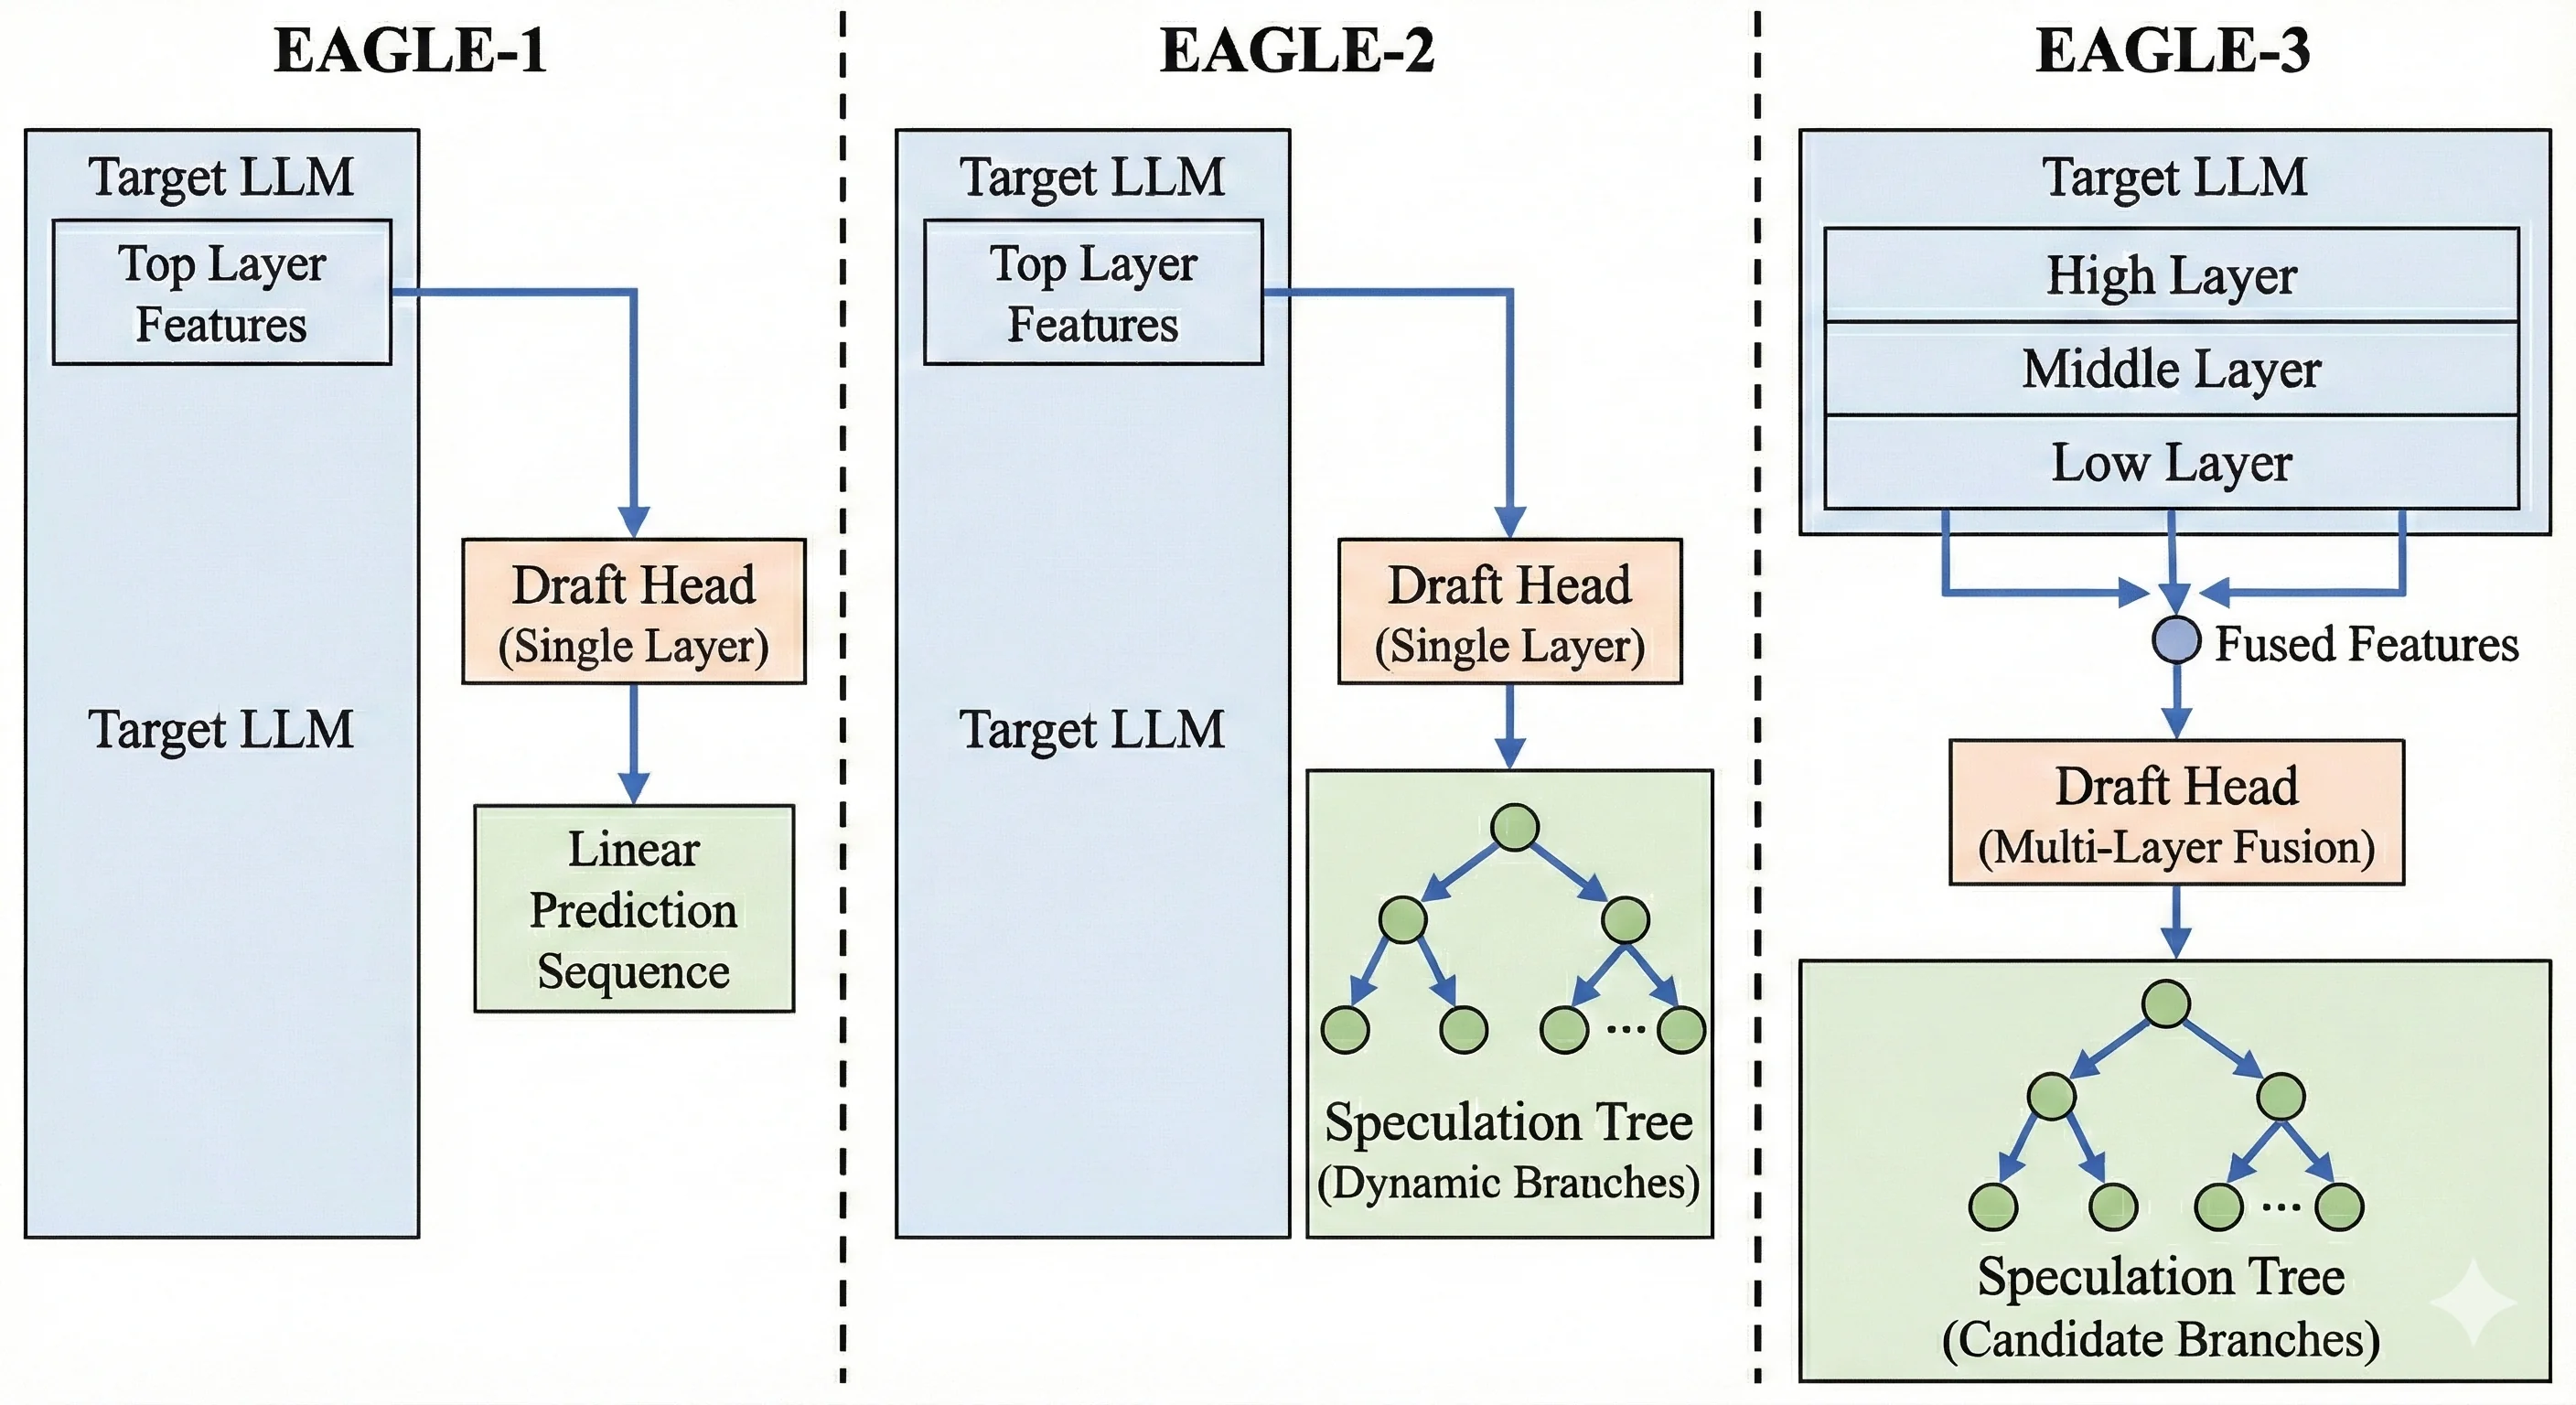
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
Advertisement Space (300x250)
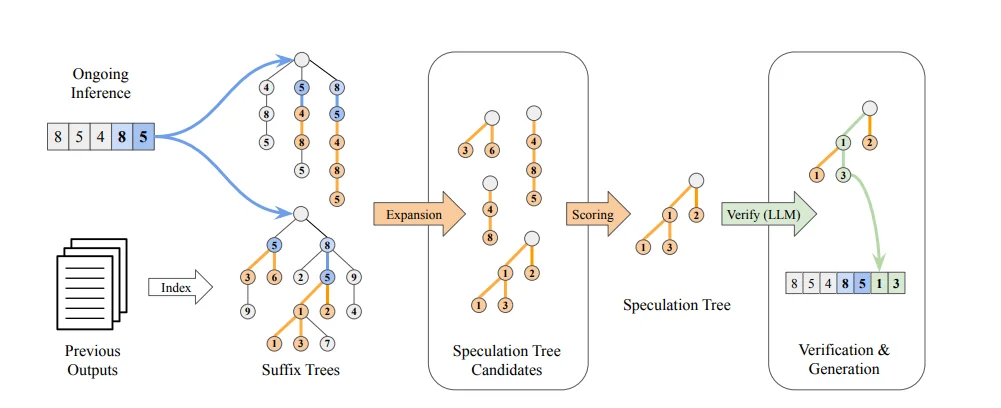
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...

Towards Efficient LLM Inference via Collective and Adaptive Speculative ...
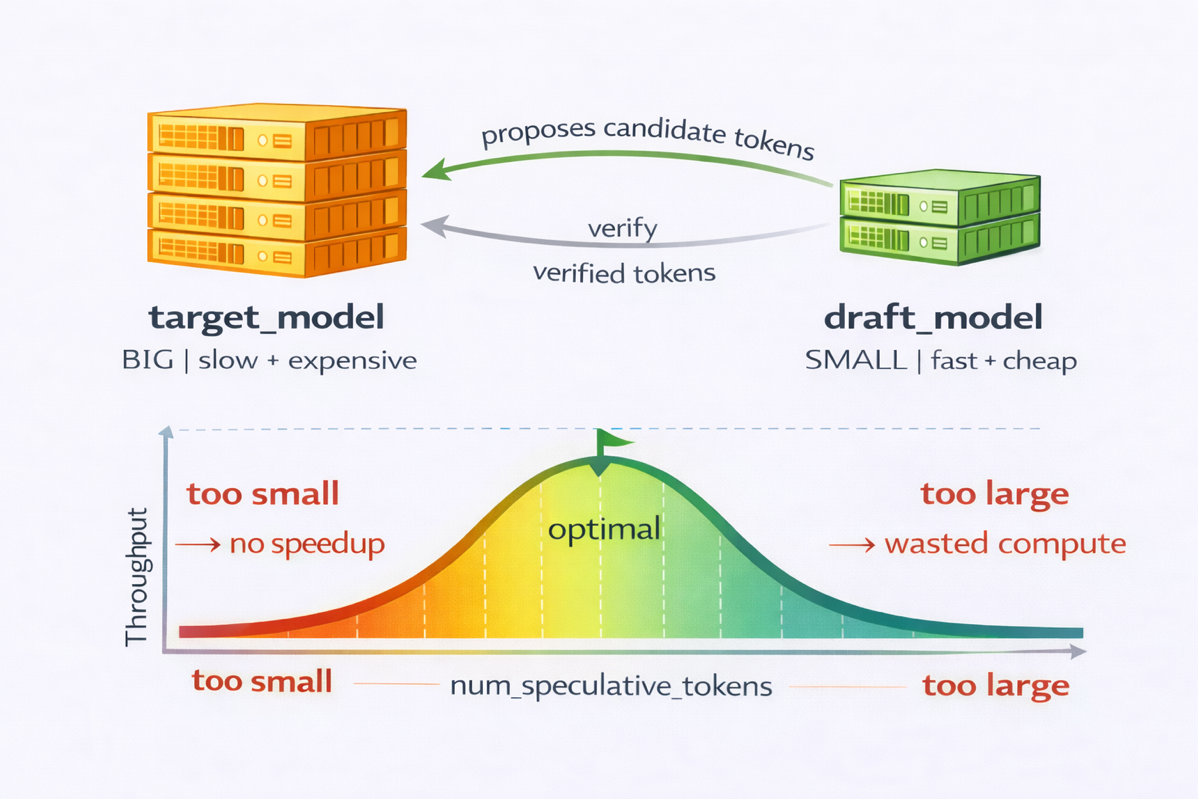
Accelerating decode-heavy LLM inference with speculative decoding on ...
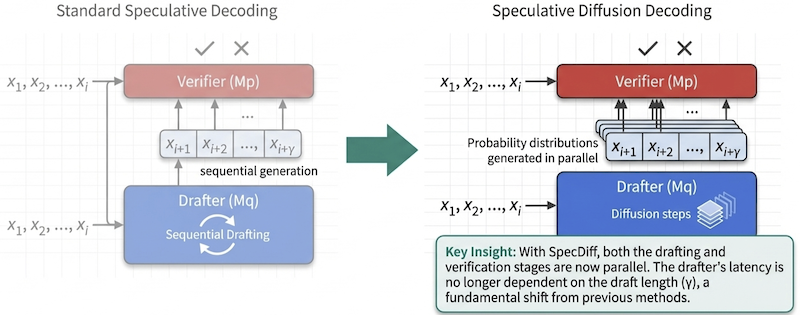
Massively Speeding up LLM inference with Speculative Diffusion Decoding ...

Towards Efficient LLM Inference via Collective and Adaptive Speculative ...

[论文评述] Efficient LLM Inference using Dynamic Input Pruning and Cache ...

Boosting LLM Inference Speed Using Speculative Decoding | Towards Data ...
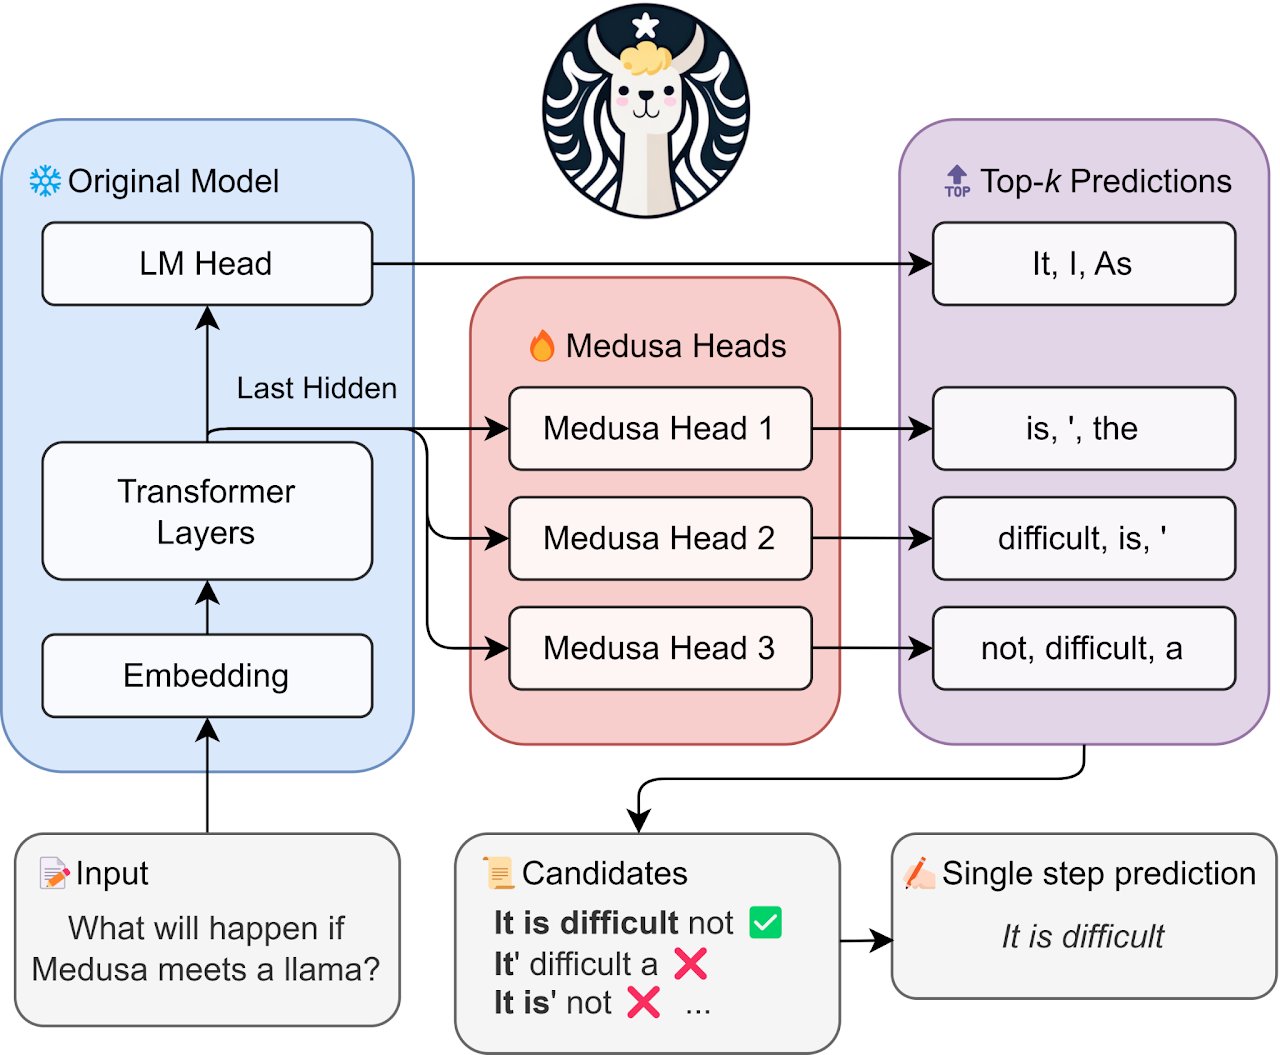
Accelerate LLM Inference with Speculative Decoding | Charles Xu
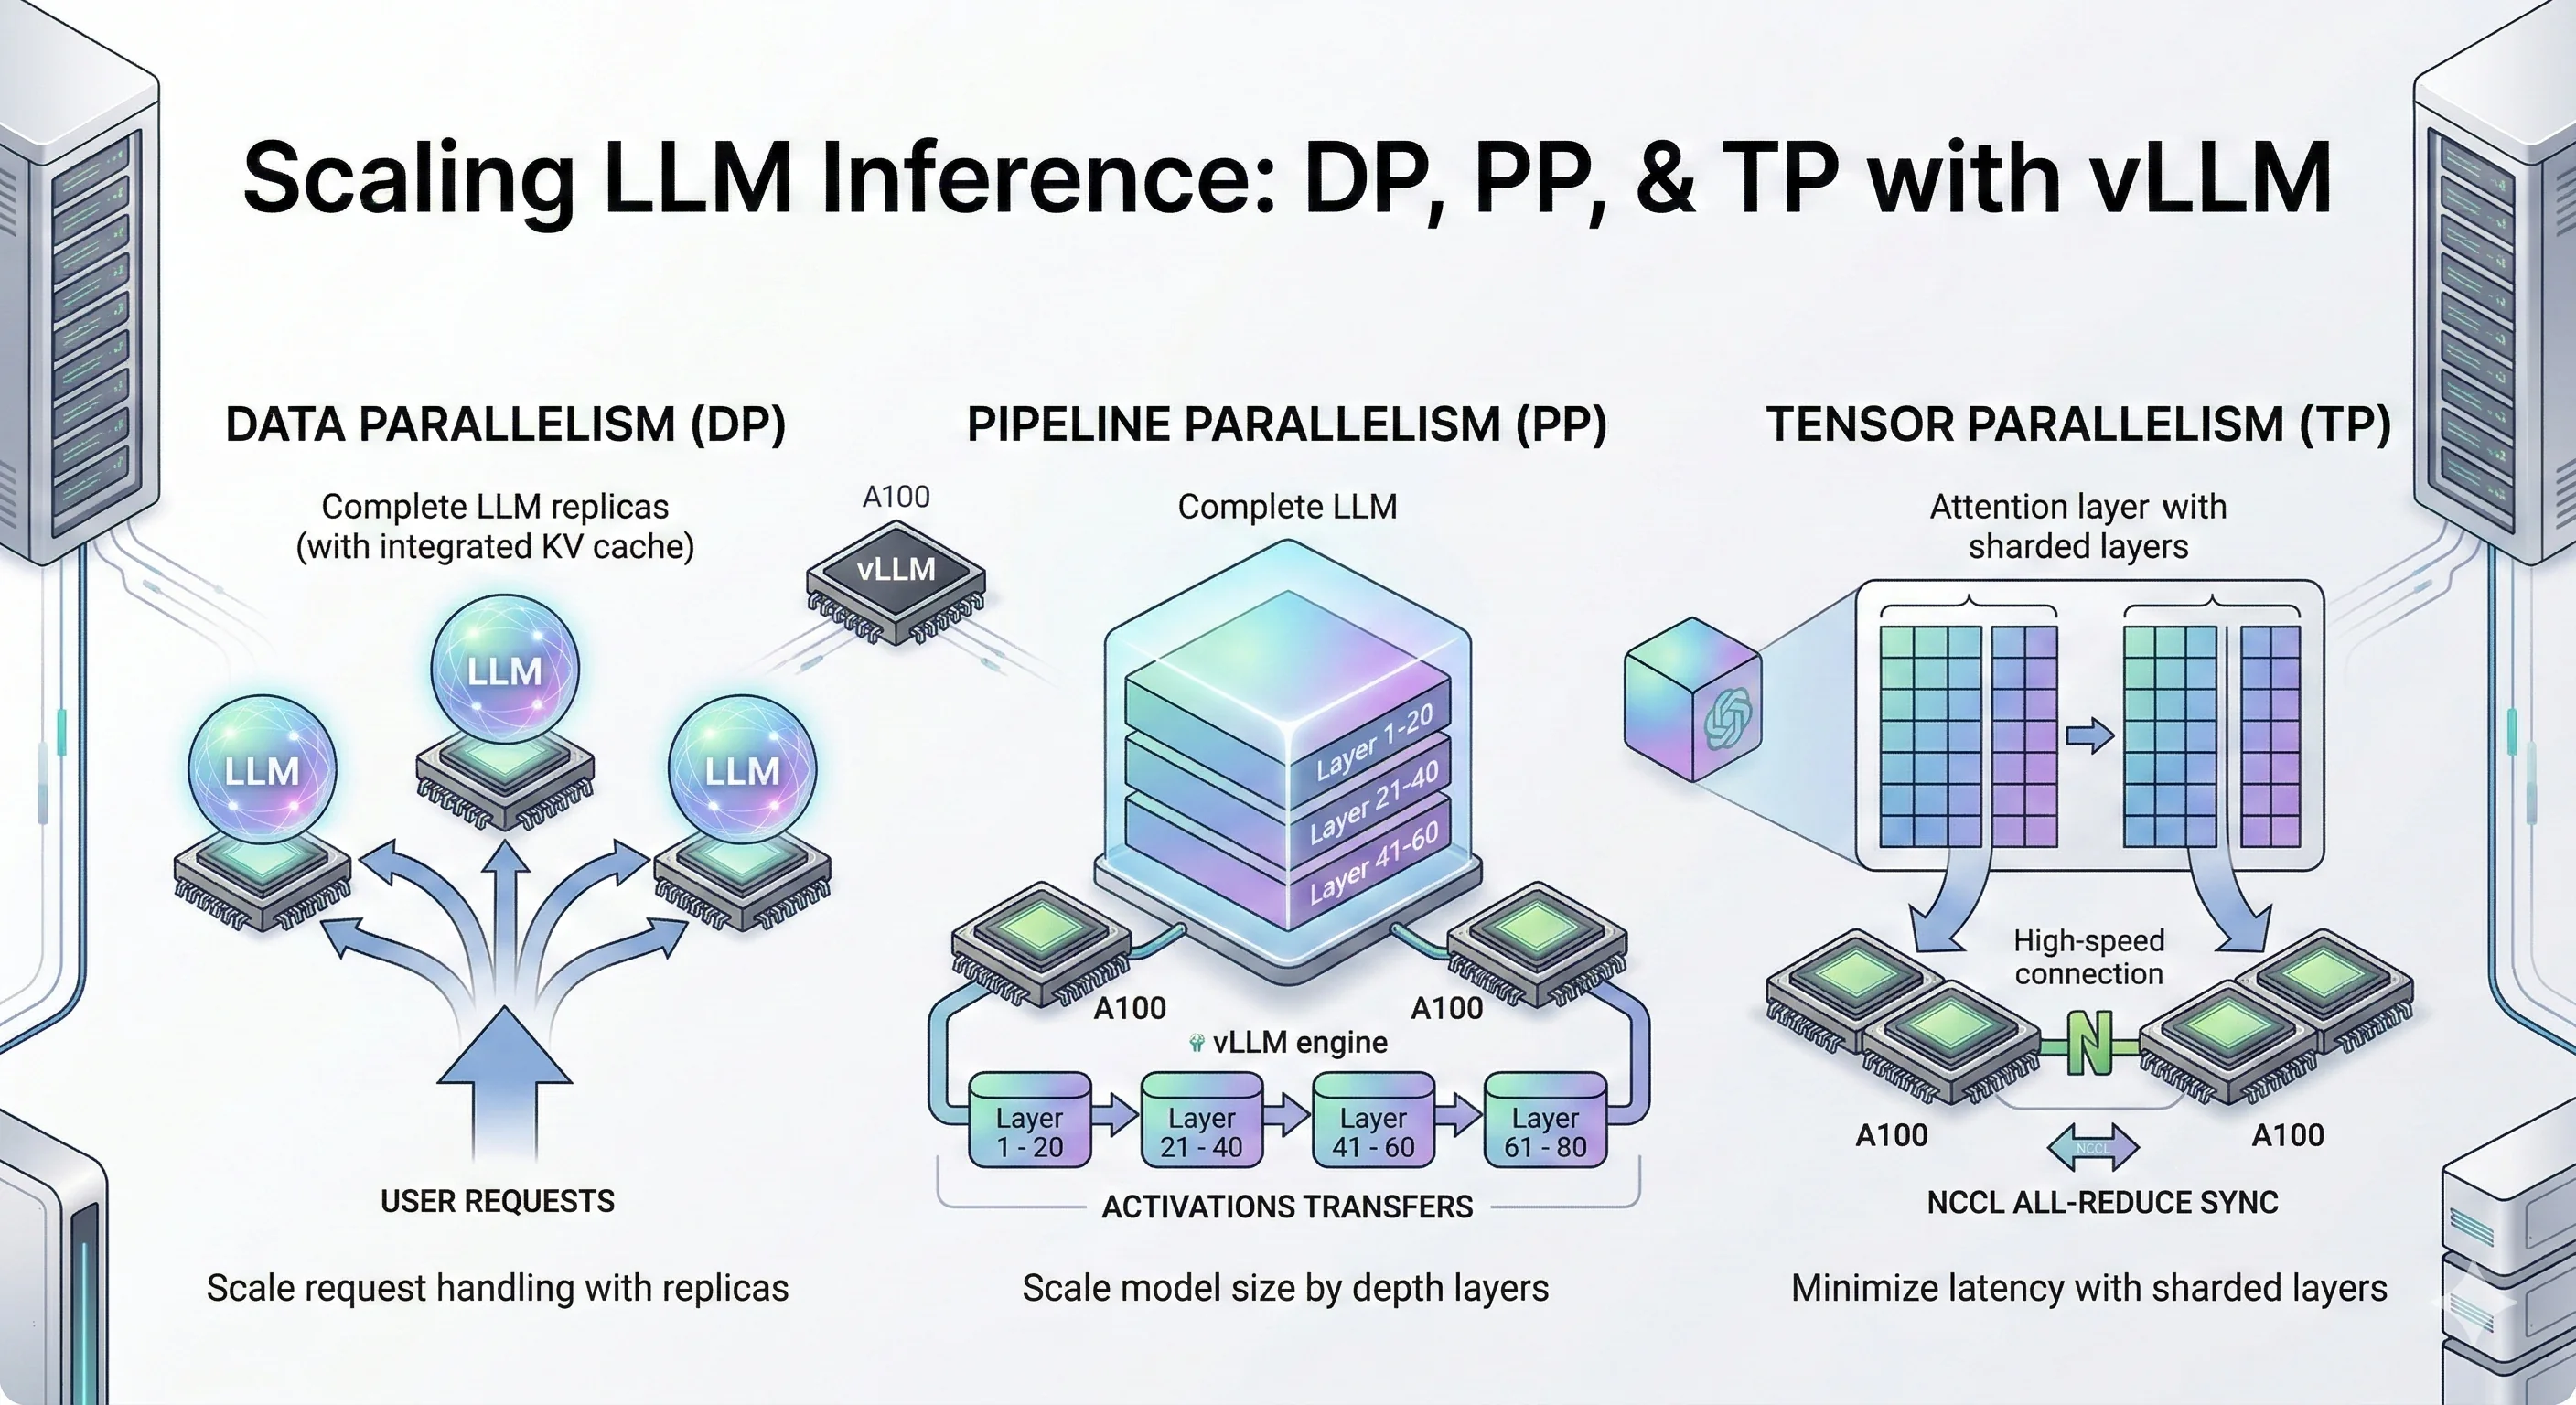
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
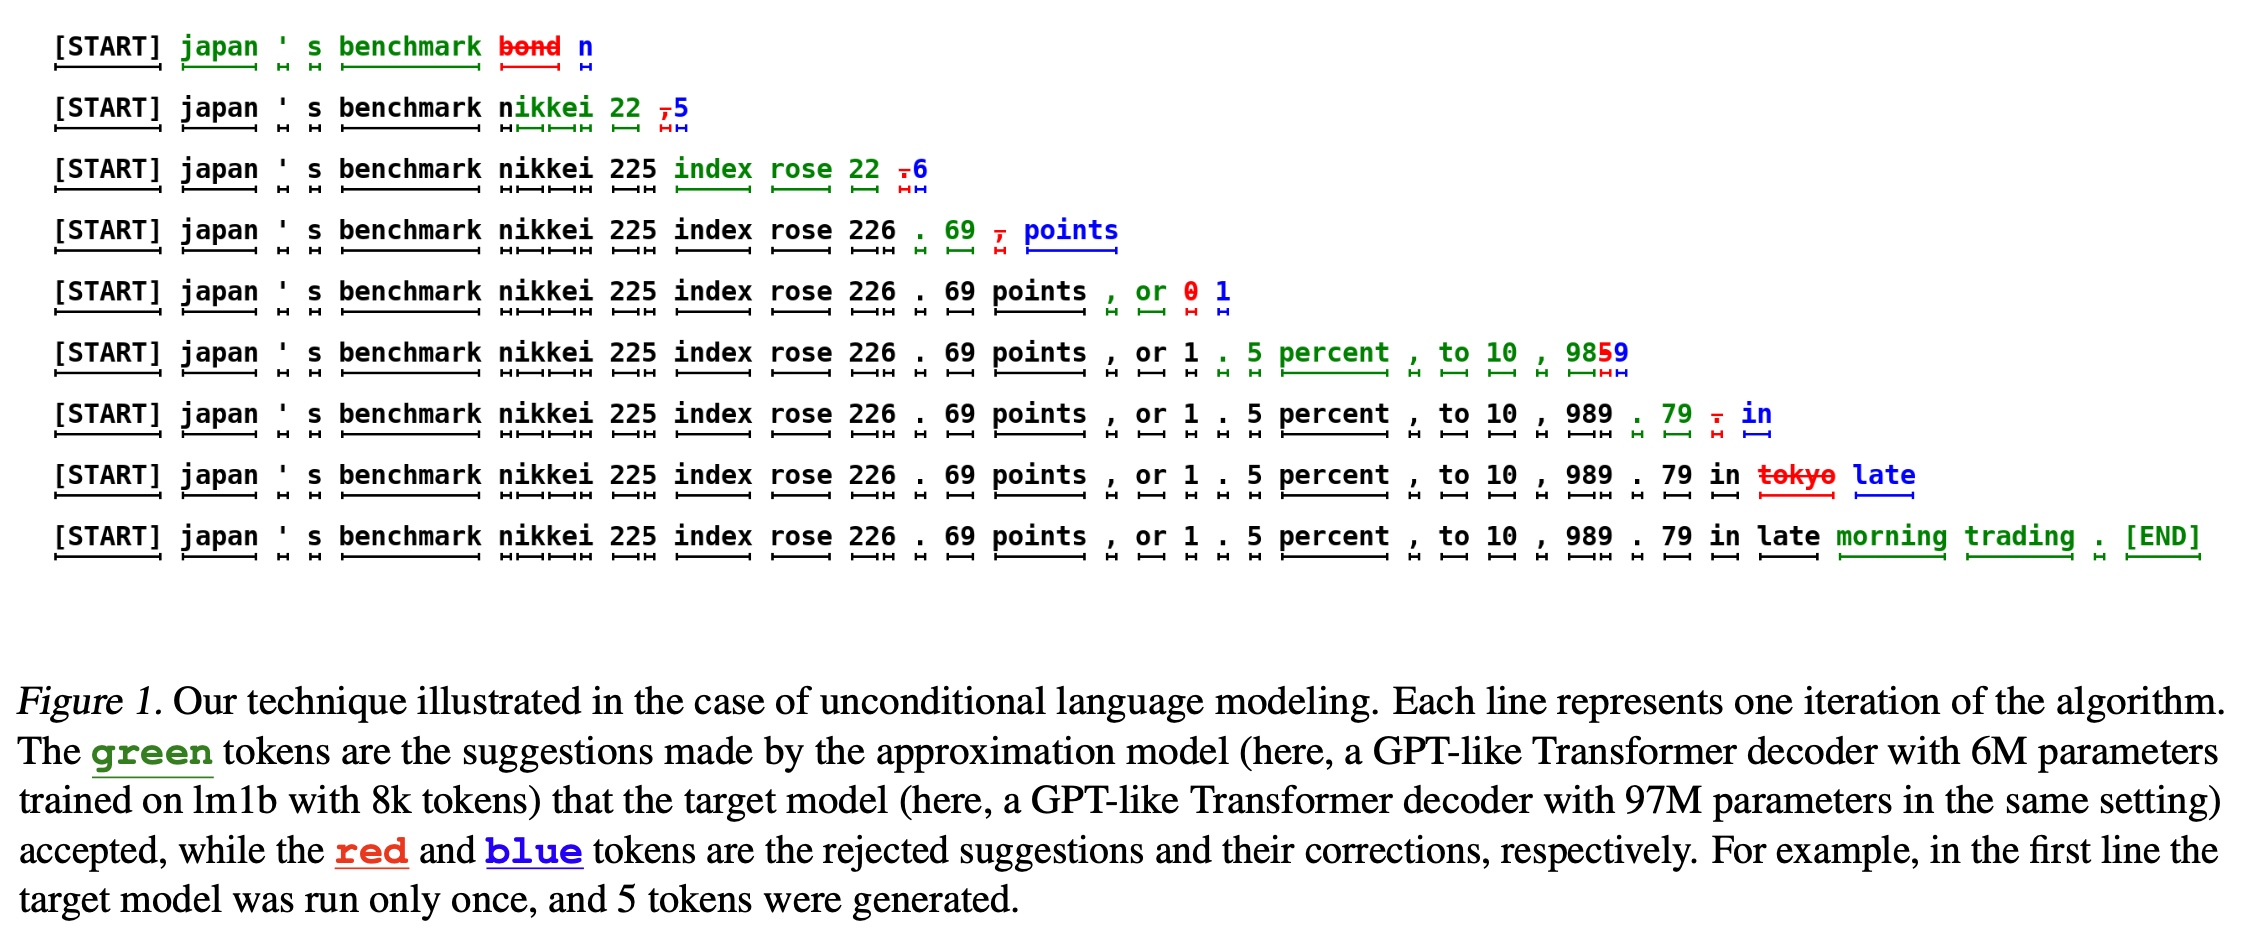
Accelerate LLM Inference with Speculative Decoding | Charles Xu
Advertisement Space (336x280)
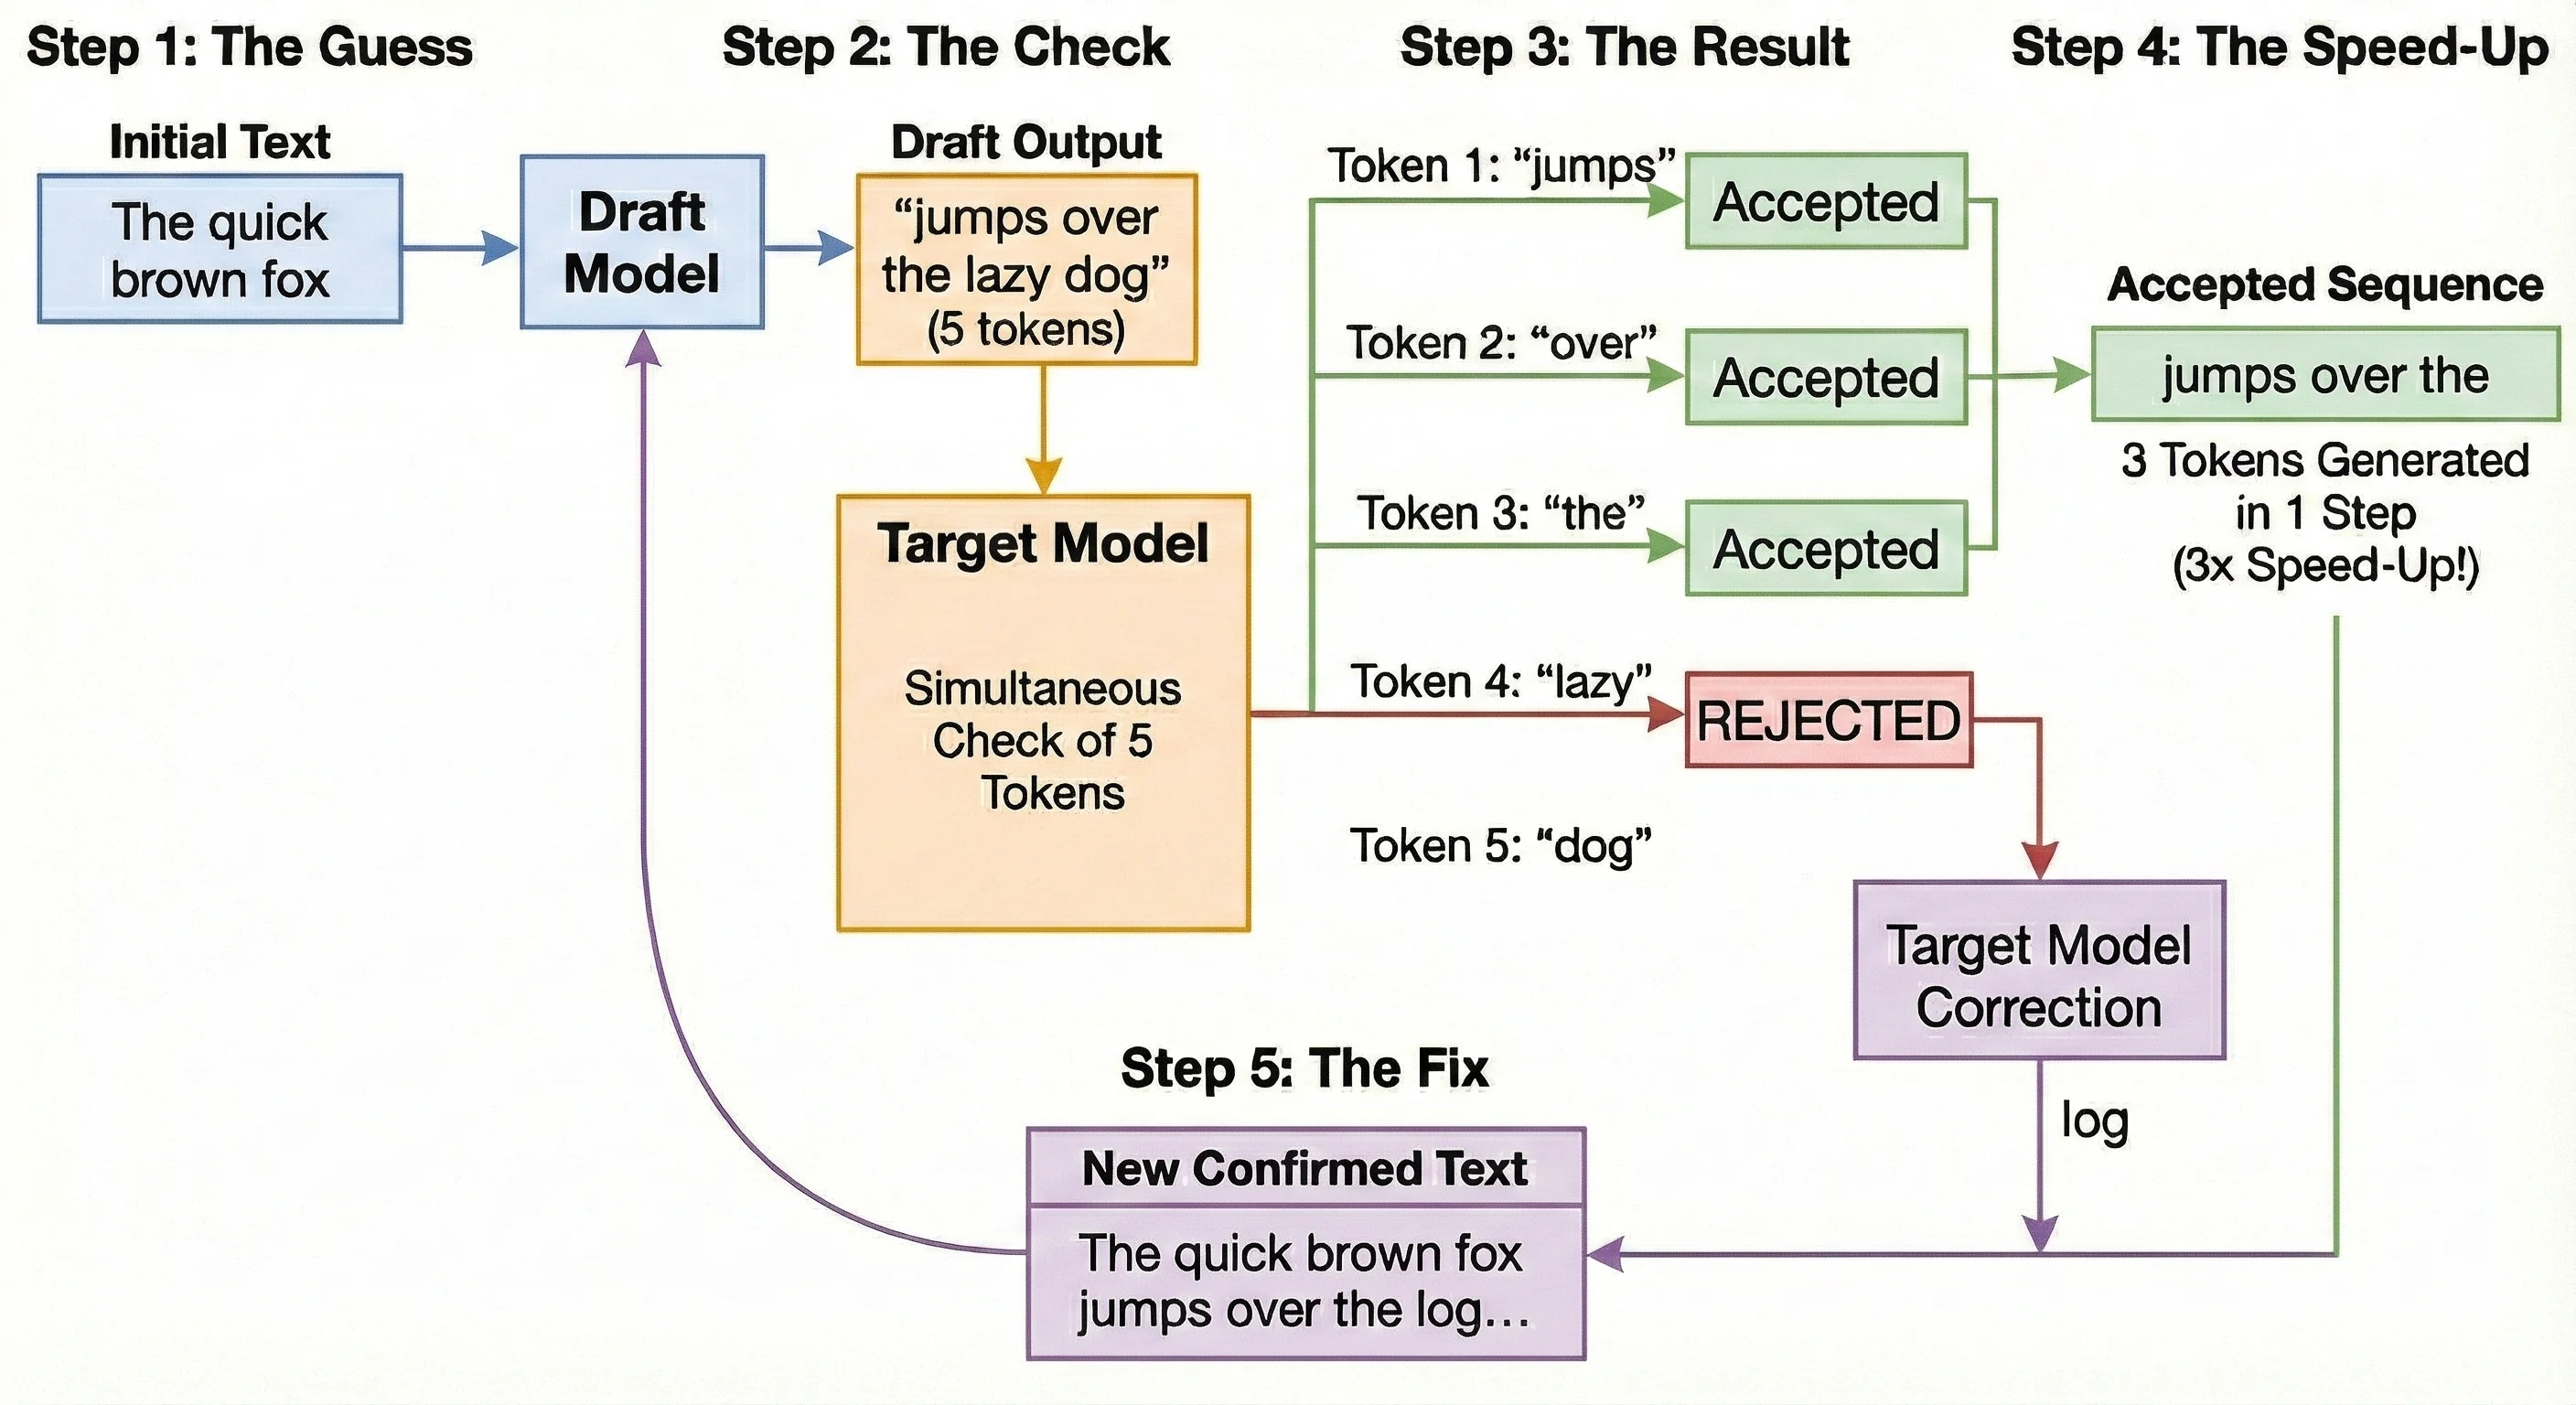
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
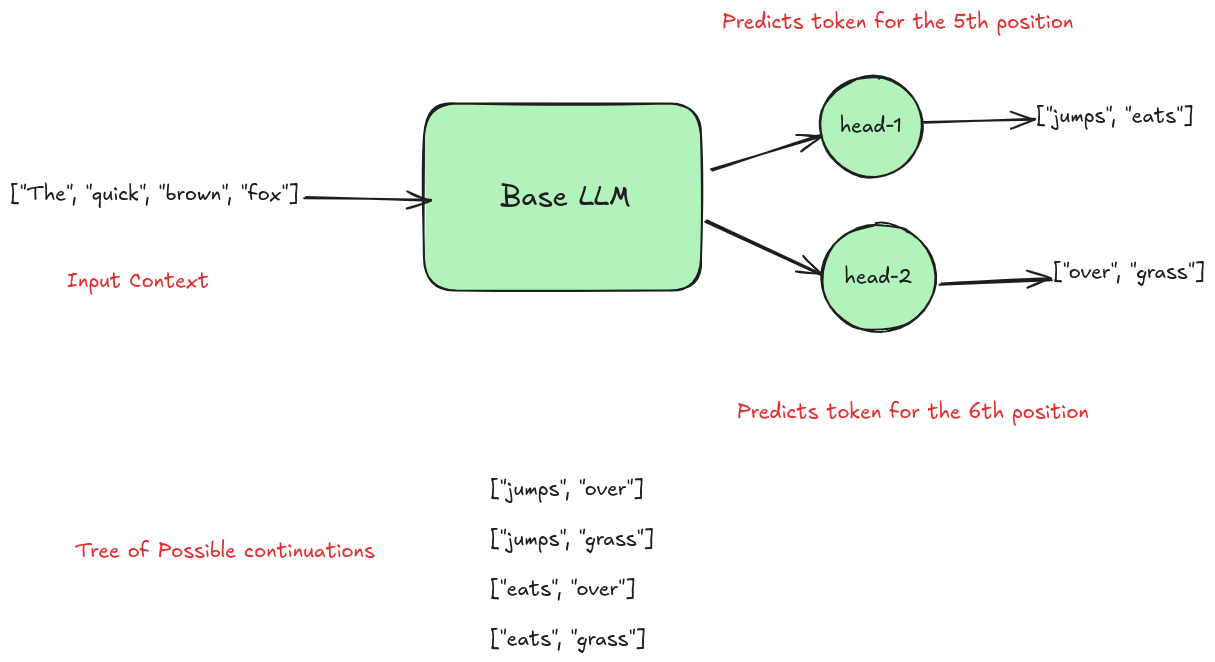
A Survey of Speculative Decoding Techniques in LLM Inference
Paper page - Accelerating LLM Inference with Staged Speculative Decoding

(PDF) Accelerating LLM Inference with Staged Speculative Decoding
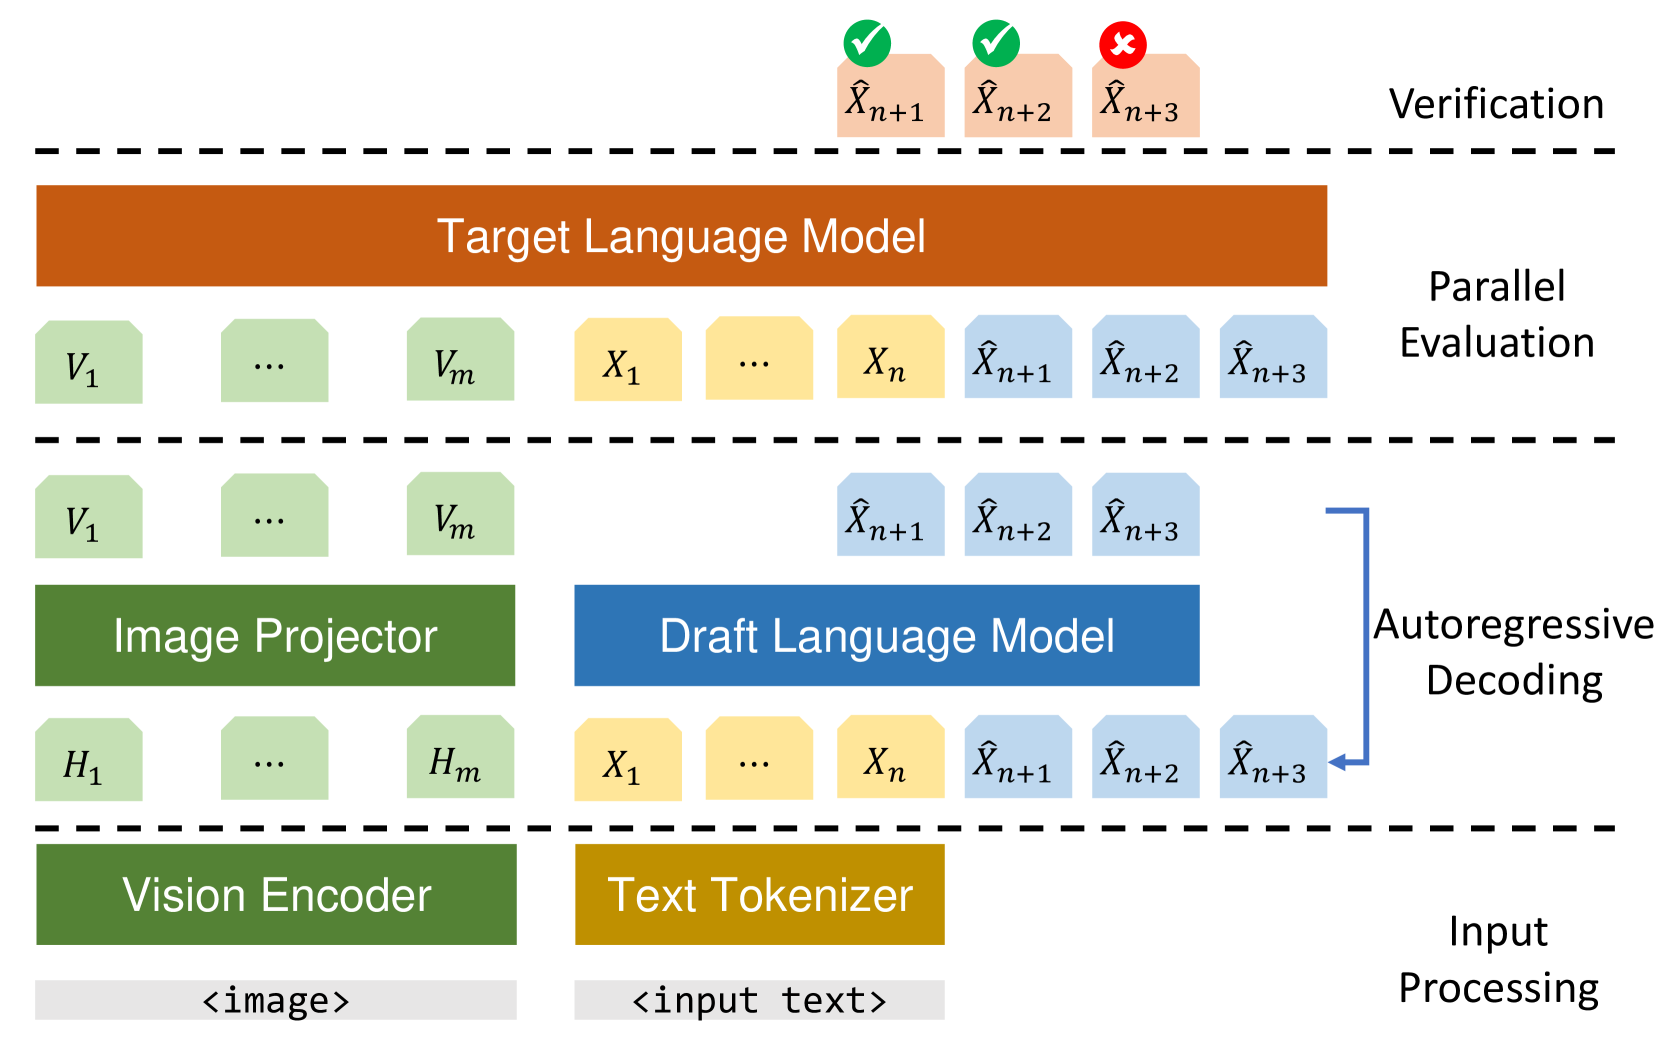
SpecExec: Massively Parallel Speculative Decoding for Interactive LLM ...
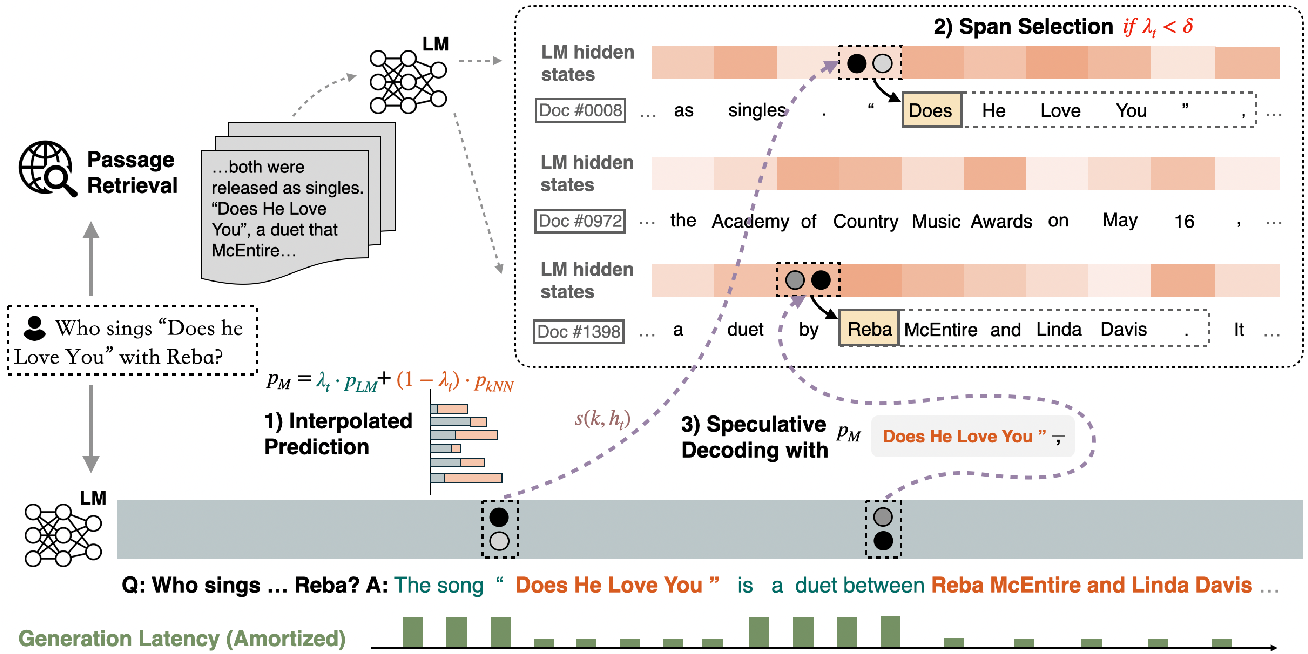
Figure 1 from Nearest Neighbor Speculative Decoding for LLM Generation ...

[논문 리뷰] SDSAT: Accelerating LLM Inference through Speculative Decoding ...
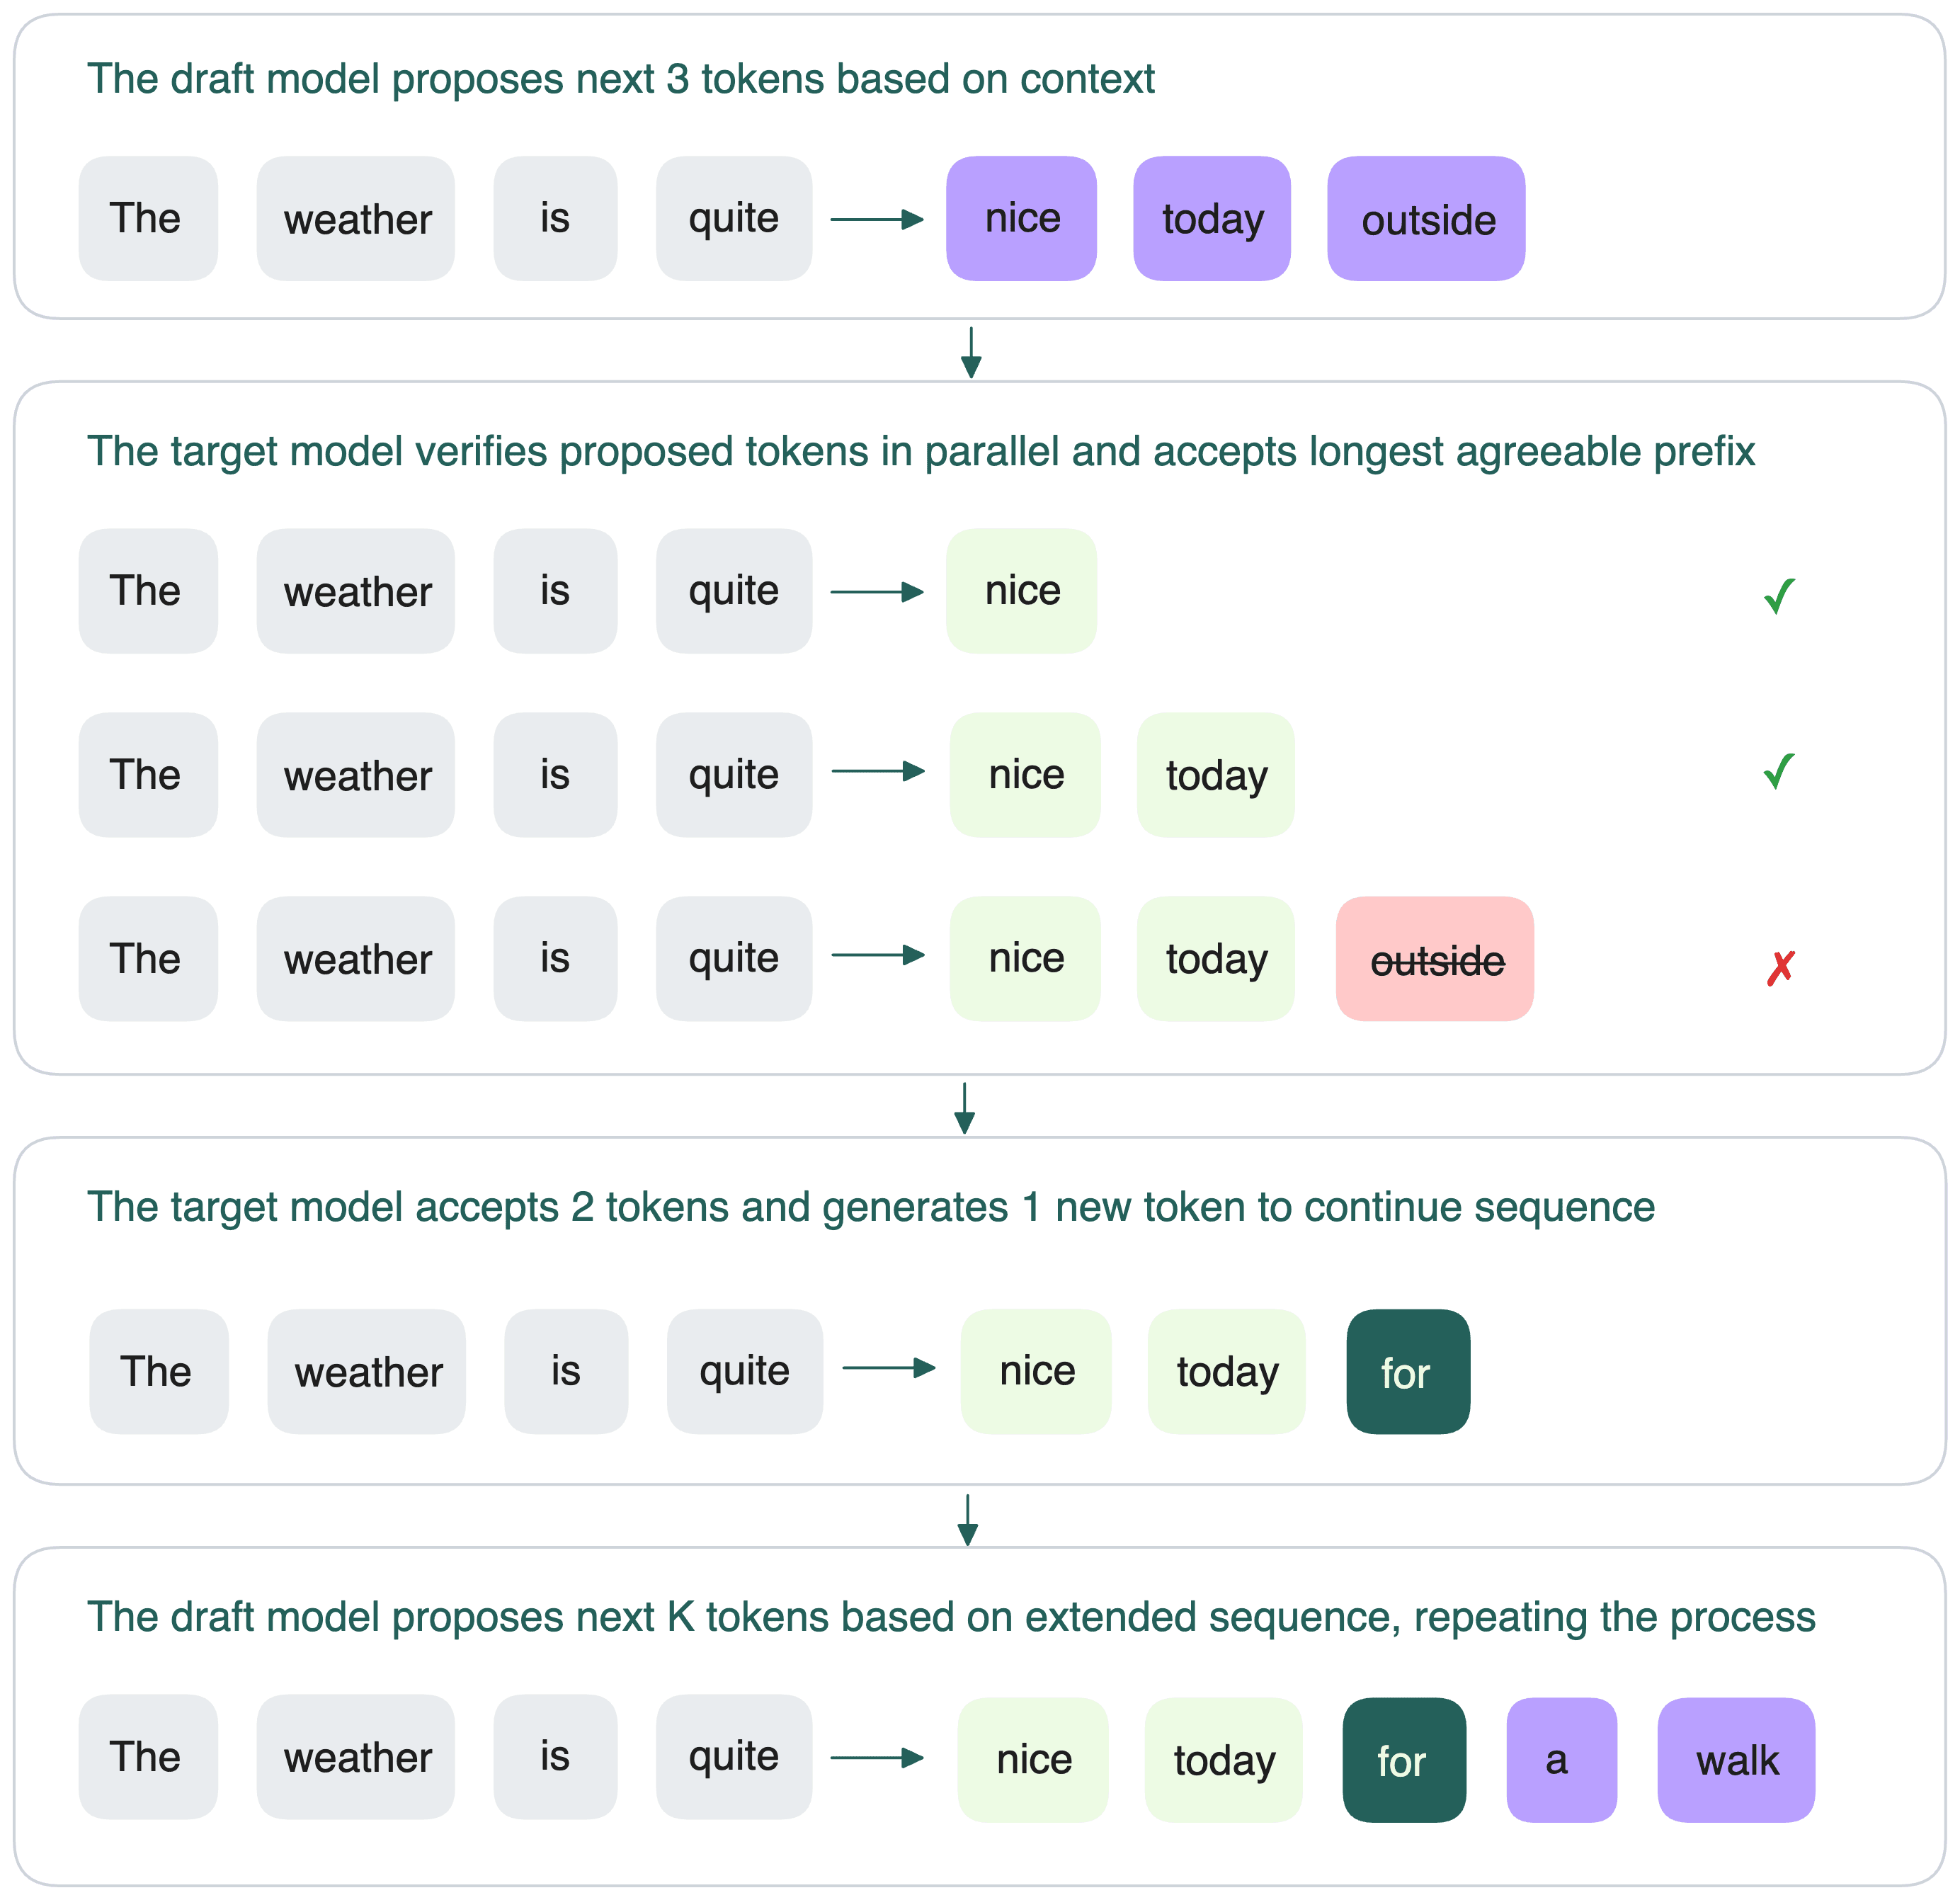
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...

AdaSD: Adaptive Speculative Decoding for Efficient Language Model ...

[论文评述] Dovetail: A CPU/GPU Heterogeneous Speculative Decoding for LLM ...
Advertisement Space (336x280)
Accelerating decode-heavy LLM inference with speculative decoding on ...

A Pipelined Collaborative Speculative Decoding Framework for Efficient ...

Paper page - DART: Diffusion-Inspired Speculative Decoding for Fast LLM ...
Speculative Decoding Production Guide: 2-5x Faster LLM Inference on GPU ...
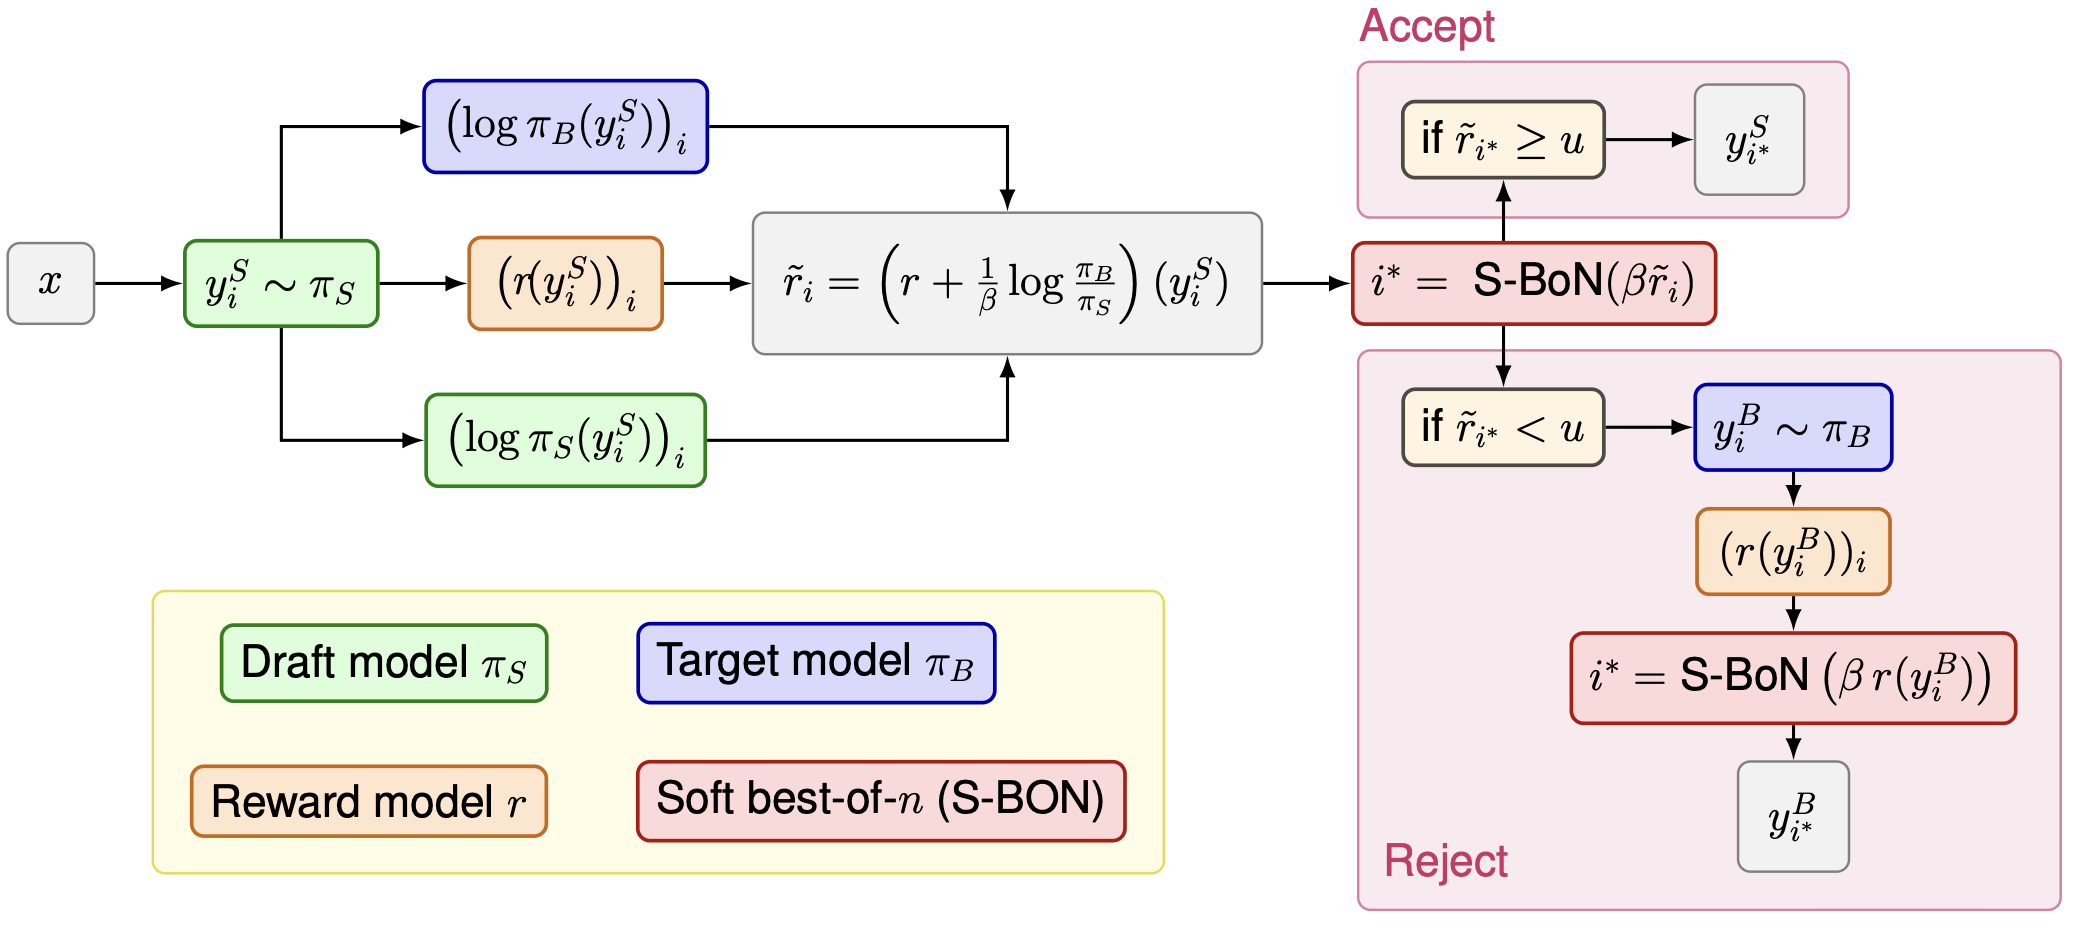
Guided Speculative Inference for Efficient Test-Time Alignment of LLMs ...

Dynamic Depth Decoding: Faster Speculative Decoding for LLMs | AI ...