
Dyspec Faster Speculative Decoding With Dynamic Token Tree Structure

DySpec: Faster speculative decoding with dynamic token tree structure ...

[논문 리뷰] DySpec: Faster Speculative Decoding with Dynamic Token Tree ...

OPT-Tree - Speculative Decoding With Adaptive Draft Tree Structure | PDF

SpecBlock: Block-Iterative Speculative Decoding with Dynamic Tree ...
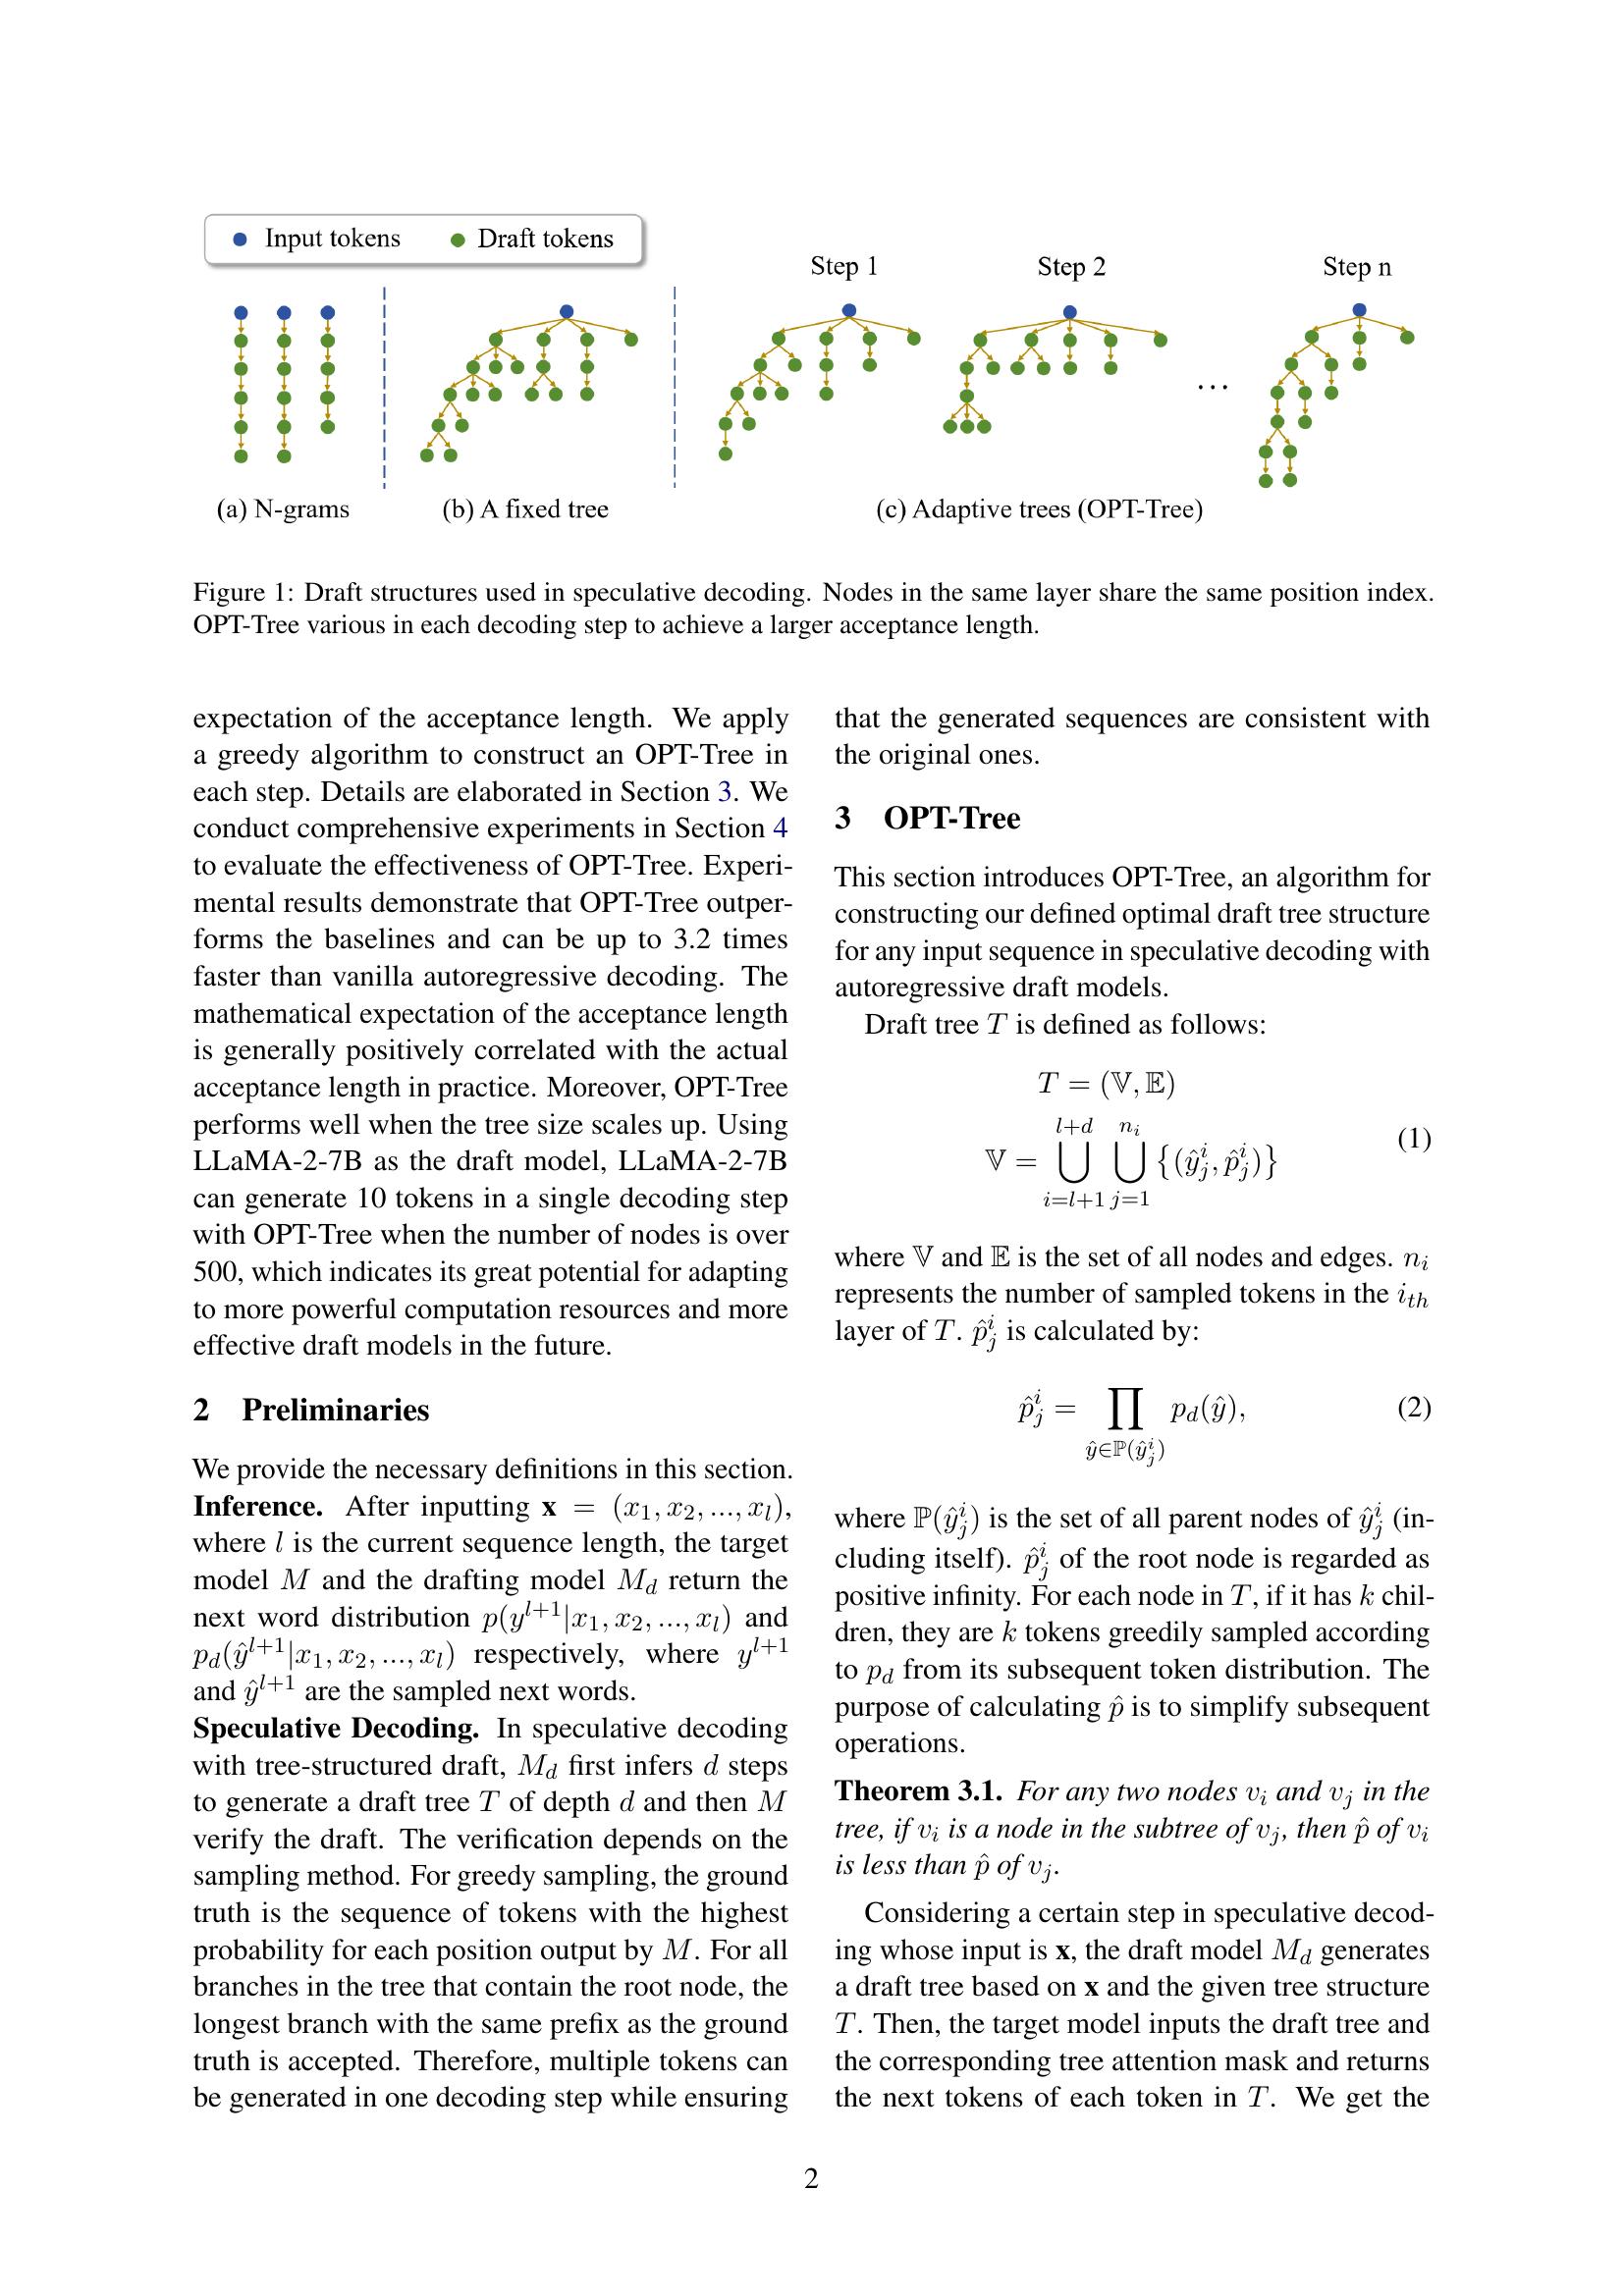
OPT-Tree: Speculative Decoding with Adaptive Draft Tree Structure - 智源社区论文
OPT-Tree: Speculative Decoding with Adaptive Draft Tree Structure - ACL ...
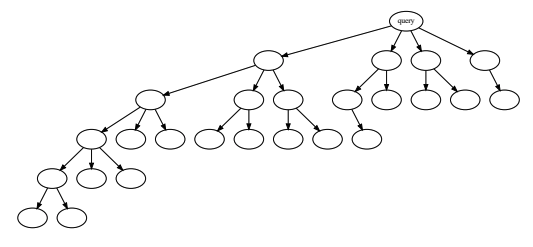
[2409.00142] Dynamic Depth Decoding: Faster Speculative Decoding for LLMs
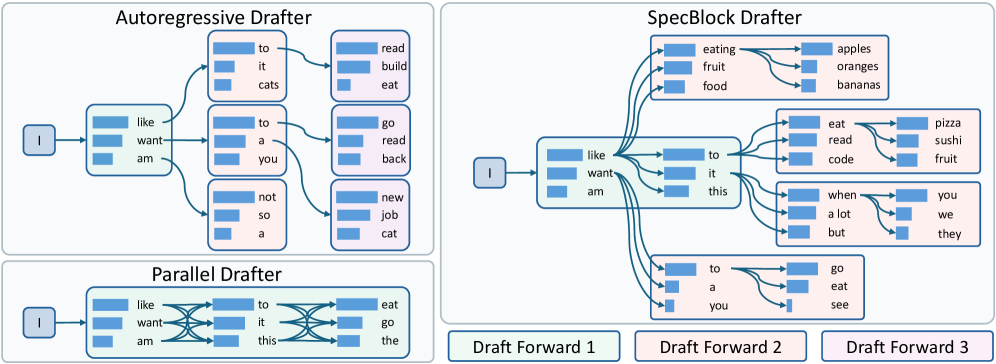
[논문리뷰] SpecBlock: Block-Iterative Speculative Decoding with Dynamic ...
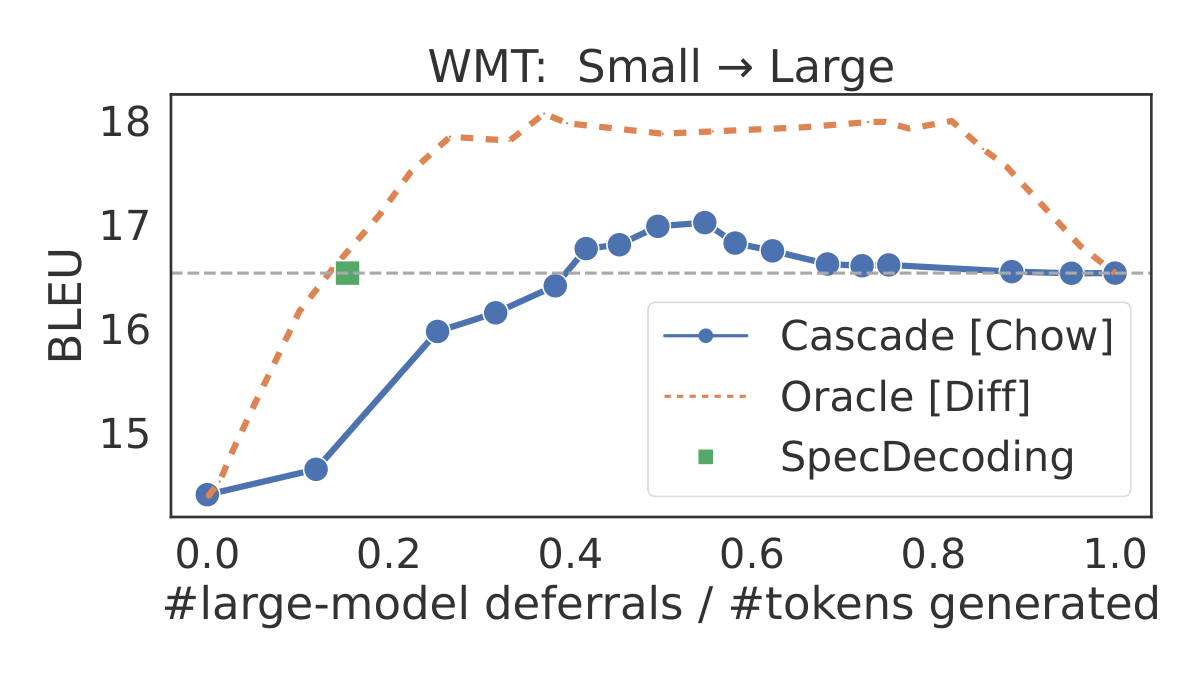
Faster Cascades via Speculative Decoding — Read with an AI tutor
Faster Speculative Decoding via Effective Draft Decoder with Pruned ...
Advertisement Space (300x250)
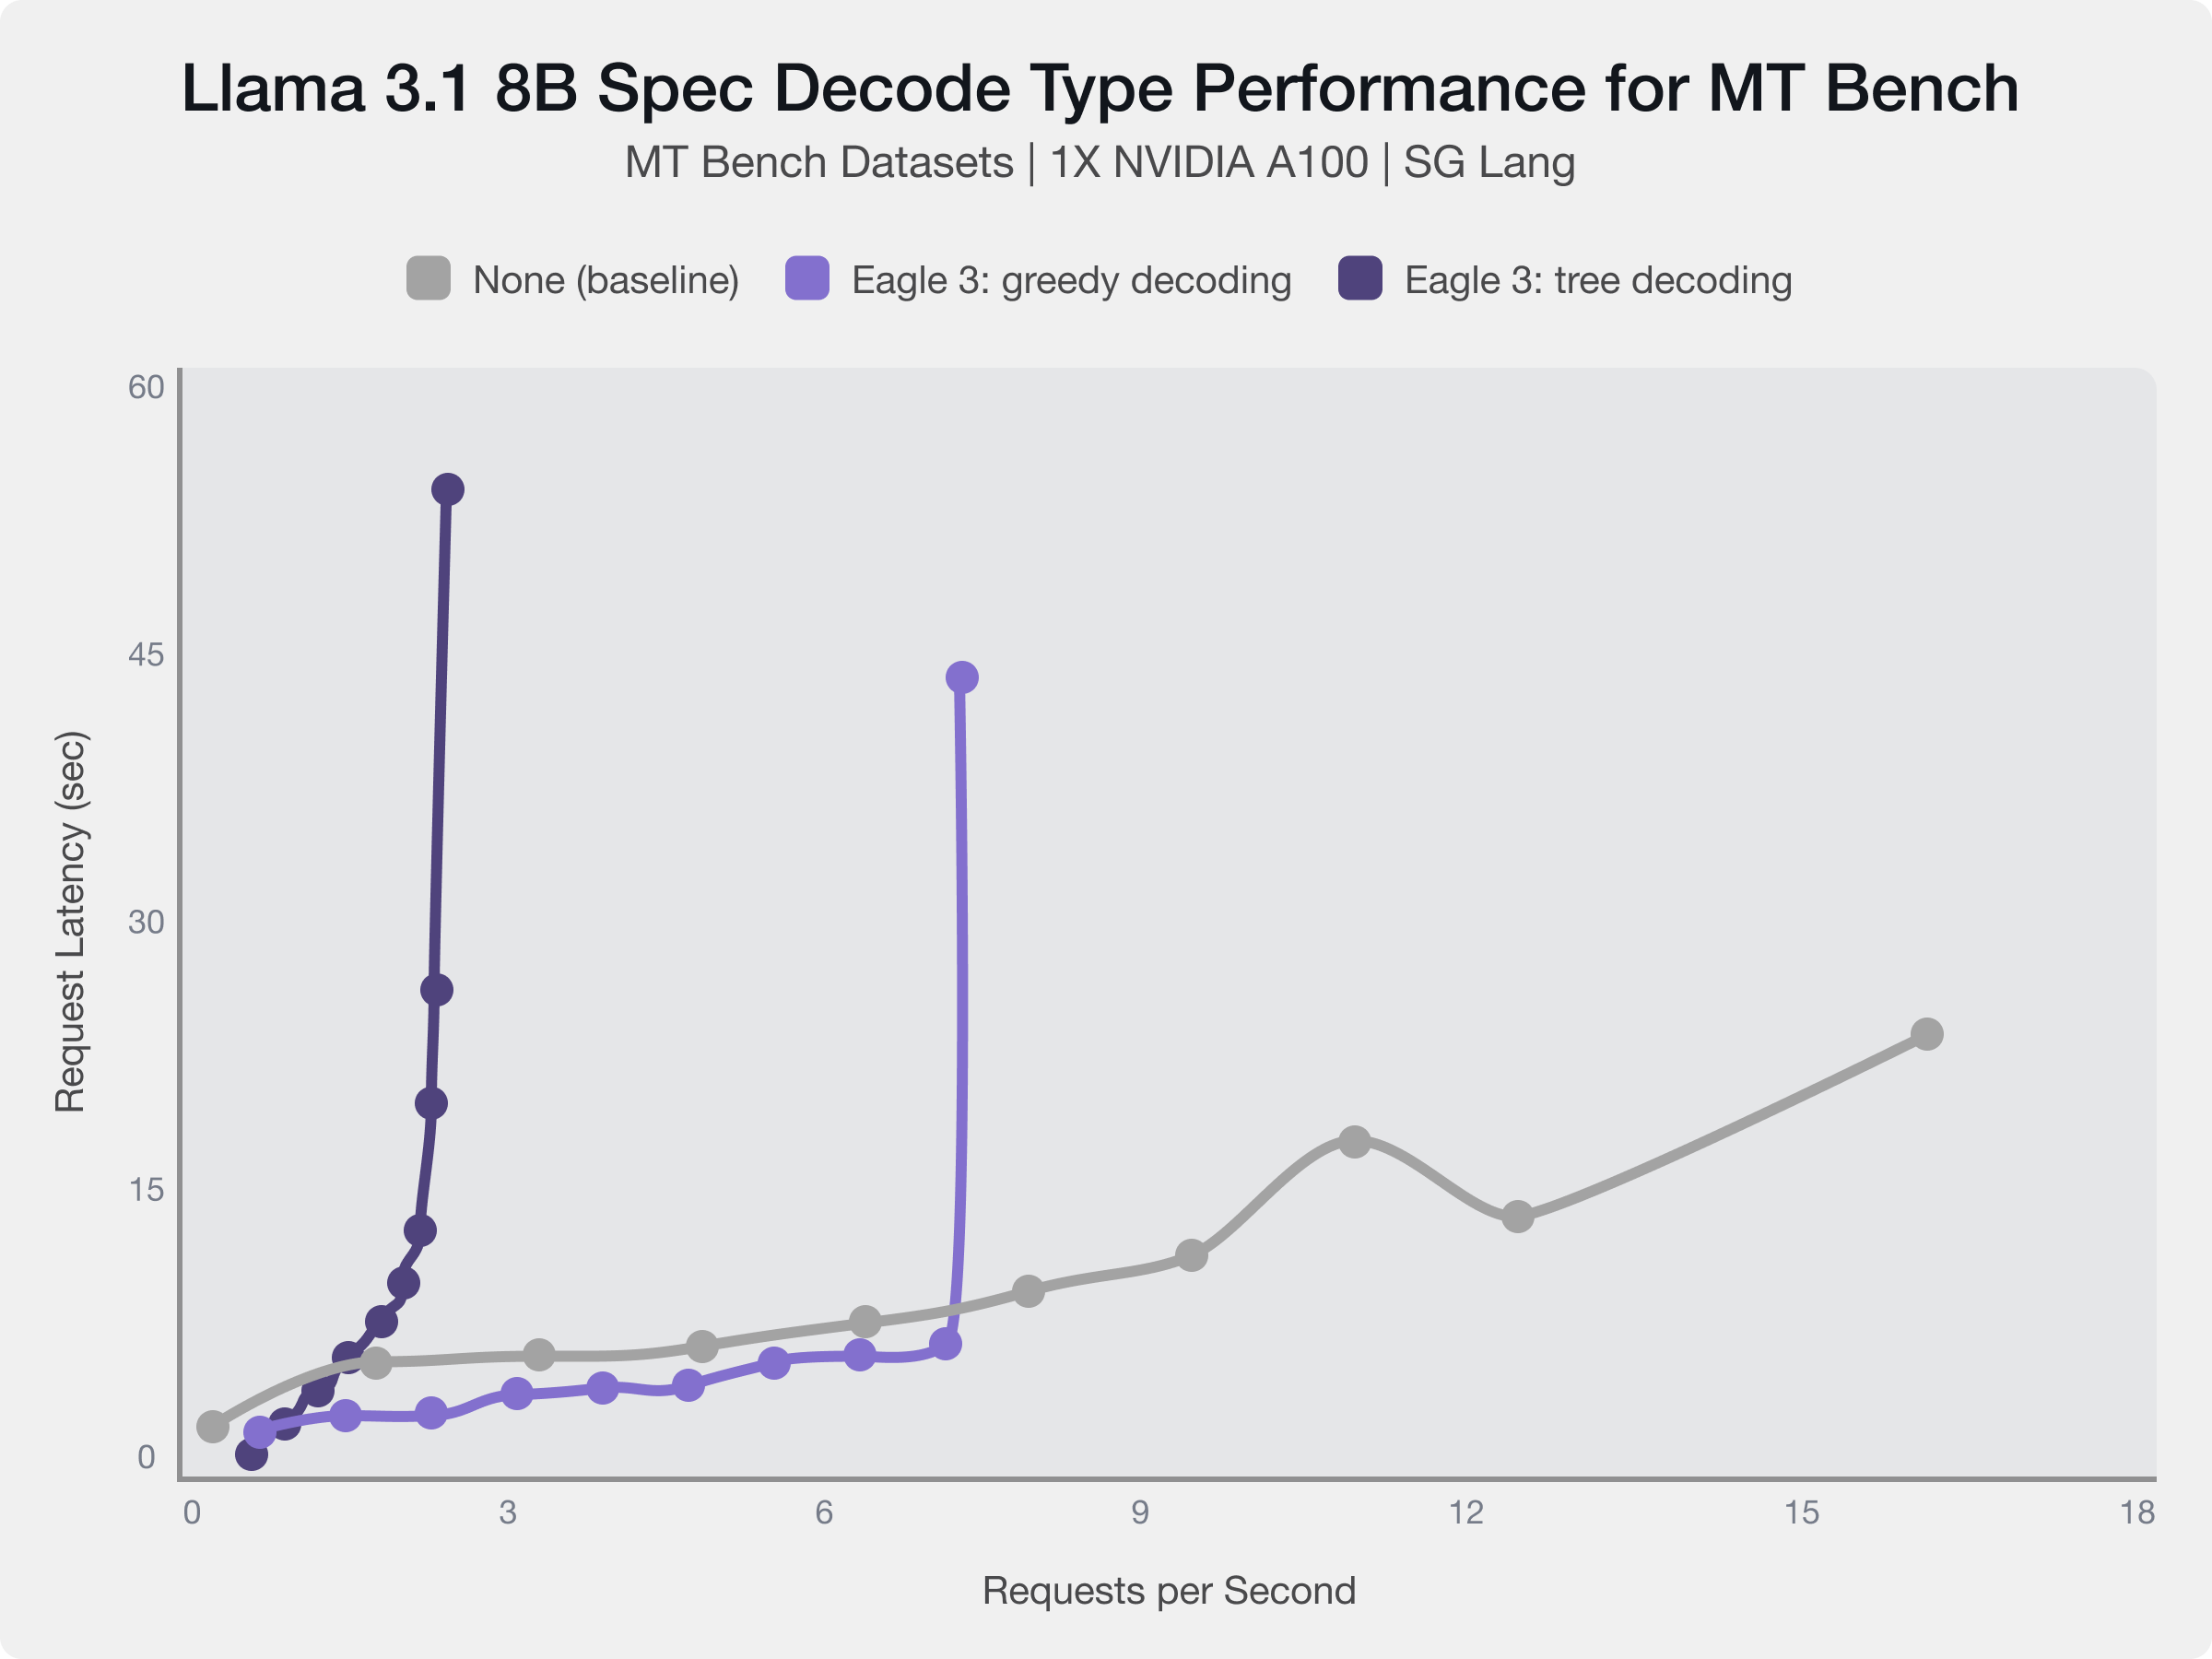
Faster inference with vLLM & speculative decoding | Red Hat Developer

(PDF) LANTERN++: Enhanced Relaxed Speculative Decoding with Static Tree ...
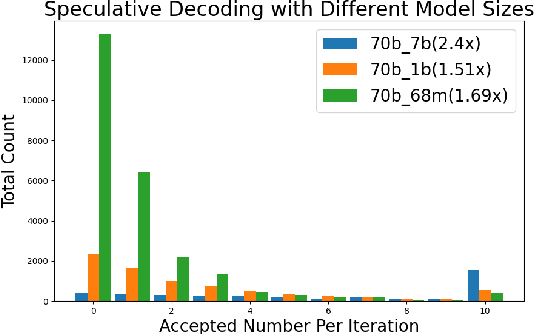
Figure 1 from Hierarchical Speculative Decoding with Dynamic Window ...
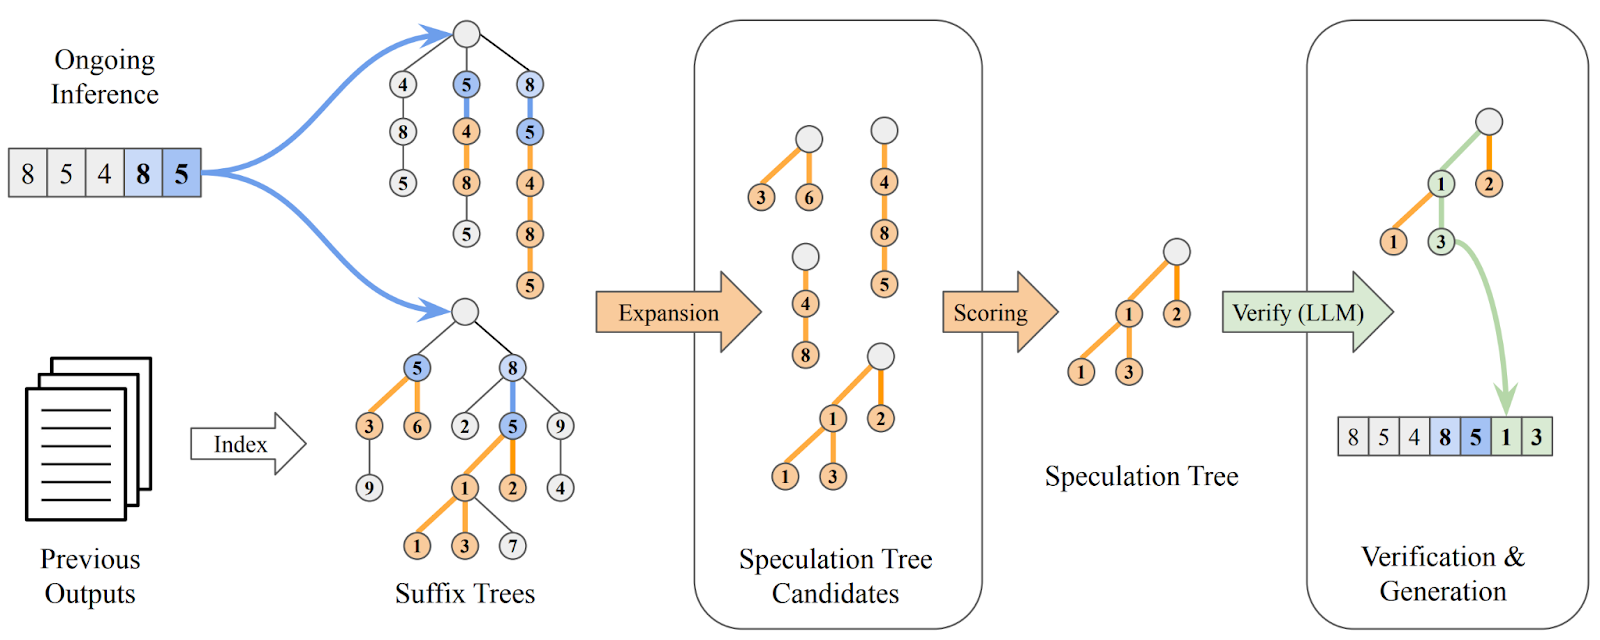
Fastest Speculative Decoding in vLLM with Arctic Inference and Arctic ...
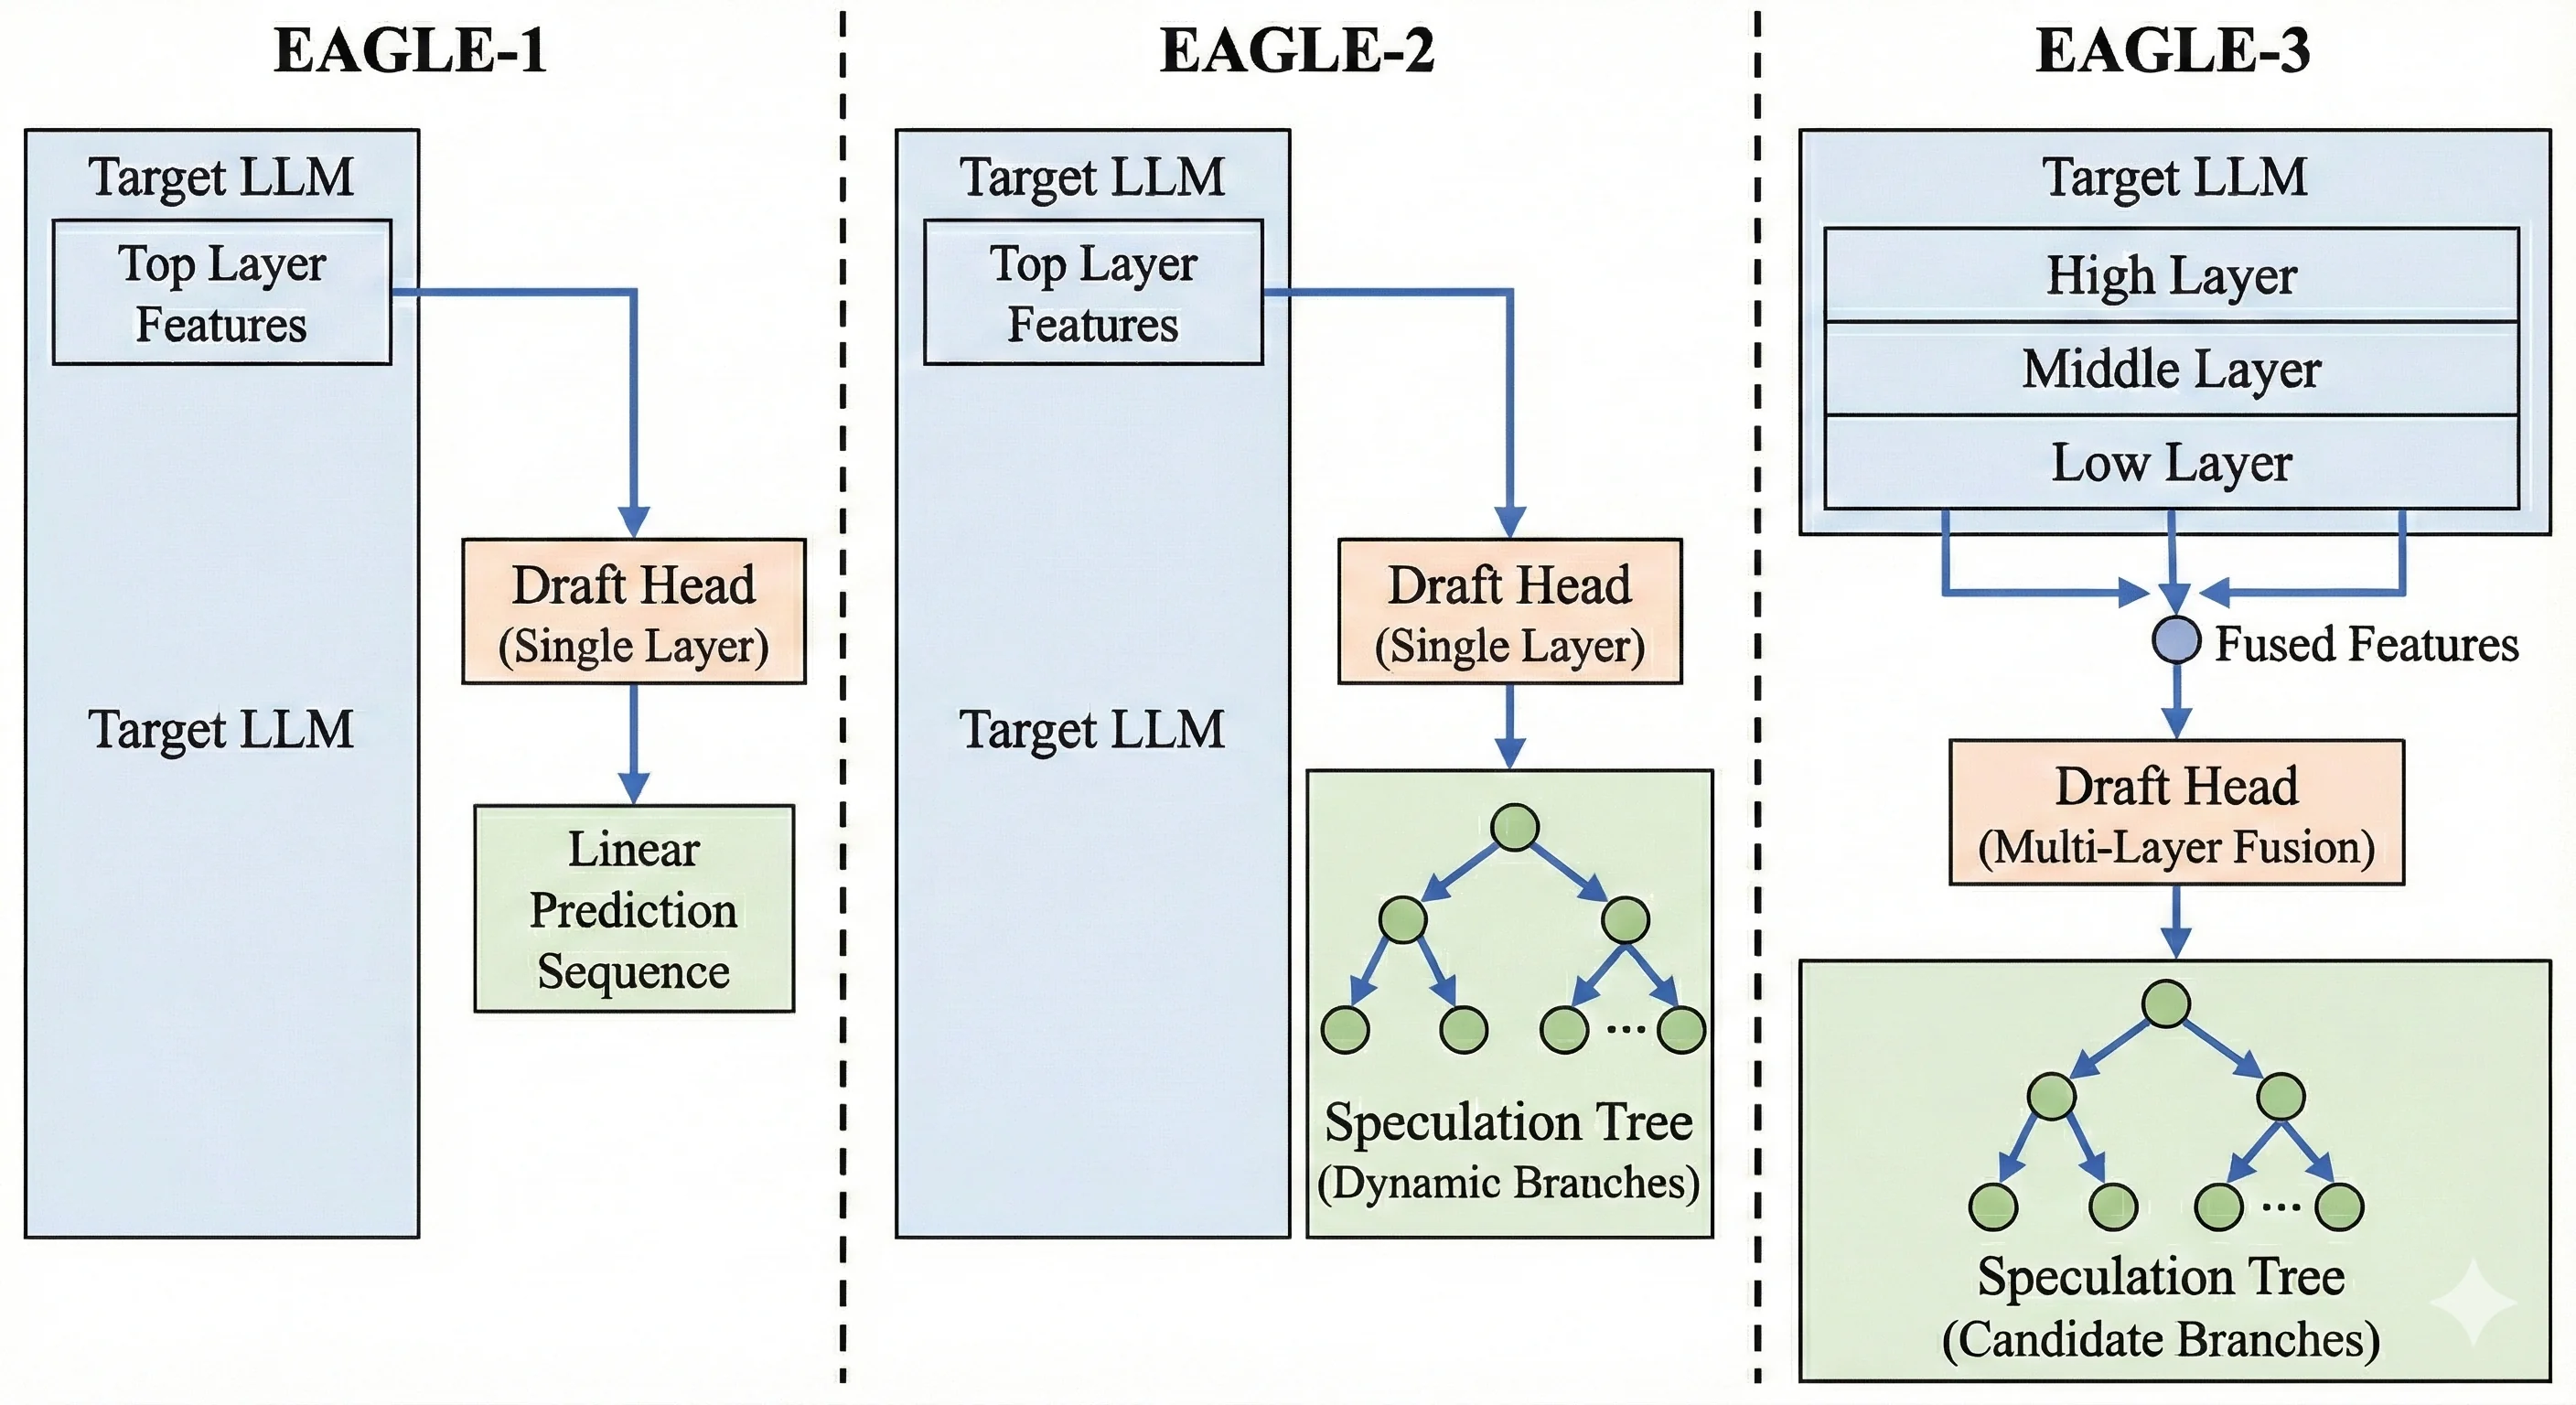
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...

DuoDecoding: Hardware-aware Heterogeneous Speculative Decoding with ...
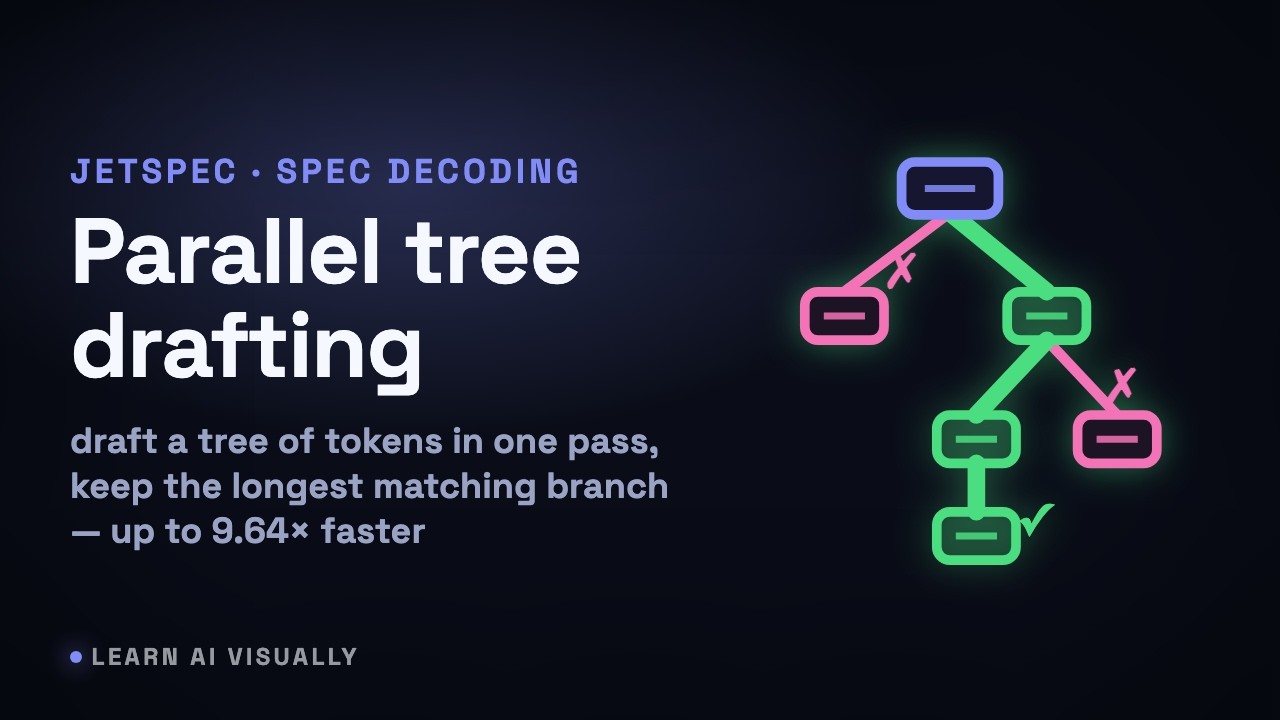
JetSpec speeds speculative decoding up to 9.64× — Parallel tree ...
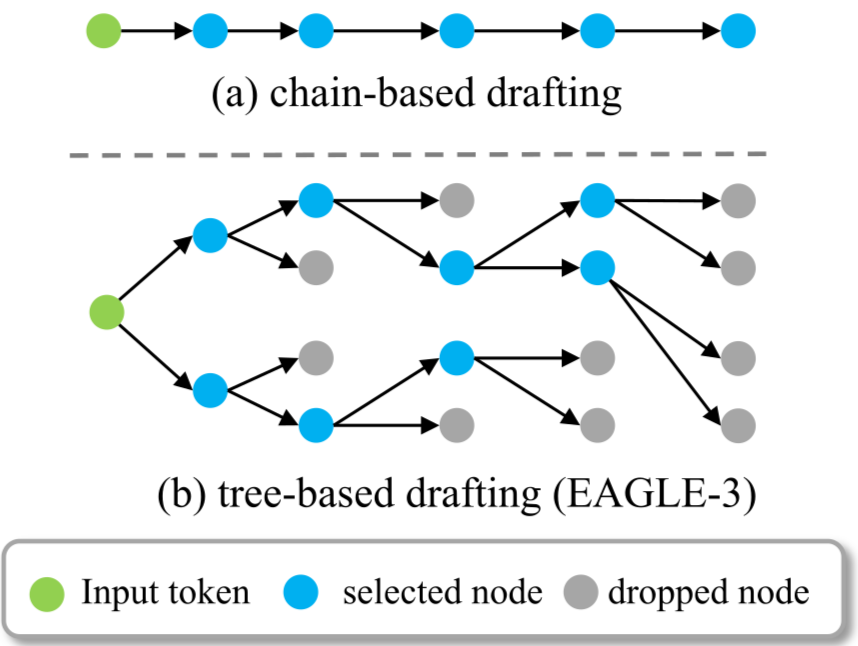
[논문 리뷰] TALON: Confidence-Aware Speculative Decoding with Adaptive ...

Dynamic Delayed Tree Expansion For Improved Multi-Path Speculative ...

TreeFlash: Parallel AR-Approximation for Faster Speculative Decoding ...
Advertisement Space (336x280)
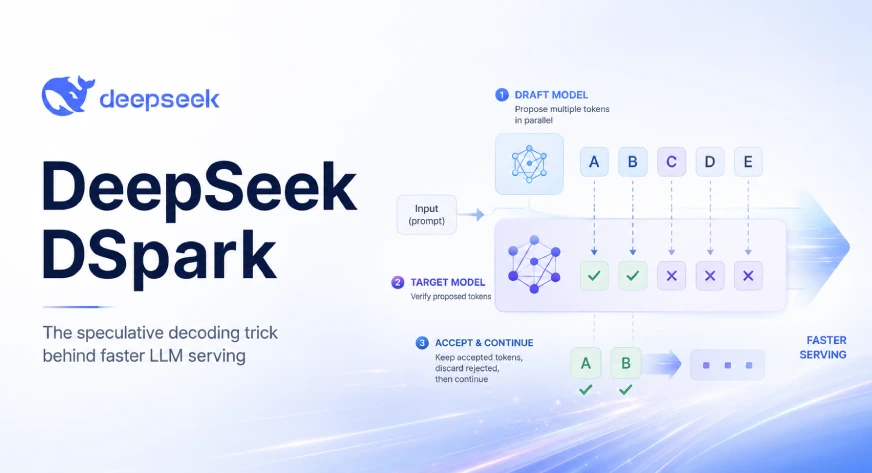
DeepSeek DSpark: Speculative Decoding for 400% Faster LLMs
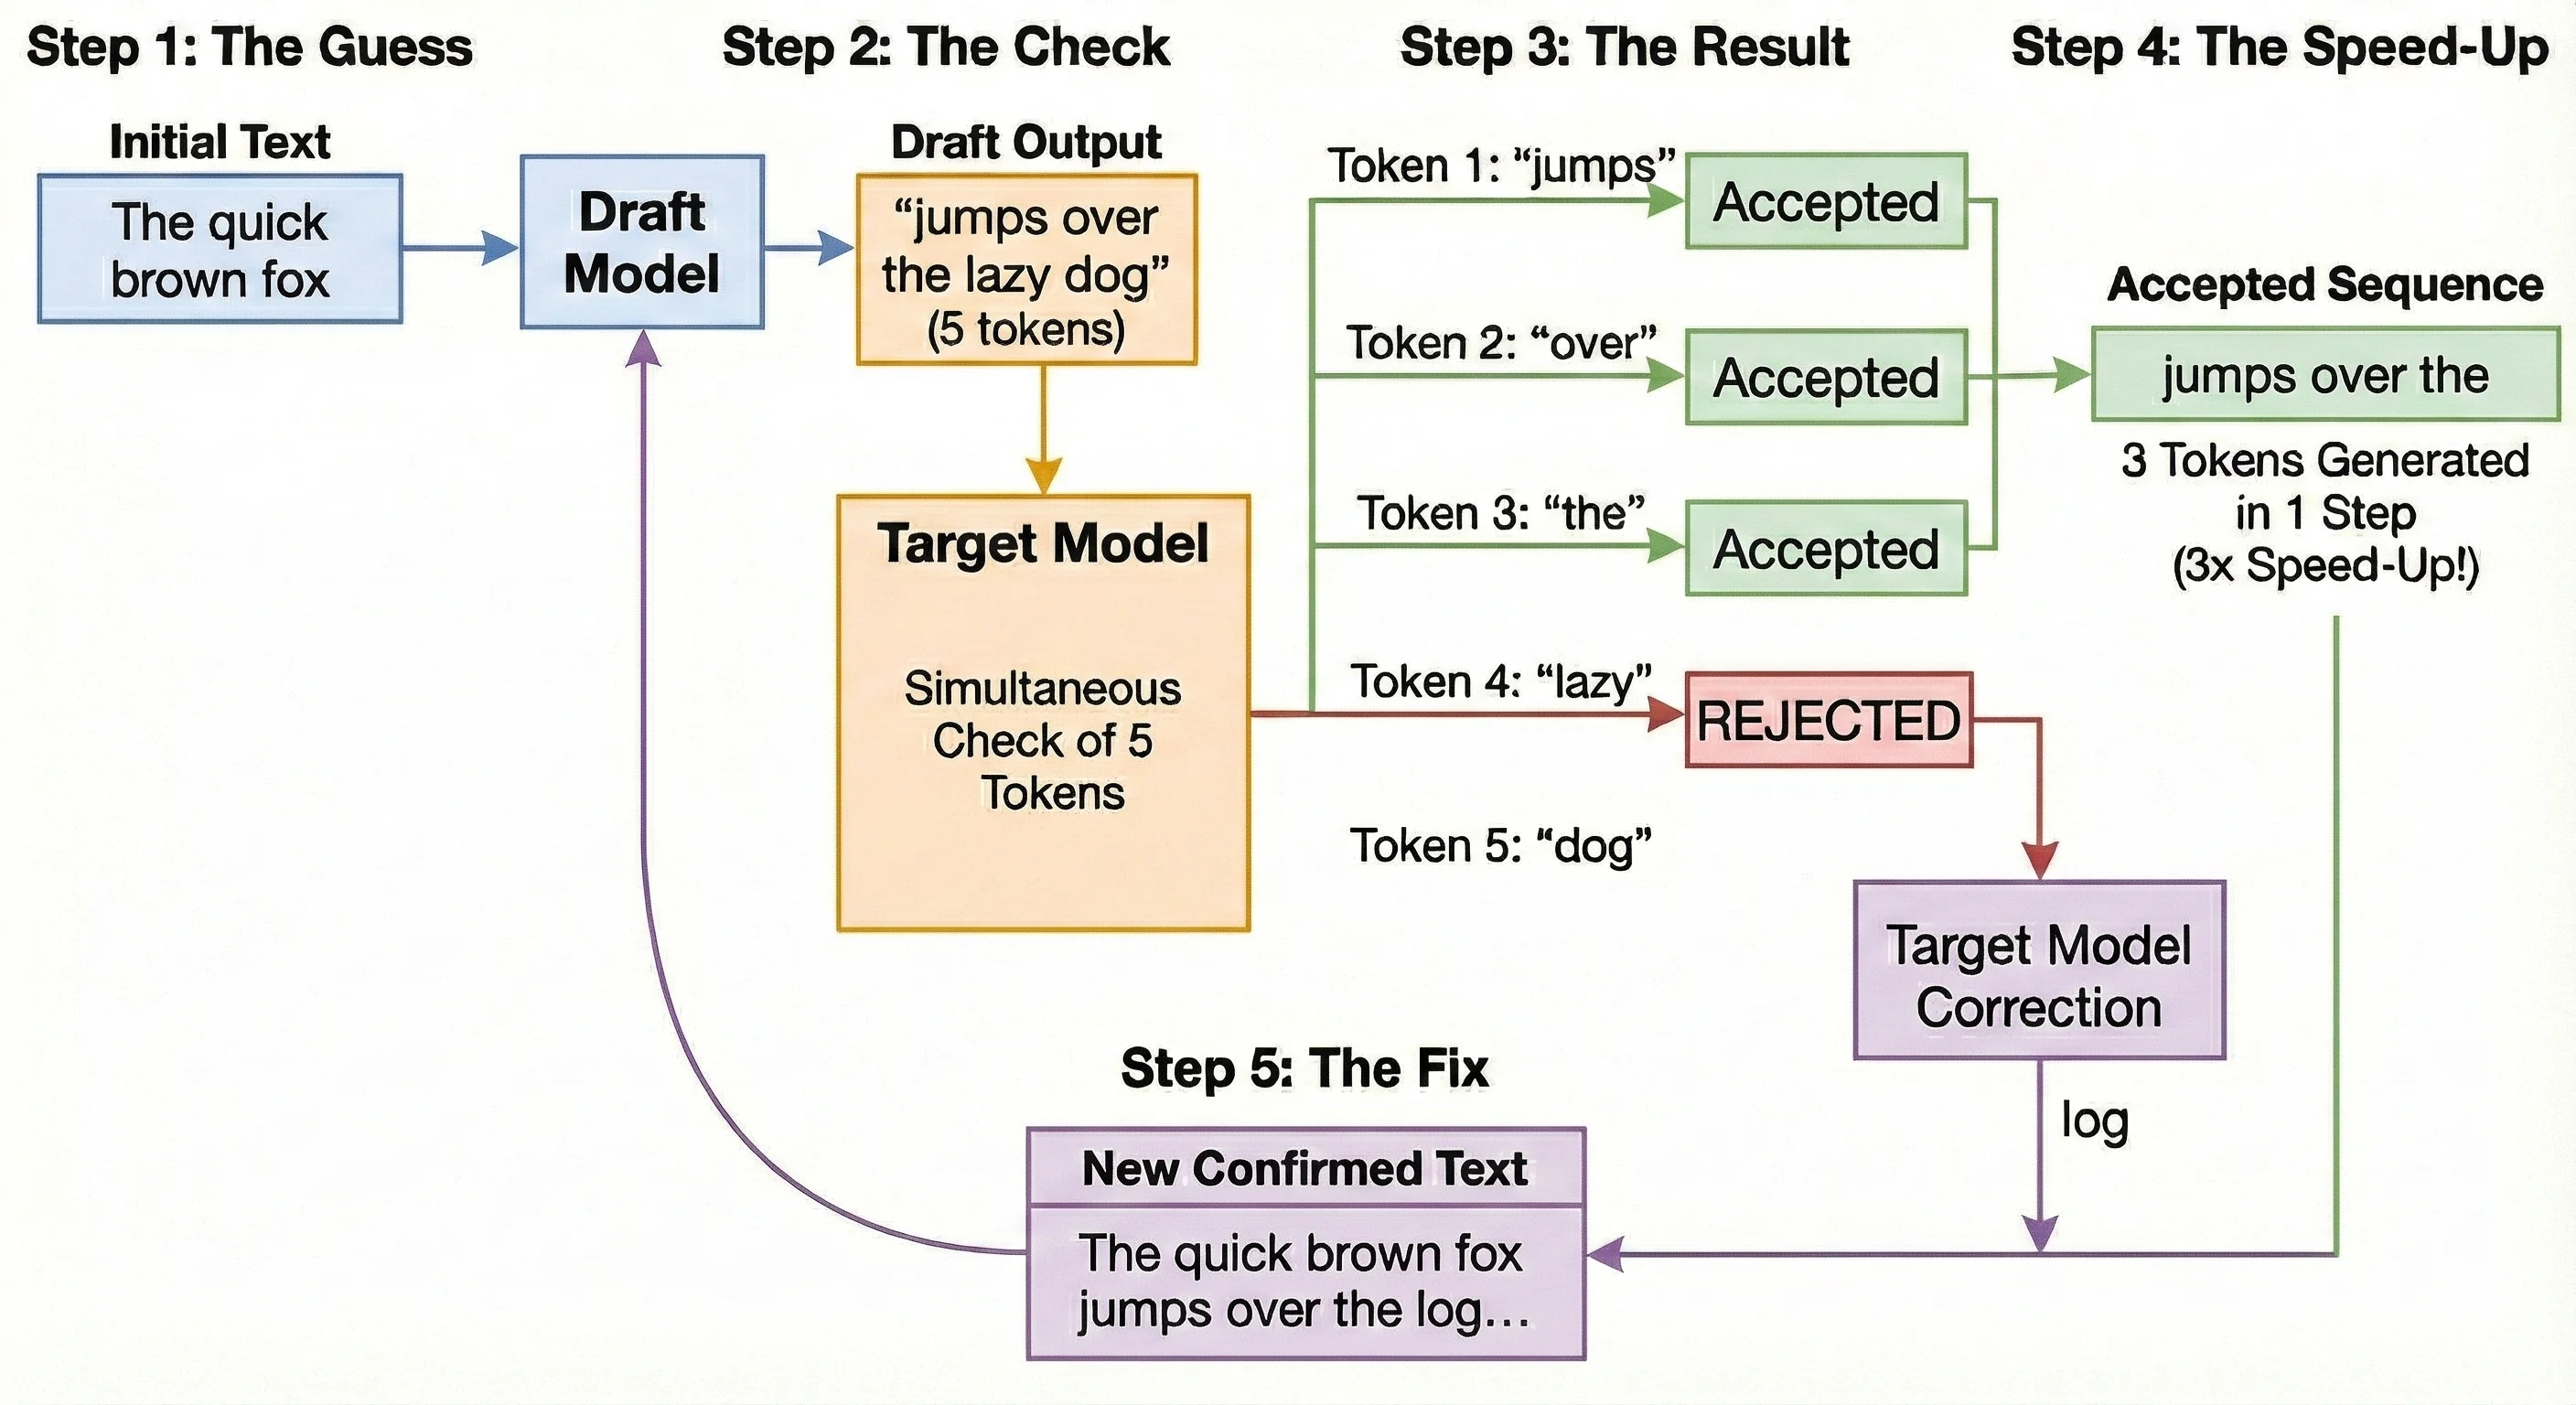
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
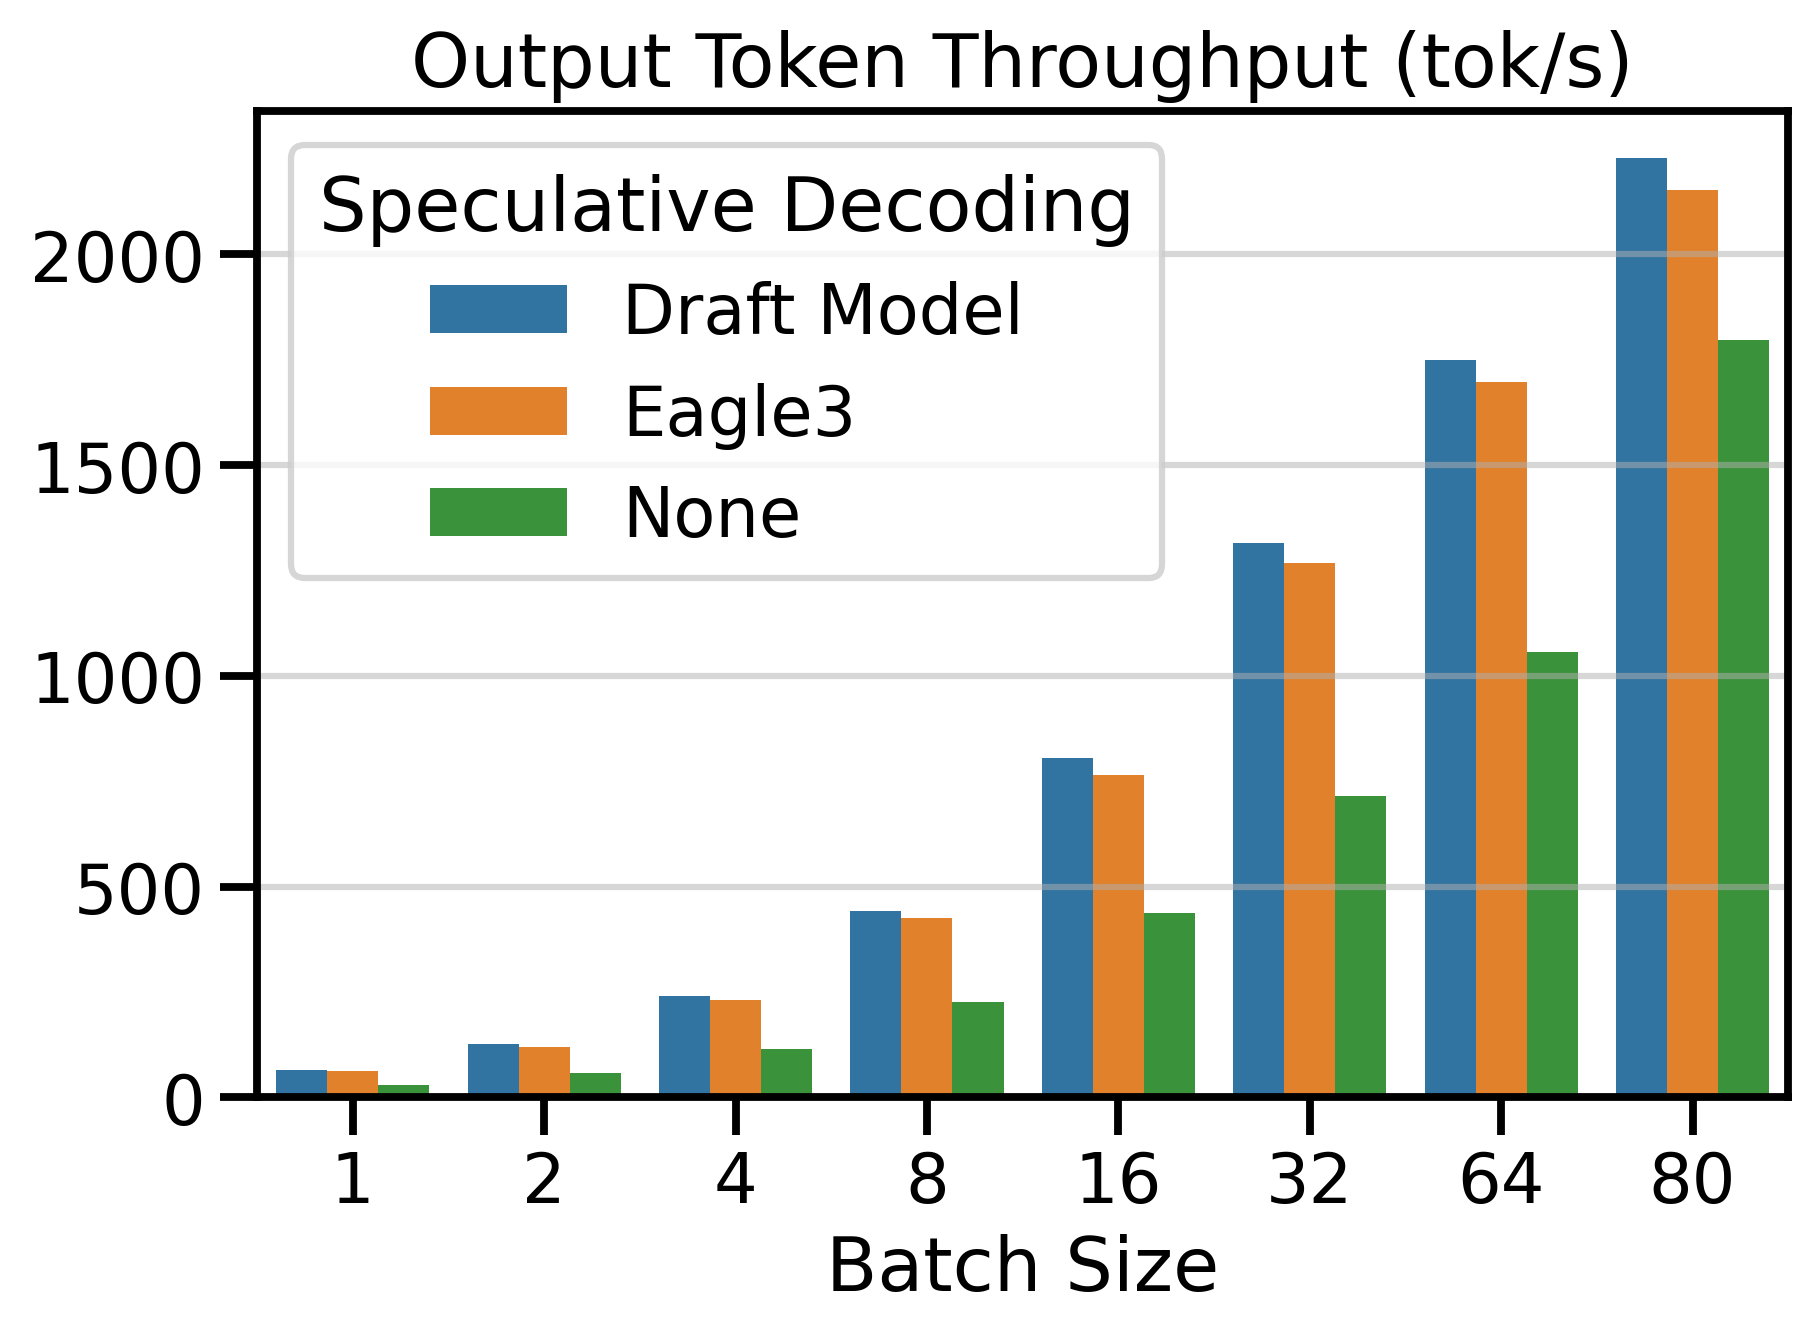
Up to 3.55x Faster: Contributing Speculative Decoding with Draft Models ...
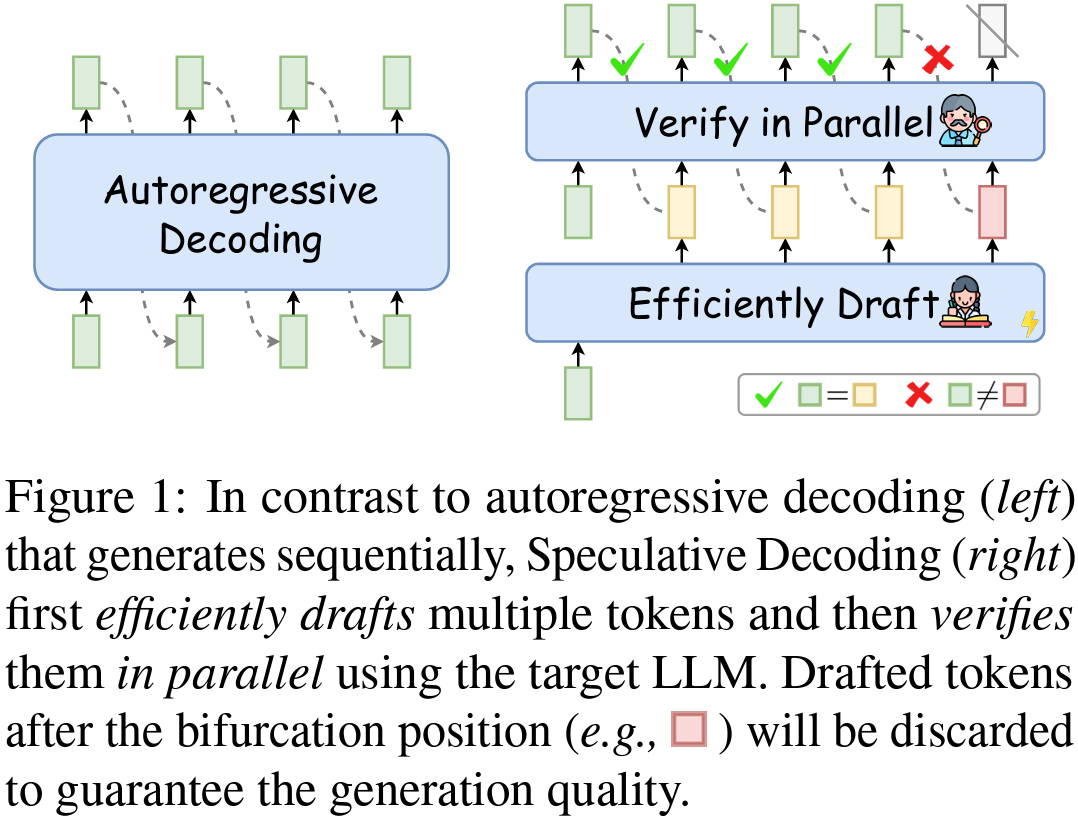
This AI Paper Unveils the Potential of Speculative Decoding for Faster ...
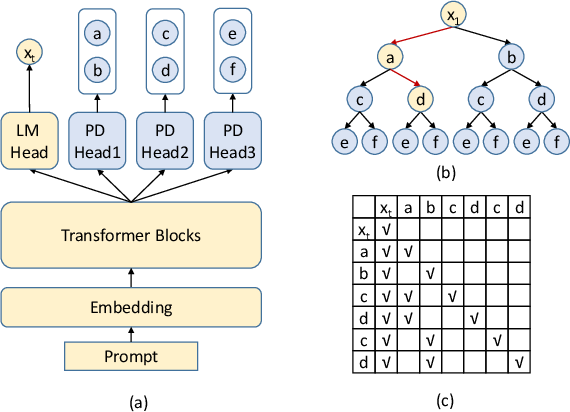
Figure 2 from ProPD: Dynamic Token Tree Pruning and Generation for LLM ...
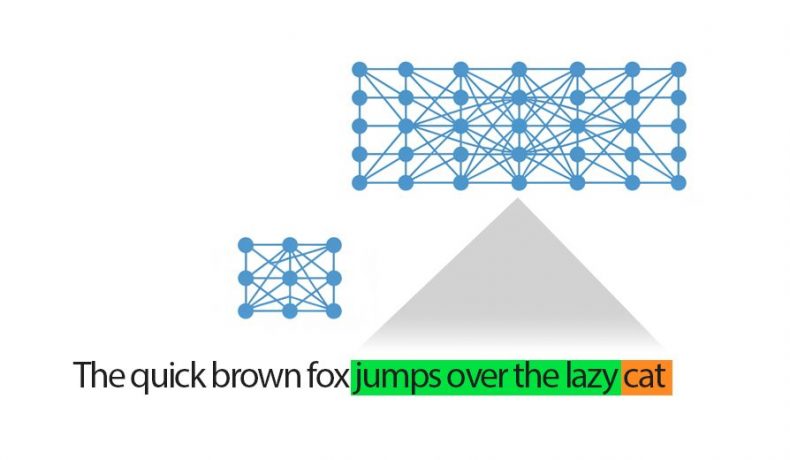
Speculative Decoding Explained: Faster Inference Without Quality Loss
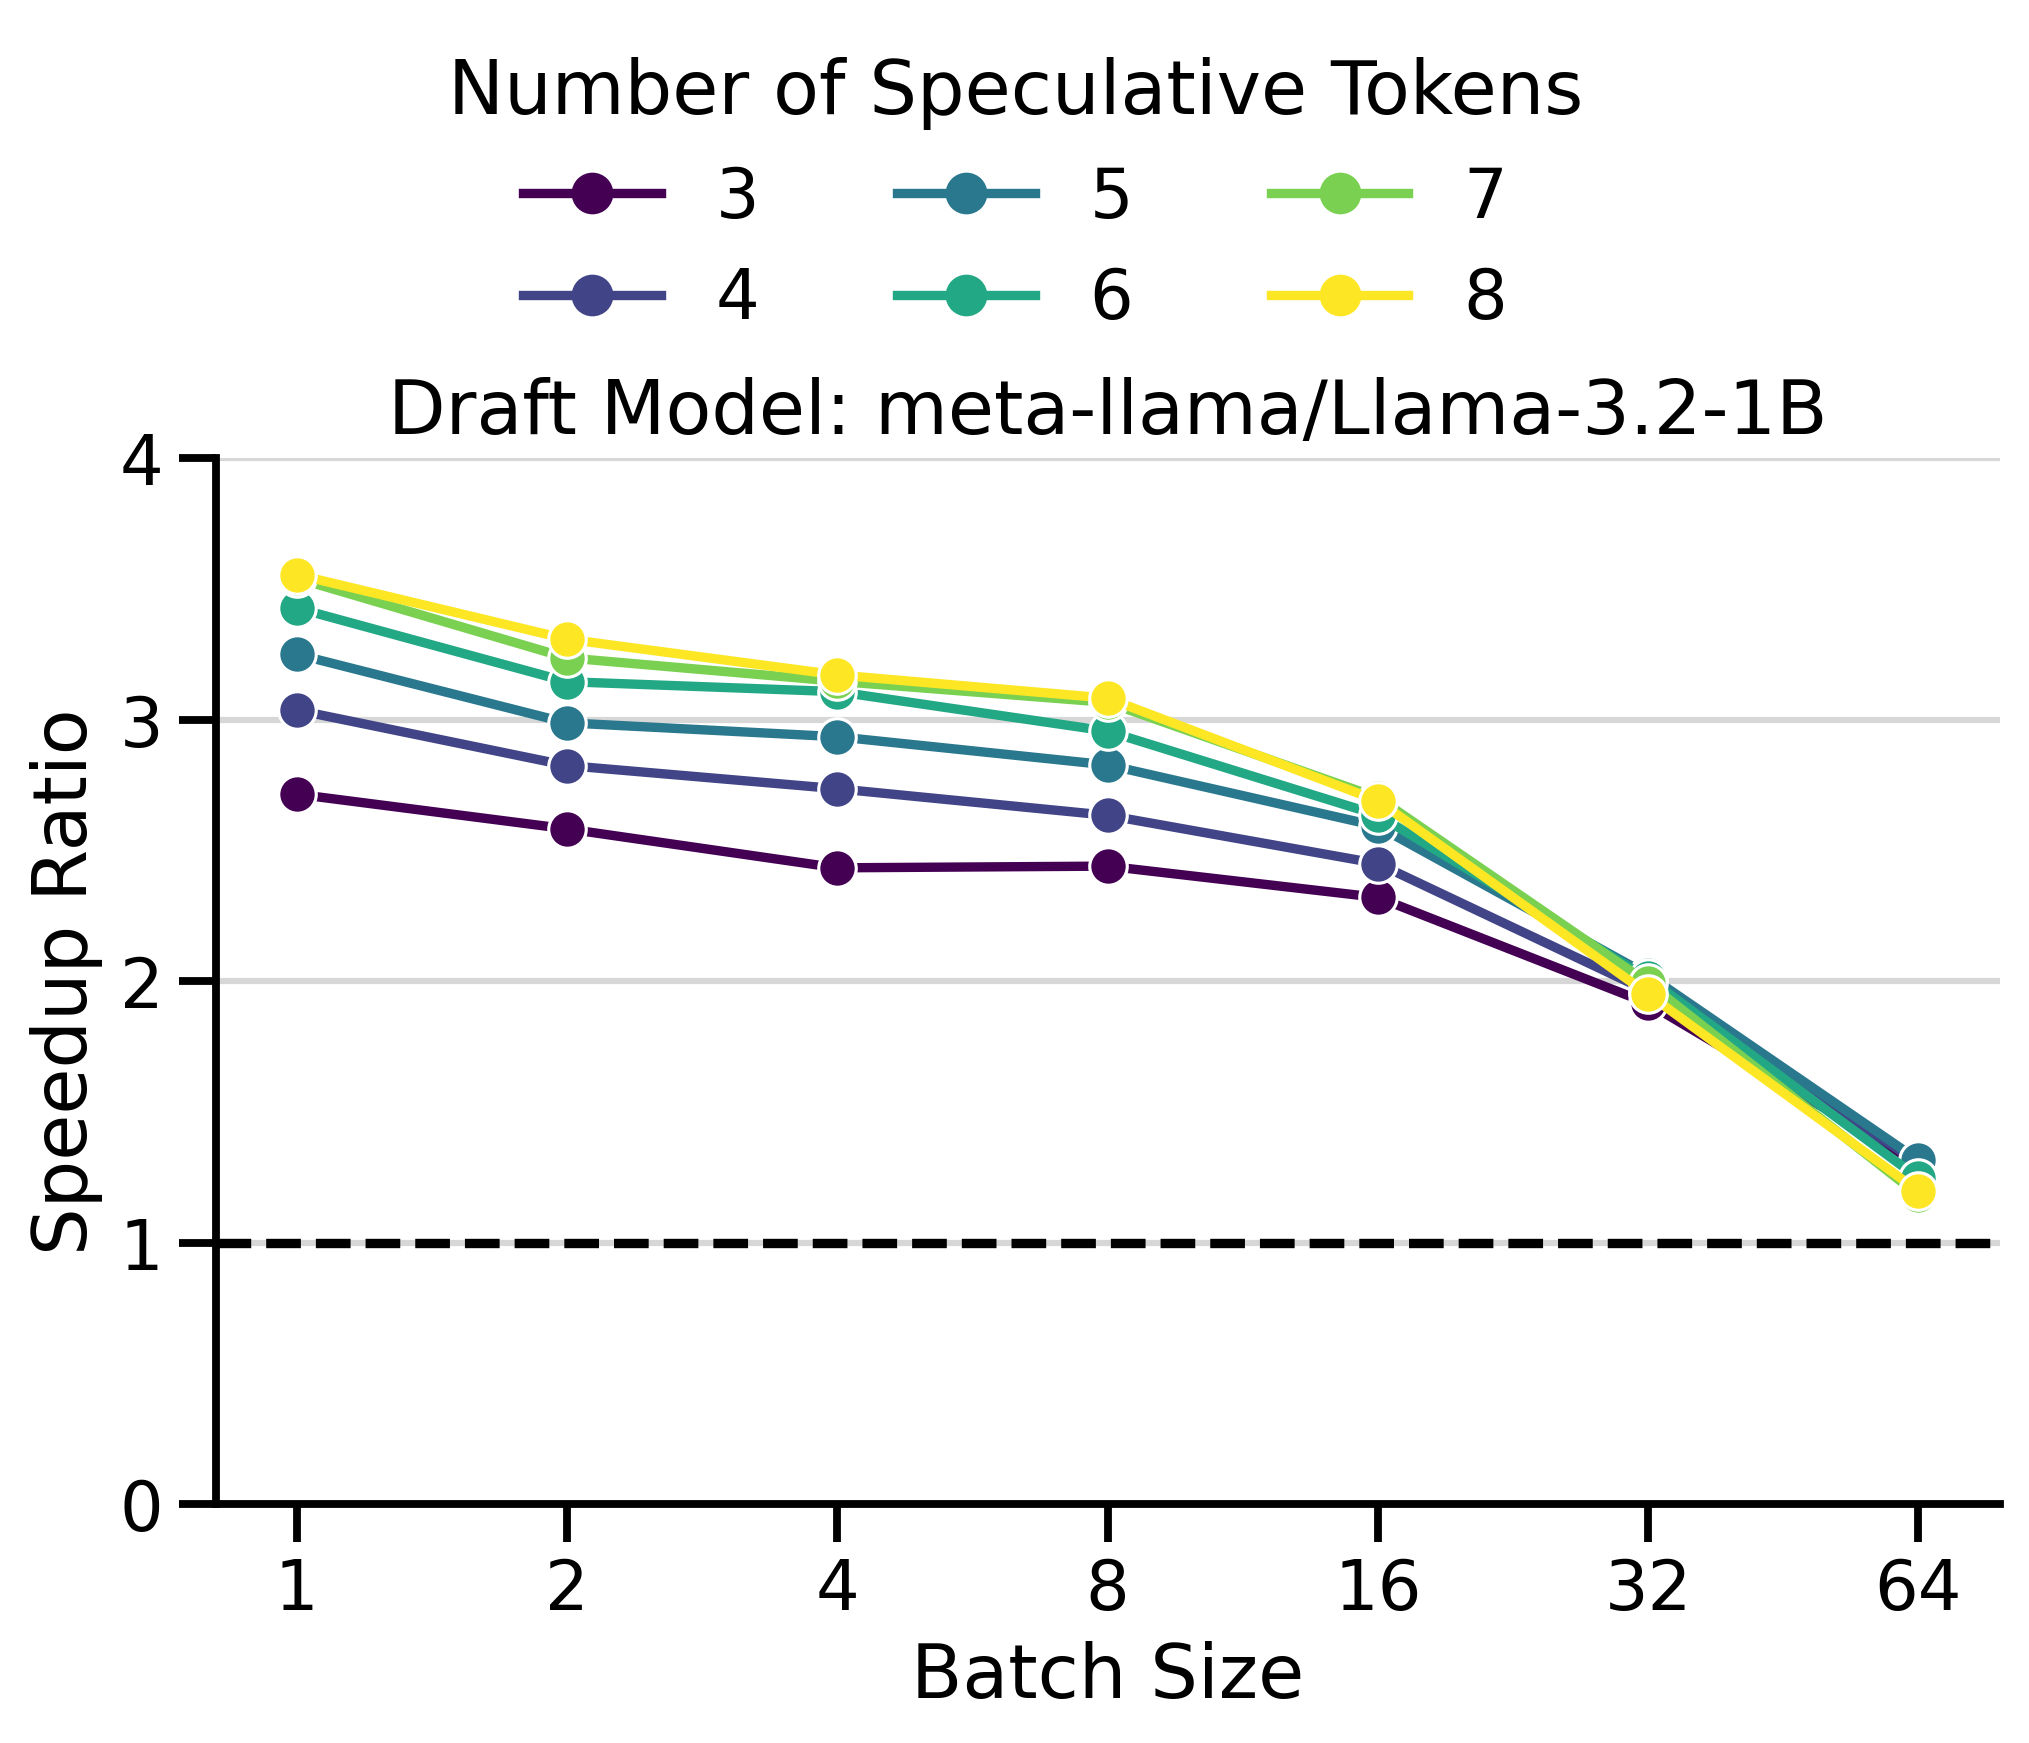
Up to 3.55x Faster: Contributing Speculative Decoding with Draft Models ...
Speculative Decoding Explained: Faster Inference Without Quality Loss
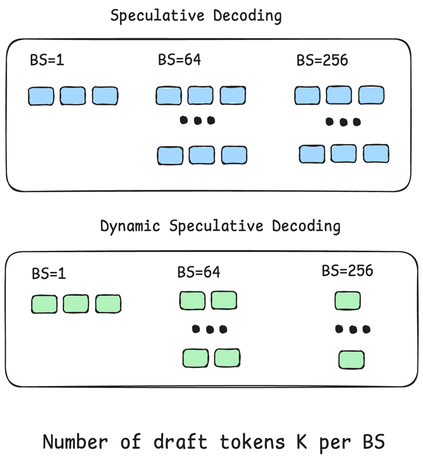
Hardware-Aware, Dynamic Speculative Decoding (DSD) | alphaXiv
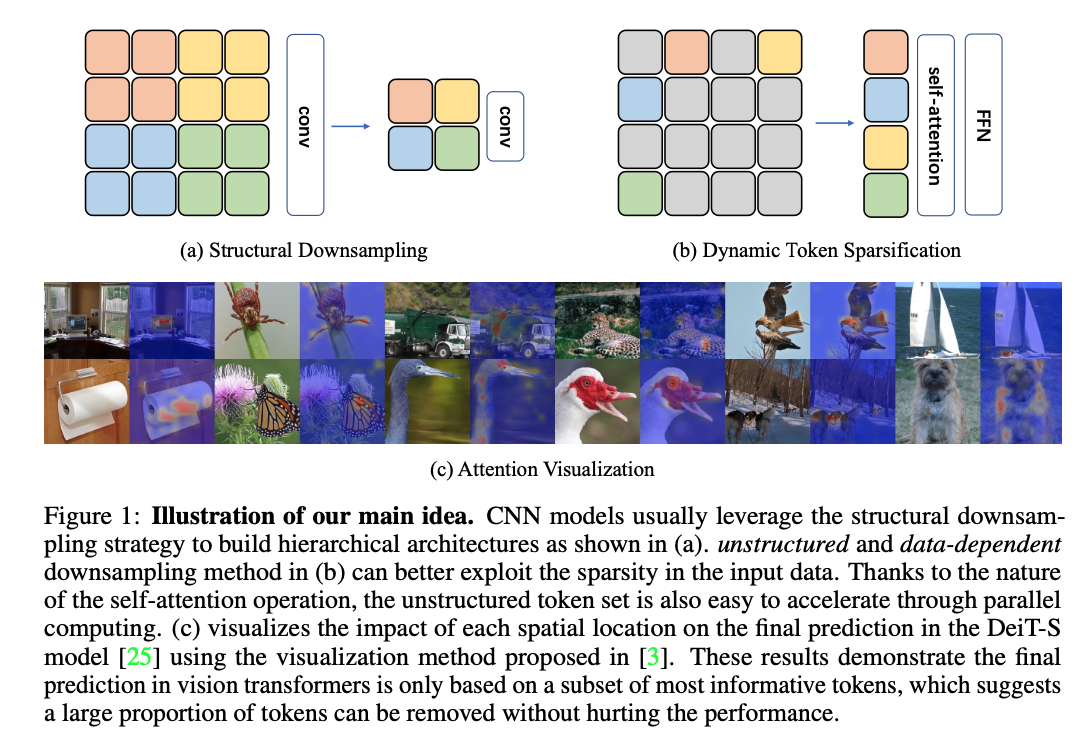
DynamicViT: Efficient Vision Transformers with Dynamic Token Sparsification
Advertisement Space (336x280)

[论文评述] Traversal Verification for Speculative Tree Decoding
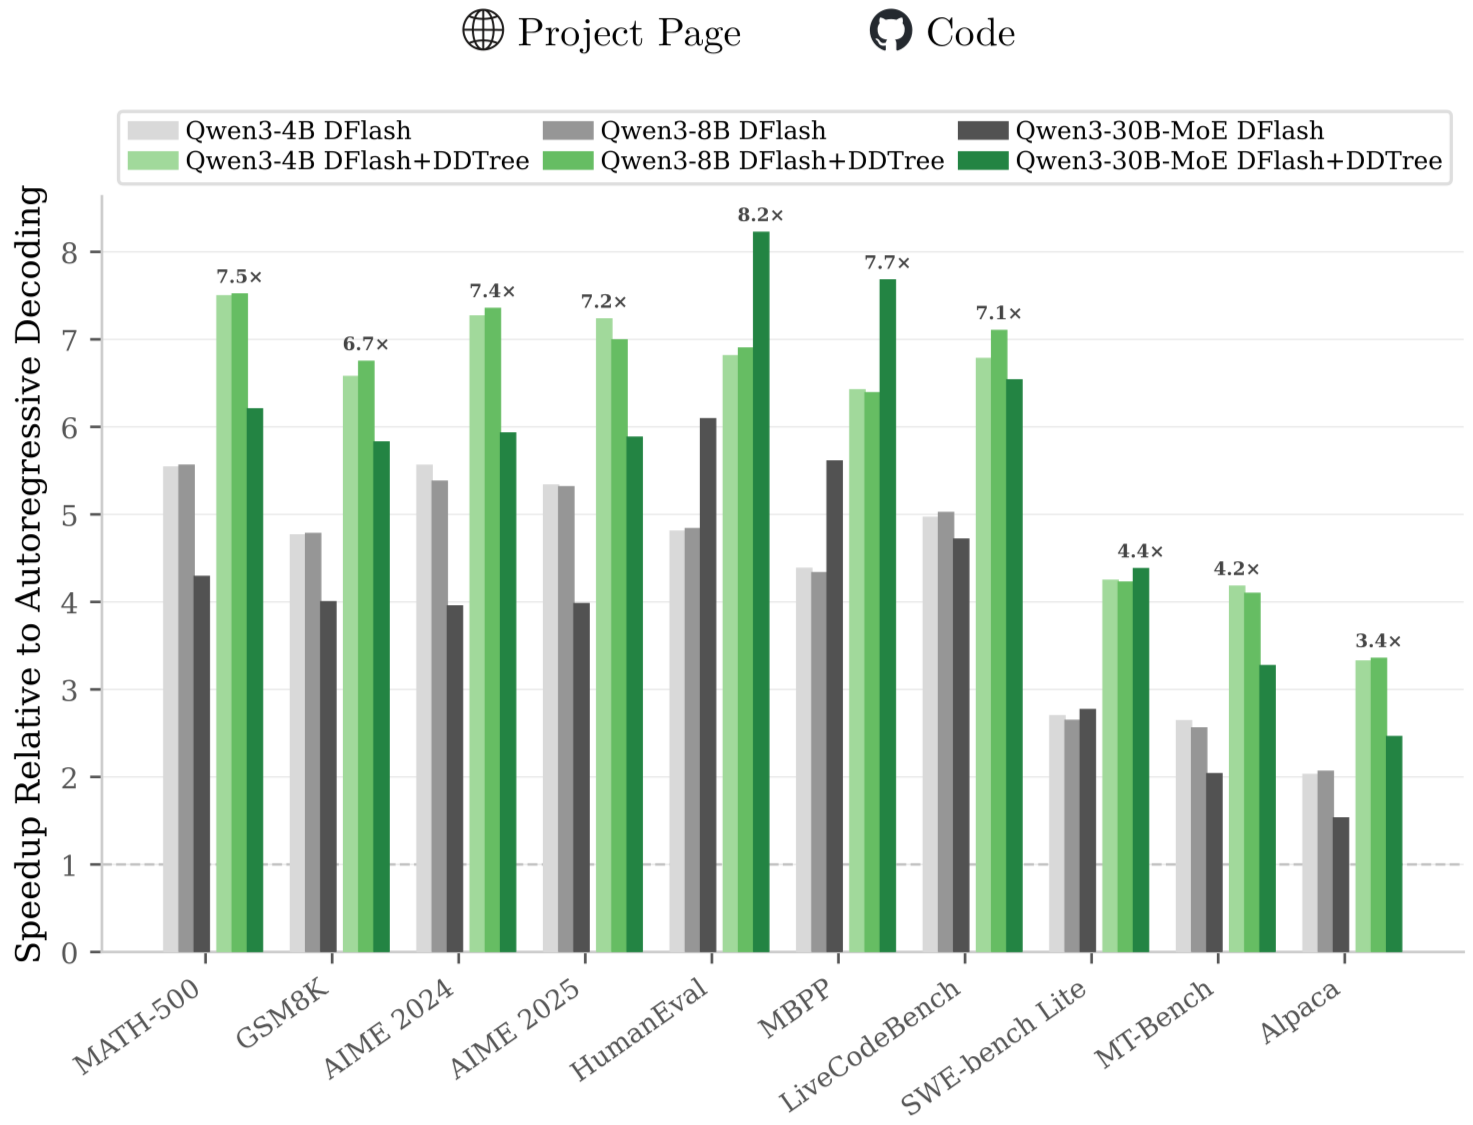
[论文评述] Accelerating Speculative Decoding with Block Diffusion Draft Trees

Speculative Decoding - Making Language Models Generate Faster Without ...

Draft Less, Retrieve More: Hybrid Tree Construction for Speculative ...
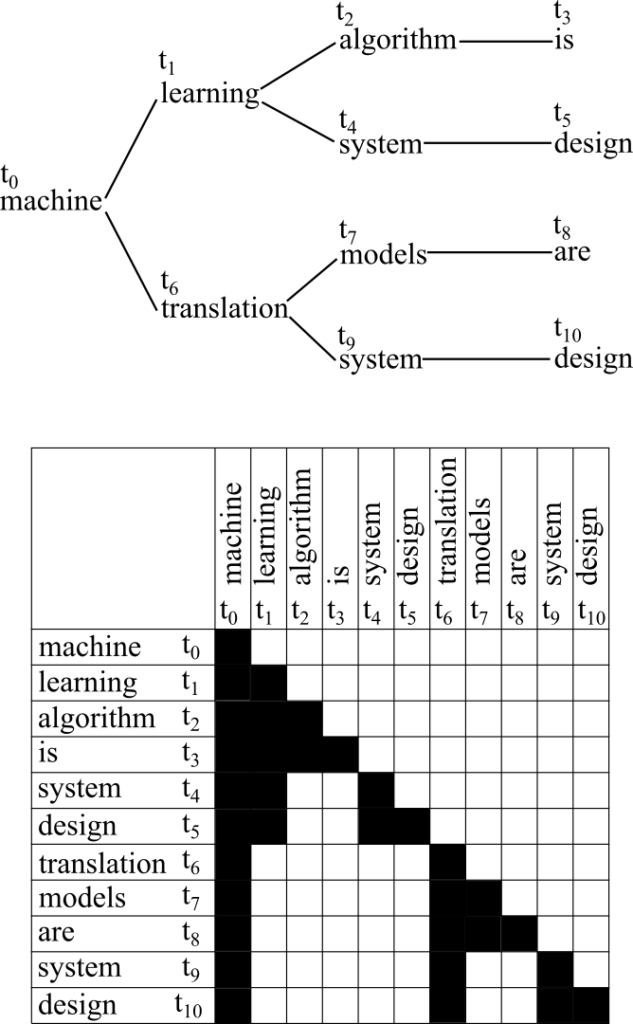
Speculative Decoding Explained | Data Processing Club

SpecEE: Accelerating Large Language Model Inference with Speculative ...