
Easily Migrating Llm Inference Serving From Vllm To Friendli Container

How to easily migrate LLM inference serving from vLLM to Friendli ...

Comparing two LLM serving frameworks: Friendli Inference vs. vLLM

LLM Serving Engine Comparative Analysis: Friendli Inference vs. vLLM vs ...

Scaling LLM Inference on GKE: Serving with vLLM or llm-d | by Don ...
How to Build a vLLM Container Image for LLM Deployment | Vultr Docs
Efficient LLM Inference and Serving with vLLM

Comparing two LLM serving frameworks: Friendli Engine vs. vLLM | by ...

VLLM: Using PagedAttention To Optimize LLM Inference and Serving ...
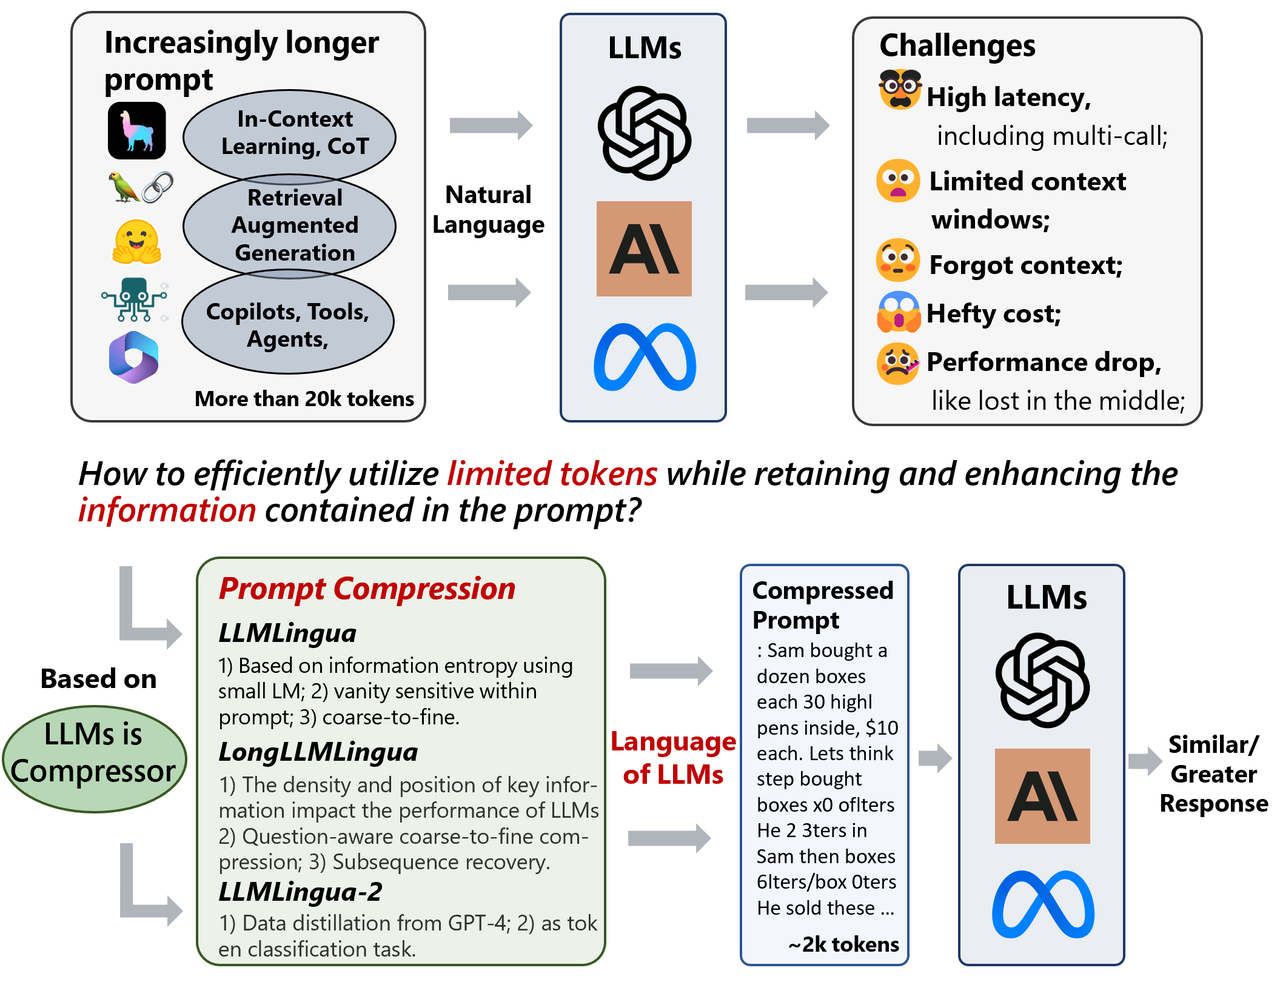
LLM Inference Optimization Overview - From Data to System Architecture ...
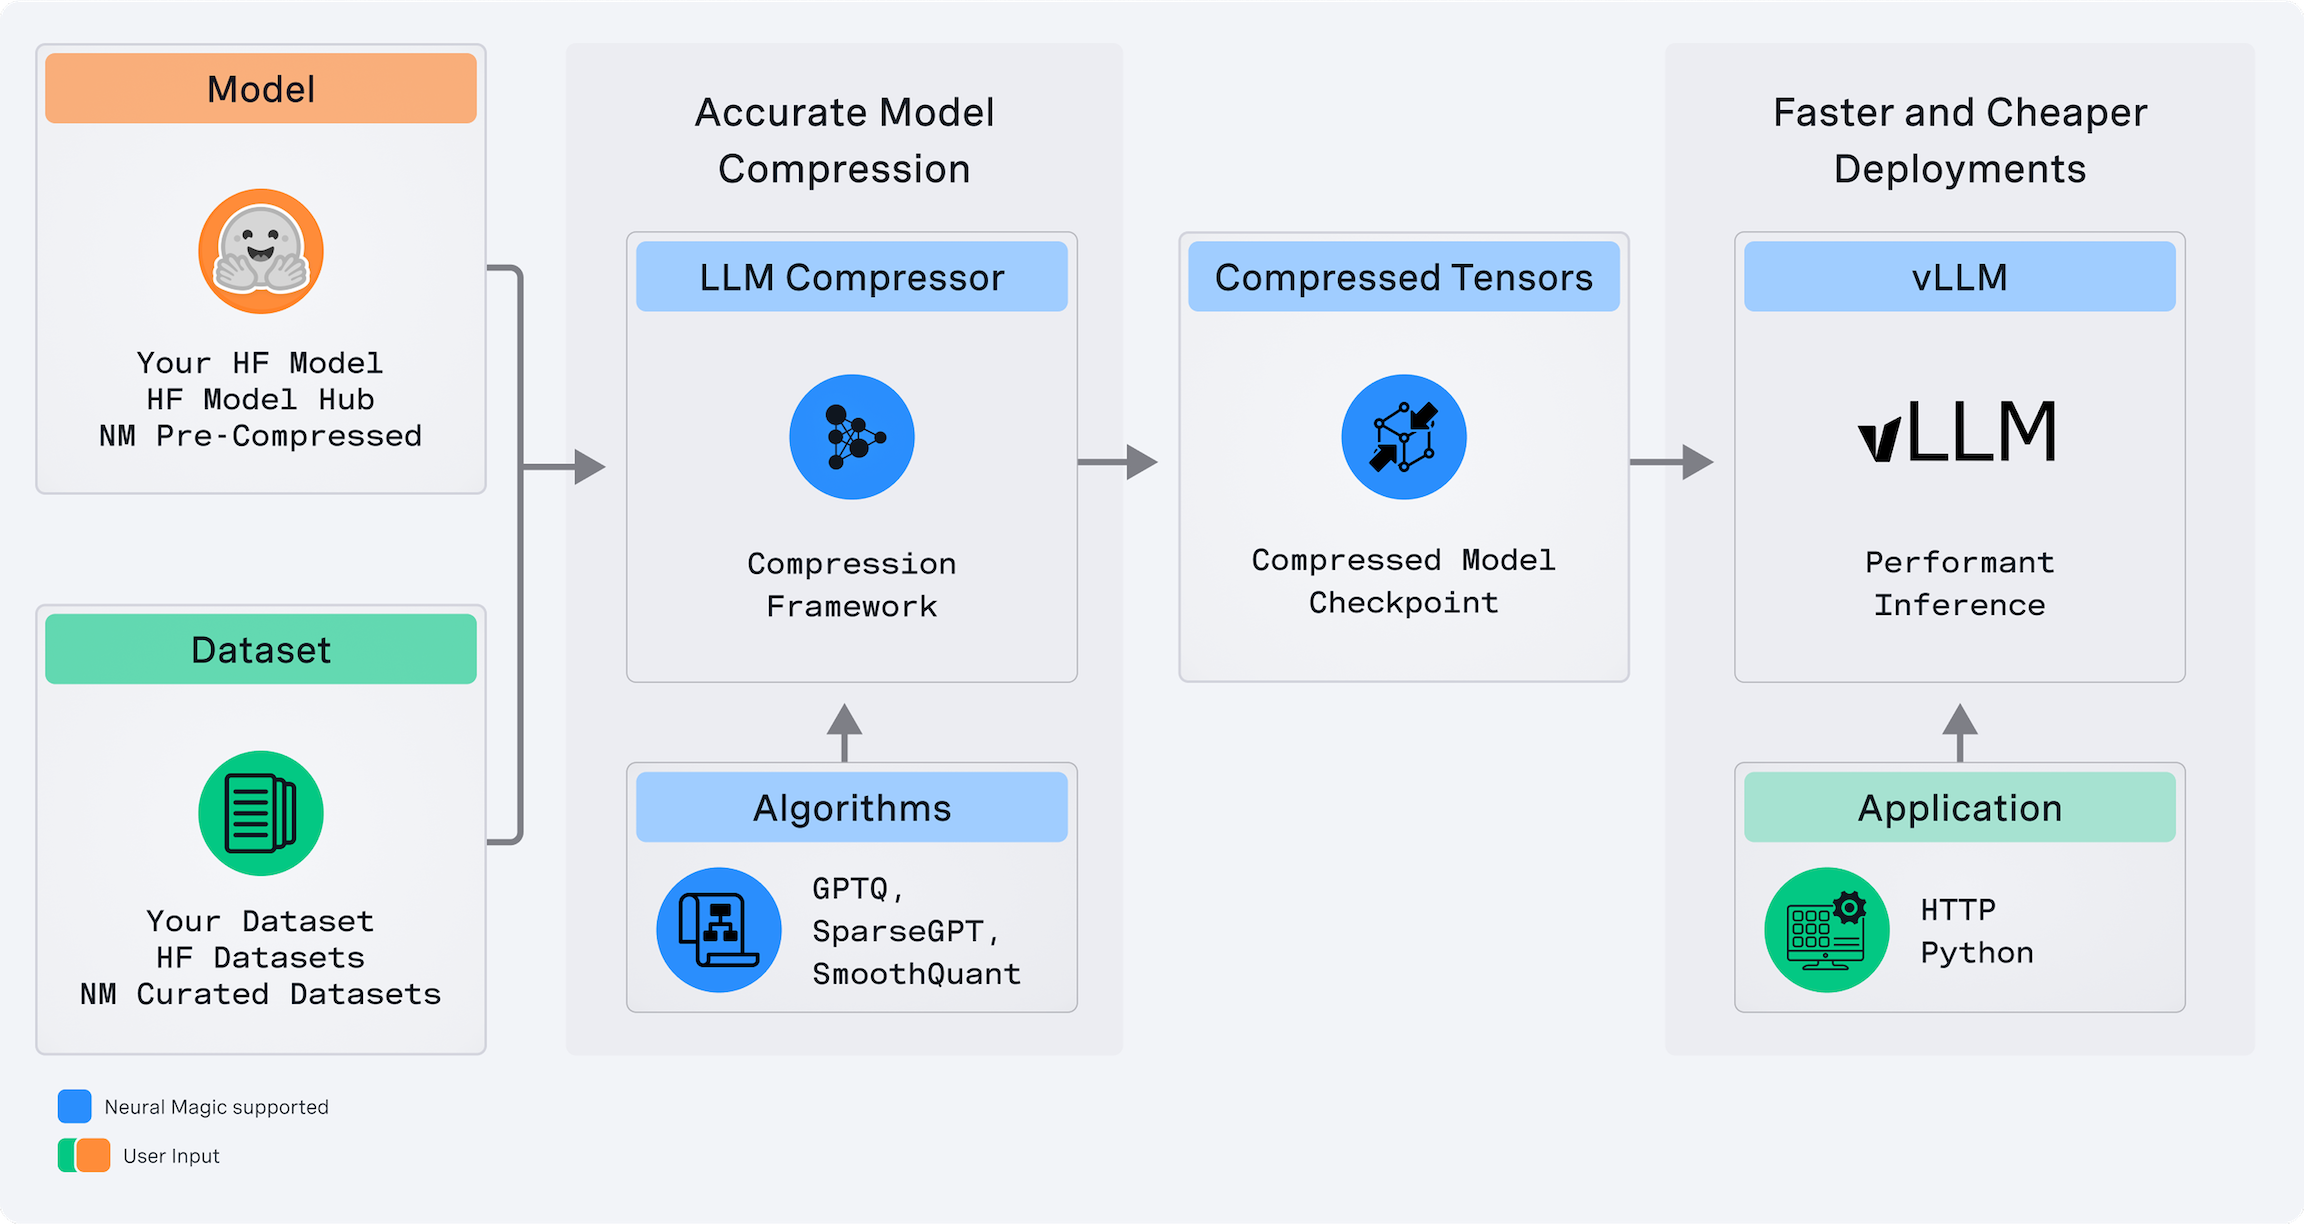
LLM Compressor is here: Faster inference with vLLM | Red Hat Developer
Advertisement Space (300x250)

Quickstart: High-throughput LLM inference with vLLM on Amazon EKS ...
Friendli Container Part 1: Efficiently Serving LLMs On-Premise

vLLM production-stack: LLM inference for Enterprises (part1) - Cloudthrill
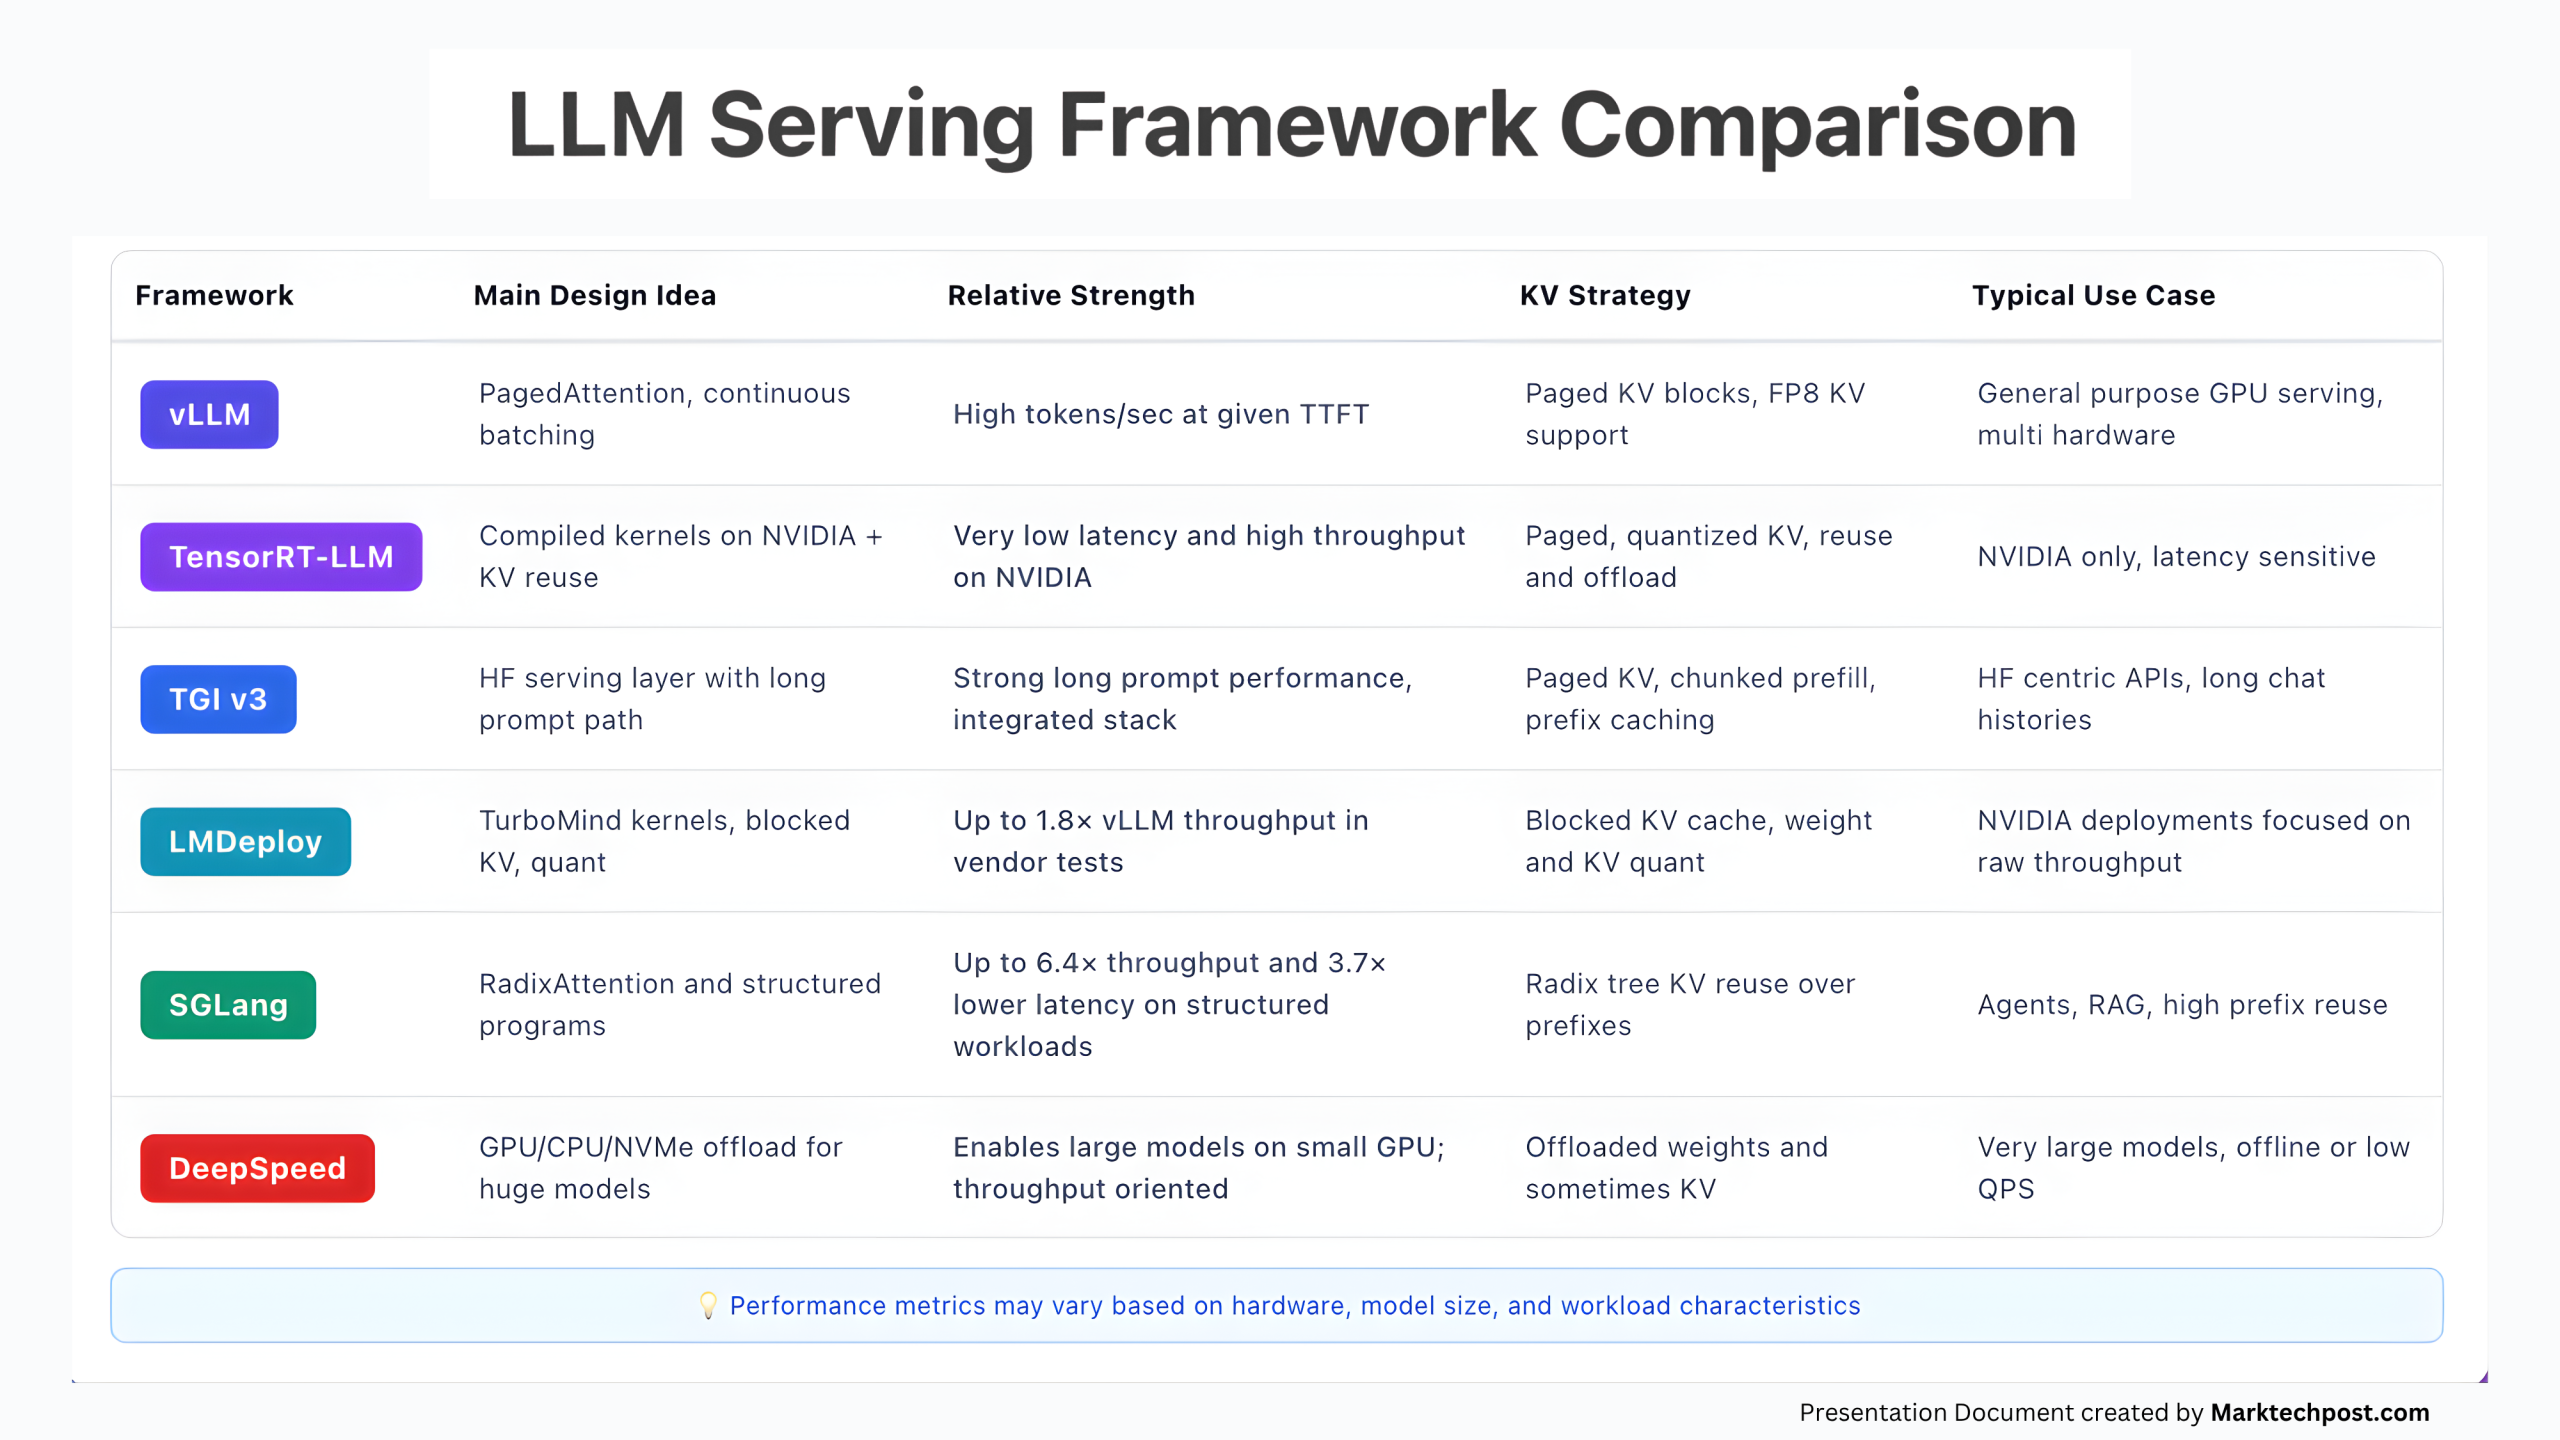
Comparing the Top 6 Inference Runtimes for LLM Serving in 2025 ...
vLLM: High-Throughput LLM Inference Serving Engine | Inference Systems

Scaling LLM inference with Ray and vLLM
Introducing Structured Output on Friendli Inference for Building LLM Agents

vLLM Review: High-Performance LLM Inference Engine for GPU ...

vLLM production-stack: LLM inference for Enterprises (part1) - Cloudthrill

Friendli TCache: Optimizing LLM Serving by Reusing Computations | by ...
Advertisement Space (336x280)
vLLM OpenTelemetry: Monitor LLM Inference Metrics with Parseable

Free Video: vLLM Inference and LLM Server Engine for Machine Learning ...
vLLM 2026: Open Source LLM Inference Engine im Detail
Optimized LLM inference API for Mistral 7B using vLLM - a Lightning ...

Meet vLLM: For faster, more efficient LLM inference and serving

How vLLM solves LLM serving issues for AI apps | Aaroh Bhardwaj posted ...
Best LLM Inference Engines and Servers to Deploy LLMs in Production - Koyeb
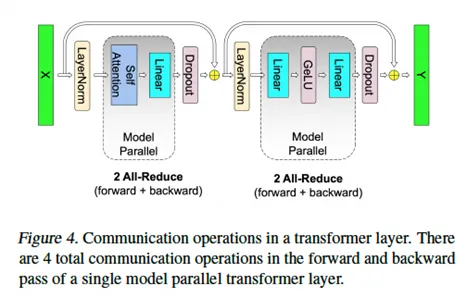
Analyzing the Distributed Inference Process Using vLLM and Ray from the ...

12 vLLM Alternatives for Efficient and Scalable LLM Inference ...
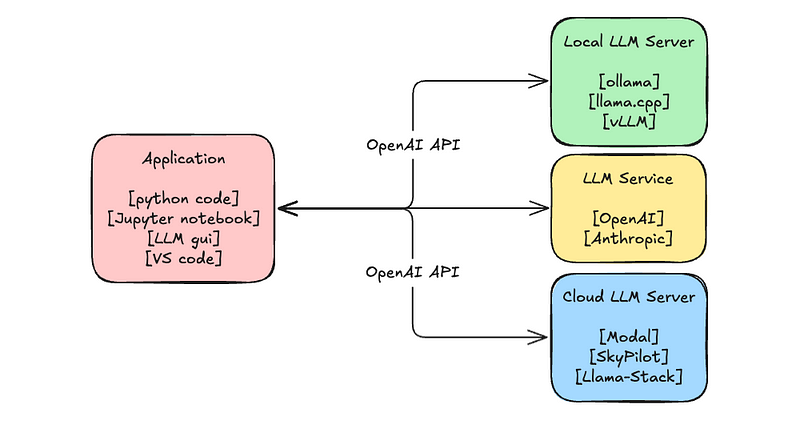
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...
Advertisement Space (336x280)
12 vLLM Alternatives for Efficient and Scalable LLM Inference ...
vLLM - High-throughput LLM inference engine with PagedAttention ... at ...
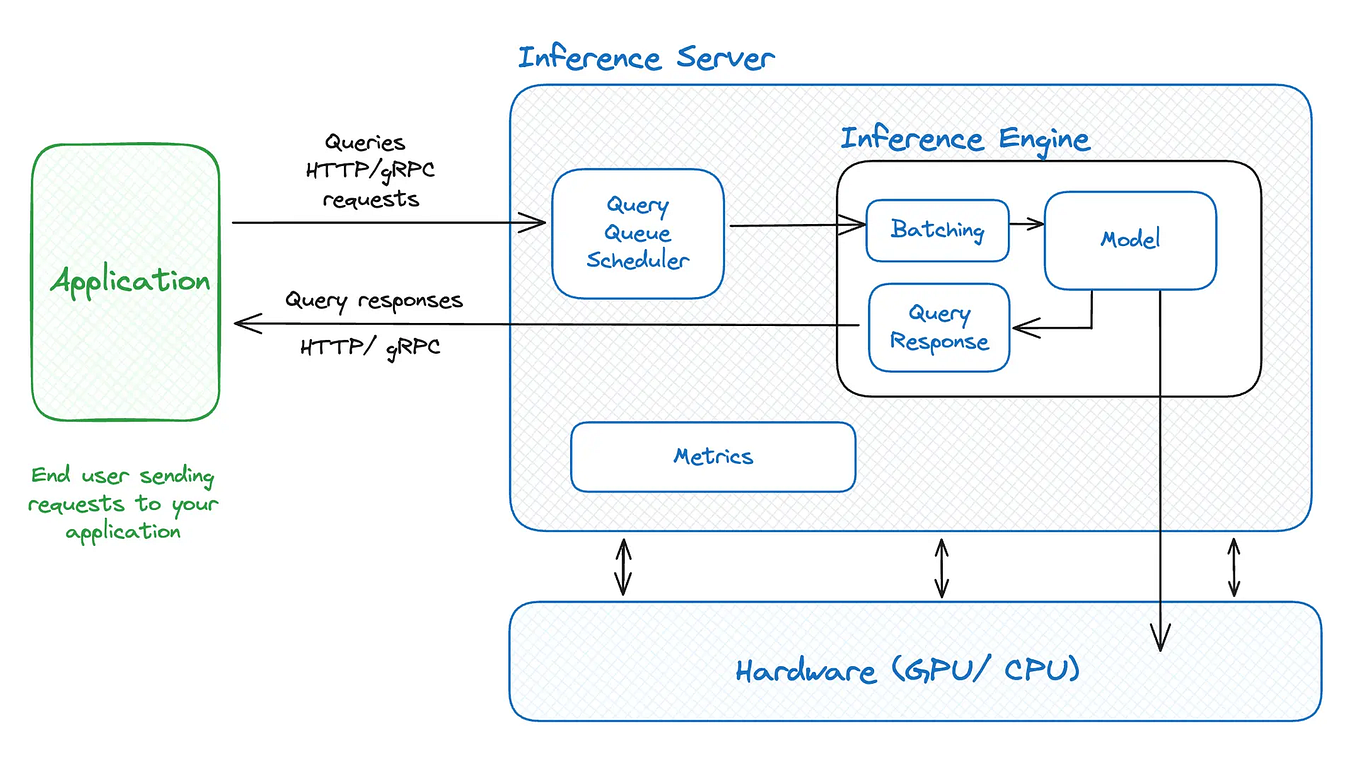
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...

Deploy the vLLM Inference Engine to Run Large Language Models (LLM) on ...

Intelligent Inference Scheduling with vLLM & llm-d: Next-Gen LLM Model ...