
How To Easily Migrate Llm Inference Serving From Vllm To Friendli

How to easily migrate LLM inference serving from vLLM to Friendli ...
How to Configure vLLM for LLM Serving

Comparing two LLM serving frameworks: Friendli Inference vs. vLLM

LLM Serving Engine Comparative Analysis: Friendli Inference vs. vLLM vs ...

VLLM: Using PagedAttention To Optimize LLM Inference and Serving ...
LLM Inference Basics — From Prompt to Response | tutorialQ
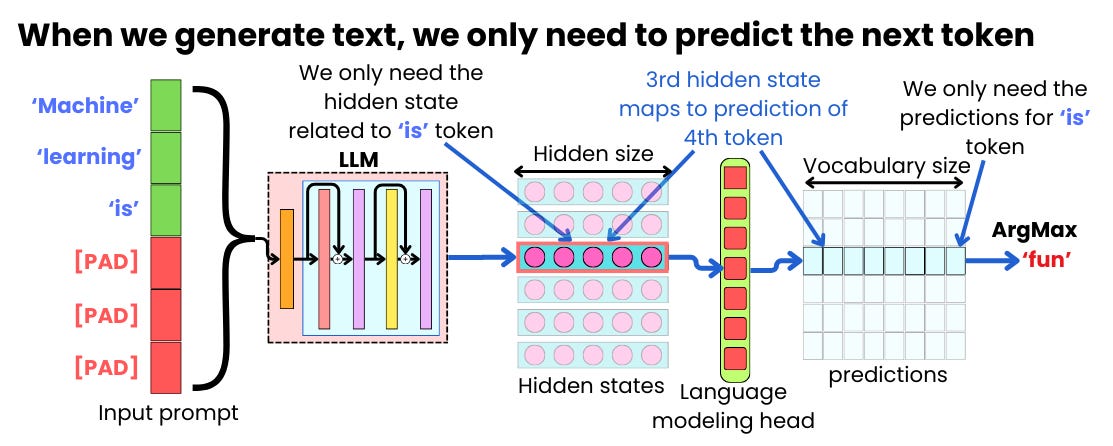
How to Scale LLM Inference - by Damien Benveniste
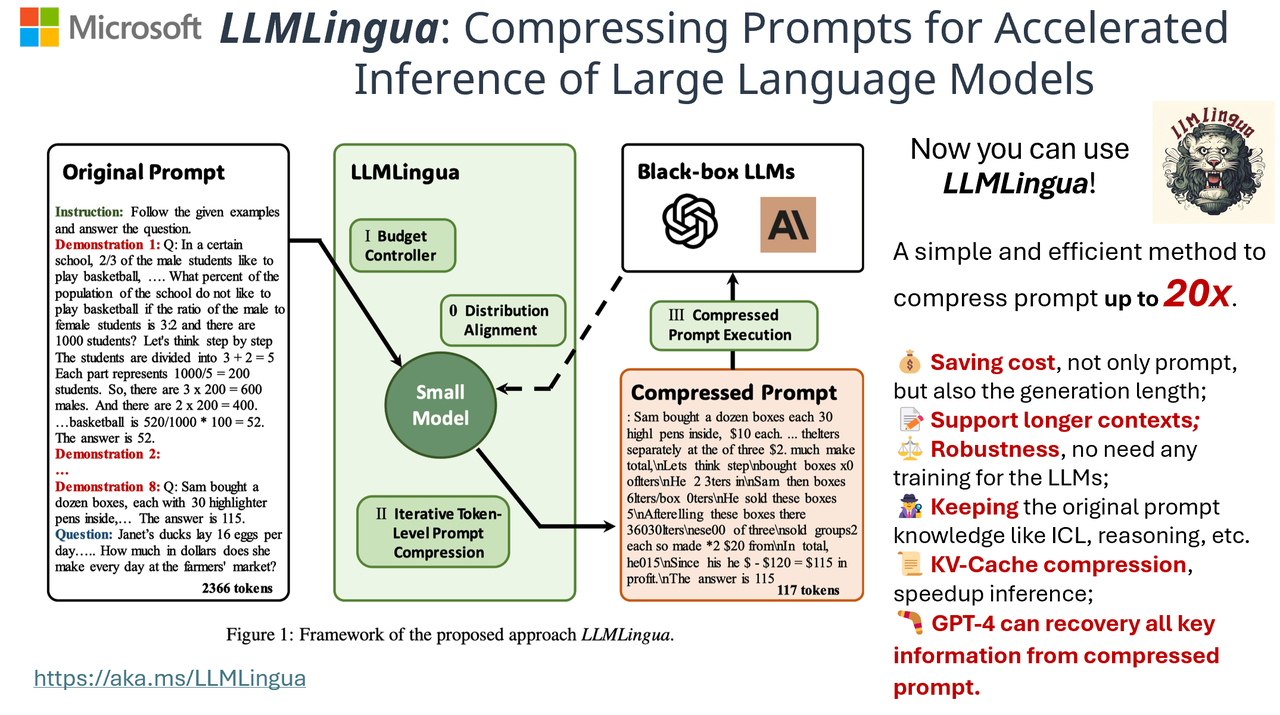
LLM Inference Optimization Overview - From Data to System Architecture ...

Scaling LLM Inference on GKE: Serving with vLLM or llm-d | by Don ...
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
Advertisement Space (300x250)
Efficient LLM Inference and Serving with vLLM

How vLLM solves LLM serving issues for AI apps | Aaroh Bhardwaj posted ...

Deploy the vLLM Inference Engine to Run Large Language Models (LLM) on ...
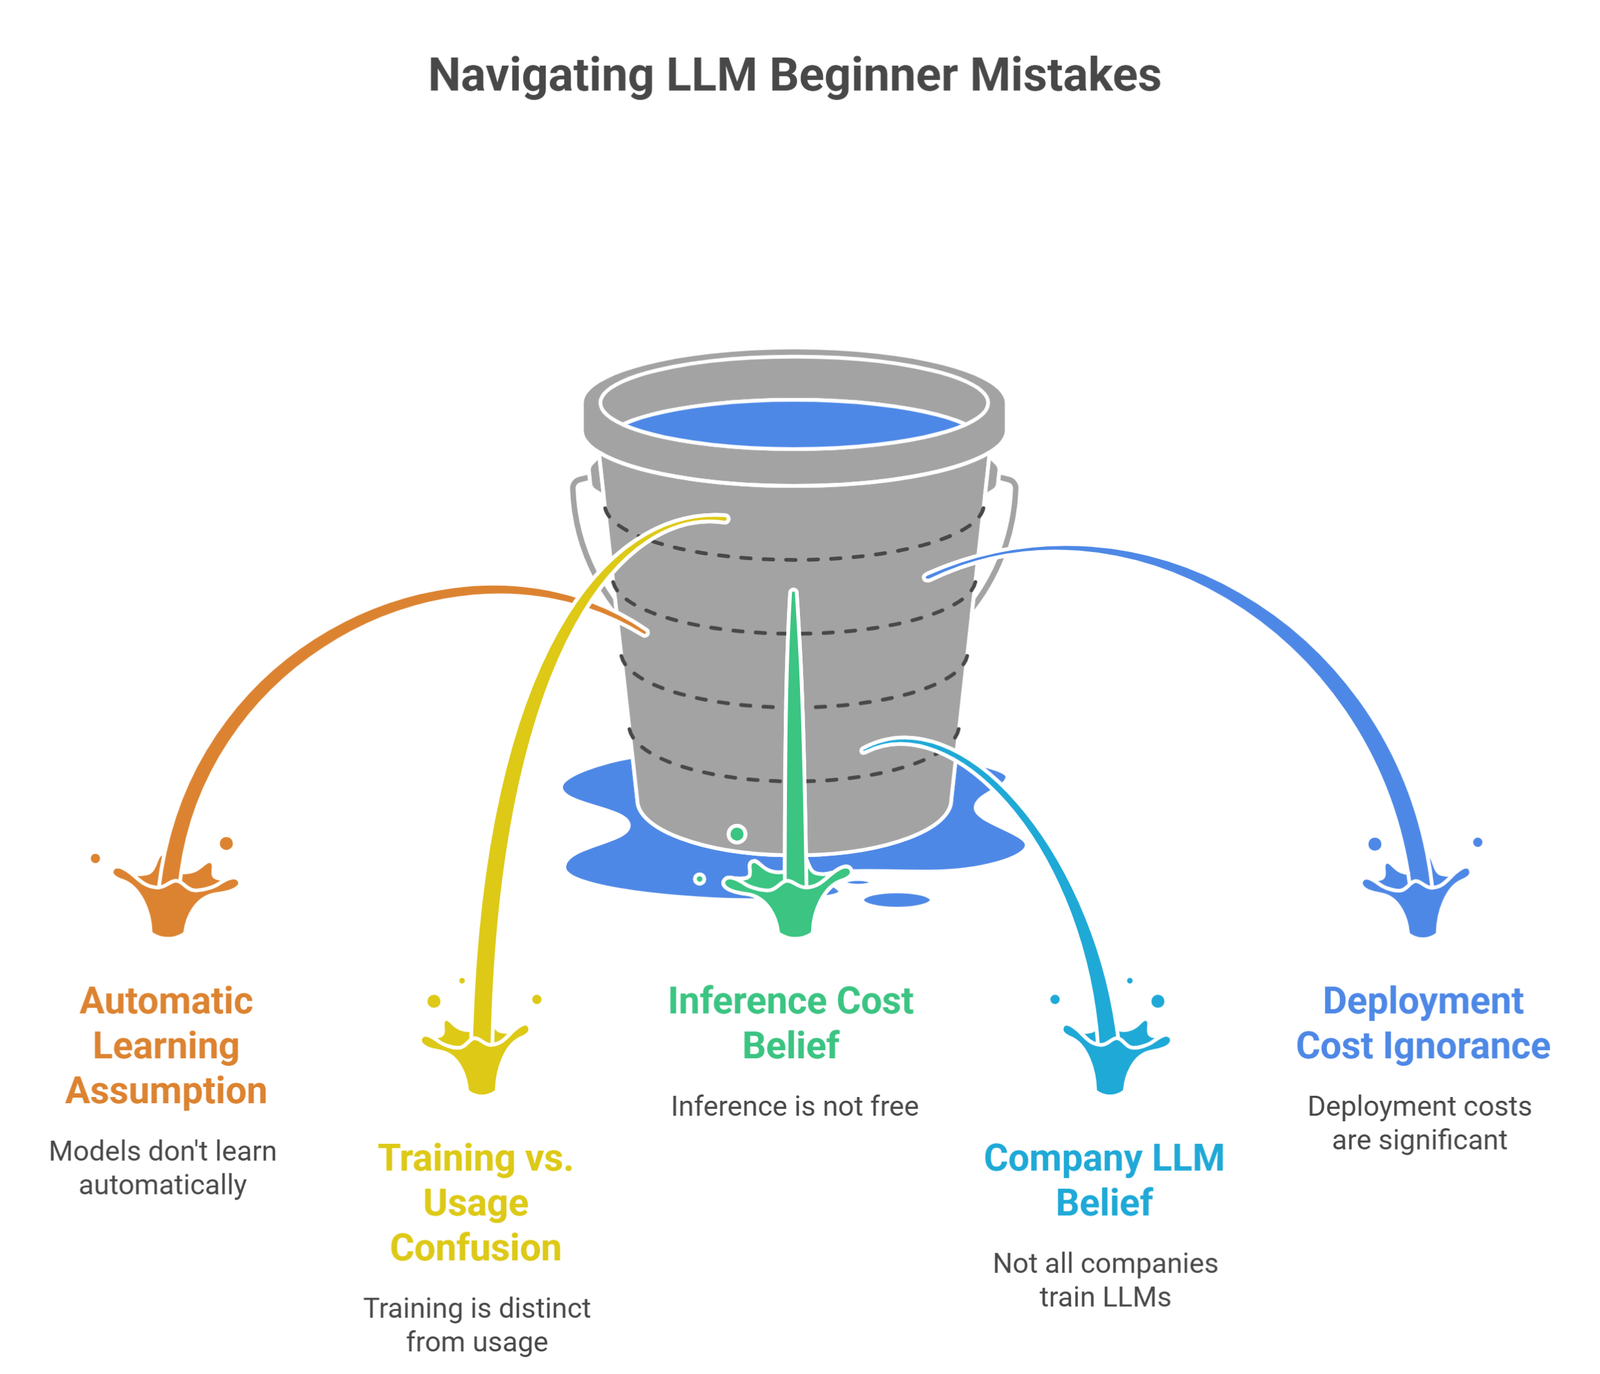
Ultimate Guide to LLM Training vs Inference in 2026 (Easy, Fast ...
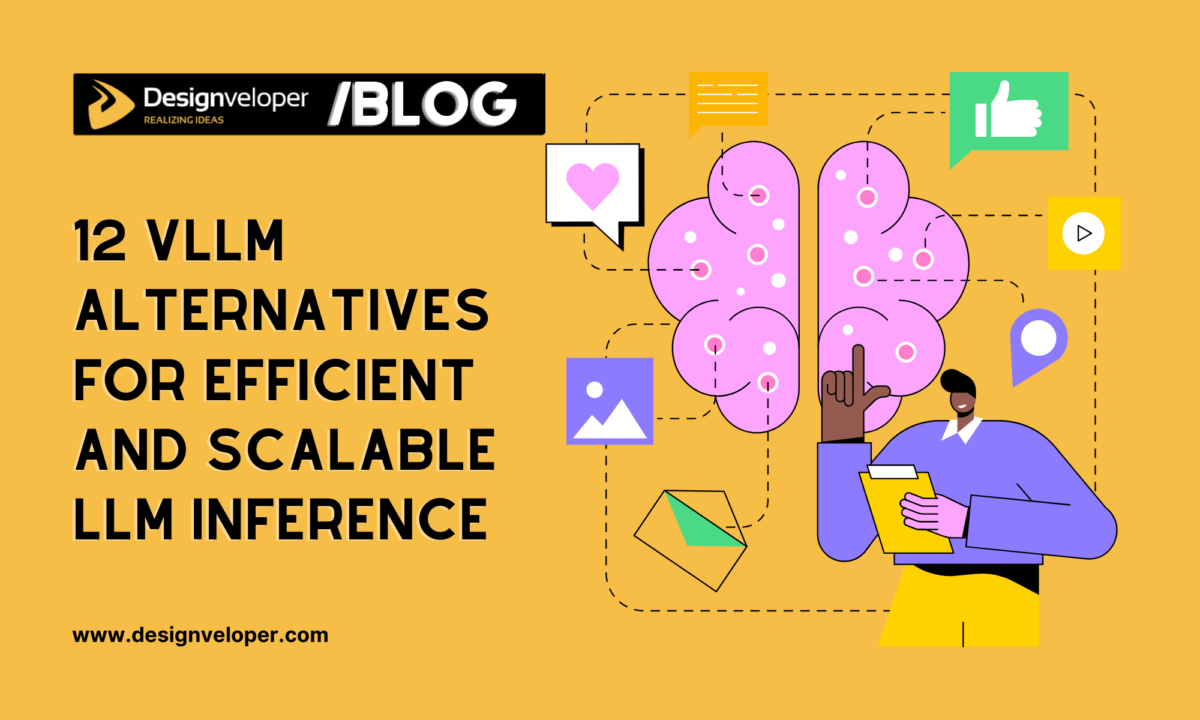
vLLM Tutorial: A Step-By-Step Guide To Deploying And Serving LLMs ...

Comparing two LLM serving frameworks: Friendli Engine vs. vLLM | by ...

How to setup an LLM on PC examples
The Complete Guide to LLM Quantization with vLLM: Benchmarks & Best ...
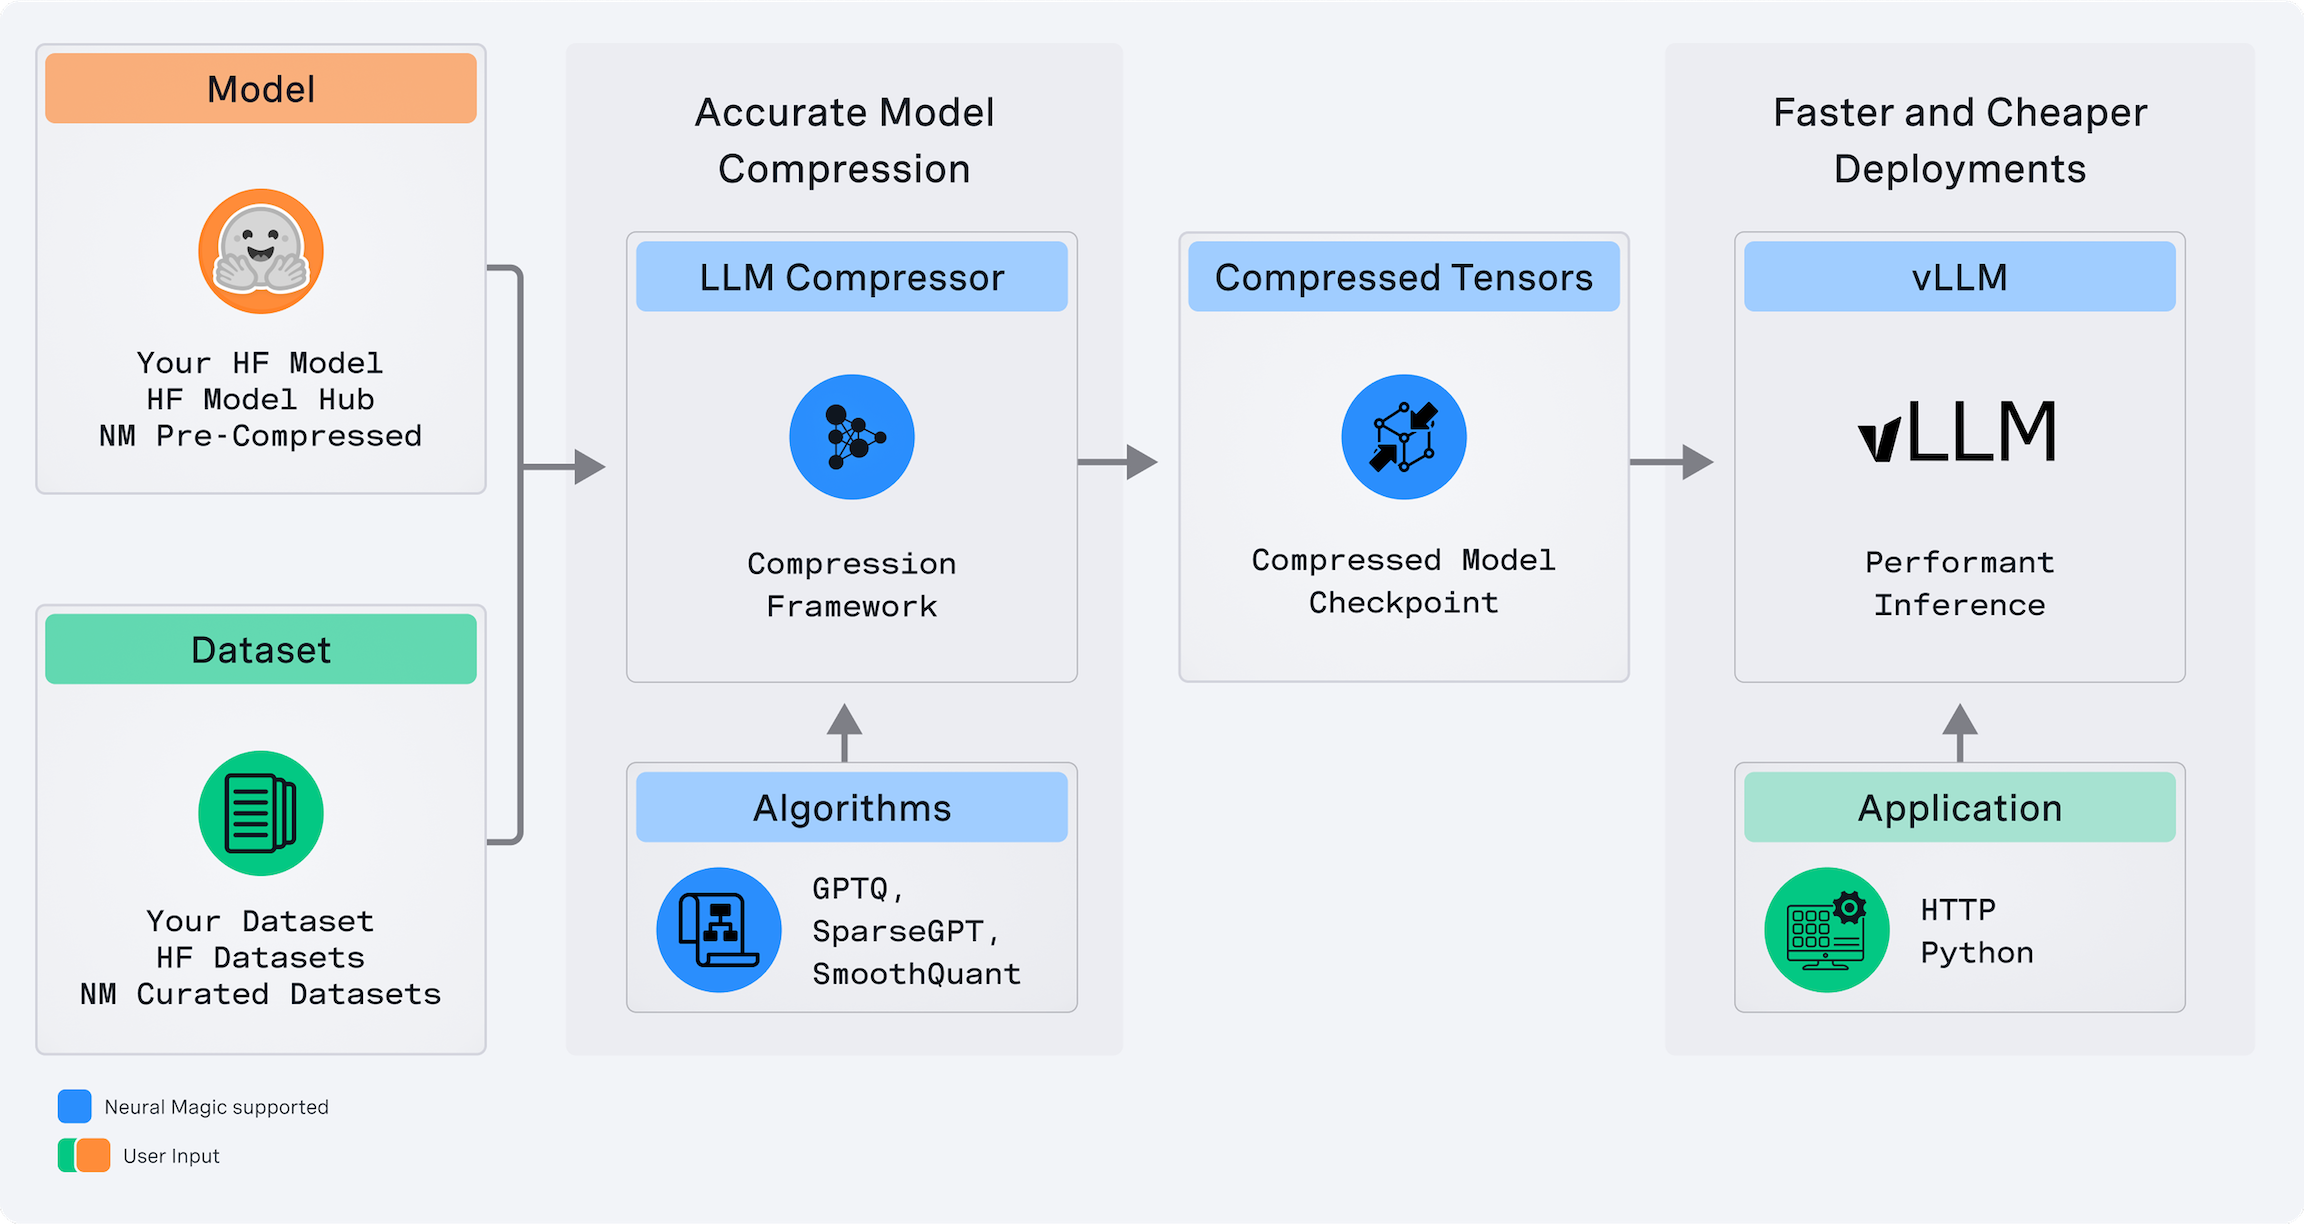
LLM Compressor is here: Faster inference with vLLM | Red Hat Developer

10 vLLM Serving Setups for High-QPS LLM APIs in Python | by Modexa | Medium
Advertisement Space (336x280)

Quickstart: High-throughput LLM inference with vLLM on Amazon EKS ...

Optimizing AI Performance: A Guide to Efficient LLM Deployment
Optimized LLM inference API for Mistral 7B using vLLM - a Lightning ...
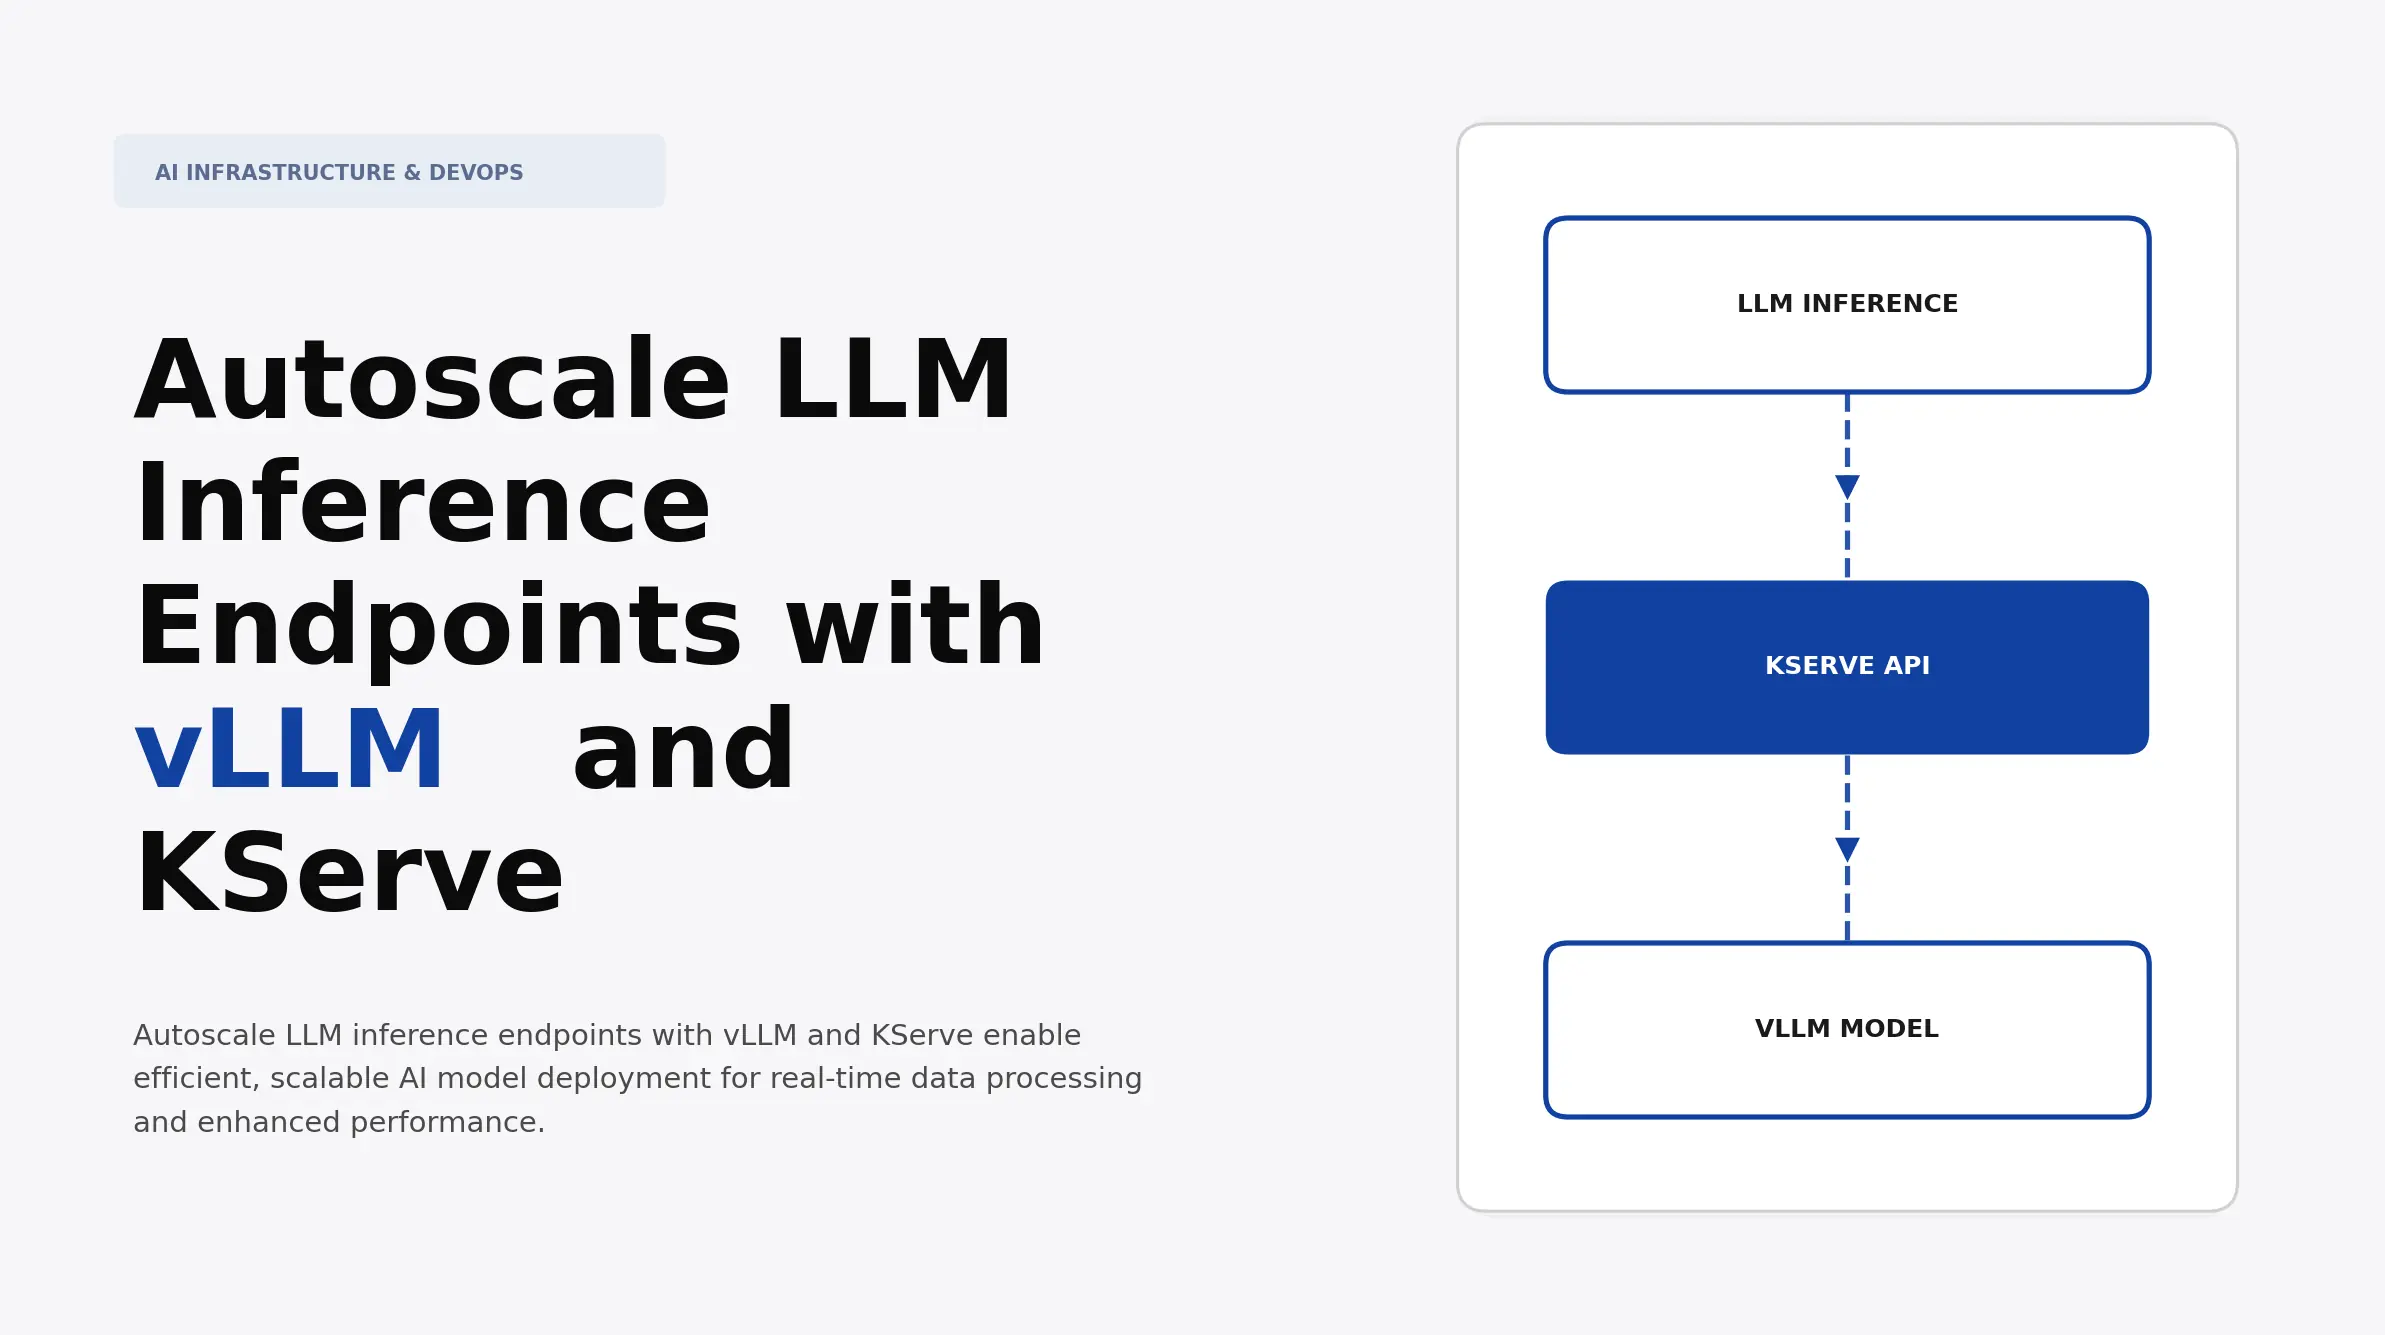
Autoscale LLM Inference Endpoints with vLLM and KServe | Atomic Loops
vLLM: High-Throughput LLM Inference Serving Engine | Inference Systems
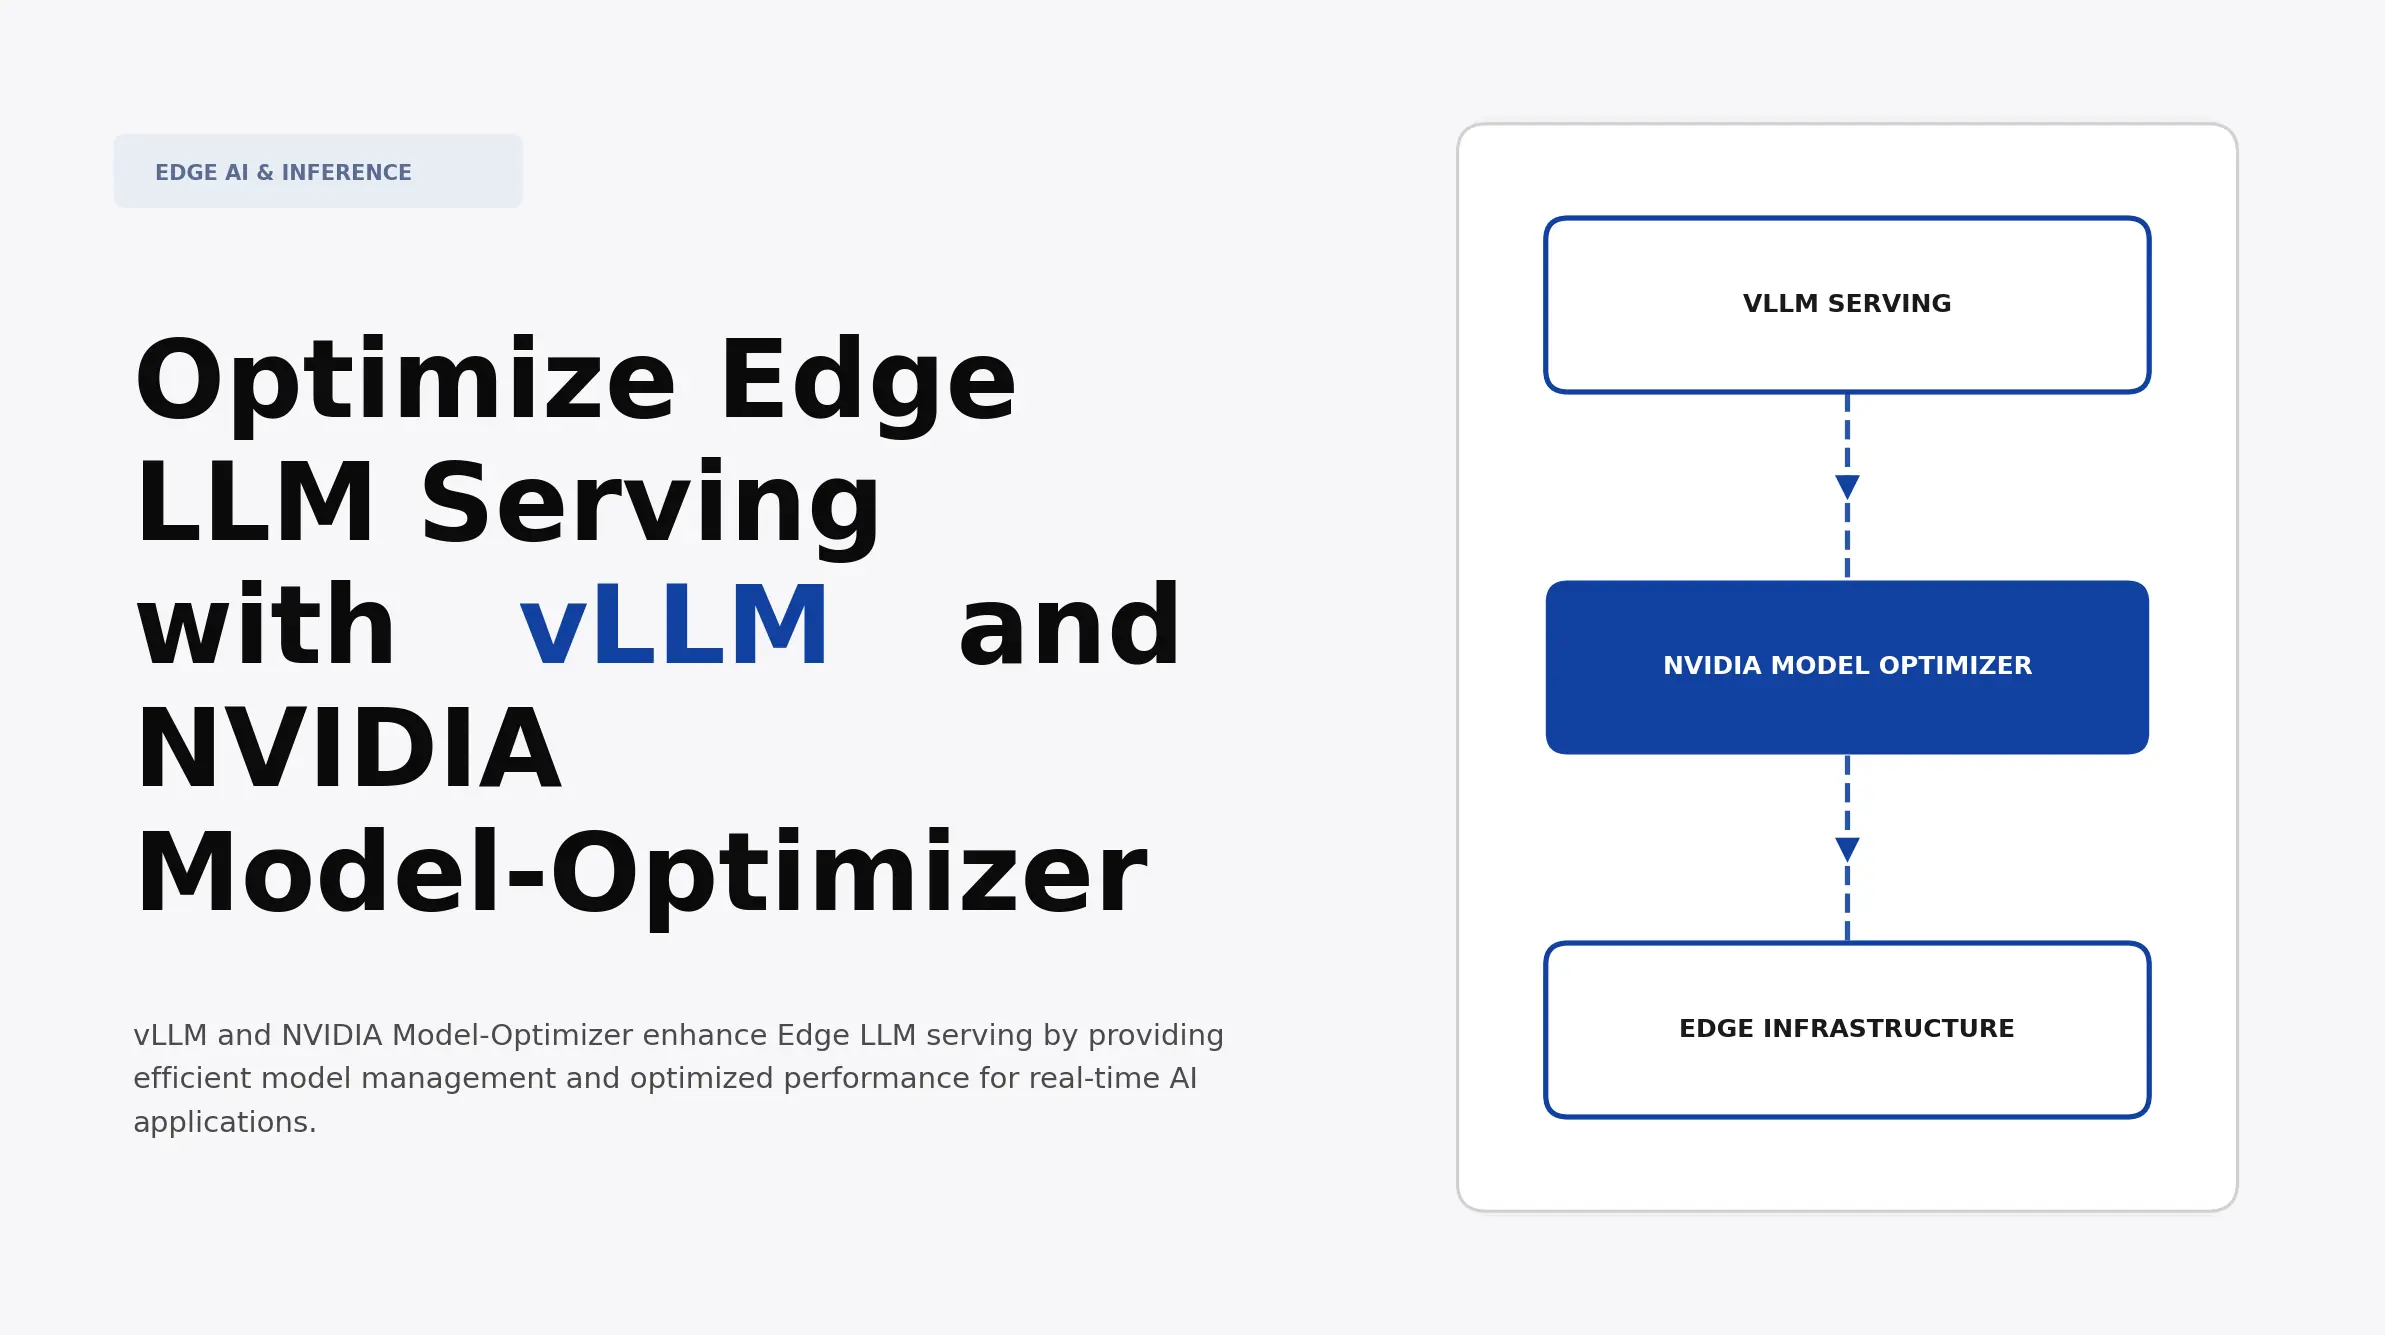
Optimize Edge LLM Serving with vLLM and NVIDIA Model-Optimizer | Atomic ...
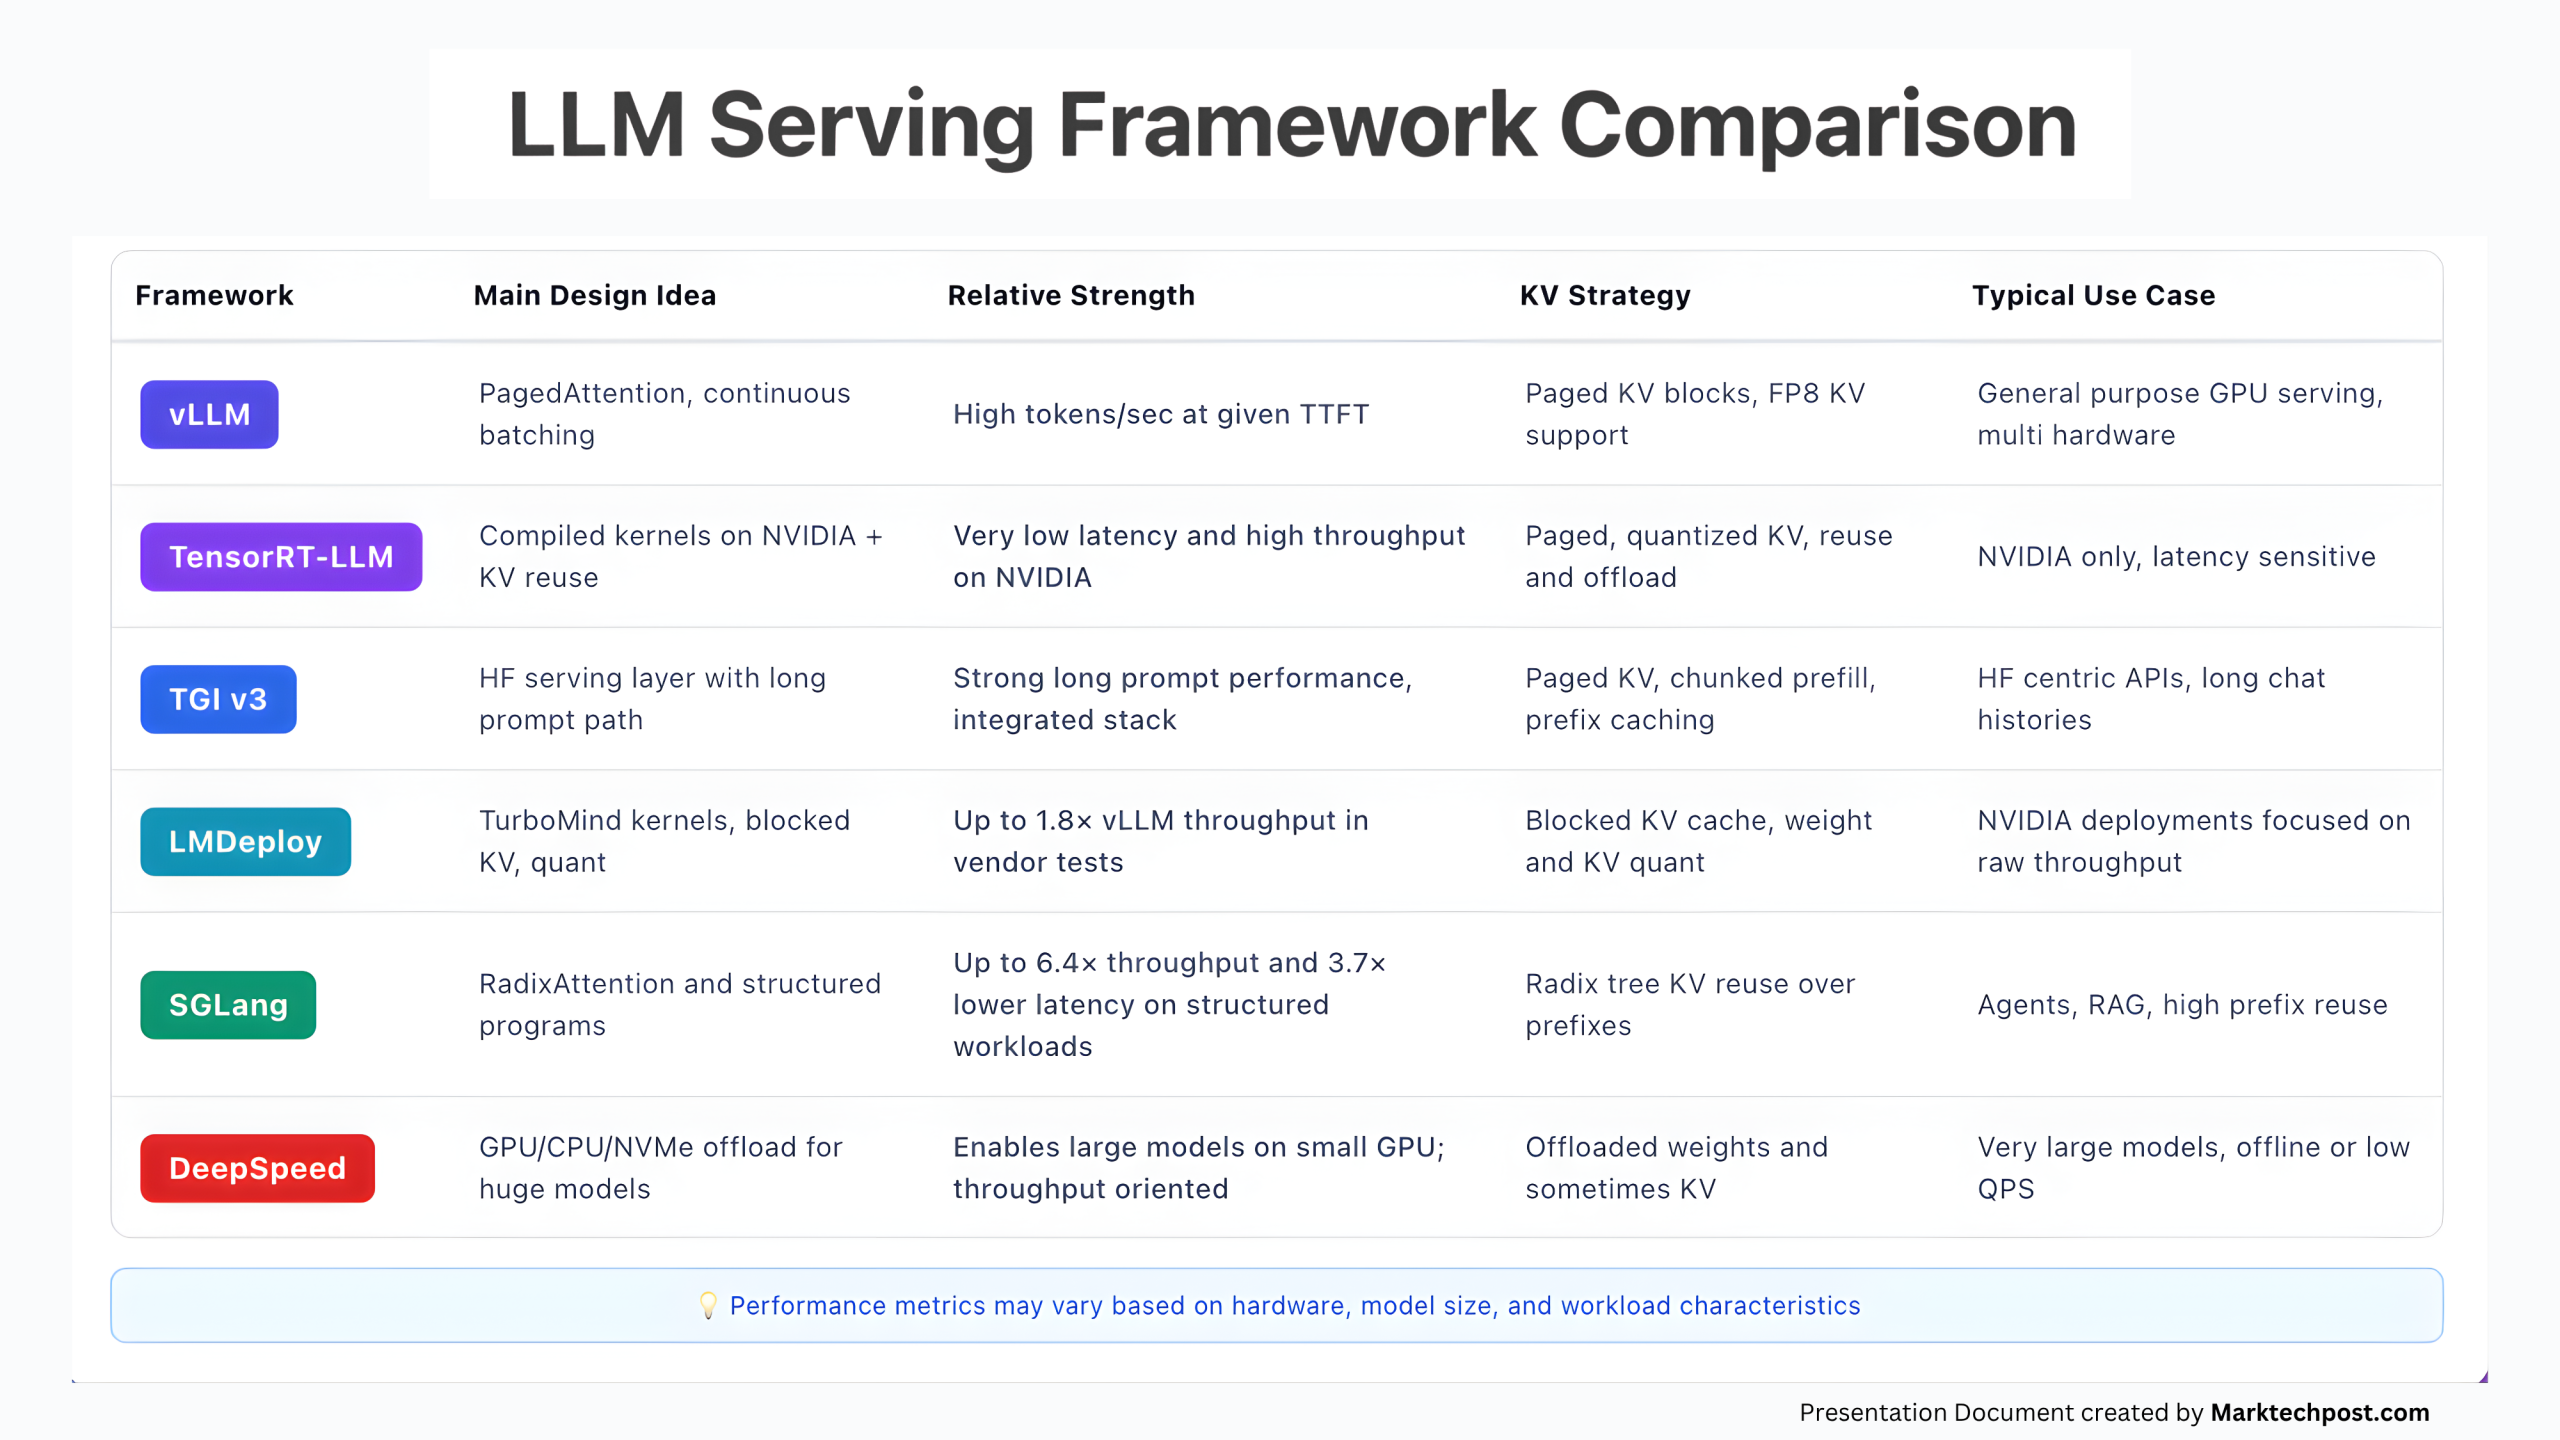
Comparing the Top 6 Inference Runtimes for LLM Serving in 2025 ...
Inside vLLM: Anatomy of a High-Throughput LLM Inference System | vLLM Blog

vLLM Review: High-Performance LLM Inference Engine for GPU ...

How the vLLM inference engine works? - DevOps Video | Pulse
Advertisement Space (336x280)

Meet vLLM: For faster, more efficient LLM inference and serving
Optimize LLM inference with vLLM | Sebae Videos
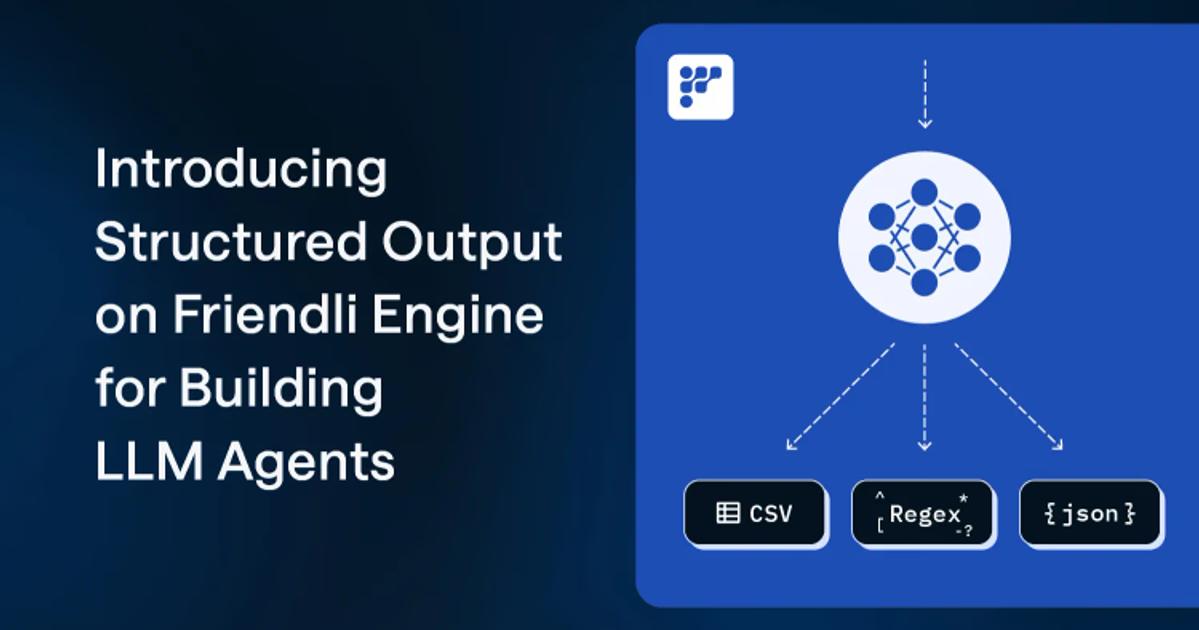
Introducing Structured Output on Friendli Inference for Building LLM Agents

Install vLLM on Linux for Production LLM Serving (2026 Guide)

How the VLLM inference engine works? - YouTube

Intelligent Inference Scheduling with vLLM & llm-d: Next-Gen LLM Model ...