
Efficient Kv Cache Spillover Management On Memory Constrained Gpu For

Efficient KV Cache Spillover Management on Memory-Constrained GPU for ...

Efficient KV Cache Spillover Management on Memory-Constrained GPU for ...
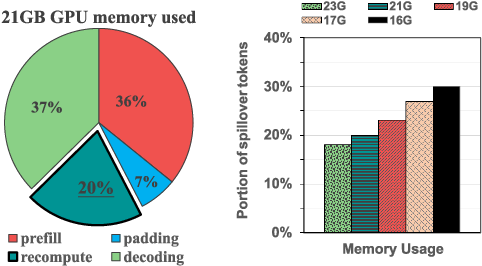
Figure 1 from Efficient KV Cache Spillover Management on Memory ...

Figure 1 from Efficient KV Cache Spillover Management on Memory ...
Predictive Multi-Tier Memory Management for KV Cache in Large-Scale GPU ...
KV Cache Sizing — GPU Memory for LLM Serving | tutorialQ

Comparative Characterization of KV Cache Management Strategies for LLM ...
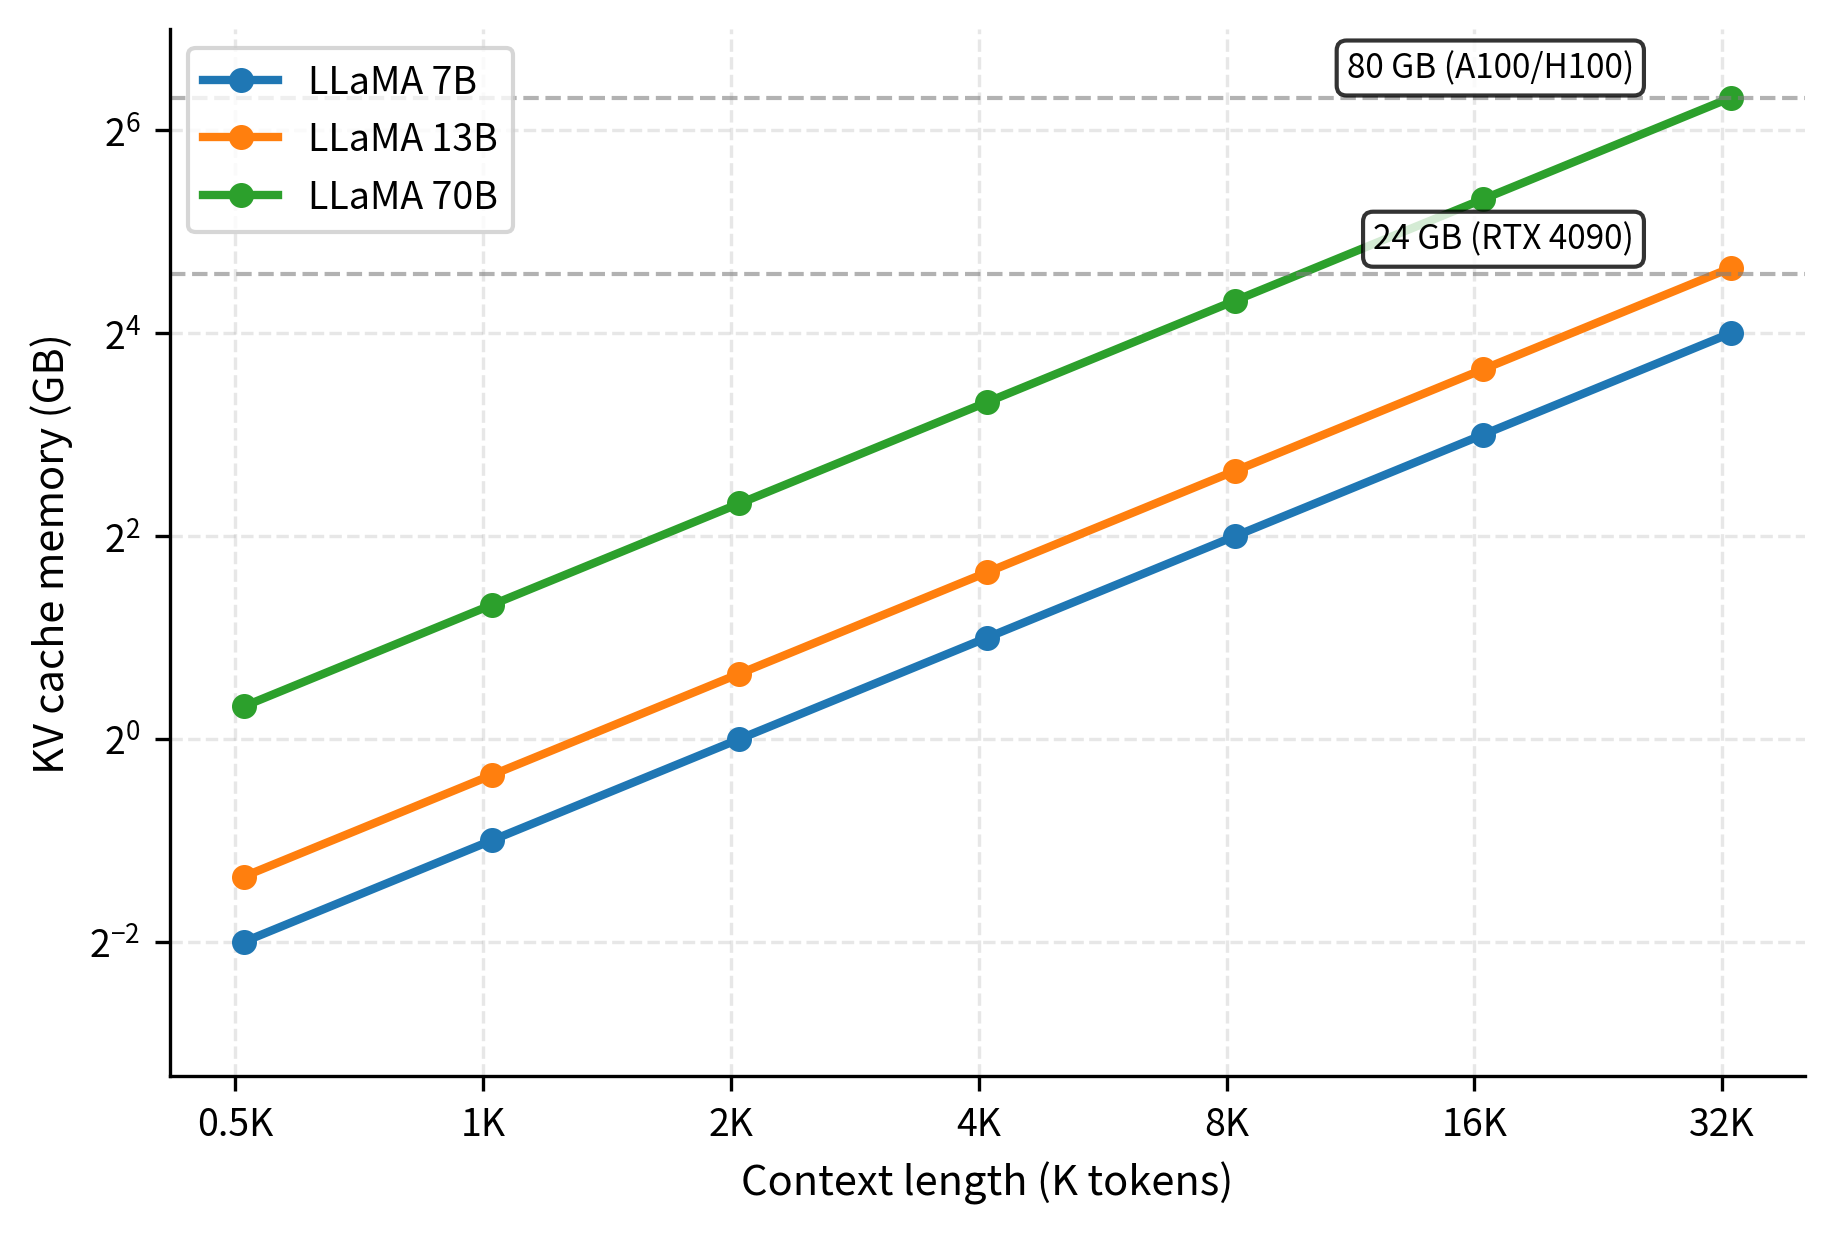
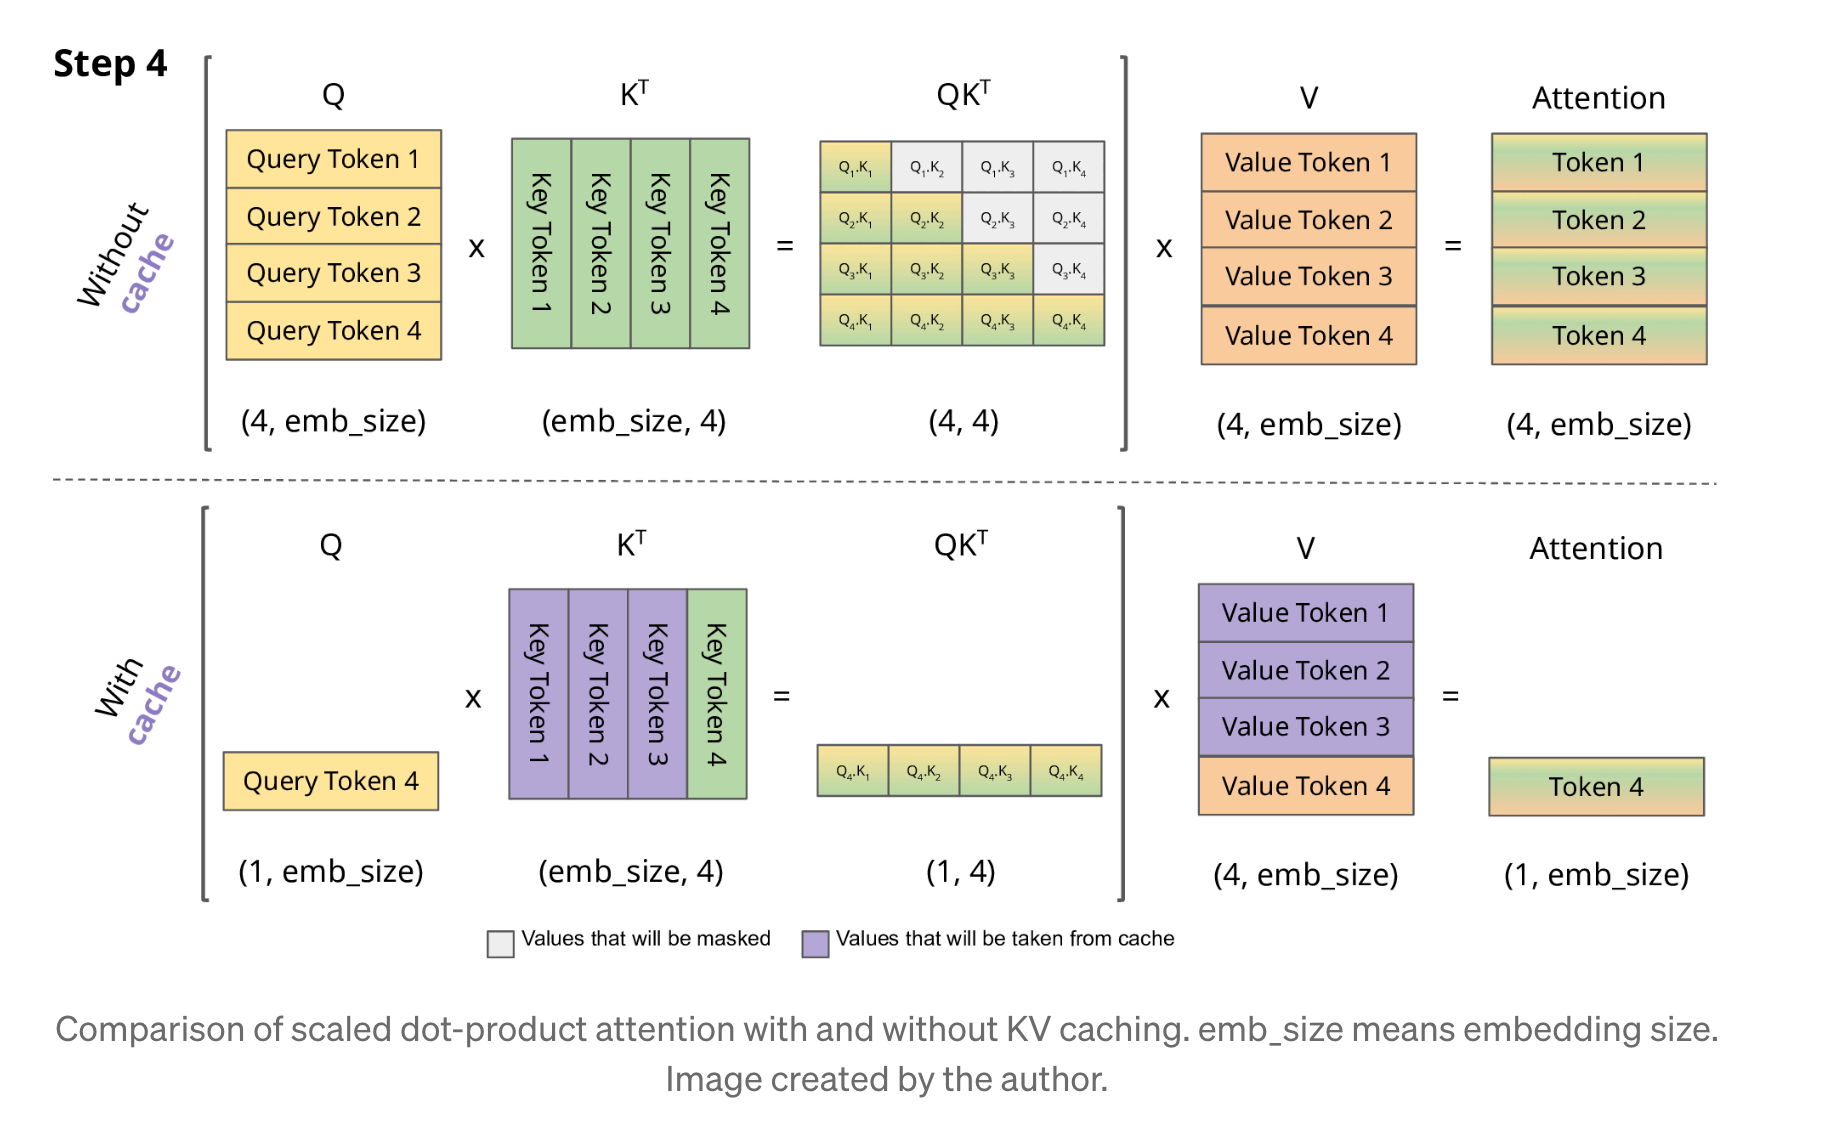
KV Cache Explained: Efficient Attention for LLM Generation ...
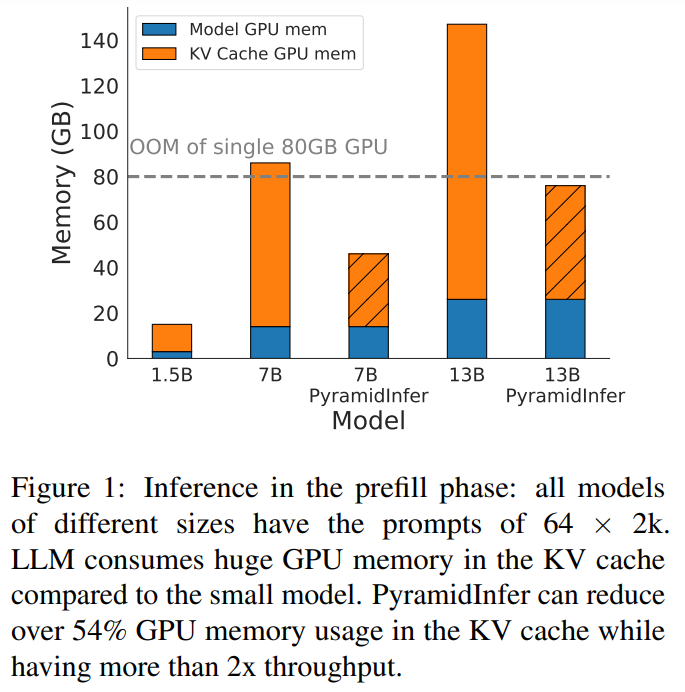
PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM ...

Advancements in Efficient KV Cache Quantization and Management — AI ...
Advertisement Space (300x250)

KEEP: A KV-Cache-Centric Memory Management System for Efficient ...
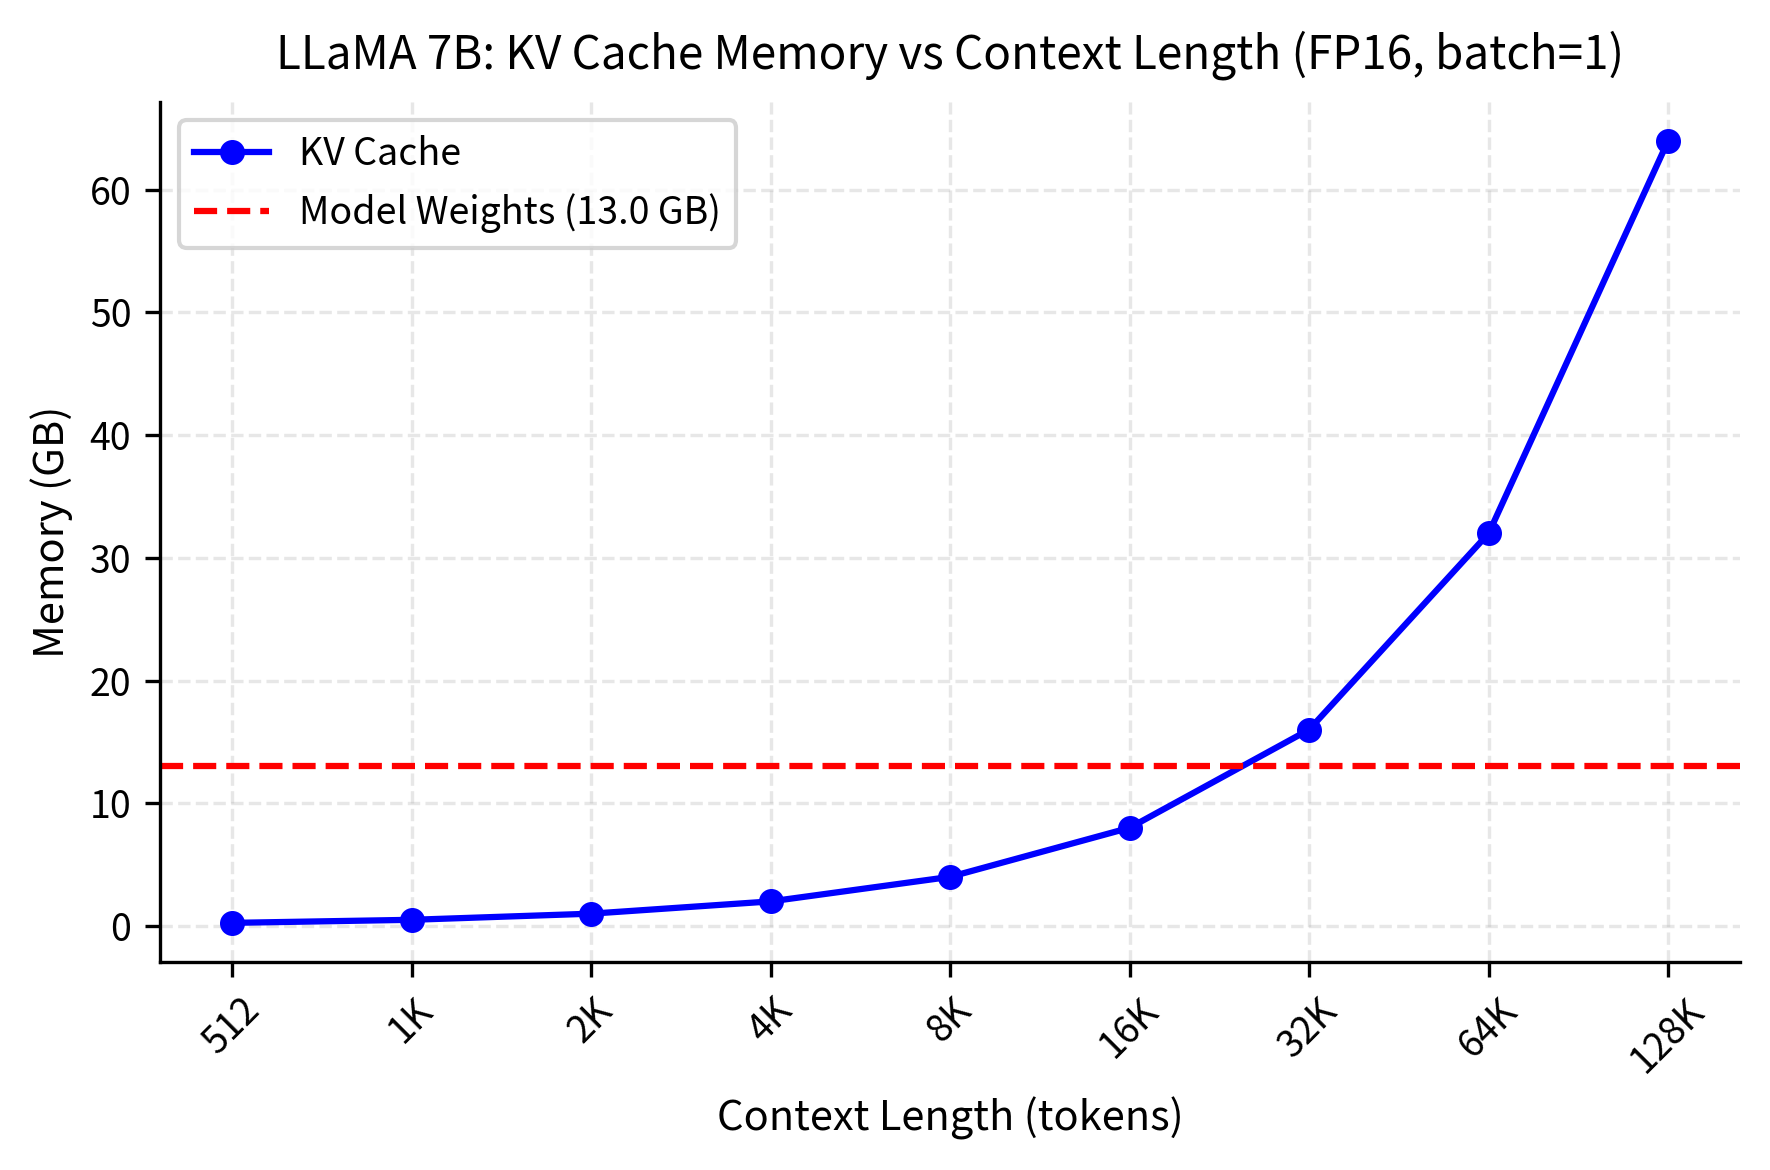
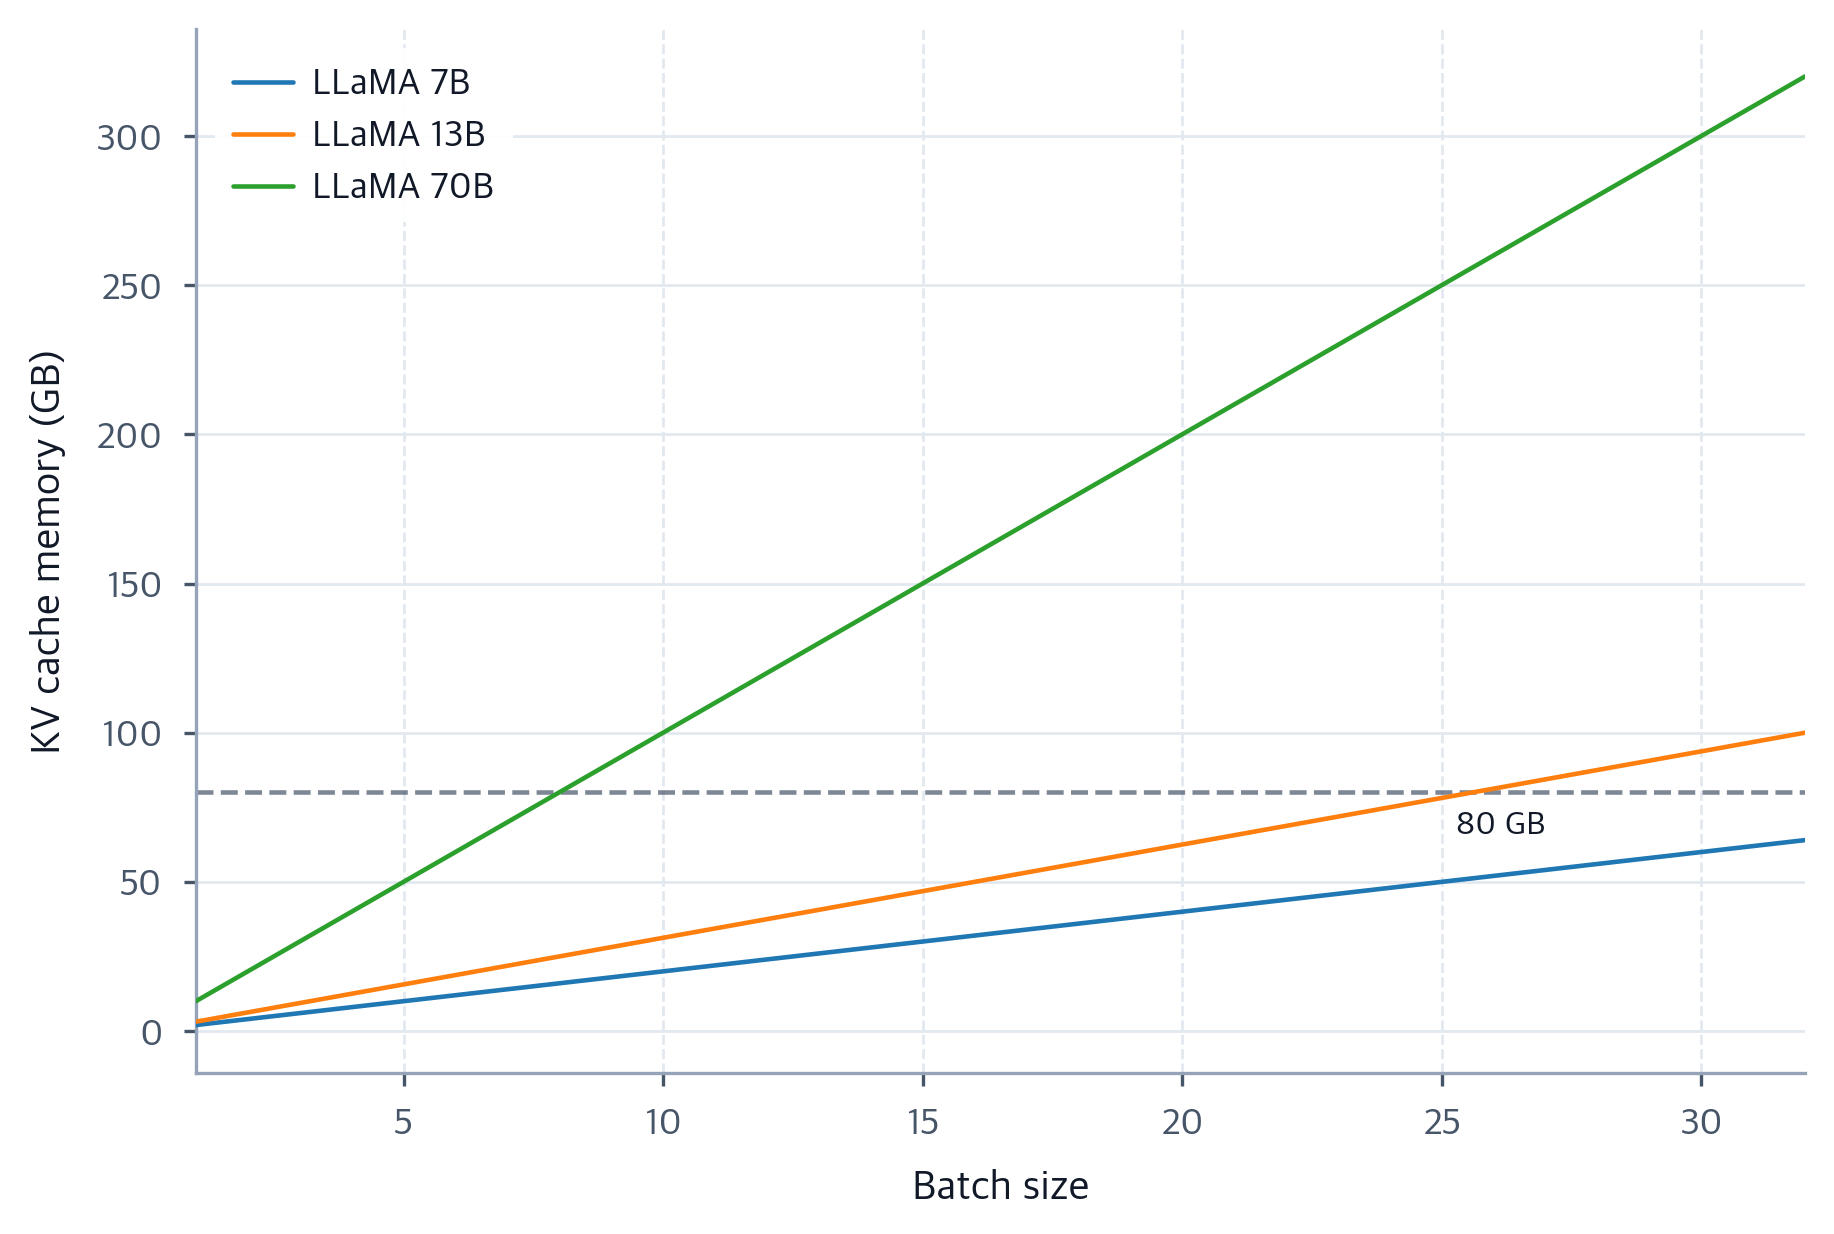
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...

LLM Inference Bottleneck: KV Cache vs GPU Memory | Osama Altaf posted ...
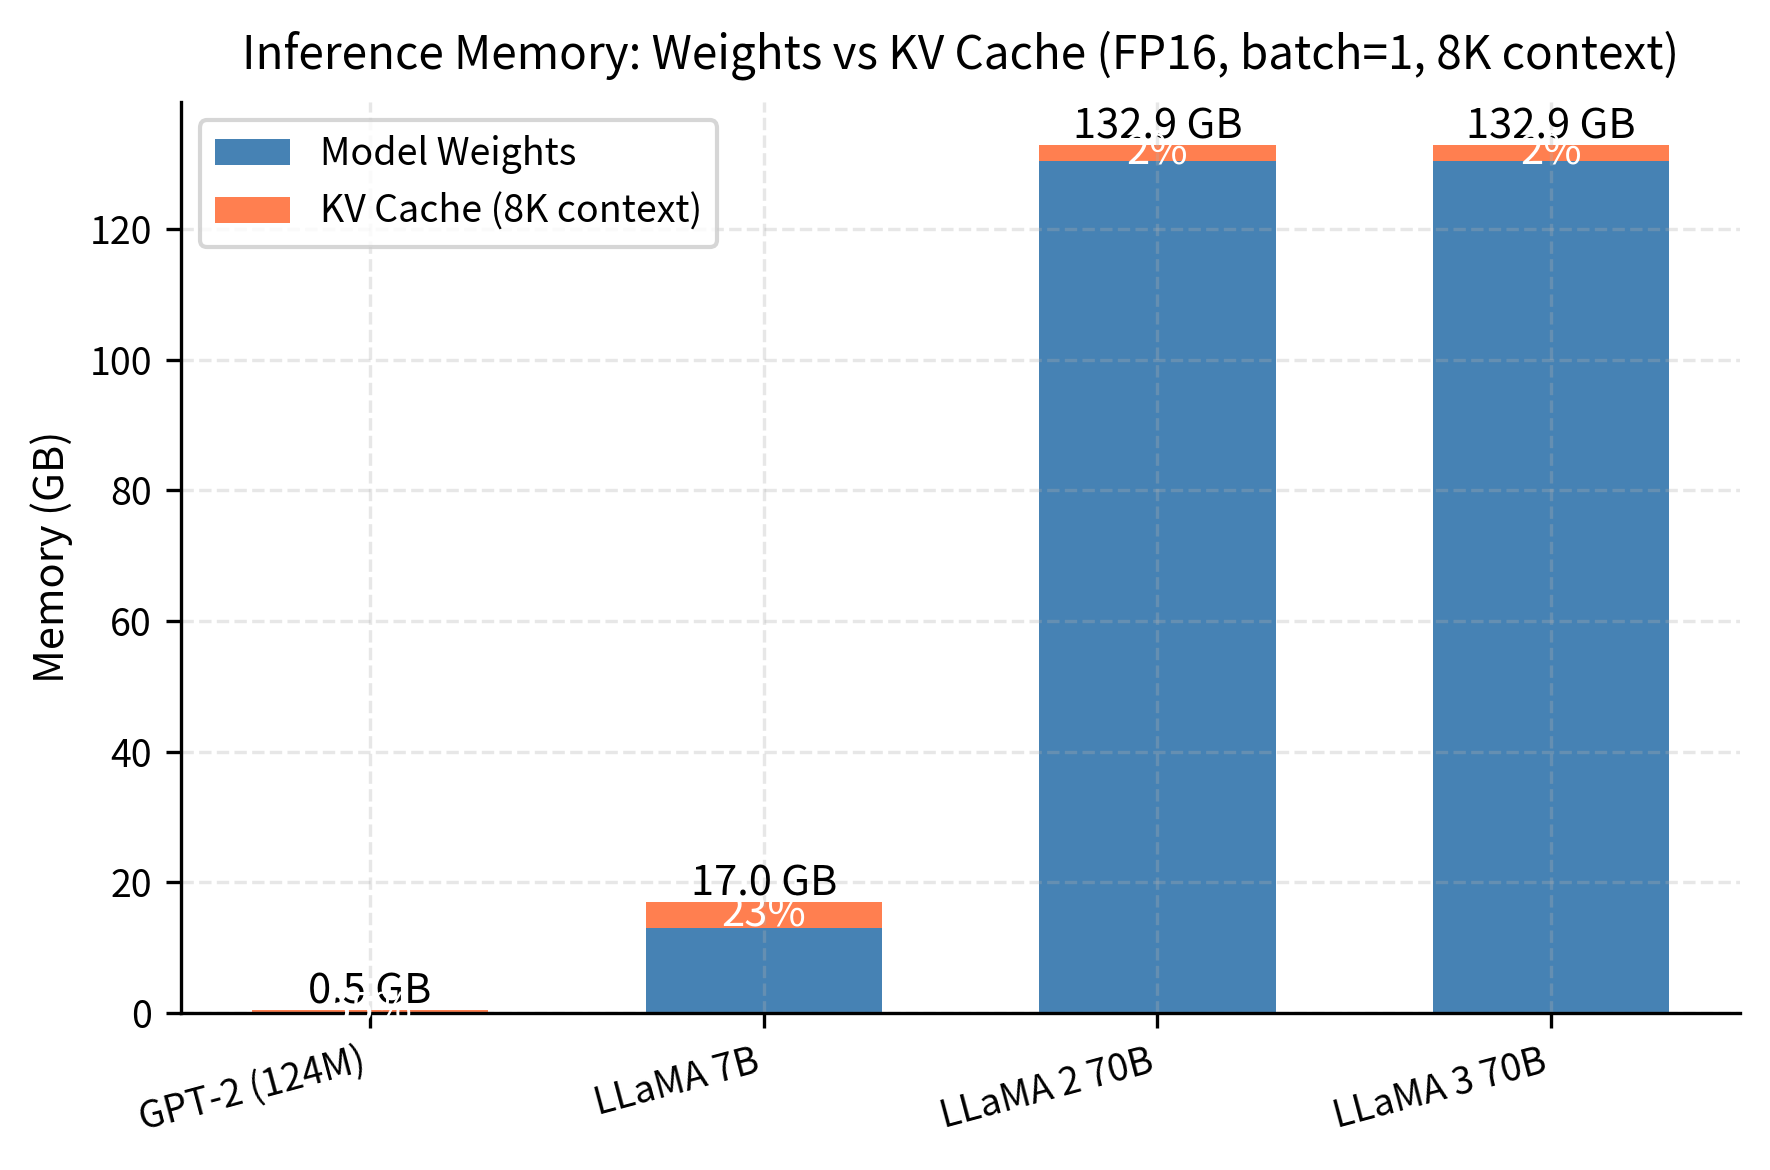
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...

KEEP: A KV-Cache-Centric Memory Management System for Efficient ...

Comparative Characterization of KV Cache Management Strategies for LLM ...

Comparative Characterization of KV Cache Management Strategies for LLM ...
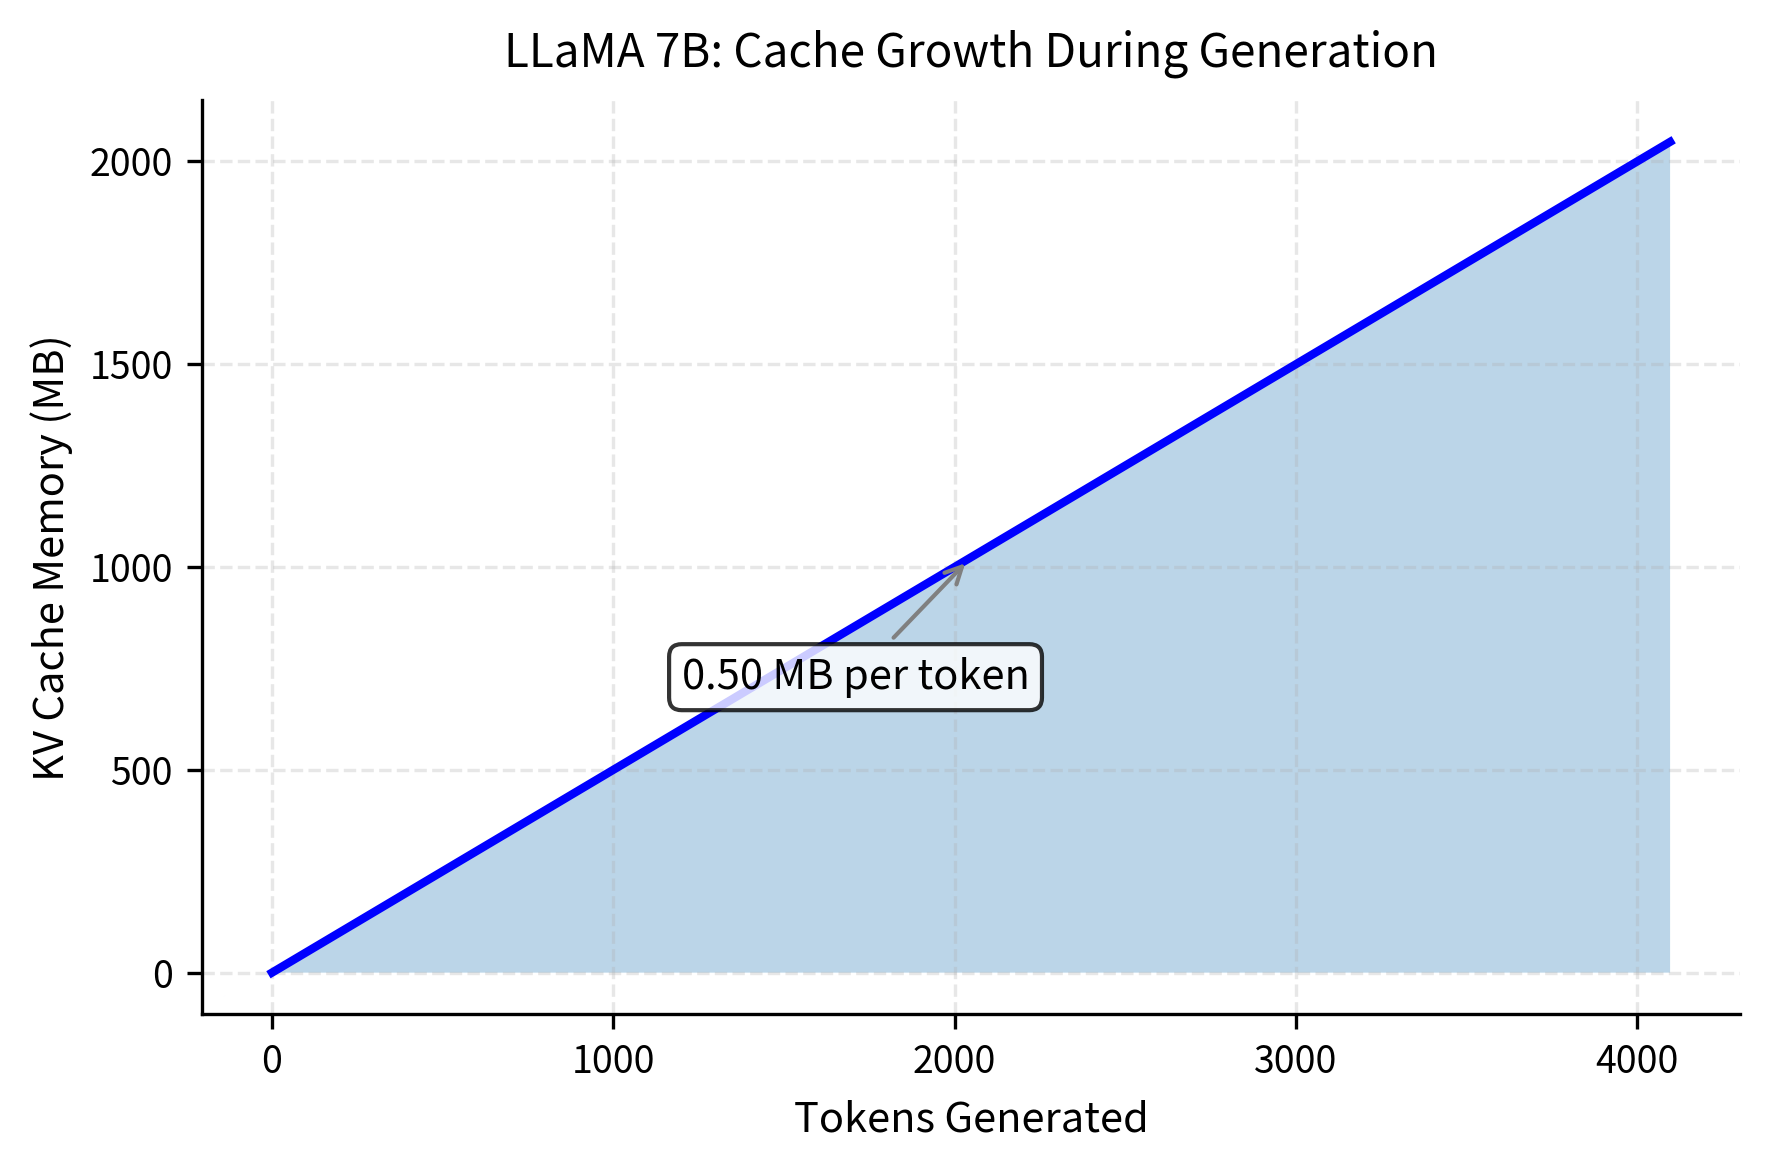
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference
KV Cache Optimization: Serve 10x More Users on the Same GPU (2026 ...
Advertisement Space (336x280)
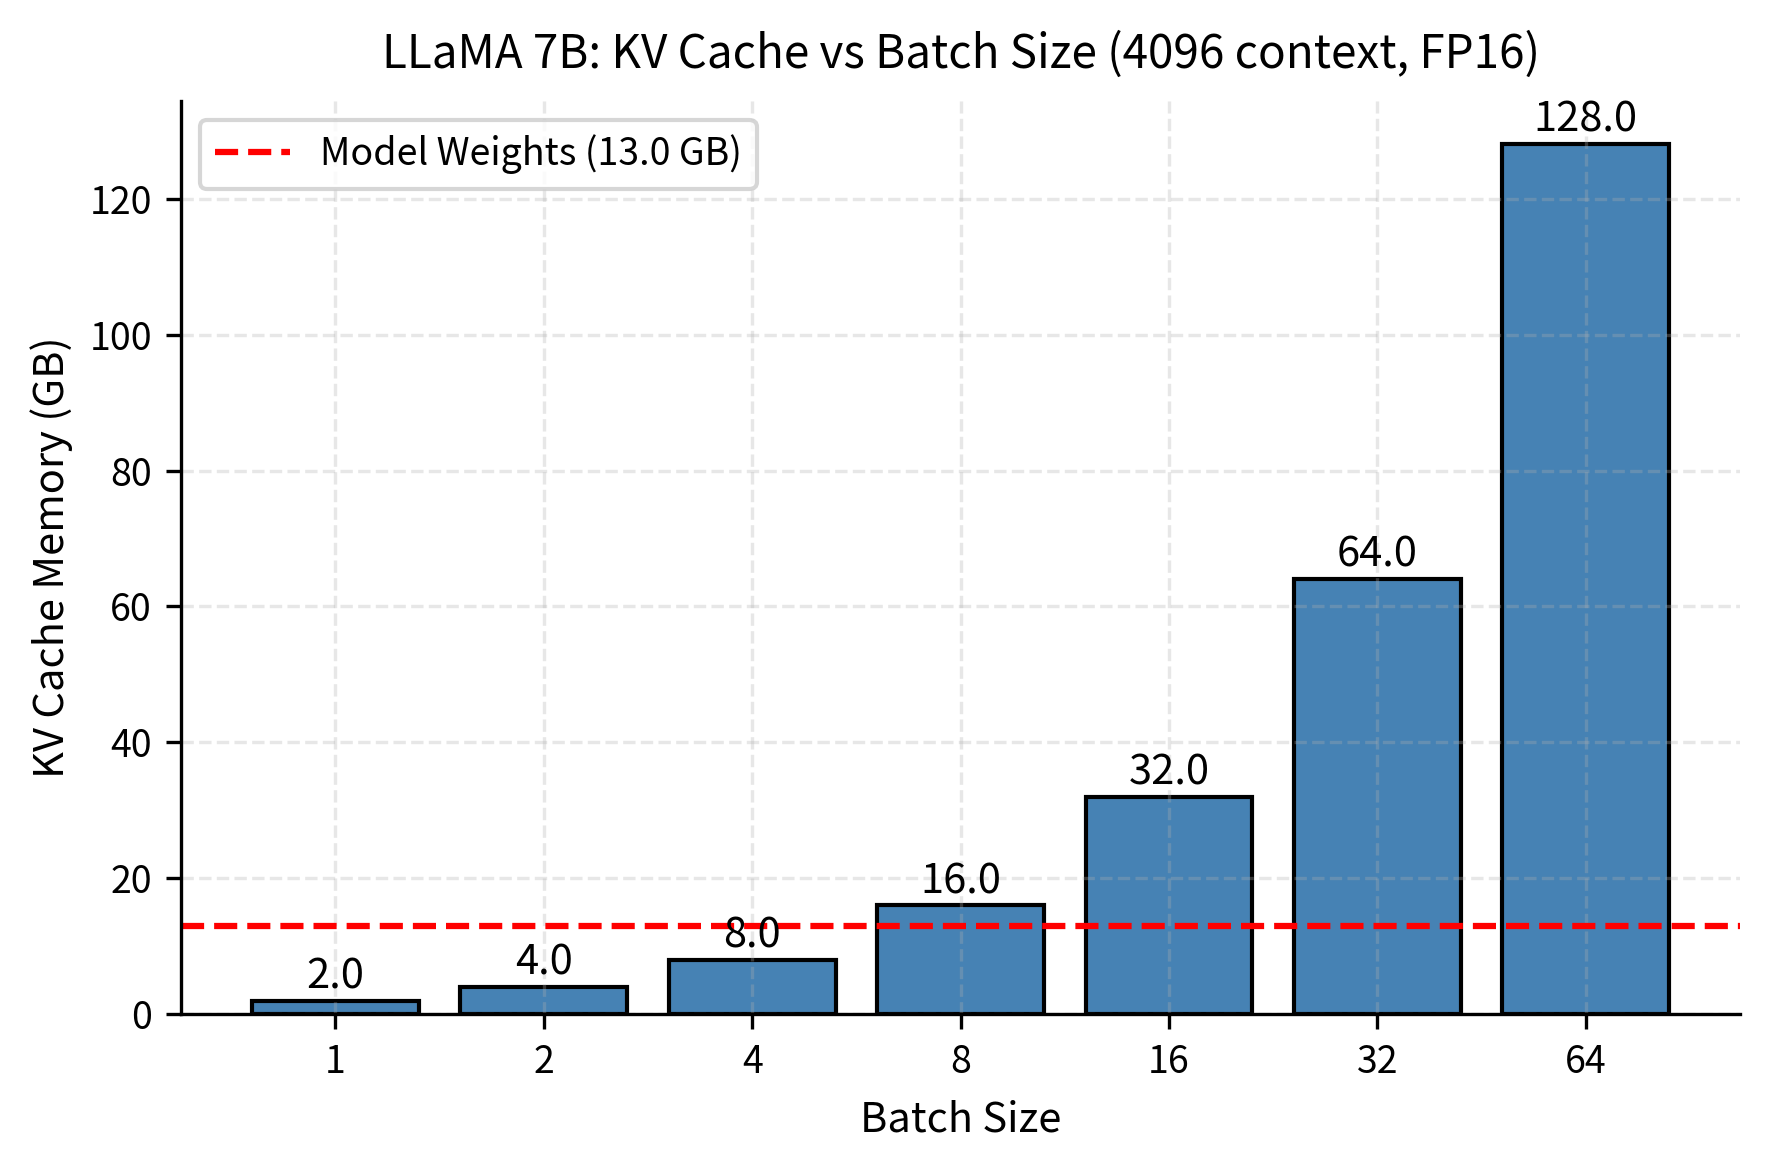
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...

Figure 1 from XKV: Personalized KV Cache Memory Reduction for Long ...
[논문 리뷰] Efficient Memory Management for Large Language Model Serving ...
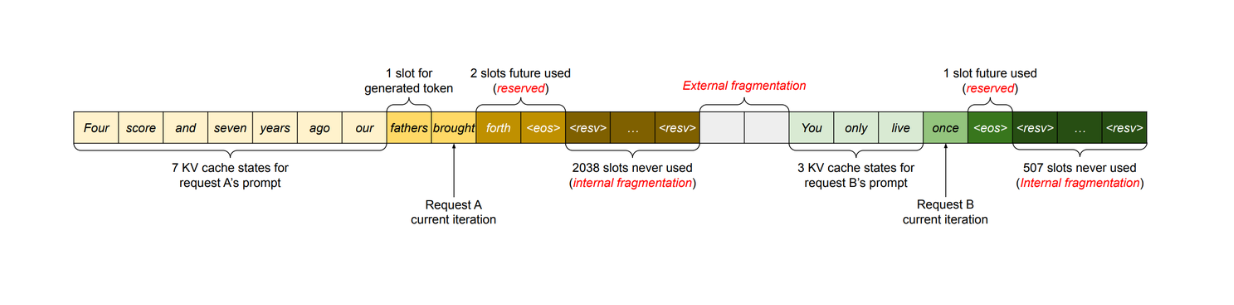
Efficient Memory Management for Large Language Model Serving with ...
KV-Cache Optimization: Efficient Memory Management for Long Sequences ...

KV Cache Reuse - The GPU Memory Game
KV Cache Explained: Efficient Attention for LLM Generation ...

LRAgent: Efficient KV Cache Sharing for Multi-LoRA LLM Agents | AI ...
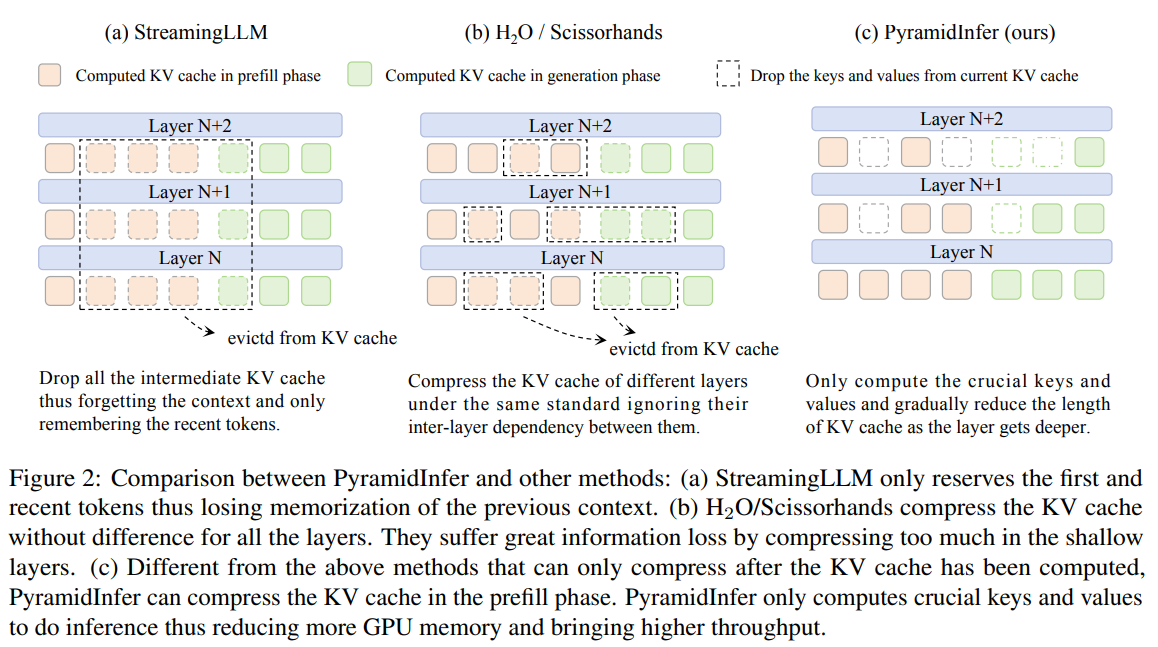
PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM ...

[论文评述] SparKV: Overhead-Aware KV Cache Loading for Efficient On-Device ...
Advertisement Space (336x280)

Paper page - LMCache: An Efficient KV Cache Layer for Enterprise-Scale ...

GEAR: An Efficient KV Cache Compression Recipe for Near-Lossless ...

KVSharer: method for efficient LLM inference via dissimilar KV Cache ...
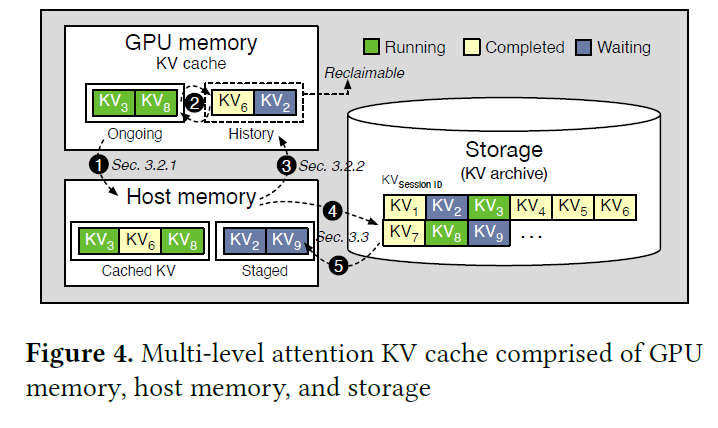
How KV Cache Works & Why It Eats Memory | by M | Foundation Models Deep ...

Tutti: Making SSD-Backed KV Cache Practical for Long-Context LLM Serving

Multi-Segment Attention: Enabling Efficient KV-Cache Management for ...