
Efficient Scaling Of Large Language Models With Mixture Of Experts And

Efficient scaling of large language models with mixture of experts and ...

Efficient scaling of large language models with mixture of experts and ...
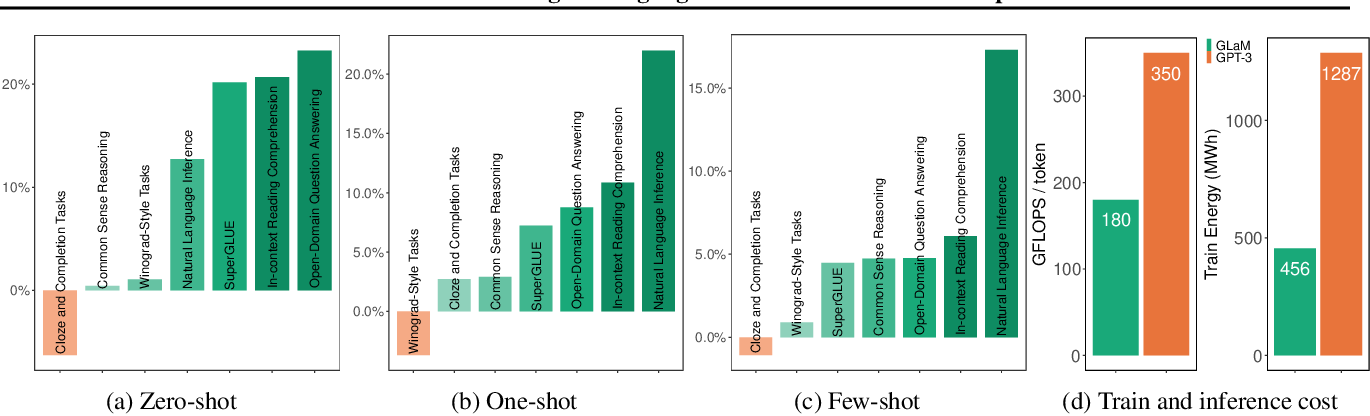
Figure 1 from GLaM: Efficient Scaling of Language Models with Mixture ...

Google Glam: Efficient Scaling of Language Models with Mixture of ...

GLaM: Efficient Scaling of Language Models with Mixture-of-Experts | DeepAI
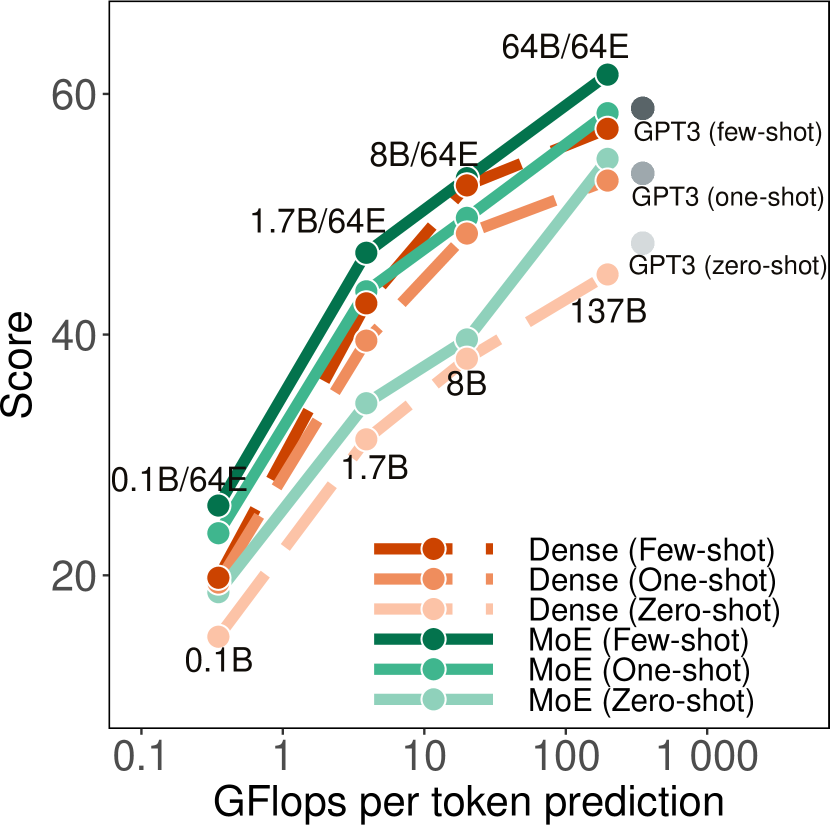
[2112.06905] GLaM: Efficient Scaling of Language Models with Mixture-of ...
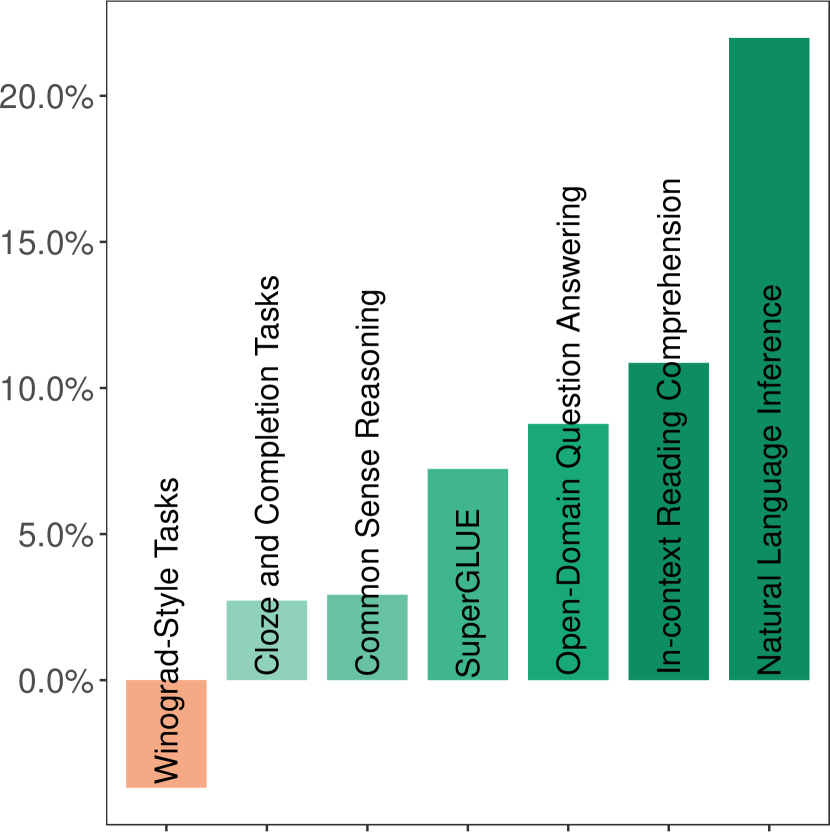
[2112.06905] GLaM: Efficient Scaling of Language Models with Mixture-of ...
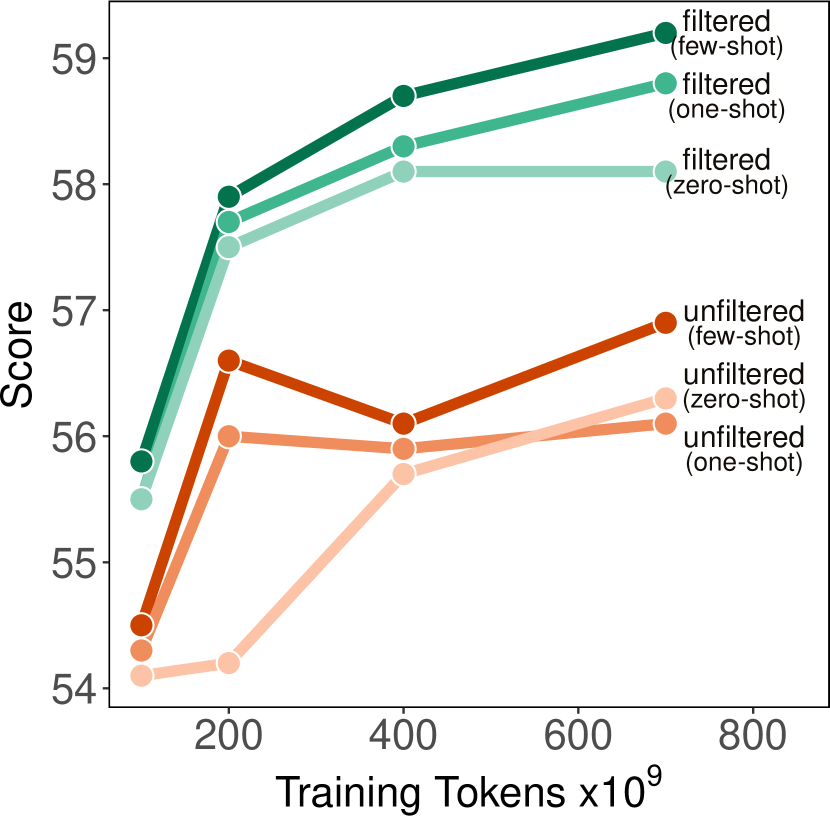
[2112.06905] GLaM: Efficient Scaling of Language Models with Mixture-of ...
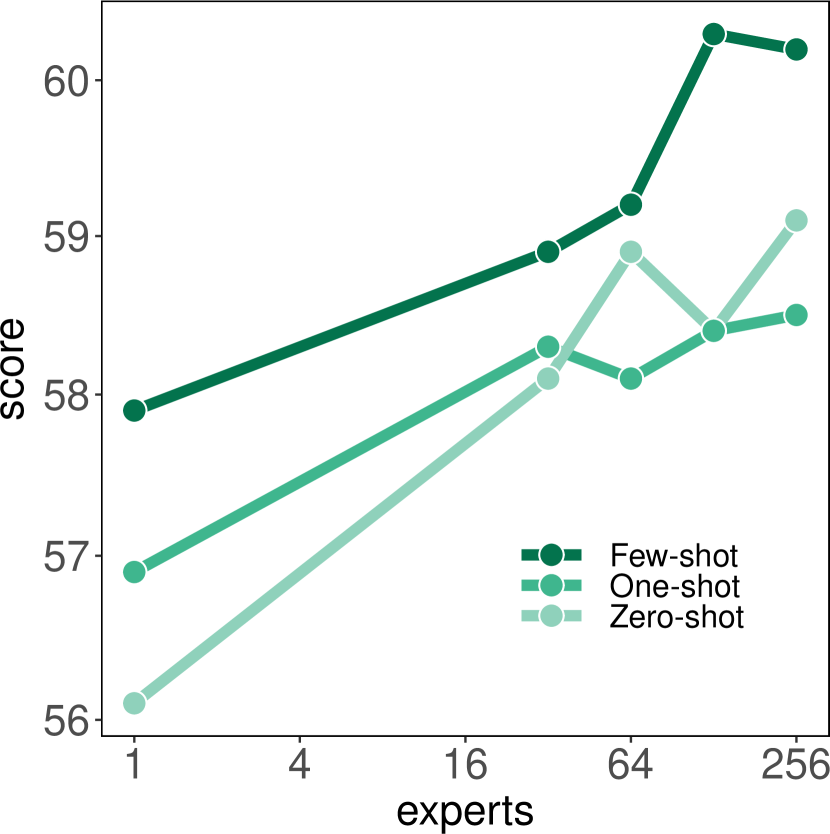
[2112.06905] GLaM: Efficient Scaling of Language Models with Mixture-of ...
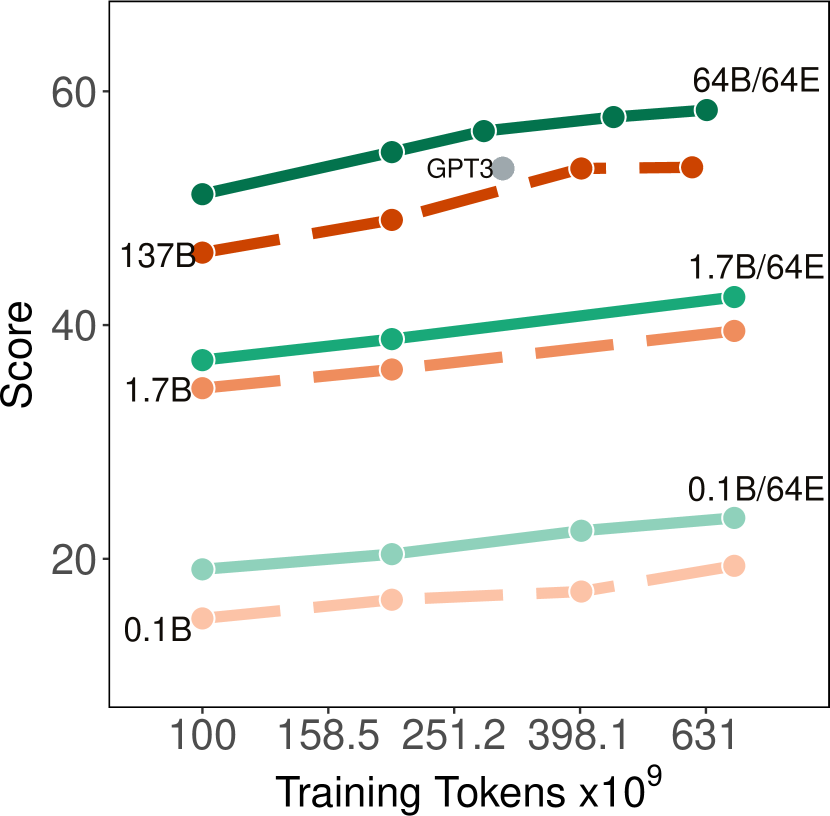
[2112.06905] GLaM: Efficient Scaling of Language Models with Mixture-of ...
Advertisement Space (300x250)

(PDF) GLaM: Efficient Scaling of Language Models with Mixture-of-Experts

GLaM: Efficient Scaling of Language Models with Mixture-of-Experts
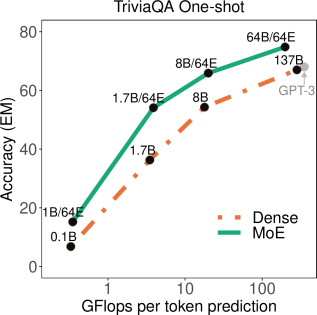
GLaM: Efficient Scaling of Language Models with Mixture-of-Experts | DeepAI

Mixture of Experts in Large Language Models | AI Research Paper Details

(PDF) Efficient Large Scale Language Modeling with Mixtures of Experts

GLaM: Efficient Scaling of Language Models with Mixture-of-Experts
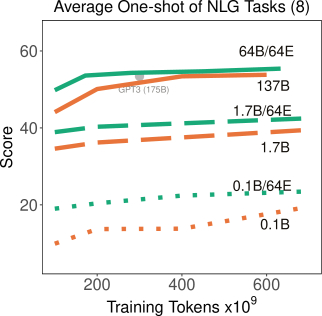
GLaM: Efficient Scaling of Language Models with Mixture-of-Experts | DeepAI

GLaM: Efficient Scaling of Language Models with Mixture-of-Experts | DeepAI

Bayesian Mixture of Experts For Large Language Models | AI Research ...

Paper page - GLaM: Efficient Scaling of Language Models with Mixture-of ...
Advertisement Space (336x280)
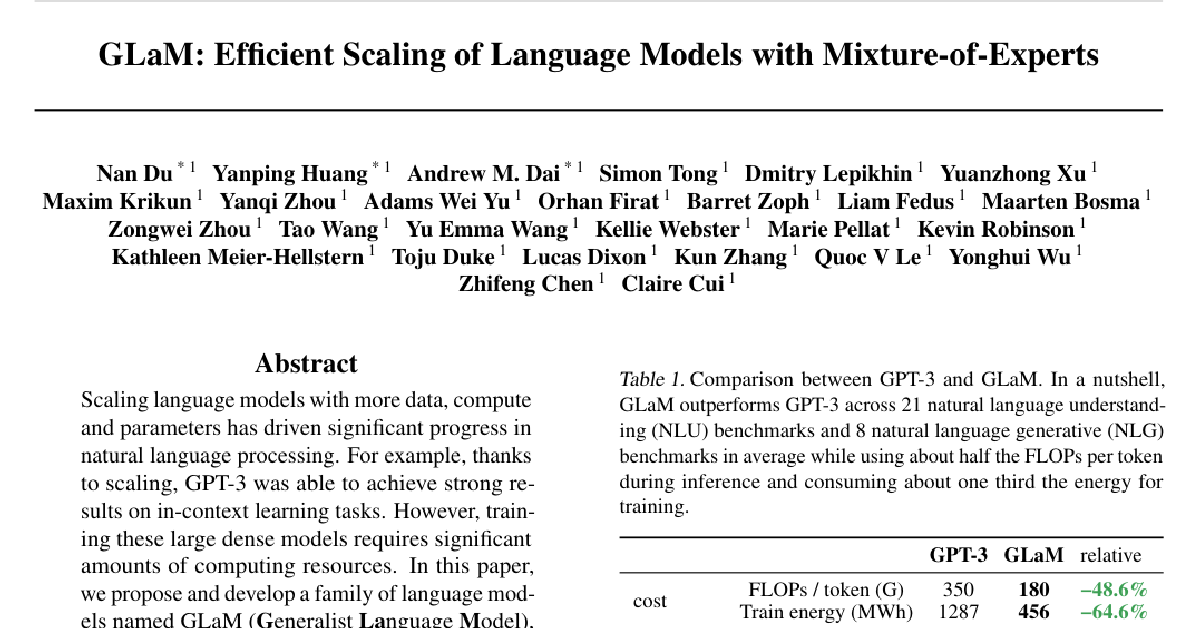
GLaM: Efficient Scaling of Language Models with Mixture-of-Experts ...

GLaM: Efficient Scaling of Language Models with Mixture-of-Experts

GLaM: Efficient Scaling of Language Models with Mixture-of-Experts | DeepAI

GLaM: Efficient Scaling of Language Models with Mixture-of-Experts | DeepAI

A Survey On Mixture of Experts in Large Language Models | PDF | Machine ...
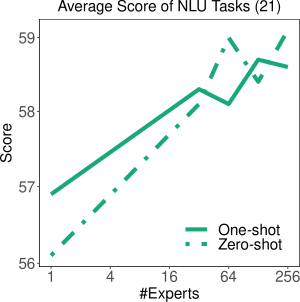
GLaM: Efficient Scaling of Language Models with Mixture-of-Experts | DeepAI

Scalable Pretraining of Large Mixture of Experts Language Models on ...

GLaM: Efficient Scaling of Language Models with Mixture-of-Experts
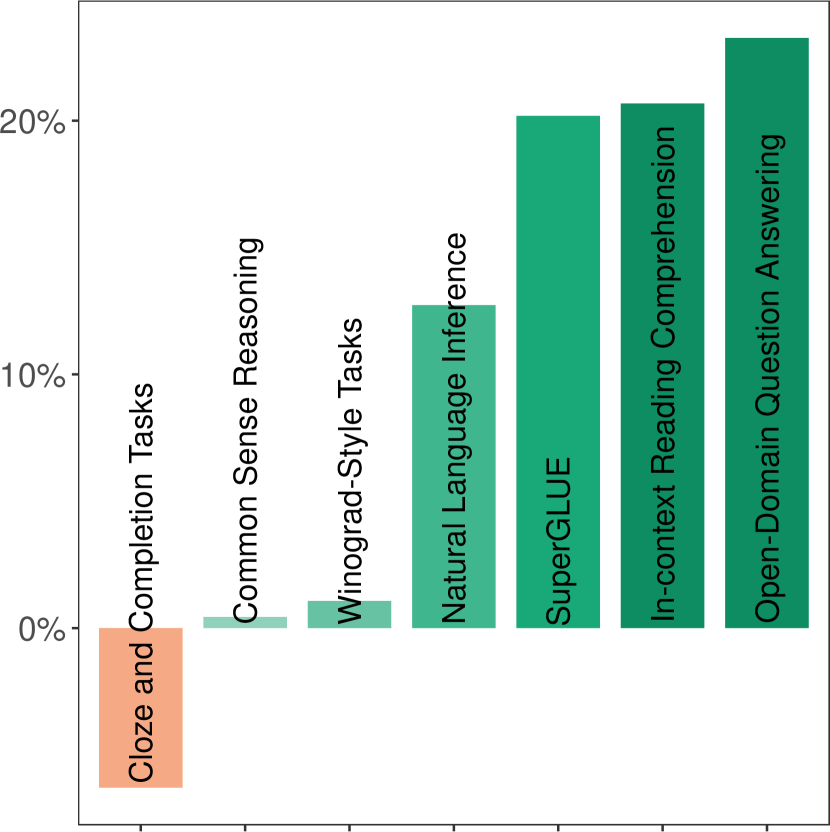
[2112.06905] GLaM: Efficient Scaling of Language Models with Mixture-of ...
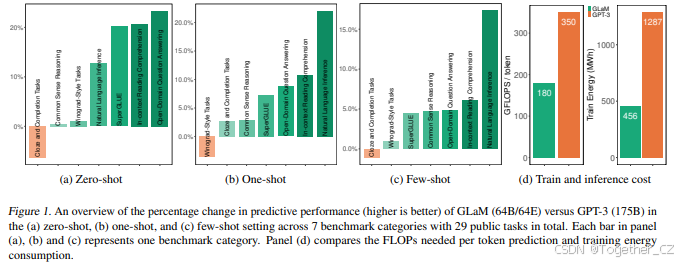
GLaM: Efficient Scaling of Language Models with Mixture-of-Experts——使用 ...
Advertisement Space (336x280)
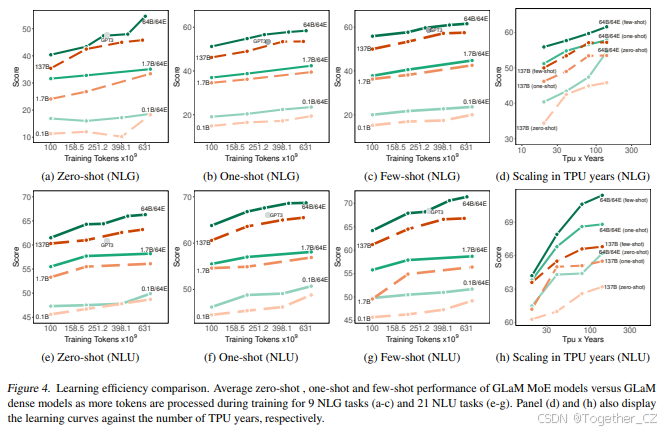
GLaM: Efficient Scaling of Language Models with Mixture-of-Experts——使用 ...

Efficient Scaling of Large Language Models Through Matrix ...
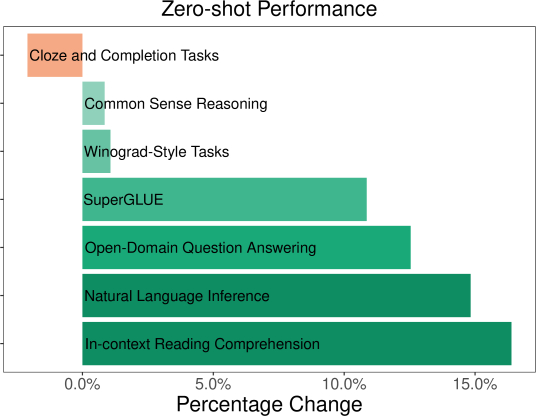
GLaM: Efficient Scaling of Language Models with Mixture-of-Experts | DeepAI
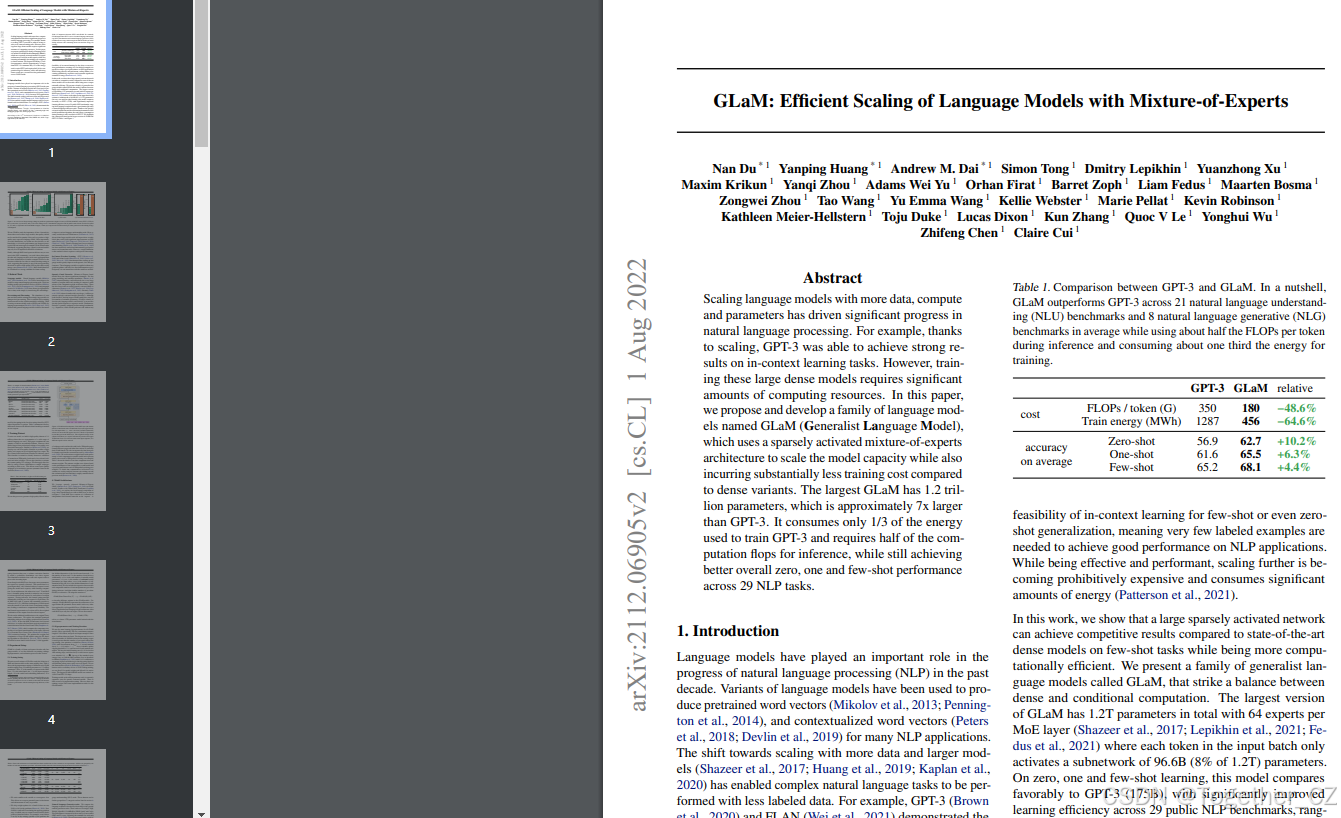
GLaM: Efficient Scaling of Language Models with Mixture-of-Experts——使用 ...
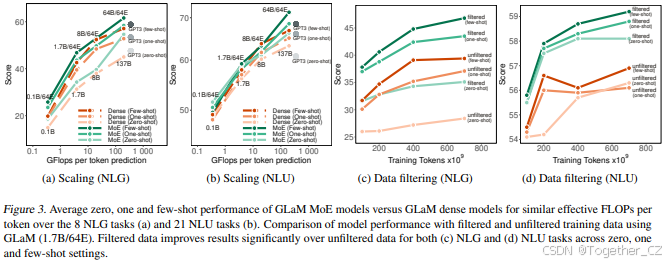
GLaM: Efficient Scaling of Language Models with Mixture-of-Experts——使用 ...

MoSE: Mixture of Slimmable Experts for Efficient and Adaptive Language ...