
Egformer An Enhanced Transformer Model With Efficient Attention

EGFormer: An Enhanced Transformer Model with Efficient Attention ...
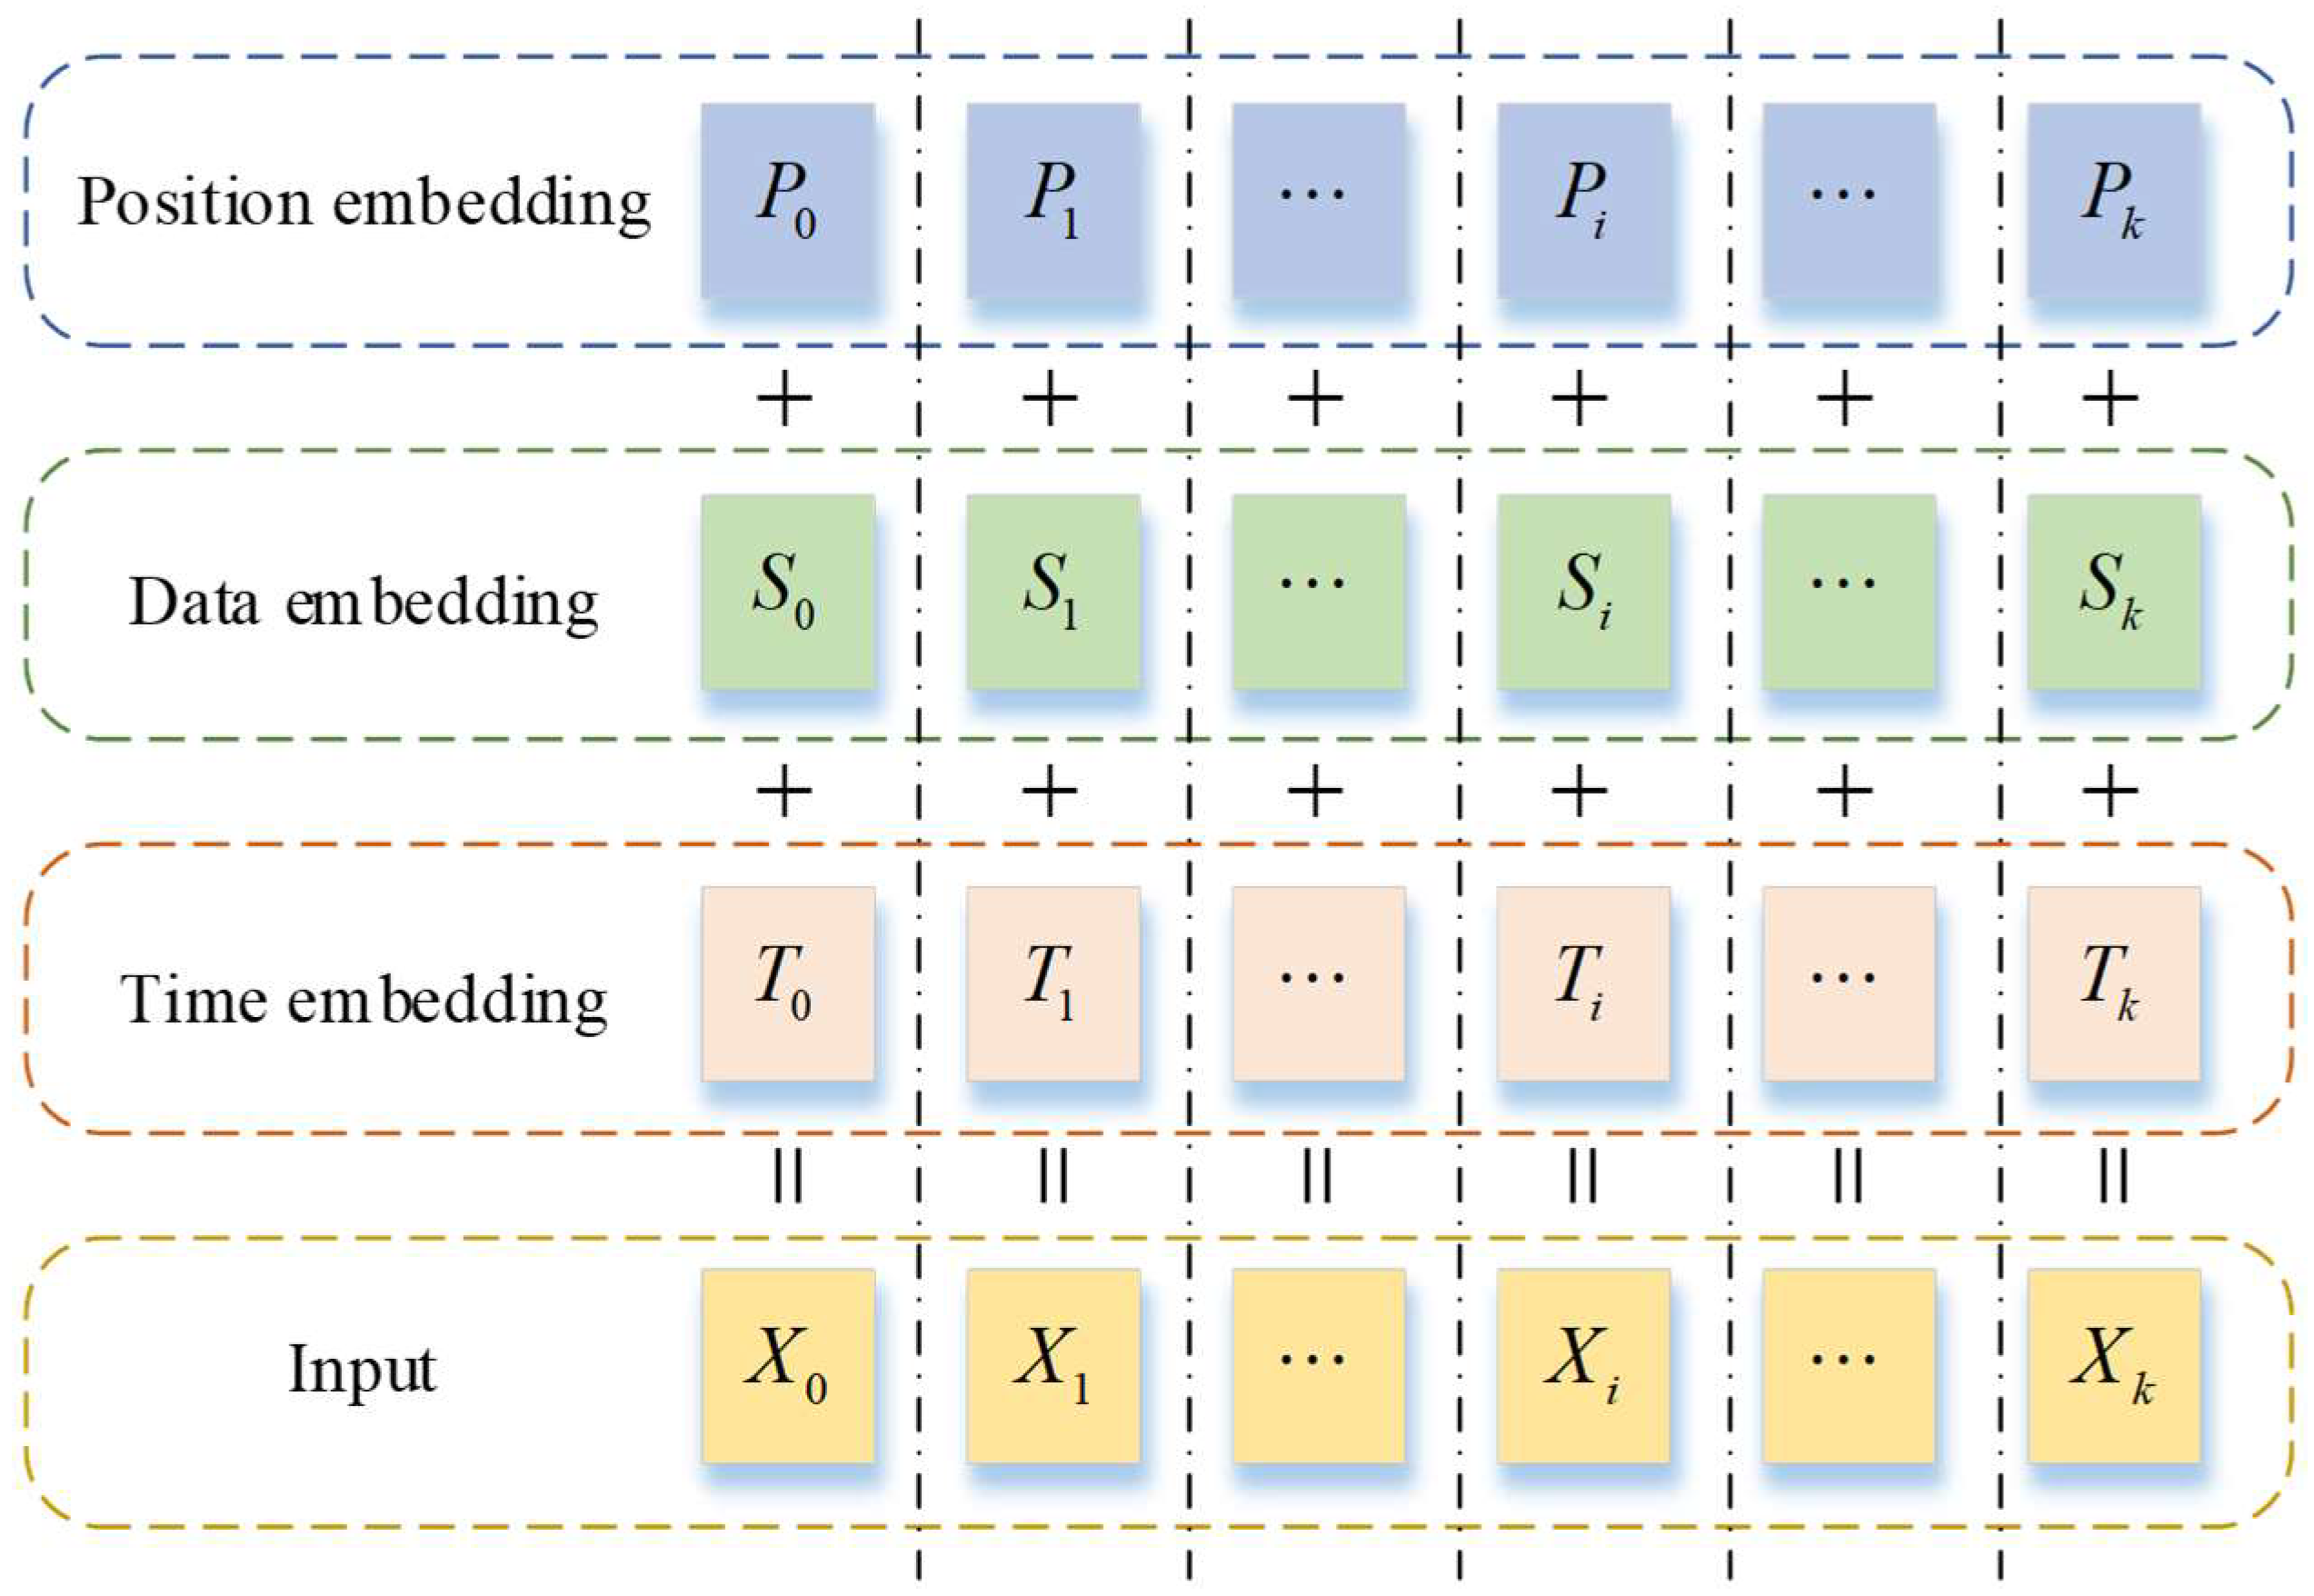
EGFormer: An Enhanced Transformer Model with Efficient Attention ...

EGFormer: An Enhanced Transformer Model with Efficient Attention ...
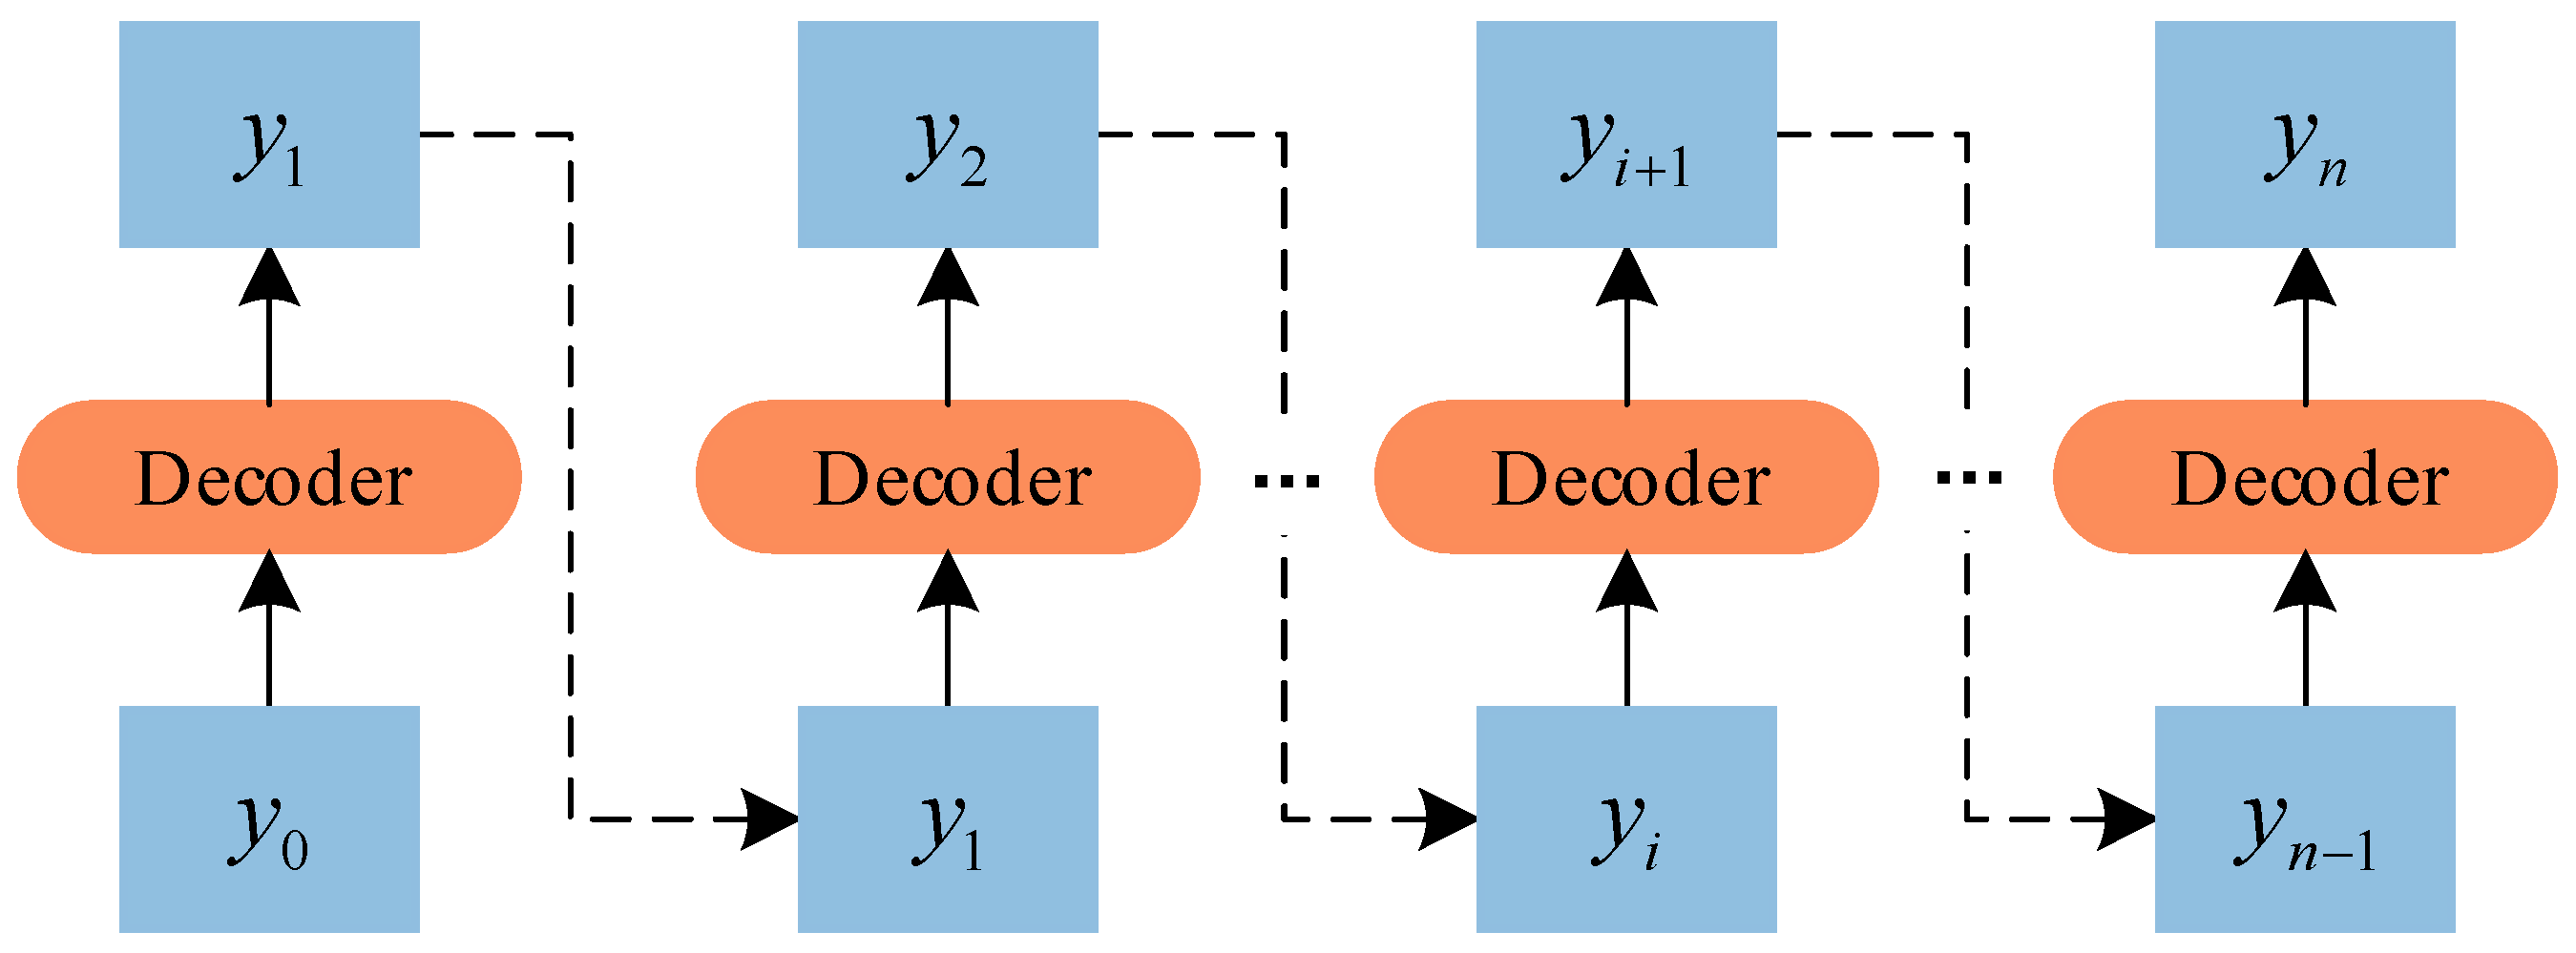
EGFormer: An Enhanced Transformer Model with Efficient Attention ...
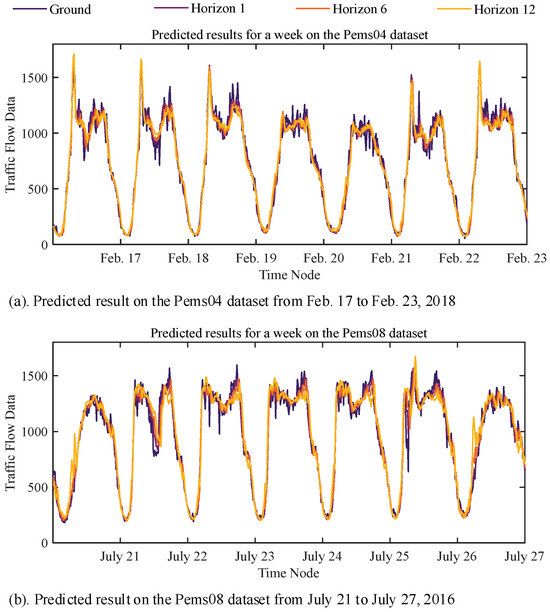
EGFormer: An Enhanced Transformer Model with Efficient Attention ...

EGFormer: An Enhanced Transformer Model with Efficient Attention ...

EGFormer: An Enhanced Transformer Model with Efficient Attention ...
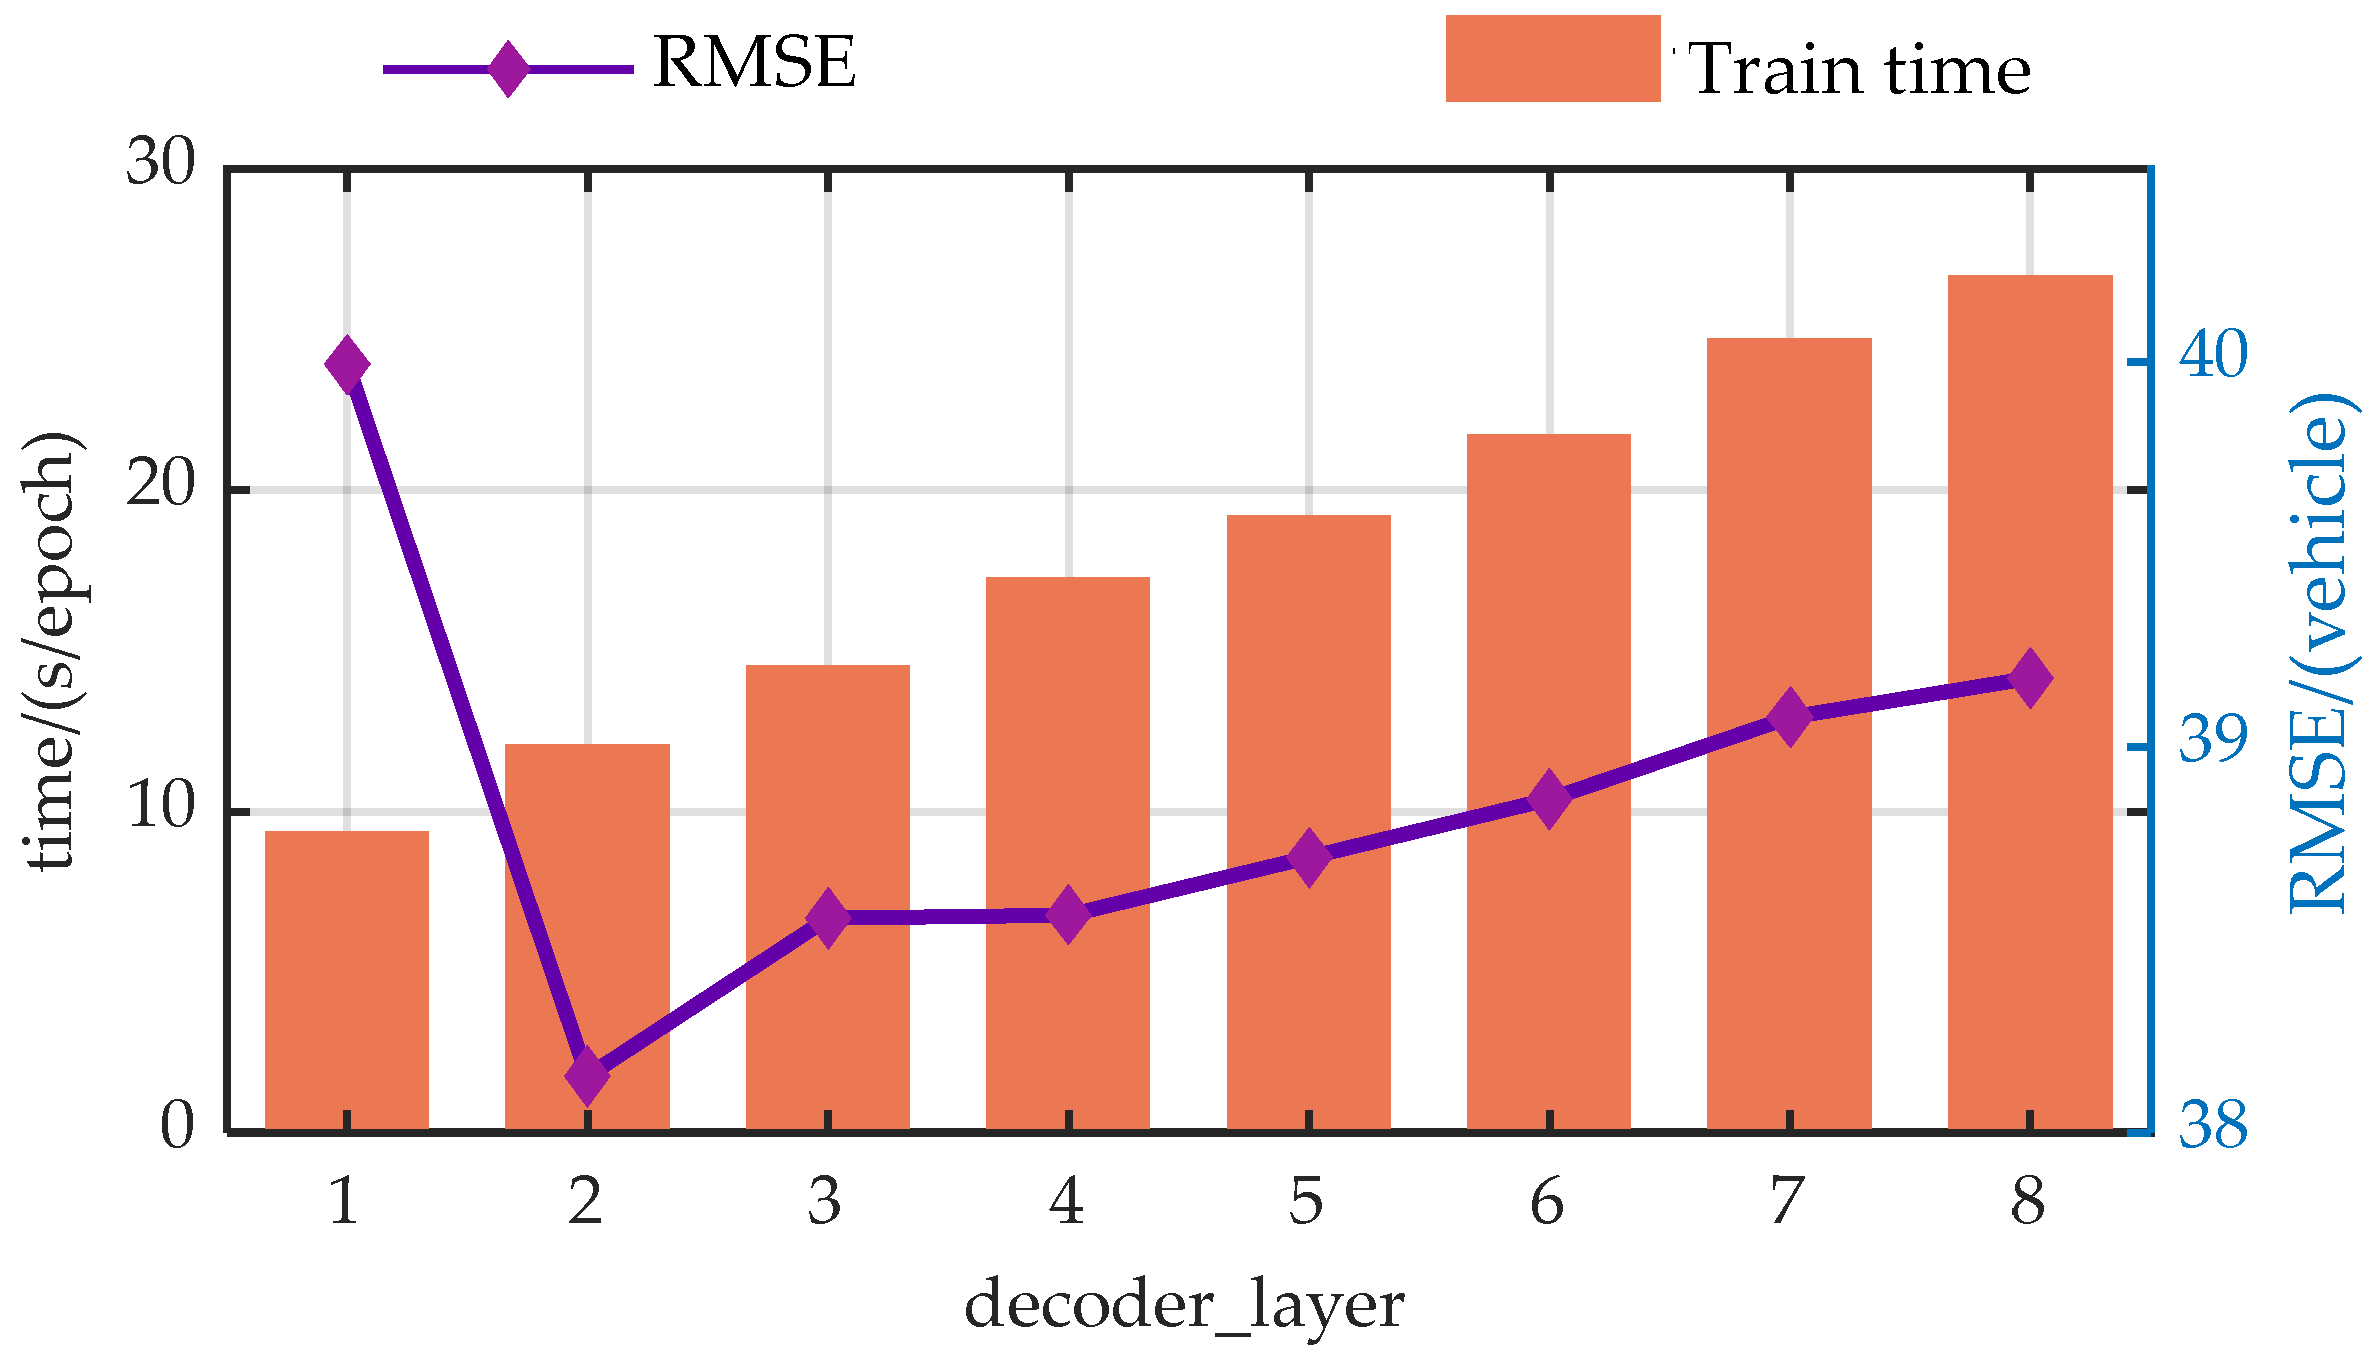
EGFormer: An Enhanced Transformer Model with Efficient Attention ...
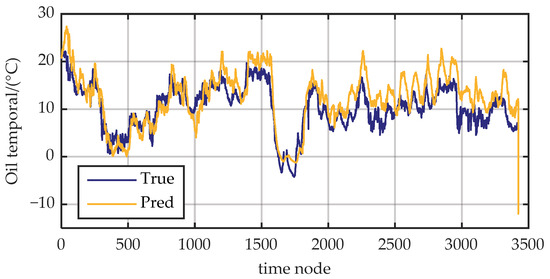
EGFormer: An Enhanced Transformer Model with Efficient Attention ...

EGFormer: An Enhanced Transformer Model with Efficient Attention ...
Advertisement Space (300x250)

MEA-EFFormer: Multiscale Efficient Attention with Enhanced Feature ...
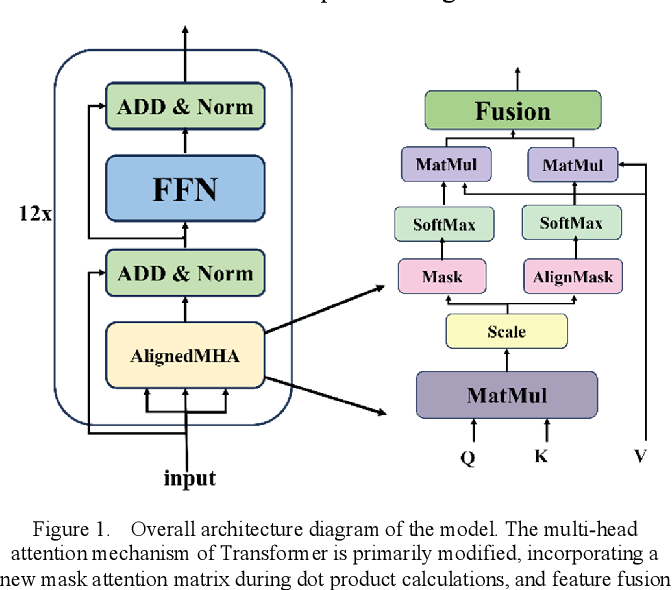
Figure 1 from Enhanced Pre-Trained Transformer with Aligned Attention ...

Semantic Segmentation Enhanced Transformer Model for Human Attention ...

Enhanced Wavelet Transform Dynamic Attention Transformer Model for ...

EEViT: Efficient Enhanced Vision Transformer Architectures with ...
Transformer Model Fig. 2: Attention mechanism (a) shows complete ...

Graph External Attention Enhanced Transformer | AI Research Paper Details

論文解説 EfficientViT: Memory Efficient Vision Transformer with Cascaded ...

A Multiscale Visualization of Attention in the Transformer Model | PPT

Graph External Attention Enhanced Transformer | AI Research Paper Details
Advertisement Space (336x280)

3. Comparison of the attention mechanism in original transformer model ...

Figure 1 from Enhanced Transformer Model for Data-to-Text Generation ...

Paper page - FEAT: Full-Dimensional Efficient Attention Transformer for ...

Transformer Models: Understanding Sequences with Attention
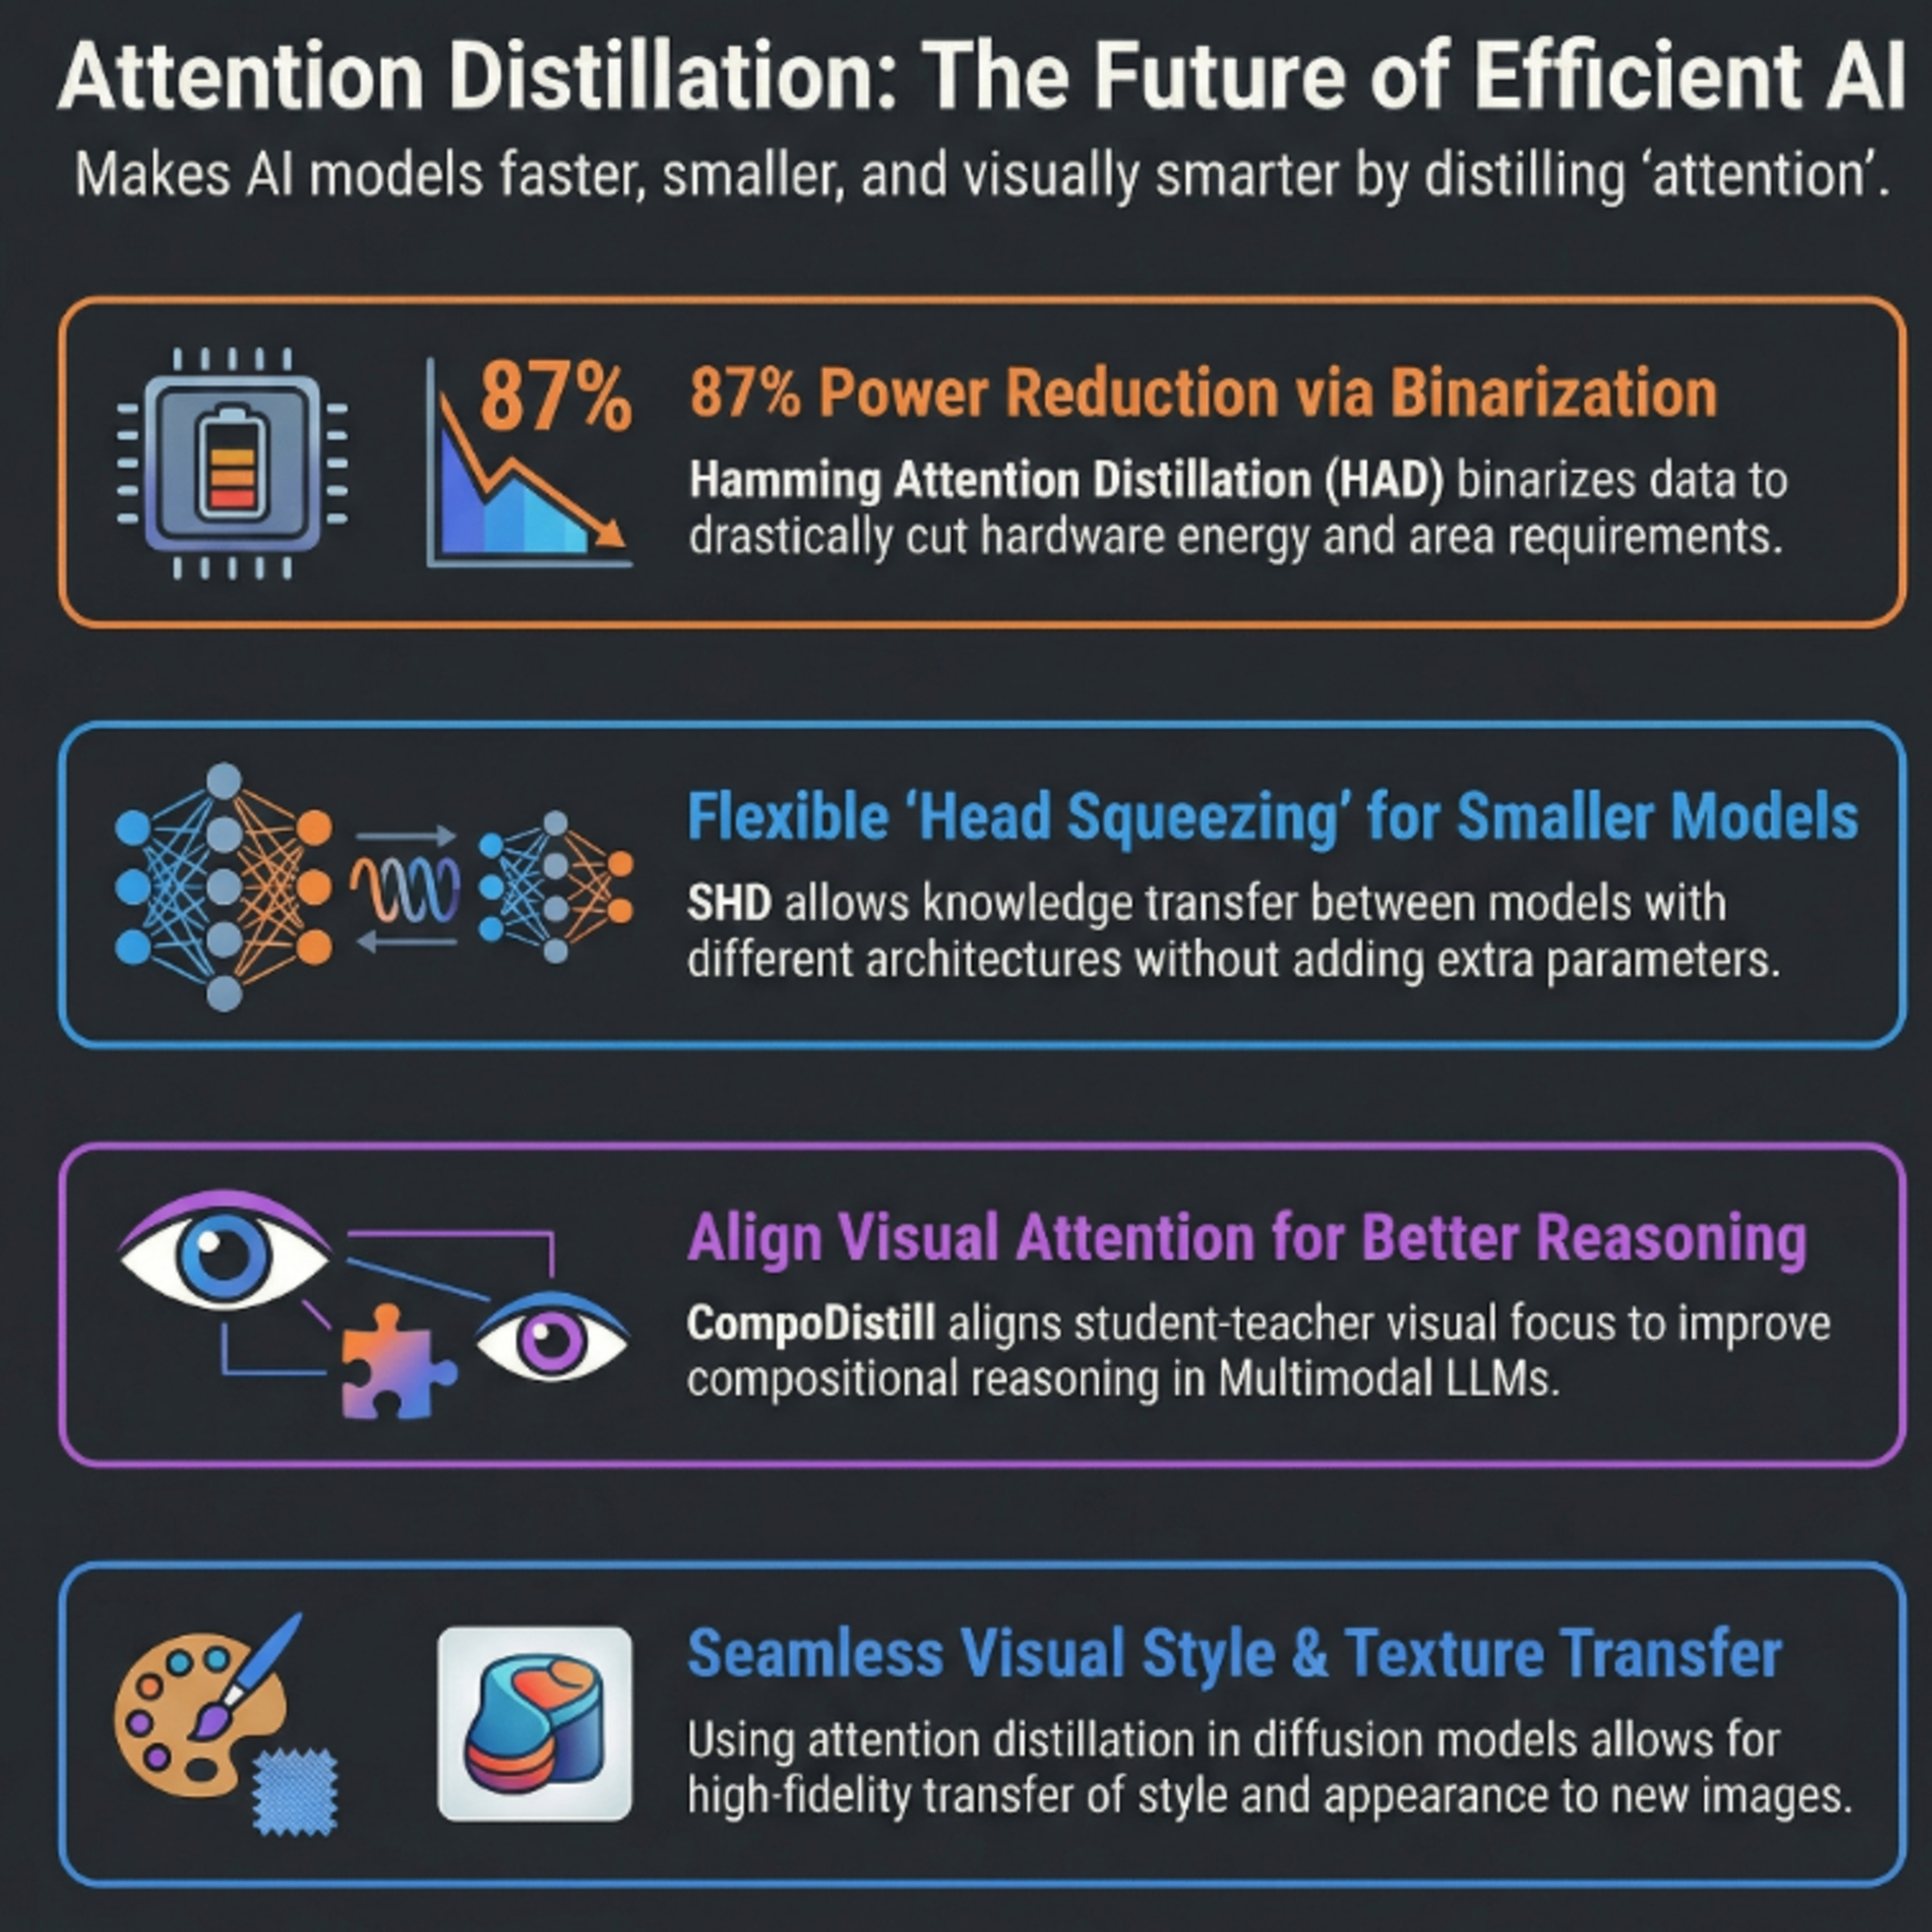
Advances in Attention Distillation for Efficient Transformer Models ...
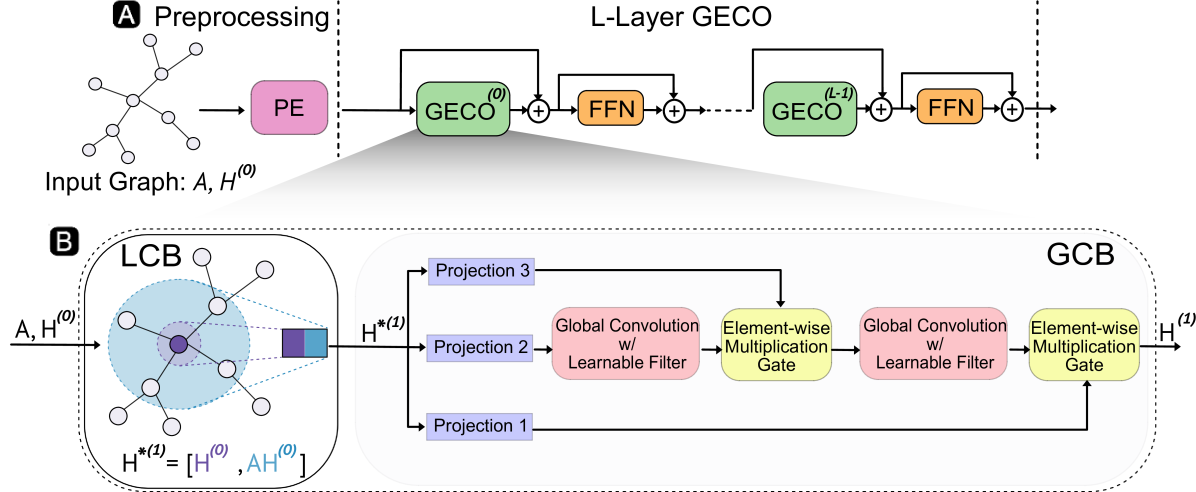
Graph External Attention Enhanced Transformer | AI Research Paper Details
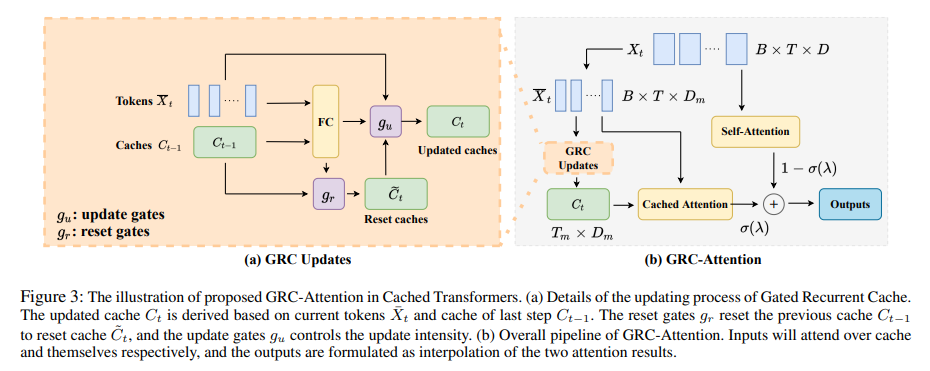
This AI Paper Unveils the Cached Transformer: A Transformer Model with ...

A Multiscale Visualization of Attention in the Transformer Model | PPT

A Multiscale Visualization of Attention in the Transformer Model | PPT

Transformer Model Fig. 2: Attention mechanism (a) shows complete ...
Advertisement Space (336x280)
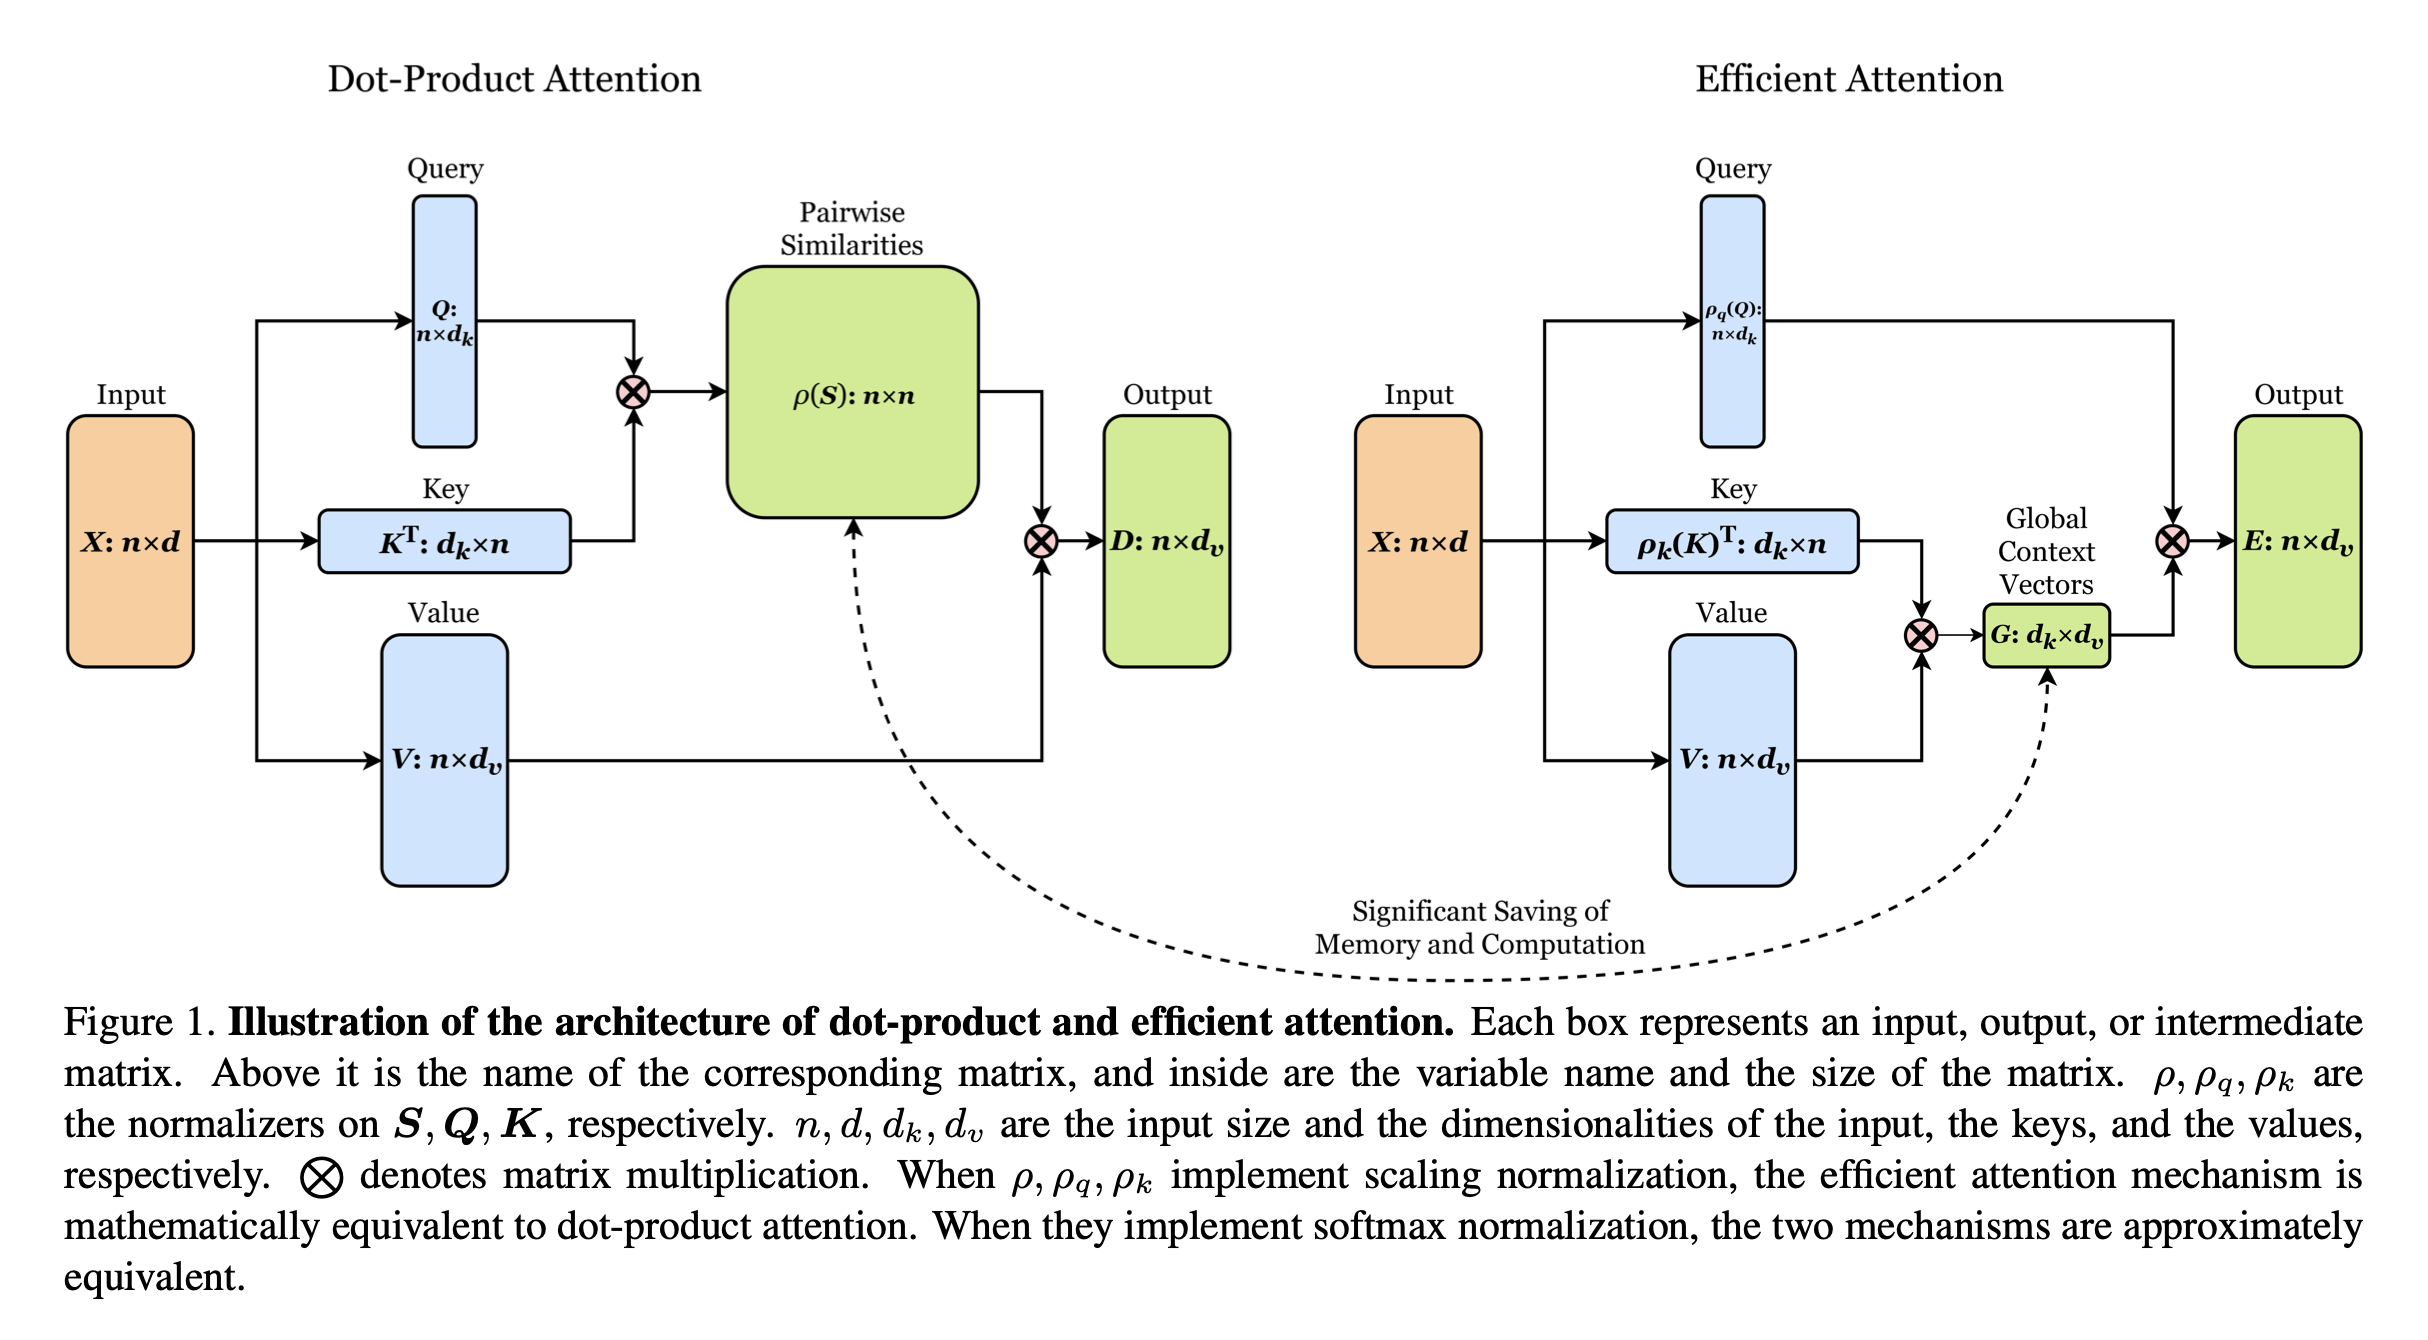
RoFormer: Enhanced Transformer with Rotary Position Embedding Paper review

A Simplified Query-Only Attention for Encoder-Based Transformer Models

RT-CBAM: Refined Transformer Combined with Convolutional Block ...
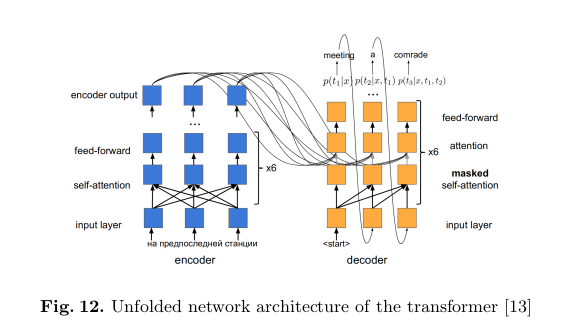
Attention Is All You Need: The Transformer - Sayef's Tech Blog

RT-CBAM: Refined Transformer Combined with Convolutional Block ...
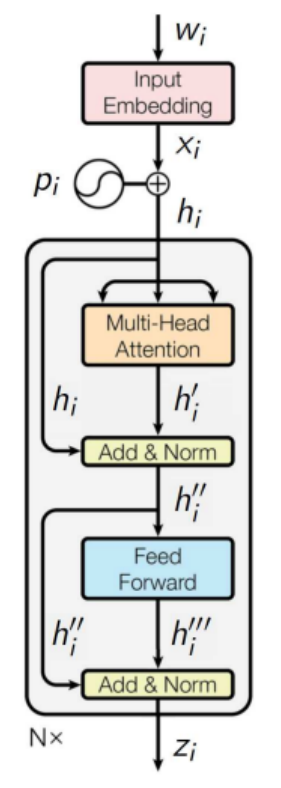
Attention mechanism and Transformer architecture