
Evaluation Benchmark Issue 53 Freedomintelligencellmzoo Github
Evaluation benchmark · Issue #53 · FreedomIntelligence/LLMZoo · GitHub
SWE-Bench | Benchmark Guide for Real-World GitHub Issue Evaluation
GitHub - NVlabs/FVEval: LLM Evaluation Benchmark on Hardware Formal ...
GitHub - modelscope/MCPBench: The evaluation benchmark on MCP servers ...
GitHub - TaoZhen1110/MemConflict: Benchmark and evaluation toolkit for ...
Evaluation results on the VideoEval-Pro benchmark · Issue #292 ...
[Feature Request] finetuning Model effect evaluation benchmark · Issue ...
GitHub - cuishiyao96/FFT: Benchmark for LLM Harmlessness Evaluation ...
Evaluation / Testing data · Issue #33 · facebookresearch/jepa · GitHub
evaluation metrics · Issue #823 · open-mmlab/mmsegmentation · GitHub
Advertisement Space (300x250)
Benchmark datasets · Issue #1 · nudt-bioinfo/SpaBalance · GitHub
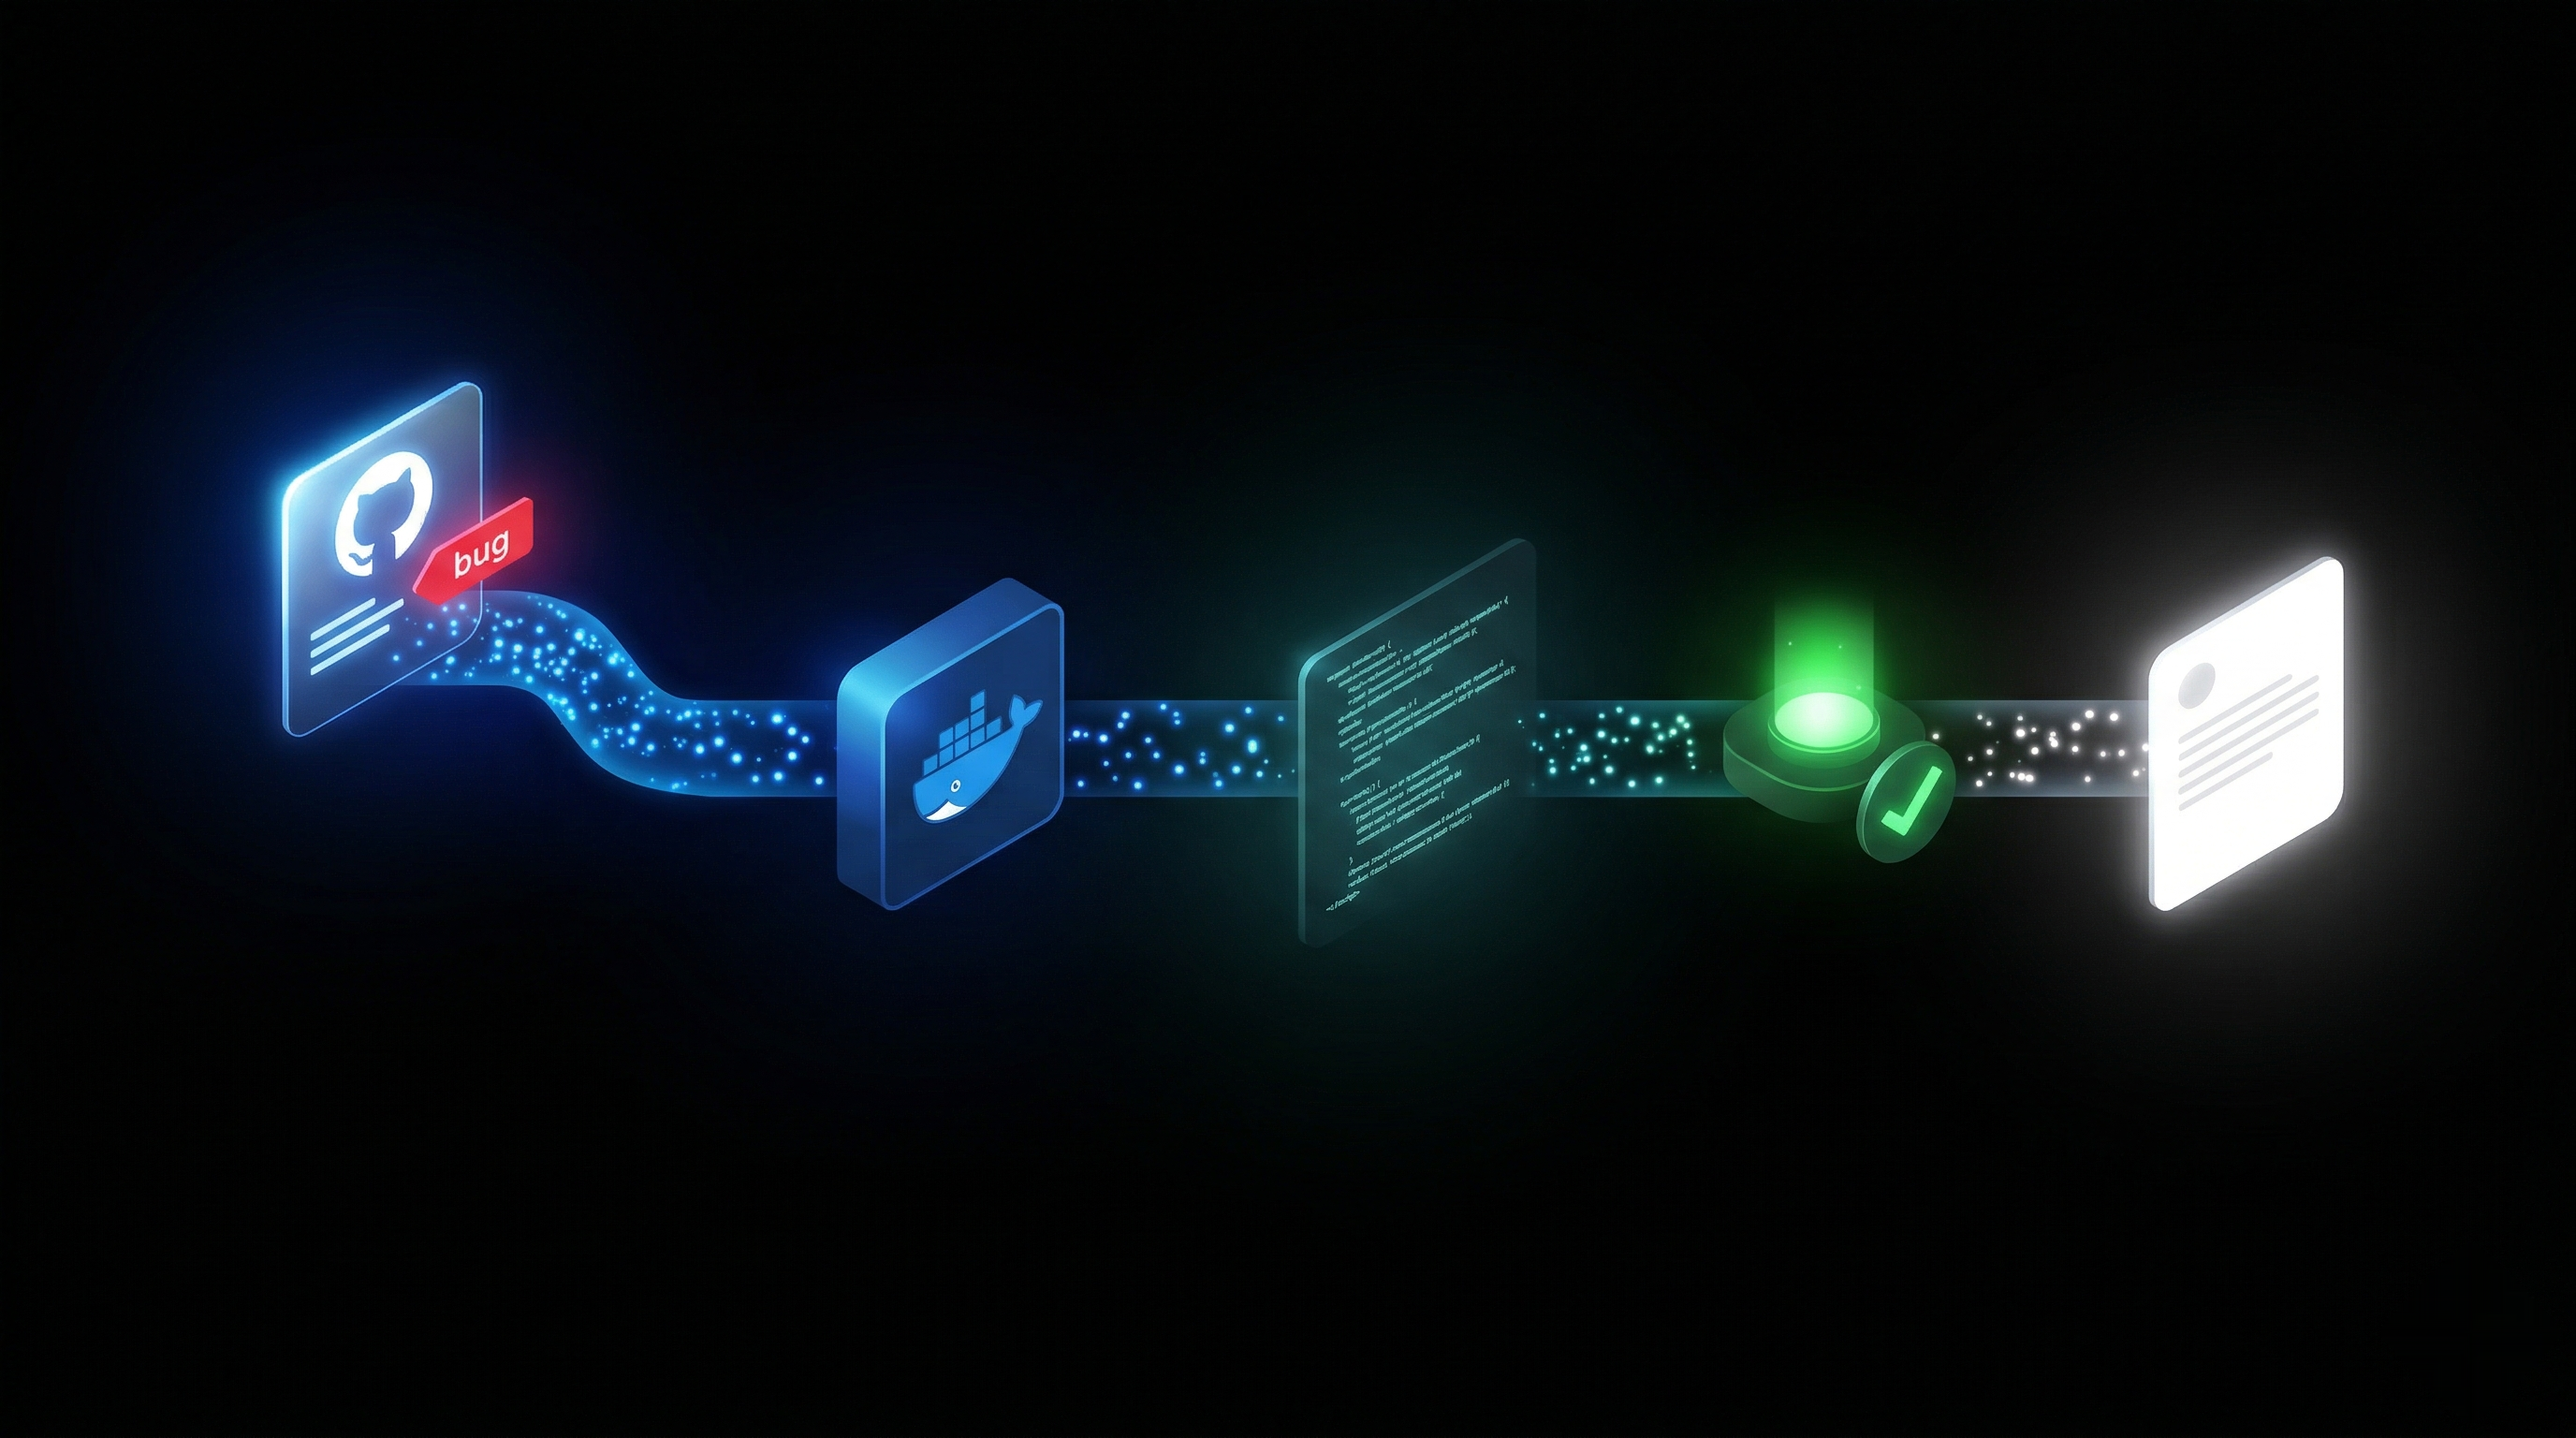
The Anatomy of an Agentic Benchmark: From GitHub Issue to Evaluation ...

GitHub - om-ai-lab/OVDEval: A Comprehensive Evaluation Benchmark for ...
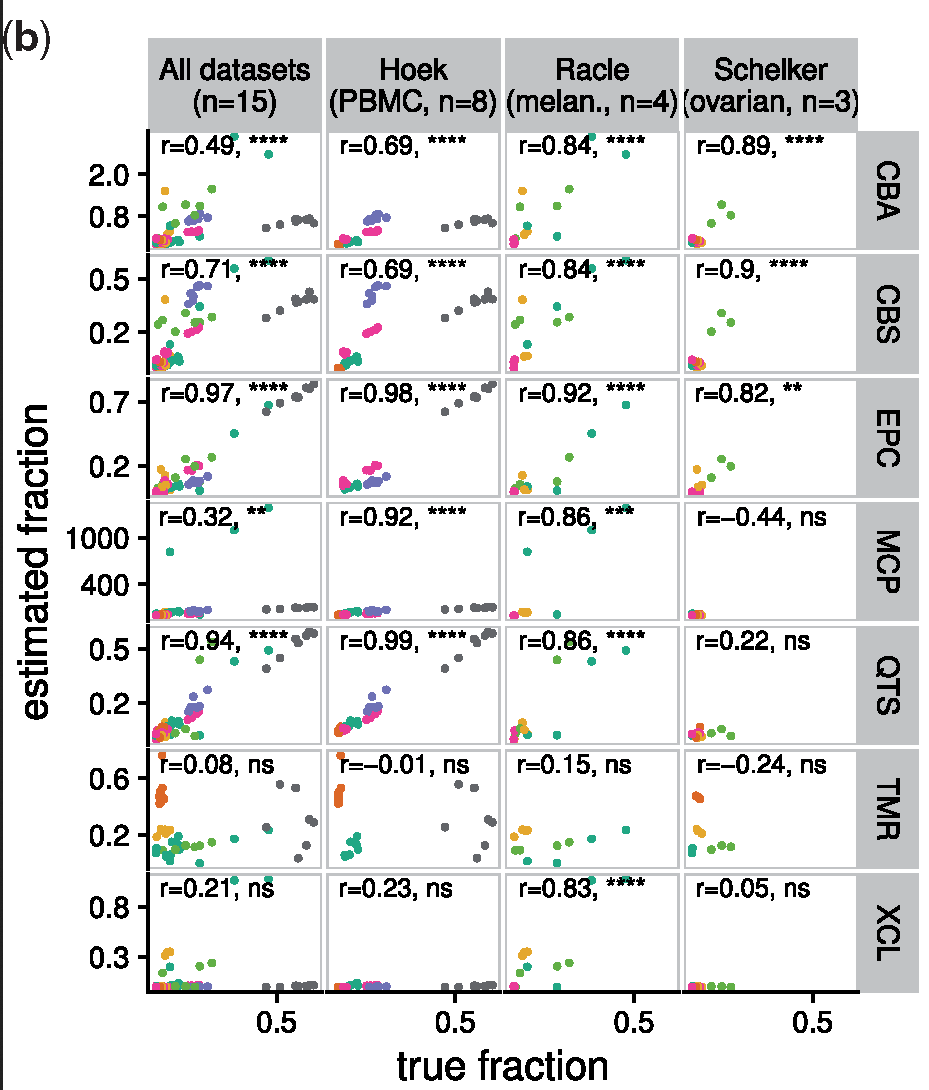
mini benchmark · Issue #36 · omnideconv/omnideconv · GitHub
GitHub - symflower/eval-dev-quality: DevQualityEval: An evaluation ...
GitHub - TRI-ML/vlm-evaluation: VLM Evaluation: Benchmark for VLMs ...
[Performance] Evaluation not terminating · Issue #531 · EvolvingLMMs ...
Some questions about the evaluation metrics · Issue #53 · williamSYSU ...
Benchmark tests giving different results · Issue #1269 · EleutherAI/lm ...
GitHub - marklabz/omnidocbench: [CVPR 2025] A Comprehensive Benchmark ...
Advertisement Space (336x280)
Issue · GitHub
GitHub - gipplab/pdf-benchmark: A Benchmark of PDF Information ...
GitHub - awslabs/unified-text2sql-benchmark: UNITE: A Unified Benchmark ...
about evaluation · Issue #498 · facebookresearch/maskrcnn-benchmark ...
some issues for MMLU benchmark when loading local dataset · Issue #2469 ...
BBH, gsm8k benchmark accuracy mismatch with paper · Issue #1075 ...
GitHub - zeyofu/BLINK_Benchmark: This repo contains evaluation code for ...
GitHub - CASIA-IVA-Lab/SciVQR: This repo holds the official evaluation ...
How to RUN BENCHMARK on GGUF Models ? · Issue #2086 · EleutherAI/lm ...
GitHub - MLAI-Yonsei/lm-evaluation-harness: for LLM benchmark ...
Advertisement Space (336x280)
Requesting model to test? · Issue #3 · Aider-AI/refactor-benchmark · GitHub
Issue · GitHub
IPEX.LLM performance benchmark and 3rd Gen Intel Xeon · Issue #546 ...
Request for Evaluation in Simulation · Issue #5 · FlagOpen/RoboBrain-X0 ...
GitHub - Orange-OpenSource/benchmark_pipeline_solidity_llm: Evaluation ...
GitHub - xiandshi/chineseGLUE: Language Understanding Evaluation ...