
Faster Inference Torchcompile Vs Tensorrt
Faster inference: torch.compile vs TensorRT
Faster inference: torch.compile vs TensorRT
Faster inference: torch.compile vs TensorRT

TensorRT to faster inference for Deeplearning Model- Viblo
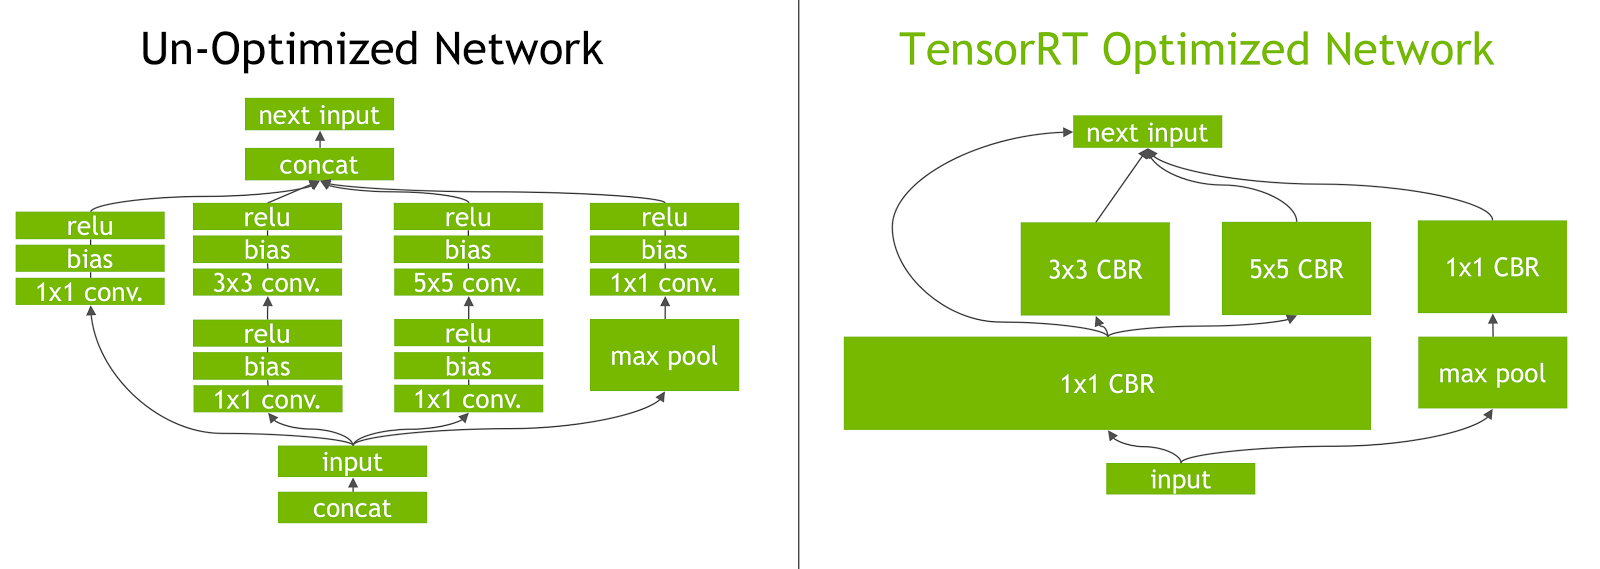
TensorRT 3: Faster TensorFlow Inference and Volta Support | NVIDIA ...
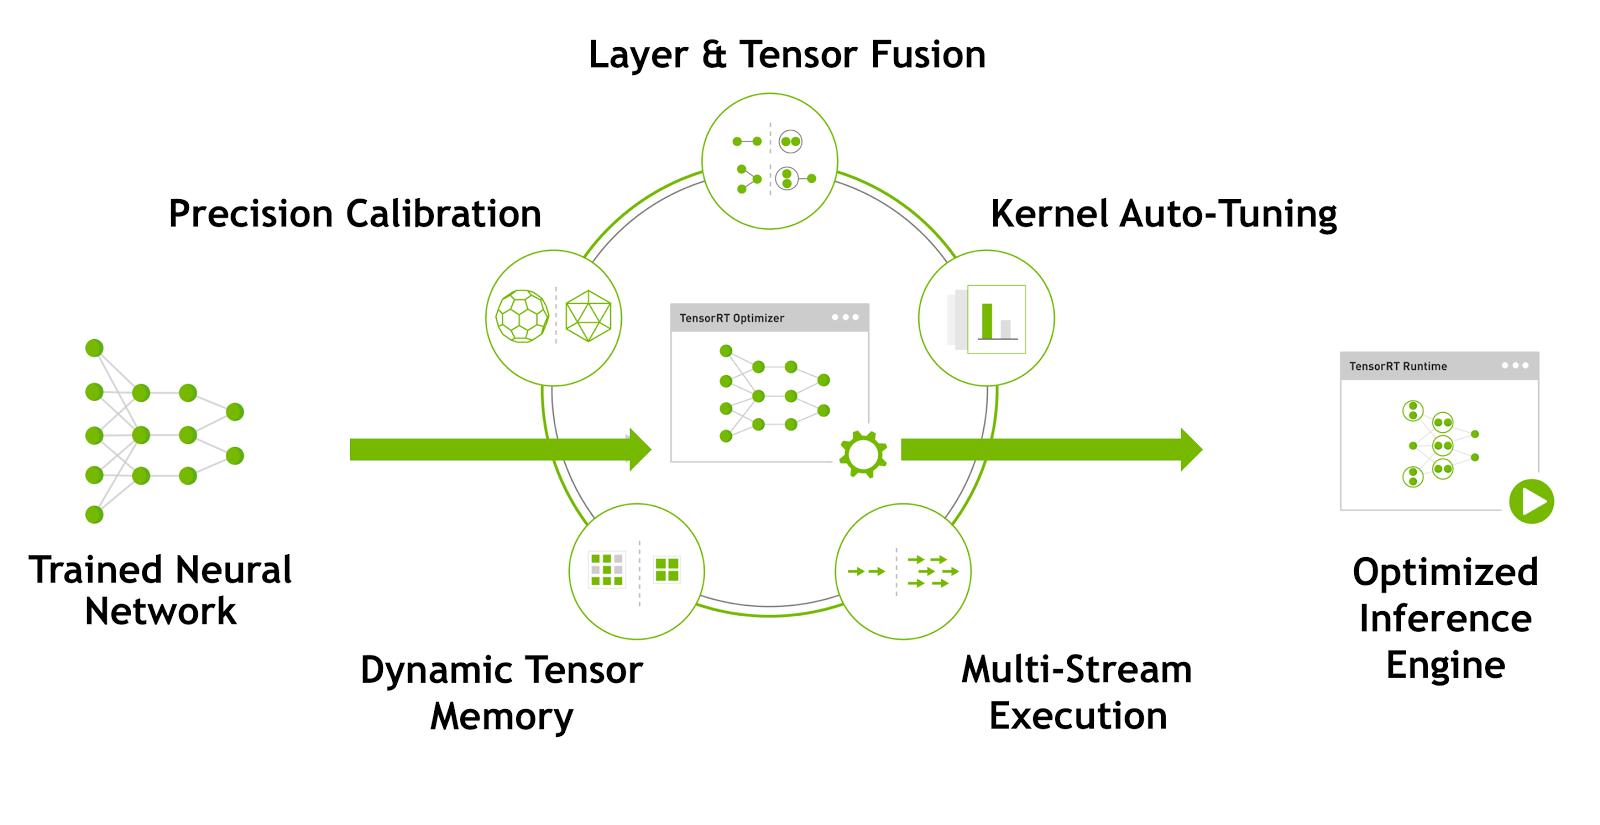
TensorRT 3: Faster TensorFlow Inference and Volta Support | NVIDIA ...
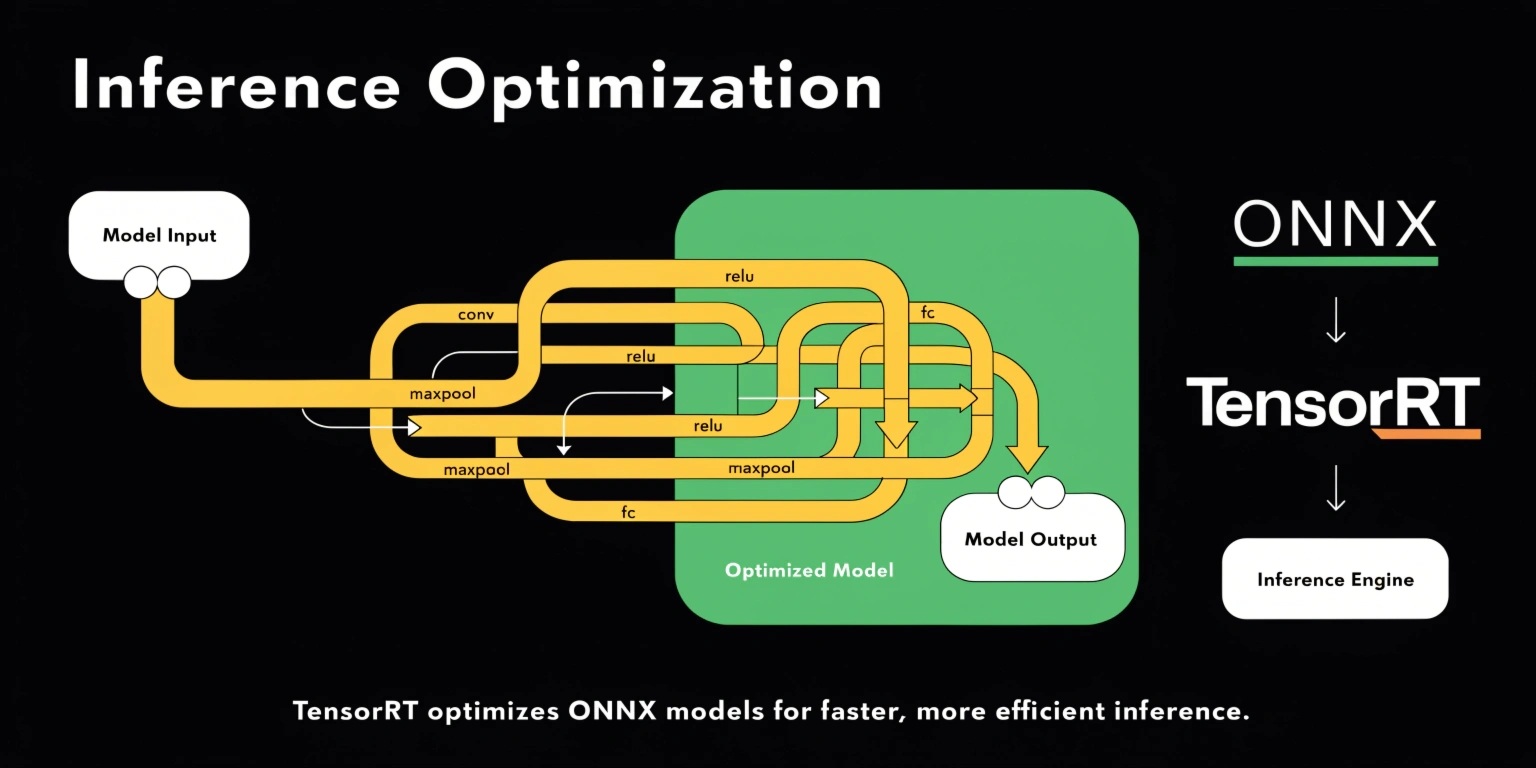
Inference Optimization Using TensorRT and ONNX for Faster AI Model ...

TensorRT 3: Faster TensorFlow Inference and Volta Support | NVIDIA ...

FASTER Inference with Torch TensorRT Deep Learning for Beginners - CPU ...

TensorRT 3: Faster TensorFlow Inference and Volta Support | NVIDIA ...
Advertisement Space (300x250)

TensorRT 3: Faster TensorFlow Inference and Volta Support | NVIDIA ...

TensorRT 3: Faster TensorFlow Inference and Volta Support | NVIDIA ...
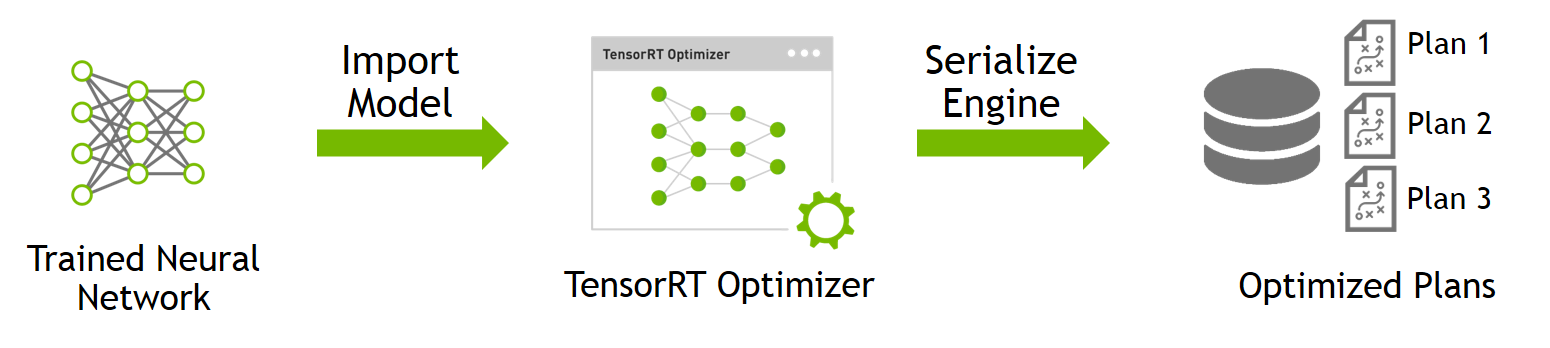
TensorRT 3: Faster TensorFlow Inference and Volta Support | NVIDIA ...

TensorRT 3: Faster TensorFlow Inference and Volta Support | NVIDIA ...
AI Inference Optimization: TensorRT vs OpenVINO vs ONNX Runtime

TensorRT 3: Faster TensorFlow Inference and Volta Support | NVIDIA ...
ONNX Runtime vs TensorRT for Try-On Model Inference Optimization ...

TensorRT vs vLLM: The Complete Guide to LLM Inference Engines

TensorRT 3: Faster TensorFlow Inference and Volta Support | NVIDIA ...

Accelerating Inference Up to 6x Faster in PyTorch with Torch-TensorRT ...
Advertisement Space (336x280)

Accelerating Inference Up to 6x Faster in PyTorch with Torch-TensorRT ...

Accelerating Inference Up to 6x Faster in PyTorch with Torch-TensorRT ...

NVIDIA TensorRT Accelerates Stable Diffusion Nearly 2x Faster with 8 ...
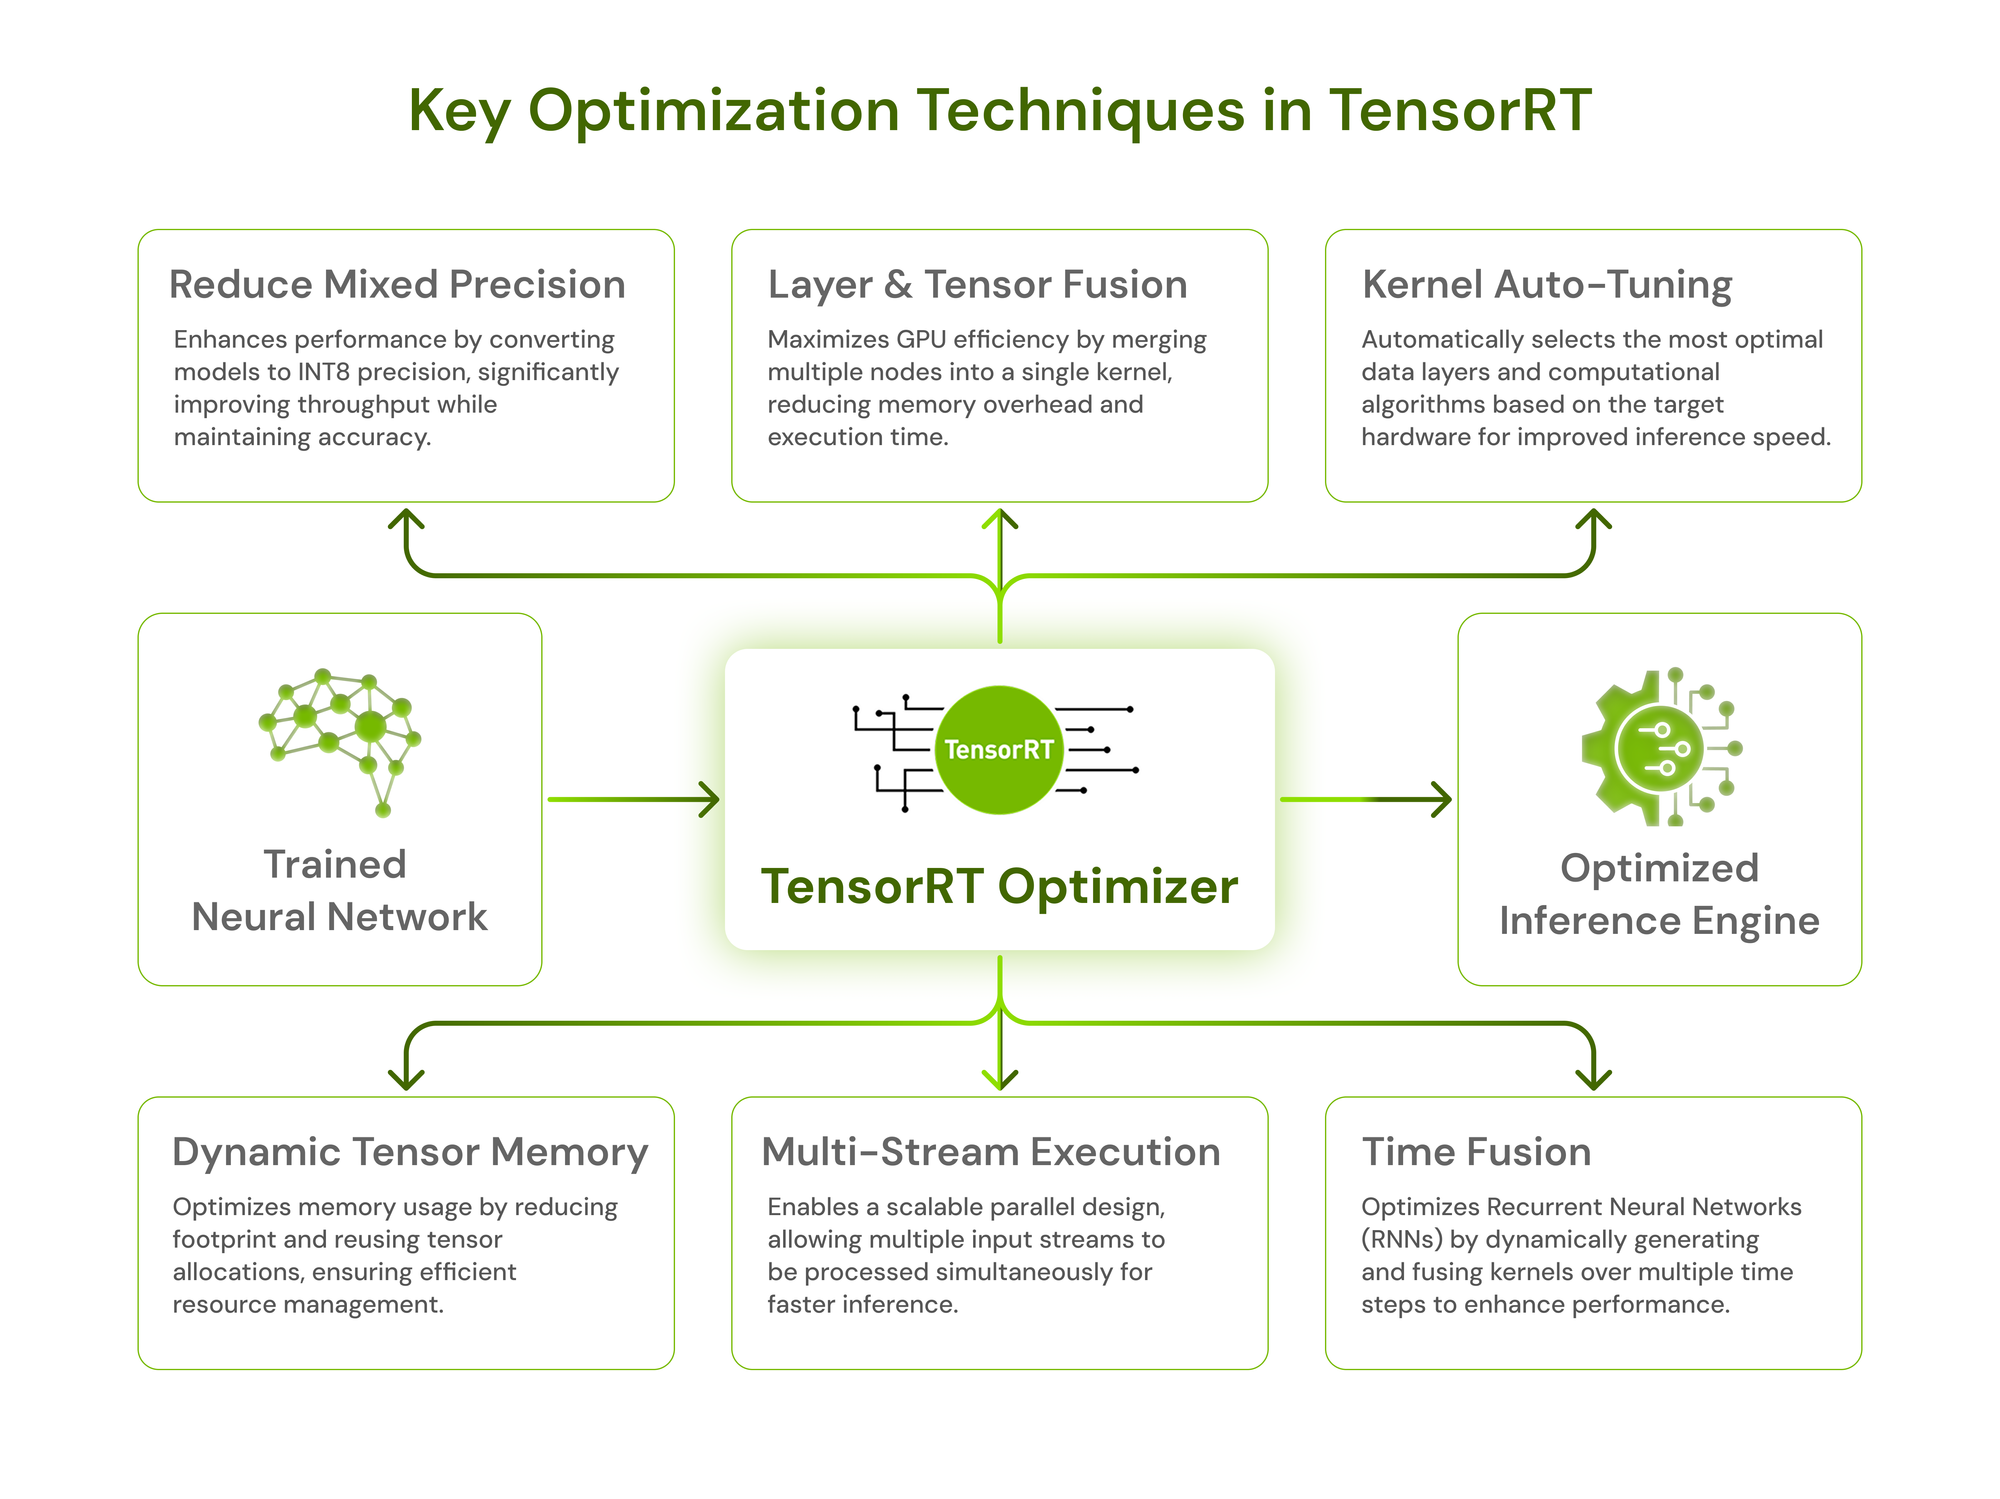
How to optimize inference using TensorRT on Jetson AGX Orin

How to Convert a Model from PyTorch to TensorRT and Speed Up Inference ...

NVIDIA TensorRT Accelerates Stable Diffusion Nearly 2x Faster with 8 ...
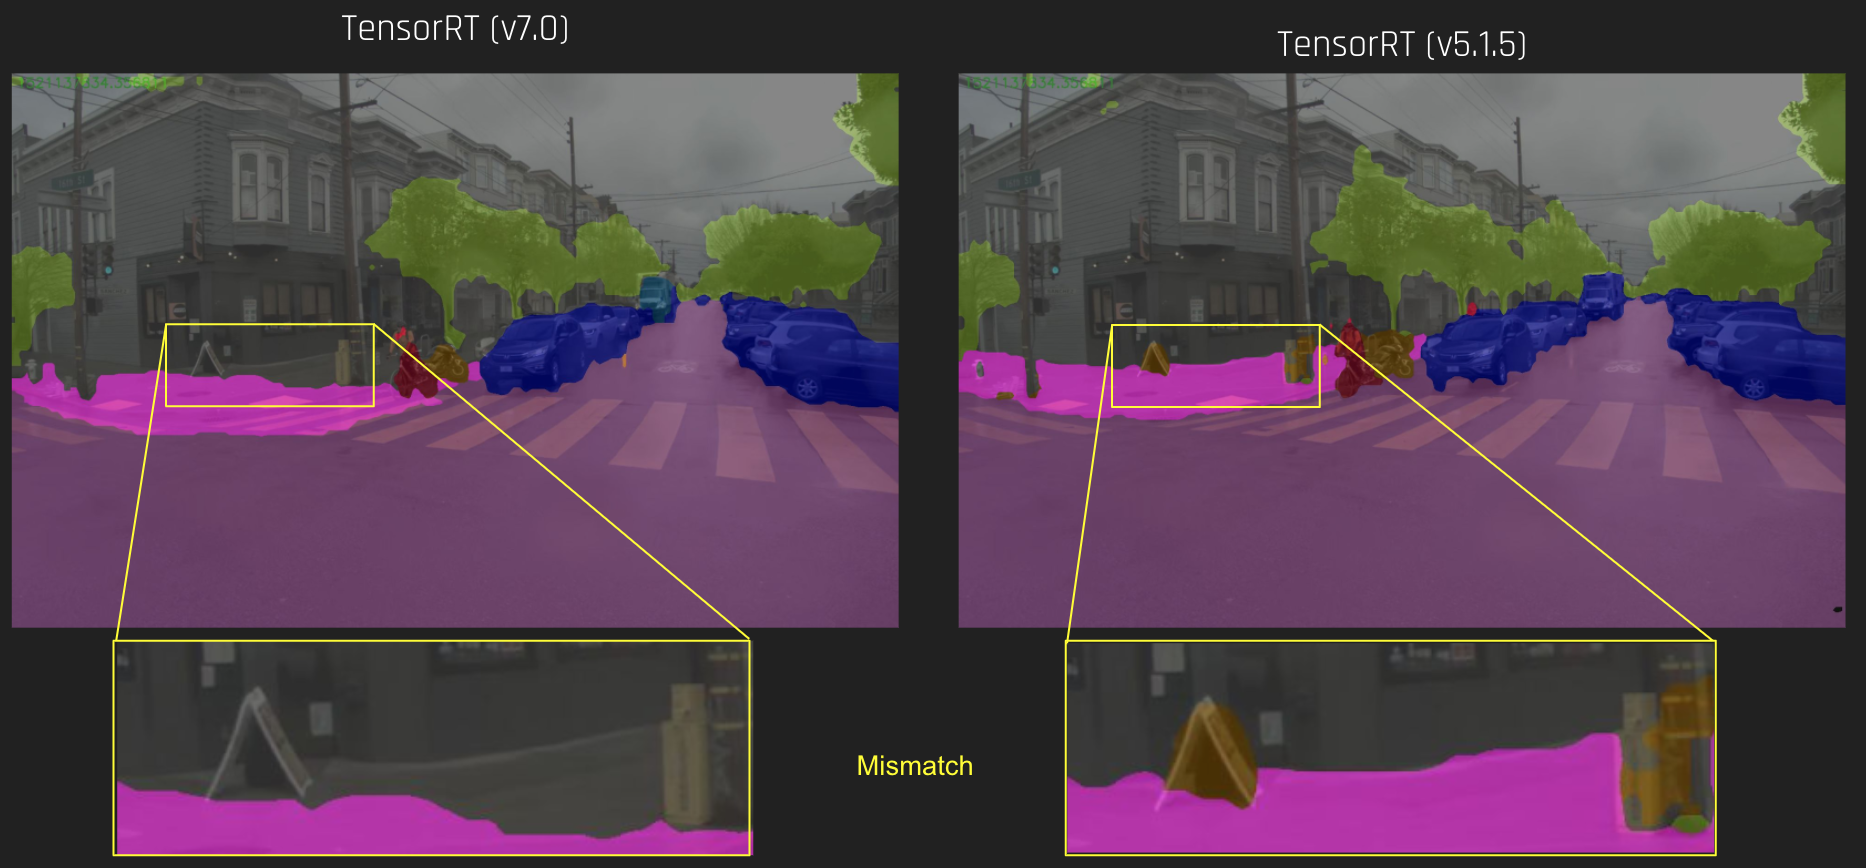
Fast INT8 Inference for Autonomous Vehicles with TensorRT 3 | NVIDIA ...

vLLM vs TensorRT-LLM: Which Inference Engine Should You Use in 2026 ...

Faster YOLOv5 Inference With TensorRT, Run YOLOv5 At 27 FPS, 52% OFF
Boost inference speeds with NVIDIA TensorRT on UbiOps - UbiOps - AI ...
Advertisement Space (336x280)
TensorRT vs. ONNX Runtime | Inference Engine Comparison | Inference Systems

TensorRT inference optimization process. | Download Scientific Diagram

TensorRT Integration Speeds Up TensorFlow Inference | NVIDIA Technical Blog
TensorRT Inference | cfzd/Ultra-Fast-Lane-Detection-v2 | DeepWiki
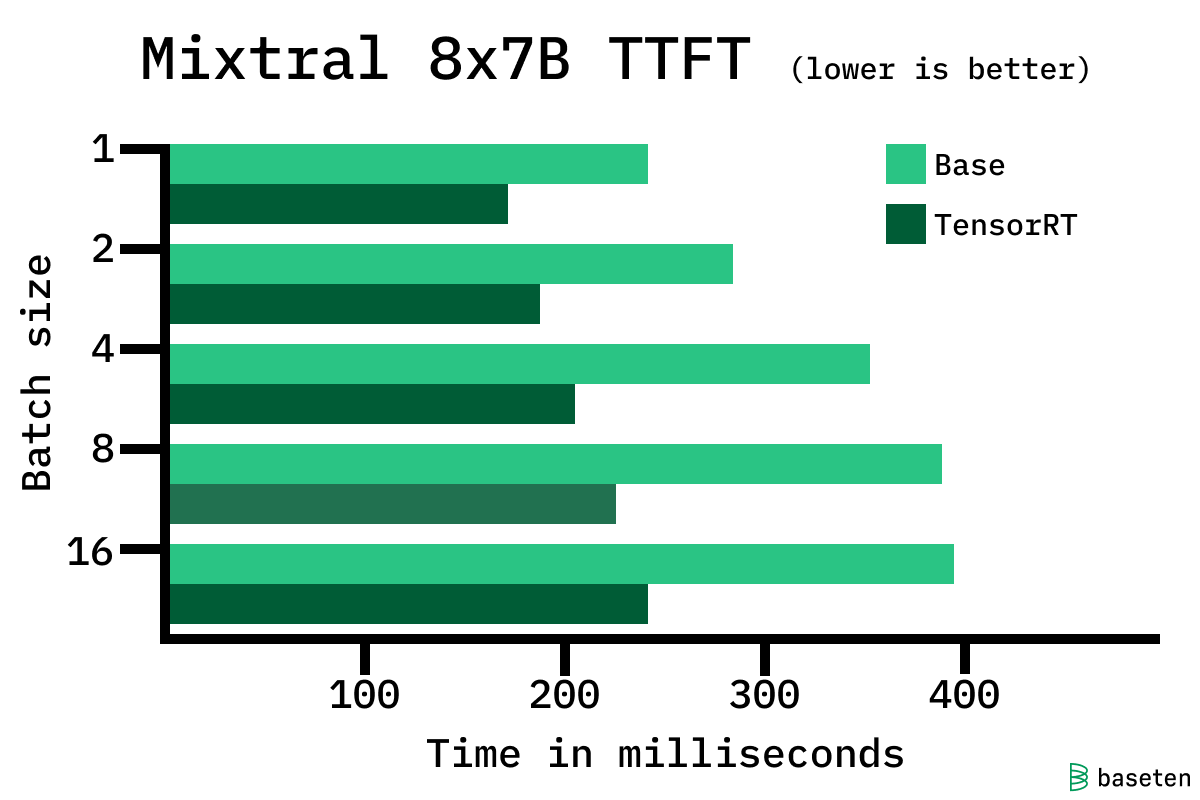
Faster Mixtral inference with TensorRT-LLM and quantization | Baseten Blog
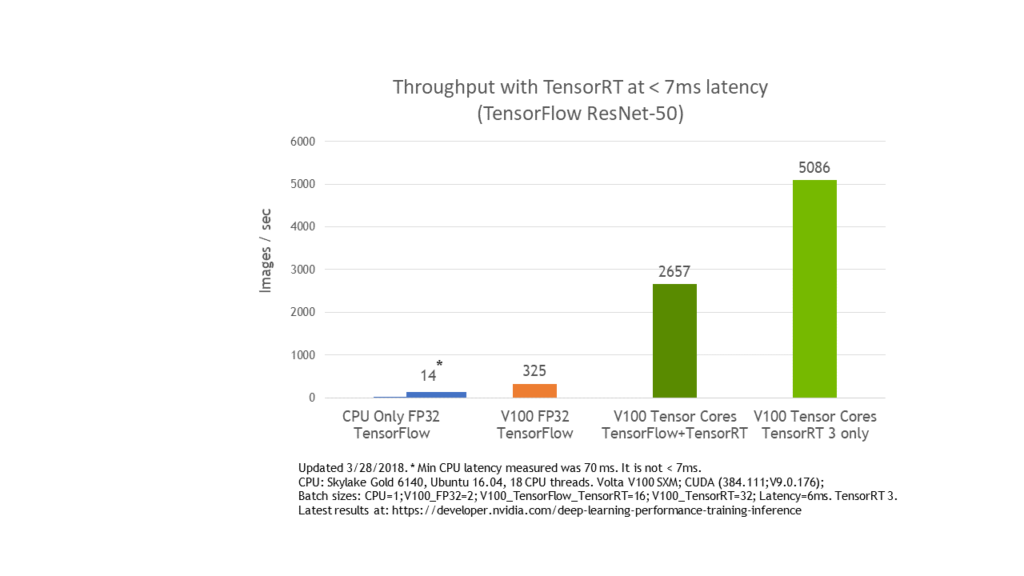
TensorRT Integration Speeds Up TensorFlow Inference | NVIDIA Technical Blog