
Faster Speculative Decoding Via Effective Draft Decoder With Pruned
Faster Speculative Decoding via Effective Draft Decoder with Pruned ...
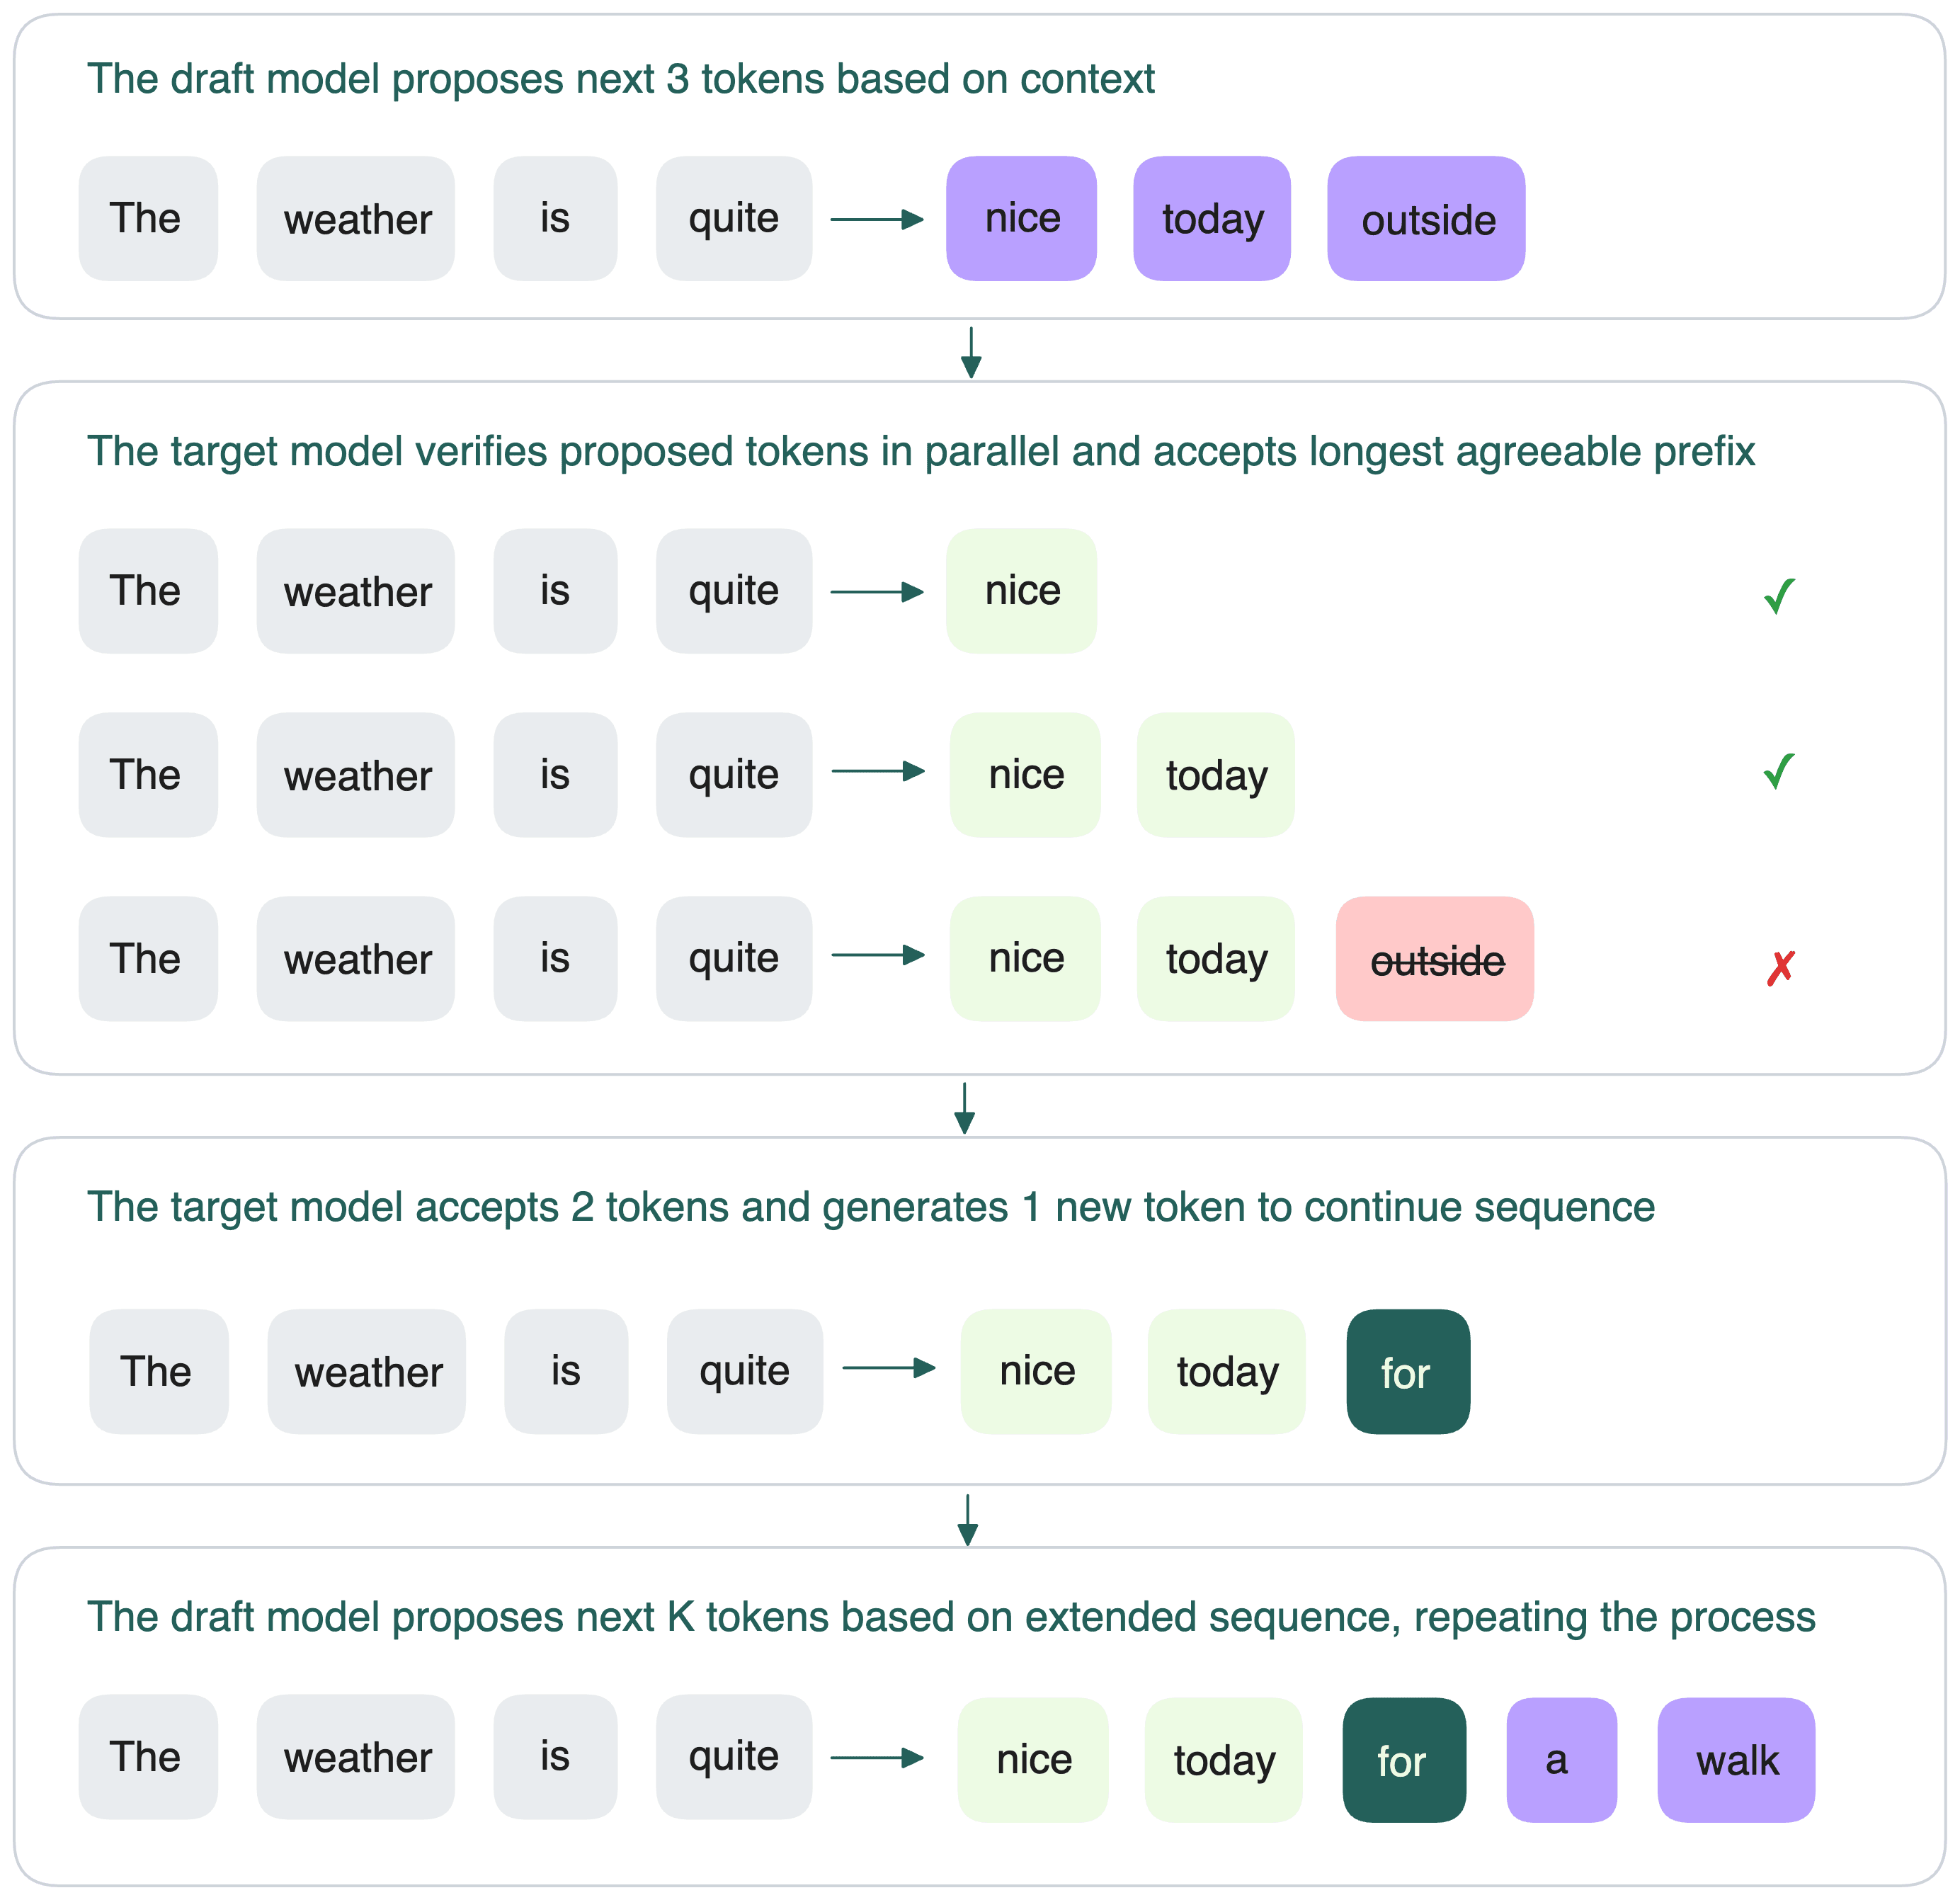
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...

Parallel Speculative Decoding with Adaptive Draft Length
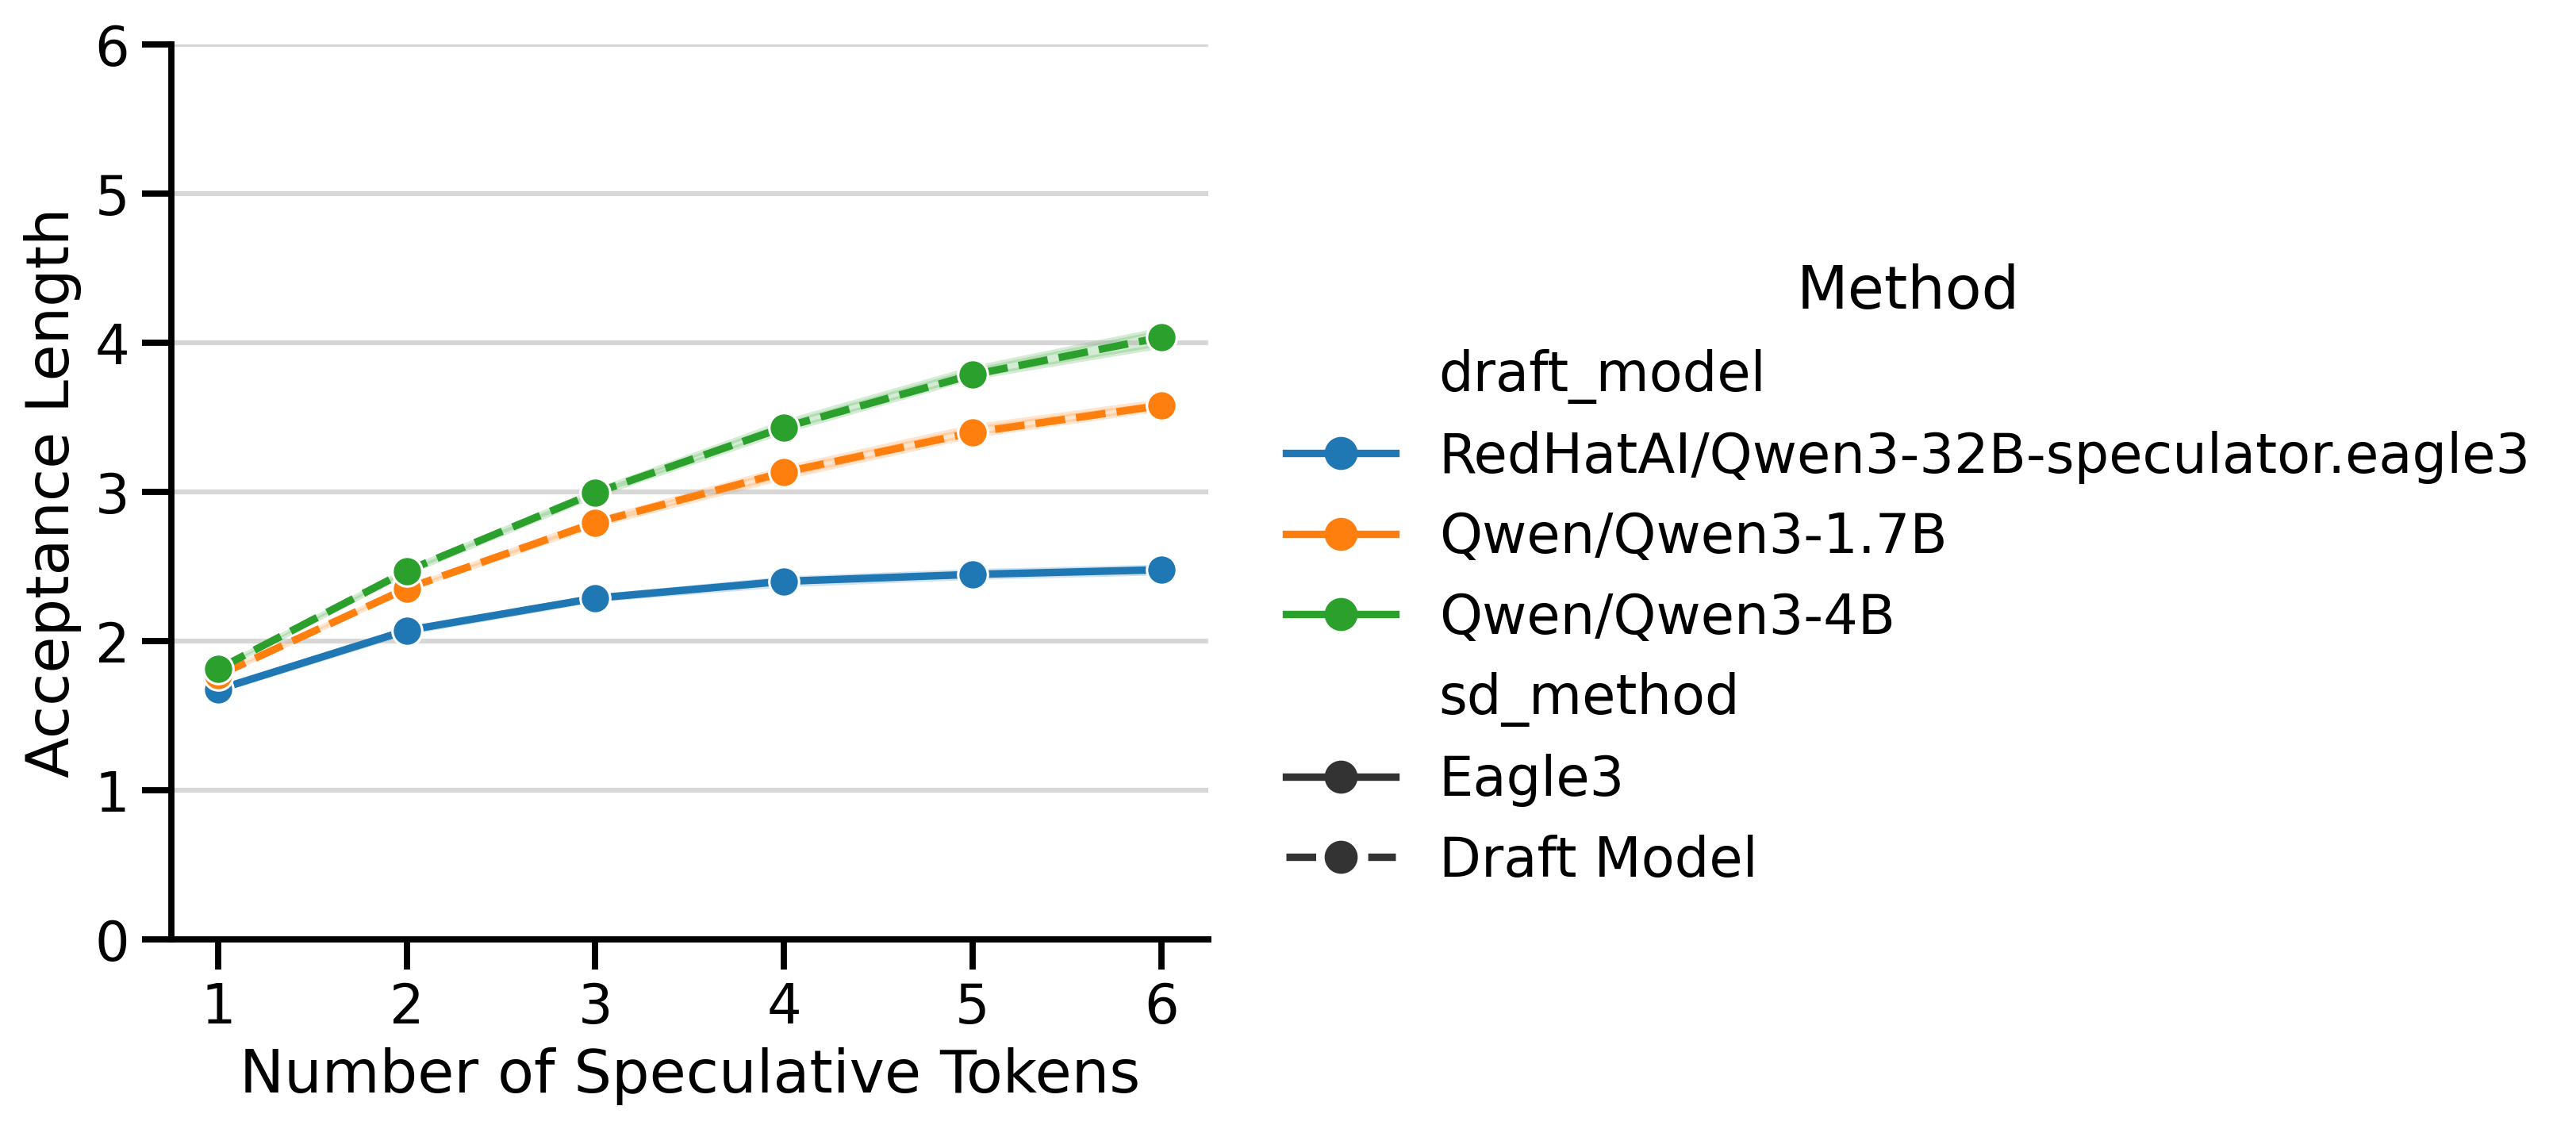
Up to 3.55x Faster: Contributing Speculative Decoding with Draft Models ...

[논문 리뷰] DySpec: Faster Speculative Decoding with Dynamic Token Tree ...

OPT-Tree: Speculative Decoding with Adaptive Draft Tree Structure | AI ...

[논문 리뷰] PEARL: Parallel Speculative Decoding with Adaptive Draft Length

(PDF) Faster Cascades via Speculative Decoding
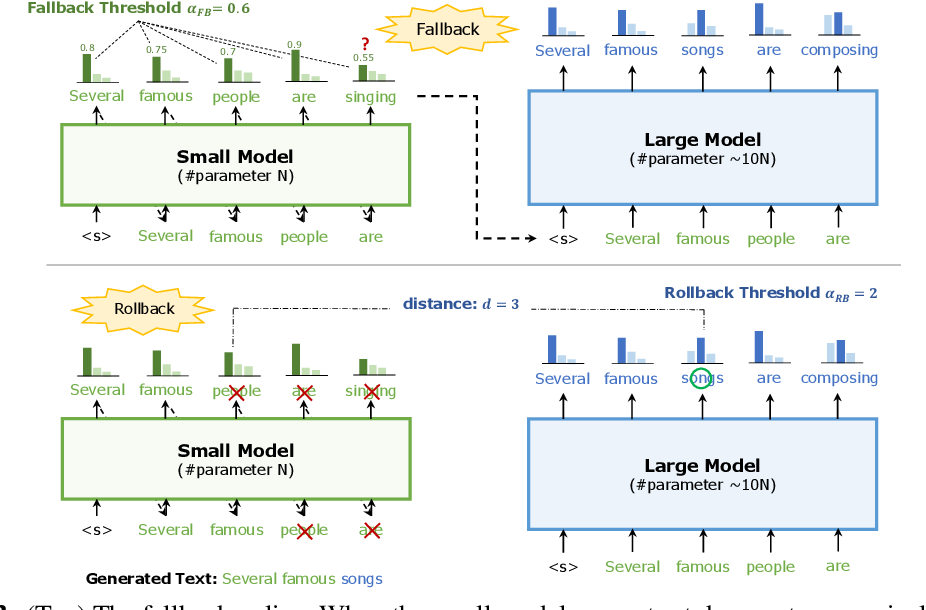
Figure 3 from Speculative Decoding with Big Little Decoder | Semantic ...

Faster LLMs with speculative decoding and AWS Inferentia2 | Artificial ...
Advertisement Space (300x250)
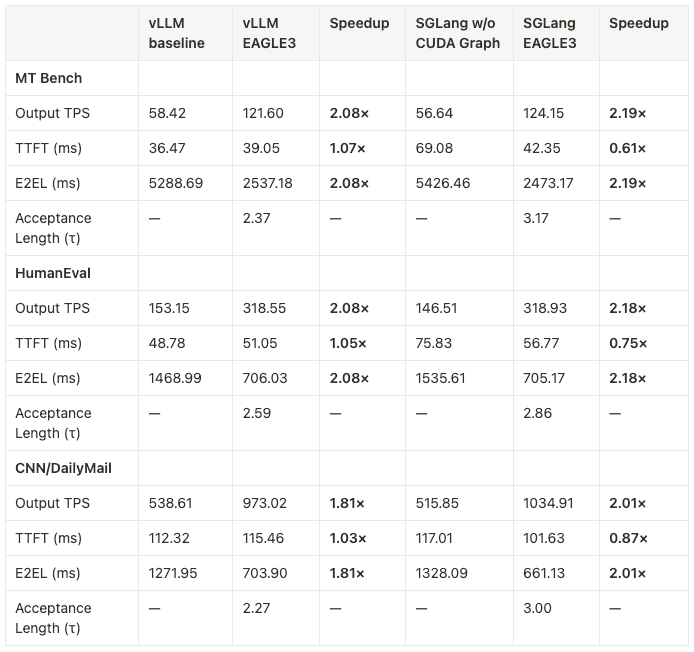
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...
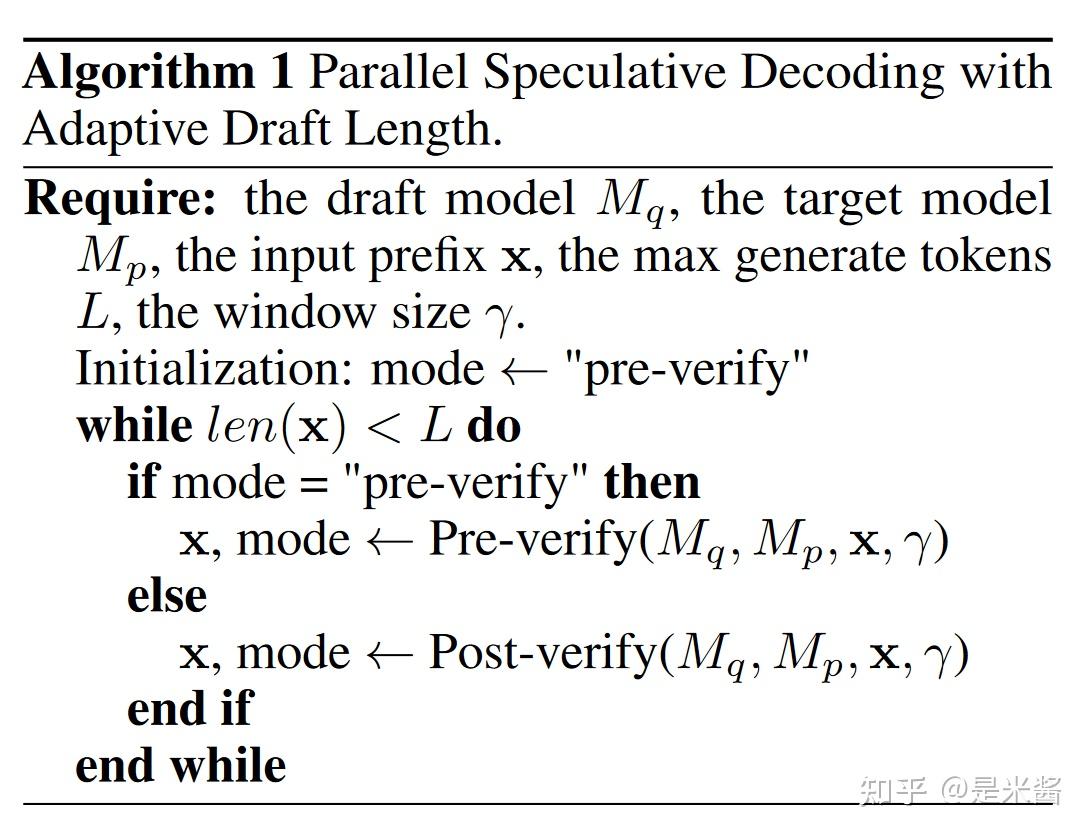
论文笔记2 Parallel Speculative Decoding with Adaptive Draft Length - 知乎
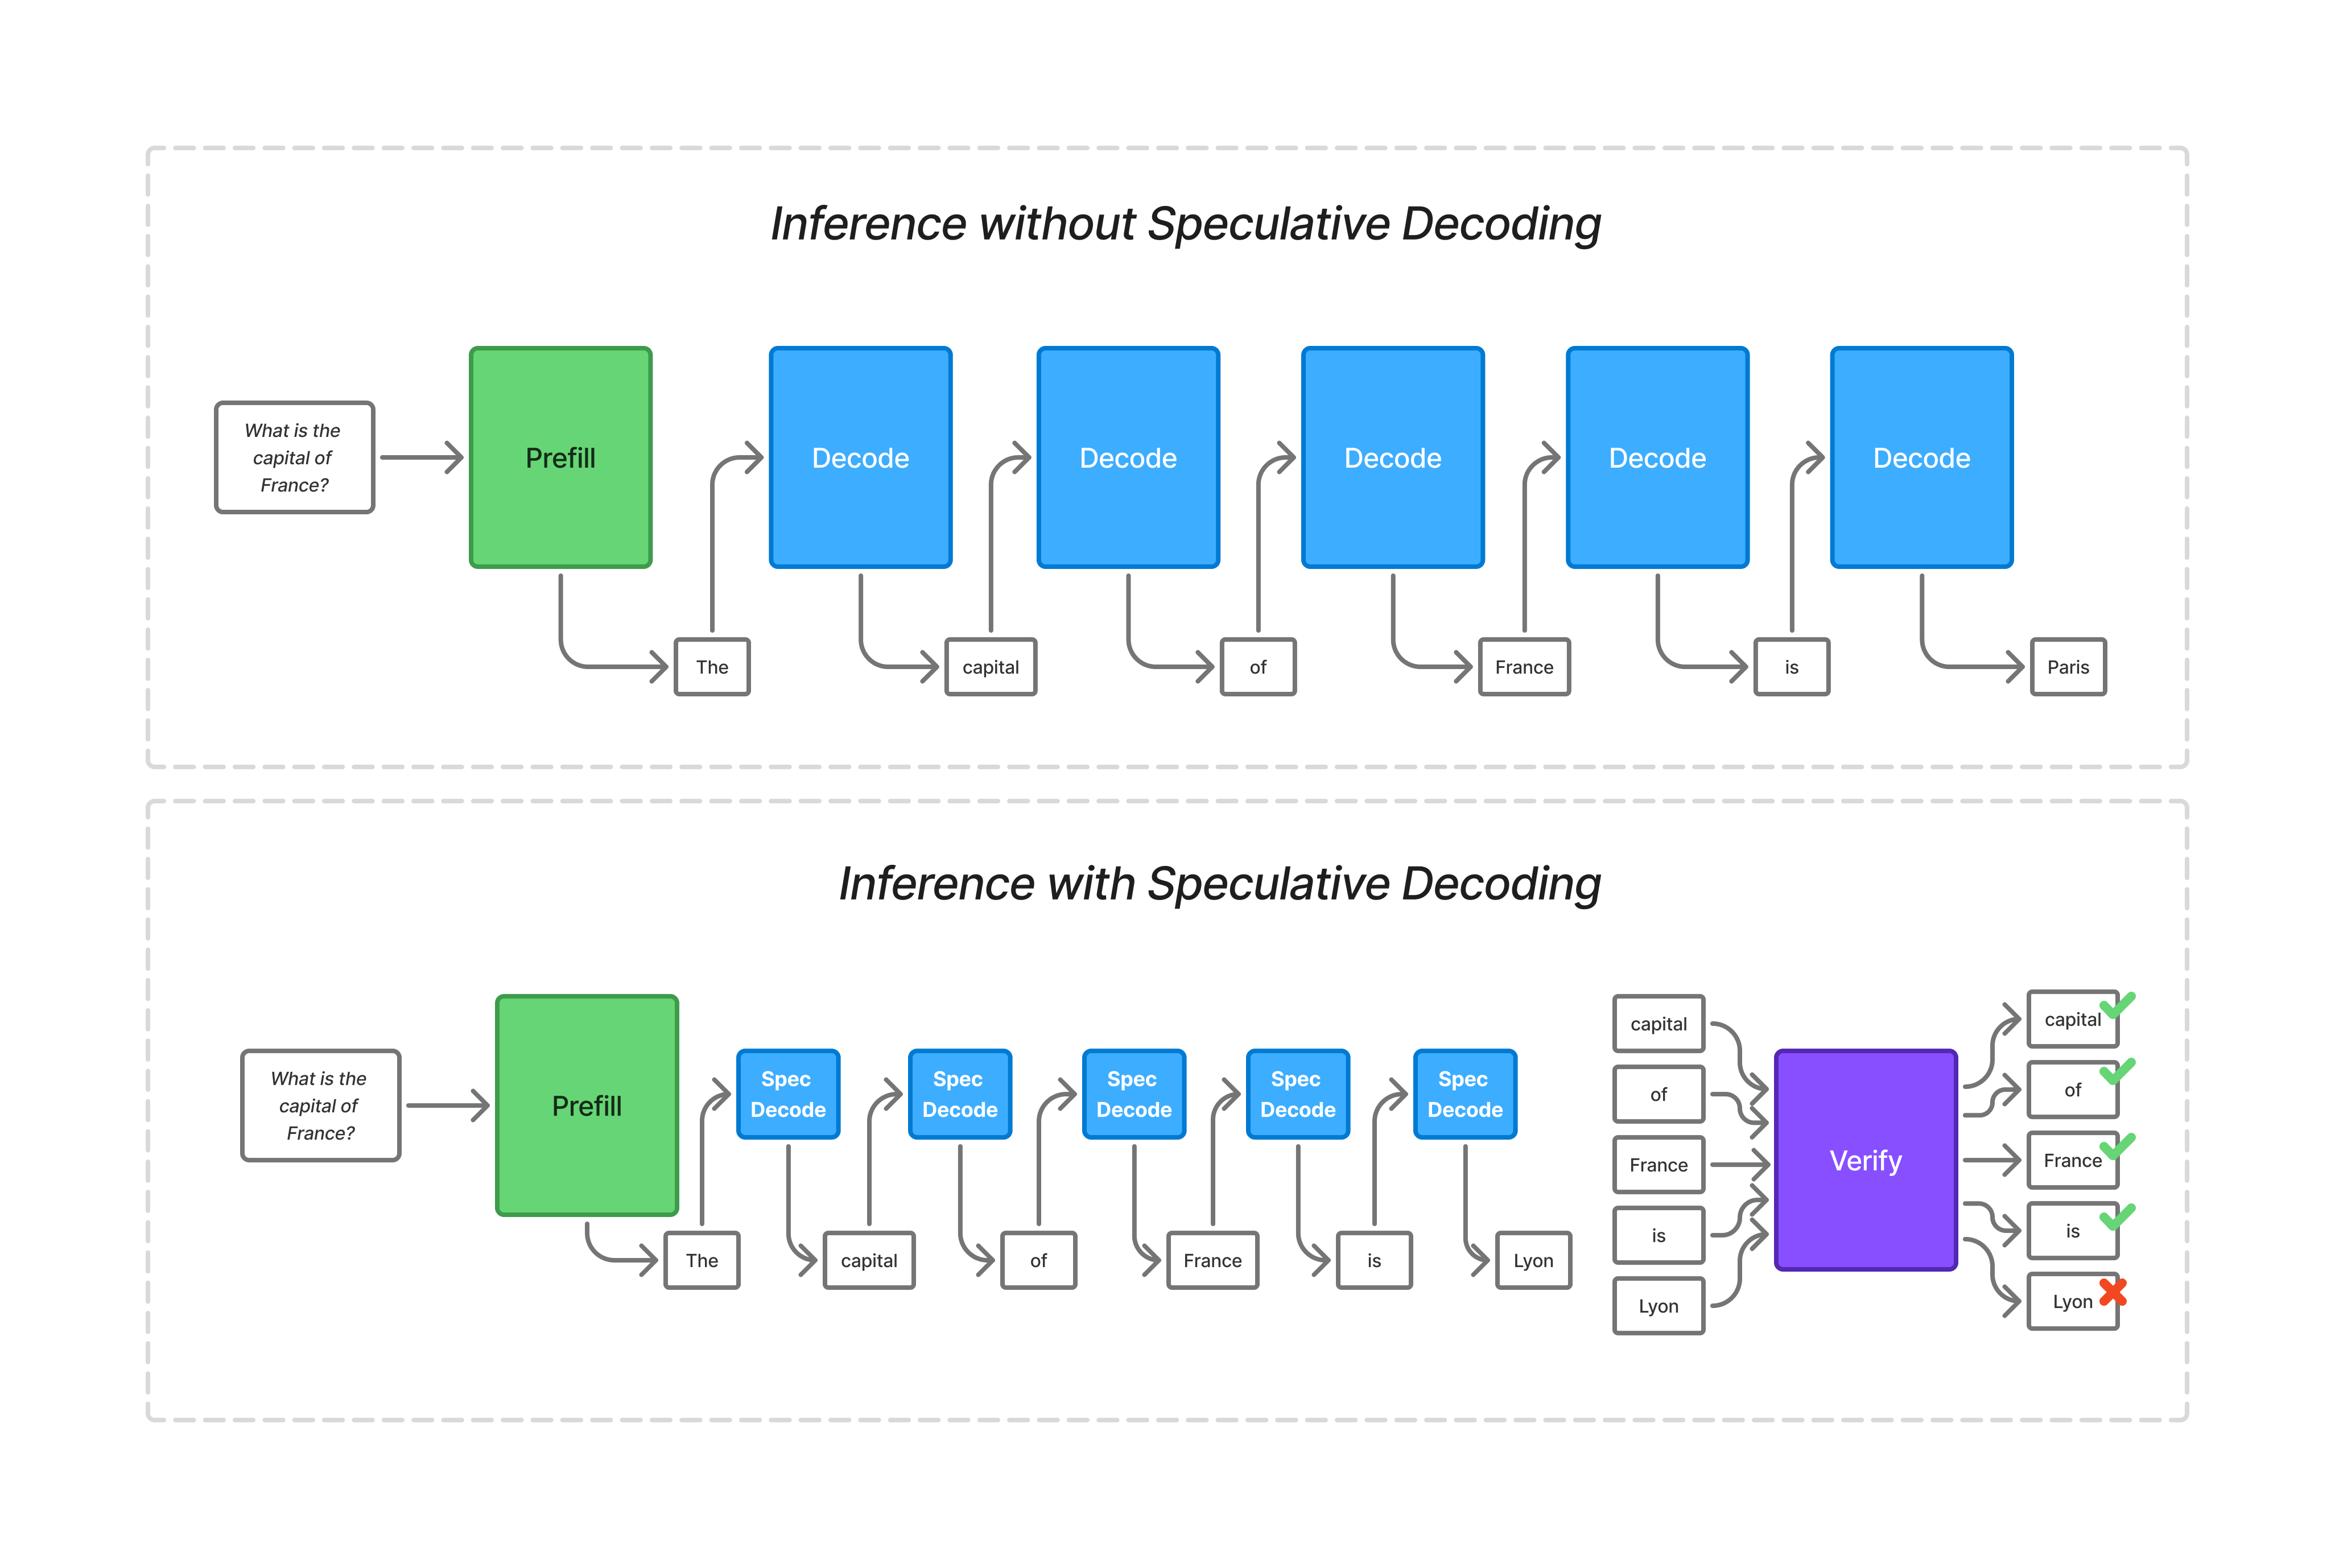
Low-Latency Inference with Speculative Decoding on d-Matrix Corsair and ...
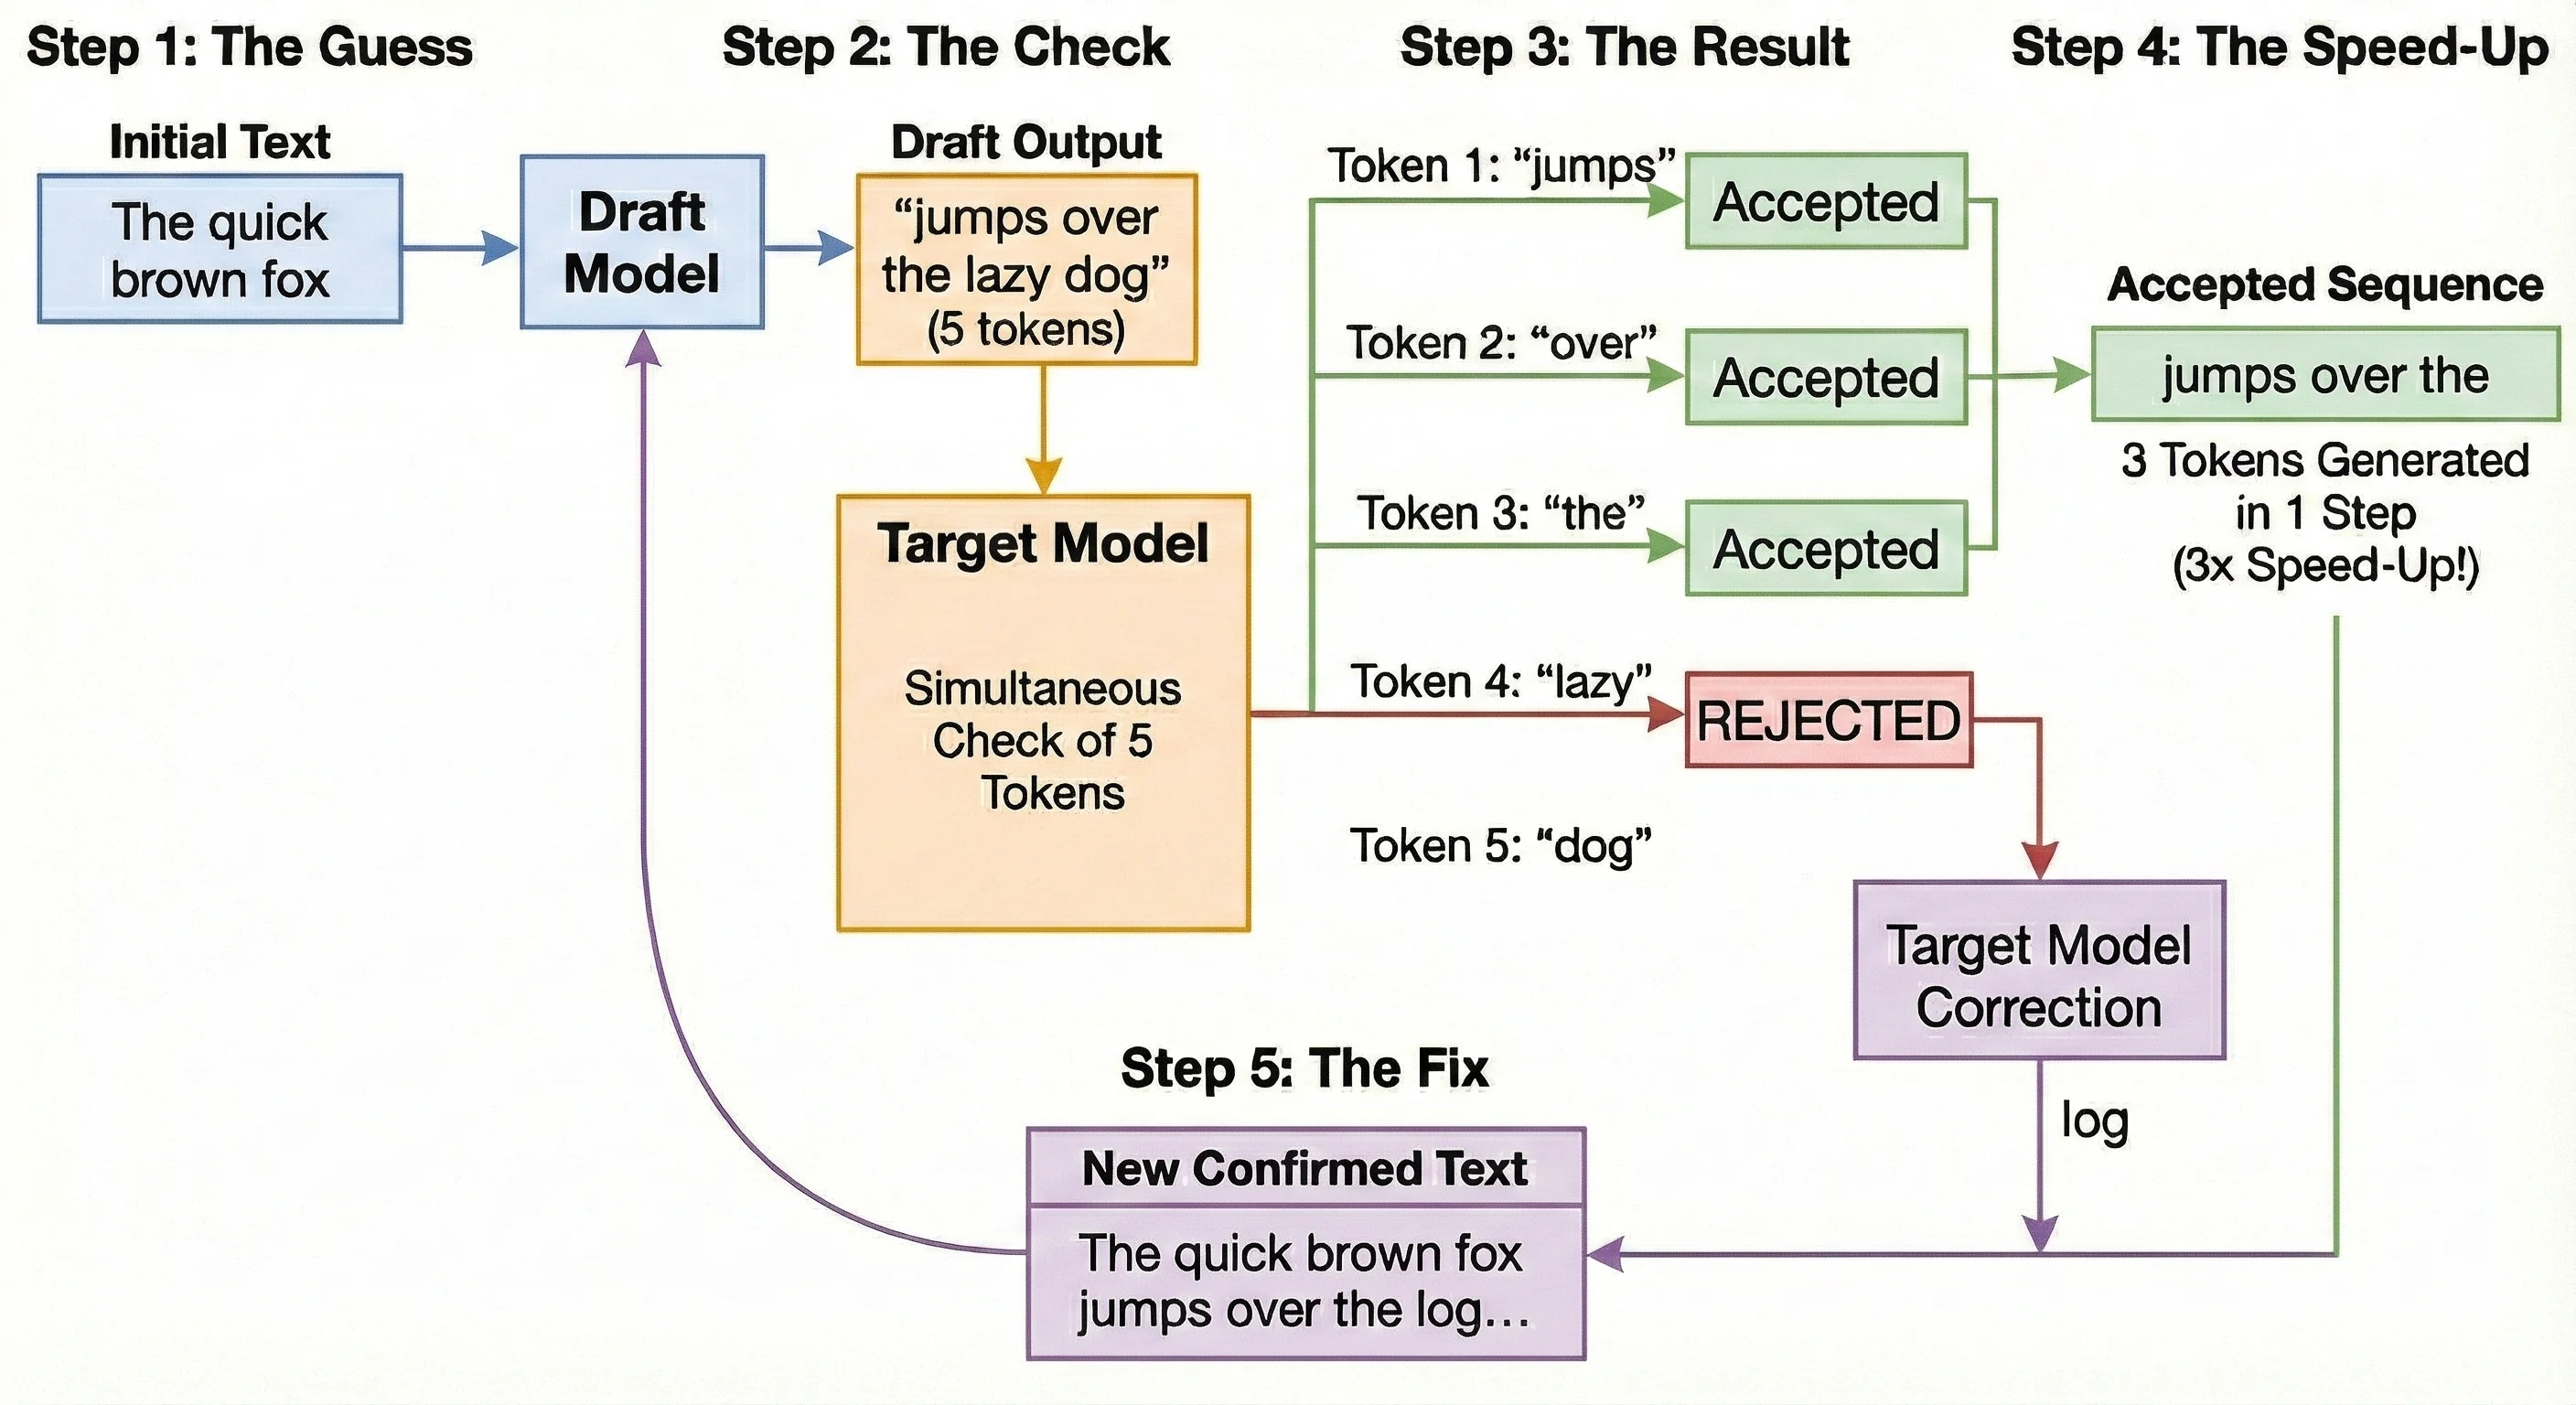
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
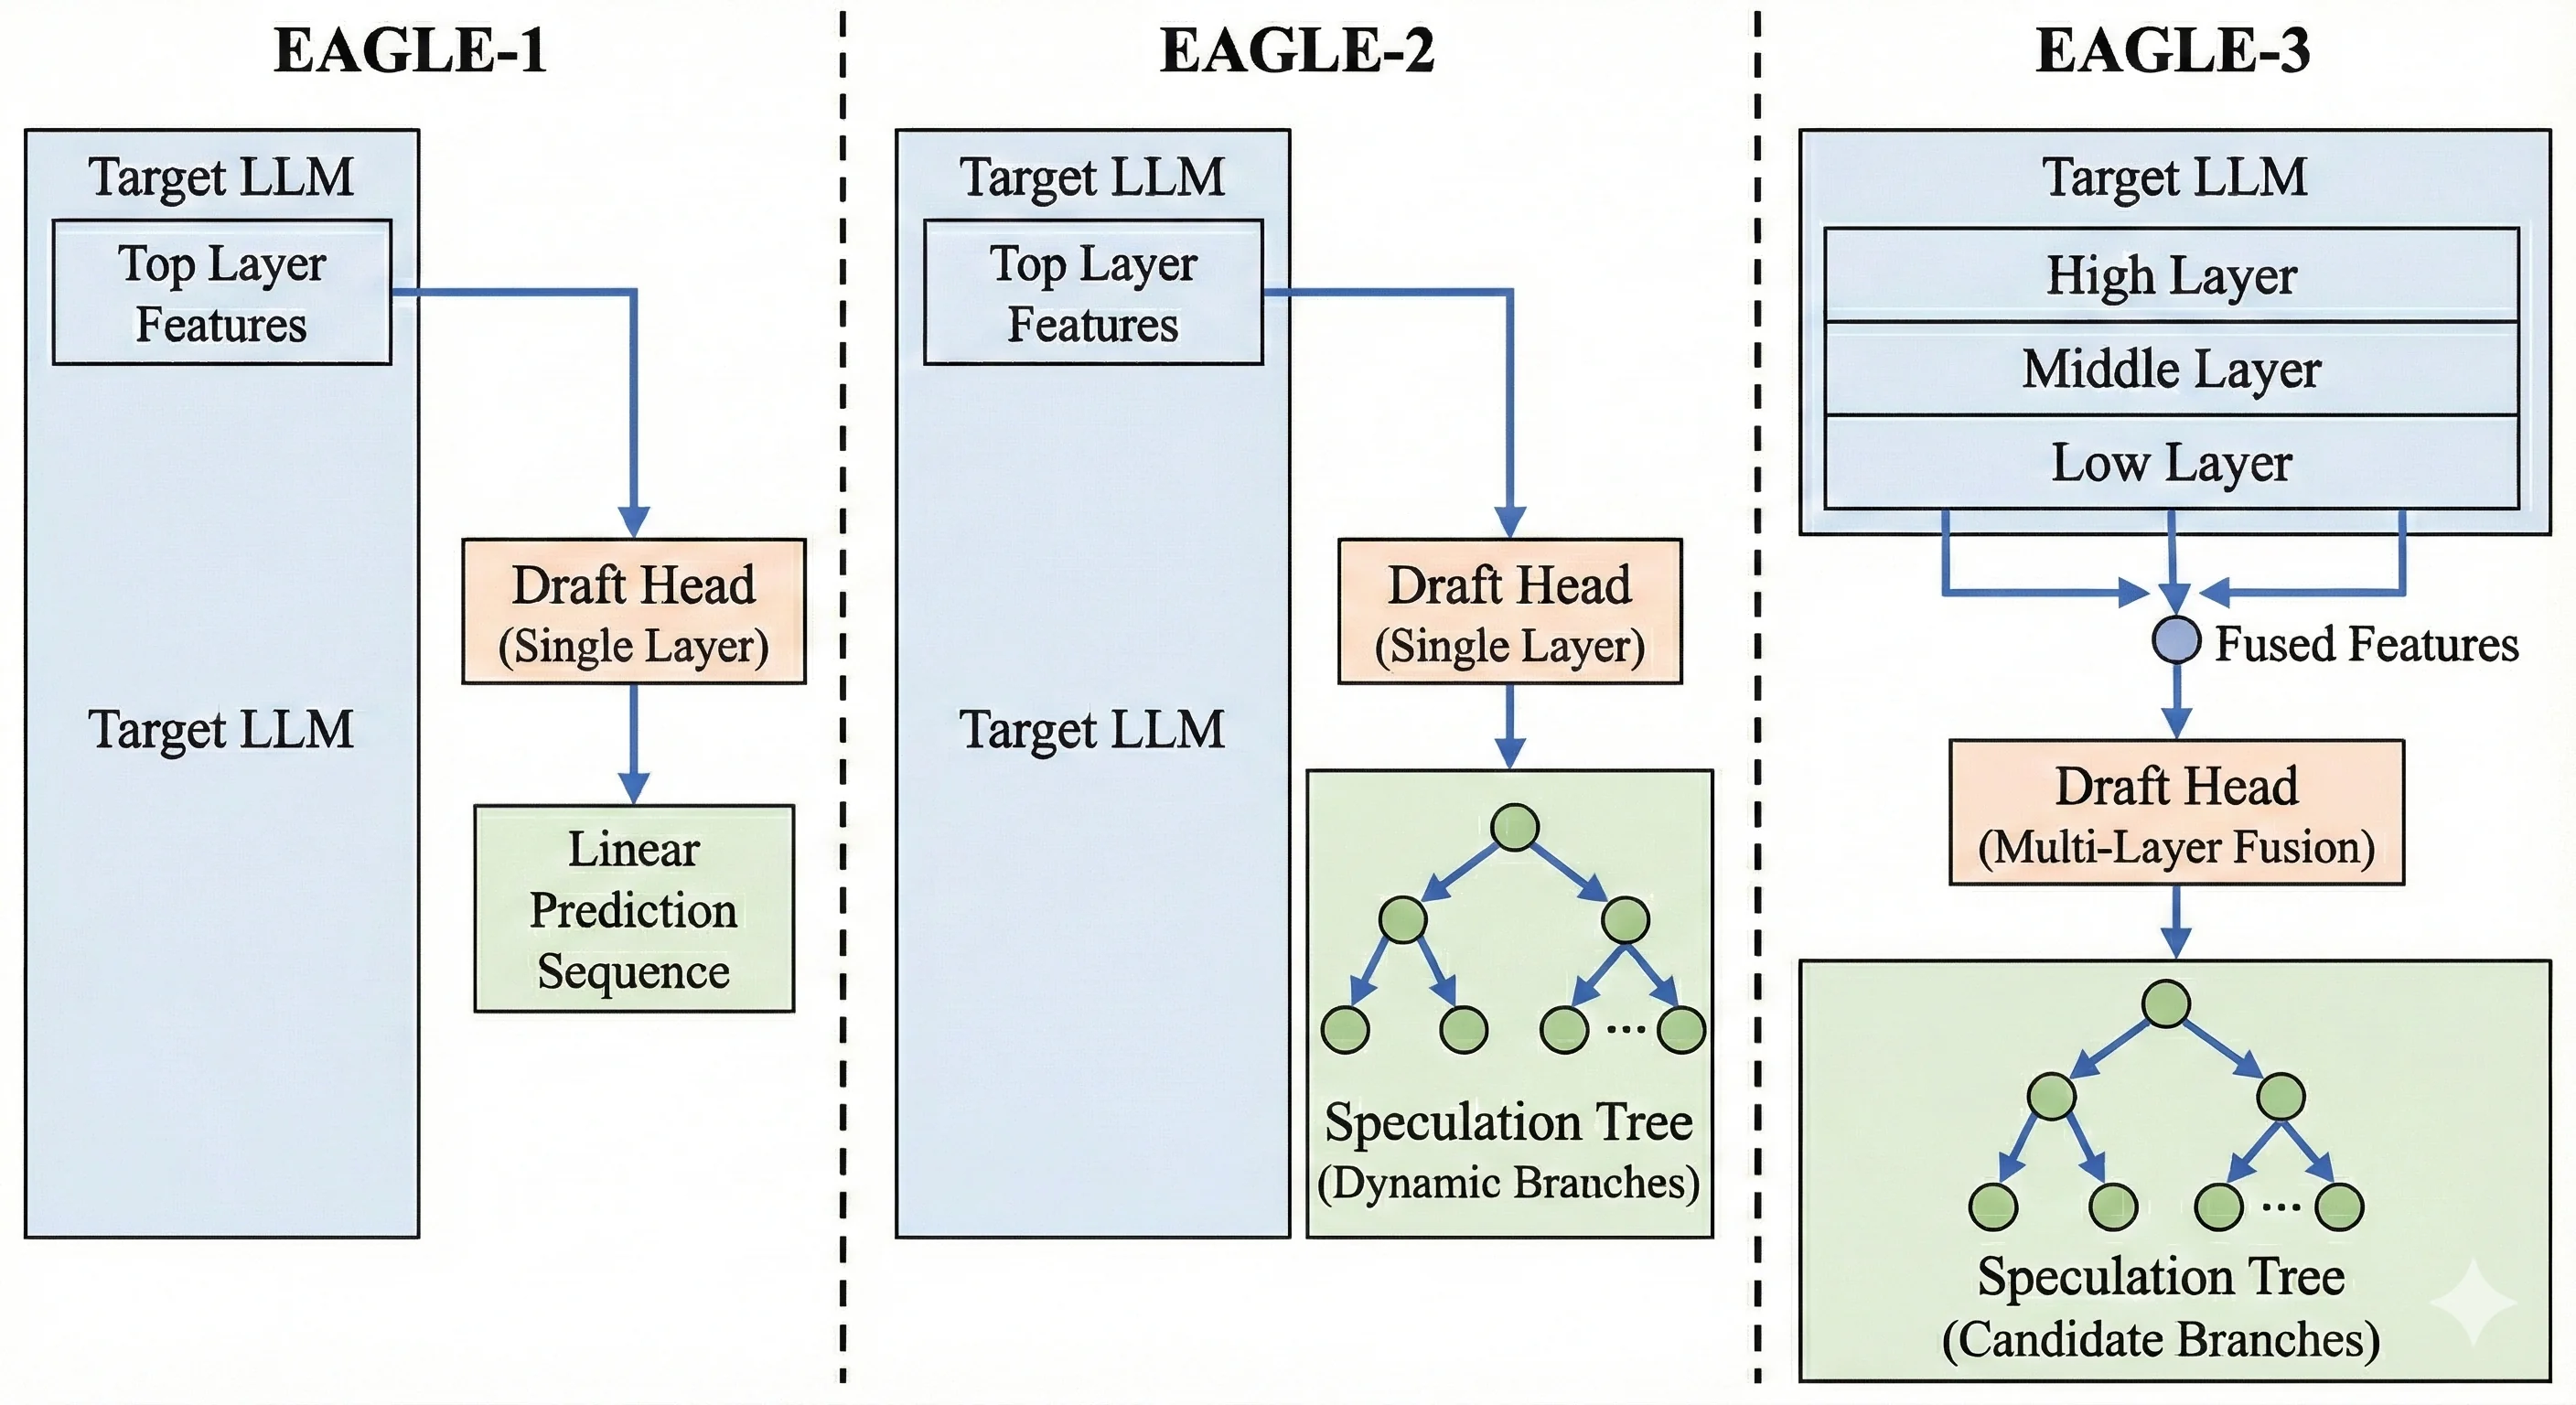
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...

[论文评述] Scaling Speculative Decoding with Lookahead Reasoning
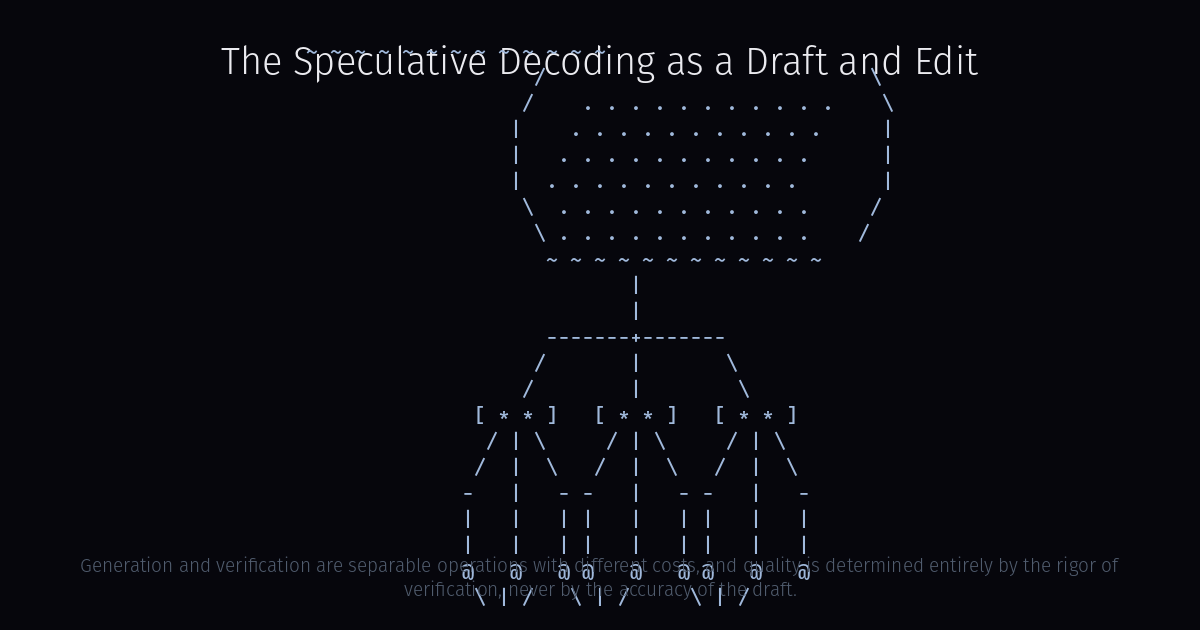
The Speculative Decoding as a Draft and Edit | Emberverse

Speculative Decoding - Making Language Models Generate Faster Without ...

SDFP Speculative Decoding With FIT-Pruned2602.05499v1 | PDF | Computing ...

Speculative Decoding Draft Models - a OpenVINO Collection
Advertisement Space (336x280)

Make Every Draft Count: Hidden State based Speculative Decoding | AI ...
Speculative Decoding for Large Language Models: How Draft and Verifier ...
Speculative Decoding Explained: Faster Inference Without Quality Loss

(PDF) Fast Inference from Transformers via Speculative Decoding

Learning To Draft: Adaptive Speculative Decoding with Reinforcement ...

Speculative Decoding - Making Language Models Generate Faster Without ...

[논문 리뷰] Speeding up Speculative Decoding via Approximate Verification
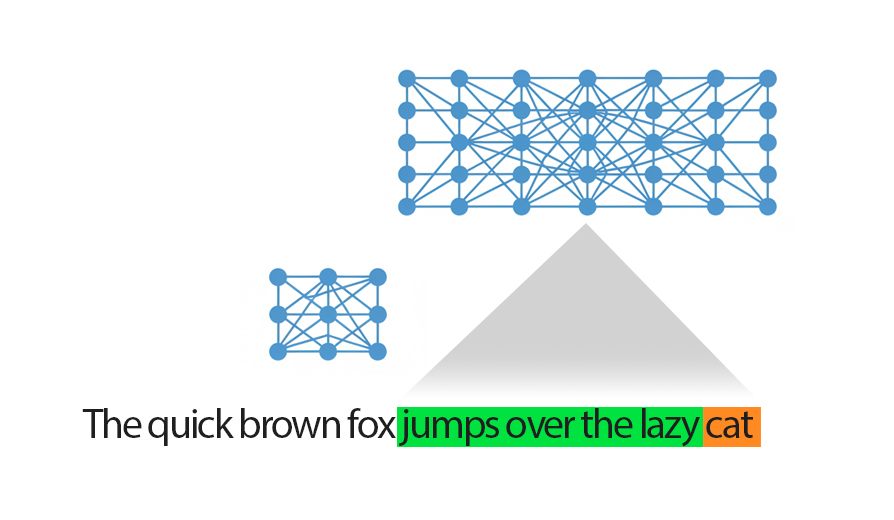
Speculative Decoding Explained: Faster Inference Without Quality Loss
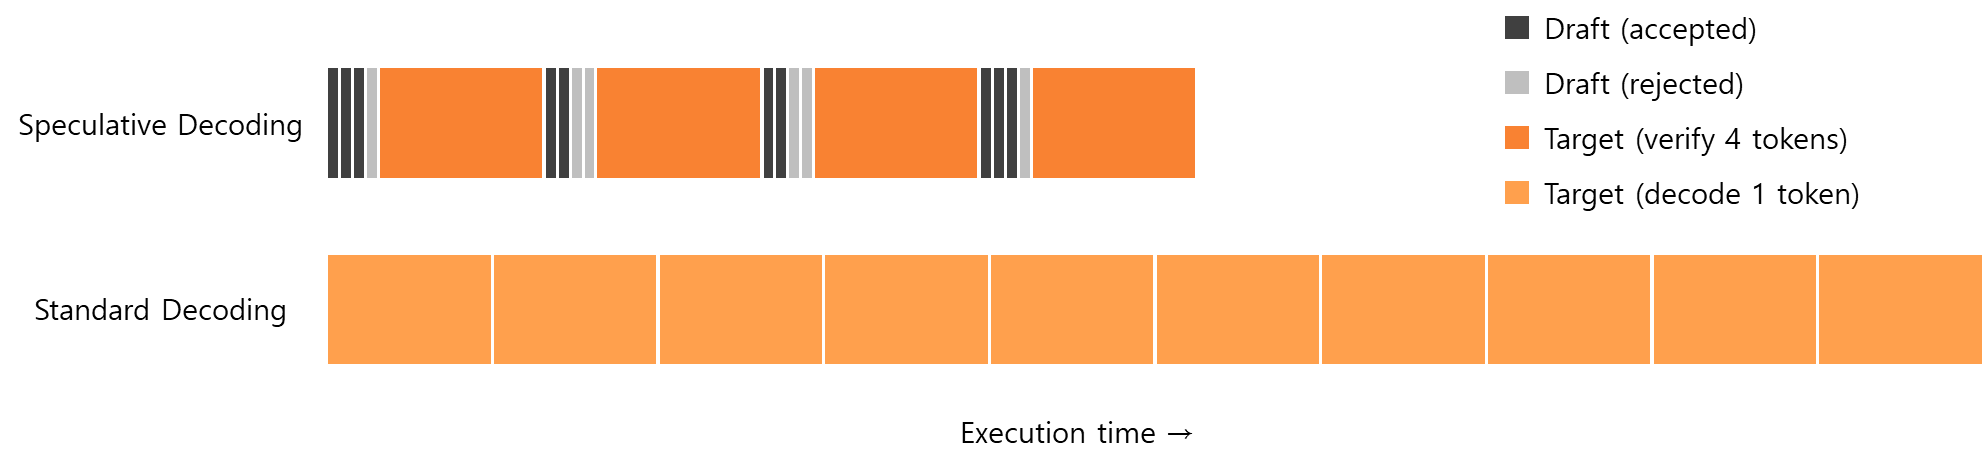
Runtime Draft Model Training: Adapting Speculative Decoding to Real ...
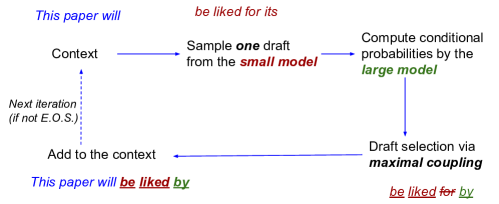
[2310.15141] SpecTr: Fast Speculative Decoding via Optimal Transport
Advertisement Space (336x280)
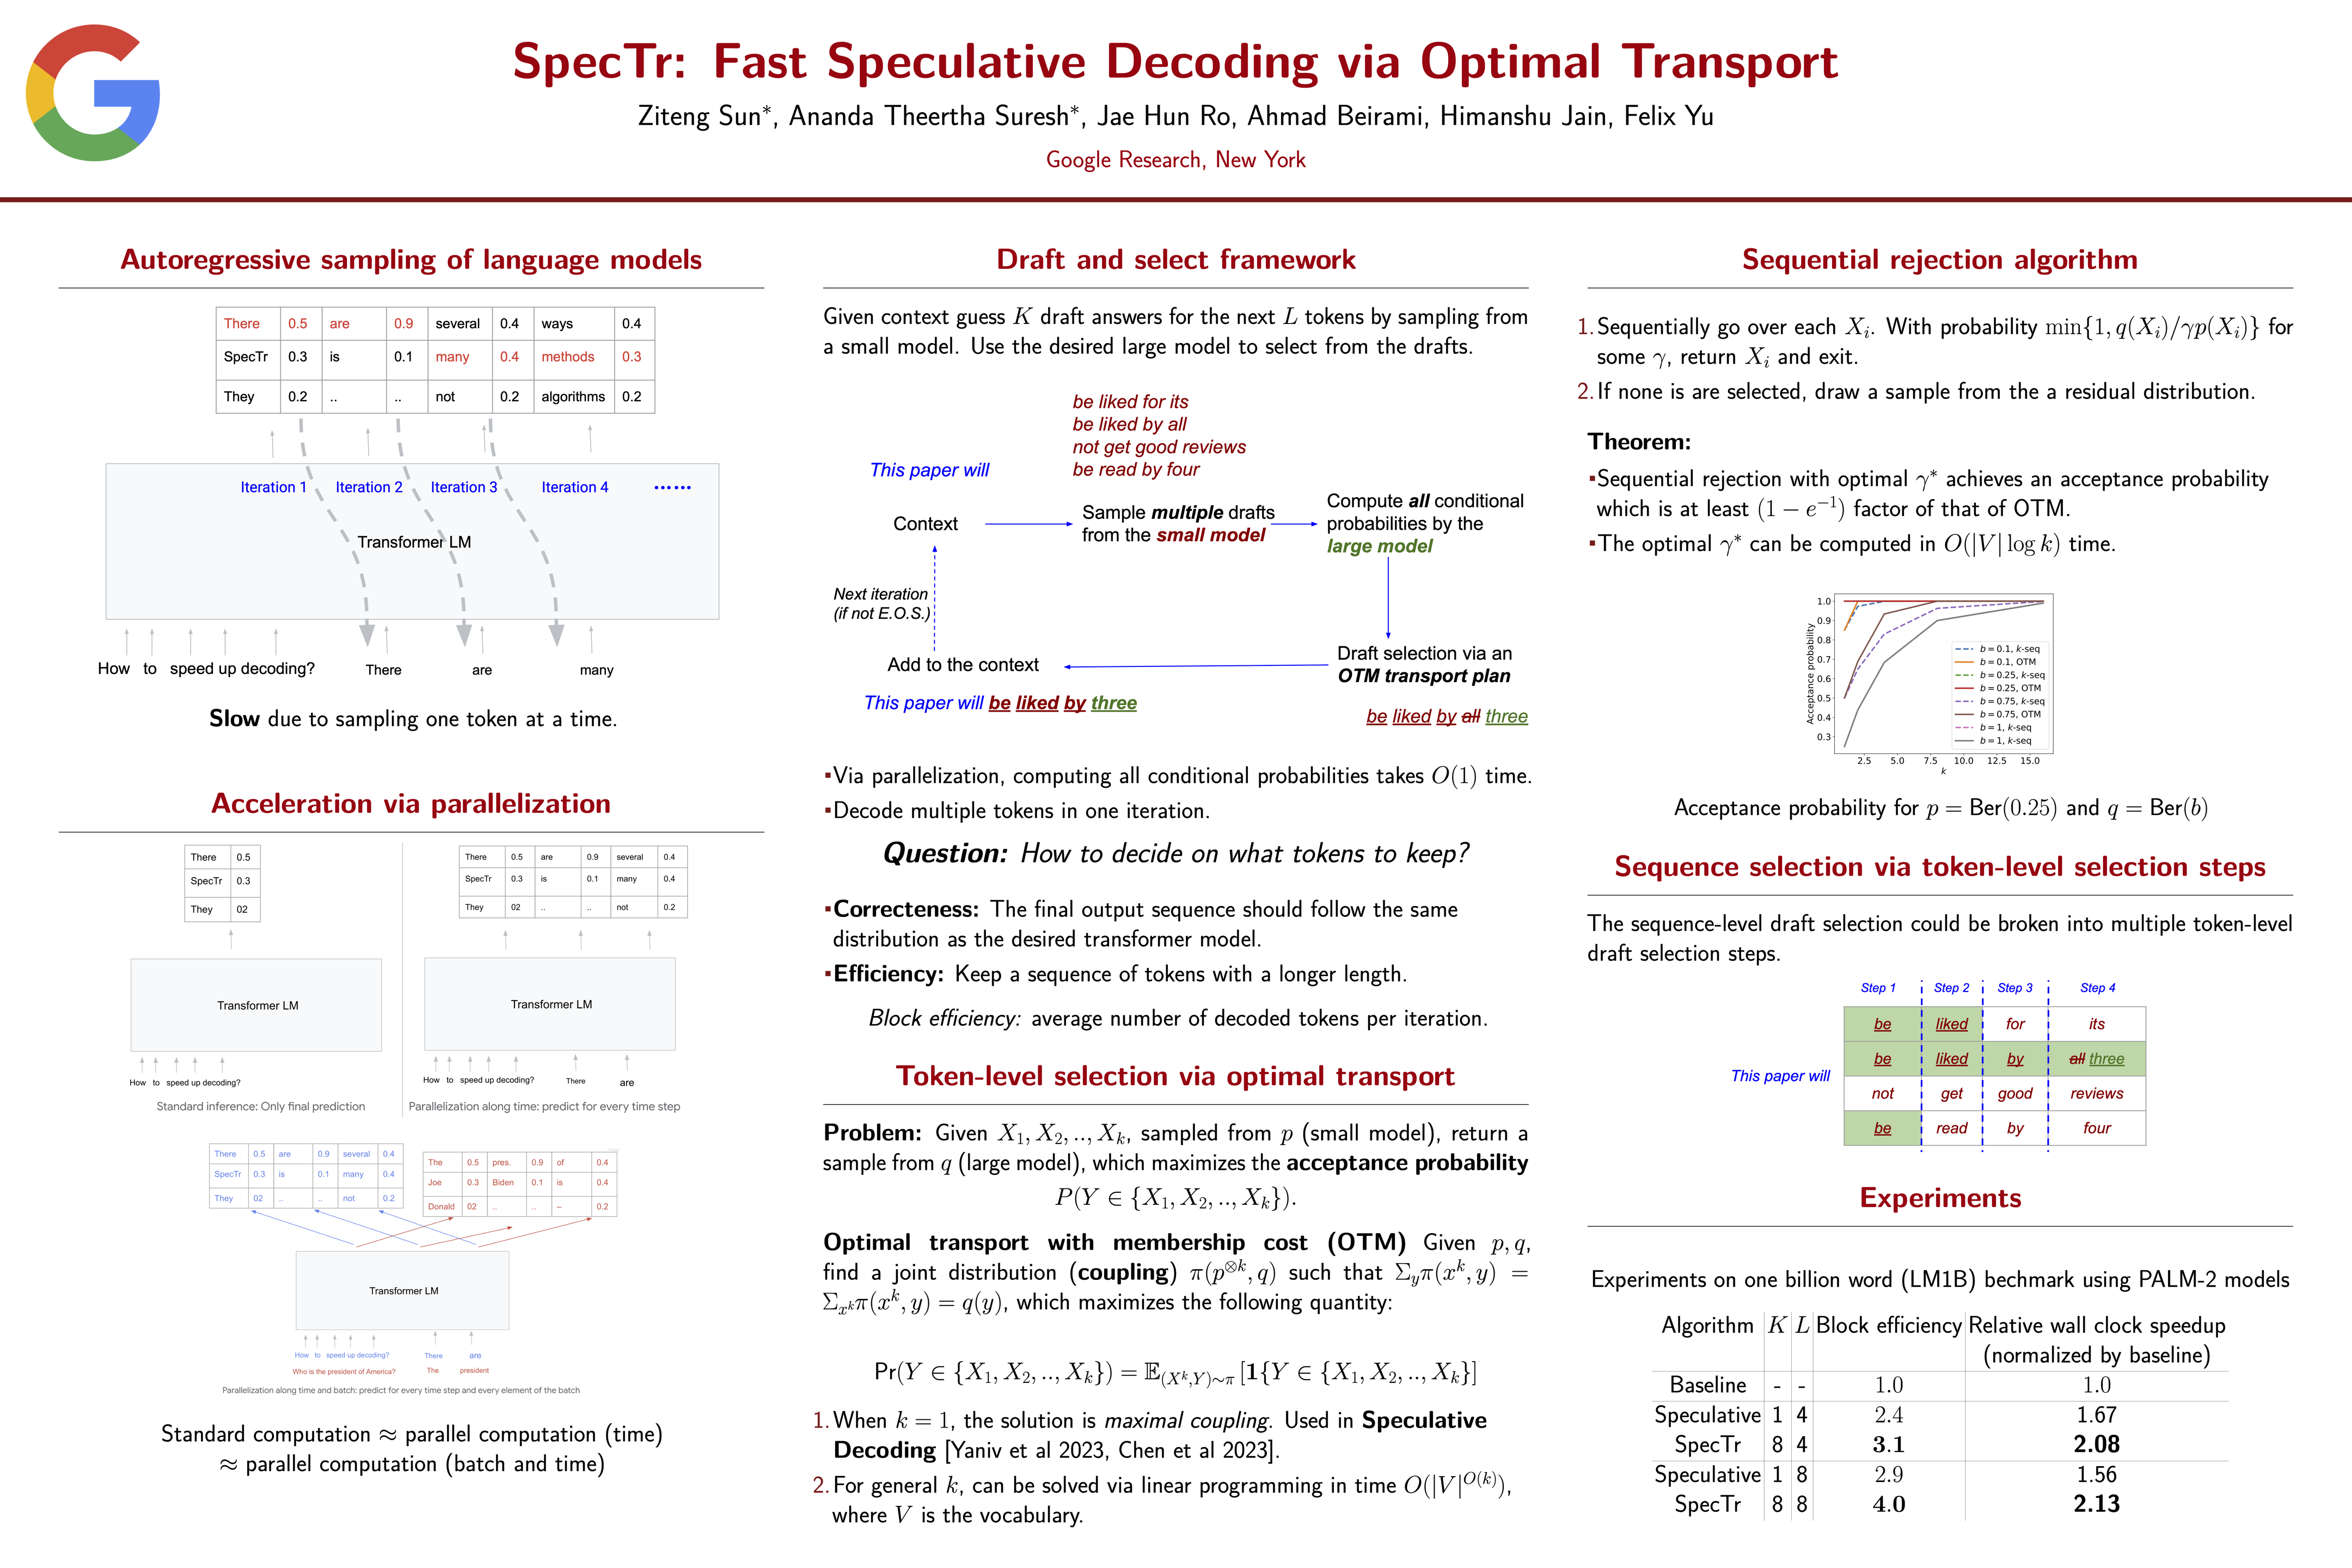
NeurIPS Poster SpecTr: Fast Speculative Decoding via Optimal Transport

[논문 리뷰] BanditSpec: Adaptive Speculative Decoding via Bandit Algorithms

Dynamic Depth Decoding: Faster Speculative Decoding for LLMs | AI ...
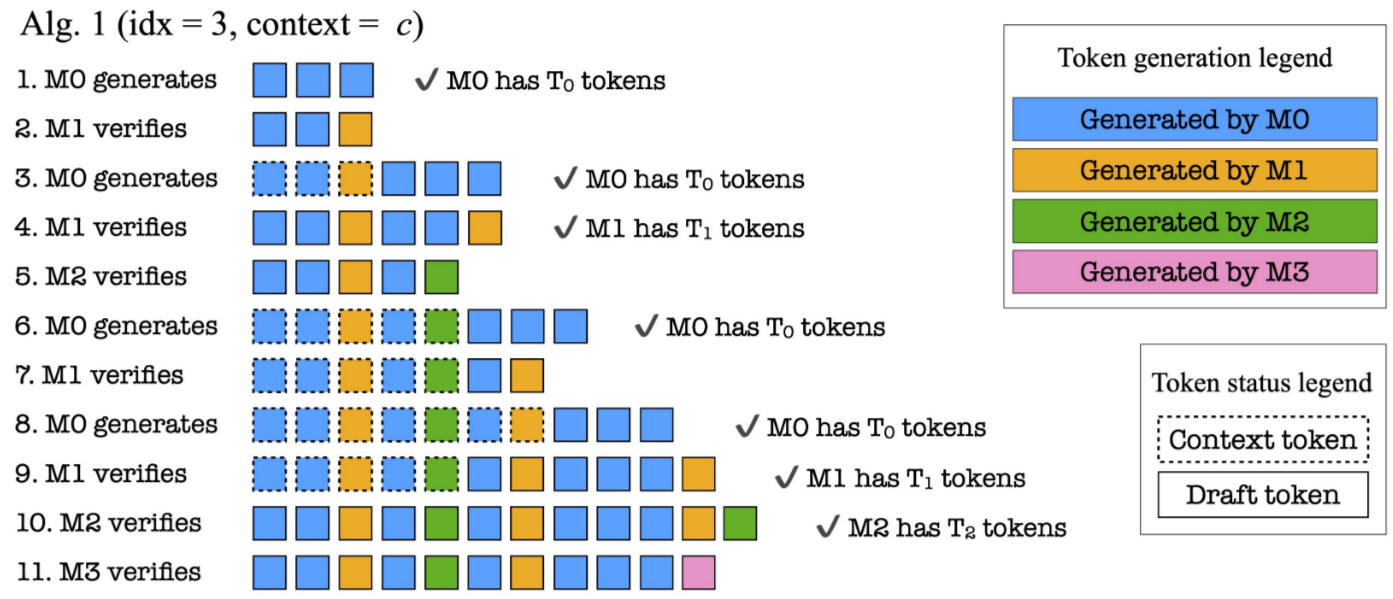
[논문 리뷰] Fast Inference via Hierarchical Speculative Decoding

[논문 리뷰] ParallelSpec: Parallel Drafter for Efficient Speculative Decoding

Speculative Decoding: Unlocking Faster Inference in Transformers