
Figure 1 From A Joint Encoding Model For Image Text Matching Based On

Figure 1 from A Joint Encoding Model for Image-Text Matching Based on ...

Figure 1 from A Joint Encoding Model for Image-Text Matching Based on ...

Figure 1 from A Joint Encoding Model for Image-Text Matching Based on ...

Figure 1 from A Joint Encoding Model for Image-Text Matching Based on ...

Table 1 from A Joint Encoding Model for Image-Text Matching Based on ...

Figure 1 from A Multimodal Text Matching Model for Obfuscated Language ...
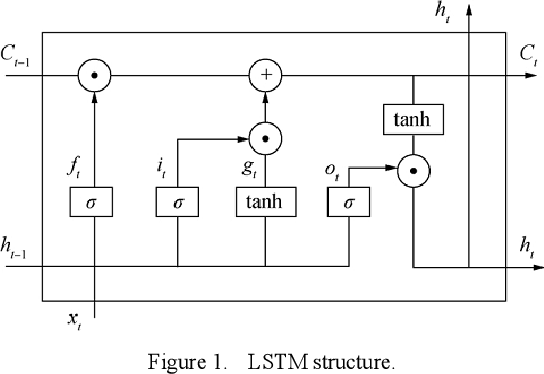
Figure 1 from Text Classification Based on A New Joint Network ...

Figure 1 from Encoding Text Information By Pre-trained Model For ...

Figure 1 from A Novel Joint Extraction Model for Entity Relations Using ...
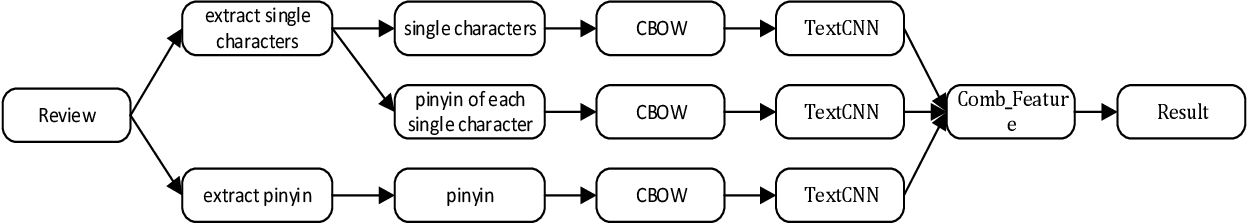
Figure 1 from A Novel Text Features Jointing Model for Review Spam ...
Advertisement Space (300x250)
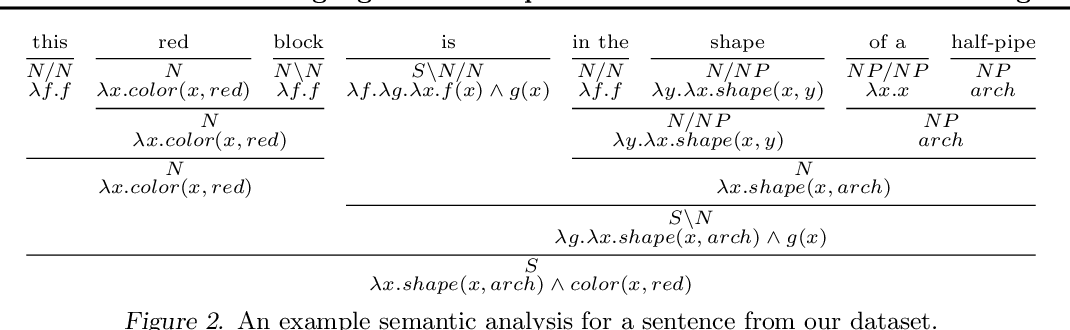
Figure 1 from A Joint Model of Language and Perception for Grounded ...

Figure 1 from A Probabilistic Model for Joint Learning of Word ...

Figure 1 from Multispectral palmprint matching based on joint sparse ...

Figure 1 from Text-to-Image Synthesis based on Object-Guided Joint ...
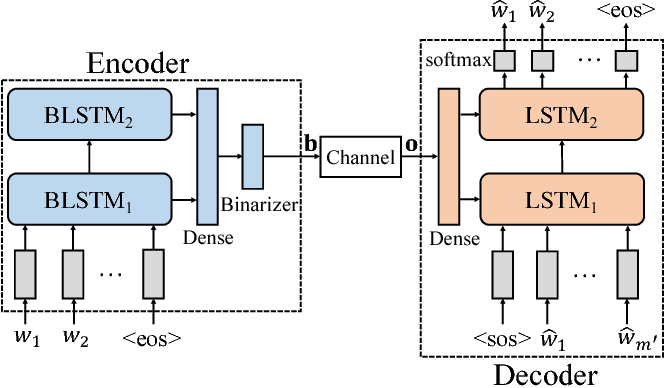
Figure 1 from Deep Learning for Joint Source-Channel Coding of Text ...

Figure 1 from Joint Token and Feature Alignment Framework for Text ...

Figure 1 from Joint Input-Label Embedding for Neural Text ...
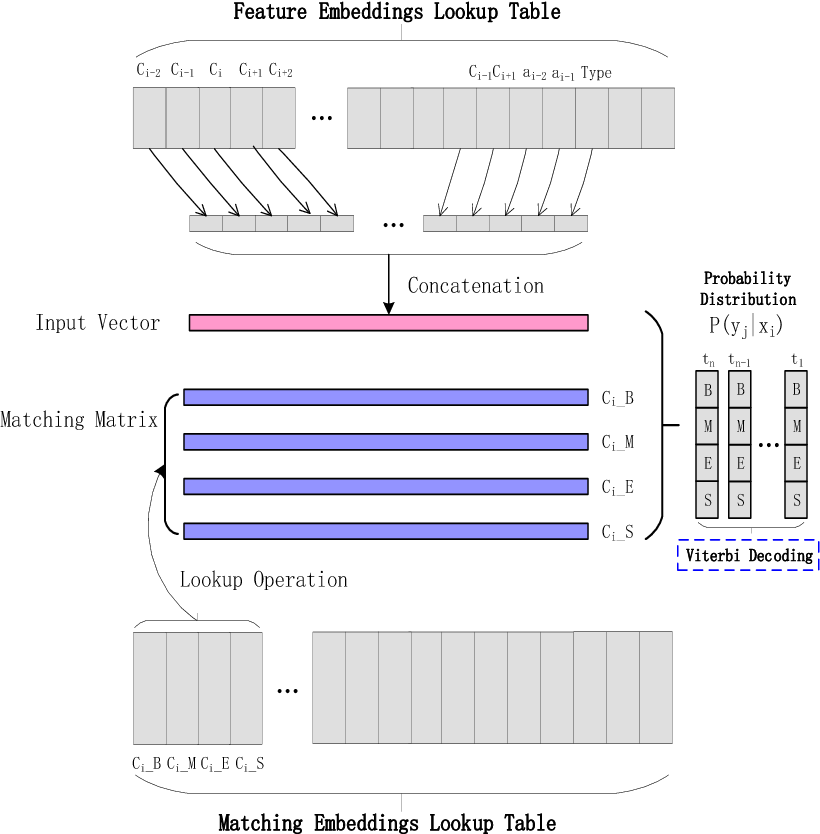
Figure 1 from An improved embedding matching model for Chinese word ...

Figure 1 from Text-Image Matching for Cross-Modal Remote Sensing Image ...
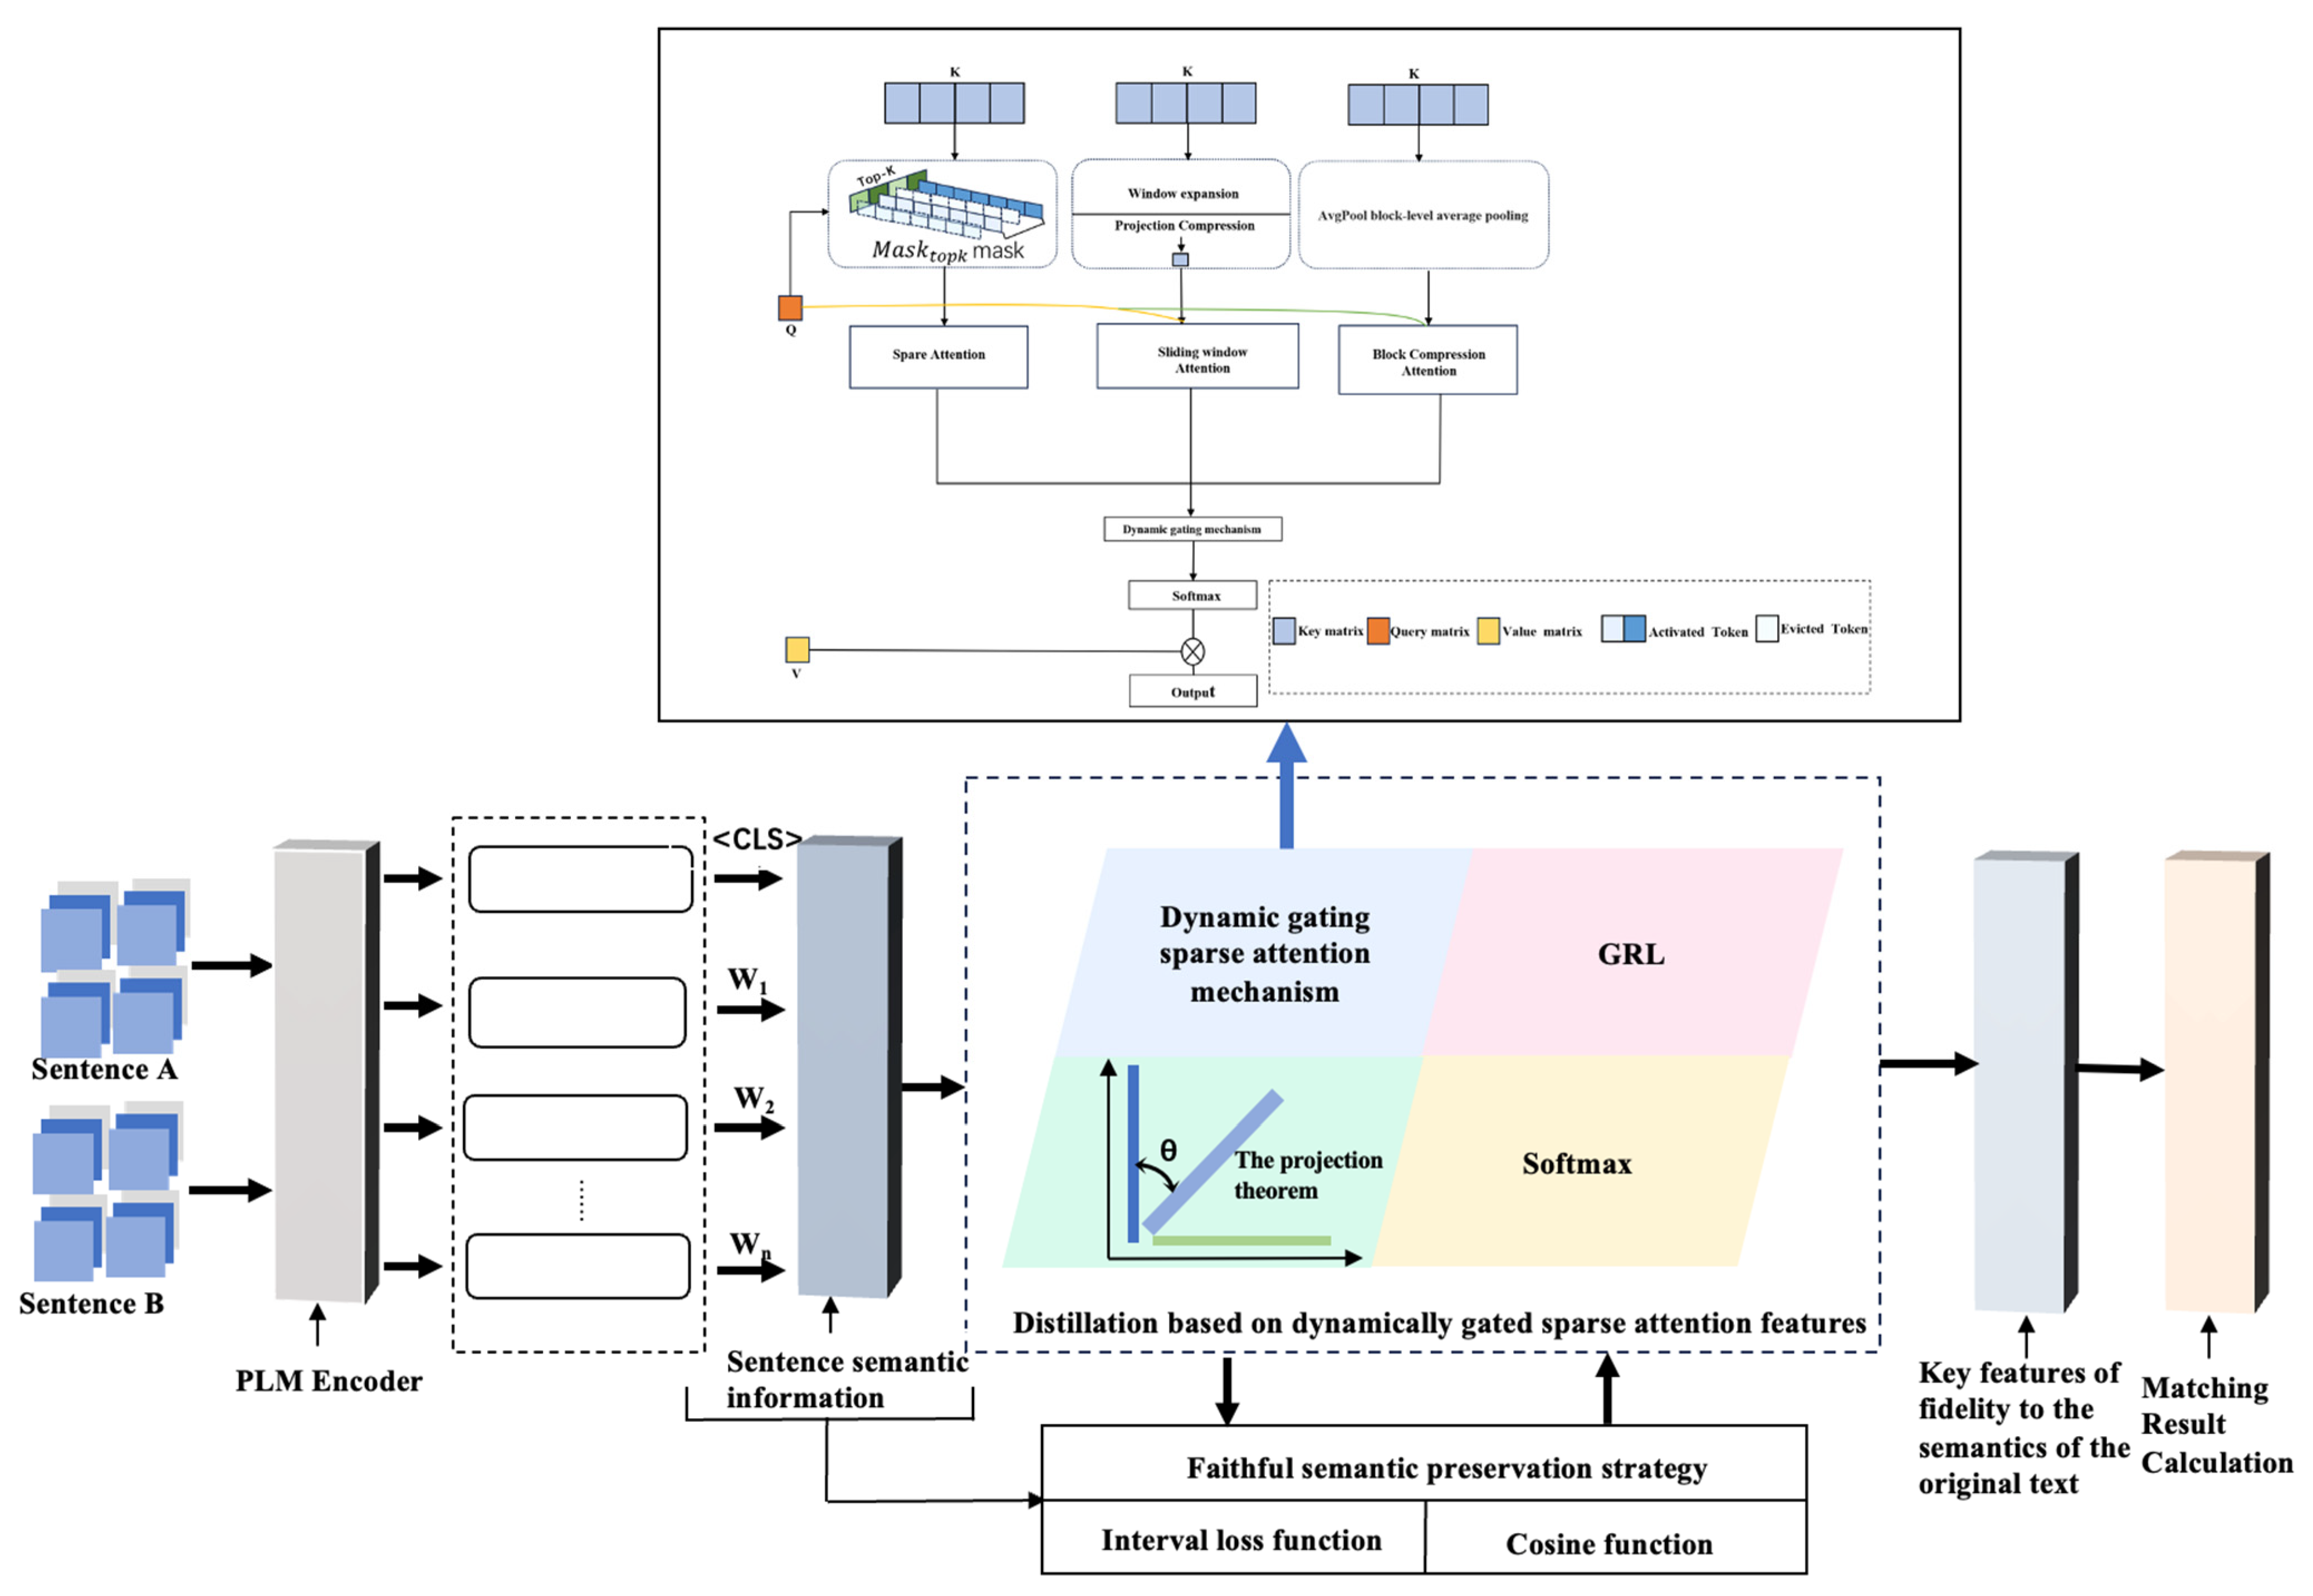
A Symmetric Dual-Drive Text Matching Model Based on Dynamically Gated ...
Advertisement Space (336x280)
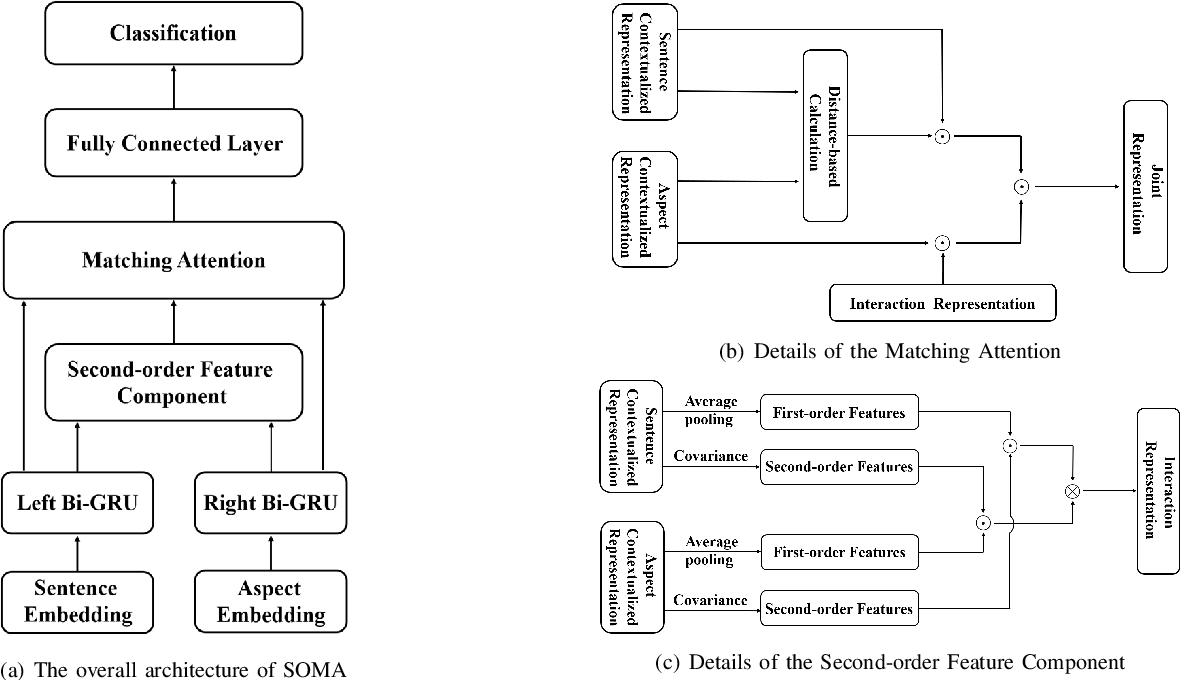
Figure 1 from A Novel Joint Model with Second-Order Features and ...
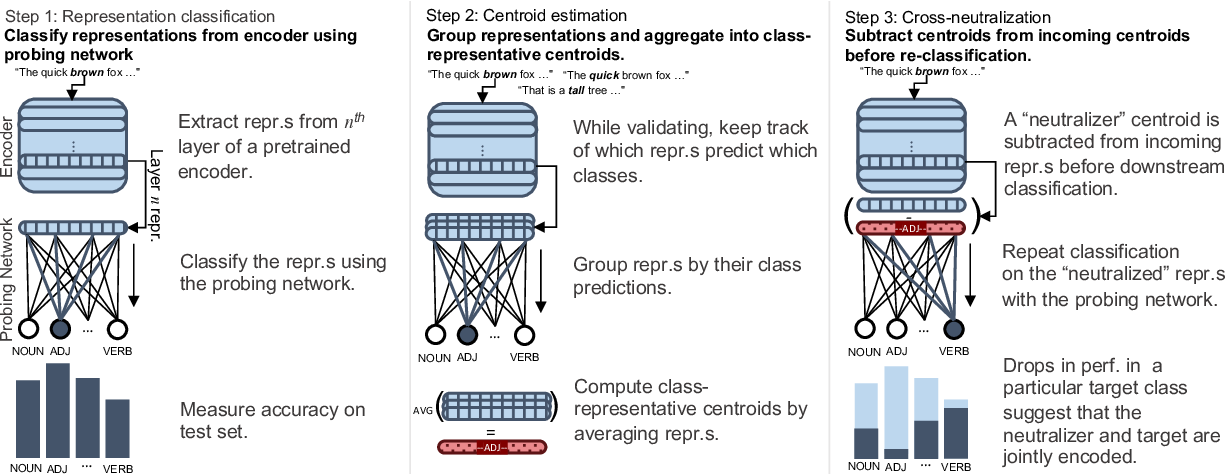
Figure 1 from Probing LLMs for Joint Encoding of Linguistic Categories ...

Figure 1 from Image and Encoded Text Fusion for Deep Multi-Modal ...
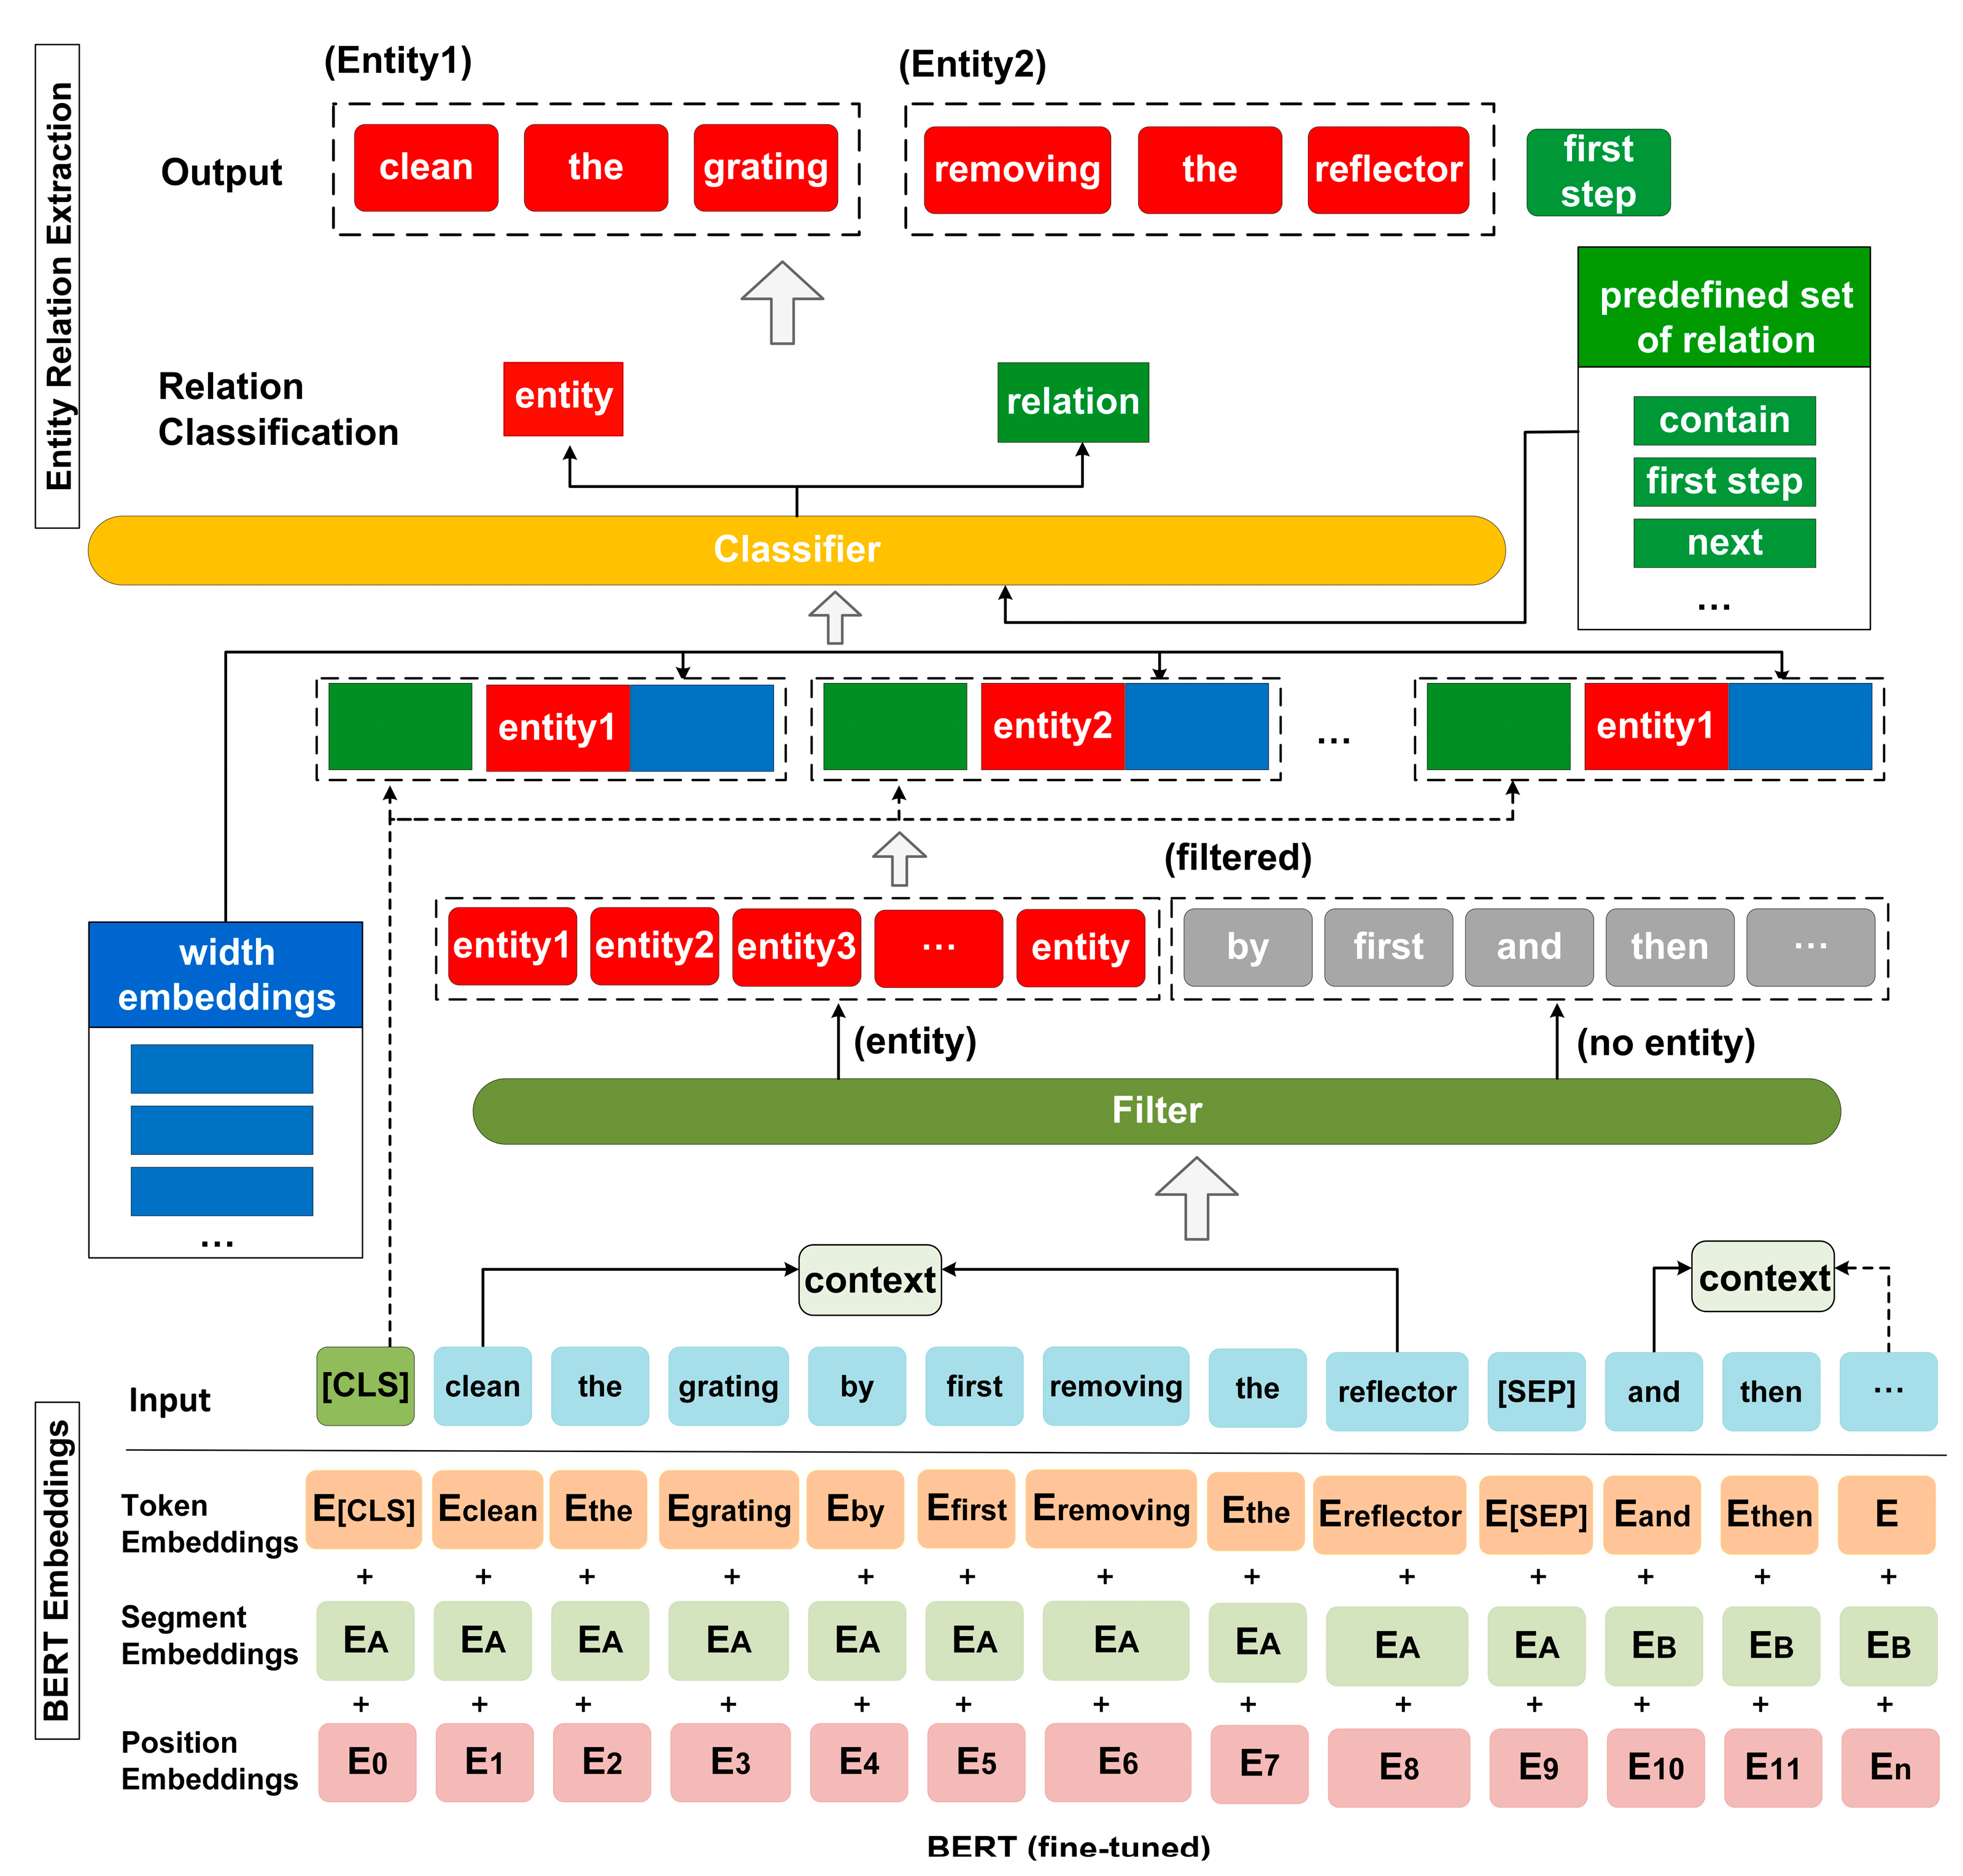
Knowledge Graph Construction Based on a Joint Model for Equipment ...

Figure 1 from Grounded Image Text Matching with Mismatched Relation ...

Figure 1 from Collaborative Encoding Method for Scene Text Recognition ...

Figure 1 from Evidence for joint encoding of motion and disparity in ...

Figure 1 from The Short Text Matching Model Enhanced with Knowledge via ...
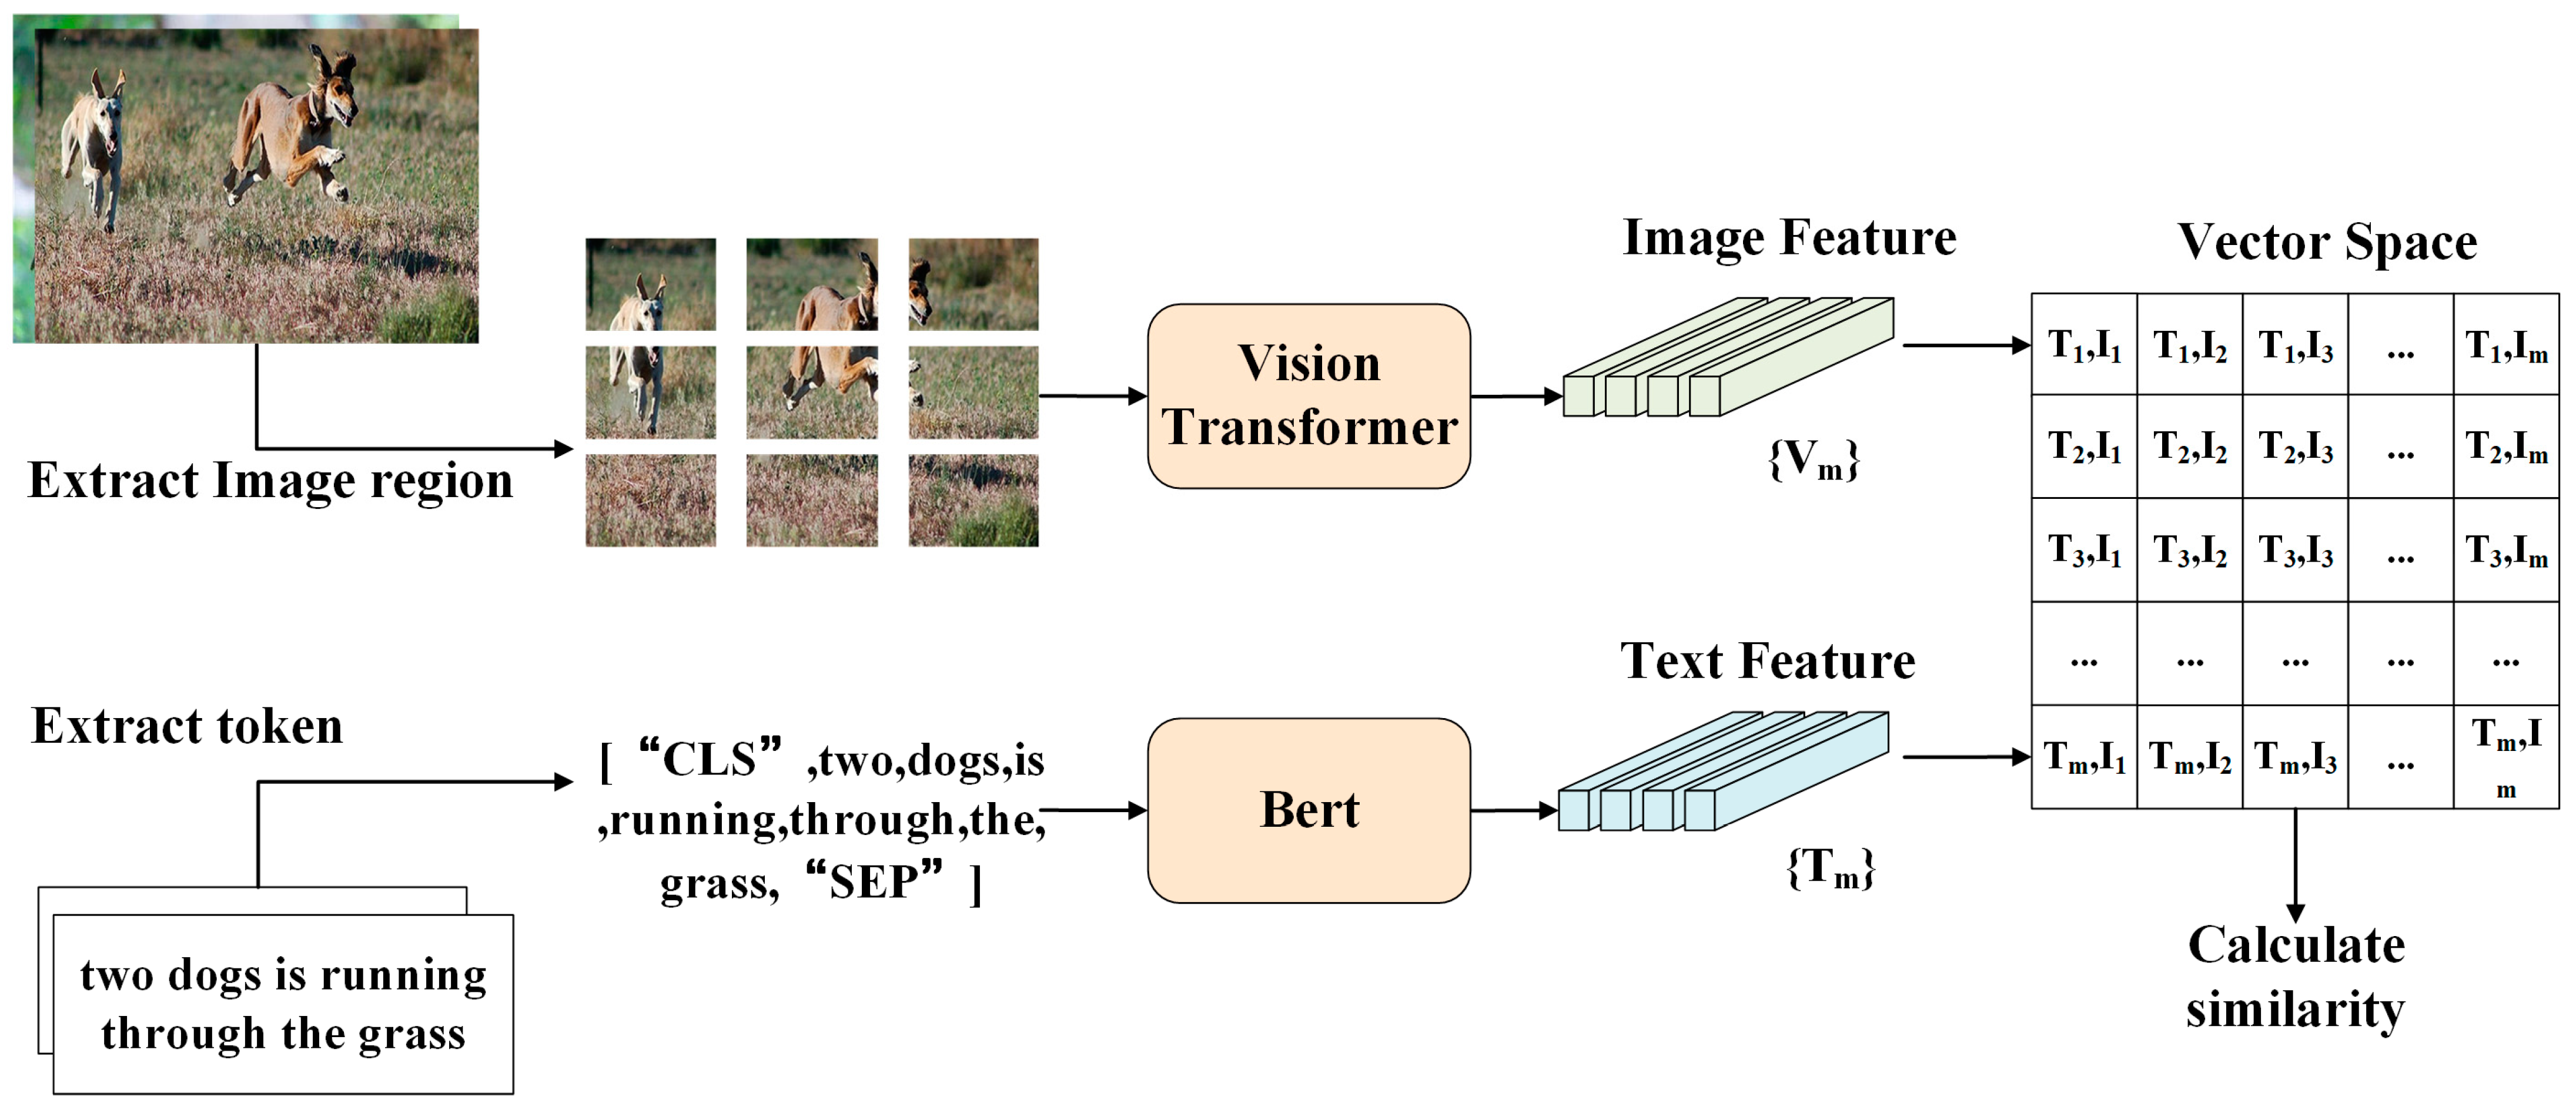
Image–Text Matching Model Based on CLIP Bimodal Encoding | MDPI

Figure 1 from JECL: Joint Embedding and Cluster Learning for Image-Text ...
Advertisement Space (336x280)

Figure 1 from Discrete Joint Semantic Alignment Hashing for Cross-Modal ...
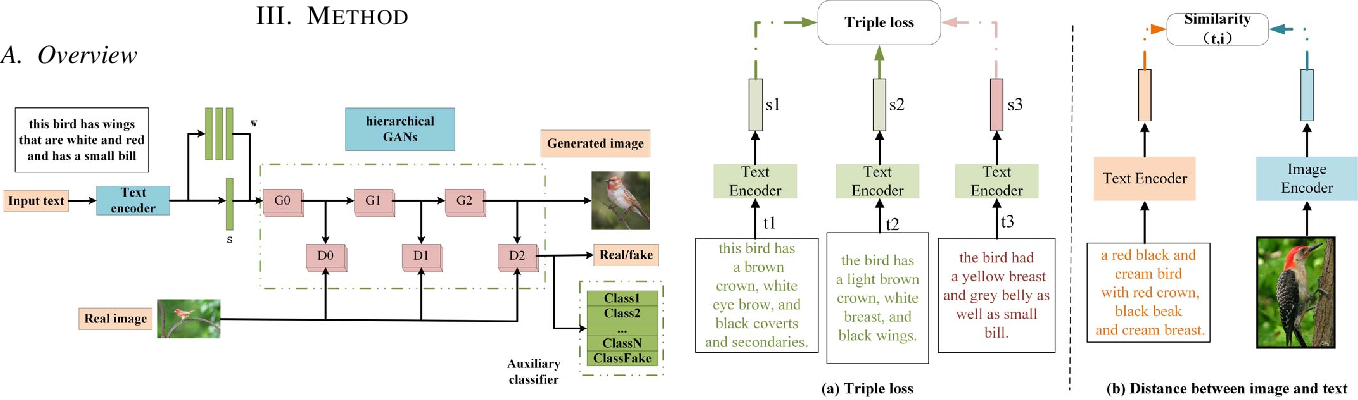
Figure 1 from Joint Embedding based Text-to-Image Synthesis | Semantic ...

Figure 1 from Simple and Effective Text Matching with Richer Alignment ...

Figure 1 from Pair-Based Joint Encoding with Relational Graph ...
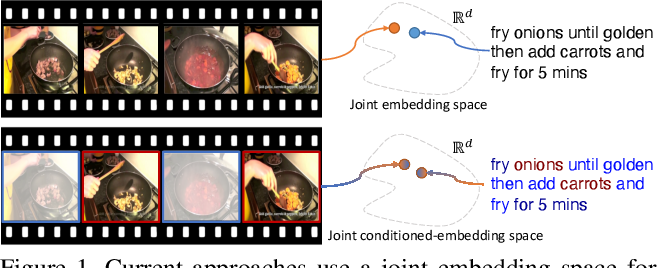
Figure 1 from Video and Text Matching with Conditioned Embeddings ...

Image–Text Matching Model Based on CLIP Bimodal Encoding