
Figure 1 From A Method Of Multi Layered Speech Segmentation Tailored

Figure 1 from A method of multi-layered speech segmentation tailored ...
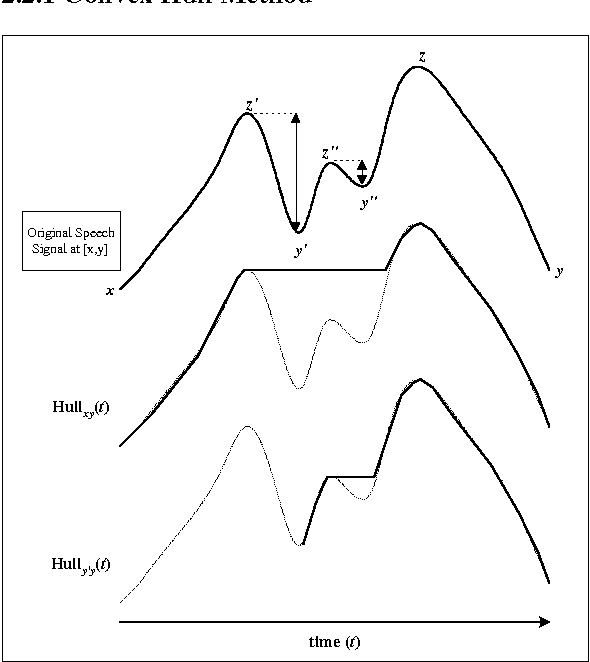
Figure 1 from A Comparative Study of Speech Segmentation and ...

Figure 1 from A c/v segmentation method for Mandarin speech based on ...

Figure 1 from A segmentation method for noisy speech using genetic ...

Figure 1 from Speech Segmentation Algorithm Based on an Analysis of the ...

Figure 1 from Syllable segmentation of thai human speech using ...
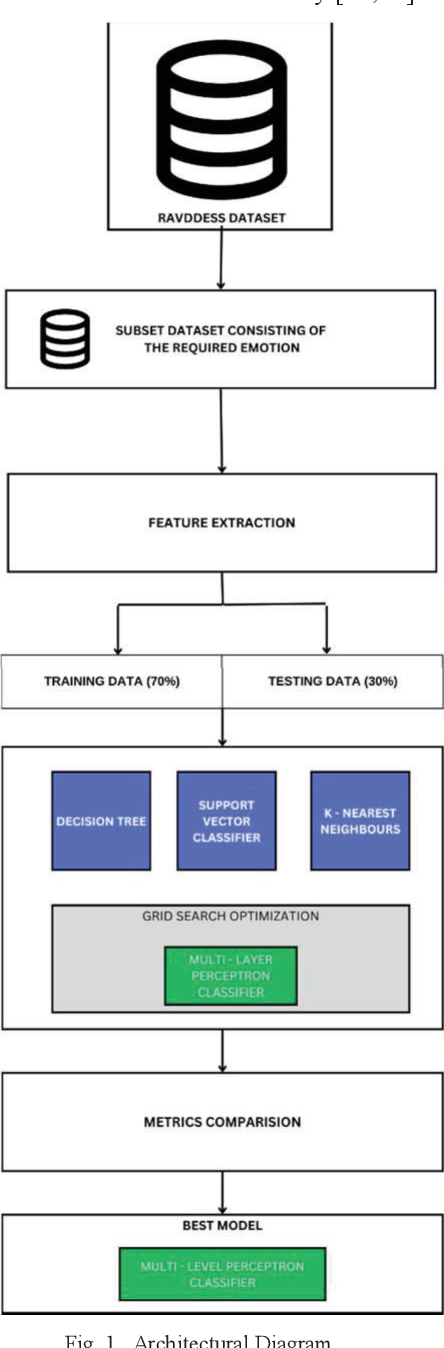
Figure 1 from Enhancing Speech Emotional Recognition through a Multi ...
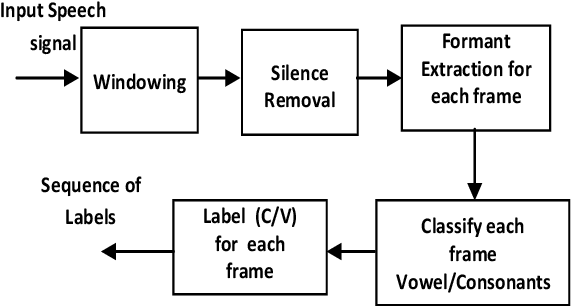
Figure 1 from Segmentation of Continuous Speech into Consonant and ...

Figure 1 from Implementation of Automatic Segmentation of Speech Signal ...

Figure 1 from A Multimodal Target Speech Extraction Algorithm Based on ...
Advertisement Space (300x250)

Figure 1 from Foreground Speech Segmentation and Enhancement Using ...
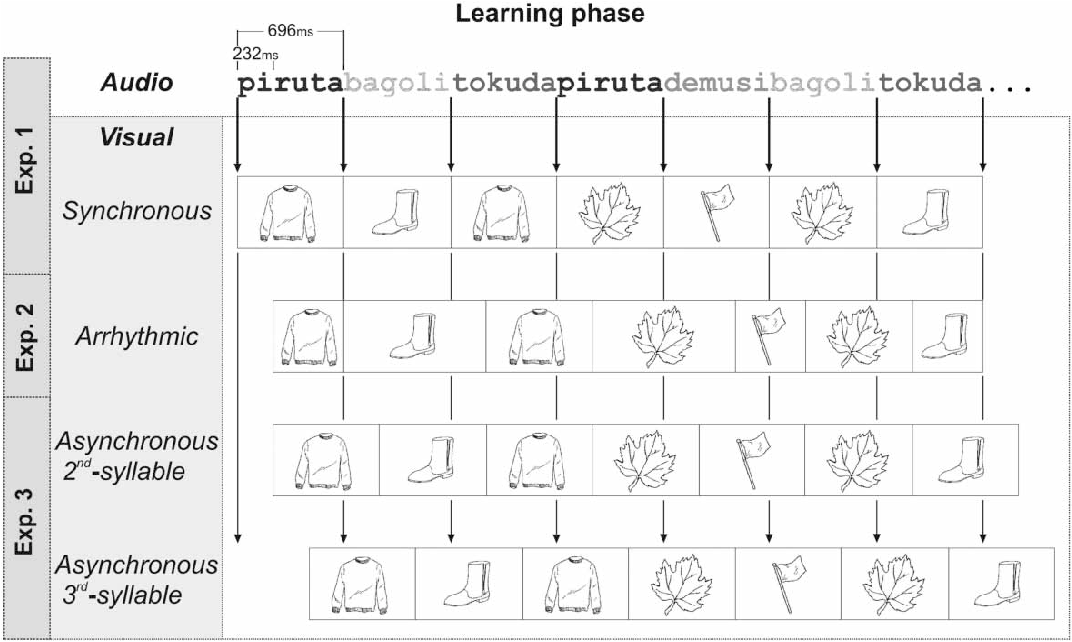
Figure 1 from Speech segmentation is facilitated by visual cues ...
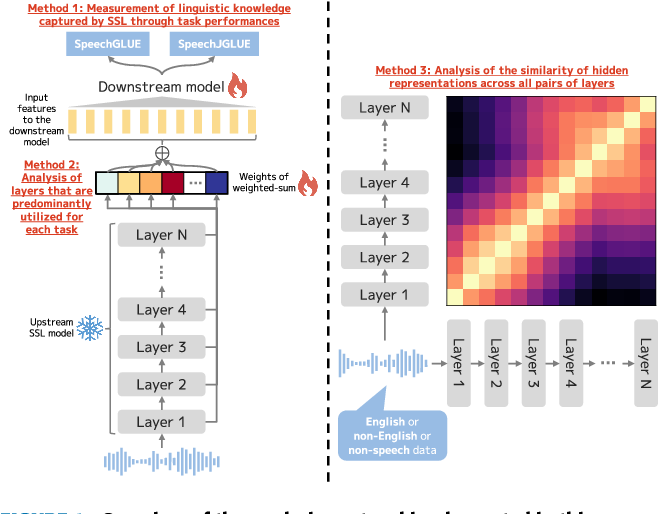
Figure 1 from Unveiling the Linguistic Capabilities of a Self ...
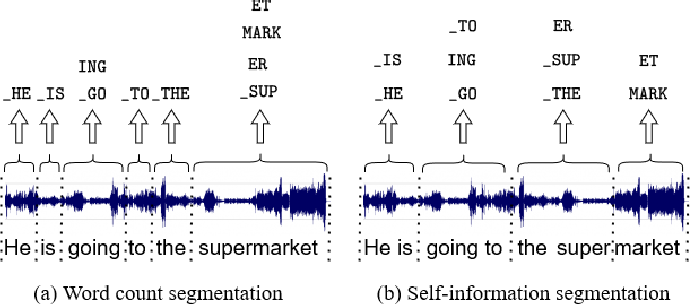
Figure 1 from Self-Information Guided Speech Segmentation for Efficient ...

Figure 1 from A Hierarchical Layered Graph Approach for Multi-Label ...

Figure 1 from Unsupervised Quasi-Silence based Speech Segmentation for ...

Figure 1 from Unsupervised Audio Speech Segmentation Using the Voting ...
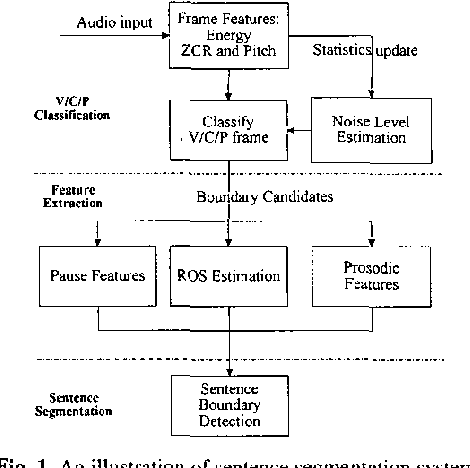
Figure 1 from Speech segmentation without speech recognition | Semantic ...
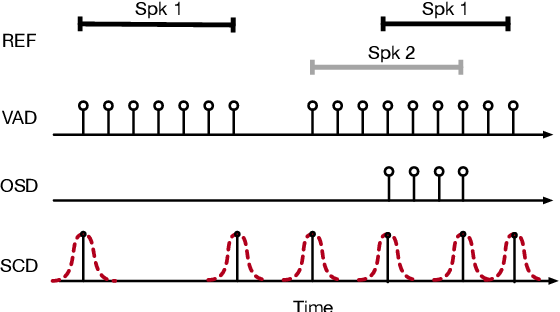
Figure 1 from Multi-microphone Automatic Speech Segmentation in ...

Figure 1 from Large-Scale Multilingual Speech Recognition with a ...
Advertisement Space (336x280)

Figure 1 from Visual speech segmentation and speaker recognition for ...
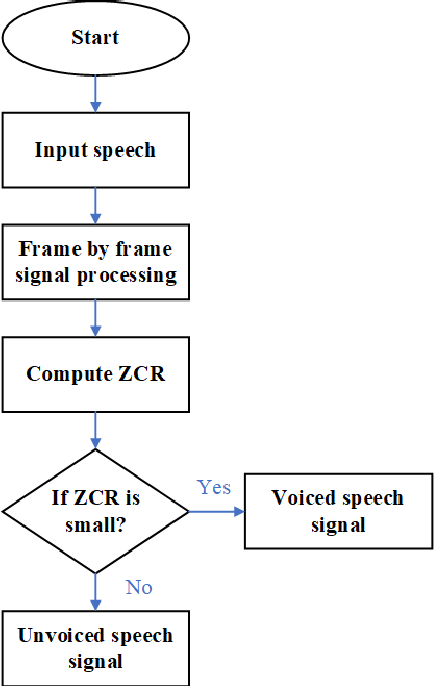
Figure 1 from Speech Signal Segmentation using Zero Crossing Rate and ...
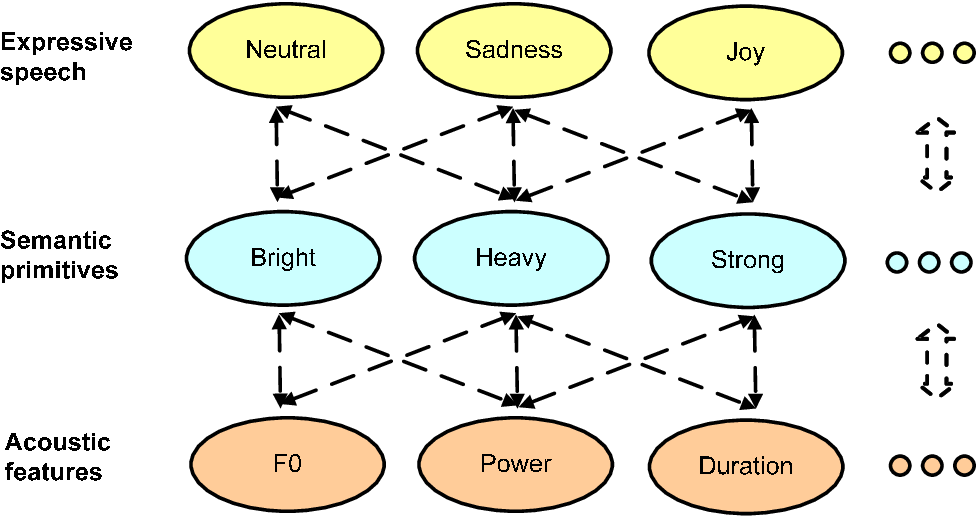
Figure 1 from A three-layered model for expressive speech perception ...

Figure 1 from Example-Based Correction of Word Segmentation and Part of ...
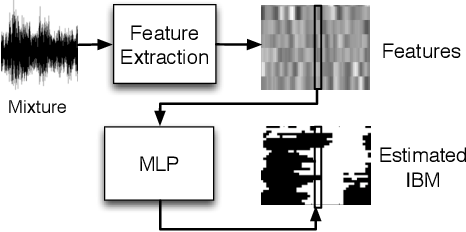
Figure 1 from A feature study for classification-based speech ...
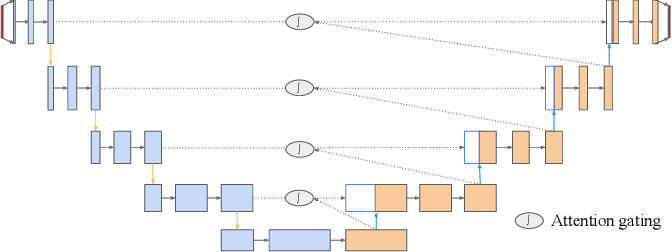
Figure 1 from DEEP ARTICULATORY SEGMENTATION AND SPEECH SYNTHESIS USING ...

Figure 1 from A practical framework for multi-domain speech recognition ...

Figure 1 from Application of Wavelet Transform for Speech Signal ...

Figure 1 from Comparative Layer-Wise Analysis of Self-Supervised Speech ...
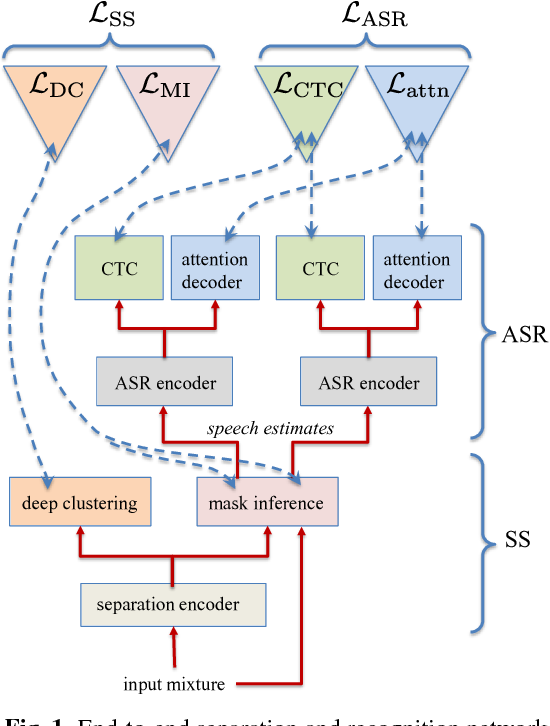
Figure 1 from End-to-End Multi-Speaker Speech Recognition | Semantic ...
Advertisement Space (336x280)
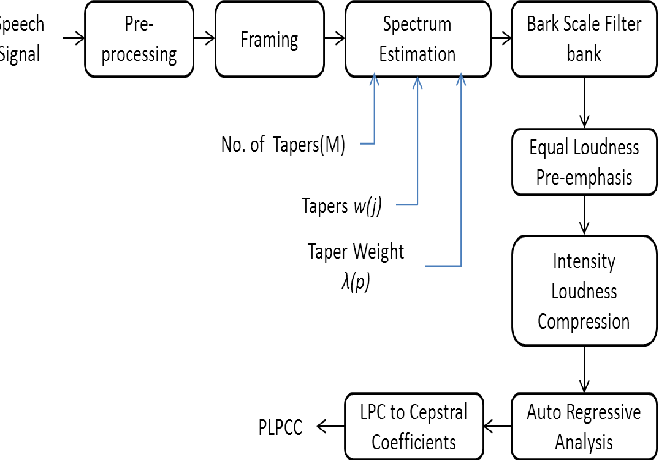
Figure 1 from Robust phonetic segmentation using multi-taper spectral ...
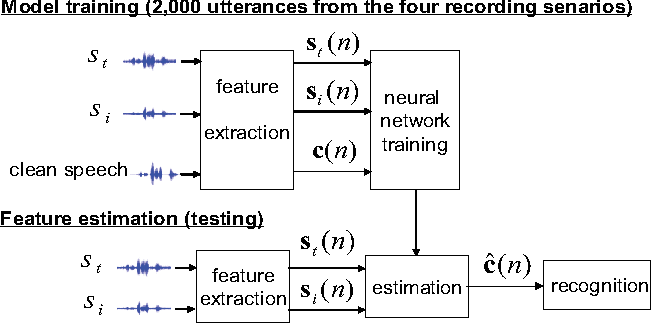
Figure 1 from Non-linear mapping for multi-channel speech separation ...

Figure 1 from Multi-channel Speech Separation Using Deep Embedding ...

Figure 1 from Multi-Speaker Multi-Style Speech Synthesis with Timbre ...

Figure 1 from Adapting Self-Supervised Models to Multi-Talker Speech ...
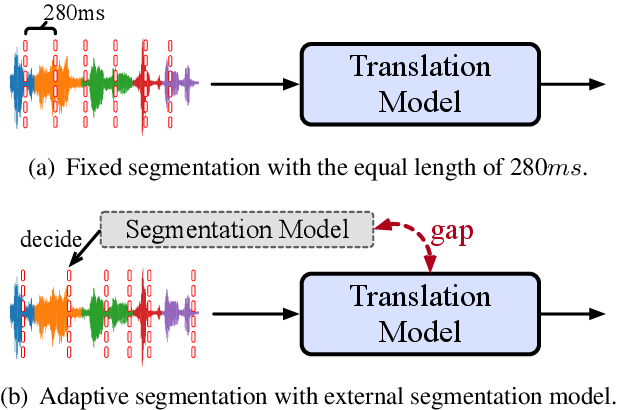
Figure 1 from End-to-End Simultaneous Speech Translation with ...