
Figure 1 From A Visually Grounded Parallel Corpus With Phrase To Region
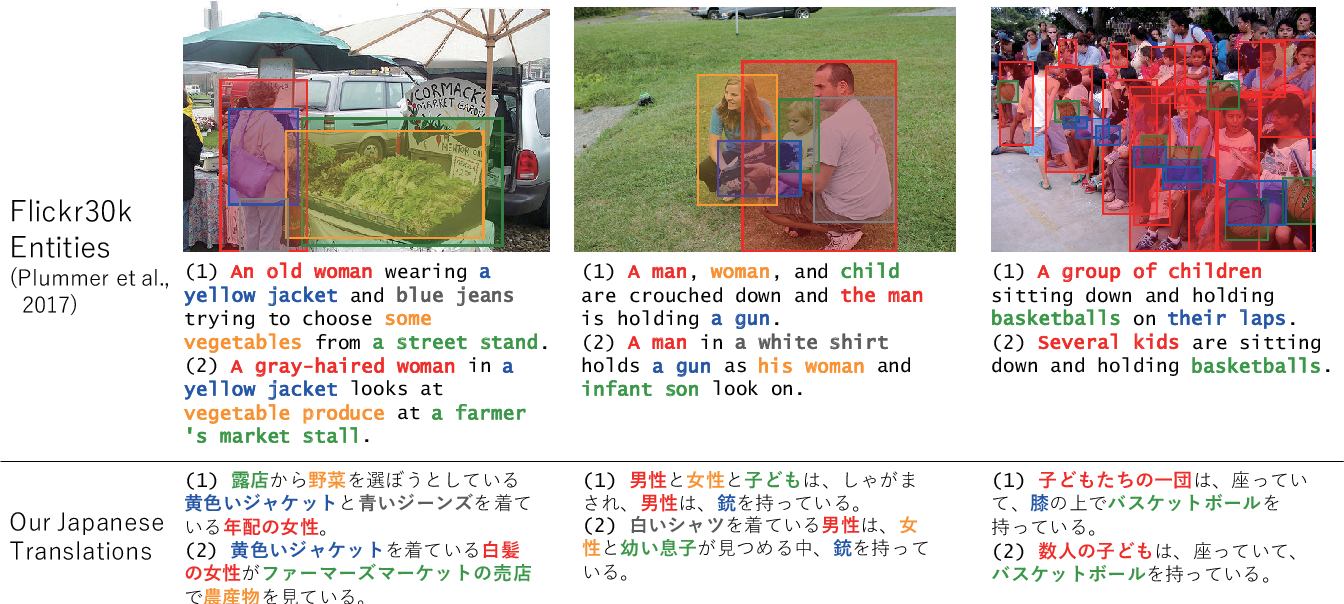
Figure 1 from A Visually-Grounded Parallel Corpus with Phrase-to-Region ...

Figure 1 from A probabilistic approach to learning a visually grounded ...

Figure 1 from Learning to Recognise Words Using Visually Grounded ...
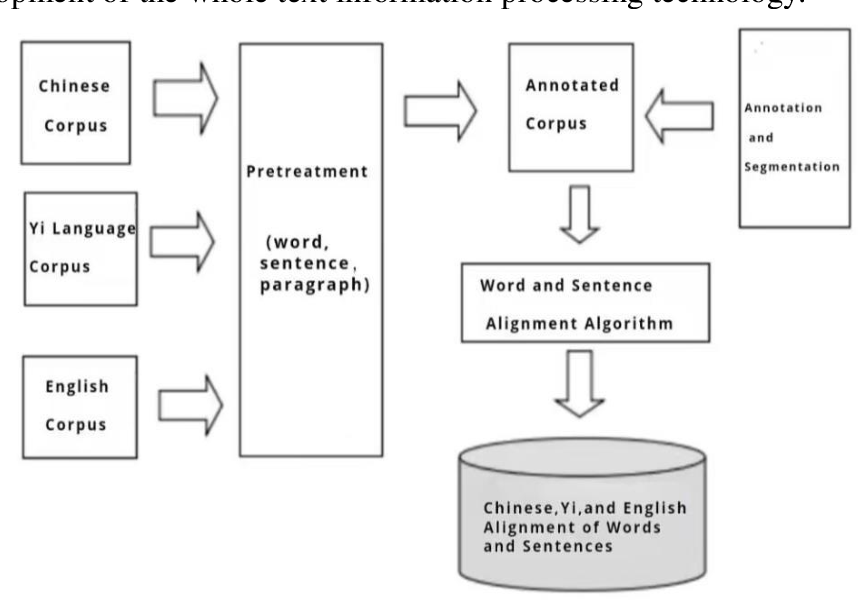
Figure 1 from The Construction of a Multilingual Parallel Corpus for ...

Table 1 from A Visually-Grounded Parallel Corpus with Phrase-to-Region ...

Table 1 from A Visually-Grounded Parallel Corpus with Phrase-to-Region ...

Figure 1 from Inflating a Small Parallel Corpus into a Large Quasi ...

Figure 1 from How to Fool Systems and Humans in Visually Grounded ...
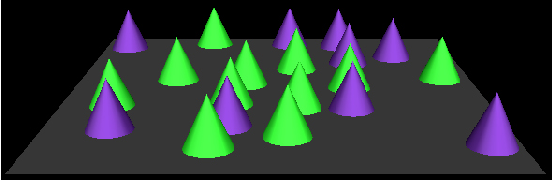
Figure 1 from A visually grounded natural language interface for ...

Figure 1 from Designing a parallel corpus as a multifunctional ...
Advertisement Space (300x250)
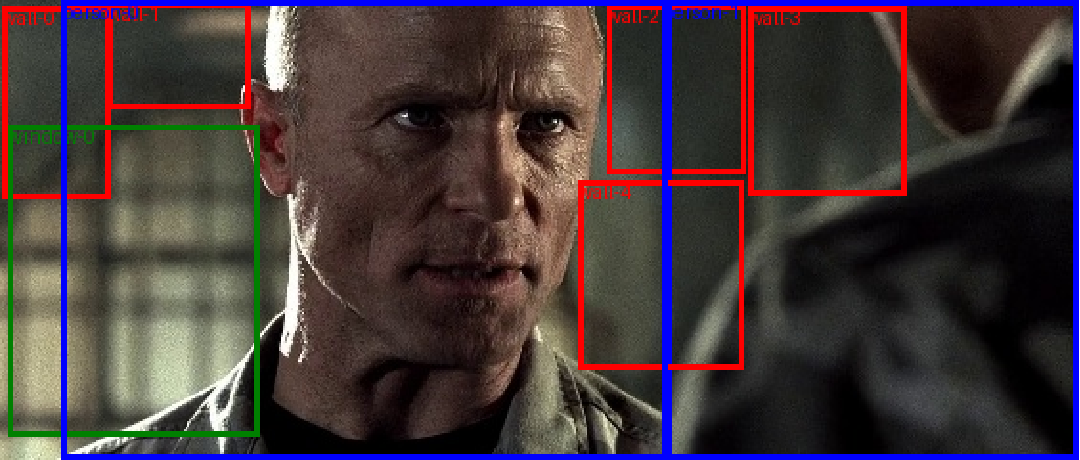
Figure 1 from GroundCap: A Visually Grounded Image Captioning Dataset ...

Figure 1 from Medical Phrase Grounding with Region-Phrase Context ...

Figure 1 from Visually Grounded Paraphrase Extraction | Semantic Scholar

Figure 1 from Learning Visually Grounded Sentence Representations ...

Figure 1 from A Joint Study of Phrase Grounding and Task Performance in ...

Figure 1 from Disambiguating Reference in Visually Grounded Dialogues ...

Figure 1 from Visually Grounded Continual Learning of Compositional ...
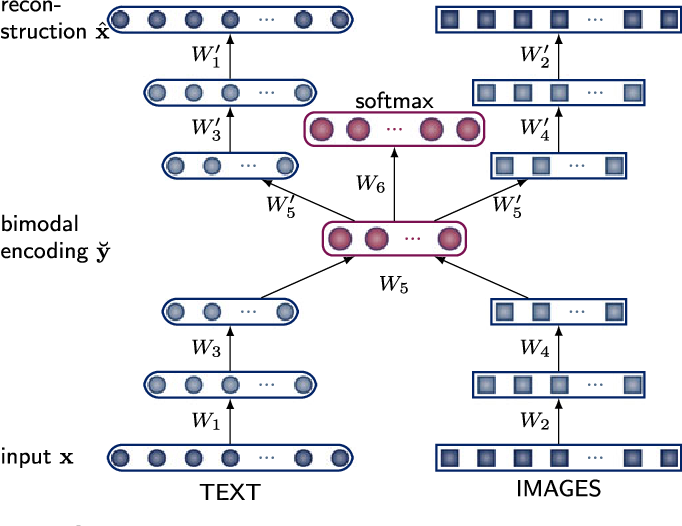
Figure 1 from Visually Grounded Meaning Representations | Semantic Scholar
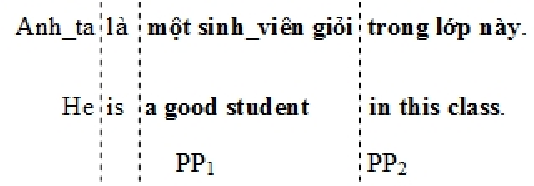
Figure 1 from Parallel phrase extraction from English-Vietnamese ...
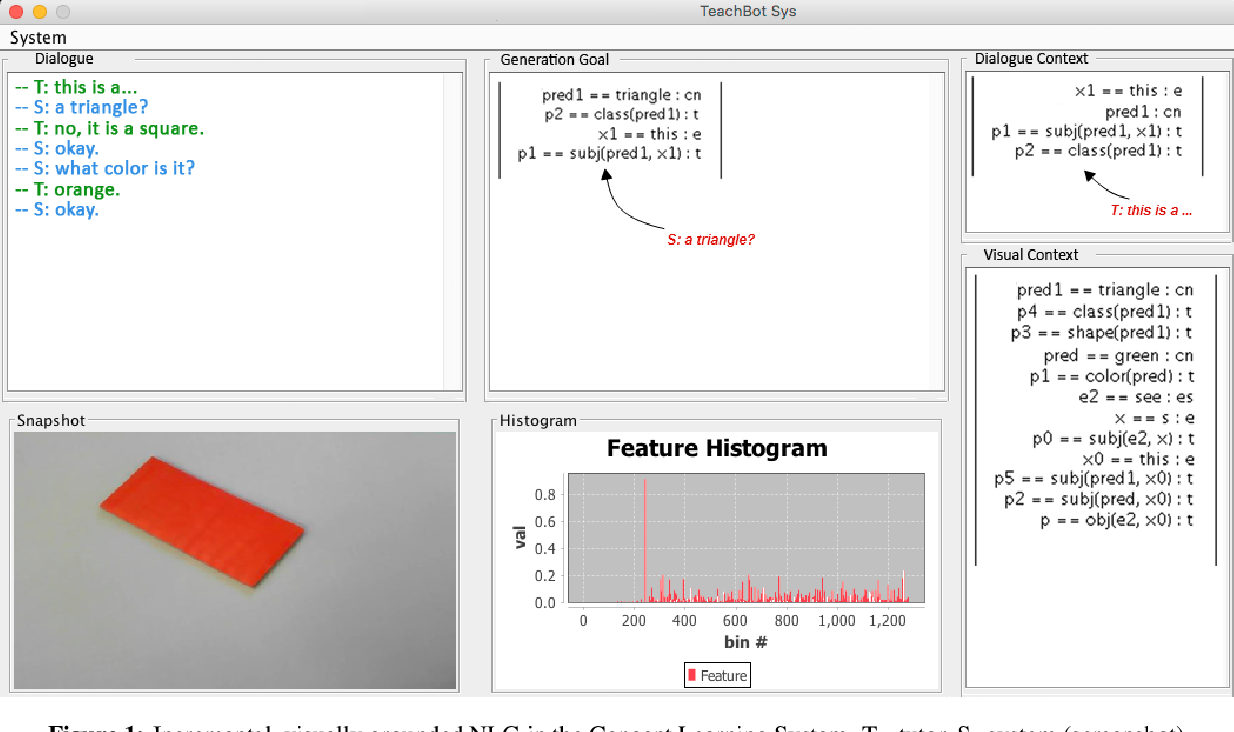
Figure 1 from Incremental Generation of Visually Grounded Language in ...
Advertisement Space (336x280)

Figure 1 from Automatic paraphrasing based on parallel corpus for ...
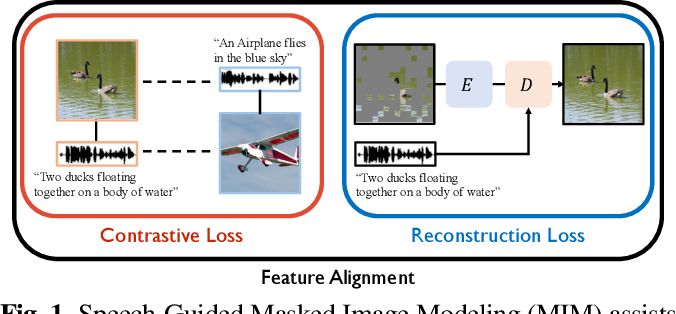
Figure 1 from Speech Guided Masked Image Modeling for Visually Grounded ...
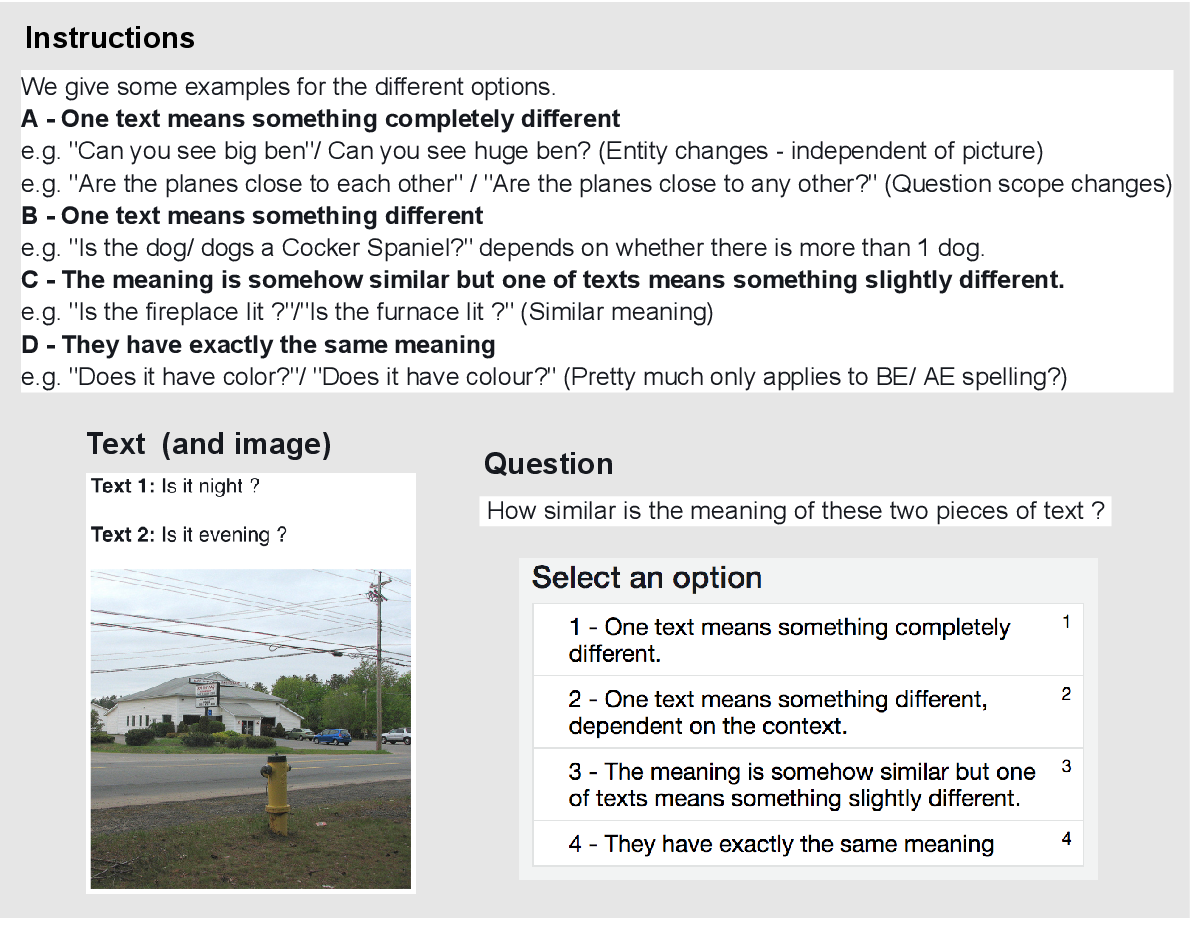
Figure 7 from How to Fool Systems and Humans in Visually Grounded ...
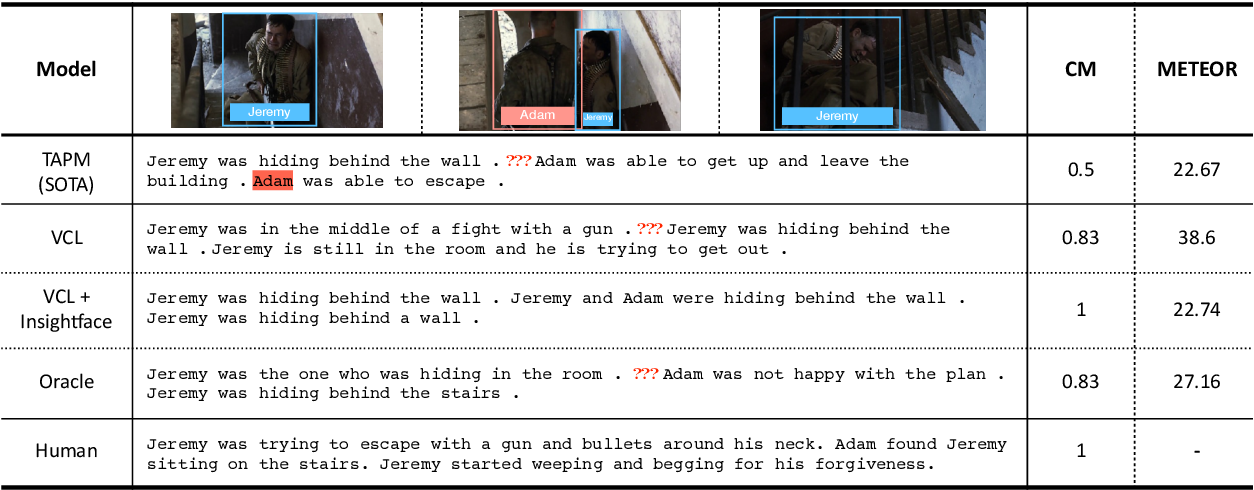
Figure 1 from Visual Coherence Loss for Coherent and Visually Grounded ...
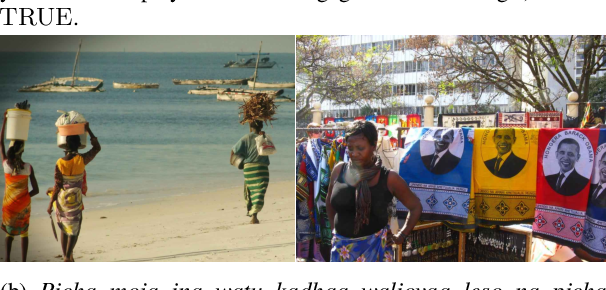
Figure 1 from Visually Grounded Reasoning across Languages and Cultures ...

Figure 2 from Visually Grounded Continual Language Learning with ...
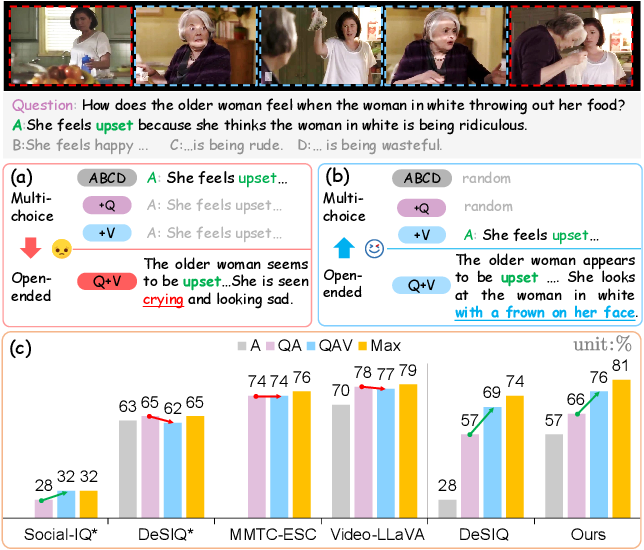
Figure 1 from VEGAS: Towards Visually Explainable and Grounded ...
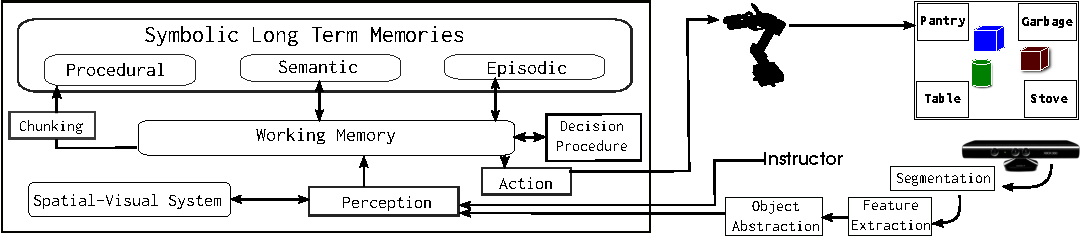
Figure 1 from Acquiring Grounded Representations of Words with Situated ...

Figure 2 from Visually Grounded Continual Language Learning with ...
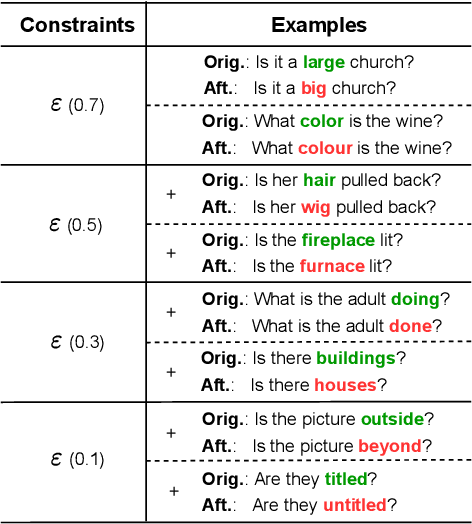
Figure 4 from How to Fool Systems and Humans in Visually Grounded ...
Advertisement Space (336x280)
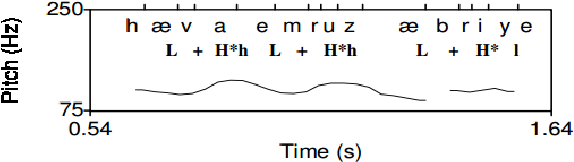
Figure 1 from Visually Grounded Cross-Lingual Keyword Spotting in ...

Figure 1 from Modelling word learning and recognition using visually ...

Figure 1 from Modelling Large Parallel Corpora: The Zurich Parallel ...

A Visually-Grounded Parallel Corpus with Phrase-to-Region Linking - ACL ...
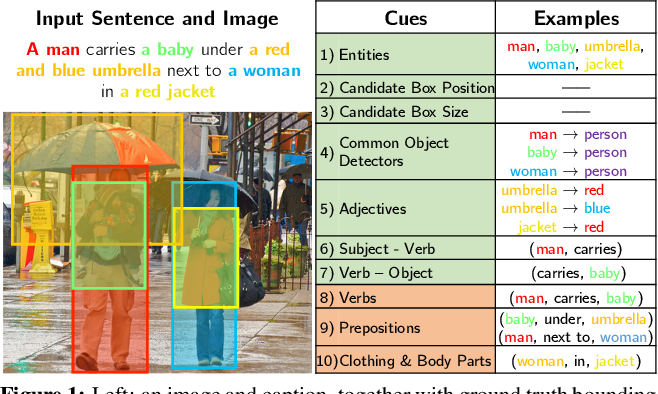
Figure 1 from Phrase Localization and Visual Relationship Detection ...

Figure 1 from Contrastive Region Guidance: Improving Grounding in ...