
Figure 1 From Acoustic Word Embeddings For End To End Speech Synthesis
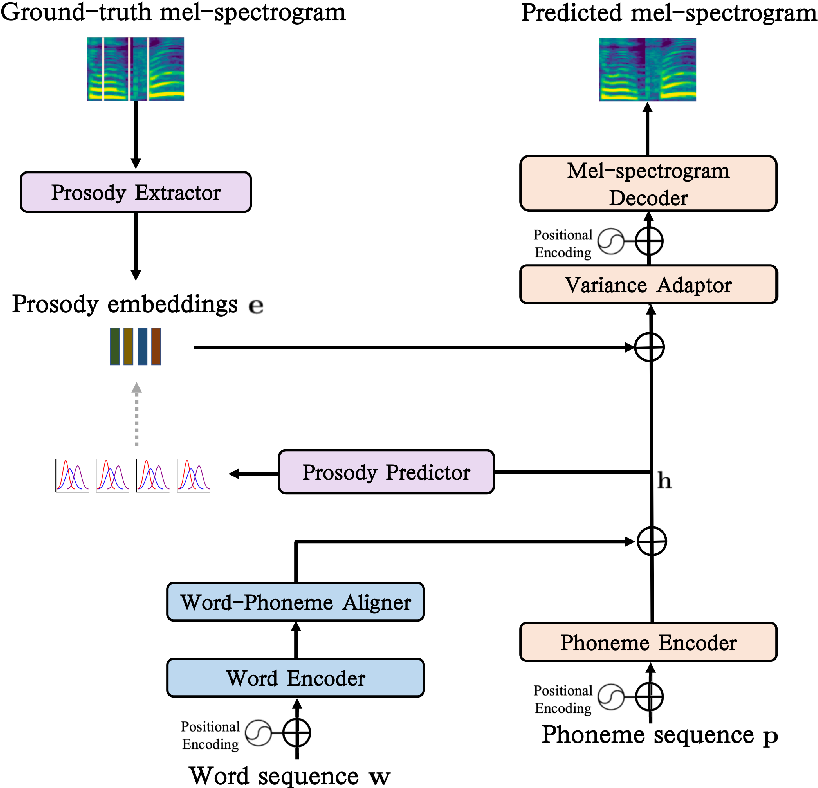
Figure 1 from Acoustic Word Embeddings for End-to-End Speech Synthesis ...
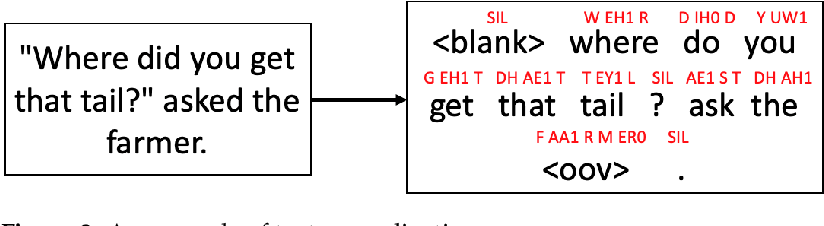
Figure 1 from Acoustic Word Embeddings for End-to-End Speech Synthesis ...

Figure 1 from SPEECH RECOGNITION : CONTEXTUAL ACOUSTIC WORD EMBEDDINGS ...

Figure 1 from Acoustic Word Embeddings for Zero-Resource Languages ...
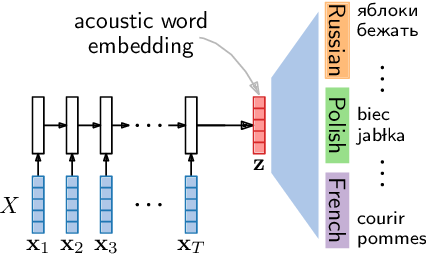
Figure 1 from Improved Acoustic Word Embeddings for Zero-Resource ...

Figure 1 from Neural Speech Embeddings for Speech Synthesis Based on ...

Figure 1 from Learning Word Embeddings from Speech | Semantic Scholar

(PDF) Acoustic Word Embeddings for End-to-End Speech Synthesis

Figure 1 from Improving Acoustic Word Embeddings through Correspondence ...
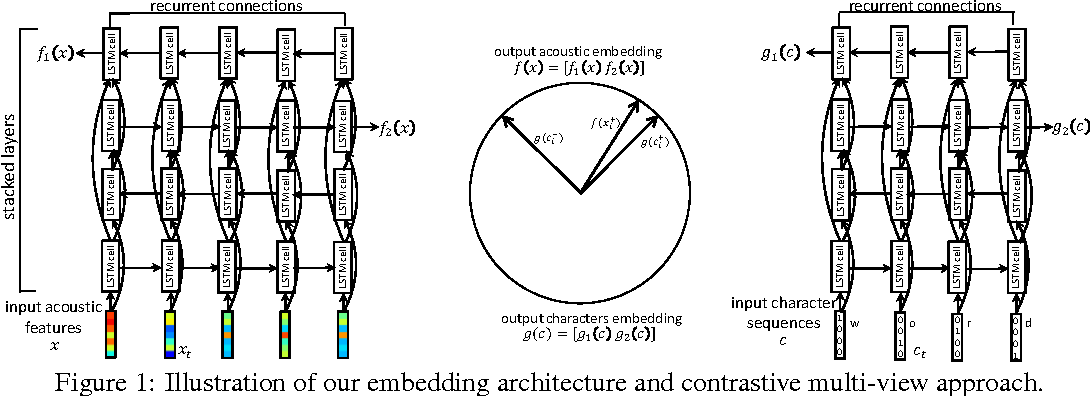
Figure 1 from Multi-view Recurrent Neural Acoustic Word Embeddings ...
Advertisement Space (300x250)
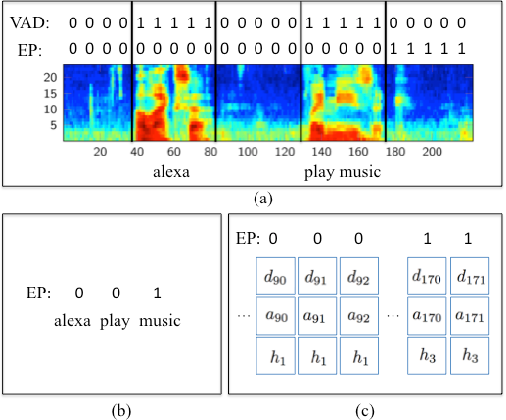
Figure 1 from Combining Acoustic Embeddings and Decoding Features for ...
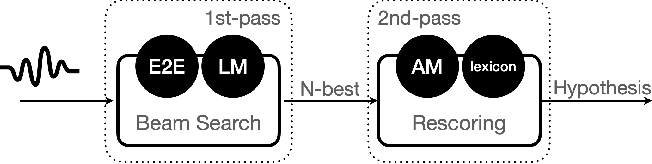
Figure 1 from Acoustic Model Fusion For End-to-End Speech Recognition ...

Acoustic Word Embeddings for End-to-End Speech Synthesis

Figure 1 from Pretrained Semantic Speech Embeddings for End-to-End ...

Acoustic Word Embeddings for End-to-End Speech Synthesis

Figure 1 from Deep convolutional acoustic word embeddings using word ...
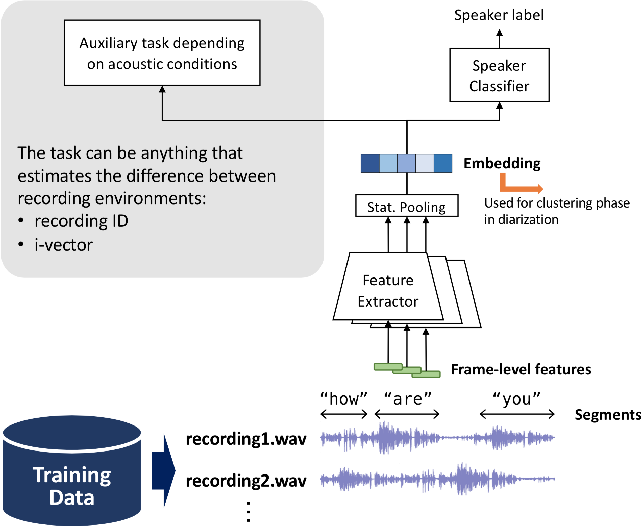
Figure 1 from Speaker Embeddings Incorporating Acoustic Conditions for ...

Figure 1 from Acoustic Word Embedding System for Code-Switching Query ...
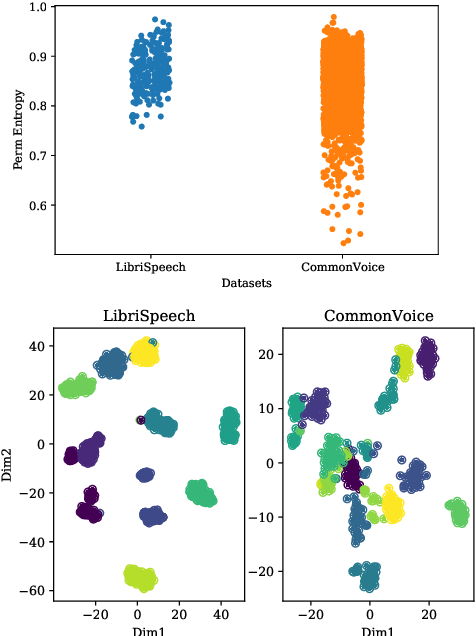
Figure 1 from End-to-End Speech Recognition from Federated Acoustic ...
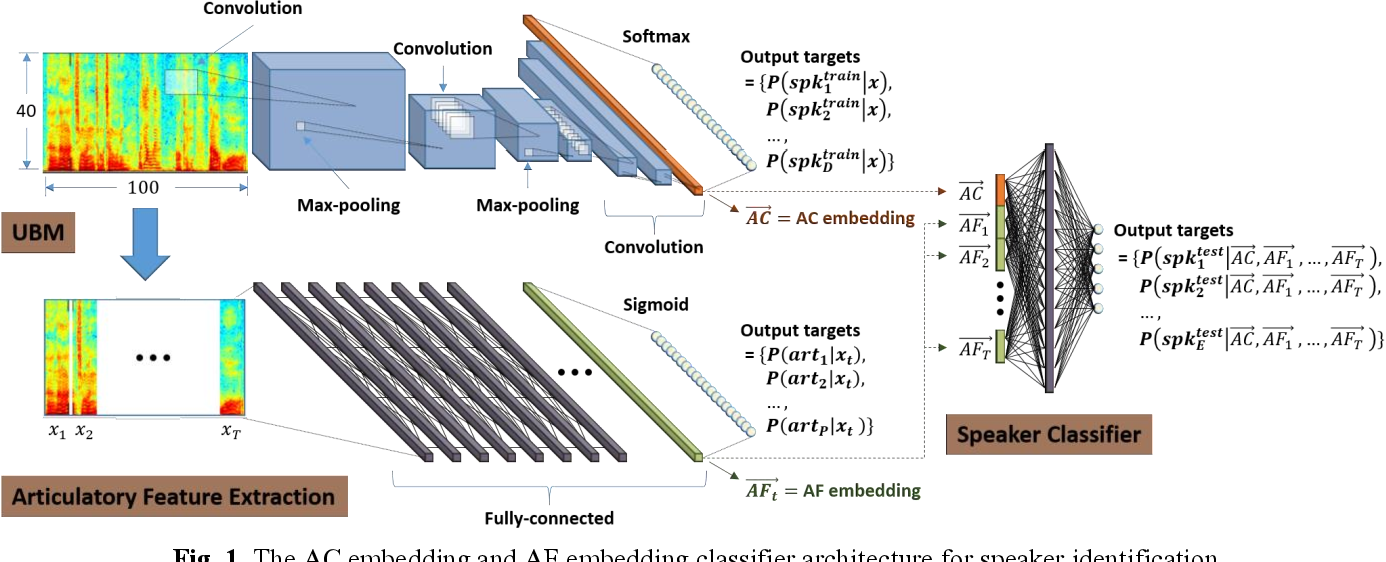
Figure 1 from Combining Deep Embeddings of Acoustic and Articulatory ...
Advertisement Space (336x280)

Figure 1 from End-to-End Binaural Speech Synthesis | Semantic Scholar

Figure 1 from Efficient decoding self-attention for end-to-end speech ...
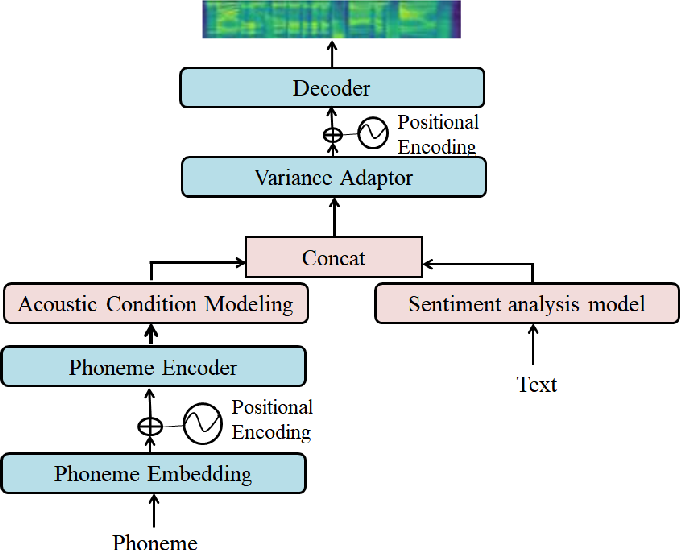
Figure 1 from Fusing Acoustic and Text Emotional Features for ...
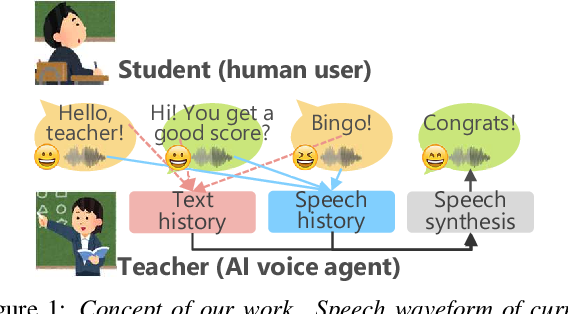
Figure 1 from Acoustic Modeling for End-to-End Empathetic Dialogue ...

Figure 1 from Analysis of Embedding Space of Speech Synthesis System as ...

Figure 1 from Speech Rhythm-Based Speaker Embeddings Extraction from ...
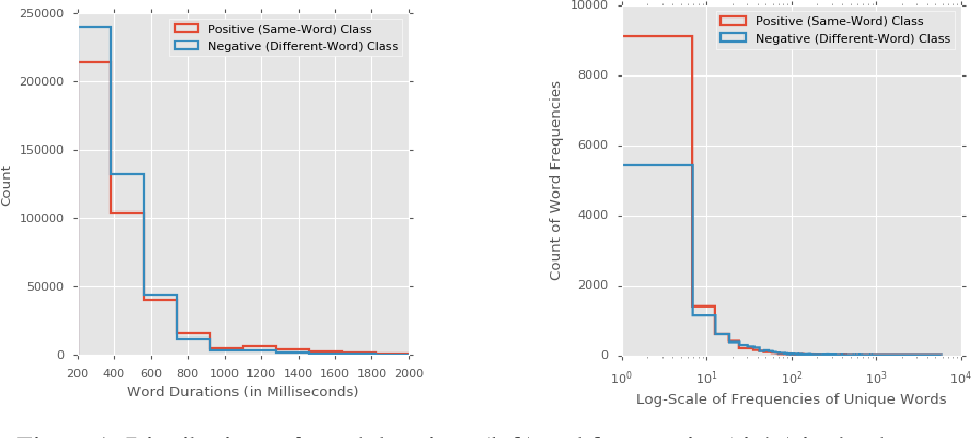
Figure 1 from Learning Joint Acoustic-Phonetic Word Embeddings ...
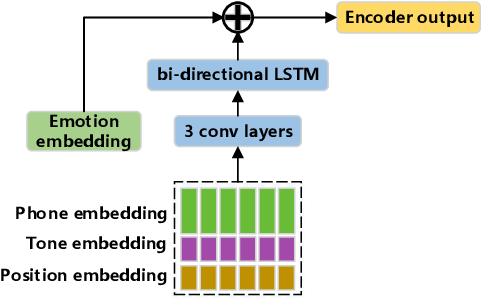
Figure 1 from End-to-End Emotional Speech Synthesis Using Style Tokens ...
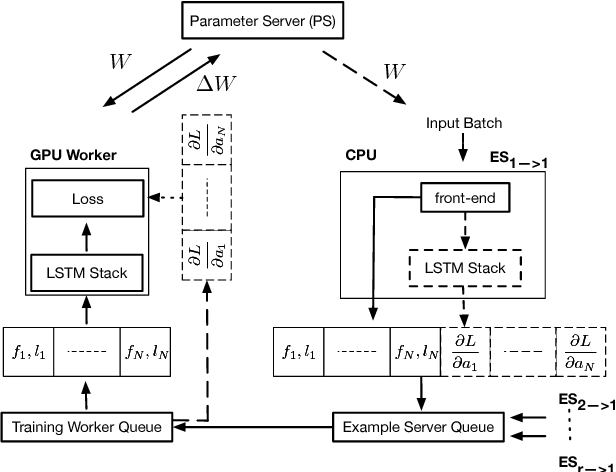
Figure 1 from End-to-End Training of Acoustic Models for Large ...
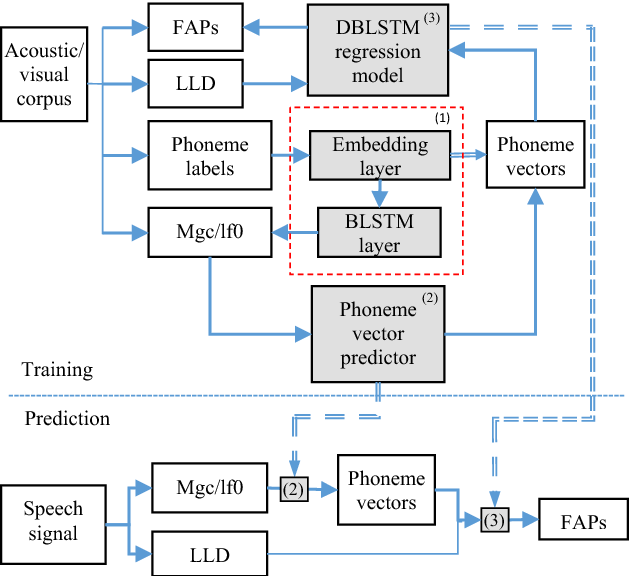
Figure 1 from Phoneme Embedding and its Application to Speech Driven ...
Advertisement Space (336x280)
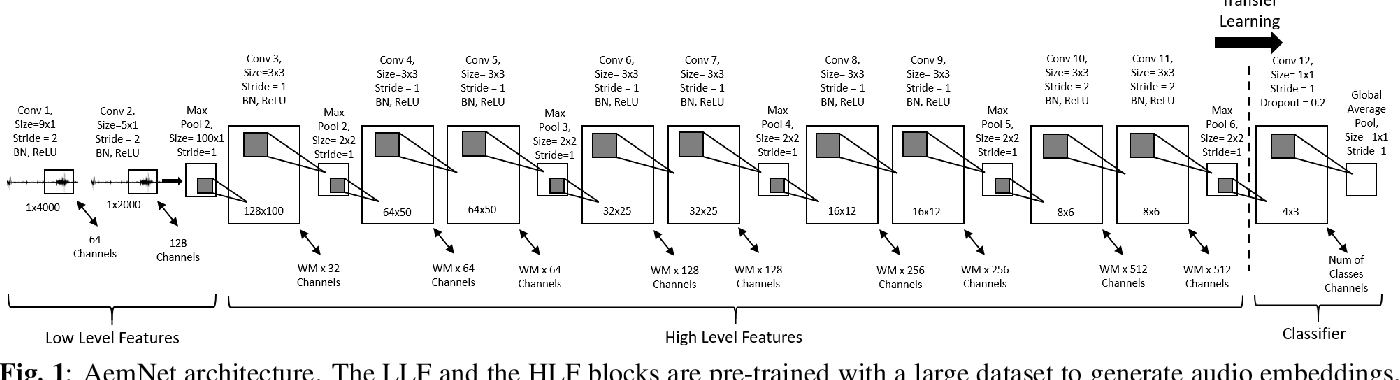
Figure 1 from Efficient End-to-End Audio Embeddings Generation for ...

Figure 4 from Analyzing Acoustic Word Embeddings from Pre-Trained Self ...

Figure 1 from End-to-End Text-To-Speech synthesis for under resourced ...
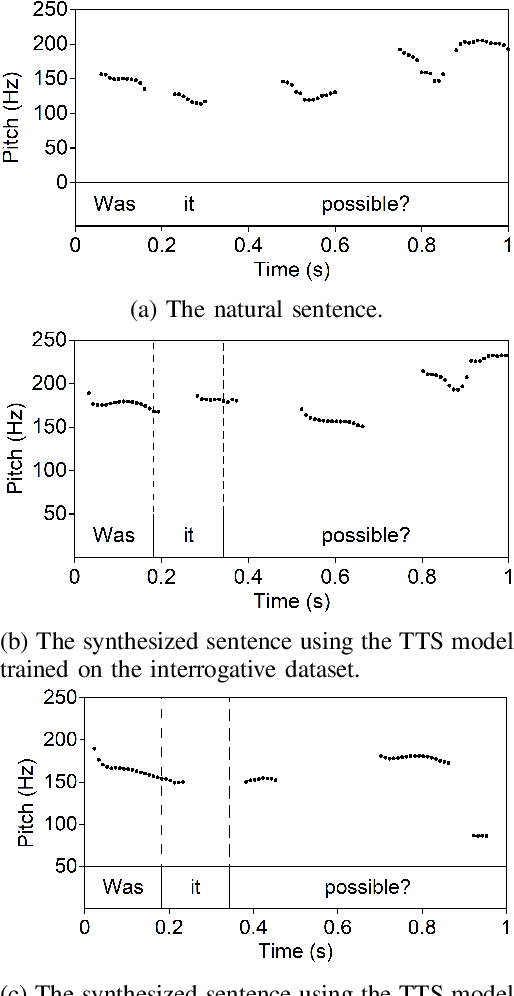
Figure 1 from Enhancing End-to-End Speech Synthesis by Modeling ...
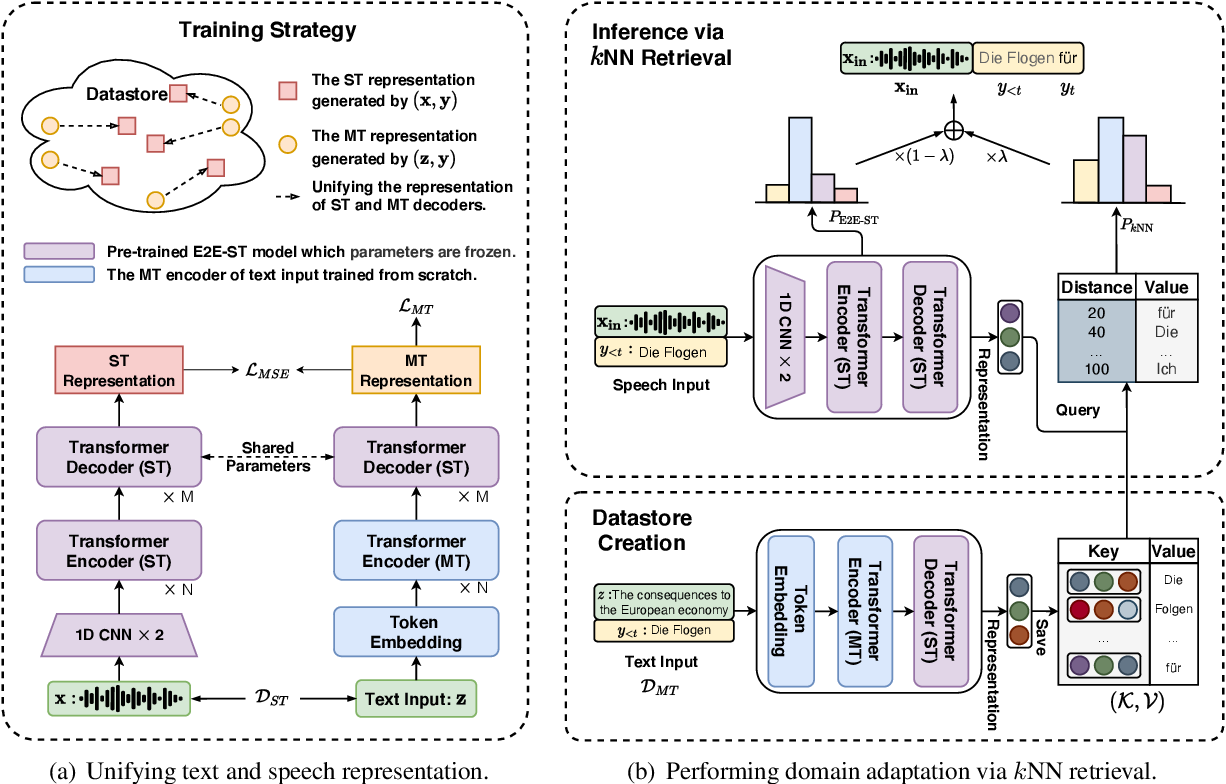
Figure 1 from Non-Parametric Domain Adaptation for End-to-End Speech ...
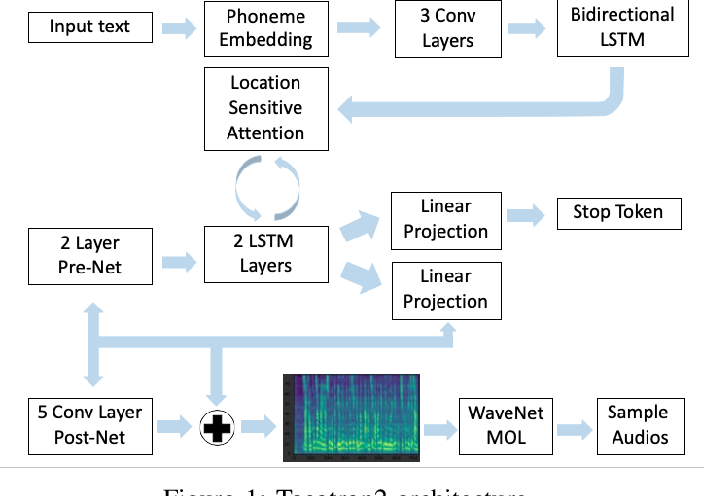
Figure 1 from Vietnamese Speech Synthesis with End-to-End Model and ...