
Figure 1 From Aligning Large Multimodal Model With Sequential

Figure 1 from Aligning Large Multimodal Model with Sequential ...
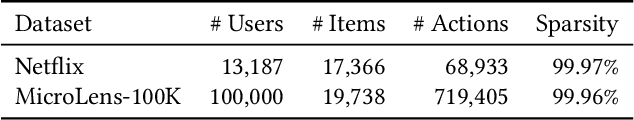
Table 1 from Aligning Large Multimodal Model with Sequential ...
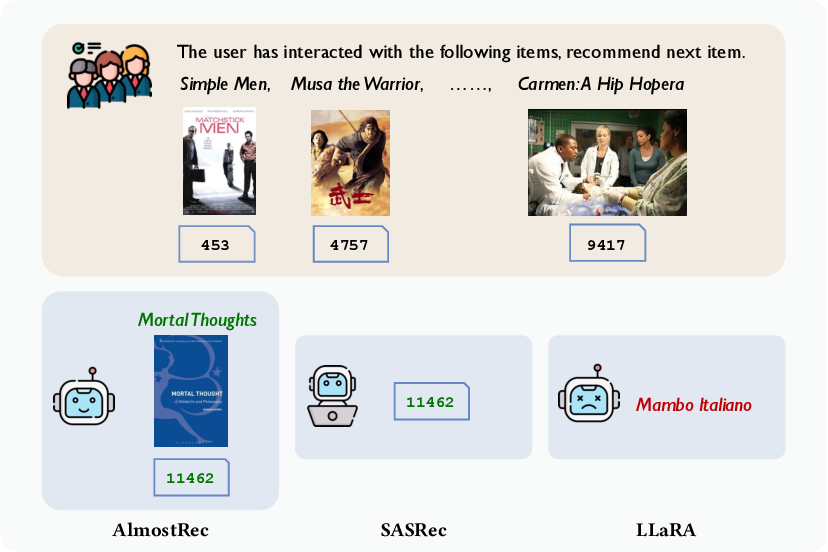
Figure 4 from Aligning Large Multimodal Model with Sequential ...

Figure 1 from SurgLLM: A Versatile Large Multimodal Model with Spatial ...

Table 2 from Aligning Large Multimodal Model with Sequential ...
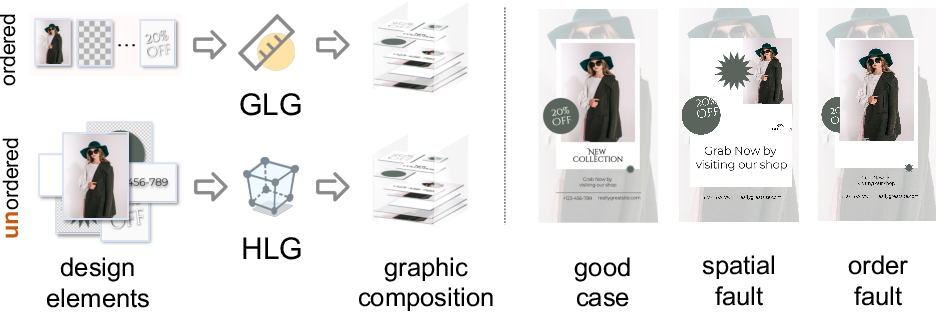
Figure 1 from Graphic Design with Large Multimodal Model | Semantic Scholar

Figure 1 from Empowering Large Language Model for Sequential ...

Figure 1 from Empowering Large Language Model for Sequential ...

Figure 1 from Harnessing Multimodal Large Language Models for ...
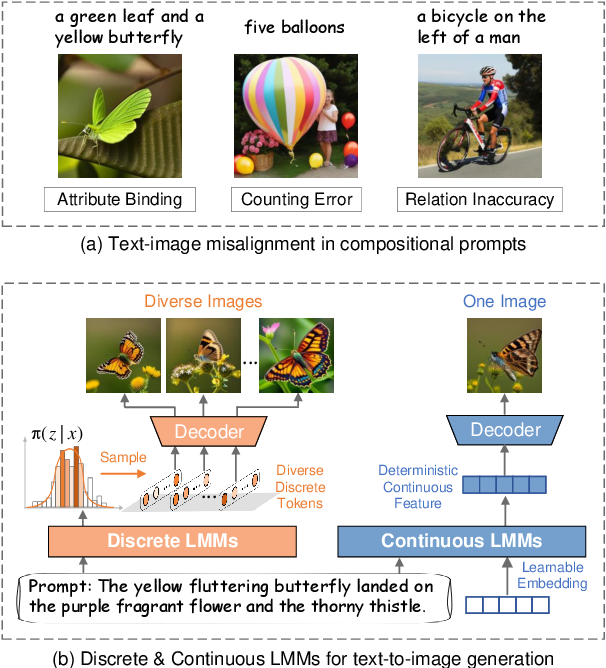
Figure 1 from SILMM: Self-Improving Large Multimodal Models for ...
Advertisement Space (300x250)
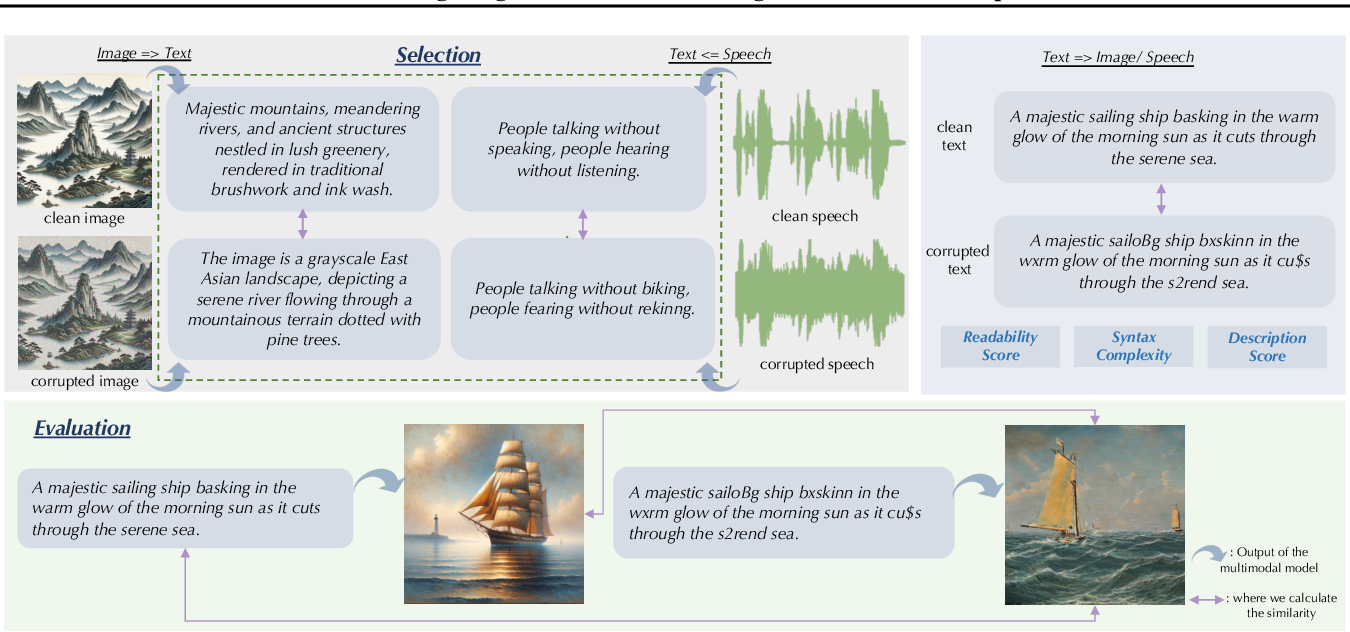
Figure 1 from Benchmarking Large Multimodal Models against Common ...

Figure 1 from On the Robustness of Large Multimodal Models Against ...

Figure 1 from Structure-Aware Multimodal Sequential Learning for Visual ...

Figure 1 from Adapting Large Multimodal Models to Distribution Shifts ...

Figure 1 from Structure-Aware Multimodal Sequential Learning for Visual ...

Figure 1 from Enhancing Multimodal Alignment with Momentum Augmentation ...

Figure 1 from Multimodal Large Models are Effective Action Anticipators ...

Figure 1 from End-to-end training of Multimodal Model and ranking Model ...
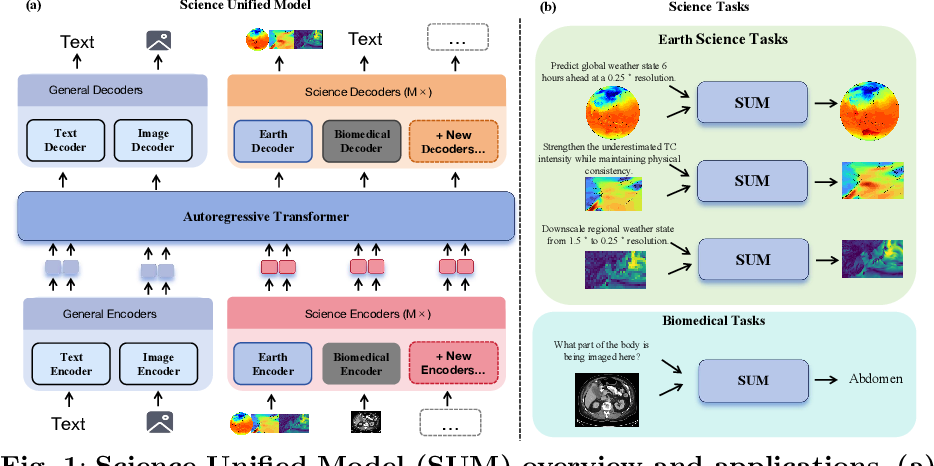
Figure 1 from A unified multimodal understanding and generation model ...
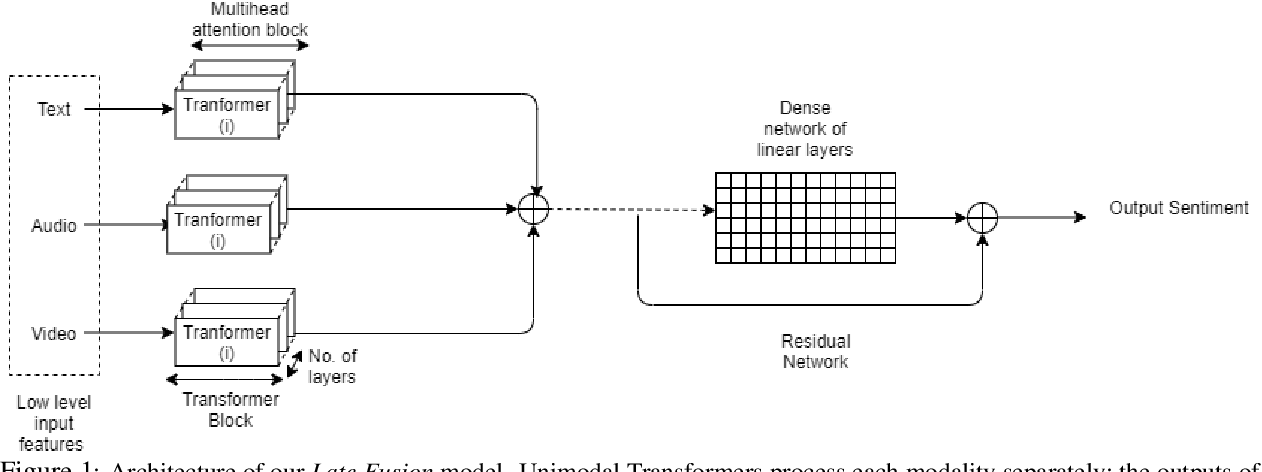
Figure 1 from Lightweight Models for Multimodal Sequential Data ...
Advertisement Space (336x280)
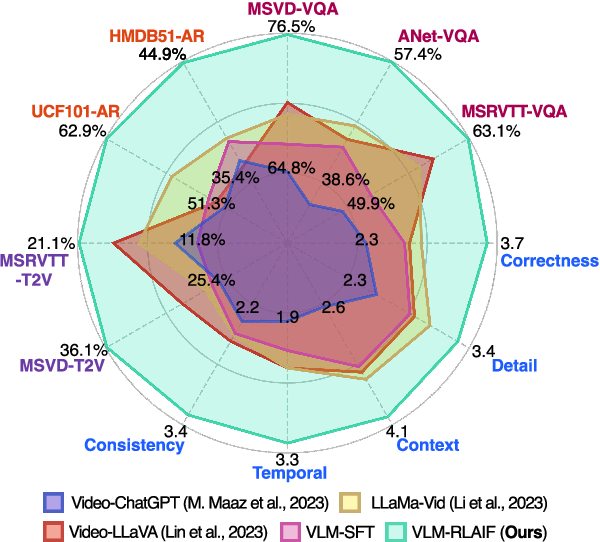
Figure 1 from Tuning Large Multimodal Models for Videos using ...

Figure 1 from Multimodal Sequential Generative Models for Semi ...
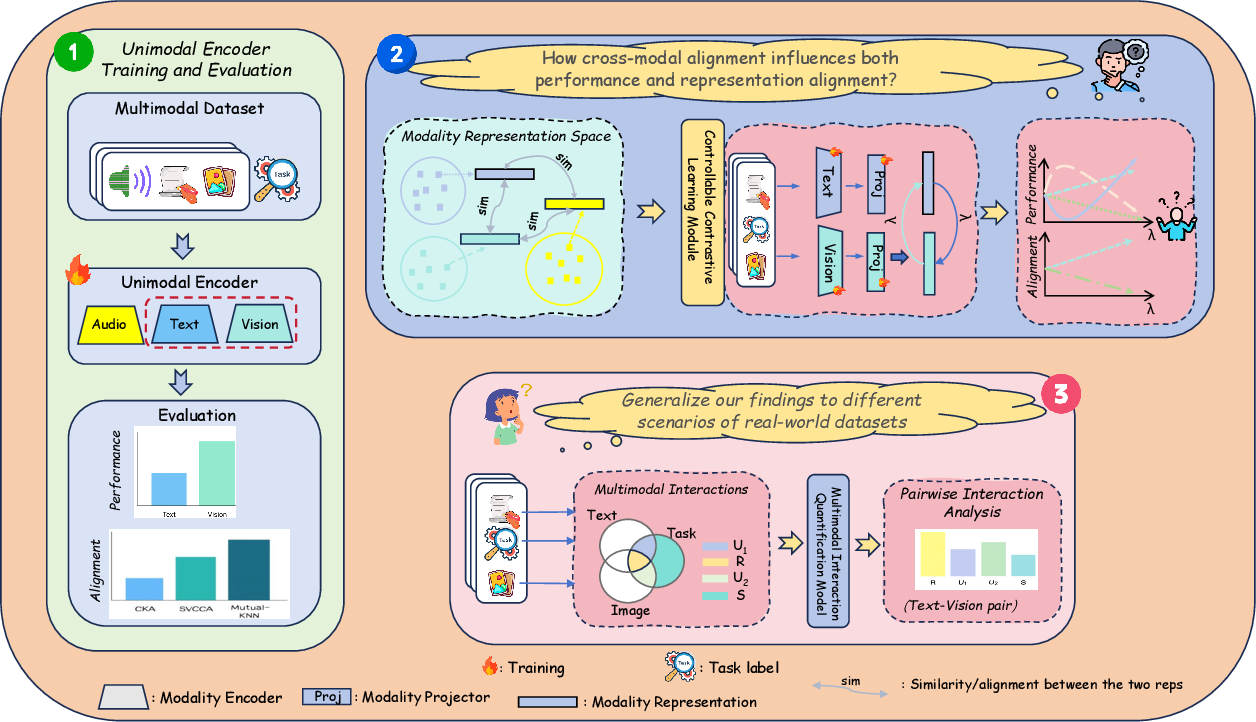
Figure 1 from To Align or Not to Align: Strategic Multimodal ...

Figure 1 from Prototype-Aware Multimodal Alignment for Open-Vocabulary ...

Figure 1 from Rethinking the Multimodal Correlation of Multimodal ...

Figure 1 from A Concept-Based Explainability Framework for Large ...
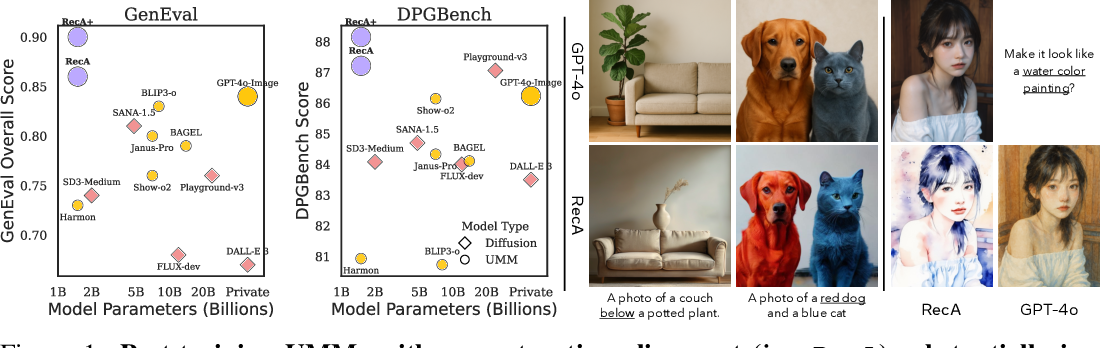
Figure 1 from Reconstruction Alignment Improves Unified Multimodal ...
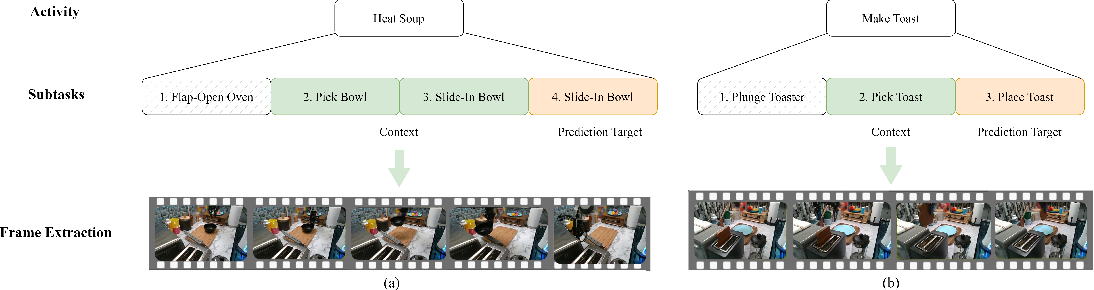
Figure 1 from Benchmarking Sequential Visual Input Reasoning and ...
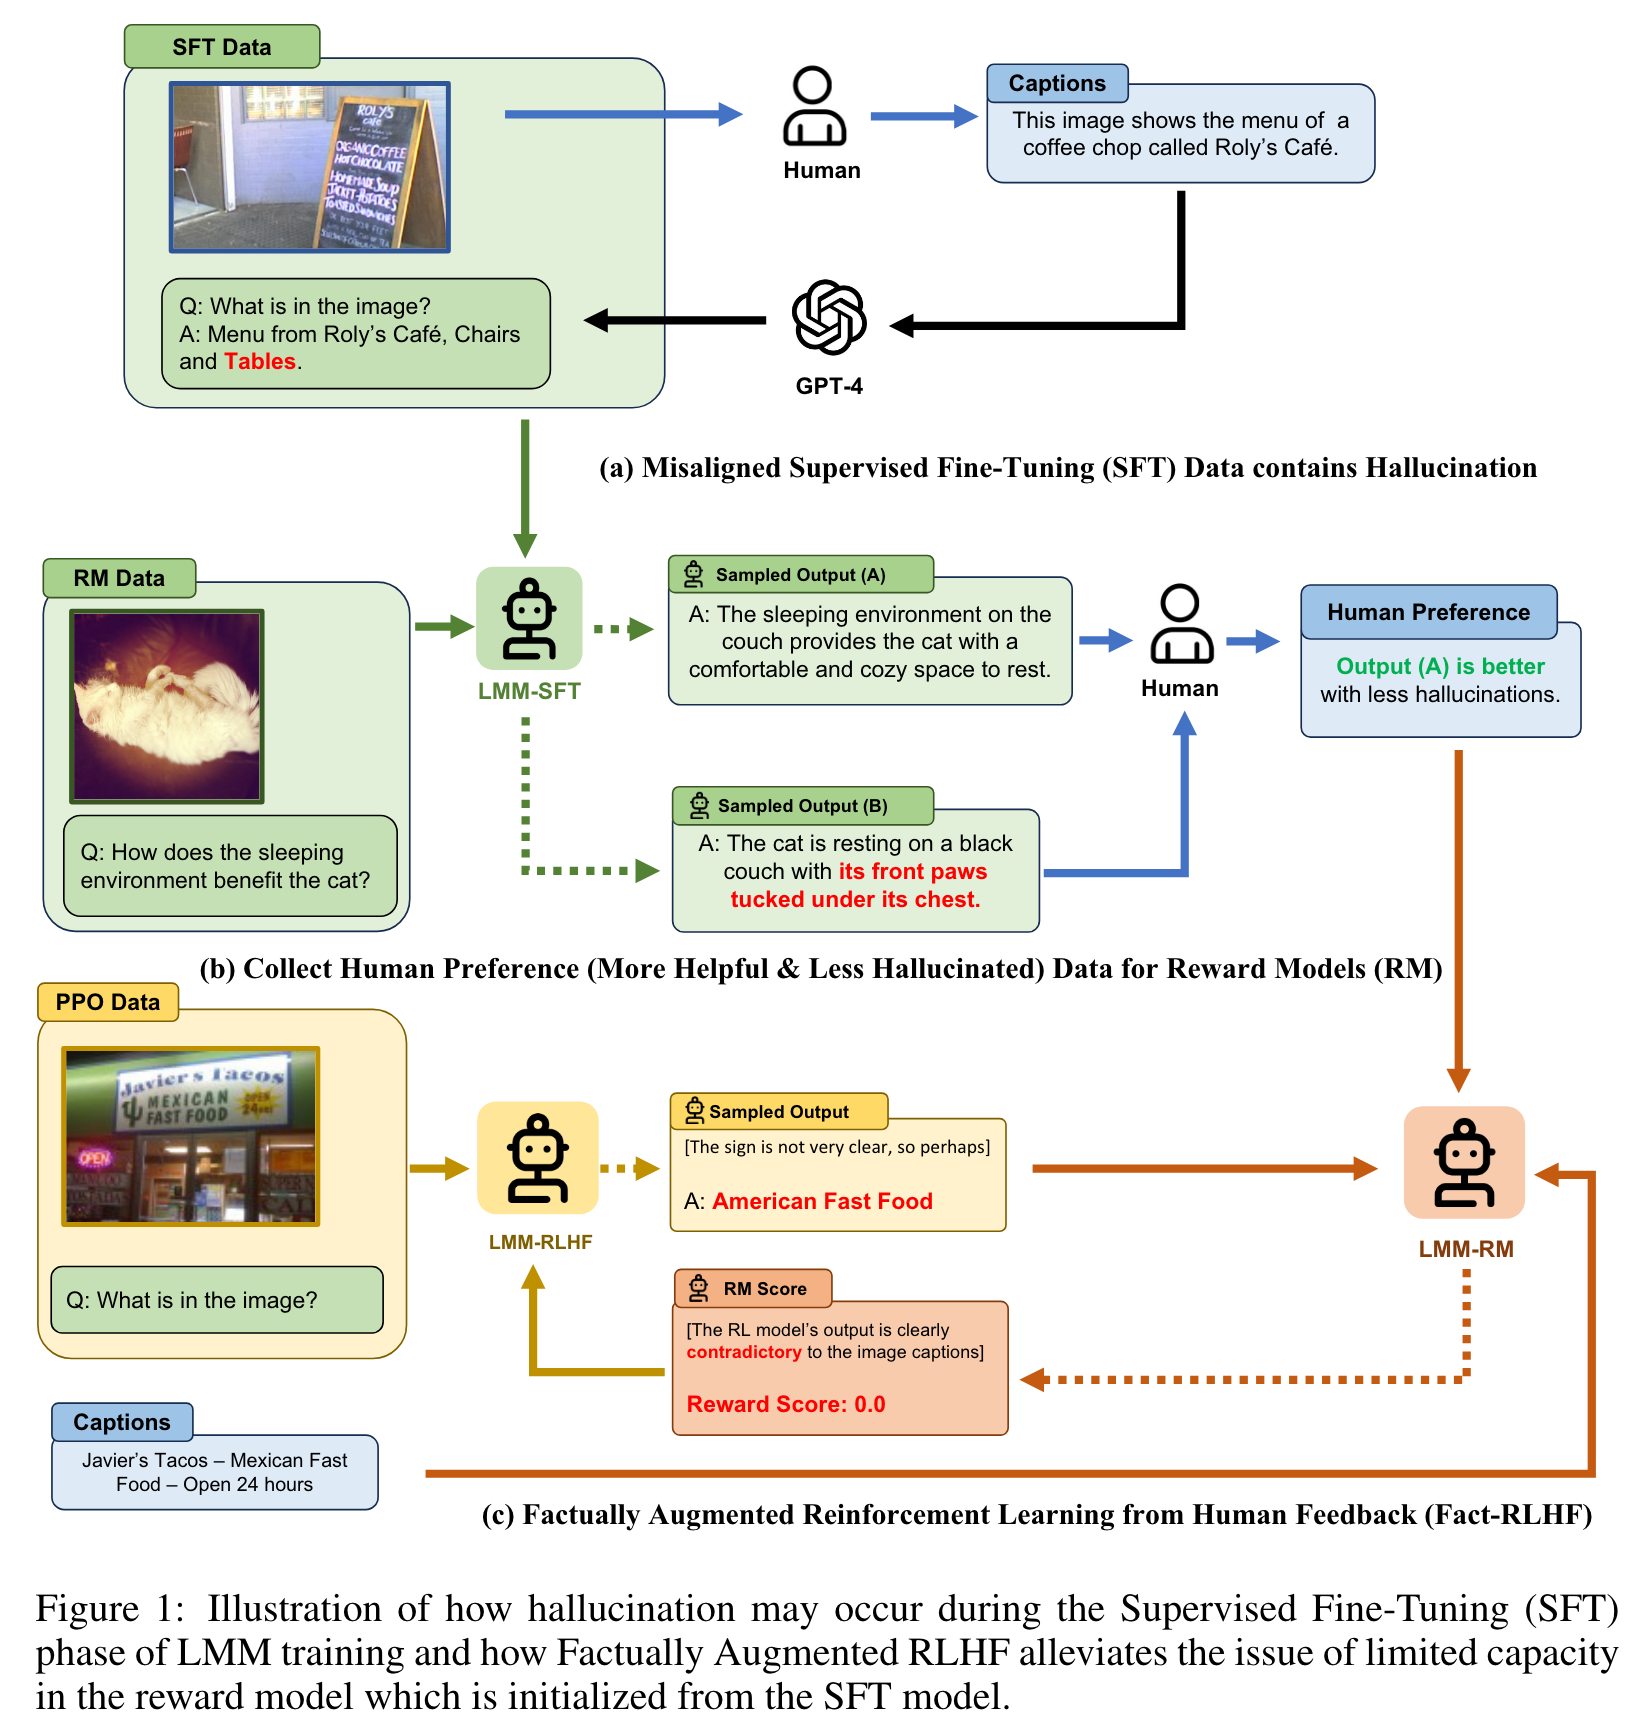
Aligning Large Multimodal Models with Factually Augmented RLHF | Qiang ...

Figure 1 from Relative Alignment Network for Source-Free Multimodal ...
Advertisement Space (336x280)

Figure 1 from Dense Multimodal Alignment for Open-Vocabulary 3D Scene ...

The variational context model for multimodal alignment, figure from ...
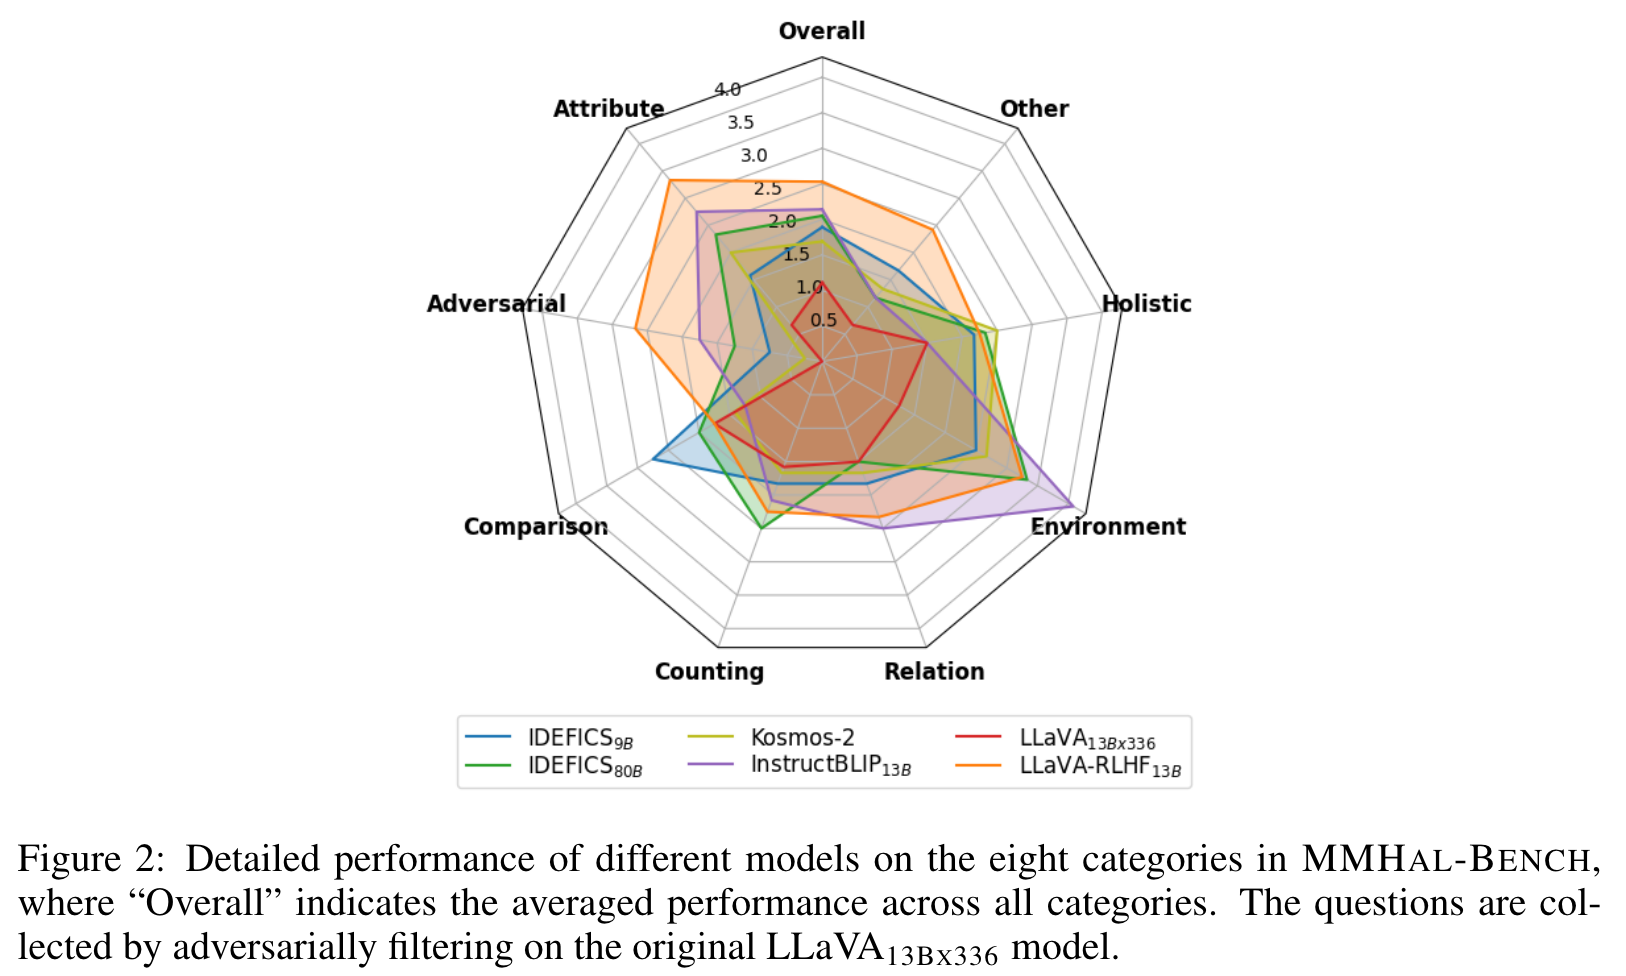
Aligning Large Multimodal Models with Factually Augmented RLHF | Qiang ...

Figure 1 from MM-Instruct: Generated Visual Instructions for Large ...
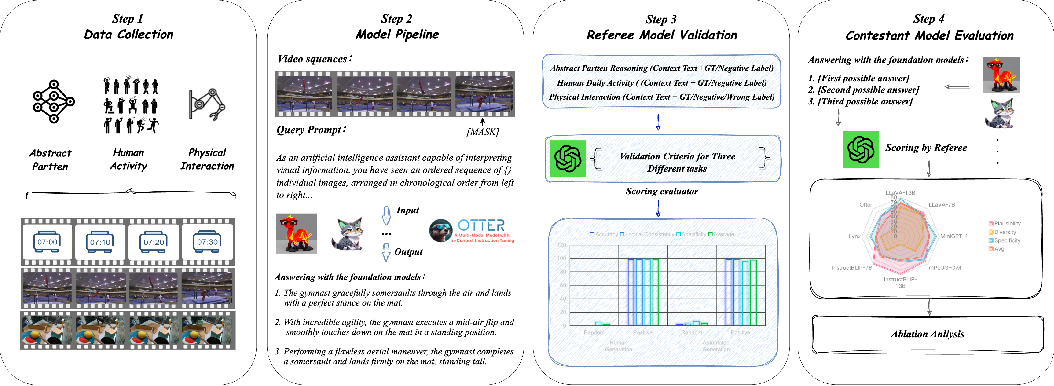
Figure 1 from Benchmarking Sequential Visual Input Reasoning and ...
Final Exam: Aligning Large Multimodal Models with Factually Augmented ...