
Figure 1 From An Attention Based End To End Model For Multiple Text

Figure 1 from Attention based end to end Speech Recognition for Voice ...
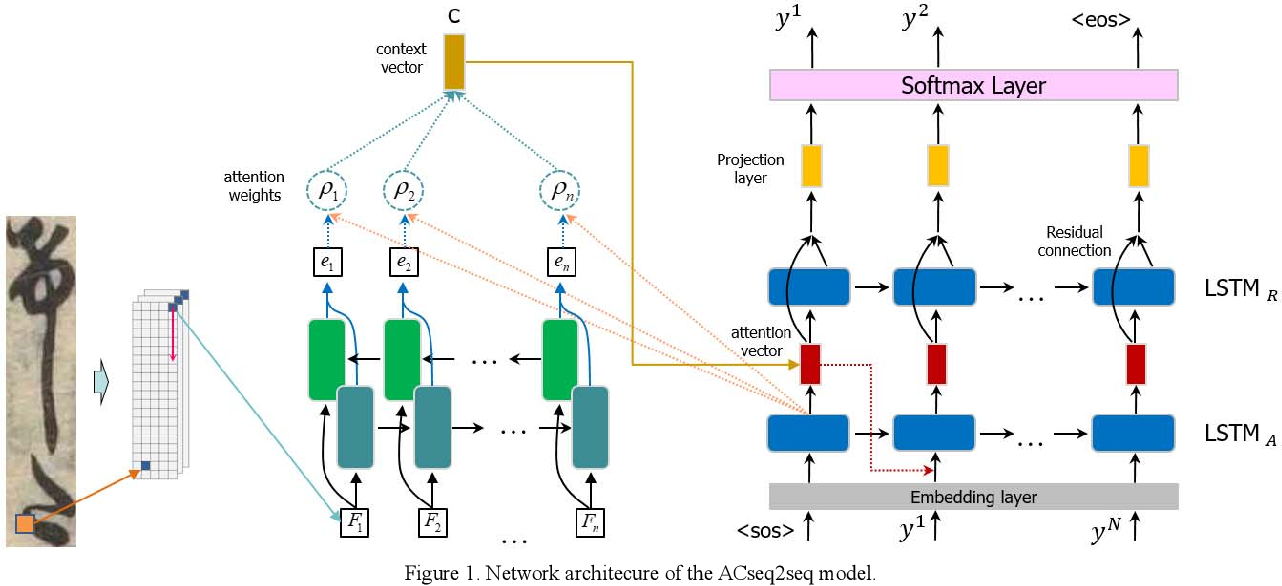
Figure 1 from An Attention-Based End-to-End Model for Multiple Text ...

Figure 2 from On Comparison of Encoders for Attention based End to End ...

Figure 1 from AACFlow: an end-to-end model based on attention augmented ...
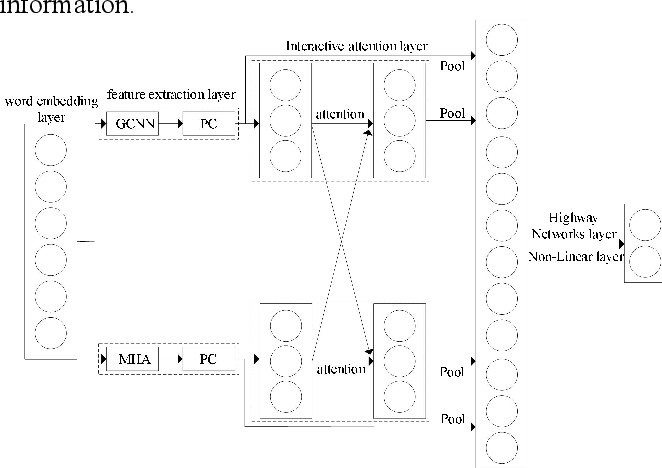
Figure 1 from A Dual-channel Text Classification Model based on an ...

Figure 1 from An Attention-Based Joint Acoustic and Text on-Device End ...
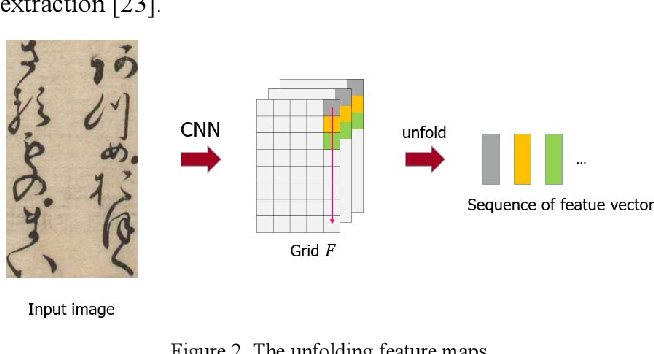
Figure 2 from An Attention-Based End-to-End Model for Multiple Text ...

Figure 1 from An Attention-based Sequence Learning Model for Scene Text ...

Figure 1 from Improving Attention Based Sequence-to-Sequence Models for ...

[2404.07602] Attention based End to end network for Offline Writer ...
Advertisement Space (300x250)
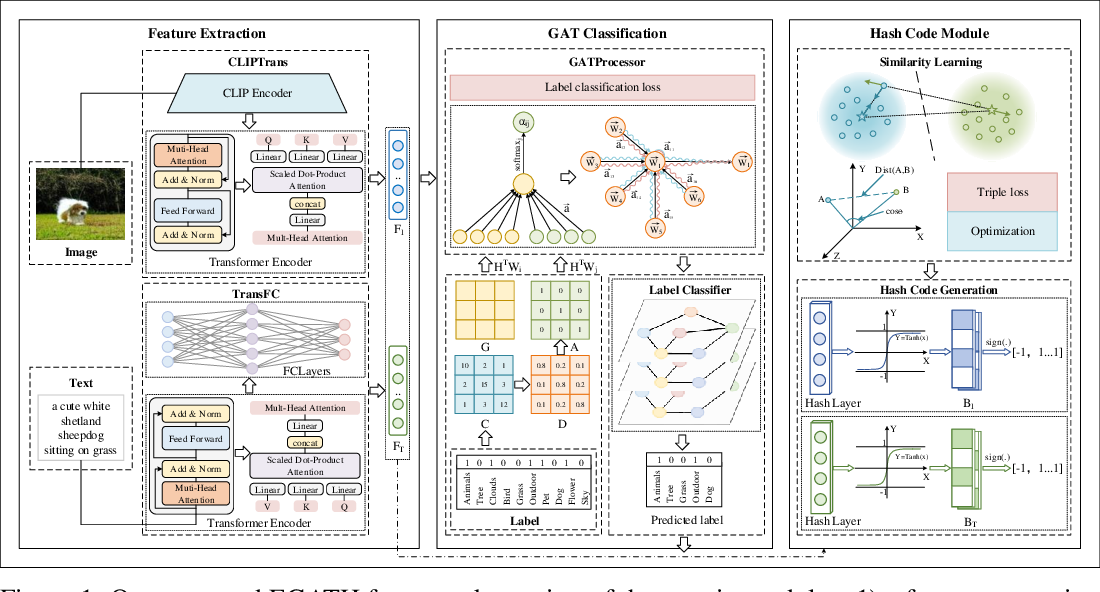
Figure 1 from An End-To-End Graph Attention Network Hashing for Cross ...
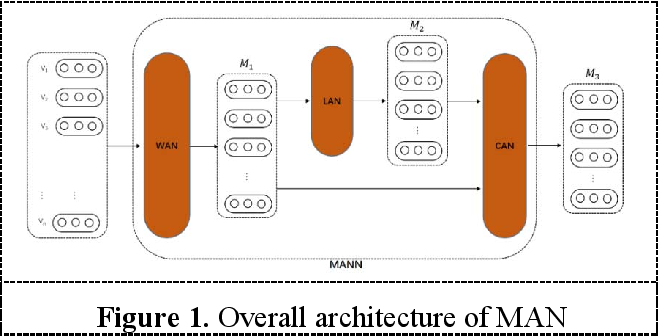
Figure 1 from Short Text Classification Model Based on Multi-Attention ...

Figure 1 from AgeNet-AT: An End-to-End Model for Robust Joint Speaker ...
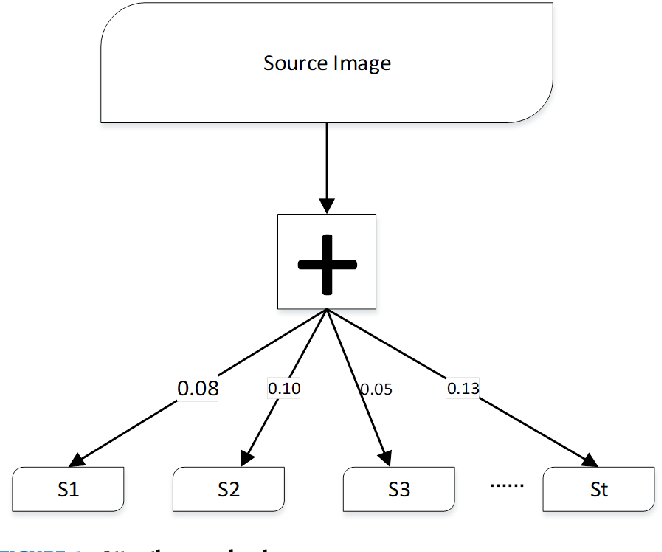
Figure 1 from Multilayer Dense Attention Model for Image Caption ...

Figure 3 from An End-to-End Spatio-Temporal Attention Model for Human ...
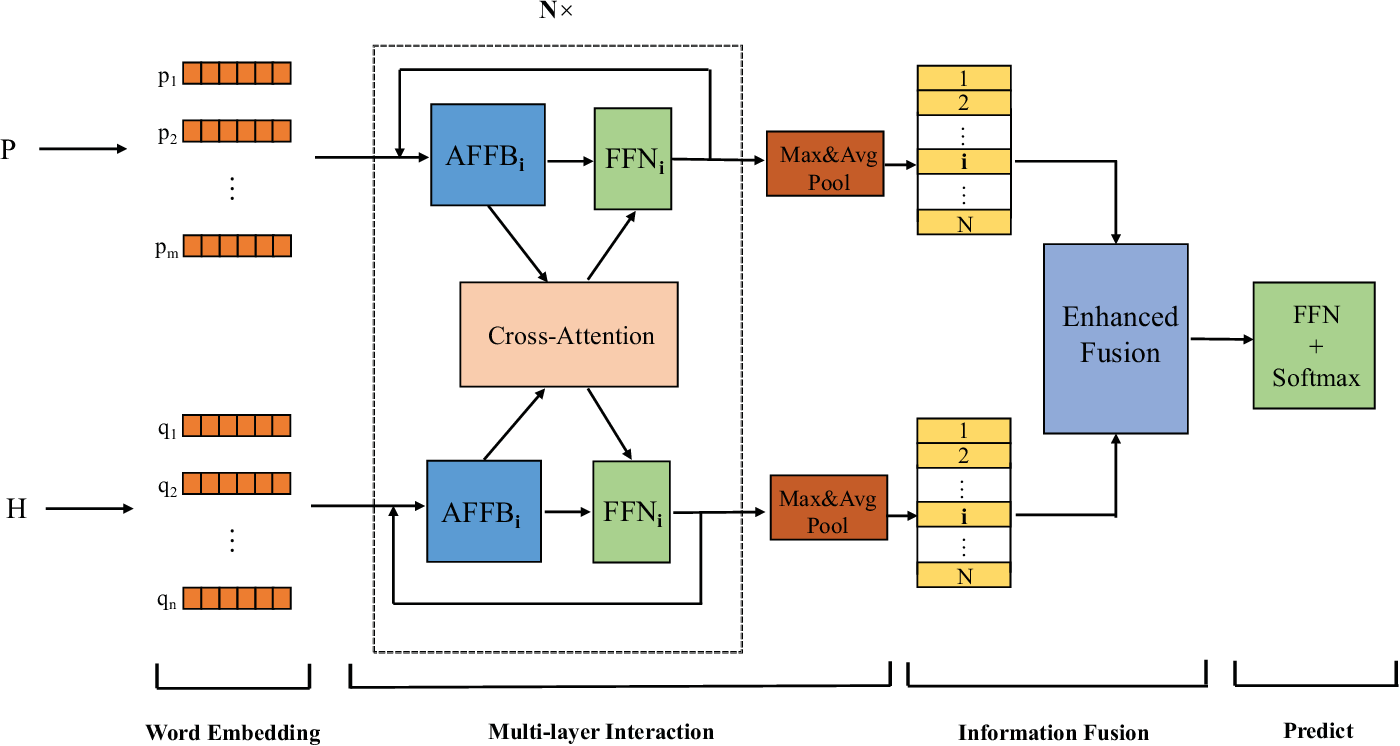
Figure 1 from Attention-Based Multi-level Network for Text Matching ...
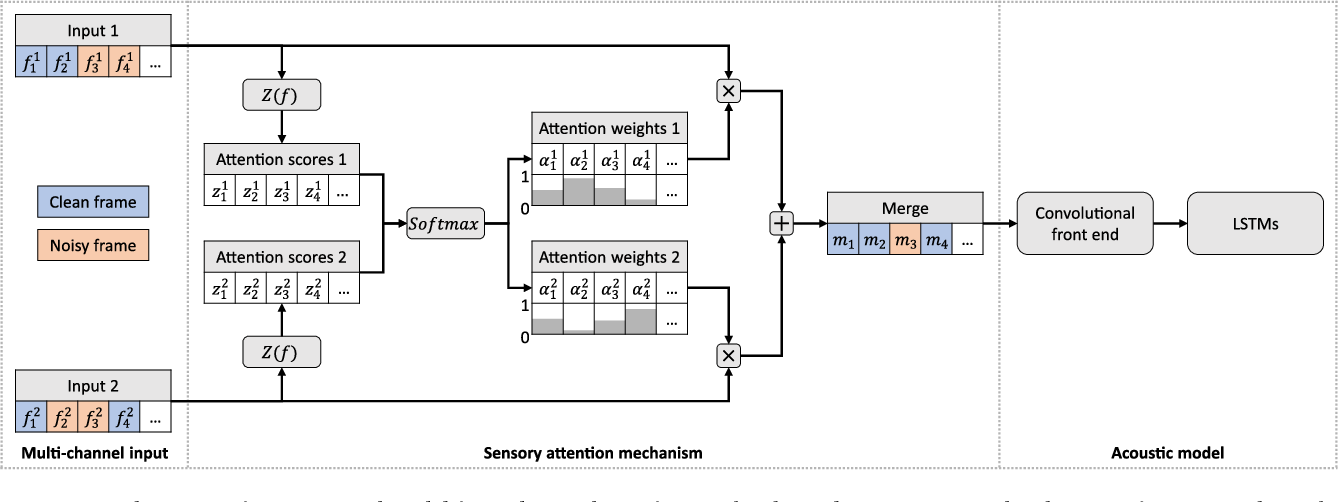
Figure 1 from Multi-channel Attention for End-to-End Speech Recognition ...

Figure 1 from Streaming Bilingual End-to-End ASR Model Using Attention ...
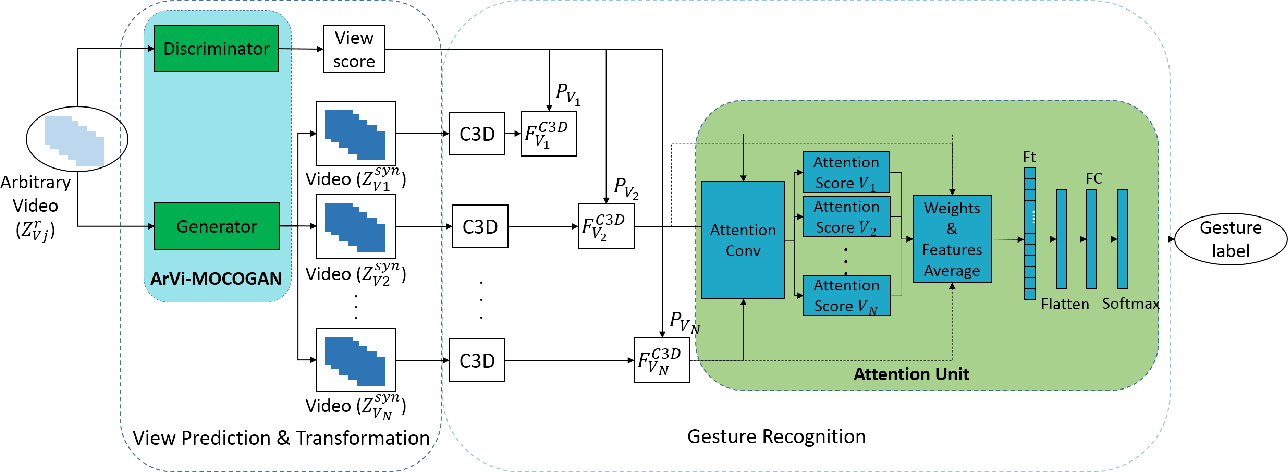
Figure 1 from An End-to-End Model of ArVi-MoCoGAN and C3D with ...

Block diagram of end to end attention based person re-identification ...
Advertisement Space (336x280)
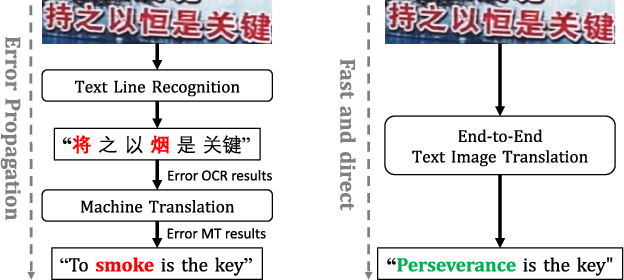
Figure 1 from Modal Contrastive Learning Based End-to-End Text Image ...
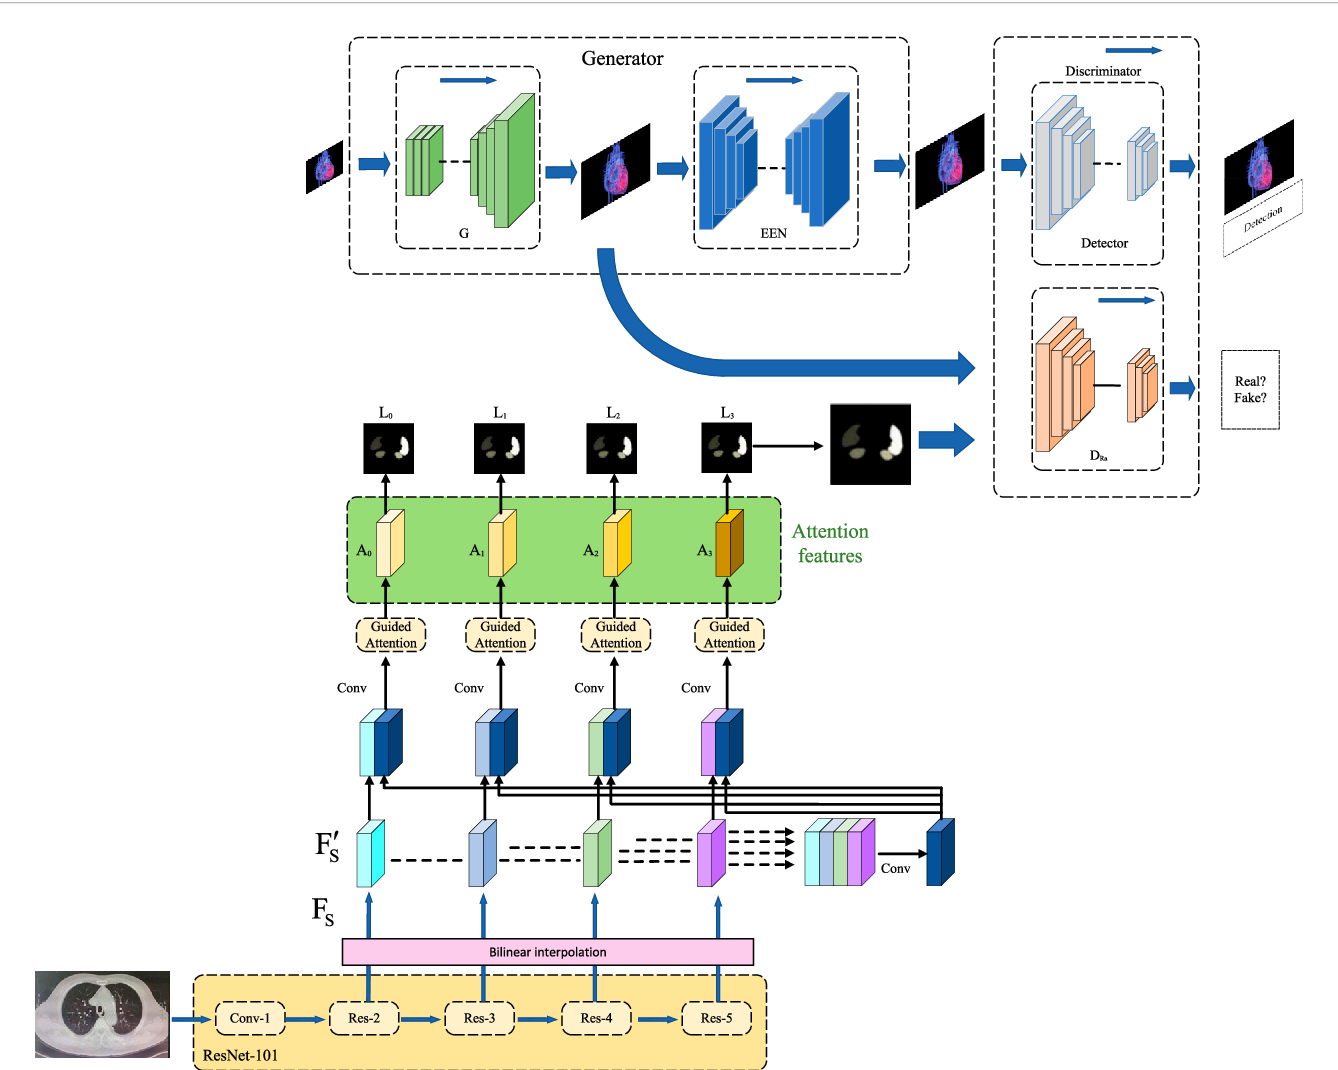
Figure 1 from Application of an end-to-end model with self-attention ...

An Ensemble Model with Attention Based Mechanism for Image Captioning ...

Figure 2 from AgeNet-AT: An End-to-End Model for Robust Joint Speaker ...
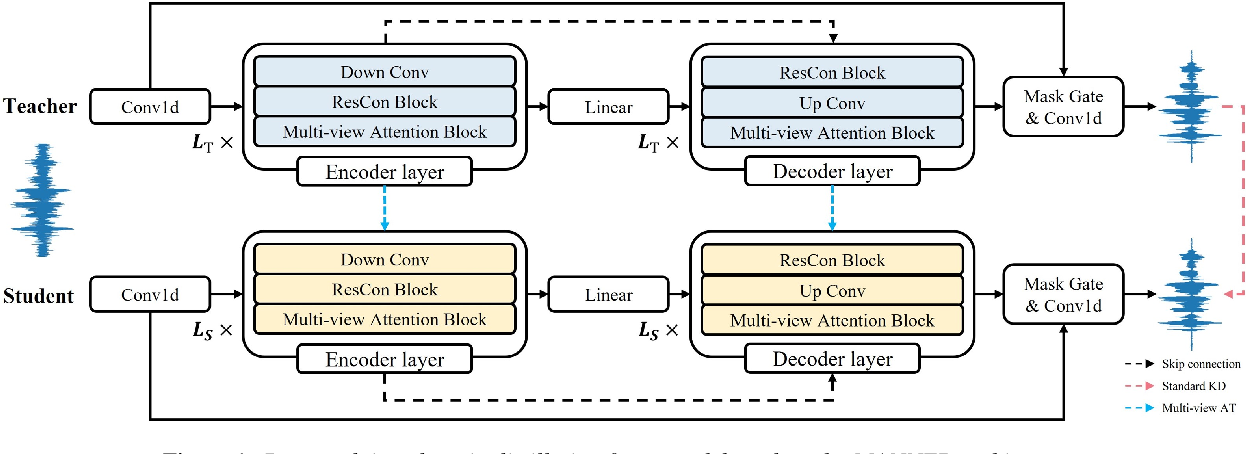
Figure 1 from Multi-View Attention Transfer for Efficient Speech ...

Figure 1 from Gate-Attention and Dual-End Enhancement Mechanism for ...

Figure 1 from End-to-end model-based trajectory prediction for ro-ro ...

Figure 1 from End-To-End Multi-Task Learning With Attention | Semantic ...

Figure 1 from SPLC: An Attention-Based End-to-End Superpixels and Land ...
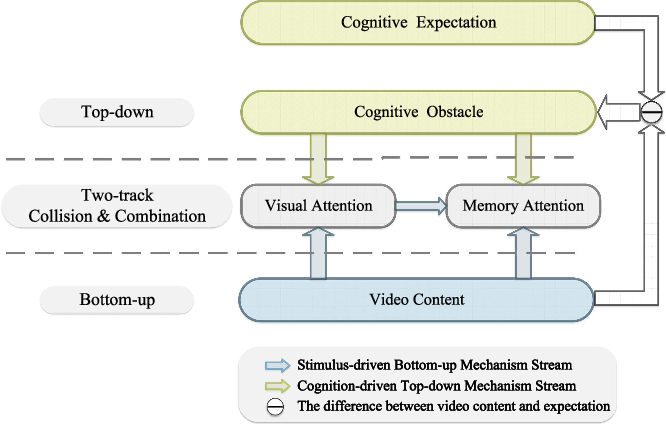
Figure 1 from End-to-End Blind Video Quality Assessment Based on Visual ...
Advertisement Space (336x280)

Figure 1 from Attention-based end-to-end CNN framework for content ...

Figure 1 from End-To-End Multi-Task Learning With Attention | Semantic ...

Figure 3 from Modal Contrastive Learning Based End-to-End Text Image ...
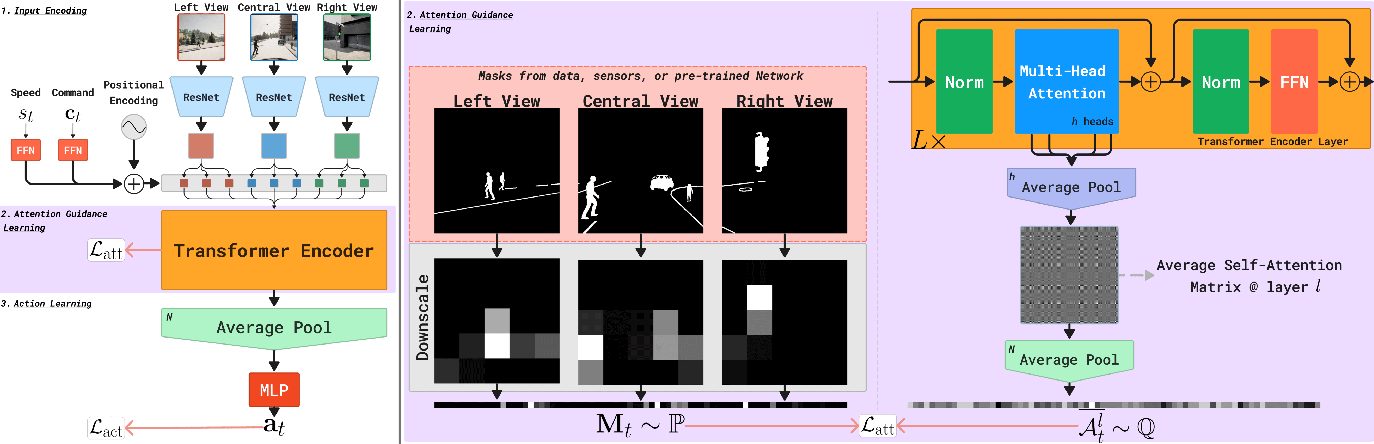
Figure 1 from Guiding Attention in End-to-End Driving Models | Semantic ...

AACFlow: an end-to-end model based on attention augmented convolutional ...
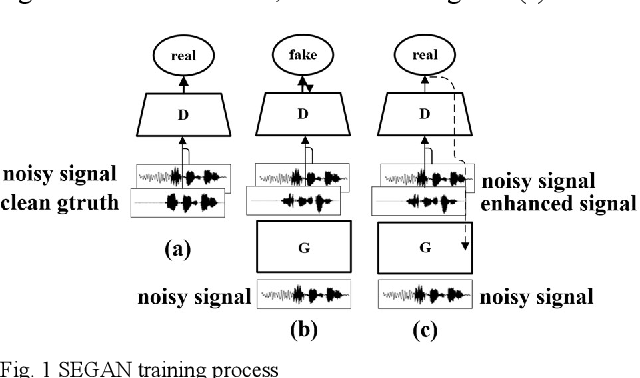
Figure 1 from An End-to-End Speech Enhancement Method Combining ...