
Figure 1 From An Efficient Transformer With Distance Aware Attention
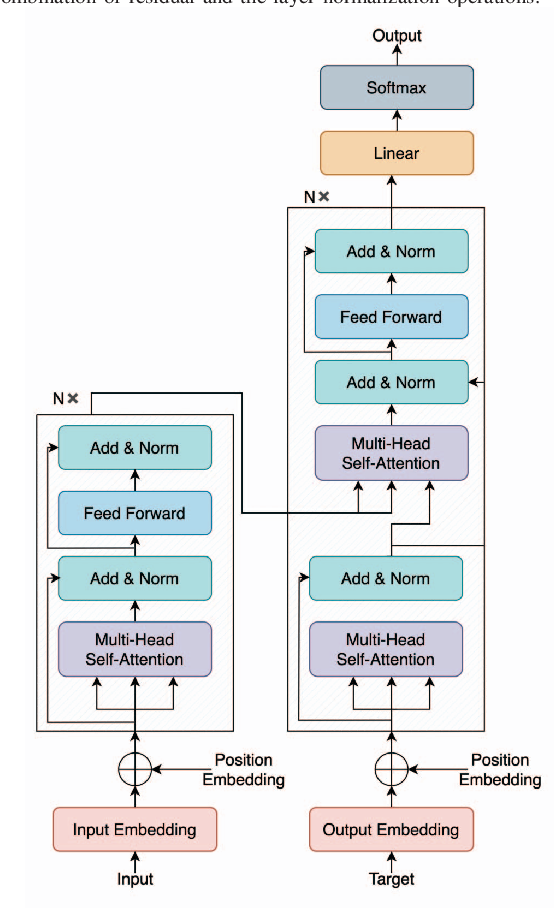
Figure 1 from An Efficient Transformer with Distance-aware Attention ...

Figure 1 from Exploring Attention Map Reuse for Efficient Transformer ...

Figure 1 from Efficient Transformer Inference with Statically ...
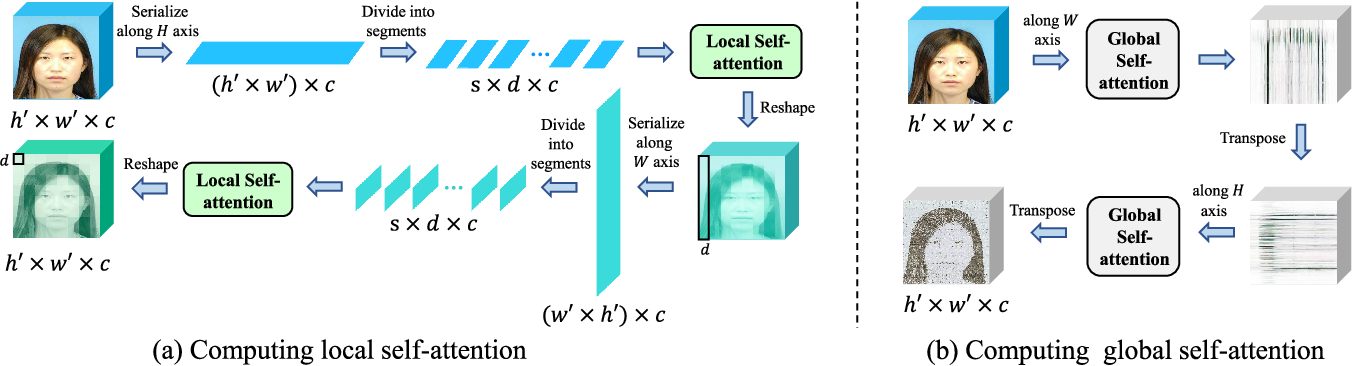
Figure 1 from An Efficient Transformer Based on Global and Local Self ...

Figure 1 from Efficient Dual Attention Transformer for Image Super ...
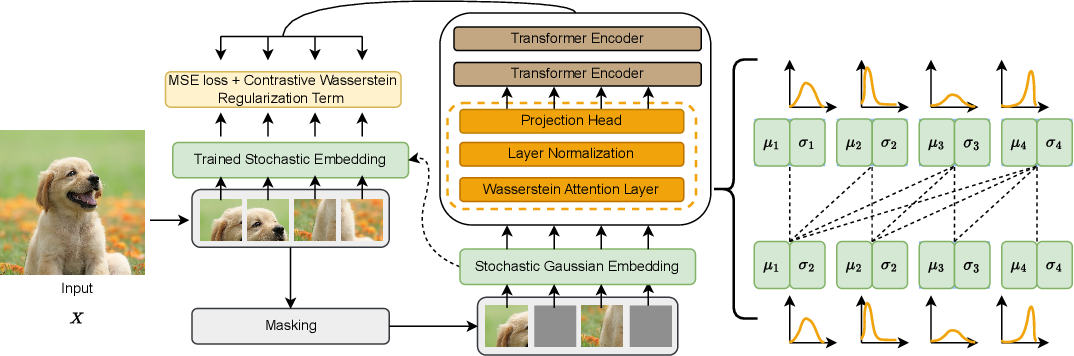
Figure 1 from Stochastic Vision Transformers with Wasserstein Distance ...

Figure 1 from A Point Transformer Accelerator With Distribution-Aware ...
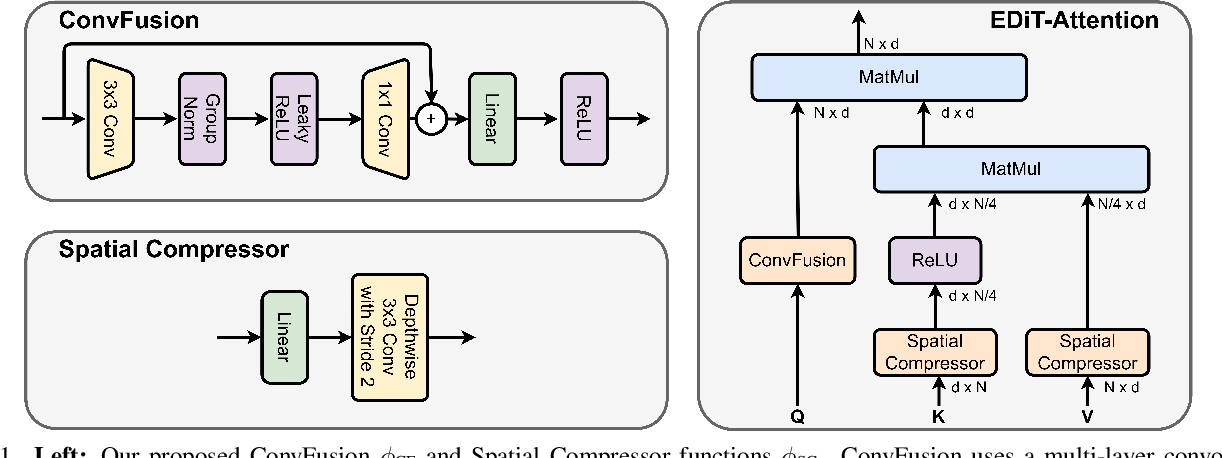
Figure 1 from Edit: Efficient Diffusion Transformers with Linear ...
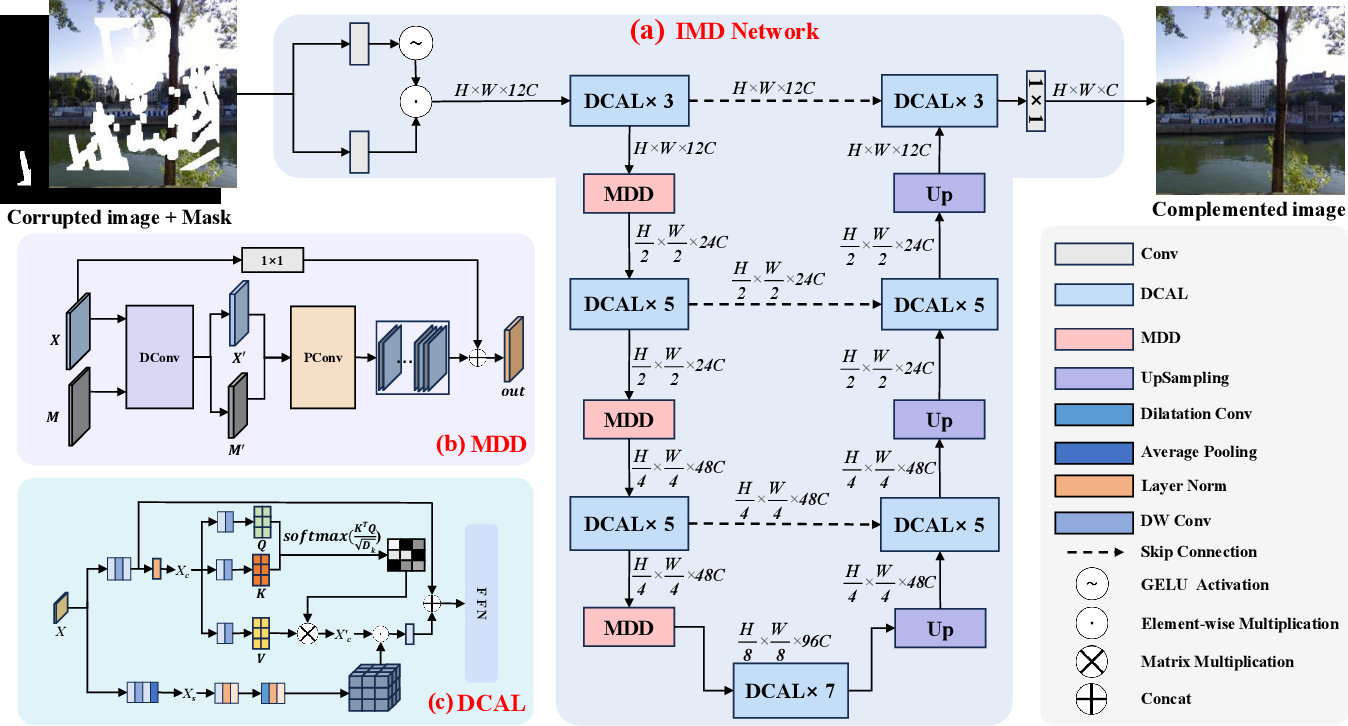
Figure 1 from Image Inpainting Transformer with Mask-Aware Encoding and ...

Figure 1 from Abstracting Local Transformer Attention for Enhancing ...
Advertisement Space (300x250)

Figure 1 from Accelerating Transformers with Fourier-Based Attention ...

Figure 1 from An Exploration of Hierarchical Attention Transformers for ...

Figure 1 from Efficient Context-Aware Graph Transformer for Vehicle ...

Efficient transformer tracking with adaptive attention - Xiao - 2024 ...

Figure 2 from ETMA: Efficient Transformer-Based Multilevel Attention ...

Efficient transformer tracking with adaptive attention - Xiao - 2024 ...

Figure 1 from Content-aware Token Sharing for Efficient Semantic ...

Figure 2 from An Exploration of Hierarchical Attention Transformers for ...

Figure 1 from DualToken-ViT: Position-aware Efficient Vision ...

Figure 1 from Efficient Zero-shot Visual Search via Target and Context ...
Advertisement Space (336x280)

Figure 1 from Temporal Aware Mixed Attention-based Convolution and ...

(PDF) Efficient Multi-Scale Transformer with Convolutional Attention ...
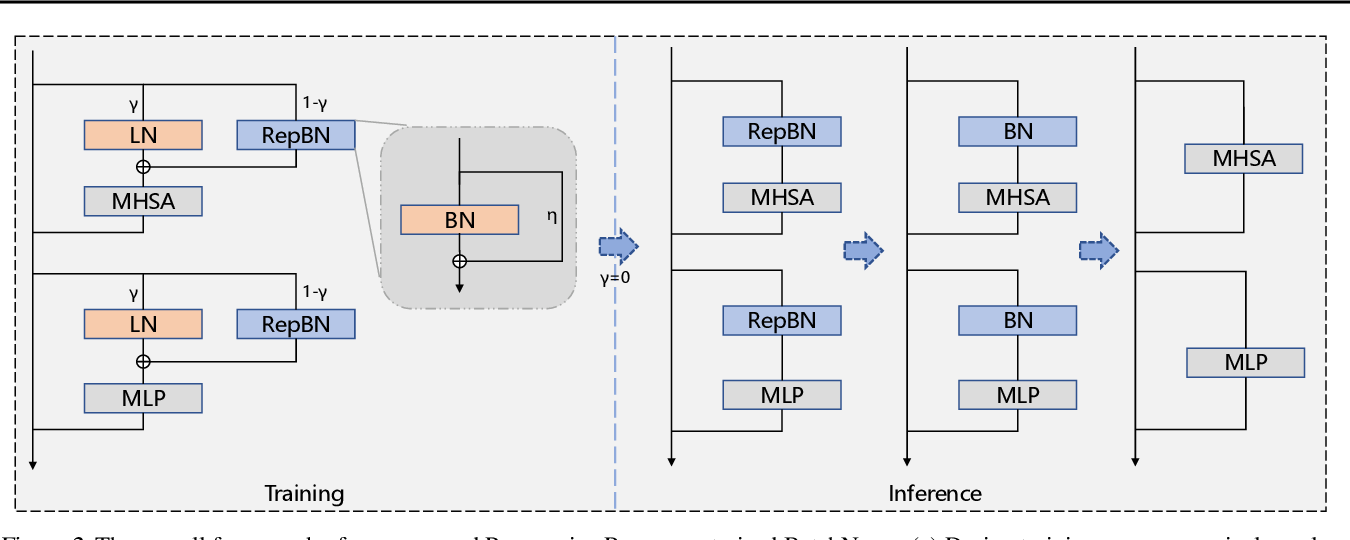
Figure 2 from SLAB: Efficient Transformers with Simplified Linear ...

Figure 1 from Molecular Geometry-aware Transformer for accurate 3D ...
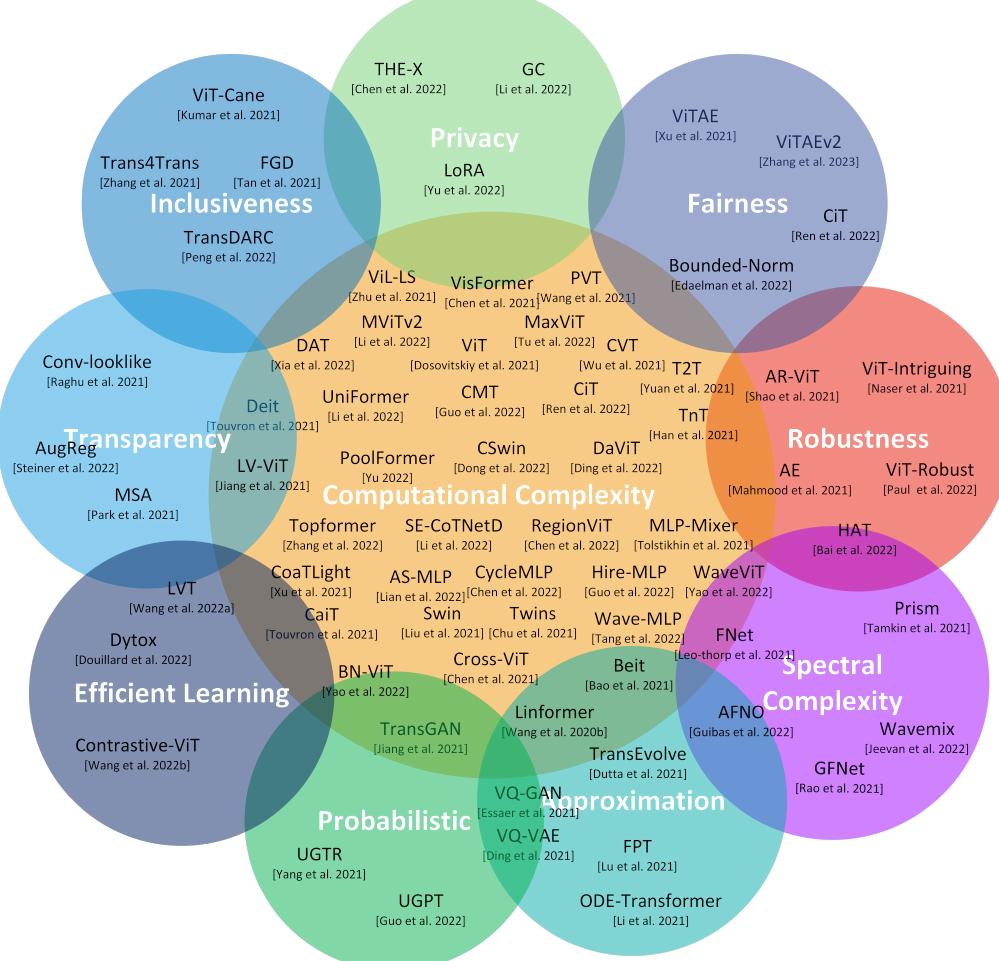
Figure 1 - from Efficiency 360: Efficient Vision

Exploring Attention Map Reuse for Efficient Transformer Neural Networks
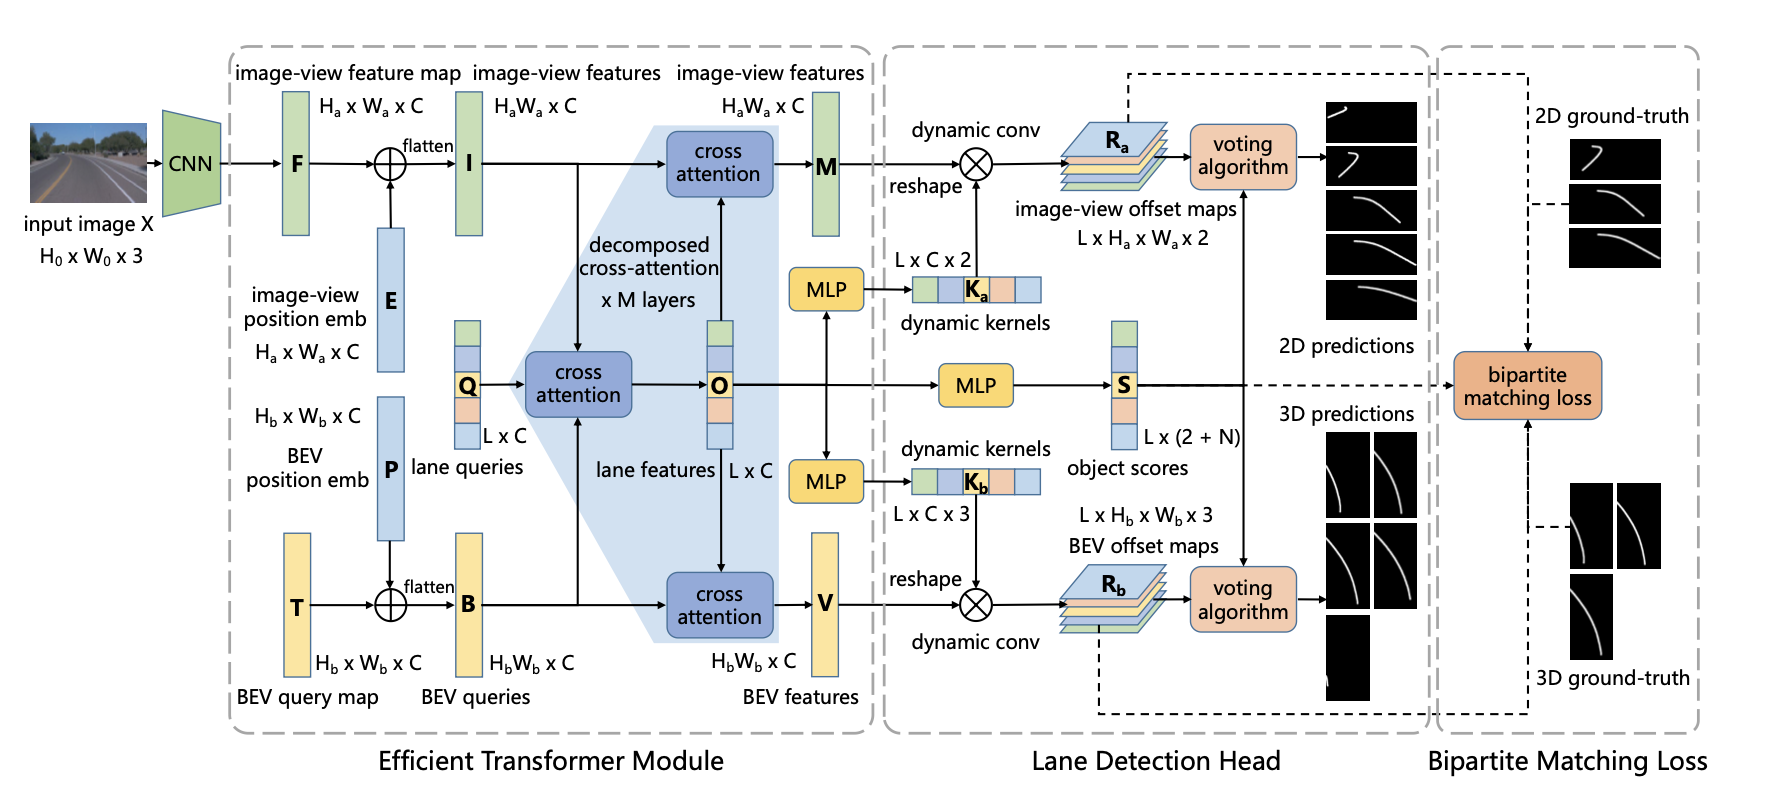
An Efficient Transformer for Simultaneous Learning of BEV and Lane ...
Time-aware Transformer with one attention layer for learning unseen ...

Time-aware Transformer with one attention layer for learning unseen ...
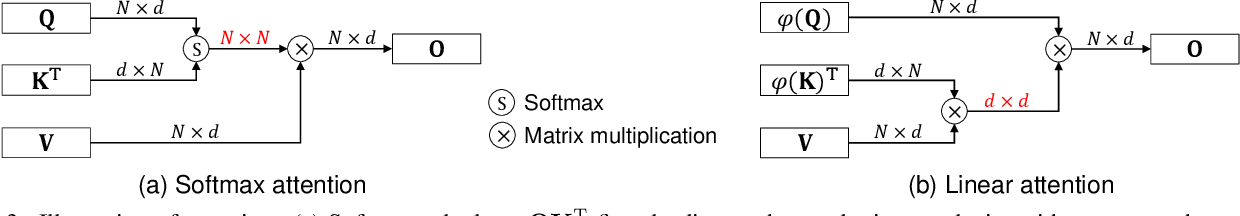
Figure 3 from Neural Architecture Search on Efficient Transformers and ...
Advertisement Space (336x280)
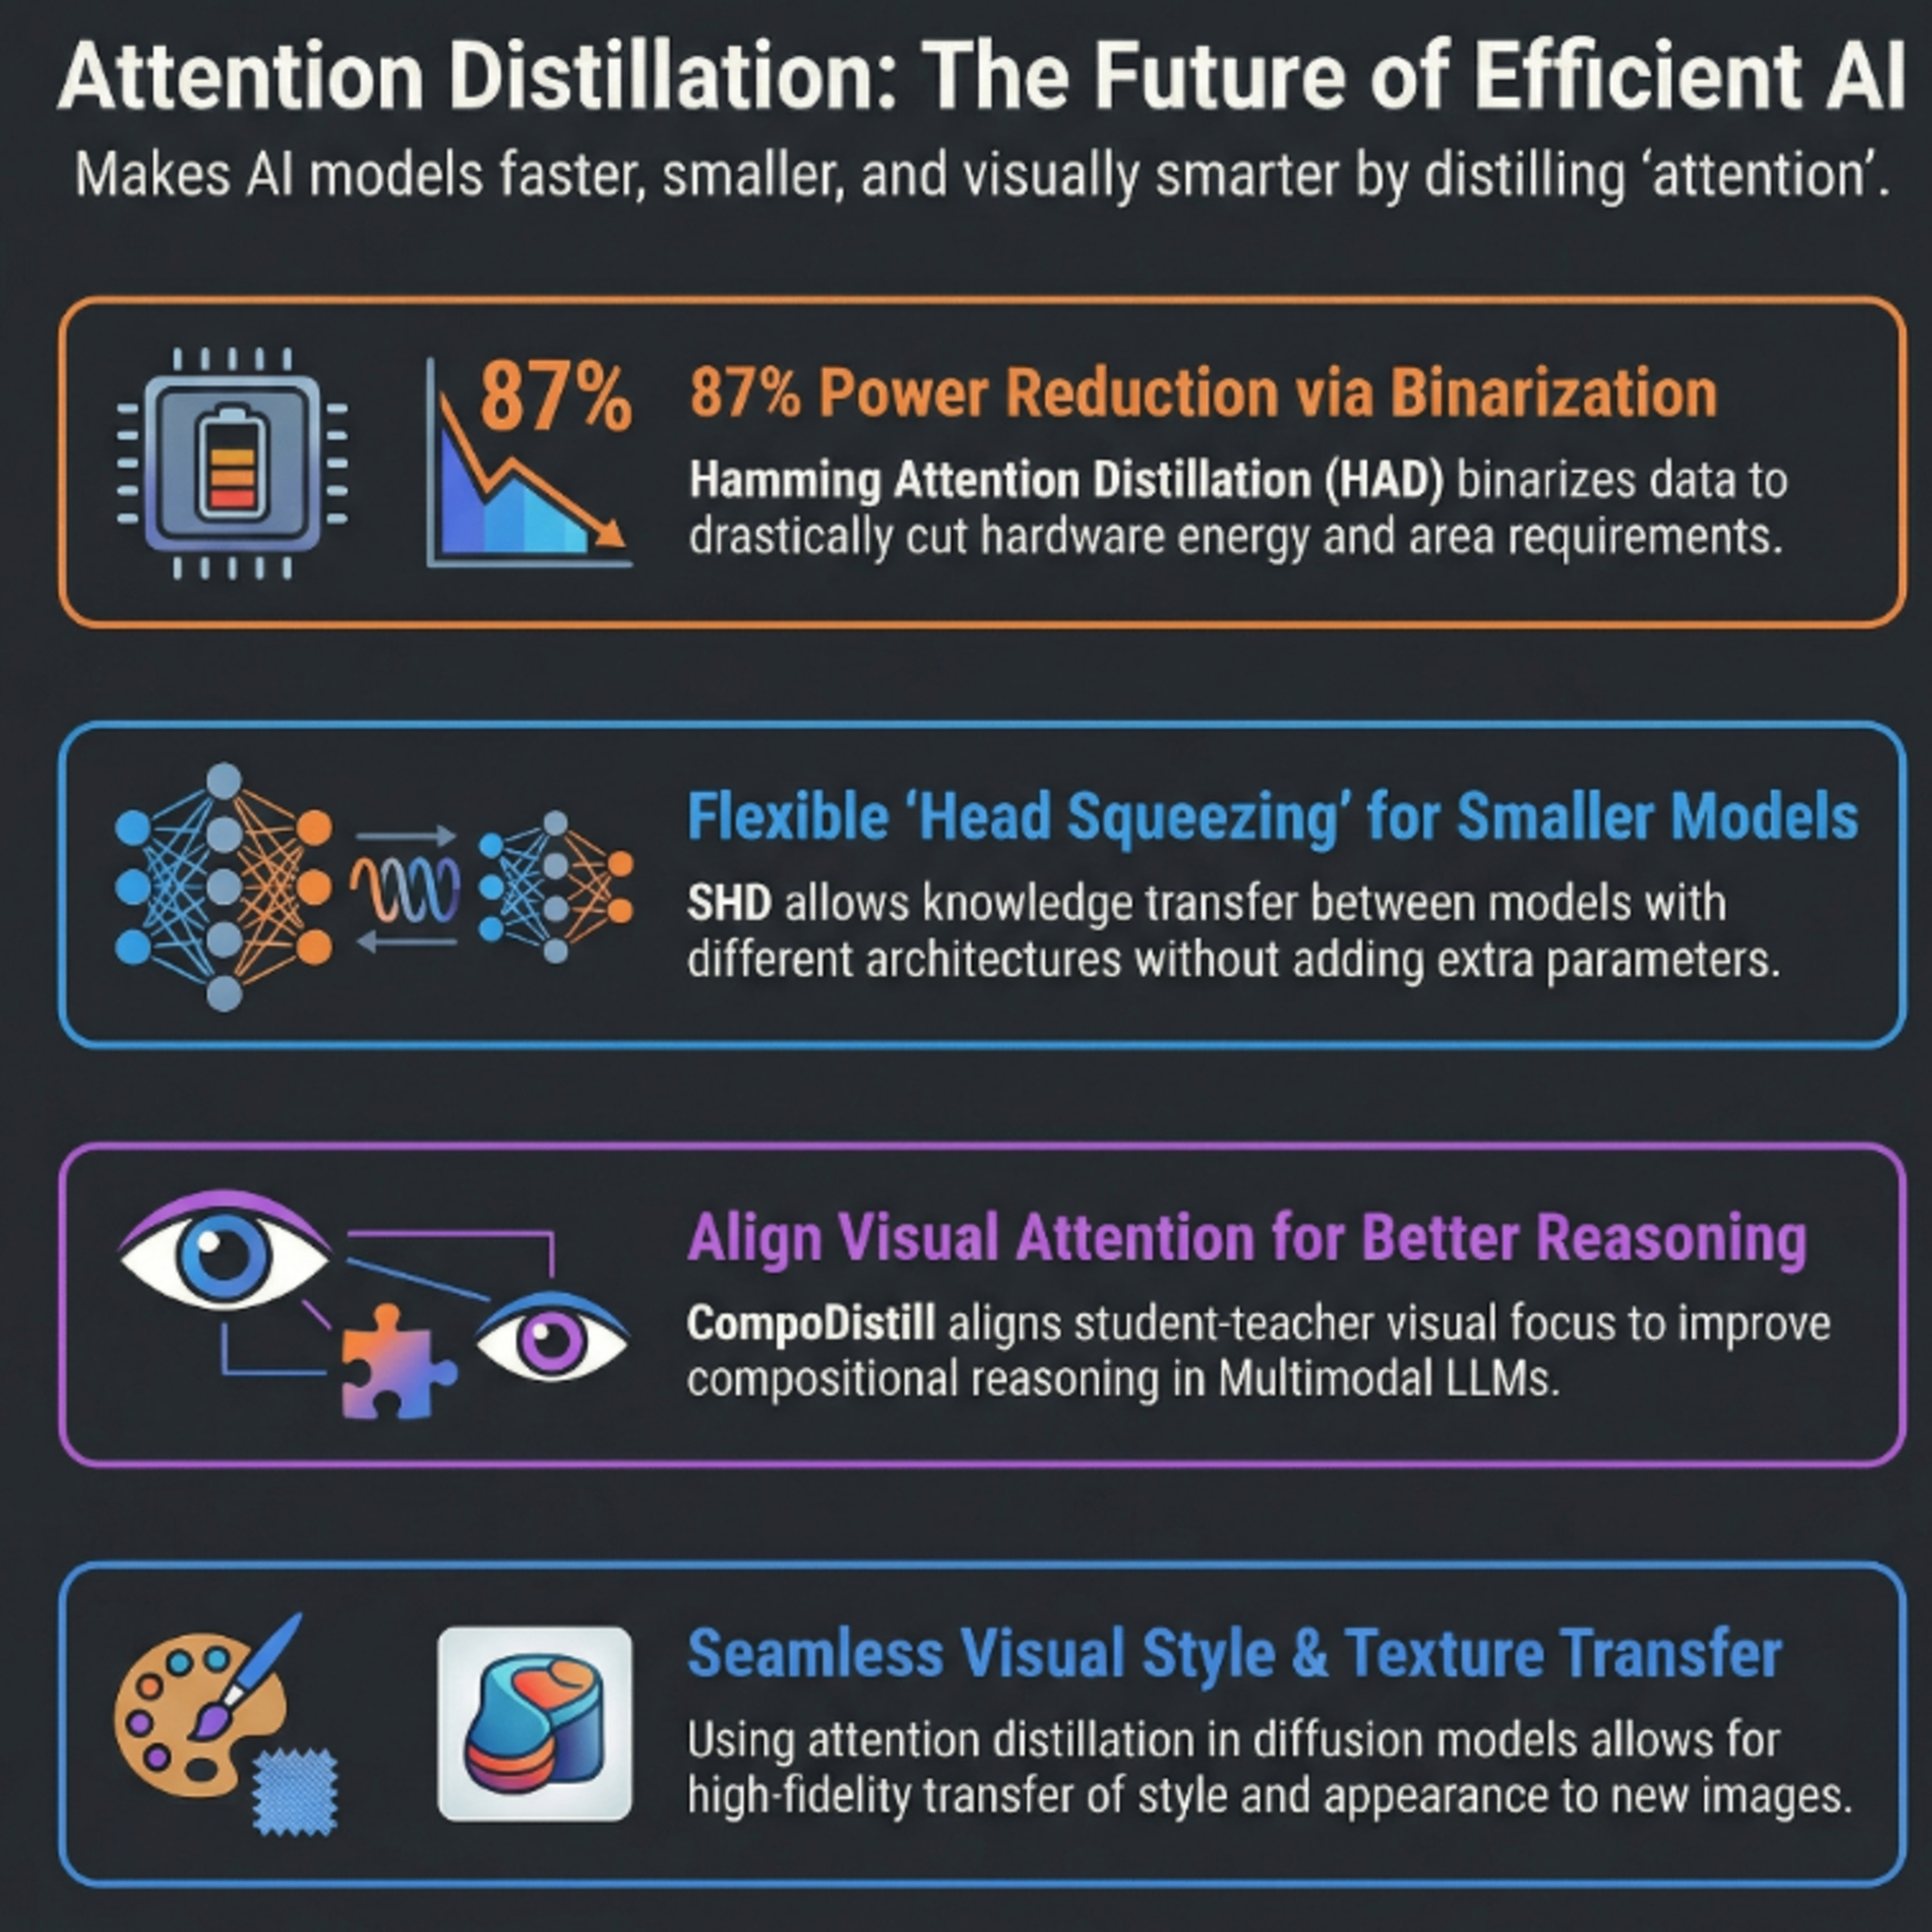
Advances in Attention Distillation for Efficient Transformer Models ...

論文解説 EfficientViT: Memory Efficient Vision Transformer with Cascaded ...

(PDF) Exploring Attention Map Reuse for Efficient Transformer Neural ...

Emulating the Attention Mechanism in Transformer Models with a Fully ...

(PDF) Diffuser: Efficient Transformers with Multi-hop Attention ...

Figure 1 from Low-Bit Integerization of Vision Transformers Using ...